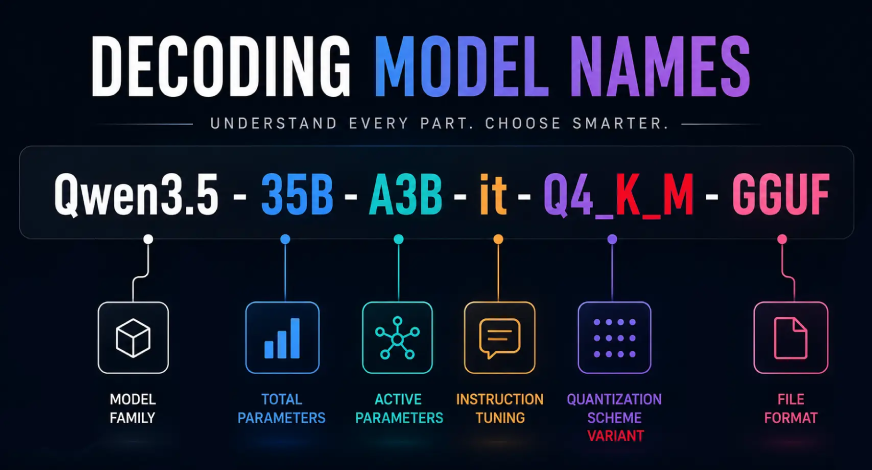
In case you have ever tried downloading a neighborhood LLM, you could have most likely seen mannequin names that appear to be this:
Qwen3.8-27B-A3B-It-2507-gguf-q2ks-mixed-AutoRound
At first, it appears like meaningless technical shorthand.
It isn’t!
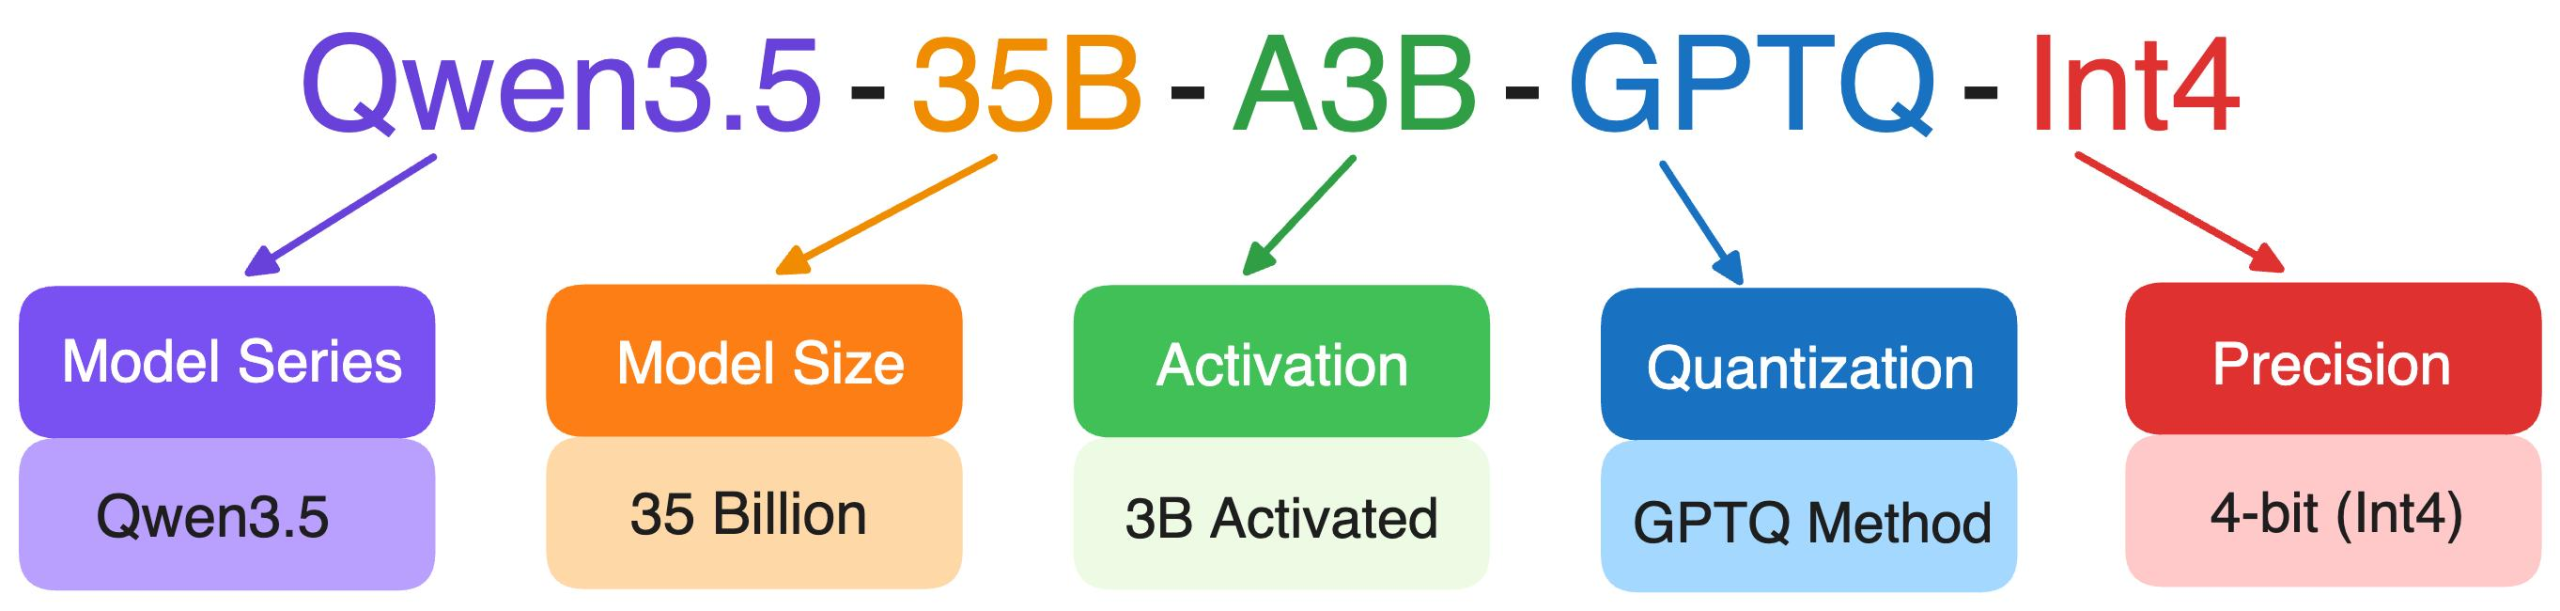
Each a part of that identify tells you one thing in regards to the mannequin: how giant it’s, how it’s constructed, how a lot of it’s used at a time, how its weights are saved, and what format the file makes use of.
When you perceive these items, selecting a neighborhood mannequin turns into a lot simpler.
1. 7B, 14B, 35B… How Giant Is the Mannequin?
The primary quantity you often see is the mannequin’s parameter depend.
The B means billion.
So:
7B = 7 billion parameters
14B = 14 billion parameters
35B = 35 billion parameters
70B = 70 billion parameters
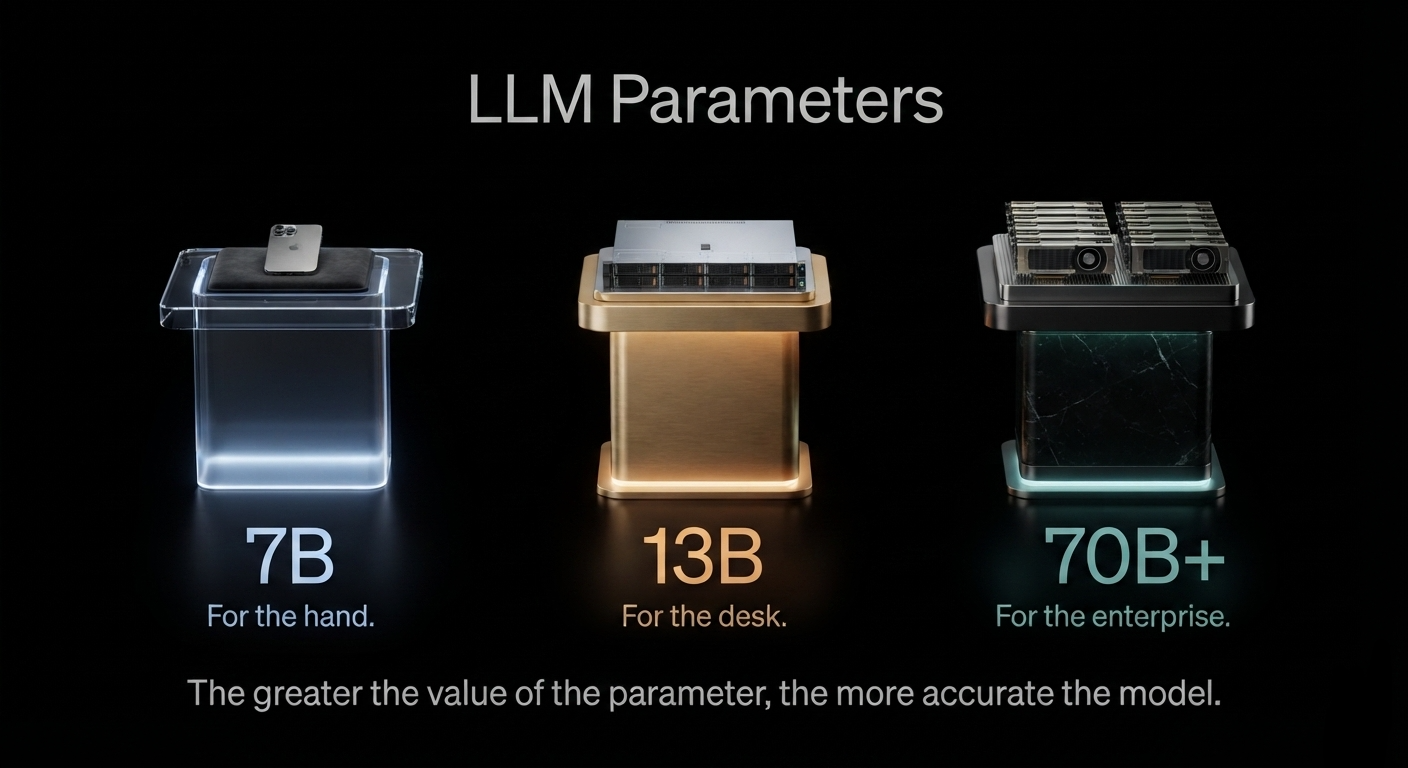
Parameters are the discovered values that make up the mannequin.
For native AI, parameter depend issues as a result of a bigger mannequin usually requires extra reminiscence to run.
Word
Proprietary fashions like Gemini 3 Professional, Claude Opus 5 and so forth. can have parameter counts in trillions.
However there is a vital complication.
A mannequin with 35B parameters doesn’t essentially use all 35 billion each time it generates a token.
That brings us to MoE fashions.
2. MoE: Does the Mannequin Use Every little thing at As soon as?
There are two broad sorts of fashions you’ll encounter:
Dense fashions and Combination-of-Consultants (MoE) fashions.
A dense mannequin makes use of basically its total parameter set for every token. So, a 35B dense mannequin makes use of roughly all 35B parameters throughout inference.
An MoE mannequin works in a different way.
It incorporates a a lot bigger pool of parameters, divided into completely different consultants. A routing mechanism decides which consultants ought to be used for a specific token.
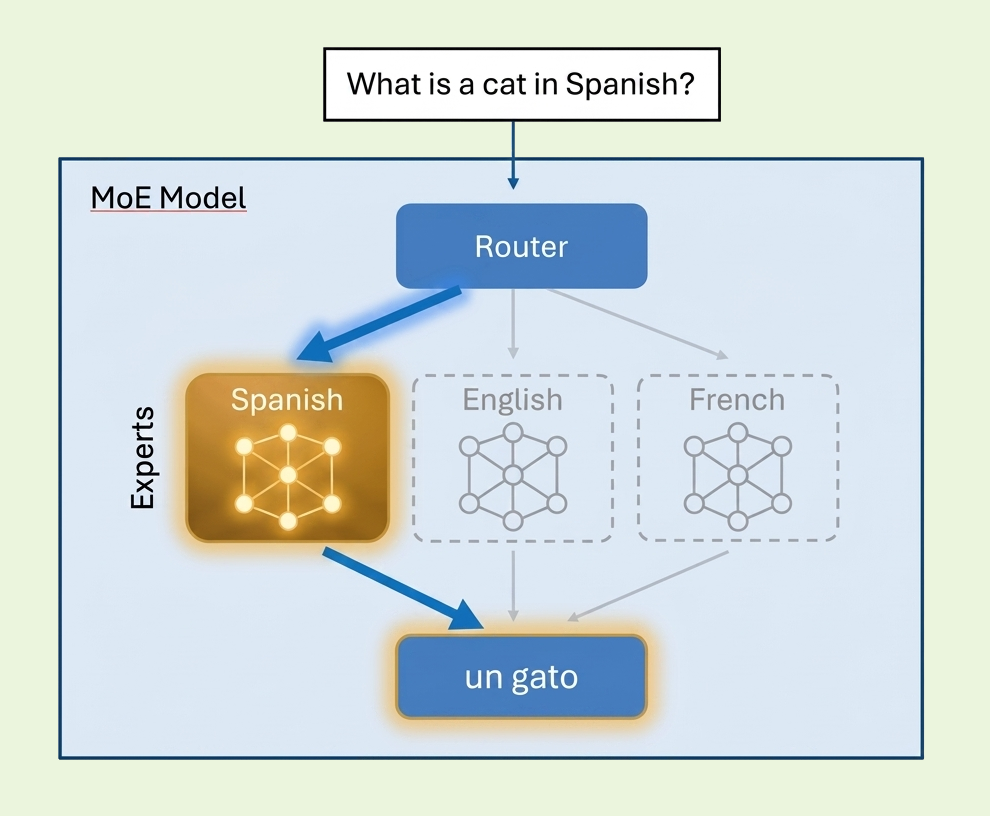
This implies an MoE mannequin can have a big whole parameter depend with out utilizing all these parameters without delay.
And that’s the place the subsequent a part of the identify is available in.
3. A3B: How Many Parameters Are Lively?
You may see a mannequin known as:
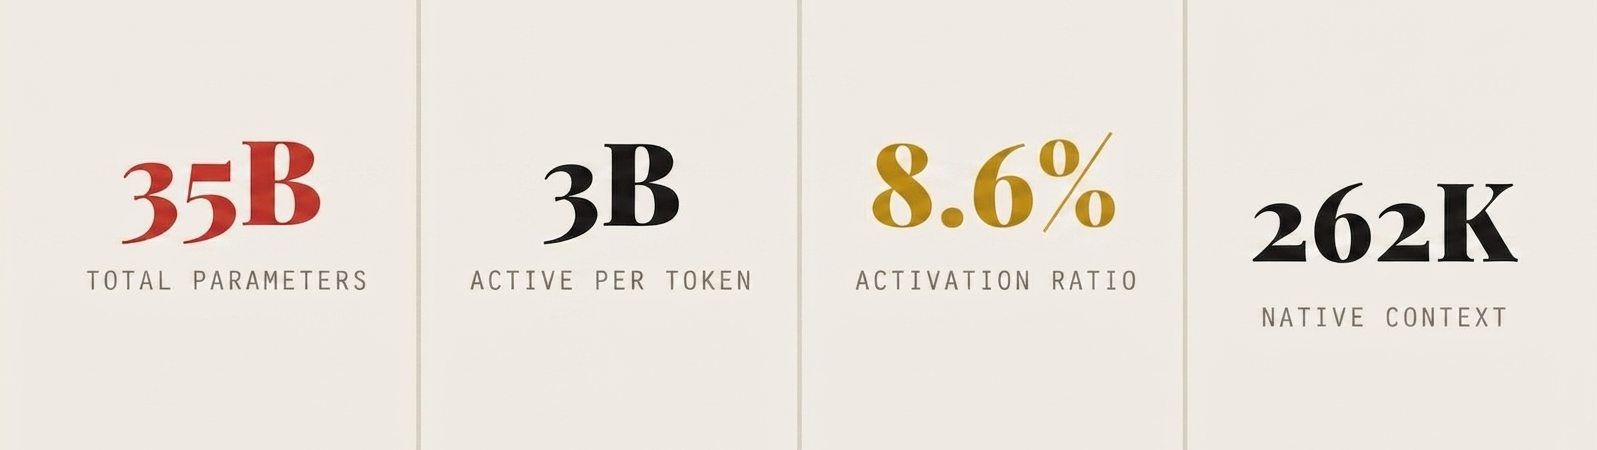
35B-A3B
The primary quantity nonetheless means:
35B = 35 billion whole parameters
The A3B tells you roughly how many parameters are energetic for every token.
So:
35B-A3B
means roughly:
35B whole parameters → 3B energetic parameters per token
The A refers back to the activated parameter depend.
For this reason an MoE mannequin can have a big whole parameter depend with out requiring the identical quantity of computation as a dense mannequin of the identical dimension.
For instance:
35B dense
→ 35B parameters energetic
35B-A3B MoE
→ 35B parameters obtainable
→ ~3B energetic for every token
The mannequin nonetheless has 35B parameters. A3B does not imply the mannequin is a 3B mannequin.
4. Base vs Instruct: How Was the Mannequin Tuned?
You may even see two variations of the identical mannequin labelled one thing like:
Qwen3.5-35B-A3B-Base
and
Qwen3.5-35B-A3B-Instruct
The distinction is how the mannequin was skilled after its preliminary pretraining.
A base mannequin is the uncooked pretrained model. It has discovered patterns from its coaching information, however it hasn’t been particularly tuned to behave like a useful assistant that follows consumer directions.
An instruct mannequin has gone by extra coaching, generally known as instruction tuning or instruction fine-tuning, to make it higher at following instructions, answering questions and finishing up duties in a conversational format.
So, broadly:
Base mannequin → learns to foretell and generate textual content
Instruct mannequin → additional tuned to comply with directions and work together with customers
This implies the 2 variations can have the identical structure, parameter depend and quantization, whereas behaving fairly in a different way.
For instance:
35B-A3B-Base-This autumn
and
35B-A3B-Instruct-This autumn
can each be 4-bit variations of the identical underlying mannequin, however the Instruct model is usually the one you’d need for a chatbot or common interactive use.
The essential factor to recollect is that Base vs Instruct has nothing to do with mannequin dimension or quantization.
It describes how the mannequin was skilled to behave.
5. FP16, BF16: How Exactly Are These Parameters Saved?
Now now we have established what number of parameters the mannequin incorporates.
The subsequent query is:
How a lot info is saved for every parameter?
That is the place you’ll see phrases corresponding to:
FP16 and BF16
Each use 16 bits per worth, however they signify these values in a different way.
FP16
BF16
Bits
16-bit
16-bit
Exponent bits
5
8
Fraction bits
10
7
Precision
Larger
Decrease
Numeric vary
Smaller
A lot bigger
Frequent use
Inference/coaching
Coaching + trendy AI workloads
For instance, a mannequin with 35 billion parameters saved at 16 bits requires roughly:
35B × 16 bits ≈ 70 GB
only for its weights.
That’s far an excessive amount of for a lot of client machines. So folks compress the weights.
6. This autumn, Q5, Q6, Q8: Quantization
That is the place This autumn, Q5, Q6 and Q8 are available in.
These are completely different ranges of quantization.
As an alternative of storing mannequin weights utilizing 16 bits, quantization shops them utilizing fewer bits.
You’ll generally see:
Q8 → roughly 8-bit Q6 → roughly 6-bit Q5 → roughly 5-bit This autumn → roughly 4-bit Q3 → roughly 3-bit
The decrease the quantity, the smaller the mannequin usually turns into.
That may make an infinite distinction.
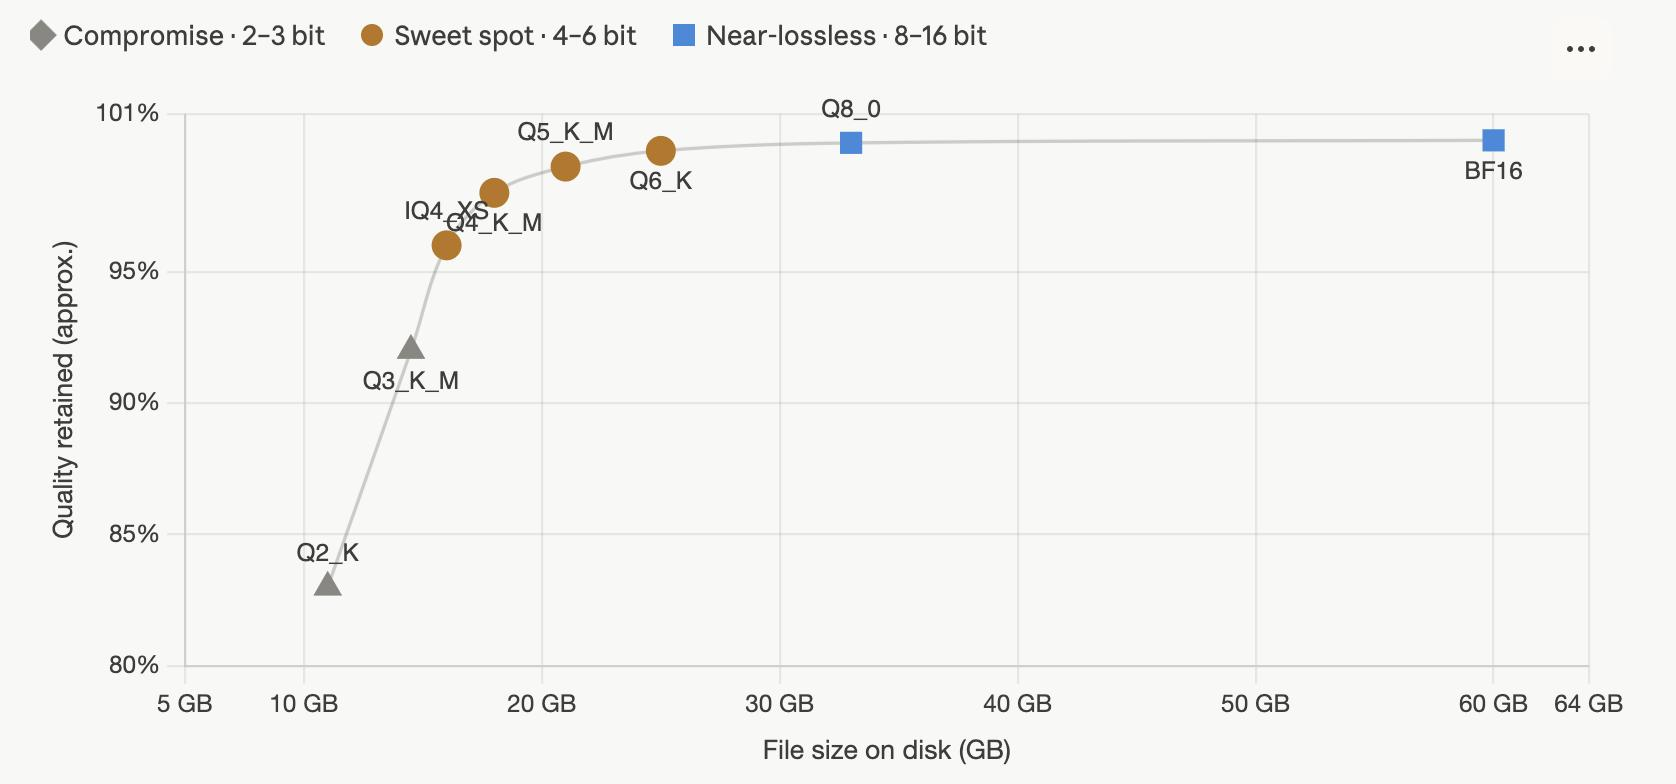
A 35B mannequin at 16-bit precision is roughly:
70 GB
At roughly 4 bits per weight, the identical mannequin is nearer to:
18 GB
The precise dimension varies as a result of actual quantization schemes have extra metadata and don’t all the time use precisely the nominal variety of bits for each worth.
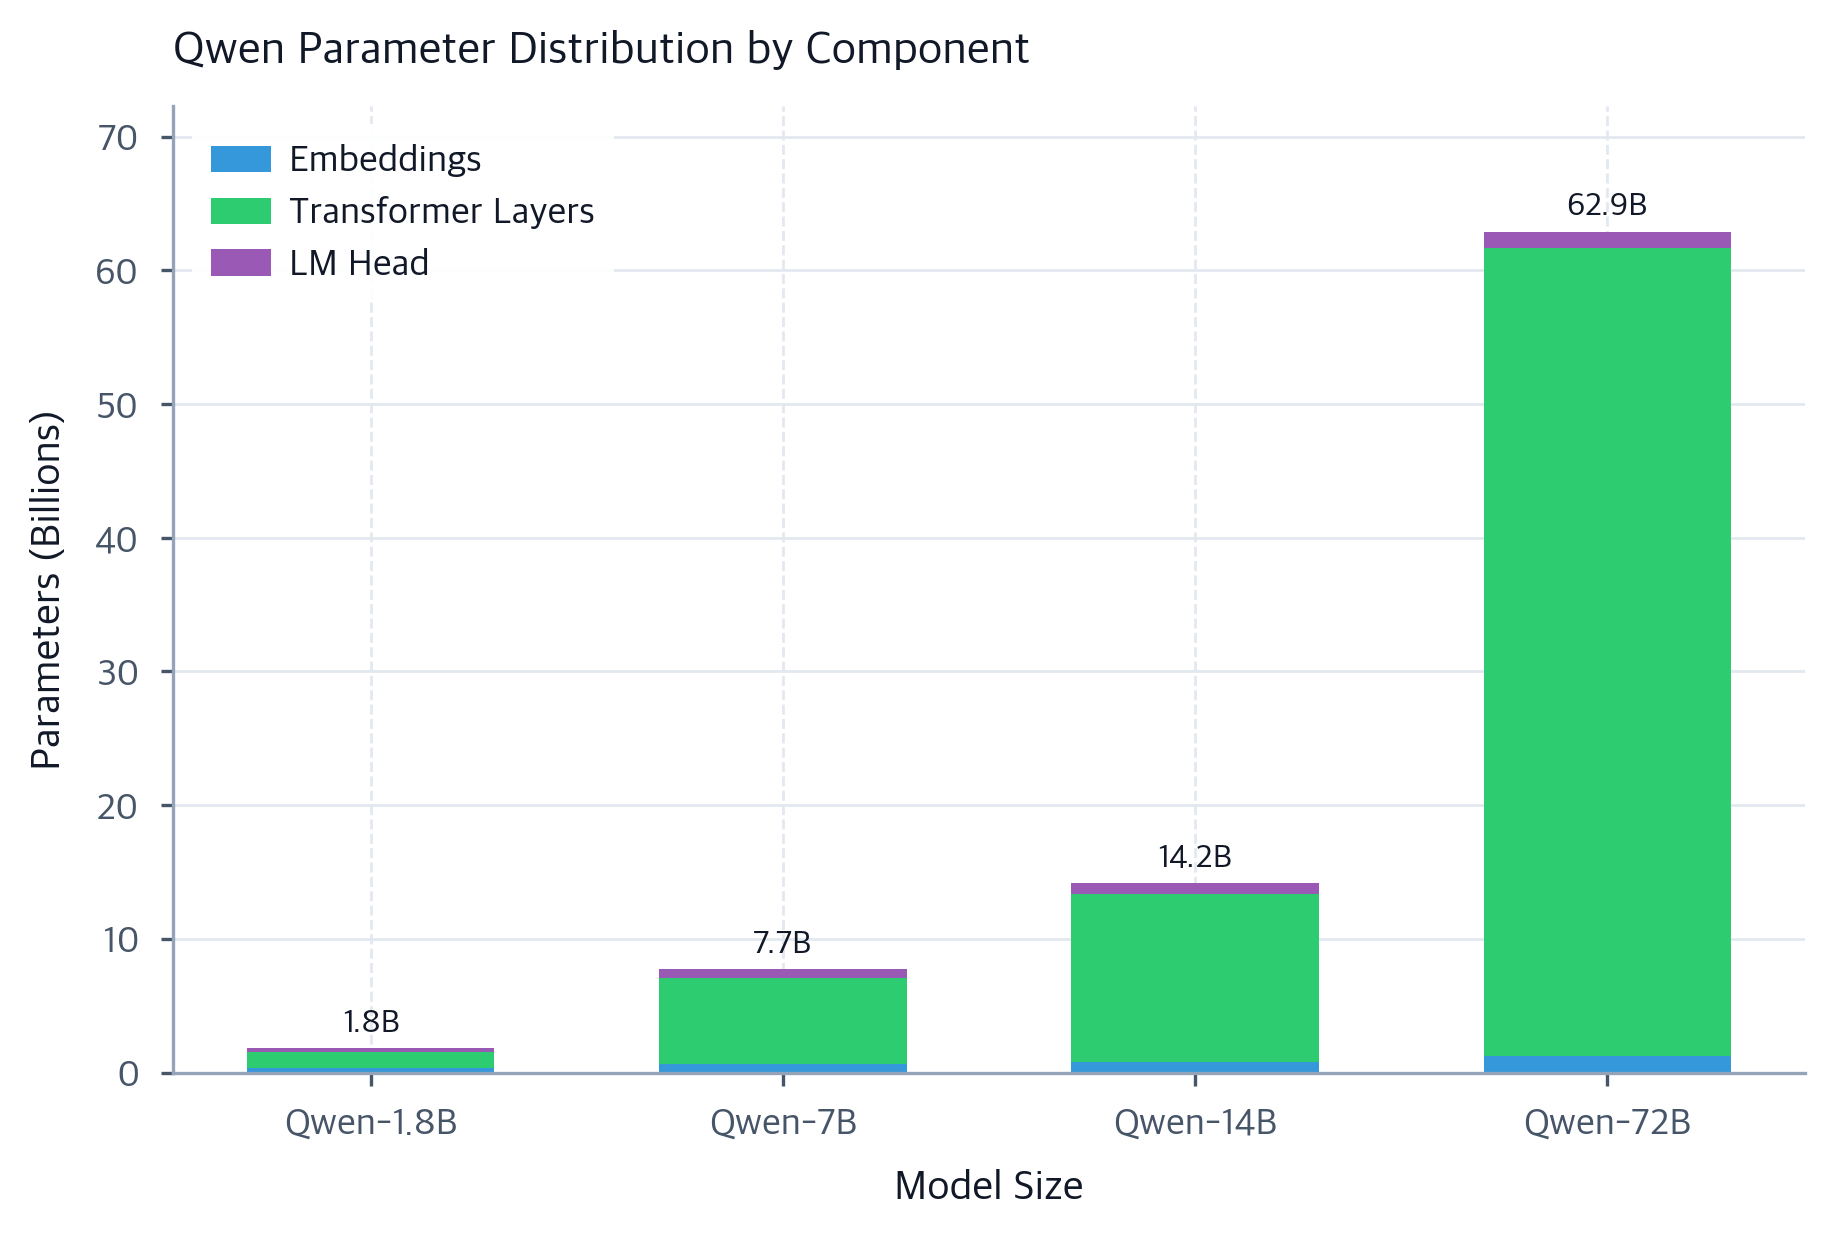
However the precept is straightforward:
Decrease-bit quantization reduces reminiscence necessities, often at the price of some mannequin high quality.
It’s possible you’ll now encounter one thing like:
Q4_K_M
You already know what This autumn means: it’s a 4-bit-class quantization.
However what are Ok and M?
They establish the particular quantization scheme.
Trendy quantization strategies don’t essentially retailer each weight in precisely the identical manner. They’ll use completely different groupings, scales and precisions to attain a greater stability between mannequin dimension and high quality.
That’s the reason you’ll encounter names corresponding to:
Q4_K_M
q2ks (Similar factor simply with underscores eliminated)
Q6_K_s
Q8_0
You don’t must memorize the implementation particulars of each variant.
For many customers, the helpful info is:
Q4_K_M = a generally used 4-bit-class quantization designed to stability dimension and high quality.
So when evaluating two variations of the identical mannequin, Q4_K_M and Q6_K, you’re primarily evaluating completely different quantization ranges and schemes.
8. GGUF: What Is the File?
Lastly, you may even see:
GGUF
That is completely different from all the things we’ve mentioned to this point.
GGUF is a mannequin file format.
It tells the software program how the mannequin is packaged and saved.
Which means a filename like:
Qwen3-30B-A3B-Instruct-2507-q2ks-mixed-AutoRound-gguf
Could be learn as:
Qwen3 → which model30B → what number of parameters existA3B → what number of are energetic per tokenInstruct → the way it was tuned2507 → model/date identifiergguf → container/file formatq2ks → quantization formatmixed → not each layer will get the identical bit widthAutoRound → quantization algorithm
That’s your complete “alphabet soup.”
Placing It All Collectively
Now take the scary-looking filename once more:
Qwen3.5-35B-A3B-Q4_K_M-GGUF
Learn it from left to proper. It’s principally a spec sheet compressed into one line.
The Cheat Sheet
Time period
What it means
7B / 35B / 70B
Whole variety of parameters
MoE
Combination-of-Consultants structure
A3B
Approximate energetic parameters per token
FP16
16-bit floating-point illustration
BF16
16-bit bfloat illustration
This autumn / Q5 / Q6 / Q8
Quantization degree
Q4_K_M
Particular quantization scheme
it / be
Instruction-tuned mannequin or base mannequin
GGUF
Mannequin file format
Continuously Requested Questions
A. They point out the mannequin’s whole variety of parameters, with B representing billions.
A. A3B signifies the approximate variety of parameters energetic for every token throughout inference.
A. Q4_K_M is a 4-bit-class quantization scheme designed to stability mannequin dimension and high quality.

Finding out, evaluating, and explaining AI programs for over 6 years.
“𝘖𝘯𝘤𝘦 𝘮𝘦𝘯 𝘵𝘶𝘳𝘯𝘦𝘥 𝘵𝘩𝘦𝘪𝘳 𝘵𝘩𝘪𝘯𝘬𝘪𝘯𝘨 𝘰𝘷𝘦𝘳 𝘵𝘰 𝘮𝘢𝘤𝘩𝘪𝘯𝘦𝘴 𝘪𝘯 𝘵𝘩𝘦 𝘩𝘰𝘱𝘦 𝘵𝘩𝘢𝘵 𝘵𝘩𝘪𝘴 𝘸𝘰𝘶𝘭𝘥 𝘴𝘦𝘵 𝘵𝘩𝘦𝘮 𝘧𝘳𝘦𝘦. 𝘉𝘶𝘵 𝘵𝘩𝘢𝘵 𝘰𝘯𝘭𝘺 𝘱𝘦𝘳𝘮𝘪𝘵𝘵𝘦𝘥 𝘰𝘵𝘩𝘦𝘳 𝘮𝘦𝘯 𝘸𝘪𝘵𝘩 𝘮𝘢𝘤𝘩𝘪𝘯𝘦𝘴 𝘵𝘰 𝘦𝘯𝘴𝘭𝘢𝘷𝘦 𝘵𝘩𝘦𝘮.” — 𝖥𝗋𝖺𝗇𝗄 𝖧𝖾𝗋𝖻𝖾𝗋𝗍, 𝖣𝗎𝗇𝖾
Login to proceed studying and luxuriate in expert-curated content material.
Preserve Studying for Free