On August 17, GitHub skilled an outage that lasted 7 hours and 47 minutes. It disrupted github.com, authentication, GitHub Actions, APIs, pull requests, points, and Copilot, affecting builders and organizations all over the world. For those who have been attempting to ship software program that day, we allow you to down.
This was our second important incident in August, following an actions failure on August 6. In March and April, I shared the work underway to enhance GitHub’s reliability. We have now made progress, however these incidents clarify that we should speed up this work.
What occurred
Our investigation discovered that the outage started when site visitors reached a brand new peak, and a vital infrastructure element in our Central US information middle did not scale with it. The ensuing capability strain unfold by our programs, inflicting authentication failures and disrupting a number of GitHub providers.
Restoration required a number of coordinated actions. Groups rerouted site visitors, remoted affected infrastructure, and restored providers in levels. Most GitHub providers recovered earlier that day, however some Copilot providers took longer. Errors in these providers triggered a client-side retry loop that elevated site visitors throughout restoration. We needed to mitigate that habits earlier than we may safely restore site visitors. The total root trigger evaluation features a detailed technical timeline.
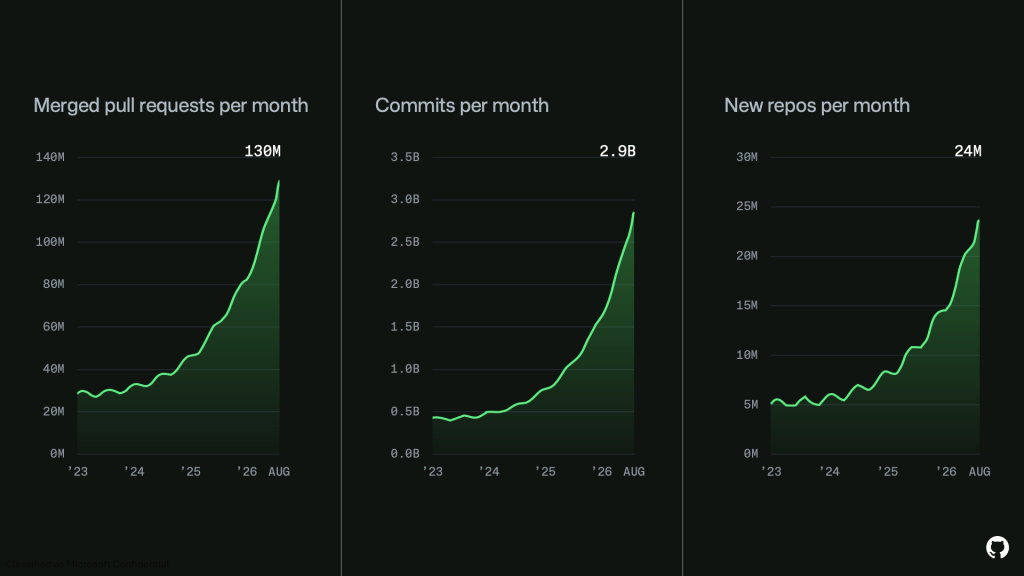
Neither outage was brought on by a code or configuration change. Each incidents have been capability failures at their core. We did not scale vital elements earlier than demand exceeded their capability. Since April, month-to-month commits have grown from 1.4 billion to 2.9 billion. That progress explains the strain on our programs, however it doesn’t excuse these outages.
What we now have executed and what comes subsequent
As a part of the reliability commitments we made earlier this 12 months, we now have centered on three priorities: including capability, enhancing effectivity, and eradicating architectural bottlenecks. We have now since added greater than 3 million CPU cores, 120 petabytes of high-speed storage, and important community capability. We put in as a lot {hardware} as accessible energy allowed in our present information facilities whereas accelerating our migration to Azure.
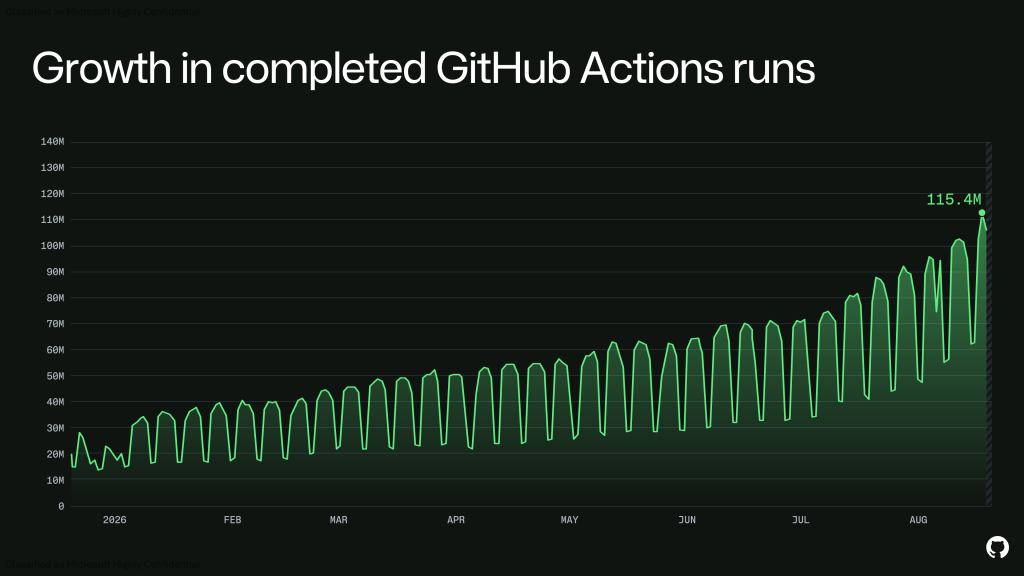
At this time, Azure serves roughly 58% of GitHub’s platform load and half of all Git operations, up from 12% of platform load in Might. This expanded footprint has additionally supported the expansion in GitHub Actions job runs proven under.
Azure’s infrastructure and capability have additionally accelerated our work to scale the most important monorepos. Our subsequent milestone is an structure that scales learn capability linearly with the variety of readers, enabling limitless learn operations. We’ll roll it out steadily, starting with the most important monorepos.

Scale just isn’t our solely problem. Because the tempo and complexity of change elevated, our present operational practices didn’t sustain. We have now redirected groups and assets towards availability and invested in stronger testing, safer rollouts, higher observability, and more practical alerting. We have now made progress, however this work just isn’t full.
As well as, we’re additionally isolating vital programs and eradicating shared dependencies between them. This work is designed to cut back the probability of an outage and restrict its impression when one happens.
We be taught from each outage and add new work to our availability workstream. The August 6 and August 17 incidents led to 2 quick modifications. First, we’re making use of constant retry limits, retry budgets, and variable timeouts throughout service-to-service interactions to stop retry storms and cascading load. Second, we’re reviewing lower-priority CPU and reminiscence alerts to determine elements that might fail throughout sudden site visitors spikes.
Our dedication to excessive availability isn’t only a technical promise. The developer group is determined by GitHub to construct, ship, and function their work. That’s solely doable if you happen to can depend on us, and on August 17, you couldn’t. It’s our duty to repair that. We’ll earn your belief by the scaling and reliability of the platform.
Written by