This publish is co-written with Chris Dickens from OpenAI.
Amazon Bedrock now gives OpenAI GPT-5.6 fashions on Amazon Bedrock in additional than 25 AWS Areas, with cross-Area inference. Three GPT-5.6 variants assist cross-Area inference, Sol, Terra, and Luna, every tuned for a unique steadiness of functionality and value.
Cross-Area inference (CRIS) in Amazon Bedrock works via inference profiles, which outline a mannequin and the AWS Areas to which Amazon Bedrock can route a request. You name the profile from a supply Area, and Amazon Bedrock routes the request to a vacation spot Area utilizing compute in that Area. CRIS is primarily a capability mechanism. By permitting requests to attract on a broader pool of compute moderately than being sure to 1 Area’s accessible capability, it improves throughput and helps keep constant efficiency beneath load. A geographic inference profile routes requests inside a single geography, so you’ll be able to scale whereas maintaining knowledge processed inside that geography. For GPT-5.6, this launch introduces US geographic (US cross-Area inference) and world CRIS. A world inference profile routes throughout all supported AWS business Areas the place the mannequin is deployed, based mostly on real-time capability, supplying you with broad entry to Amazon Bedrock capability.
On this publish, we stroll via an outline of GPT-5.6 fashions on Amazon Bedrock, how geographic and world cross-Area inference work for these fashions, and name them from the Amazon Bedrock console and in code with the OpenAI Responses API, the OpenAI Chat Completions API, and the Amazon Bedrock Converse API.
GPT-5.6 on Amazon Bedrock
The GPT-5.6 household on Amazon Bedrock consists of general-purpose and specialised cyber safety variants. This publish covers the three general-purpose variants that assist cross-Area inference, Sol, Terra, and Luna. All three settle for textual content and picture inputs and return textual content, have a 1 million token context window, and assist reasoning mode, server-side software calling, and immediate caching. You’ll be able to name them with the OpenAI Responses API, the OpenAI Chat Completions API, and the Amazon Bedrock Converse API. Streaming is supported via the Responses and Chat Completions API (stream=True), and ConverseStream.
Amazon Bedrock inference profiles are logical identifiers you cross as an alternative of a uncooked mannequin ID.
A geographic inference profile (prefixed with a geography code equivalent to us., for instance us.openai.gpt-5.6-terra) retains inference processing inside the Areas of its predefined geography. Requests enter via your supply Area and might solely be routed to vacation spot Areas inside that geography, so workloads with knowledge residency necessities can scale throughout Areas whereas staying inside the boundary.
A International inference profile (prefixed world. equivalent to world.openai.gpt-5.6-terra) can route a request to any supported business AWS Area the place the mannequin is deployed, based mostly on real-time capability. It gives the widest capability pool and is the fitting alternative when your workload has no geographic processing necessities.
Billing and quota consumption are tracked towards your account no matter which backend Area dealt with the request, so a single spending and throughput image nonetheless applies. Knowledge processed via world CRIS could cross the Areas in that mannequin’s eligible set. In case your workload has knowledge residency necessities that prohibit processing to particular geographies, use the geographic profile for that geography (equivalent to us.openai.gpt-5.6-terra) or a direct name to 1 Area as an alternative of the worldwide profile. The Amazon Bedrock cross-Area inference documentation lists which Areas take part in every mannequin’s world and geographic profile units.
The next tables record the supply Areas the place you’ll be able to invoke the GPT-5.6 inference profiles and the vacation spot Areas the place your requests could be processed. The identical routing applies to all three variants: Sol, Terra, and Luna.
US cross-Area inference profile (us.openai.gpt-5.6-sol / -terra / -luna)
Supply Area
Vacation spot Areas
US East (N. Virginia) us-east-1
US East (N. Virginia) us-east-1, US West (Oregon) us-west-2, US East (Ohio) us-east-2
US West (Oregon) us-west-2
US East (N. Virginia) us-east-1, US West (Oregon) us-west-2, US East (Ohio) us-east-2
US East (Ohio) us-east-2
US East (N. Virginia) us-east-1, US West (Oregon) us-west-2, US East (Ohio) us-east-2
US West (N. California) us-west-1
US East (N. Virginia) us-east-1, US West (Oregon) us-west-2, US East (Ohio) us-east-2, US West (N. California) us-west-1
Canada (Central) ca-central-1
US East (N. Virginia) us-east-1, US West (Oregon) us-west-2, US East (Ohio) us-east-2, Canada (Central) ca-central-1
Canada West (Calgary) ca-west-1
US East (N. Virginia) us-east-1, US West (Oregon) us-west-2, US East (Ohio) us-east-2, Canada West (Calgary) ca-west-1
International cross-Area inference profile (world.openai.gpt-5.6-sol / -terra / -luna)
Supply Areas
Vacation spot Areas
United States: US East (N. Virginia) us-east-1, US East (Ohio) us-east-2, US West (Oregon) us-west-2, US West (N. California) us-west-1
Canada: Canada (Central) ca-central-1
Europe: Europe (Stockholm) eu-north-1, Europe (Paris) eu-west-3, Europe (Eire) eu-west-1, Europe (Frankfurt) eu-central-1, Europe (Spain) eu-south-2, Europe (Milan) eu-south-1, Europe (London) eu-west-2, Europe (Zurich) eu-central-2
Asia Pacific: Asia Pacific (Melbourne) ap-southeast-4, Asia Pacific (Sydney) ap-southeast-2, Asia Pacific (Tokyo) ap-northeast-1, Asia Pacific (Osaka) ap-northeast-3, Asia Pacific (Seoul) ap-northeast-2, Asia Pacific (Mumbai) ap-south-1, Asia Pacific (Hyderabad) ap-south-2, Asia Pacific (Singapore) ap-southeast-1, Asia Pacific (Jakarta) ap-southeast-3, Asia Pacific (Thailand) ap-southeast-7, Asia Pacific (Malaysia) ap-southeast-5, Asia Pacific (Taipei) ap-east-2
Center East: Center East (UAE) me-central-1, Israel (Tel Aviv) il-central-1
South America: South America (São Paulo) sa-east-1
Routes to supported AWS business Areas globally
Attempt GPT-5.6 within the Amazon Bedrock console
The quickest approach to attempt GPT-5.6 is the textual content playground within the Amazon Bedrock console, which requires no coding or SDK setup. You’ll be able to ship prompts, modify inference parameters, and change between variants to get a really feel for every mannequin earlier than you combine the API. The mannequin selector lists each the geographic and world cross-Area inference profiles, so you’ll be able to check both cross-Area inference choice earlier than writing code. Within the previous screenshot, the supply Area is US East (N. Virginia). The US entry within the mannequin selector is the geographic inference profile, and the International entry is the worldwide inference profile.
Open the Amazon Bedrock console in a Area the place the fashions can be found, equivalent to US East (N. Virginia).
Within the navigation pane, beneath Check, select Playground.
Select Choose mannequin in the course of the web page.
Seek for OpenAI GPT-5.6 Sol, choose both US OpenAI GPT-5.6 Sol or International OpenAI GPT-5.6 Sol, and select Apply.
Enter a immediate and select Run to generate a response.
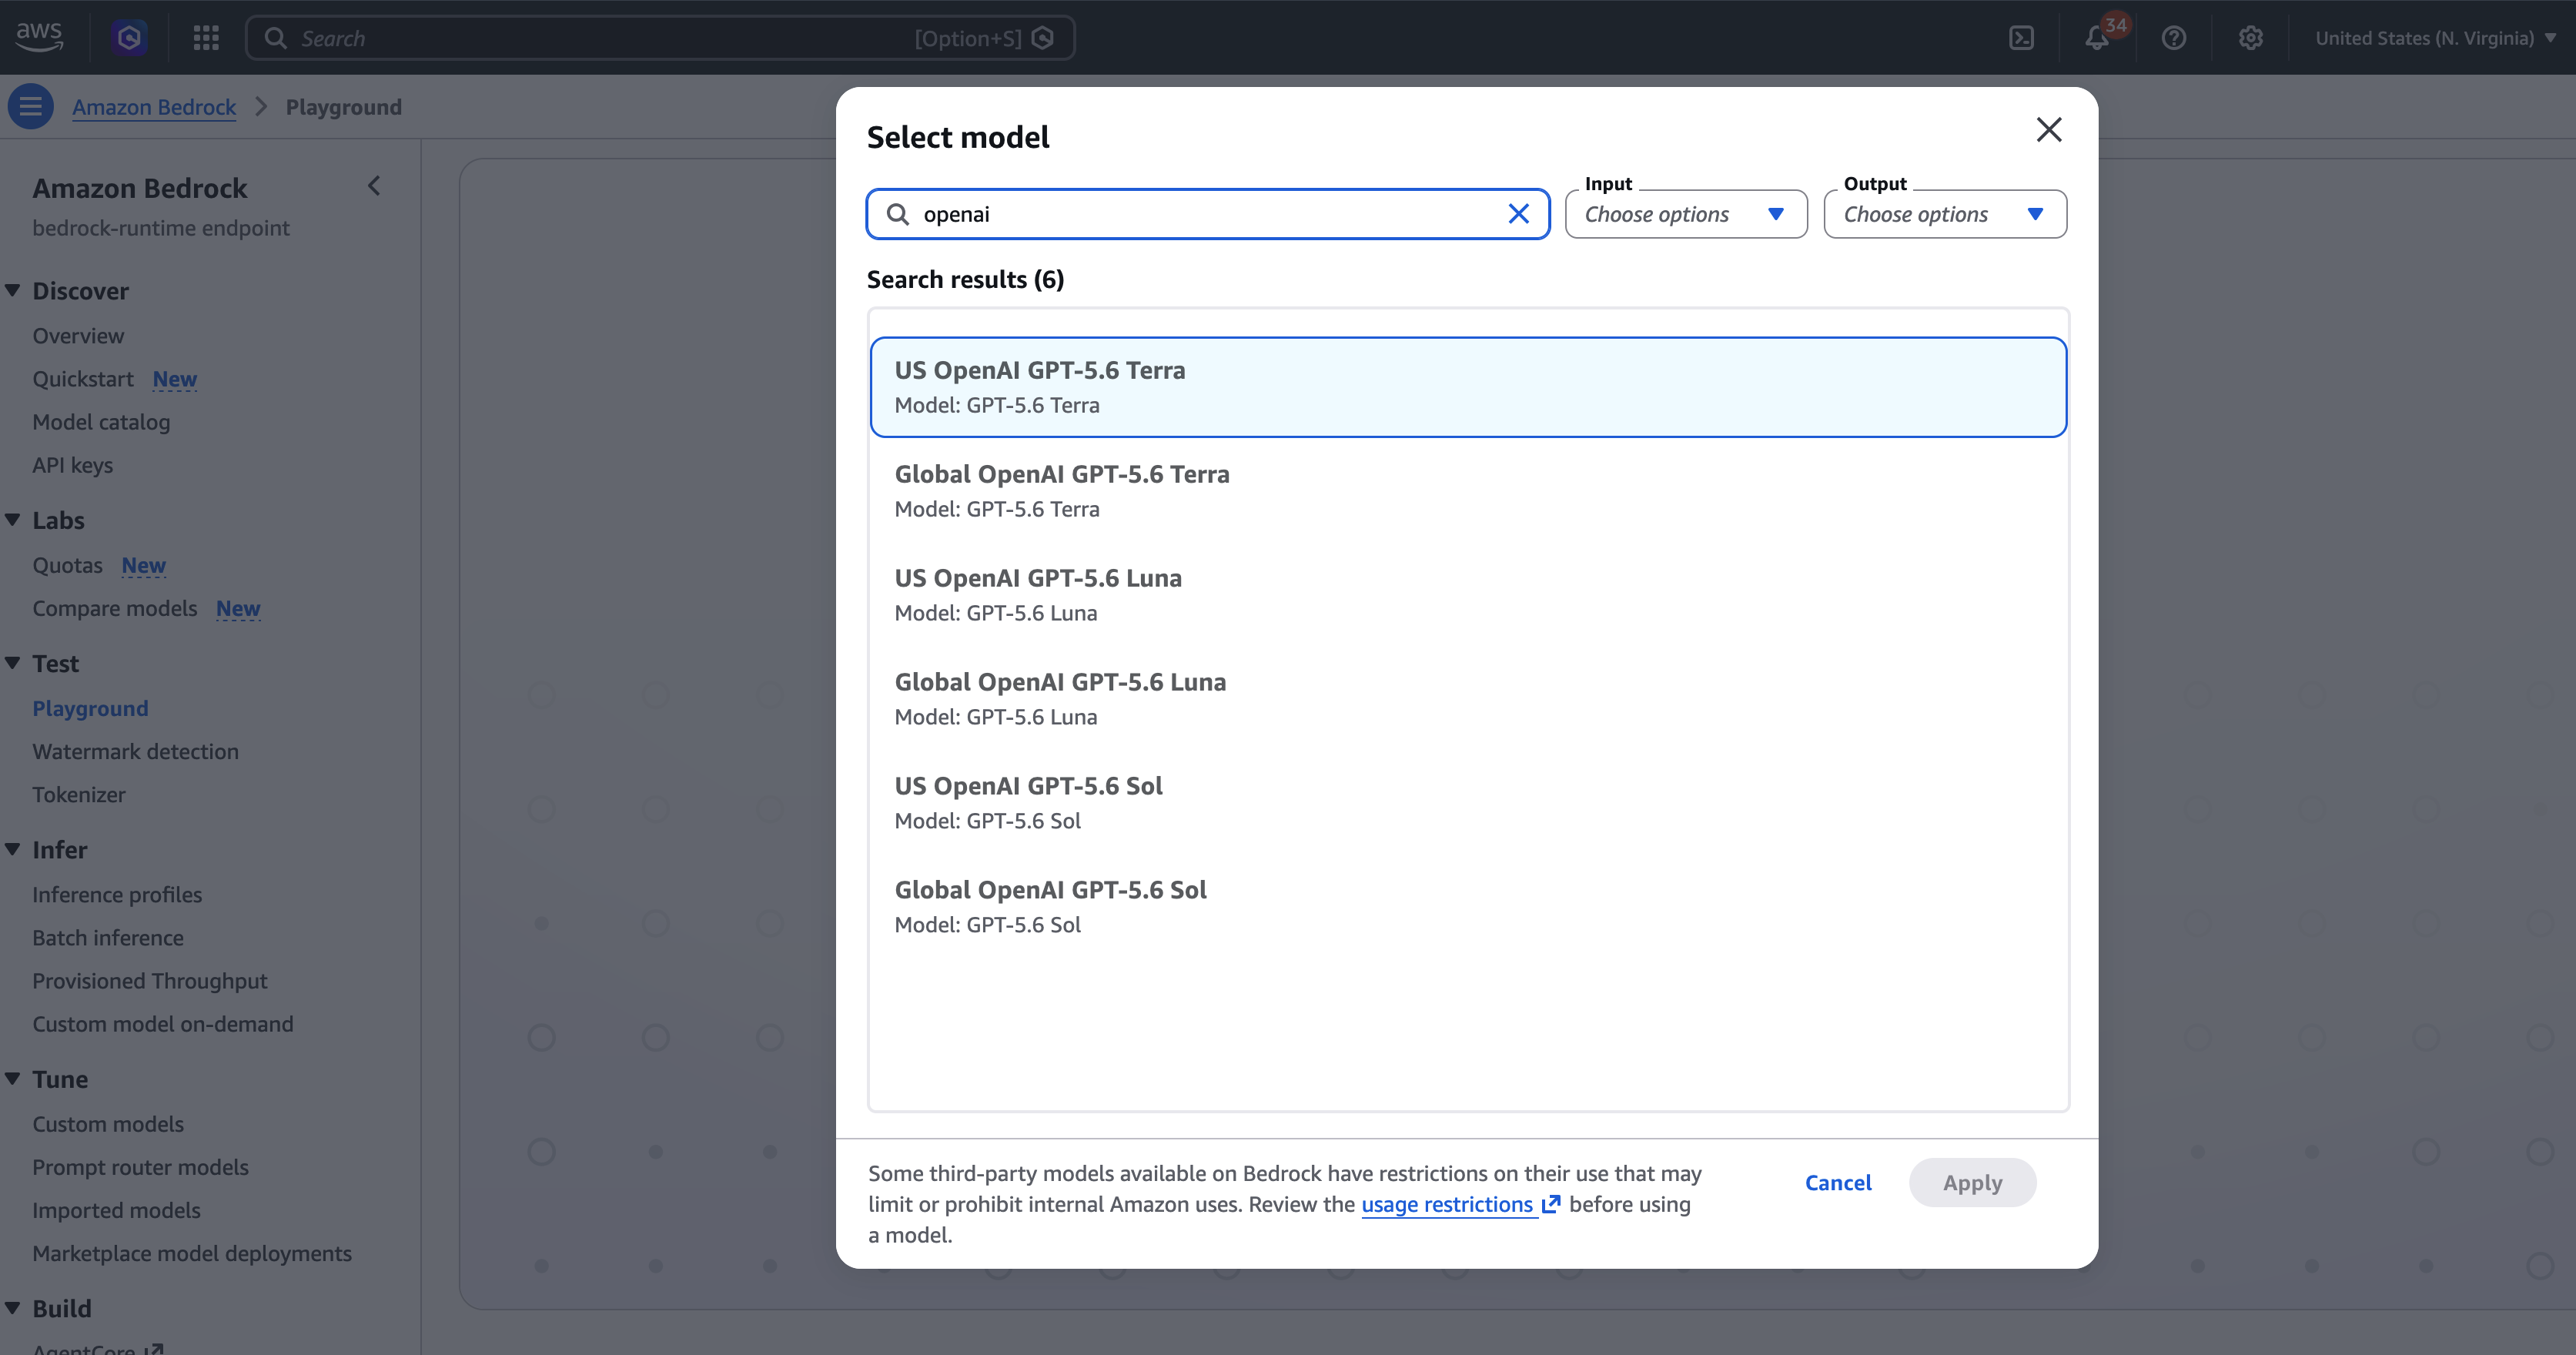
Determine 1: Deciding on a US or International GPT-5.6 inference profile within the Amazon Bedrock console mannequin selector
Getting began with the API
GPT-5.6 speaks the OpenAI Responses API codecs natively on Amazon Bedrock. In case your utility already calls OpenAI fashions, you’ll be able to level your current OpenAI SDK consumer on the Amazon Bedrock OpenAI-compatible endpoint. Then swap within the inference profile ID (world or geographic) because the mannequin parameter. For authentication, Amazon Bedrock accepts both customary AWS credentials or an Amazon Bedrock API key. The API key path is probably the most direct match for the OpenAI SDK, which passes it because the bearer token. For manufacturing, generate short-term API keys programmatically utilizing the aws-bedrock-token-generator package deal, which derives a bearer token out of your current AWS credentials (long-term keys are advisable just for exploration).
For the complete record of supported parameters, see the OpenAI GPT mannequin parameters web page within the Amazon Bedrock Person Information. The identical consumer additionally works with the Chat Completions API, helpful in case your utility already makes use of this format.
Should you’re calling Amazon Bedrock straight moderately than via the OpenAI SDK, use the Amazon Bedrock Converse API, which supplies you a similar request form you already use for different fashions on Bedrock:
For streaming responses, name converse_stream with the identical arguments and iterate over the occasion stream:
Safety and compliance
Cross-Area inference makes use of the identical Amazon Bedrock safety mannequin as direct in-Area calls. Requests are authenticated along with your AWS Identification and Entry Administration (IAM) credentials, and IAM insurance policies management which inference profiles a job can invoke. Amazon Bedrock makes use of a zero-operator entry (ZOA) safety mannequin enforced on the chip, so no AWS operators can entry your prompts or completions. Each mannequin name runs beneath your IAM insurance policies, could be reached privately out of your digital personal cloud (VPC) via a VPC endpoint, and is logged on AWS CloudTrail. Knowledge perimeter insurance policies assist stop exfiltration throughout account and community boundaries.
For sure fashions, together with GPT-5.6, content material flagged by the Amazon Bedrock automated abuse-detection classifiers is retained for as much as 30 days for offline abuse detection. To see which fashions this is applicable to and the way it works, see Abuse detection within the Amazon Bedrock Person Information. To know extra about knowledge retention configuration on Bedrock, see the Amazon Bedrock knowledge retention documentation. For the authoritative record of Areas in every profile’s routing set, see the Amazon Bedrock cross-Area inference assist web page.
Cross-Area inference requests seem on AWS CloudTrail in your supply Area, and the additionalEventData.inferenceRegion area data which Area processed every request. Should you allow mannequin invocation logging, the request and response payloads are delivered to Amazon Easy Storage Service (Amazon S3) or Amazon CloudWatch Logs in the identical account and Area.
Establishing IAM permissions for cross-Area inference
To let a job invoke GPT-5.6 via an inference profile, grant it entry to the inference profile and to the inspiration mannequin in each Area the profile can path to. You should utilize this managed coverage AmazonBedrockLimitedAccess or create your individual.
For a geographic inference profile, the coverage has three statements. The primary grants entry to the geographic inference profile and the default venture in your supply Area. The second grants entry to the inspiration mannequin in your supply Area and in each vacation spot Area within the geography, with a situation that limits this entry to requests made via that profile. The third grants the bearer-token authentication the OpenAI-compatible APIs use.
A world inference profile makes use of a four-part coverage. The primary grants entry to the worldwide inference profile and the default venture in your supply Area. The second grants entry to the inspiration mannequin in your supply Area. The third grants entry to the inspiration mannequin via the Area-agnostic world ARN, which is what allows cross-Area routing. The fourth grants the bearer-token authentication utilized by the OpenAI-compatible APIs.
These insurance policies grant bedrock:CallWithBearerToken and bedrock:InvokeModel on the venture/default useful resource, which the OpenAI Responses and Chat Completions APIs use to authenticate with an Amazon Bedrock API key and run inference. Should you use the streaming Converse API (ConverseStream), add bedrock:InvokeModelWithResponseStream to the inference-profile and foundation-model statements.
The statements work collectively, so eradicating one denies that profile’s cross-Area entry for the function, which additionally offers you a clear approach to flip both functionality off for particular roles. Alternatively, you’ll be able to connect an express deny that targets world. or us. inference profiles.
Service management coverage consideration for world cross-Area inference
In case your group makes use of Area-restrictive service management insurance policies (SCPs), International CRIS requests set aws:RequestedRegion to unspecified moderately than a selected Area identify. Geographic CRIS requests are evaluated towards each vacation spot Area within the profile. The advisable strategy is to exempt cross-Area inference with the bedrock:InferenceProfileArn situation moderately than widening your Area allowlist. Amazon Bedrock units that situation key when it authorizes the inspiration mannequin, so you’ll be able to permit CRIS routing whereas maintaining your allowlist tight for each different service. Your supply Area nonetheless needs to be within the allowlist. Should you choose to not use the situation, you’ll be able to as an alternative add the vacation spot Areas and unspecified to your allowlist, however that opens these Areas to each service, not solely Amazon Bedrock. For a ready-to-use SCP and step-by-step steering, see the Bedrock CRIS Area-control SCP pattern.
The next SCP denies Amazon Bedrock inference exterior your authorised Areas (Sydney and N. Virginia are proven) and exempts the us. and world. inference profiles that GPT-5.6 makes use of. The primary assertion retains the Area allowlist enforced for each different service, so embrace the worldwide companies your group makes use of in its NotAction record.
Mannequin entry should be enabled for the account and Area for each profile sorts. For the complete guidelines, see Stipulations for inference profiles.
Working with immediate caching
All three GPT-5.6 variants assist immediate caching on the bedrock-runtime endpoint. When your requests share a protracted immediate prefix, equivalent to a system immediate or a set of few-shot examples, Amazon Bedrock caches that prefix. Later requests reuse the cached prefix as an alternative of reprocessing it. This lowers enter value and latency for the cached portion.
GPT-5.6 helps two caching modes on Amazon Bedrock. Implicit caching is the default: the service locations a cache breakpoint on the newest consumer or software message, which fits conversations that develop by appending messages. In case your requests share a steady prefix adopted by content material that modifications on each request, you’ll be able to mark the tip of the steady content material with an express cache breakpoint as an alternative. In each modes, cross the non-obligatory prompt_cache_key parameter so requests with the identical prefix are routed to the identical cache. Each modes work with geographic and world inference profiles. Every cache breakpoint wants a immediate prefix of not less than 1,024 tokens. For extra info, see Immediate caching for quicker mannequin inference.
Immediate caching additionally impacts quota utilization. Cache learn tokens are usually not counted towards your TPM quota, so requests that reuse a cached prefix devour much less of it. The subsequent part describes how quotas are calculated. The next instance makes use of express immediate caching with the consumer and model_id from the Getting began part:
To substantiate that caching is working, examine the utilization object of every response.
Quota administration
On-demand quotas for GPT-5.6 are managed as tokens per minute (TPM), and so they connect to the inference profile you name: a geographic profile and a worldwide profile for a similar mannequin carry separate quota allocations, so switching between them modifications the pool you draw from. To view your present allocations or request a rise, seek for the GPT-5.6 mannequin inference quotas within the AWS Service Quotas console from the Area your utility calls Amazon Bedrock in.
If you dimension a quota enhance request, account for the burndown fee: the speed at which enter and output tokens convert into token quota utilization for the throttling system. Enter tokens rely towards your quota at 1:1, whereas output tokens can devour quota at the next a number of. For GPT-5.6 fashions, the burndown fee is 10x for output tokens, which means one output token consumes 10 tokens out of your TPM quota, so output-heavy workloads deplete quota significantly quicker than uncooked token counts counsel. The per-request calculation is:
For instance, a request with 2,000 enter tokens and 1,000 output tokens depletes 12,000 tokens out of your quota. Cache learn tokens are usually not a part of this calculation, which is what makes immediate caching (earlier part) efficient for quota administration and value. For the present burndown charges by mannequin, see the Amazon Bedrock quotas web page. Three practices enable you keep away from surprises:
Request will increase earlier than deployment. Should you anticipate excessive utilization, request the rise via the Service Quotas console forward of your launch moderately than reacting to throttling in manufacturing.
Monitor utilization. Amazon CloudWatch publishes quota utilization metrics in actual time per inference profile, so you’ll be able to set alerts when utilization approaches thresholds and monitor historic patterns to plan future will increase.
Load check with lifelike visitors (together with peak patterns and production-size prompts) earlier than you commit a workload to manufacturing, and validate towards the profile kind you’ll really use, since geographic and world quotas are separate.
Monitoring and logging
As a result of GPT-5.6 requests run via the Bedrock Runtime API, requests made via a geographic or world inference profile seem in Amazon Bedrock mannequin invocation logging the identical means on-demand requests do, with the inference profile ARN recorded alongside the request and response payloads (topic to your logging configuration). You’ll be able to ship invocation logs to Amazon S3 or Amazon CloudWatch Logs. Whichever profile kind you employ, invocation logs and metrics are recorded in your supply Area, so your observability stays in a single place even when the request is processed elsewhere.
Amazon CloudWatch metrics masking invocation counts, token counts, latency, throttles, and errors are printed per inference profile. As a result of geographic and world profiles are distinct sources, their metrics are reported individually. Per-request latency will differ considerably with the vacation spot Area a request lands in, so in case your dashboards break metrics down by Area at this time, take into account including a view that aggregates by inference profile ID as an alternative, since that’s the ID your utility code and quota consumption are tied to. Utilization can also be itemized on AWS Value Explorer and the AWS Value and Utilization Report, so you’ll be able to attribute GPT-5.6 spend by mannequin and by profile the identical means you do for the remainder of your Bedrock workloads.
Conclusion
GPT-5.6 brings three OpenAI mannequin variants to Amazon Bedrock. With this launch you’ll be able to name every of them via two sorts of cross-Area inference profiles. You should utilize a geographic profile when inference processing wants to remain inside a geography (scaling throughout the Areas inside it), and a worldwide profile while you need the widest capability pool throughout supported business AWS Areas. Both means, your utility talks to 1 endpoint with one profile ID, logs, quotas and billing keep in your supply Area. The fashions converse the OpenAI Chat Completions API and Responses API, together with streaming, and the Amazon Bedrock Converse API.
To get began, open the Amazon Bedrock console and ship a check immediate to GPT-5.6 Sol, Terra, or Luna via an inference profile, or name the fashions programmatically via the Responses API. Overview the Amazon Bedrock pricing web page for present GPT-5.6 charges earlier than sizing a manufacturing workload. In case your utility wants long-context (1 million token) processing, examine the Amazon Bedrock mannequin assist by Area web page for Area availability.
In regards to the authors
Melanie Li
Melanie Li, PhD, is a Senior Generative AI Specialist Options Architect at AWS based mostly in Sydney, Australia, the place her focus is on working with clients to construct options utilizing state-of-the-art AI/ML instruments. She has been actively concerned in a number of generative AI initiatives throughout APJ, harnessing the ability of LLMs. Previous to becoming a member of AWS, Dr. Li held knowledge science roles within the monetary and retail industries.
Zohreh Norouzi
Zohreh is a Senior Safety Options Architect at Amazon Net Providers (AWS). She helps clients make good safety selections and speed up their journey to the AWS Cloud. She has been actively concerned in AI safety initiatives, utilizing her experience to assist clients construct safe AI options at scale.
Saurabh Trikande
Saurabh is a Senior Product Supervisor for Amazon Bedrock and Amazon SageMaker Inference. He’s keen about working with clients and companions, motivated by the aim of democratizing AI. He focuses on core challenges associated to deploying advanced AI purposes, inference with multi-tenant fashions, value optimizations, and making the deployment of generative AI fashions extra accessible. In his spare time, Saurabh enjoys climbing, studying about modern applied sciences, following TechCrunch, and spending time together with his household.
Chase Kernan
Chase is a Principal Engineer at AWS.
Chris Dickens
Chris is a Member of Product Employees at OpenAI centered on the OpenAI APIs. His work consists of collaboration with AWS on Amazon Bedrock to make OpenAI’s frontier fashions broadly accessible to builders.