


Claude now marks AI-generated content material. But it surely doesn’t mark the whole lot the identical manner.
Anthropic at the moment makes use of embedded watermarks for textual content and signed C2PA provenance metadata for supported information. Code sits someplace in between: it’s nonetheless textual content, however its construction provides the watermark fewer locations to work.
I went into element about Claude’s watermarks in my article how Claude’s watermarking works, and right here I’d reply the plain query:
How do you take away the watermark?
You’ll quickly discover out the watermark isn’t exhausting to take away in any respect.
Take away Claude Watermark from Textual content
That is the toughest case. At the very least on paper, as a result of:
Claude doesn’t add a hidden character that you would be able to seek for and delete.
Anthropic says its watermark relies on SynthID-Textual content. That is the textual content variant of the normal SynthID that’s utilized by Gemini fashions for watermarking.
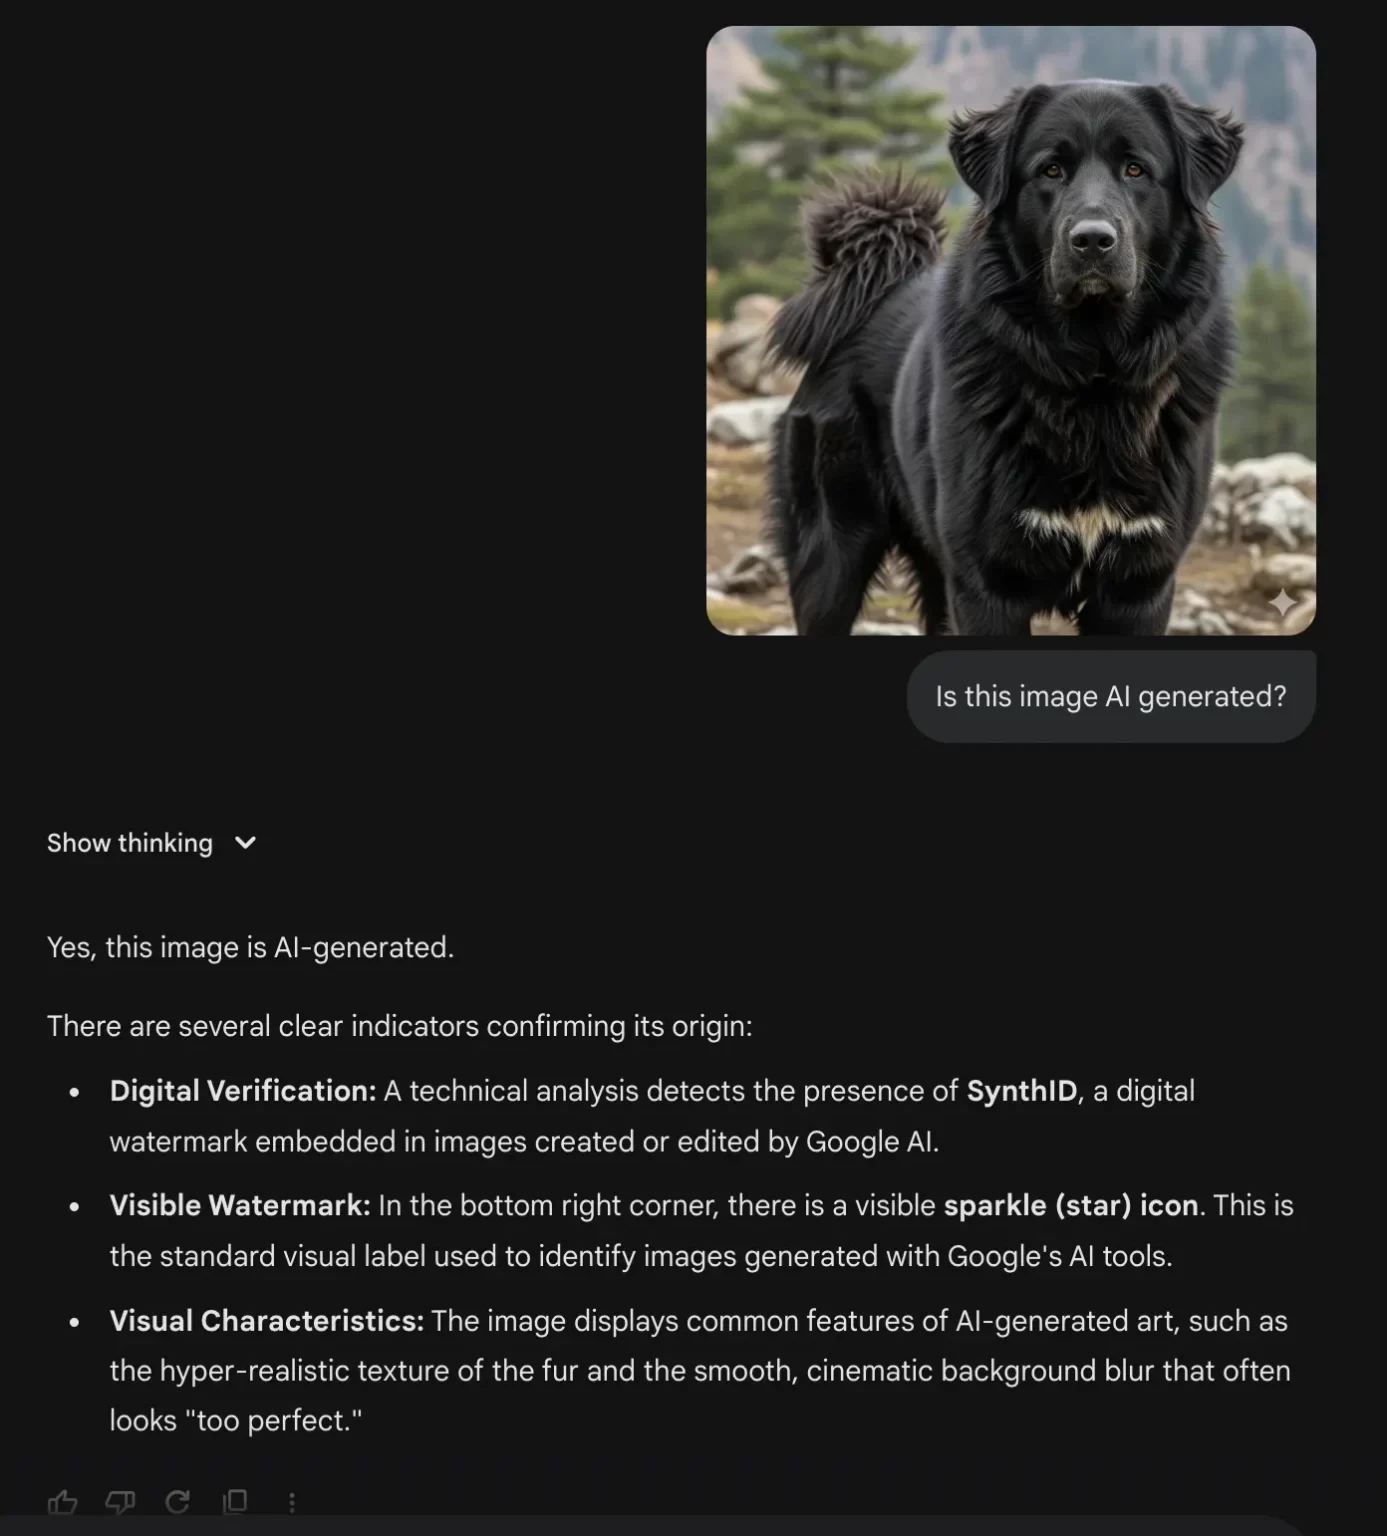
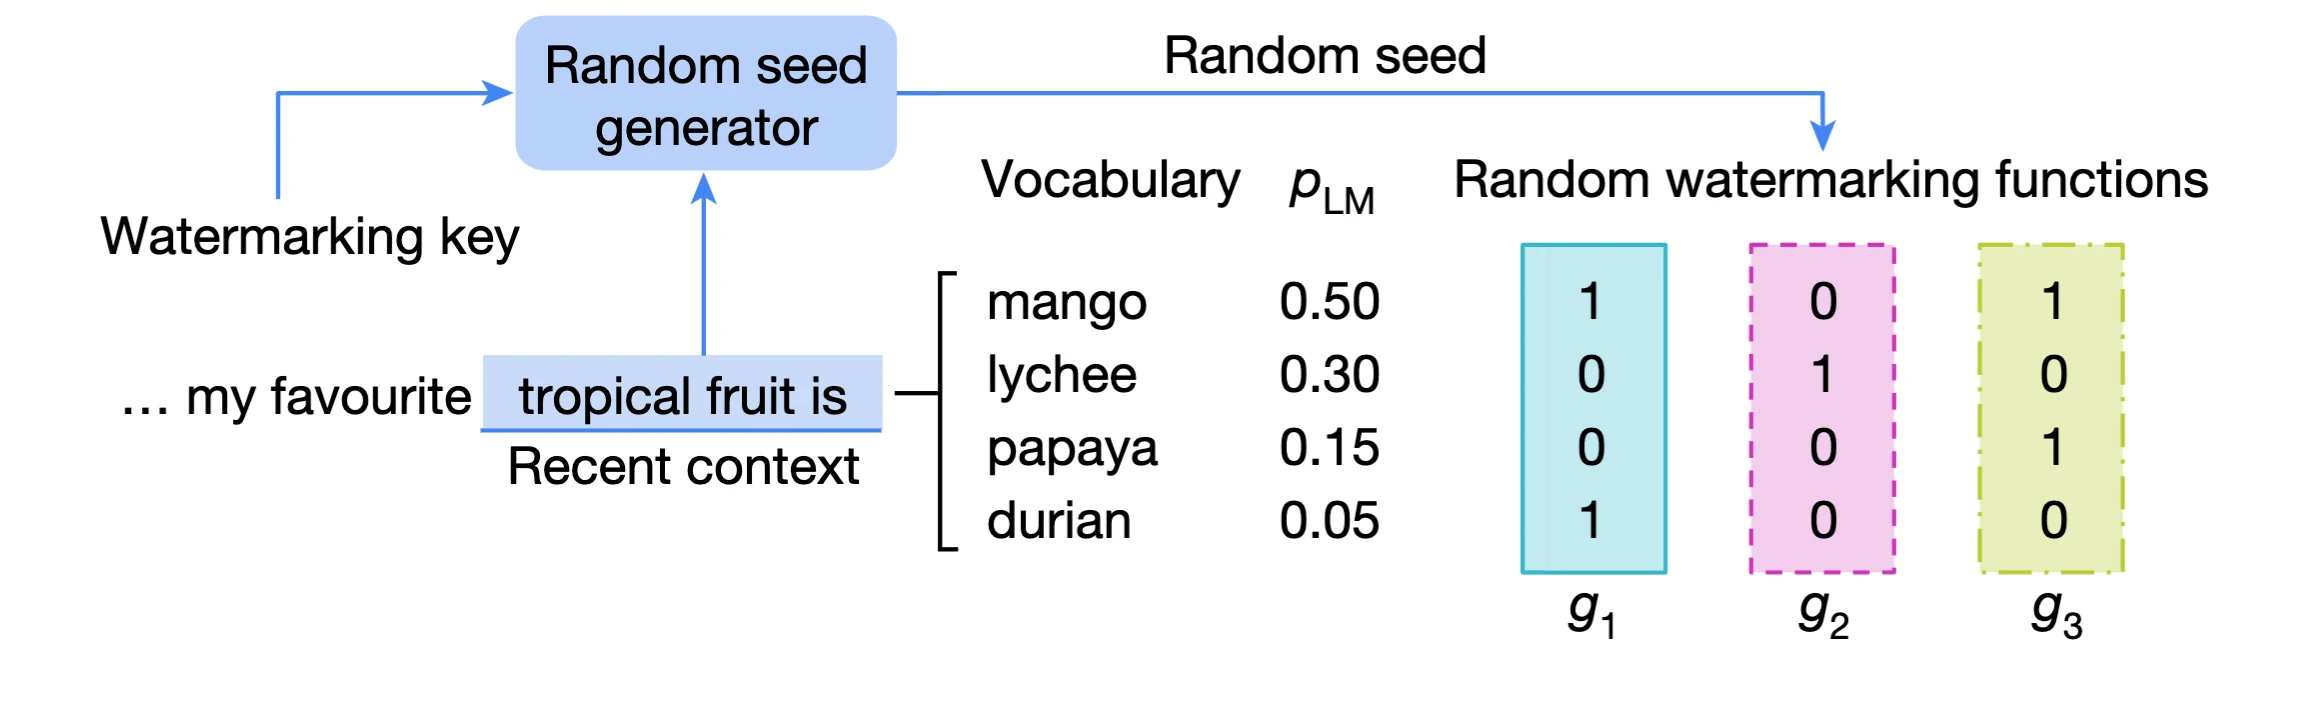
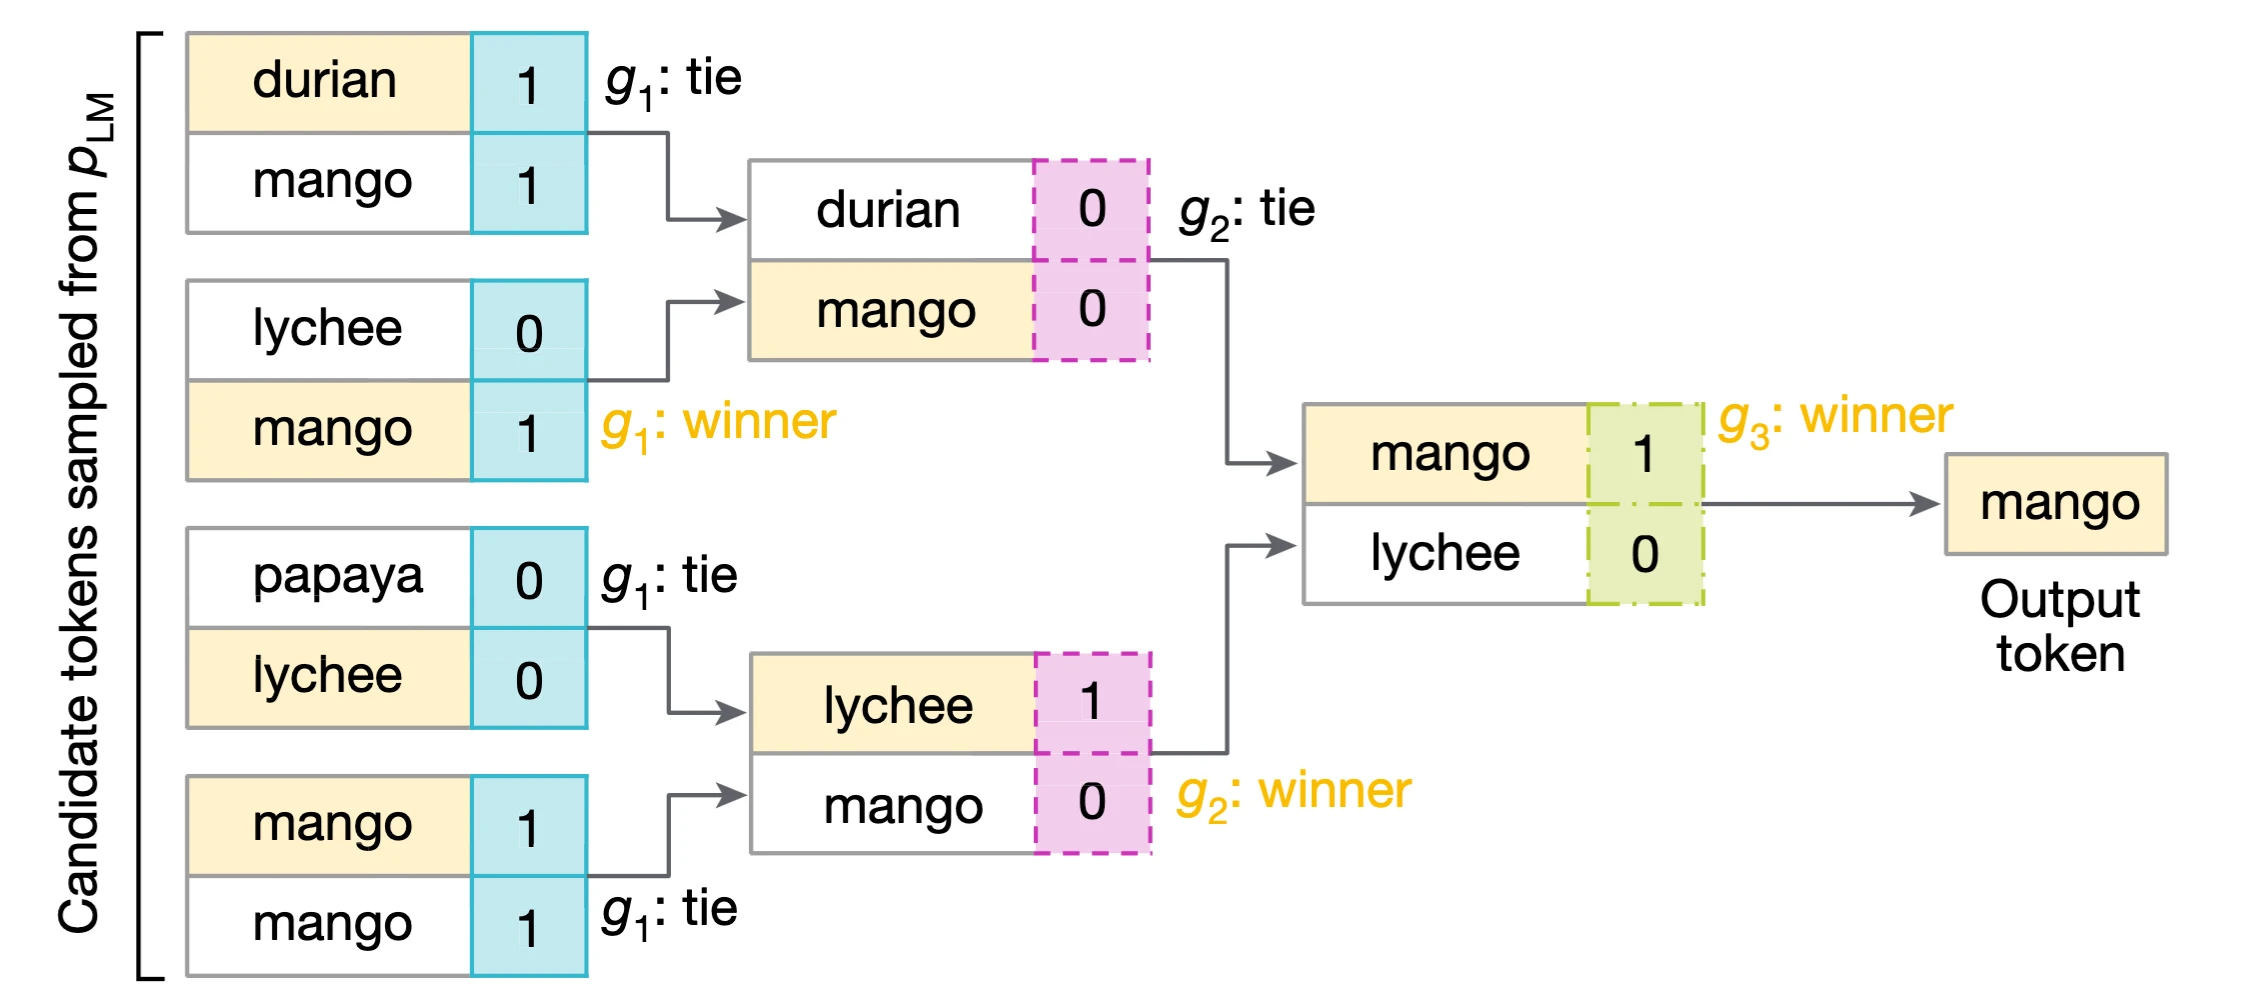
Moreover, the mannequin adjustments the supply of randomness it makes use of when selecting between attainable phrases. Throughout a sufficiently lengthy passage, these decisions create a statistical sample that may be detected later.
Click on right here to view the performance of SynthID-Textual content
For instance, take a look at these three sentences:
The compiler rejected the patch.
The patch was rejected by the compiler.
The compiler wouldn’t settle for the patch.
They’re primarily relaying the identical data, though in a unique method (wording clever). This minor change would barely be detected by a human, however machines can disguise patterns utilizing such seemingly secure decisions.
As well as, a mannequin has some freedom to decide on between them. Subsequently, that freedom is the place a textual content watermark is positioned. It’s all within the patterns…
Rewrite, don’t “strip”
Nonetheless, there isn’t a metadata-cleaning operation for Claude’s textual content watermark. For the reason that watermark is a sample that’s distributed throughout textual content:
Edits wouldn’t be enough
Copying the textual content to a different editor doesn’t clear up it
What does work then?
A considerable rewrite or paraphrase
Rewriting the textual content is the best selection for countering watermarks. However should you’re not concerned about an overhaul, paraphrasing would suffice. Equally, that is necessary as a result of there are numerous paraphrasing instruments freely obtainable on-line:
That provides us a easy rule:
Nonetheless, altering the file doesn’t take away a textual content watermark. Altering the textual content does.
Python method
For the reason that watermarking is in Claude’s writing, redoing the textual content in different LLMs (which don’t have SynthID-Textual content) would scale back the watermarks.
The next code makes use of a generic OpenAI-compatible endpoint. Utilizing a mannequin apart from Claude for the rewrite:
import os
from openai import OpenAI
def rewrite_text(textual content: str) -> str:
shopper = OpenAI(api_key=os.environ[“OPENAI_API_KEY”])
immediate = f”””
Rewrite the next textual content fully in new wording.
Guidelines:
– Protect the info and which means.
– Protect technical accuracy.
– Change sentence construction all through.
– Don’t merely exchange a couple of phrases with synonyms.
– Rebuild paragraphs the place helpful.
– Return solely the rewritten textual content.
TEXT:
{textual content}
“””
response = shopper.responses.create(
mannequin=os.getenv(“REWRITE_MODEL”, “gpt-5”),
enter=immediate,
)
return response.output_text
if __name__ == “__main__”:
authentic = open(“enter.txt”, “r”, encoding=”utf-8″).learn()
rewritten = rewrite_text(authentic)
with open(“output.txt”, “w”, encoding=”utf-8″) as f:
f.write(rewritten)
This would scale back the watermarks.
Elimination isn’t assured except we plug in a detector to verify the output watermark share. However this could suffice as a starter code.
Take away Claude Watermark from Code
Code is extra fascinating.
In the meantime, Anthropic doesn’t describe a separate “code watermark.” Generated code falls underneath the textual content watermarking system. However code accommodates far fewer arbitrary decisions than regular prose. It’s because packages should observe a particular syntax.
For instance:
for i in vary(len(customers)):
course of(customers[i])
may legally turn into:
for index in vary(len(customers)):
course of(customers[index])
This system behaves the identical.
A variable identify can change.
A remark can change.
Formatting can change.
However you can’t arbitrarily change a required Python key phrase or API name with out doubtlessly breaking this system.
That’s the reason watermarking is of course weaker in code.
A Python AST rewrite
For Python code particularly, we will make substantial source-level adjustments whereas preserving this system’s construction.
The script beneath:
renames native identifiers,
removes feedback,
removes standalone docstrings,
reconstructs the supply utilizing Python’s AST.
import ast
import key phrase
import random
import string
from pathlib import Path
class IdentifierRenamer(ast.NodeTransformer):
def __init__(self, seed: int = 42):
self.rng = random.Random(seed)
self.mapping = {}
def _new_name(self, old_name: str) -> str:
if old_name in self.mapping:
return self.mapping[old_name]
prefix = random.selection([“tmp”, “value”, “item”, “obj”, “data”])
suffix = “”.be part of(
self.rng.selection(string.ascii_lowercase)
for _ in vary(5)
)
candidate = f”{prefix}_{suffix}”
whereas key phrase.iskeyword(candidate):
suffix = “”.be part of(
self.rng.selection(string.ascii_lowercase)
for _ in vary(6)
)
candidate = f”{prefix}_{suffix}”
self.mapping[old_name] = candidate
return candidate
def visit_Name(self, node):
node.id = self._new_name(node.id)
return self.generic_visit(node)
def visit_arg(self, node):
node.arg = self._new_name(node.arg)
return self.generic_visit(node)
def visit_alias(self, node):
if node.asname:
node.asname = self._new_name(node.asname)
return self.generic_visit(node)
def remove_docstrings(tree: ast.AST) -> None:
for node in ast.stroll(tree):
if not isinstance(node, (ast.Module, ast.FunctionDef,
ast.AsyncFunctionDef, ast.ClassDef)):
proceed
if not node.physique:
proceed
first = node.physique[0]
if (
isinstance(first, ast.Expr)
and isinstance(first.worth, ast.Fixed)
and isinstance(first.worth.worth, str)
):
node.physique.pop(0)
def rewrite_python(supply: str) -> str:
tree = ast.parse(supply)
remove_docstrings(tree)
transformer = IdentifierRenamer()
tree = transformer.go to(tree)
ast.fix_missing_locations(tree)
return ast.unparse(tree)
def rewrite_file(input_path: str, output_path: str) -> None:
supply = Path(input_path).read_text(encoding=”utf-8″)
rewritten = rewrite_python(supply)
Path(output_path).write_text(
rewritten,
encoding=”utf-8″,
)
if __name__ == “__main__”:
rewrite_file(
“enter.py”,
“rewritten.py”,
)
That is deliberately a supply transformation, not a watermark decoder.
Lastly, it adjustments considerably extra of the generated floor than merely changing one variable identify.
And there is a crucial caveat: AST reconstruction can change formatting and a few source-level particulars. Take a look at the ensuing program earlier than utilizing it.
The identical logic applies to feedback. They’ve way more linguistic freedom than executable syntax, so they supply extra alternatives for statistical marking.
Take away Claude Watermarks from Recordsdata
Recordsdata are thebest to take away watermarkfrom.
Anthropic doesn’t disguise a watermark contained in the pixels of supported photos.
As an alternative, Claude attaches a cryptographically signed C2PA content material credential to supported file sorts akin to .png, .jpg, and .svg. The credential lives within the file metadata and information that Claude processed the asset.
This is a crucial distinction.
The picture itself can stay unchanged. The provenance file sits alongside it because the metadata (header particularly) of the file.
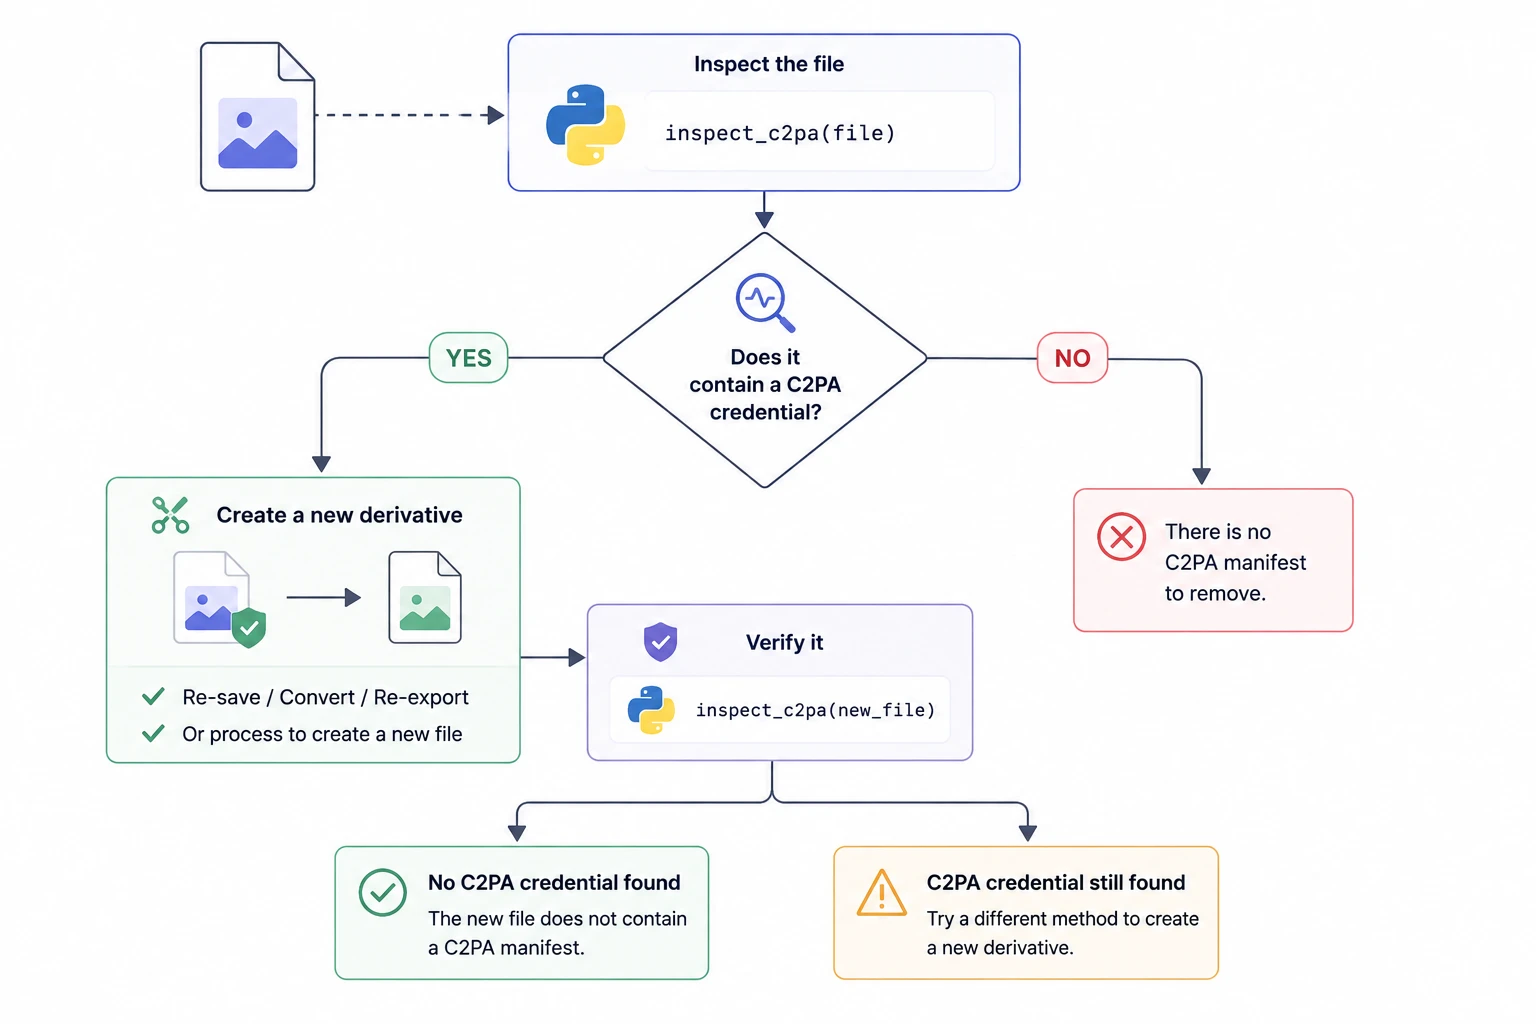
That additionally means creating a brand new spinoff file can break the hyperlink to the unique manifest. Anthropic explicitly lists format conversion, re-saving, screenshots, and comparable operations as methods metadata could also be stripped.
Use Python to examine the file
The official C2PA Python library can learn and validate manifests from supported media information. Set up the library utilizing:
pip set up c2pa-python
Then use the next code:
import json
from c2pa import Context, Reader
def inspect_c2pa(path: str) -> dict | None:
attempt:
with Context() as context:
with Reader(path, context=context) as reader:
knowledge = reader.json()
return json.hundreds(knowledge)
besides Exception as exc:
print(f”No readable C2PA manifest: {exc}”)
return None
if __name__ == “__main__”:
manifest = inspect_c2pa(“picture.png”)
if manifest:
print(json.dumps(manifest, indent=2))
This solutions the primary query:
Does this file include a C2PA manifest?
Don’t strip metadata blindly. Examine first.
What About PDFs and Different Recordsdata?
That is the place you have to be cautious with broad claims.
Anthropic says provenance metadata applies the place Claude helps processing information. Its present documentation explicitly provides .svg, .png, and .jpg as examples. It additionally says some platforms or options might not assist each marking kind.
So don’t write:
“Each Claude PDF has a watermark.”
That isn’t what Anthropic paperwork.
The Python C2PA library is beneficial right here too as a result of it could actually learn supported media information relatively than counting on assumptions.
Can You Take away the Mark Fully?
Let’s face the bottom-line:
Textual content
A whole rewrite can totally take away the unique Claude watermark. Gentle enhancing might not.
Problem: ModerateRecommended Device: Quillbot paraphrases your textual content free of charge.
Code
Code behaves like textual content, however its watermark is usually weaker as a result of there are fewer cheap decisions. Important supply transformation can change the unique statistical sample, however there isn’t a official Claude code-watermark removing API.
Problem: Arduous
Recordsdata
A C2PA credential is metadata. Creating a brand new spinoff file can go away the unique manifest behind. Anthropic explicitly lists format conversion, re-saving, and screenshots amongst operations that may strip file metadata.
Problem: Simple
The Sensible Answer
The three circumstances are basically totally different:
Simply observe the steps outlined on this article to take care of the Claude watermark problem going ahead.
Incessantly Requested Questions
A. No, copying textual content doesn’t take away the watermark as a result of the statistical sample is embedded inside the writing itself, not the file format.
A. Code has strict syntax necessities, leaving fewer alternatives for the mannequin to make the arbitrary phrase decisions that create the statistical watermark sample.
A. You may usually strip the metadata by performing operations like re-saving the file, changing the picture format, or taking a screenshot of the unique.

Finding out, evaluating, and explaining AI programs for over 6 years.
“𝘖𝘯𝘤𝘦 𝘮𝘦𝘯 𝘵𝘶𝘳𝘯𝘦𝘥 𝘵𝘩𝘦𝘪𝘳 𝘵𝘩𝘪𝘯𝘬𝘪𝘯𝘨 𝘰𝘷𝘦𝘳 𝘵𝘰 𝘮𝘢𝘤𝘩𝘪𝘯𝘦𝘴 𝘪𝘯 𝘵𝘩𝘦 𝘩𝘰𝘱𝘦 𝘵𝘩𝘢𝘵 𝘵𝘩𝘪𝘴 𝘸𝘰𝘶𝘭𝘥 𝘴𝘦𝘵 𝘵𝘩𝘦𝘮 𝘧𝘳𝘦𝘦. 𝘉𝘶𝘵 𝘵𝘩𝘢𝘵 𝘰𝘯𝘭𝘺 𝘱𝘦𝘳𝘮𝘪𝘵𝘵𝘦𝘥 𝘰𝘵𝘩𝘦𝘳 𝘮𝘦𝘯 𝘸𝘪𝘵𝘩 𝘮𝘢𝘤𝘩𝘪𝘯𝘦𝘴 𝘵𝘰 𝘦𝘯𝘴𝘭𝘢𝘷𝘦 𝘵𝘩𝘦𝘮.” — 𝖥𝗋𝖺𝗇𝗄 𝖧𝖾𝗋𝖻𝖾𝗋𝗍, 𝖣𝗎𝗇𝖾
Login to proceed studying and luxuriate in expert-curated content material.
Preserve Studying for Free

