


NVIDIA Nemotron 3.5 Lightning is designed for the quick, specialised mannequin execution required by high-volume agentic workloads. With NVIDIA Nemotron 3.5 Lightning on Amazon SageMaker JumpStart, you possibly can entry an open mannequin designed for high-volume agentic workloads.
With this launch, you possibly can deploy Nemotron 3.5 Lightning from Amazon SageMaker JumpStart with out configuring the serving infrastructure your self. NVIDIA describes Lightning because the quickest open mannequin in its class for powering always-on brokers. It delivers as much as 4x greater throughput and as much as 30% sooner process completion on high-volume agentic workloads. At 30B complete parameters with solely 3B energetic, it may possibly run on a single supported GPU. Repetitive, specialised steps in agent workflows can subsequently run with out frontier-scale infrastructure. On this put up, we present you tips on how to deploy Nemotron 3.5 Lightning from SageMaker JumpStart.
Overview of NVIDIA Nemotron 3.5 Lightning
Nemotron 3.5 Lightning is a publicly obtainable basis mannequin distilled from NVIDIA’s frontier Nemotron 3 Extremely and developed with the Nemotron Coalition. It makes use of a hybrid Combination-of-Consultants (MoE) structure and is skilled particularly for agentic device use throughout widespread agent harnesses. It’s skilled on open datasets and launched as an open mannequin, so you possibly can customise it, personal the ensuing weights, and deploy it wherever your brokers run.
The next desk summarizes the important thing specs and efficiency traits of NVIDIA Nemotron 3.5 Lightning.
Specification
Particulars
Structure
Hybrid Combination-of-Consultants (MoE)
Parameters
30B complete / 3B energetic
Context size
As much as 1M tokens
Enter / Output
Textual content in, textual content out
Speculative decoding
DFlash
Throughput
As much as 4x greater for high-volume agentic workloads
Process completion
As much as 30% sooner
Distilled from
NVIDIA Nemotron 3 Extremely
Not each agent step wants a frontier mannequin
All the time-on brokers work repeatedly: they collect context, observe their surroundings, purpose over what they know, and act. Many of those steps can contain mannequin calls, however they don’t all require the identical degree of functionality. Planning a multi-stage workflow or orchestrating sub-agents can demand frontier-level reasoning. Classifying an alert, extracting fields from a kind, or checking a report in opposition to a coverage can typically be dealt with by a smaller, specialised mannequin. These duties can account for a big share of name quantity.
In lots of circumstances, working all model-backed steps by way of a single giant mannequin can add frontier-model value and latency to work {that a} smaller, specialised mannequin can deal with. A system-of-models strategy can as an alternative route every step to a mannequin suited to the duty.
Nemotron 3.5 Lightning is constructed for the high-volume finish of that system. Its MoE structure prompts 3B of 30B parameters per ahead move, serving to preserve excessive throughput throughout lengthy, multi-turn periods. DFlash speculative decoding can additional cut back per-token latency. The 1M-token context window permits an agent to hold amassed state throughout a long-running session with out repeated re-grounding.
If NVIDIA NeMo Switchyard is a part of your stack, it may possibly route particular person workflow steps throughout your chosen mannequin pool. Lightning might be chosen for high-volume specialised steps the place its velocity and domain-specific accuracy are a very good match.
Accuracy throughout reasoning and agentic benchmarks
Throughout the printed evaluations, NVFP4 stays near BF16 on many duties, as summarized within the following desk. NVIDIA stories that the analysis recipes and instructions used to provide these outcomes are printed in NeMo Fitness center. Accuracy outcomes had been measured by NVIDIA underneath a constant harness and will differ from distributors’ self-reported numbers.
The next desk compares the BF16 and NVFP4 variants of Nemotron 3.5 Lightning throughout key reasoning and agentic benchmarks.
Benchmark
BF16
NVFP4
MMLU Professional
81.94
81.62
GPQA Diamond
75.44
75.57
SWE-bench Verified
51.56
52.80
PinchBench
85.37
83.43
IFBench
71.88
72.88
AA-LCR
52.00
49.19
Customizing for area accuracy
Organizations can post-train the mannequin with NVIDIA NeMo for domain-specific instruments, workflows, and insurance policies, then deploy the ensuing mannequin of their chosen surroundings. The SageMaker JumpStart mannequin card for this launch doesn’t expose JumpStart customization.
Enterprise use circumstances
Lightning is constructed for the specialised, high-frequency work inside agent workflows:
Private brokers: Lengthy-running assistants dealing with e-mail, calendar, tasks, and bookings, with the choice to run domestically for contextual information.
Monetary companies: Extracting information from paperwork, checking coverage guidelines, monitoring danger indicators, and making ready structured summaries.
Cyber safety operations: Enriching alerts, classifying incidents, querying logs, validating controls, correlating indicators, and making ready findings for analysts.
Telecom: Triaging community alarms, optimizing community configurations, and answering billing questions.
Retail: Enriching product catalogs, resolving stock and success exceptions, aiding product discovery, and dealing with order, return, and loyalty questions.
Getting began with SageMaker JumpStart
You possibly can deploy Nemotron 3.5 Lightning by way of Amazon SageMaker JumpStart with out manually configuring the serving framework.
Stipulations
Earlier than you start, ensure you have:
An AWS account.
Appropriately scoped permissions for SageMaker JumpStart.
Enough service quota for GPU situations (for instance, ml.g6e.12xlarge, ml.p4d.24xlarge, or ml.p5.48xlarge).
Essential: Deploying this mannequin creates a SageMaker AI endpoint that incurs prices whereas working. For particulars, see Amazon SageMaker AI pricing. Delete your endpoint when completed to keep away from ongoing prices.
Deploy utilizing SageMaker Studio
Open Amazon SageMaker Studio.
Within the navigation pane, select SageMaker JumpStart.
Seek for Nemotron 3.5 Lightning.
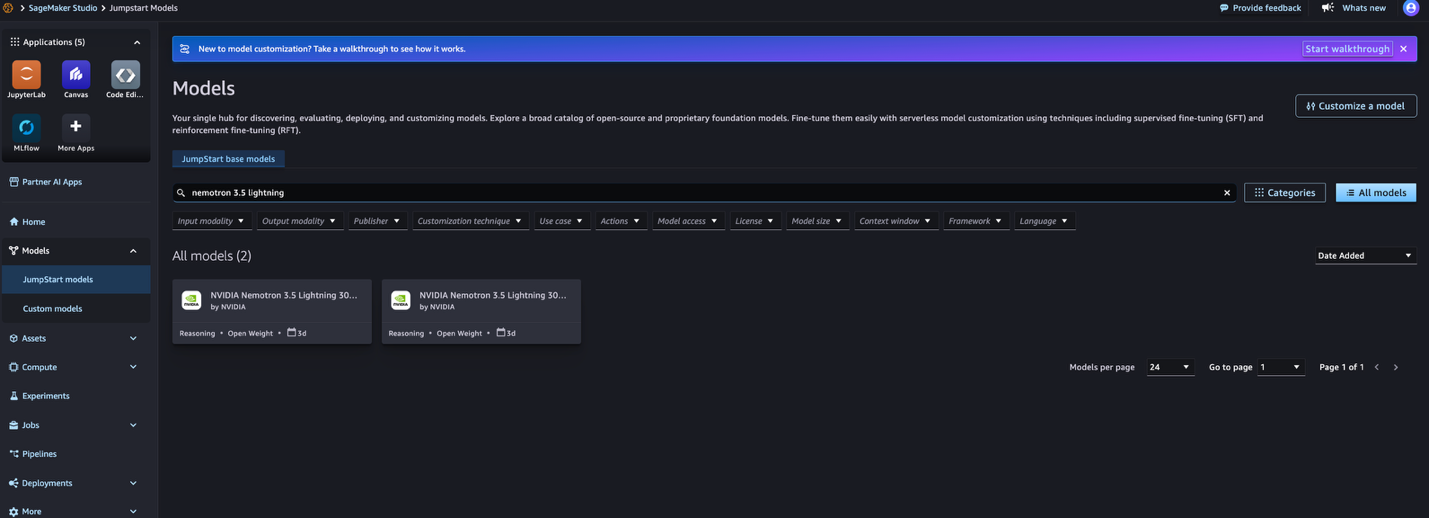
Determine 1: Trying to find Nemotron 3.5 Lightning in SageMaker JumpStart
Choose the mannequin card. The NVFP4 mannequin ID is huggingface-reasoning-nemotron-3-5-lightning-30b-a3b-nvfp4. For BF16, use huggingface-reasoning-nemotron-3-5-lightning-30b-a3b-bf16.
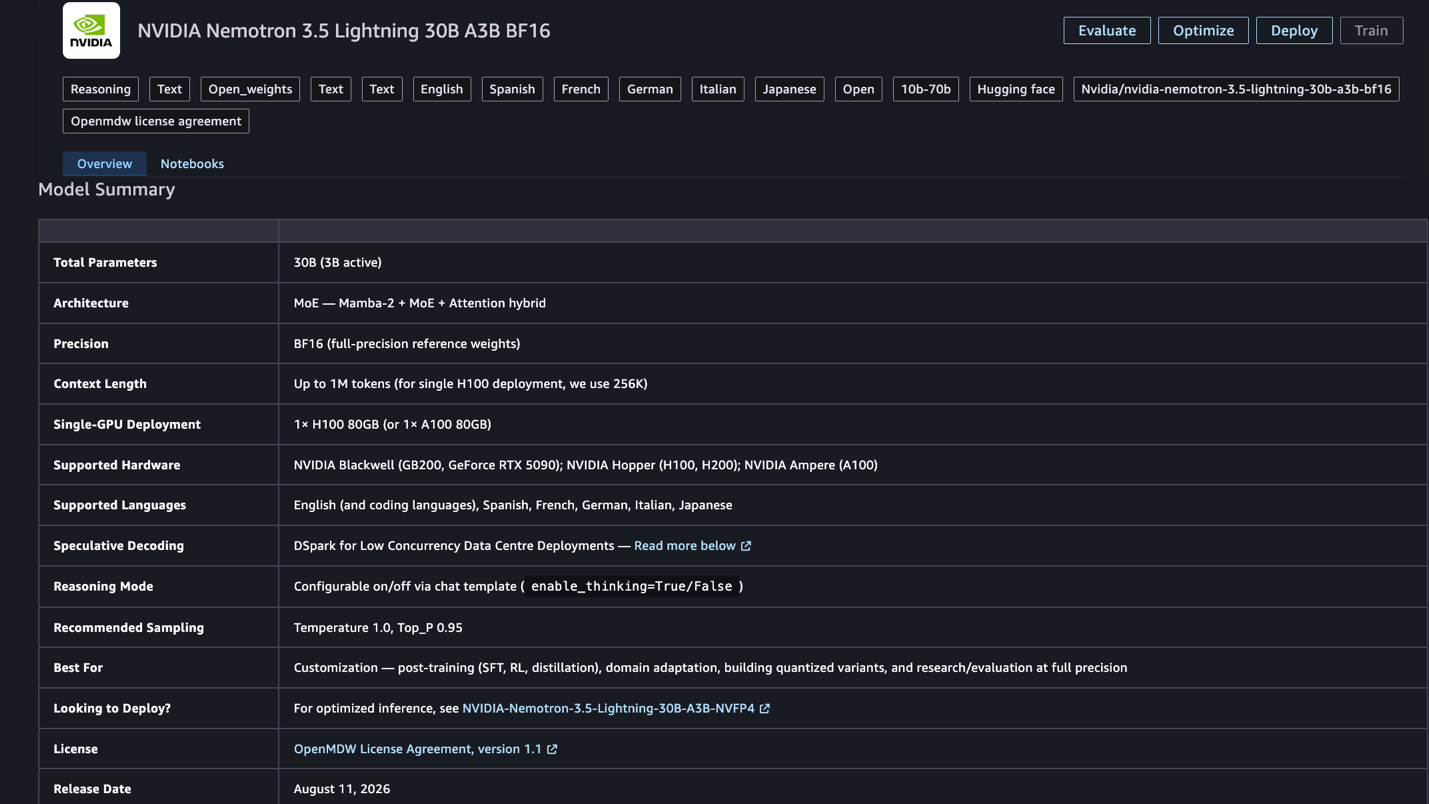
Determine 2: The Nemotron 3.5 Lightning mannequin card in SageMaker JumpStart
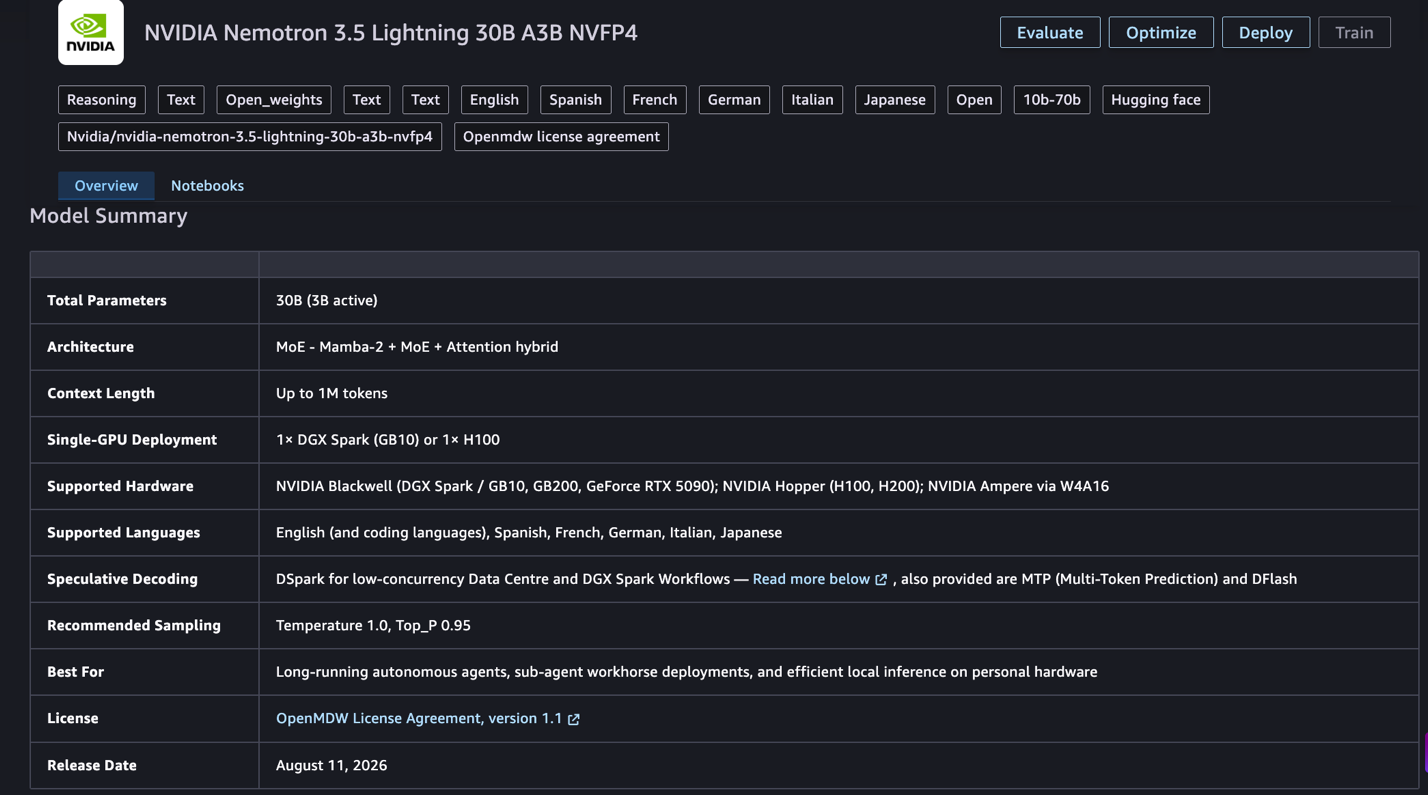
Determine 3: Mannequin card particulars for Nemotron 3.5 Lightning
Select Deploy.
Choose your occasion kind (for instance, ml.g6e.24xlarge).
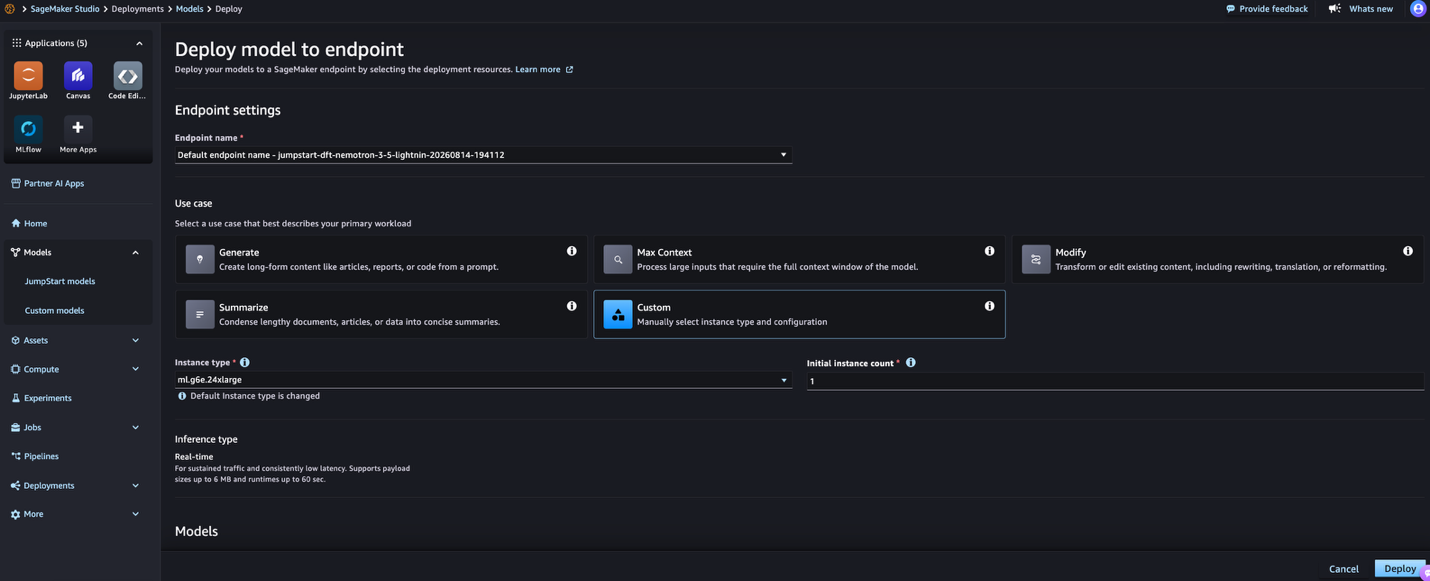
Determine 4: Deciding on an occasion kind for deployment
Overview the deployment settings. The defaults are adequate for many use circumstances.
Select Deploy to create the endpoint.
Anticipate the endpoint standing to point out InService earlier than working inference.
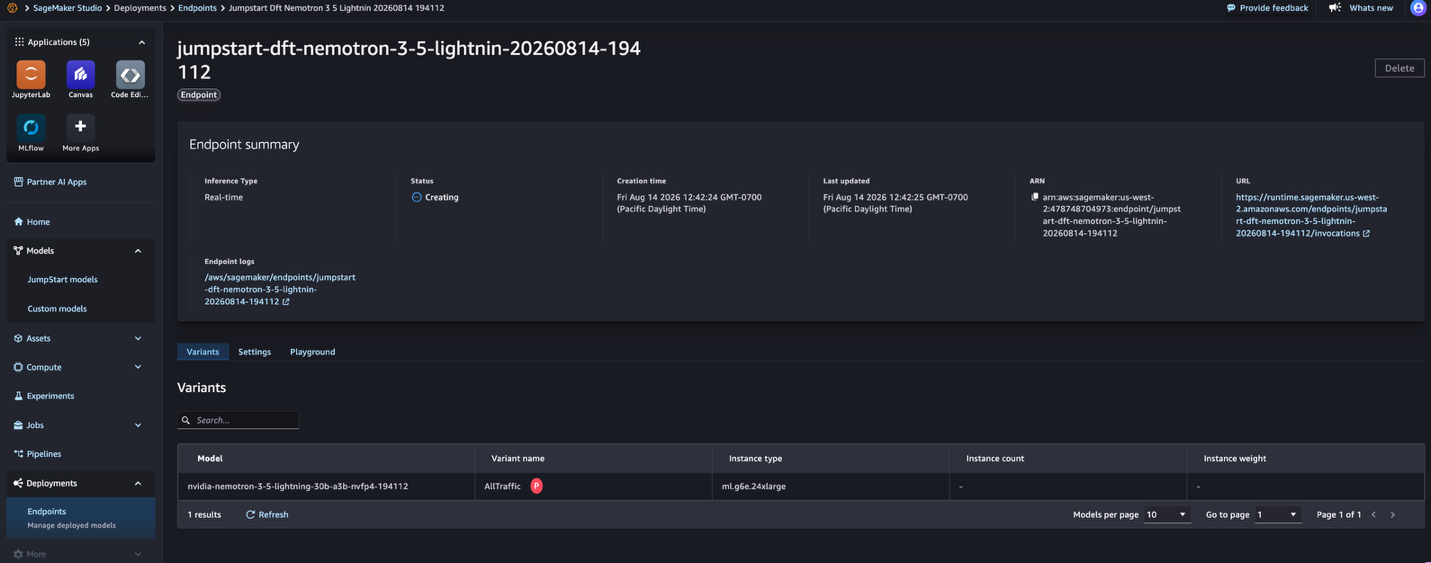
Determine 5: Endpoint standing displaying InService
Deploy from Hugging Face
You too can deploy NVIDIA Nemotron 3.5 Lightning to Amazon SageMaker AI from its Hugging Face mannequin web page. On the Hugging Face mannequin web page, select Deploy, choose Amazon SageMaker AI, after which select Deploy on SageMaker AI. This opens the SageMaker AI deployment workflow, the place you possibly can configure and deploy the mannequin.
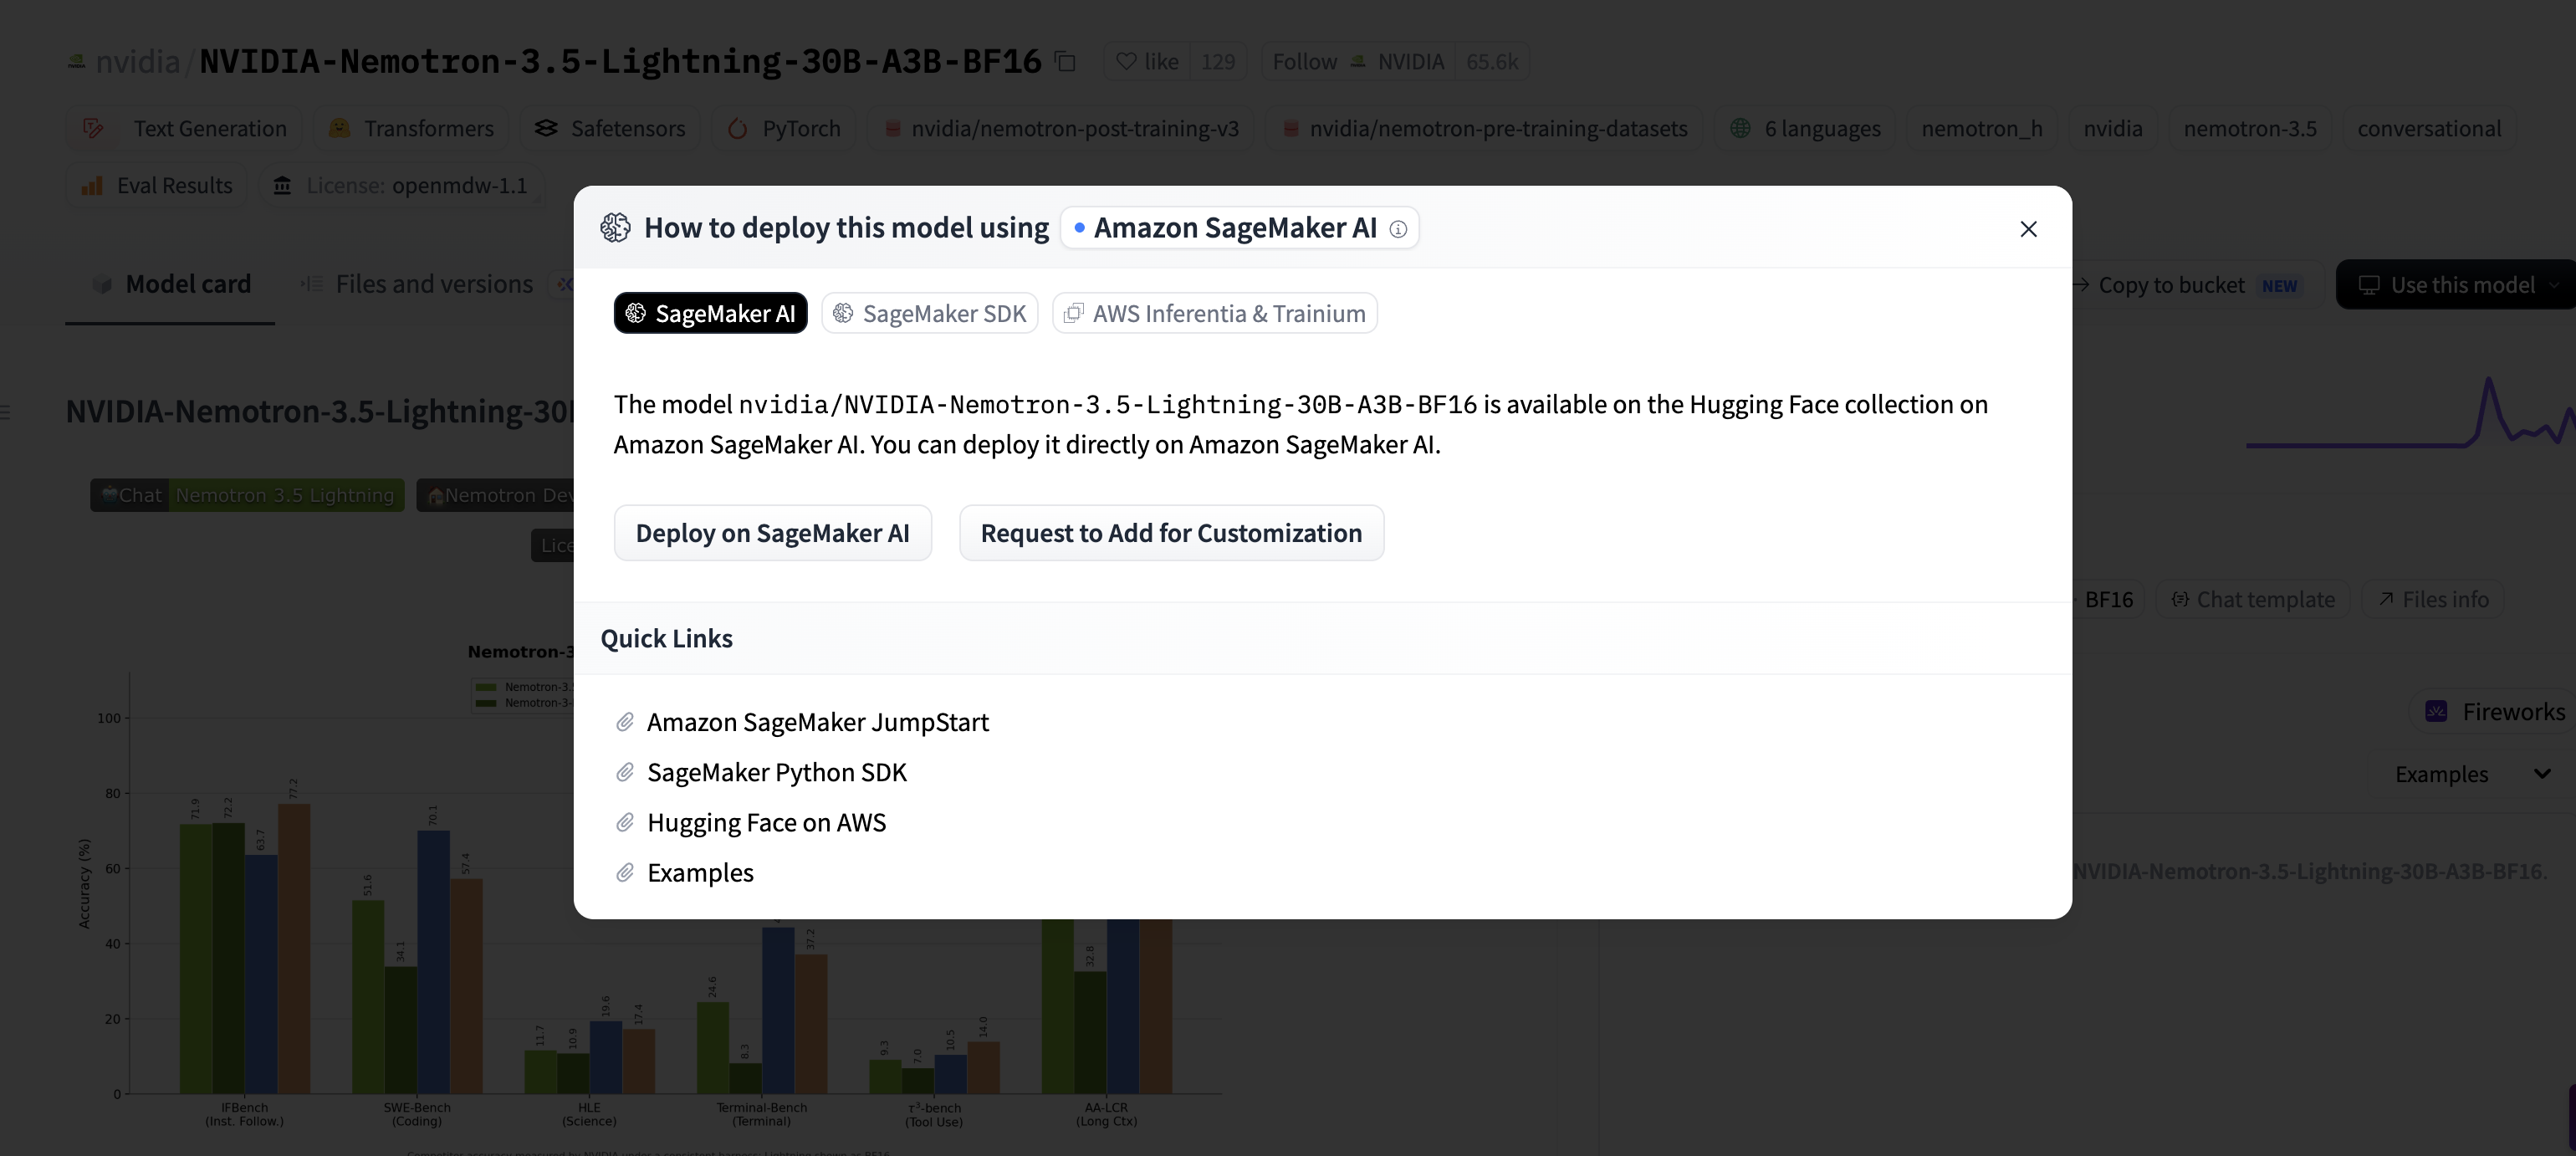
Determine 6: Deploying from the Hugging Face mannequin web page
Deploy utilizing the SageMaker Python SDK
With SageMaker JumpStart, you possibly can entry the NVFP4 and BF16 variants. The next instance makes use of the NVFP4 mannequin ID huggingface-reasoning-nemotron-3-5-lightning-30b-a3b-nvfp4. For BF16, use huggingface-reasoning-nemotron-3-5-lightning-30b-a3b-bf16.
Clear up
To keep away from pointless prices, delete the SageMaker AI endpoint when you’re achieved:
Conclusion
NVIDIA Nemotron 3.5 Lightning brings quick, specialised agent execution to Amazon SageMaker JumpStart. NVIDIA stories as much as 4x greater throughput and as much as 30% sooner process completion for high-volume specialised work. Its hybrid MoE structure, 3B energetic parameters, DFlash speculative decoding, and 1M-token context are designed for high-volume agent workflows. As a result of the mannequin is open and designed for personalisation, you possibly can post-train it to your personal instruments and insurance policies and retain management of the ensuing mannequin.
Nemotron 3.5 Lightning can assist specialised agent workloads throughout private assistants, monetary companies, safety operations, telecom, and retail. You possibly can deploy it at present from SageMaker JumpStart.
Get began by looking for Nemotron 3.5 Lightning in Amazon SageMaker JumpStart. For deployment steering, see JumpStart basis mannequin utilization within the Amazon SageMaker AI Developer Information.
Concerning the authors

Venu Kanamatareddy
Venu is an AI Specialist Options Architect at Amazon Internet Providers, the place he works with high-growth, AI-native startups to design, scale, and operationalize production-grade AI methods.

Evan Kravitz
Evan is a software program engineer at Amazon Internet Providers, engaged on SageMaker JumpStart. He’s within the confluence of machine studying with cloud computing. Evan obtained his undergraduate diploma from Cornell College and grasp’s diploma from the College of California, Berkeley. In 2021, he offered a paper on adversarial neural networks on the ICLR convention. In his free time, Evan enjoys cooking, touring, and occurring runs in New York Metropolis.

Vivek Gangasani
Vivek is a Senior Machine Studying Options Architect at Amazon Internet Providers. He works with Machine Studying startups to construct and deploy AI/ML purposes on AWS. He’s presently targeted on delivering options for MLOps, ML Inference and low-code ML. He has labored on tasks in numerous domains, together with Pure Language Processing and Pc Imaginative and prescient.

Naidile Murali
Naidile is a Product Supervisor at AWS based mostly in Bellevue, WA. She focuses on enhancing the AI/ML developer expertise on Amazon SageMaker AI, together with onboarding, IDE connectivity, and GPU capability administration. Previous to AWS, she labored as a software program engineer at HSBC. Naidile holds an MBA from Georgetown College.

