


Lengthy-running AI brokers typically spend most of their time on routine execution quite than troublesome reasoning. After making a plan, they might carry out a whole lot of device calls, file reads, validations, instructions, and formatting steps, so utilizing a frontier reasoning mannequin for each motion can turn into unnecessarily sluggish and costly.
NVIDIA’s Nemotron 3.5 Lightning takes a distinct strategy: a quick, environment friendly mannequin designed for high-volume agent execution. The concept is easy: use the costly mannequin to assume and the quick mannequin to work. On this article, we look at whether or not that structure can cut back price with out sacrificing agentic efficiency.
What’s NVIDIA Nemotron 3.5 Lightning?
Moreover, NVIDIA Nemotron 3.5 Lightning is an open-weight reasoning and instruction mannequin designed primarily for the execution layer of agentic programs.
Its core specs are:
NVIDIA’s official NVFP4 mannequin card additionally lists single-GPU deployment on a DGX Spark GB10 or H100, with help spanning Blackwell, Hopper and Ampere {hardware} relying on quantization.
The mannequin is primarily supposed for English and programming languages, whereas Spanish, French, German, Italian and Japanese are additionally formally supported.
That is necessary as a result of Nemotron 3.5 Lightning shouldn’t be evaluated as merely “one other 30B mannequin.”
After all, its supposed job is way more particular.
Why NVIDIA Constructed an Execution-Targeted Mannequin
Take into account a coding agent.
It might first want to grasp a bug and develop a plan. That could be a troublesome reasoning downside.
However after the plan exists, the agent might have to:
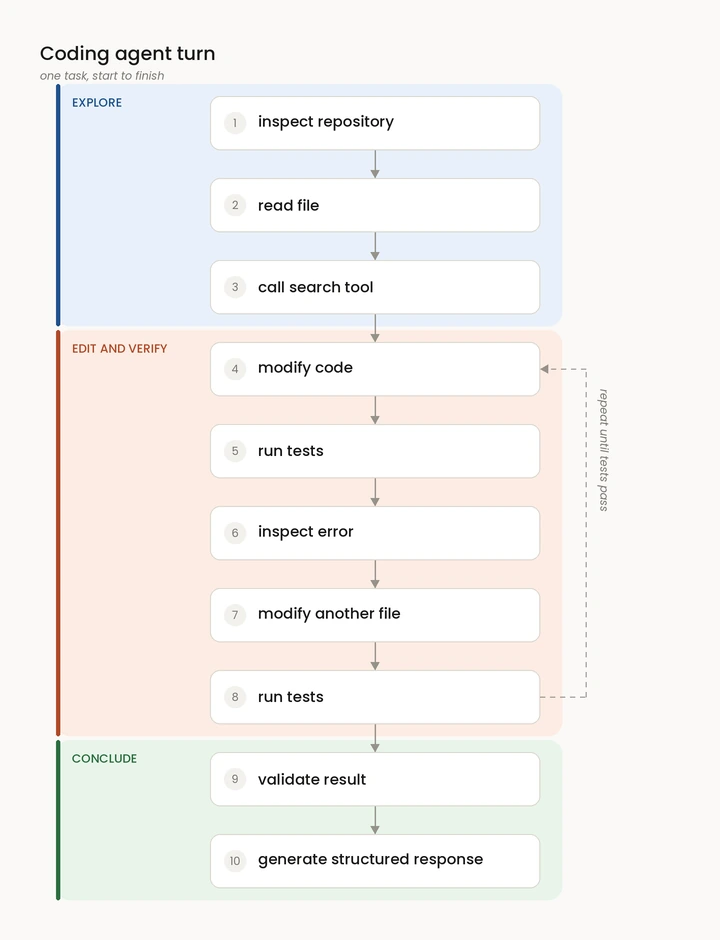
Step one might deserve a frontier mannequin.
Do all of the others?
In all probability not.
NVIDIA argues that long-running brokers spend a considerable portion of their workloads on precisely these high-volume execution operations, akin to device calls, validation and delegation. Utilizing a frontier reasoning mannequin for each execution step will increase each price and latency.
Briefly, Nemotron 3.5 Lightning is NVIDIA’s reply.
A potential manufacturing structure turns into:
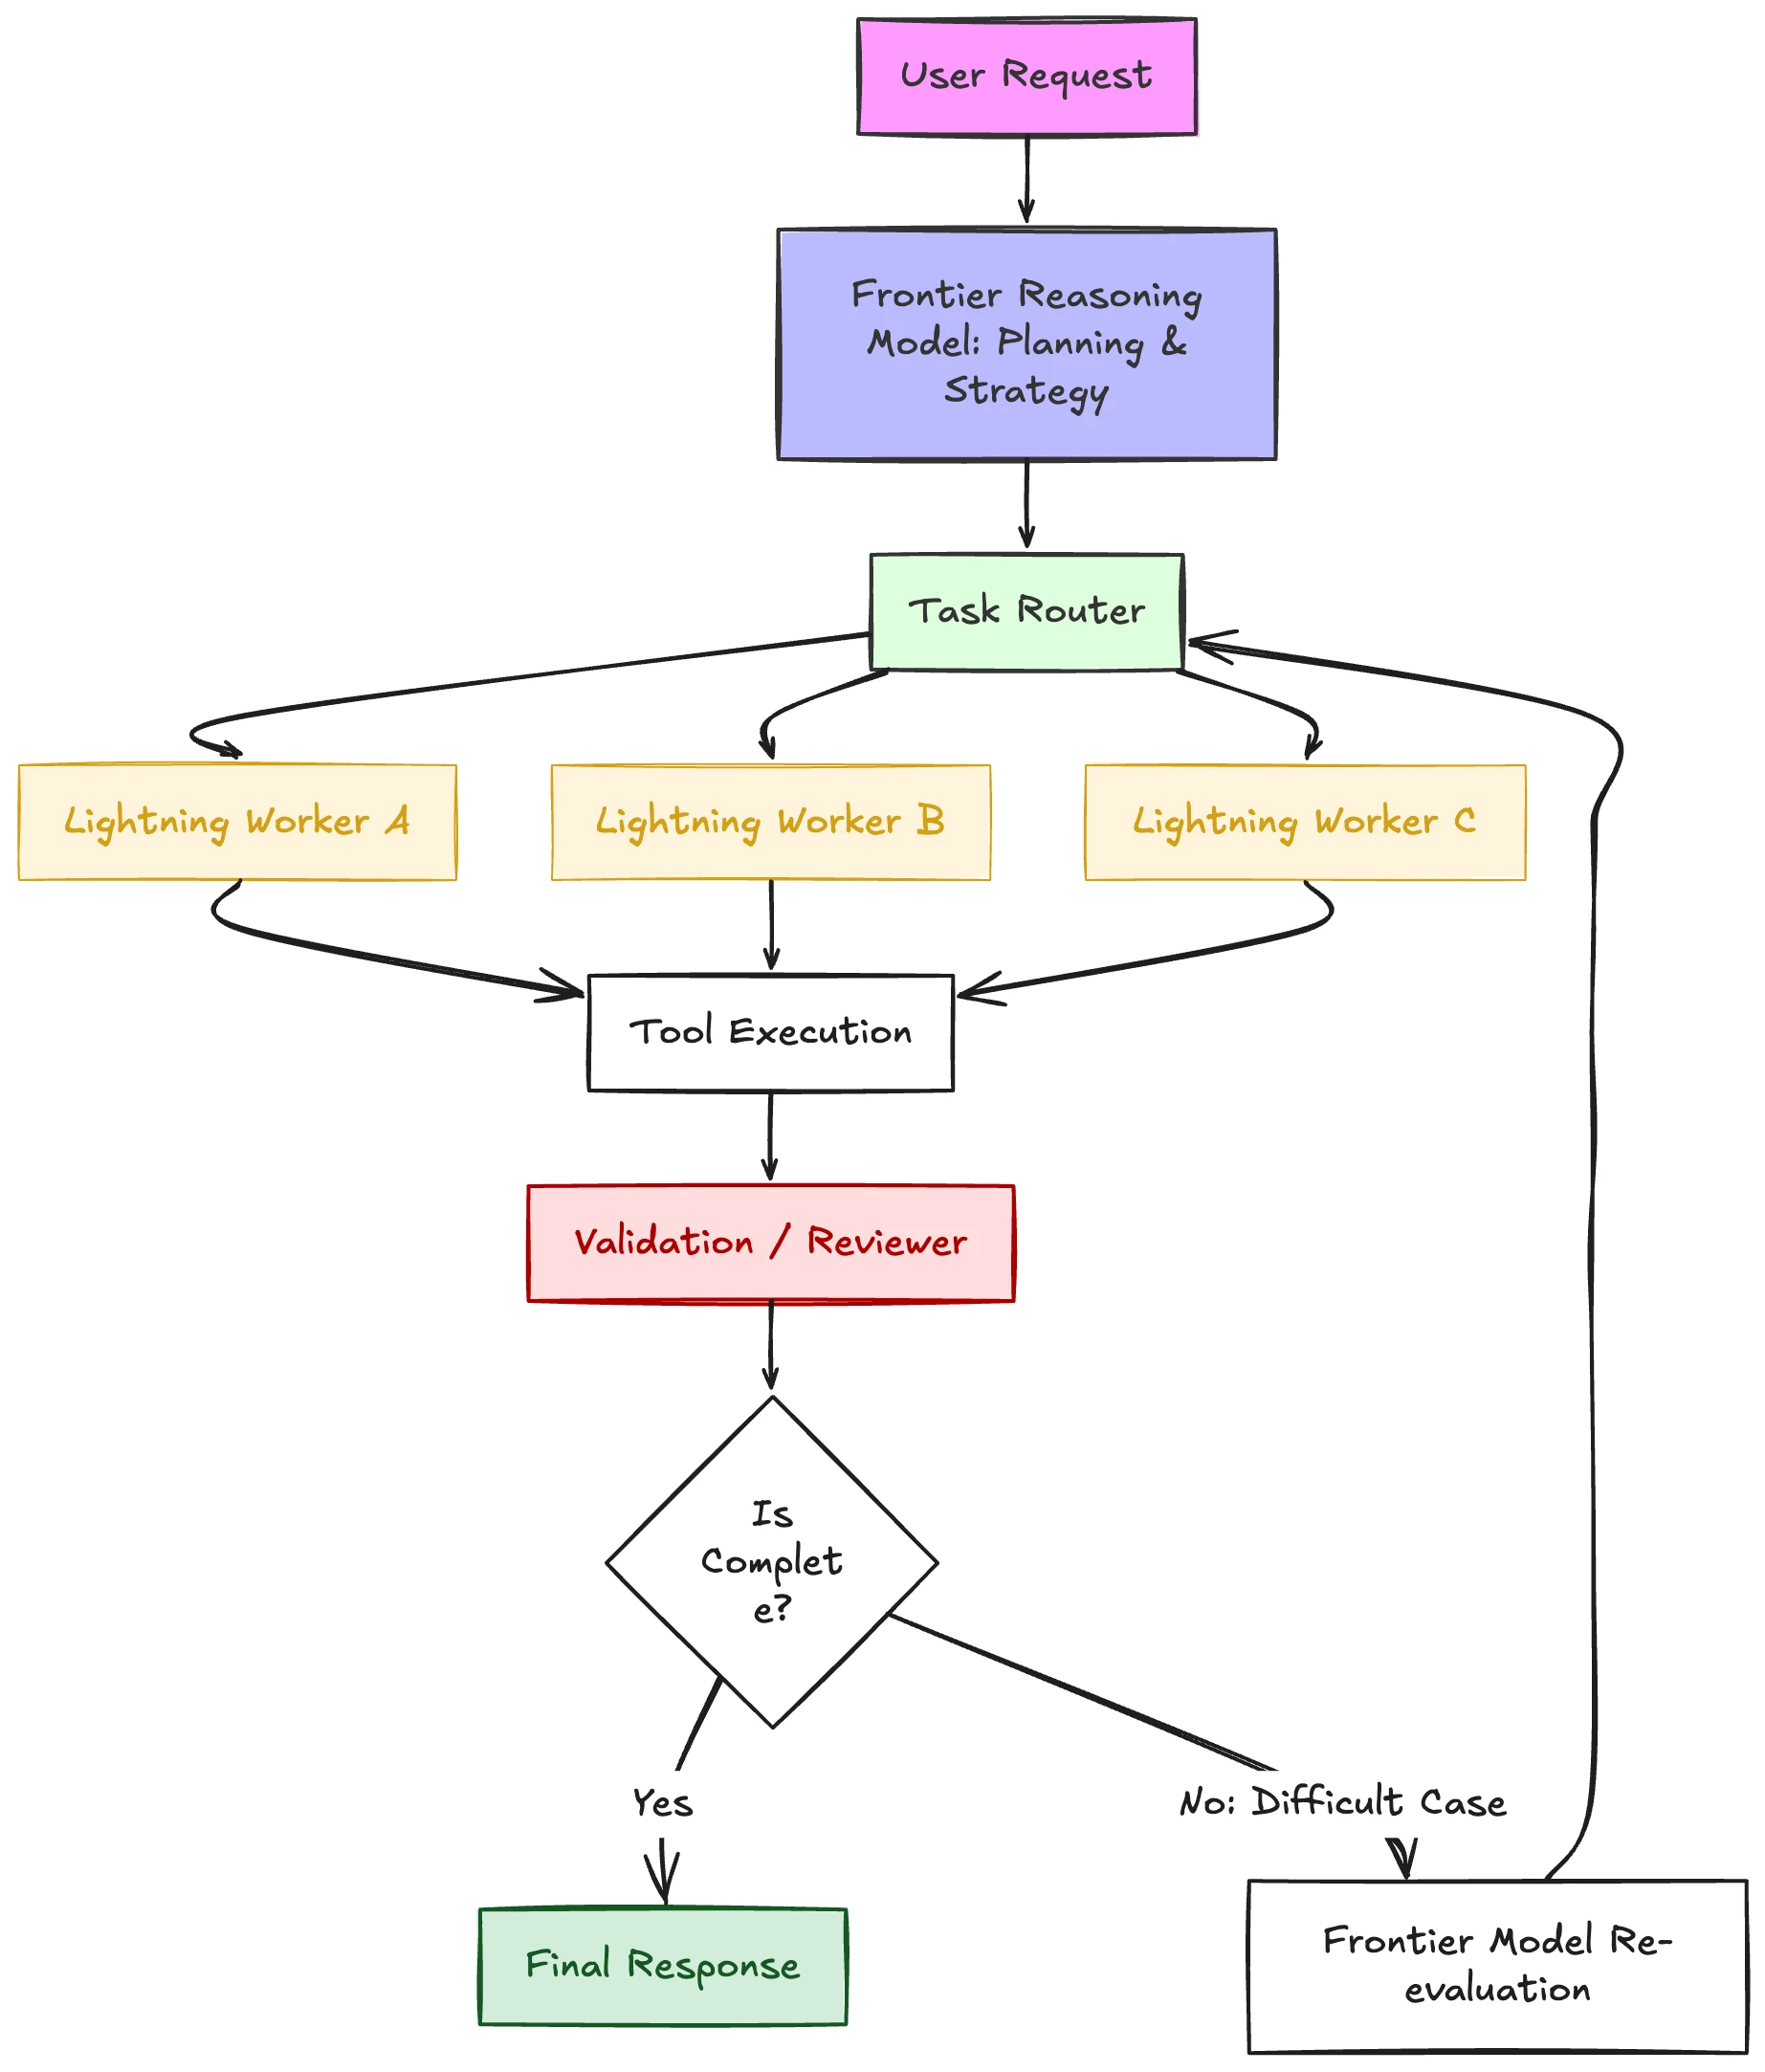
Subsequent, this modifications how we must always take into consideration mannequin choice.
As an alternative of asking:
Lastly, which single mannequin ought to energy my agent?
the extra helpful query turns into:
Equally, which mannequin ought to deal with every kind of labor inside my agent?
That’s the architectural thought behind Lightning.
Structure Deep Dive
In the meantime, Nemotron 3.5 Lightning makes use of one of many extra attention-grabbing architectures amongst present smaller agent fashions.
NVIDIA describes it as a hybrid:
Mamba-2
+
Combination-of-Specialists
+
Selective Consideration
+
Multi-Token Prediction
The mix issues as a result of every element solves a distinct effectivity downside.
1. Combination-of-Specialists: 30B Parameters, Solely 3B Lively
Nemotron 3.5 Lightning incorporates roughly 30 billion whole parameters however prompts solely round 3 billion for every token.
In a dense 30B mannequin, basically the entire community participates in inference.
In an MoE mannequin:
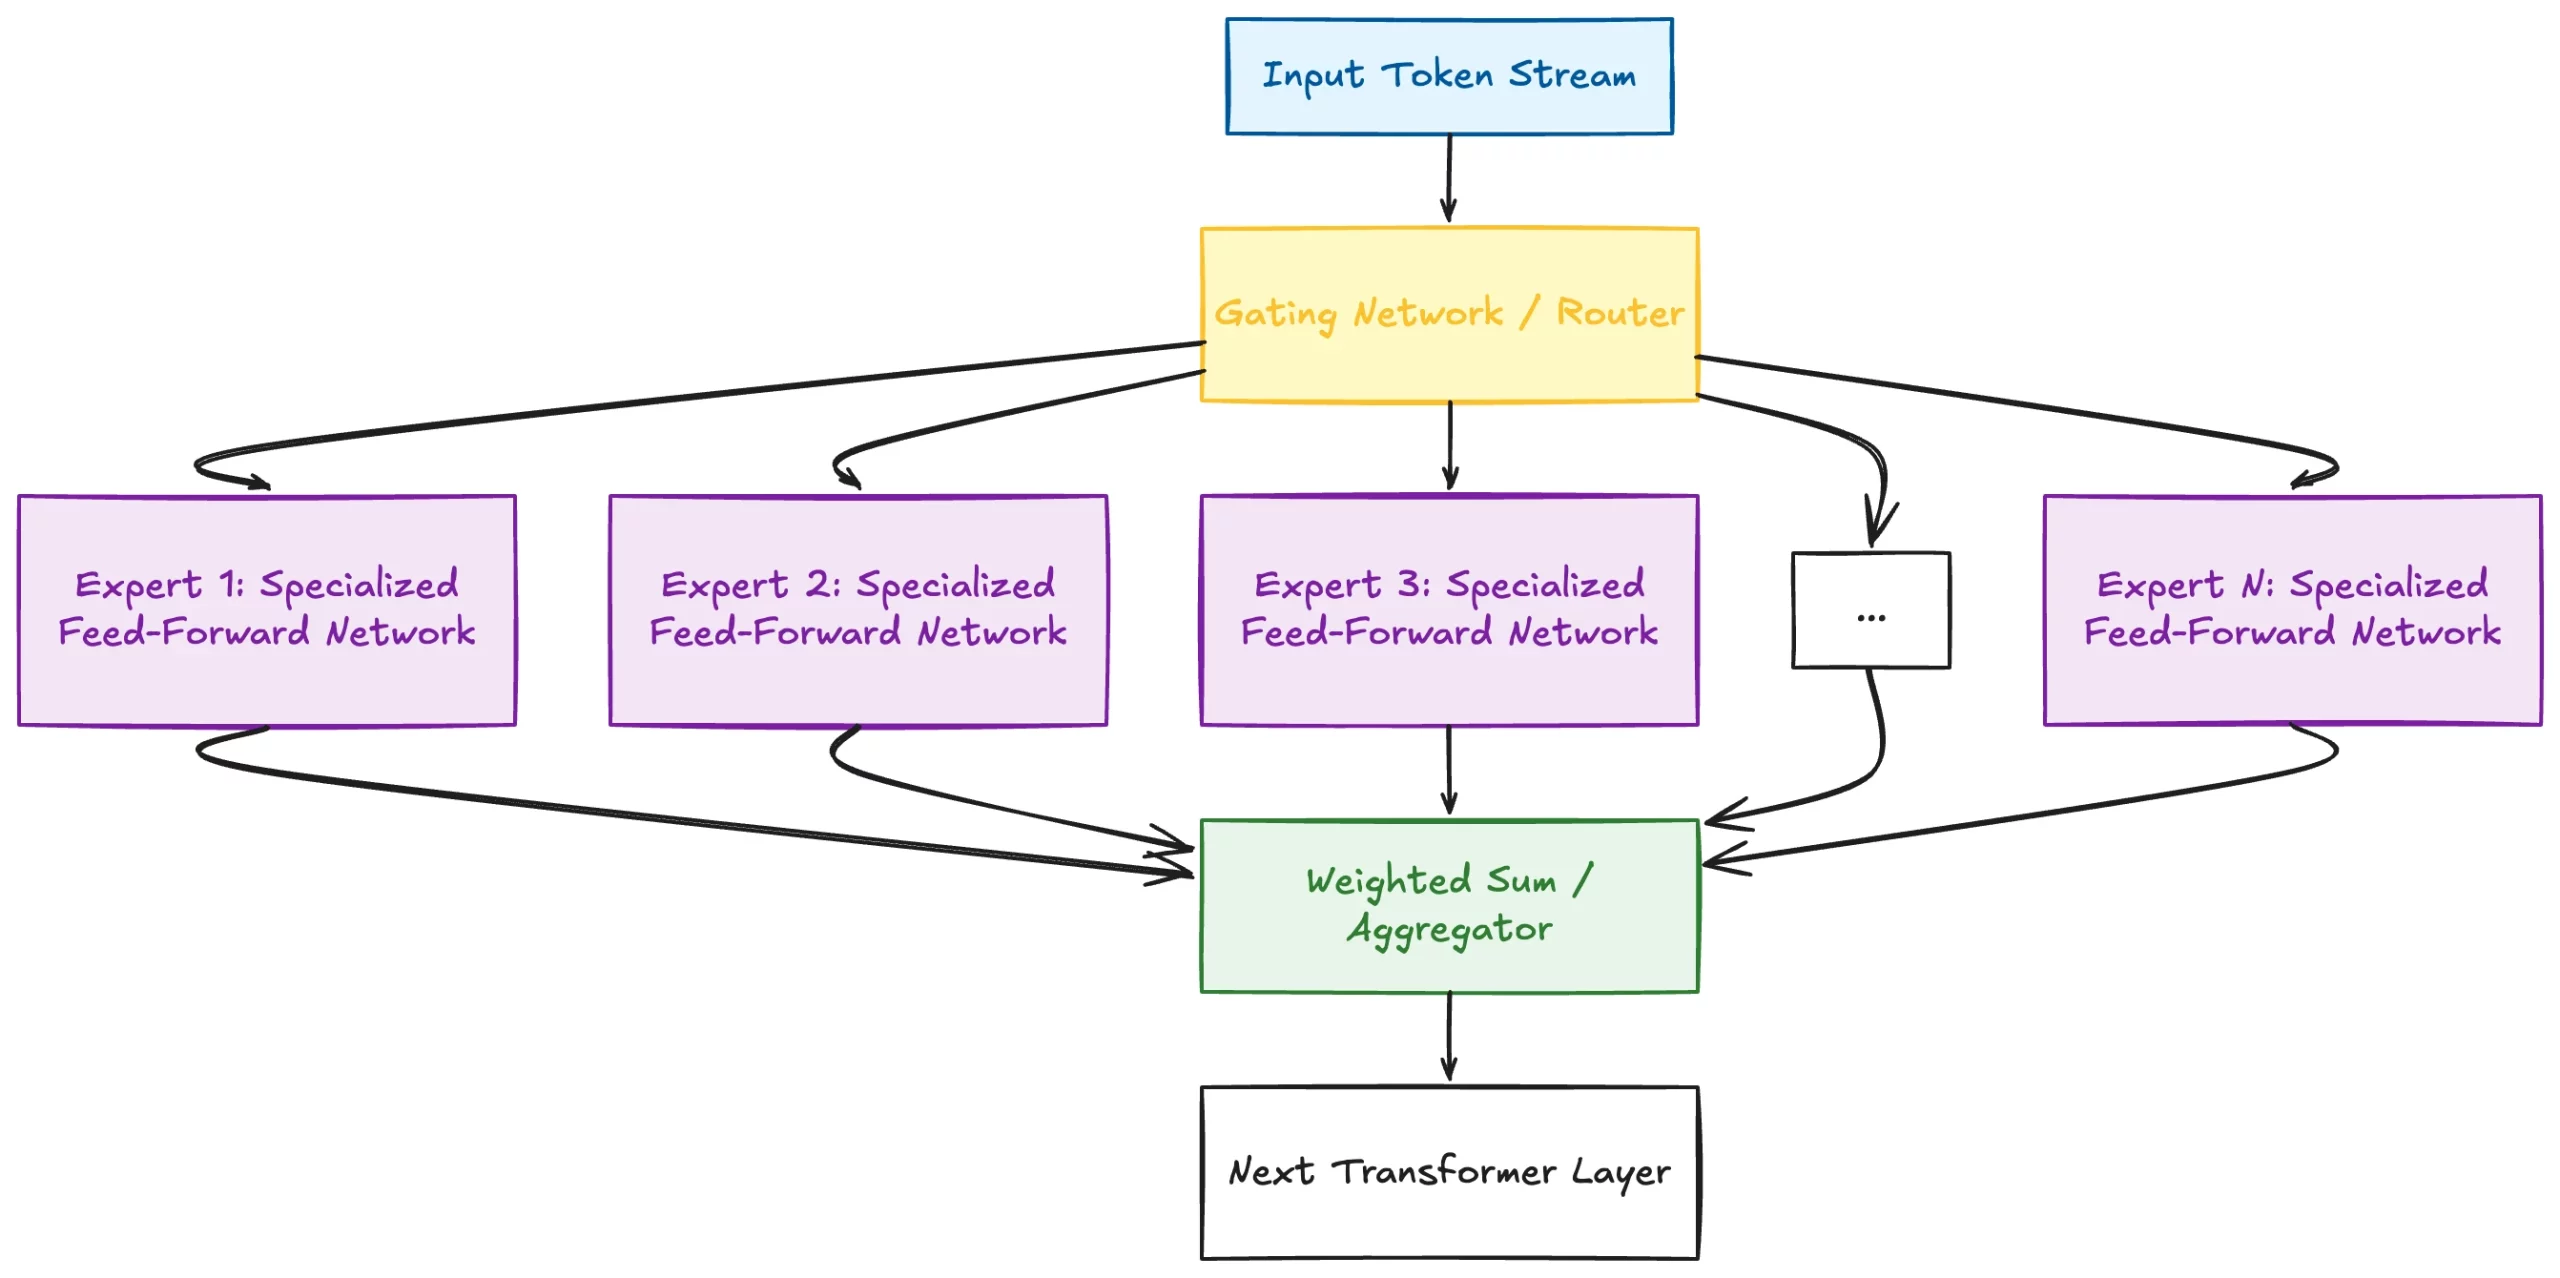
Then again, the router chooses solely a small subset of consultants.
You due to this fact retain a lot of the representational capability of a bigger mannequin whereas doing computation nearer to a considerably smaller mannequin.
That’s central to Lightning’s throughput benefit.
Printed runtime configuration additionally exposes 128 routed consultants plus a shared knowledgeable, with six routed consultants chosen per token. The configuration incorporates 52 hidden layers. Its hybrid layer sample resolves to Mamba, MoE and sparse Consideration parts quite than utilizing full self-attention at each layer. These are implementation-level configuration particulars, so builders ought to confirm them towards the precise checkpoint and runtime they deploy.
2. Mamba-2 Layers
Conventional Transformers rely closely on consideration.
Consideration is extraordinarily highly effective, however lengthy sequences turn into computationally costly.
Though Mamba relies on state-space modeling and might course of sequences extra effectively.
Nonetheless, Nemotron 3.5 Lightning doesn’t abandon consideration totally. As an alternative, NVIDIA makes use of Mamba-2 for a lot of the sequence processing whereas preserving chosen Consideration layers the place international token interplay stays helpful.
Conceptually:
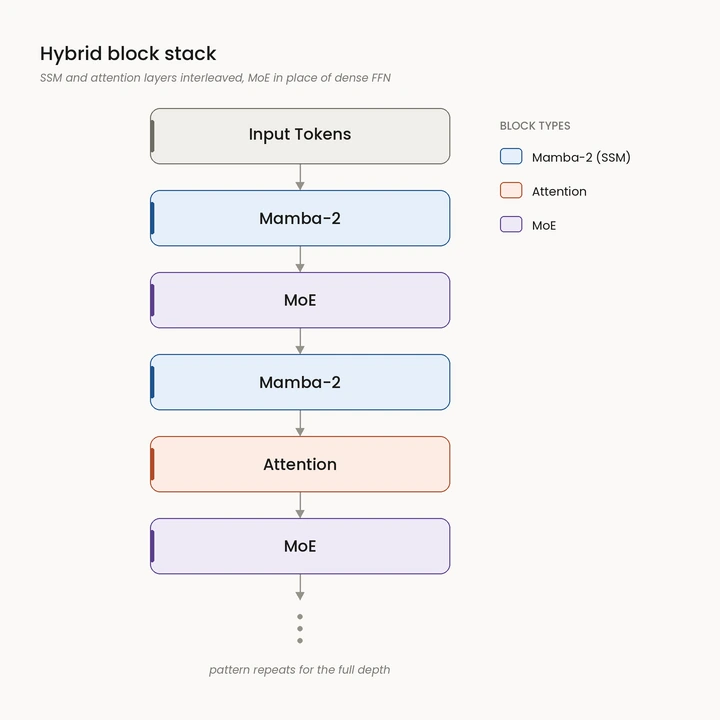
This hybrid design is especially related for long-context brokers.
As an alternative of paying full consideration prices all through your complete community, the mannequin mixes mechanisms optimized for various jobs.
3. Selective Consideration
Consideration continues to be necessary when tokens should instantly evaluate info throughout distant elements of the sequence.
That issues for:
lengthy paperwork
source-code repositories
multi-step device trajectories
dialog historical past
retrieved paperwork
agent reminiscence
Nemotron due to this fact retains chosen consideration layers as a substitute of switching to a pure state-space structure.
The architectural philosophy is just not “Mamba as a substitute of Transformer.”
It’s use costly international consideration solely the place it provides enough worth.
4. Multi-Token Prediction
Regular autoregressive LLMs study:
Token 1 → predict Token 2Token 2 → predict Token 3Token 3 → predict Token 4
Nemotron 3.5 Lightning contains Multi-Token Prediction, or MTP, layers that study to foretell a number of future tokens throughout coaching. Furthermore, NVIDIA added a devoted continued-pretraining stage for these MTP layers.
MTP improves coaching alerts, however it additionally turns into helpful throughout inference.
As an alternative of proposing solely:
subsequent token
the system can speculate about:
token t+1token t+2token t+3…
These candidates can then be verified effectively.
Consequently, this is likely one of the mechanisms behind Lightning’s excessive era throughput.
Why Is Nemotron 3.5 Lightning So Quick?
Then again, its velocity doesn’t come from one optimization. It’s the mixture of a number of.
The most suitable choice due to this fact is determined by concurrency.
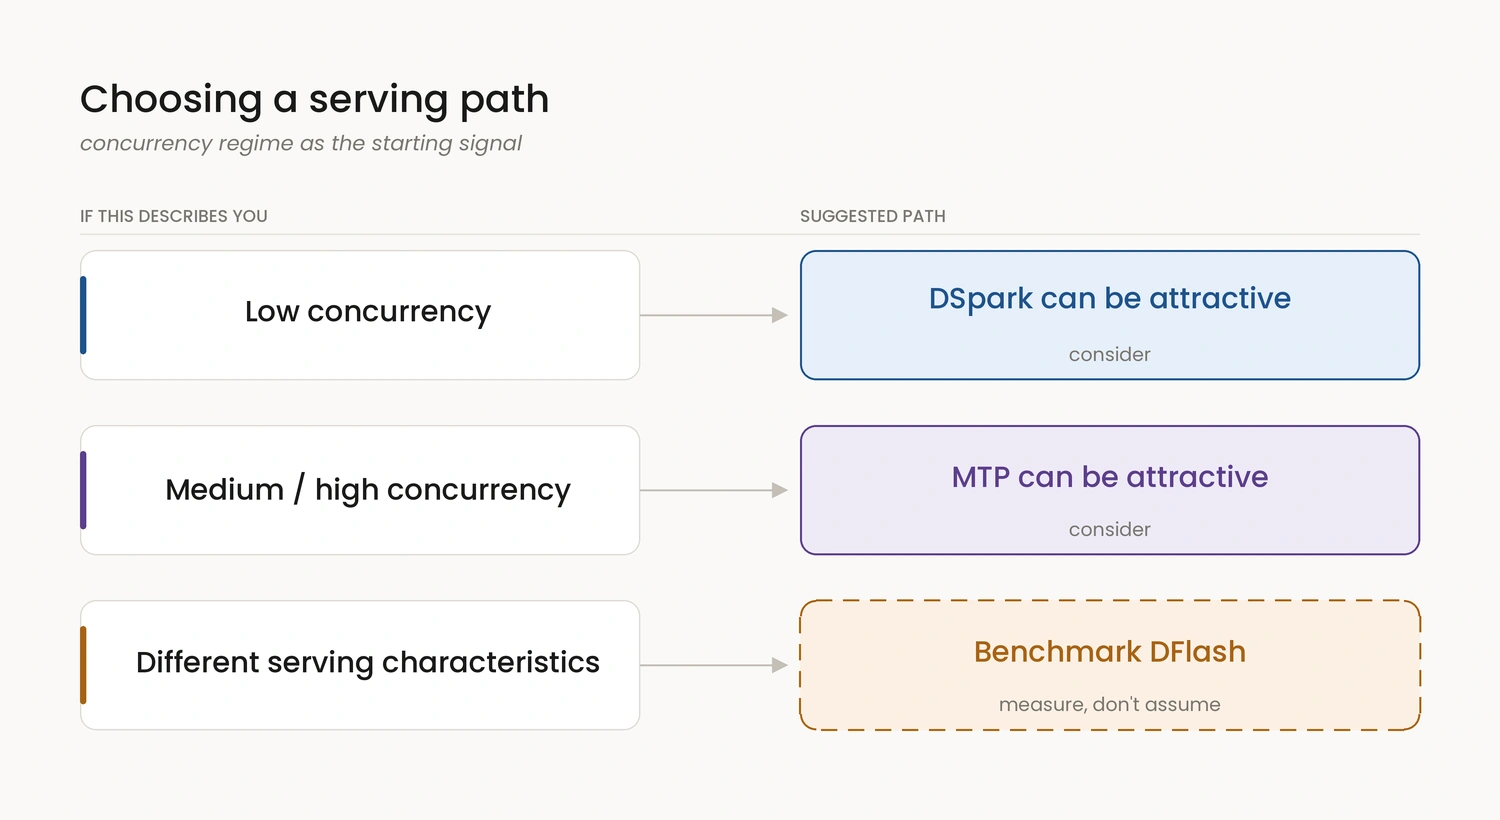
There isn’t any universally quickest configuration.
MoE Sparsity: 30B parameters present capability, however solely about 3B are lively.
Briefly, Hybrid Mamba Structure: Mamba reduces the necessity to carry out full consideration throughout each layer.
Moreover, NVFP4 Quantization: Decrease-precision inference reduces reminiscence and compute necessities.
As an alternative, Multi-Token Prediction: A number of future tokens could be proposed collectively.
After all, Speculative Decoding: NVIDIA supplies three speculative approaches:
MTP: Built-in instantly into the mannequin. NVIDIA recommends it notably for medium to excessive concurrency.
Specifically, DSpark: A devoted draft mannequin optimized for DGX Spark and lower-concurrency data-center inference.
Consequently, DFlash: A further draft mannequin that builders can benchmark towards MTP and DSpark for his or her workload.
Whereas Nemotron 3.5 Lightning combines robust intelligence with as much as 4x output velocity of similar-sized fashions, putting it on the accuracy-speed Pareto frontier for high-volume agent workloads.
NVIDIA Nemotron 3.5 Lightning Benchmark Outcomes
NVIDIA publishes each BF16 and NVFP4 outcomes throughout data, reasoning, coding, brokers, instruction following and lengthy context.
In reality, the necessary statement is that quantization doesn’t dramatically collapse mannequin high quality.
Listed here are the official reported outcomes. Benchmark-native items are preserved, so not each worth must be interpreted as a proportion.
Furthermore, NVIDIA says these evaluations had been run by a constant NeMo Fitness center and NeMo Evaluator-based harness and has printed benchmark recipes for reproducibility.
In distinction, an attention-grabbing result’s how shut NVFP4 stays to BF16.
Nemotron 3.5 Lightning Pricing
Nonetheless, pricing is barely extra sophisticated than a single quantity as a result of the mannequin is open-weight and obtainable by a number of routes.
The next displays publicly listed pricing on August 12, 2026.
Working vLLM regionally
Entry MethodCurrent CostContextBest ForNVIDIA Construct APIFree prototype endpoint1MTestingOpenRouter free routeFree1MQuick experimentationOpenRouter customary$0.05 enter / $0.20 output per 1M tokens262KSimple hosted APIFireworks serverlessSimilarly, $0.05 enter / $0.01 cached / $0.20 output per 1M262KProduction serverlessOllamaNo per-token mannequin feeRuntime dependentLocal/personal useSelf-hosted vLLMInfrastructure costUp to 1MEnterprise/self-hosting
Subsequent, NVIDIA at the moment gives a free API endpoint for prototyping by construct.nvidia.com.
In the meantime, OpenRouter lists each a free Nemotron 3.5 Lightning route with a 1M context and a normal route at the moment priced at $0.05 per million enter tokens and $0.20 per million output tokens. The usual OpenRouter route at the moment advertises a 262K context quite than the complete 1M mannequin functionality.
Lastly, Fireworks at the moment lists precisely $0.05 per million enter tokens, $0.01 per million cached enter tokens and $0.20 per million output tokens, with a 262K serverless context window.
Pricing and context limits can change shortly, notably in the course of the first weeks after a mannequin launch.
The right way to Entry NVIDIA Nemotron 3.5 Lightning
First, at launch, there are already a number of sensible methods to make use of the mannequin.
Choice 1: NVIDIA API
Go to https://construct.nvidia.com/ and login or join
Click on in your profile image after which API keys.
Generate a brand new API key.
Now use this API for inference.
Choice 2: Ollama
Set up Ollama in your system from
Run the next command in terminal to obtain and run Nemotron 3.5 lightening regionally.
ollama run nemotron-3.5-lightning”
Choice 3: OpenRouter
You may also use OpenRouter to run this mannequin. After all, its listed as a Free mannequin on OpenRouter. As an alternative, seize an API key and begin to use it
Palms-on: Utilizing Nemotron 3.5 Lightning By means of NVIDIA API
Nonetheless, NVIDIA exposes the mannequin by an OpenAI-compatible endpoint. The official instance makes use of nvidia/nemotron-3.5-lightning-30b-a3b.
Set up the shopper:
pip set up openai
Set your API key:
export NVIDIA_API_KEY=”your_api_key”
Now create a easy request:
import os
from openai import OpenAI
shopper = OpenAI(
base_url=”https://combine.api.nvidia.com/v1″,
api_key=os.environ[“NVIDIA_API_KEY”]
)
response = shopper.chat.completions.create(
mannequin=”nvidia/nemotron-3.5-lightning-30b-a3b”,
messages=[
{
“role”: “user”,
“content”: “””
A customer has submitted a warranty claim.
Purchase date: 2025-04-12
Claim date: 2026-03-02
Warranty duration: 12 months
Damage type: manufacturing defect
Determine whether the claim is within the warranty period.
Return JSON with:
decision
rationale
“””
}
],
temperature=1.0,
top_p=0.95,
max_tokens=2000,
extra_body={
“chat_template_kwargs”: {
“enable_thinking”: True
},
“reasoning_budget”: 4000
}
)
print(response.decisions[0].message.content material)
Output:
{“determination”: “permitted”,”rationale”: “The guarantee interval begins on the acquisition date of 2025-04-12 and lasts for 12 months, ending on 2026-04-12. The declare was submitted on 2026-03-02, which falls inside the lively guarantee interval. Moreover, the harm is listed as a producing defect, which is often lined beneath customary guarantee phrases.”}
This can be a higher first check than asking: Write a poem about AI.
Nemotron 3.5 Lightning is designed for structured agent workloads, so check it accordingly.
Conclusion
NVIDIA’s primary argument is that future manufacturing AI programs might rely much less on a single big mannequin and extra on a coordinated structure of planners, routers, specialised staff, quick execution fashions, and verification layers. This represents a shift from maximizing mannequin dimension to optimizing how completely different fashions work collectively.
In that structure, Nemotron 3.5 Lightning doesn’t have to be the neatest mannequin obtainable. Its worth comes from being environment friendly, quick, and succesful sufficient to deal with most routine agent duties whereas recognizing when more durable work must be escalated. NVIDIA is due to this fact optimizing for sensible, scalable agent execution quite than merely competing for the biggest or most clever mannequin.
Often Requested Questions
A. NVIDIA supplies open mannequin weights, coaching knowledge, and recipes beneath the OpenMDW 1.1 license. It’s best described as an open-weight mannequin; please overview the governing license.
A. It incorporates roughly 30B whole parameters whereas activating about 3B parameters per token.
A. The mannequin helps as much as 1 million tokens, though particular person suppliers can expose smaller limits.

Harsh Mishra is an AI/ML Engineer who spends extra time speaking to Massive Language Fashions than precise people. Obsessed with GenAI, NLP, and making machines smarter (so that they don’t substitute him simply but). When not optimizing fashions, he’s most likely optimizing his espresso consumption. 🚀☕
Login to proceed studying and luxuriate in expert-curated content material.
Hold Studying for Free

