In multi-turn reinforcement studying (RL), your {custom} reward perform decides what the mannequin truly learns. A subtly mistaken reward can quietly educate the mistaken factor whereas each coaching curve appears to be like wholesome. Designing a reward that holds up over multi-turn, agentic duties is likely one of the hardest elements of customizing Amazon Nova fashions. For multi-turn coaching, Amazon Nova Forge runs your reward logic in your personal setting by its Carry Your Personal Orchestration (BYOO) functionality. You possibly can concentrate on defining what a great consequence appears to be like like whereas Nova Forge coordinates rollouts, message passing, and dialog state throughout turns. Nova Forge additionally gives a serverless multi-turn RL choice, now typically accessible, for groups that favor to not handle that setting. This submit makes use of the BYOO path.
Amazon Nova gives a number of customization approaches, with reinforcement fine-tuning (RFT) standing out as a result of it could educate fashions the behaviors you need by iterative suggestions. RFT takes a unique method from supervised fine-tuning (SFT). Quite than requiring curated examples with annotated reasoning paths, it learns from analysis indicators on the mannequin’s personal outputs. Multi-turn RFT extends this to brokers that act over a sequence of steps, resembling calling instruments, executing code, or recovering from a mistake. It optimizes cumulative reward throughout the entire trajectory relatively than grading a single response. On the coronary heart of RFT lies the reward perform: the scoring mechanism that guides the mannequin, and the half you design.
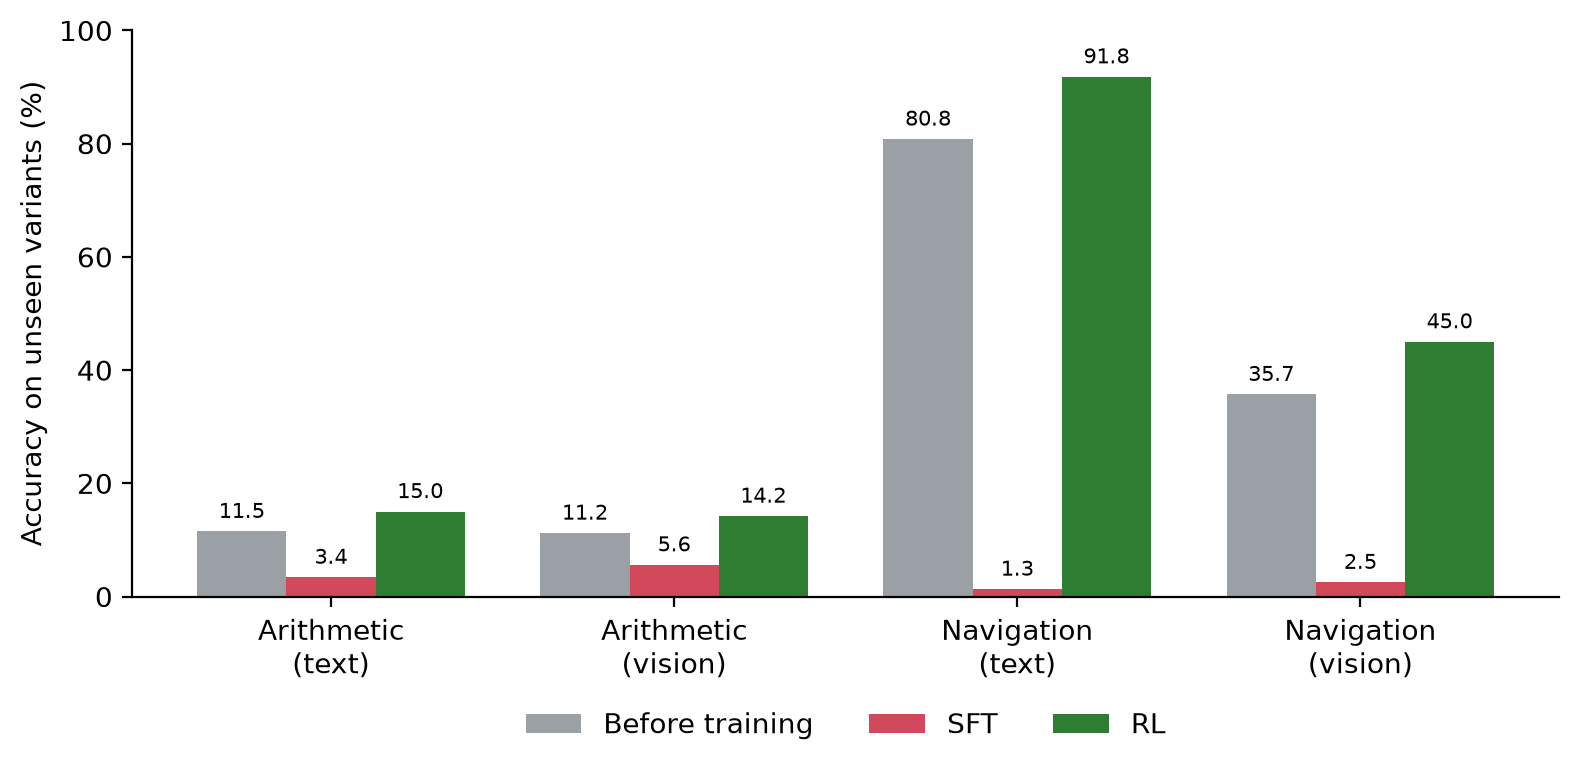
Determine 1 — Out-of-distribution (OOD) efficiency after equal-compute post-training from a shared checkpoint. RL improves OOD generalization throughout all job variants whereas SFT degrades. Tailored from Chu et al., 2025
This submit focuses on the reward perform itself: how you can design a composite multi-turn reward that Group Relative Coverage Optimization (GRPO) can study from. This submit additionally reveals how you can execute model-generated code safely contained in the reward, and why to instrument every element so you possibly can belief what coaching is studying. Half 1 of this sequence covers the Amazon SageMaker HyperPod and Nova Forge infrastructure. It additionally covers the coaching configuration that runs these rewards. We shut with the pitfalls that may quietly collapse a reward, drawn from an actual run the place the highest-weighted element silently contributed no studying sign in any respect. We present how you can catch them. The code all through is illustrative. Use it as a place to begin to your personal reward implementation.
Stipulations
To observe alongside, you want the next:
An Amazon Nova Forge subscription, which gives the Nova Customization SDK and the multi-turn RFT APIs.
The multi-turn RFT infrastructure from Half 1 of this sequence:
An Amazon SageMaker HyperPod cluster, a customer-managed setting on Amazon Elastic Container Service (Amazon ECS).
An Amazon Easy Storage Service (Amazon S3) bucket for rollout information and checkpoints.
The instance code for this submit, together with the reward setting and a walkthrough, from the aws-samples/sample-nova-multi-turn-rl-infra repository.
The {custom} reward setting is opt-in: in cdk.json, set use_custom_env to “true” and custom_env_id to your setting ID (for instance, “my-custom-env”) earlier than you deploy. By default the stack makes use of the built-in wordle setting.
Familiarity with reinforcement fine-tuning and GRPO.
Constructing {custom} rewards with Amazon Nova Forge
RFT works by sampling completions from the present mannequin and scoring them with a reward perform. In Nova Forge, the reward perform is a grader you write in code, and never a individually skilled reward mannequin. It may be a rule-based test that verifies the output (reinforcement studying with verifiable rewards), or it could name one other massive language mannequin (LLM) to evaluate the response, an method referred to as LLM-as-Choose.
RFT then adjusts the mannequin weights to make higher-reward completions extra probably. Nova Forge makes use of GRPO. For every dialog, GRPO makes use of the reward perform to rank Ok mannequin rollouts. GRPO makes use of the highest-ranked mannequin completions to replace the mannequin in keeping with the normalized reward (the benefit) of the batch. RFT with GRPO is a basic approach reaching noticeable efficiency features over preliminary SFT.
A reward sign influences studying solely by the variation it creates inside a gaggle. If a time period takes the identical worth for each completion in a gaggle, it contributes nothing to the benefit. It subsequently contributes nothing to the gradient.
How your reward perform runs with Nova Forge is determined by the duty. With single-turn RFT, you register the reward as an AWS Lambda perform and level your recipe at it by reward_lambda_arn. Multi-turn duties just like the one on this submit exceed what a single Lambda invocation helps. Multi-turn conversations and long-running scoring run previous the 15-minute Lambda invocation restrict. For these, Nova Forge makes use of BYOO. You set rollout.delegate: true and run your setting and reward logic in an setting container, for instance on Amazon ECS. Nova Forge delegates every rollout to your setting. It then collects the finished episodes again for coaching. Your container manages the multi-turn interplay and dialog state: it runs the consumer simulator, executes code, and calls a verifier. It then returns an mixture reward per pattern (aggregate_reward_score), plus an non-obligatory record of per-component scores (metrics_list). Half 1 of this sequence covers this infrastructure and its AWS Cloud Growth Package (AWS CDK) deployment. This submit focuses on the reward.
How reward analysis works
The coaching job generates candidate rollouts from the Nova mannequin for every immediate. In a multi-turn job, a rollout is a full episode with a sequence of turns (a trajectory), not a single response. Your reward perform receives every rollout and performs three steps:
Runs the duty logic. For a conversational job, this could embody a consumer simulator that responds to the mannequin flip by flip.
Scores the finished trajectory throughout a number of reward elements (for instance, job correctness, an intermediate-behavior sign, and penalties), reporting every by metrics_list.
Returns an mixture reward per rollout (aggregate_reward_score), which coaching turns into within-group benefits.
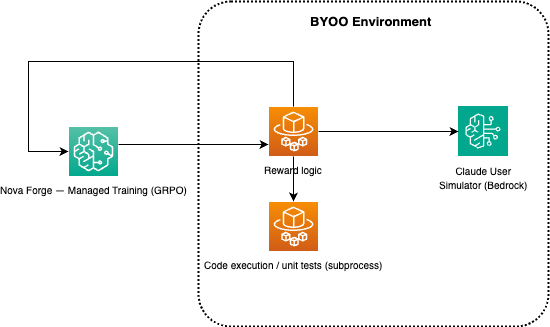
Determine 2 — A single multi-turn rollout: Nova Forge delegates to your setting container, which asks the simulator or runs the dedicated code, then returns a reward rating for GRPO
This cycle repeats over many coaching steps, progressively shaping the mannequin to maximise cumulative reward throughout the entire sequence. The mannequin optimizes towards no matter your reward truly rewards, which, as we present, is just not all the time what you suppose you wrote.
Selecting the construction of a multi-turn reward
Single scalar rewards are simple to sport, and a single terminal reward is commonly too sparse to study from in multi-turn duties. Most manufacturing multi-turn rewards subsequently mix three sorts of sign: consequence rewards, behavioral rewards, and penalties.
Episode-level (consequence) rewards seize whether or not the ultimate artifact glad the purpose. For instance, did the unit assessments cross, or did the workflow full? They aim the factor you in the end care about, however they are usually sparse and near-zero early in coaching.
Flip-level (behavioral) rewards seize whether or not the mannequin exhibited the intermediate conduct you need, resembling asking earlier than appearing, calling the fitting instrument, or avoiding loops. They’re greatest for shaping conduct the end result reward is just too sparse to show, although they are often earned with out actual progress if not designed rigorously. Penalties explicitly discourage a failure mode resembling guessing, repeating, or stalling. They separate good and unhealthy methods so the optimizer sees a gradient.
Mix these so the mannequin learns each the conduct and the end result, with out one element masking or ravenous the opposite. The remainder of this submit makes that concrete. We design a four-component reward for an actual job and execute model-generated code safely inside it. Then we stroll by the pitfalls that may collapse such a reward and how you can repair them.
Labored instance: Instructing Amazon Nova Lite 2.0 to ask earlier than coding
We constructed a multi-turn collaborative-coding job over 500 distinctive programming duties. We skilled Amazon Nova Lite 2.0 on it with multi-turn RFT, utilizing GRPO with Low-Rank Adaptation (LoRA), on Amazon SageMaker HyperPod, implementing the reward inside a customer-managed setting container (the Nova Forge BYOO path).
The mechanics are as follows:
The mannequin sees a quick, under-specified coding request.
A consumer simulator holds the complete specification privately and divulges a element solely when the mannequin asks.
Every flip, the mannequin both asks a clarifying query or commits code. If it asks, the simulator solutions and the dialog continues. If it commits code, the rollout ends and your reward handler executes that code towards hidden unit assessments to attain correctness. (Working model-generated code safely is a priority we return to later.)
The design intent is that guessing produces mistaken code, whereas asking surfaces the hidden element and results in appropriate code. “Ask first” must be compelled by the duty.
Designing the reward
Make the goal conduct straight and independently rewardable, and penalize the failure mode explicitly. For this job, the reward is a weighted sum of 4 elements:
Part
Weight
Definition
correctness
1.0
fraction of hidden unit assessments passing on the ultimate code
asked_before_coding
0.6
1.0 if requested on flip 1 then dedicated; 0.6 if requested later then dedicated; else 0 (un-gated)
guessed_immediately
0.4
penalty: -1.0 if the primary flip is code with no query
loop_penalty
0.2
-0.5 if the final two turns are greater than 80% related
Two rules drive the design. First, un-gate the conduct you need: asked_before_coding is credited by itself, not conditioned on correctness, nevertheless it does require the mannequin to finally commit code, which closes the “ask endlessly, by no means reply” loophole. Second, penalize the failure mode: guessed_immediately makes guessing strictly worse than asking, which restores variation between methods inside a GRPO group, the variation the algorithm wants to provide a gradient.
Name these element scorers contained in the reward handler within the setting container, and report every worth by metrics_list:
Executing model-generated code safely
The correctness element runs model-generated code towards unit assessments. Mannequin output below RL is optimized by exploration, so deal with it as not validated. The container runs in its personal remoted execution setting, however it’s best to nonetheless take precautions. Don’t expose credentials or community to the generated code. Apply useful resource limits and run in a short lived listing. Use a per-run random sentinel so the mannequin can not forge the end result by writing the anticipated marker to stderr. For execution that requires extra isolation, name a devoted sandbox. This harness reveals the sample:
Additionally validate the variety of assessments truly run towards the quantity anticipated, so the mannequin can not dilute the rating with its personal trivially-passing assessments. For reward features deployed in stay environments, implement these safety measures relatively than treating them as non-obligatory.
Pitfalls: What makes a reward collapse, and how you can repair it
Multi-turn reward design has a widely known set of failure modes. Reward hacking is the place the mannequin video games a proxy as an alternative of reaching the purpose. Coaching instability is the place updates diverge and entropy collapses or the Kullback-Leibler (KL) time period blows up. Reward collapse is the place the sign degenerates till within-group variation disappears and studying quietly stops. The primary two often announce themselves in transcripts or in loss and KL curves. Collapse is the harmful one: mixture reward, loss, and completion-length curves can all look wholesome whereas a element you’re relying on contributes nothing. This part covers the 2 collapse failures that value us essentially the most time on this job, and how you can catch them.
When a reward collapses to a single technique
An earlier model of this reward gated the asking bonus behind correctness. You earned the asking reward provided that the ultimate code additionally handed. It additionally added an effectivity time period that rewarded shorter conversations. Coaching collapsed. The mannequin converged to guessing on flip one. The imply reward froze, and the GRPO benefit went to zero.
Two design errors brought on it. First, the gate sat behind an unreachable situation. Correctness was close to zero on these onerous duties, so the asking bonus nearly by no means fired. The conduct we wished to reward was invisible to the optimizer. Second, the effectivity time period had a degenerate optimum. Fewer turns maximized it, so the coverage collapsed onto a single, non-committal flip. Each completion seemed alike, within-group variation vanished, and studying stopped.
The repair is the design within the earlier part: un-gate the conduct you need, and penalize the failure mode explicitly. With each in place, distinct methods maintain producing distinct rewards inside a gaggle, which preserves the variance GRPO must study.
Silently lifeless element
When a reward element returns the identical worth for each completion in a GRPO group, its within-group variance is zero. Because of this, it contributes nothing to the benefit or the gradient, even on the highest weight. The elements that also differ maintain mixture reward, coverage loss, benefit, and completion size trying wholesome, so the curves by no means reveal it. One widespread trigger in code rewards is a correctness scorer that returns 0 on each rollout as a result of the harness by no means executes the mannequin’s output. This may occur due to mismatched entry-point names, failed imports, or a setup error that makes each take a look at fail earlier than its assertions run. In our run, that is precisely what occurred: the mannequin’s clarifying-question fee rose from roughly 34–96 %. Code correctness barely moved, as a result of the correctness scorer was returning the identical worth on each rollout.
To catch a lifeless element, monitor every element’s within-group normal deviation, not the mixture reward curve. Mixture curves disguise a lifeless channel behind the stay ones. If that unfold sits at or close to zero, the element isn’t coaching, no matter its weight. The standard root trigger in code rewards is a correctness scorer caught at 0 as a result of the harness by no means truly binds to and runs the mannequin’s output. Repair that and make sure the unfold turns into non-zero.
Instrument so that you catch these early
A number of habits catch these failures, and would have caught ours on day one:
Instrument per-component contribution to the benefit, not simply per-component reward. Report every element by metrics_list, and monitor its imply and its within-group normal deviation. Any element with near-zero within-group variance contributes nothing to studying, no matter its weight. You may dismiss a flat reward imply of 0.000 as “these duties are simply onerous,” however a flat within-group variance is unambiguous. Automate this as a per-component advantage-variance panel so lifeless channels are flagged robotically, with out handbook inspection.
Learn transcripts sorted by the element you’re testing, not by complete reward. Sorting by complete reward hides a lifeless element behind the stay ones. Sorting by the suspect element surfaces the issue instantly.
Ablate or revive each element you declare is doing work. If eradicating a element modifications nothing, it was not doing work. If reviving a element recovers a metric you assumed was already optimized, it was not within the goal.
Design for within-group variance. GRPO learns from variations between completions of the identical immediate. Unreachable gates, degenerate shaping optima, and saturating phrases all collapse that variation and cease studying even when the reward appears to be like effective. Un-gate the goal conduct and penalize the failure mode so methods separate.
Look ahead to one dense reward ravenous one other. As soon as our dense asking reward saturated, the sparse correctness reward couldn’t transfer the coverage. If a behavioral shaping time period dominates, the end result time period you care about could by no means get a gradient. Contemplate down-weighting a shaping time period as soon as it saturates, or up-weighting the end result time period.
Deal with mannequin output as not validated. Sandbox any execution of generated code (no credentials, no community, useful resource limits) and make verifiers unforgeable (random sentinels, test-count validation).
Clear up
The coaching run and setting on this submit use SageMaker HyperPod and Amazon ECS assets that incur value whereas they run. If you end experimenting, observe the teardown steps in Half 1 of this sequence to delete the SageMaker HyperPod cluster and the Amazon ECS setting, which stops the biggest costs. Take away the rollout information and checkpoints out of your Amazon S3 bucket when you not want them.
Conclusion
The reward perform is the a part of RFT you design, and it’s the place the delicate failures stay. In your runs, the mannequin could study the conduct you prepare for whereas a time period you care about contributes nothing to studying, with no mixture metric revealing it. Higher instrumentation, not a greater algorithm, fastened the difficulty. Measure every element’s contribution to the benefit, learn transcripts by the lens of the element you’re testing, and ablate what you declare is working. With a {custom} reward perform on Amazon Nova Forge you will have full management over the reward, which suggests the accountability for getting it proper is yours. For the infrastructure and AWS CDK deployment that make these runs reproducible, see Half 1 of this sequence.
Acknowledgements
Particular due to Mahima Chaudhary for his or her evaluation and contributions to this submit.
Concerning the authors
Maria Masood
Maria makes a speciality of agentic AI, reinforcement fine-tuning, and multi-turn agent coaching. She has experience in Machine Studying, spanning massive language mannequin customization, reward modeling, and constructing end-to-end coaching pipelines for AI brokers. A sustainability fanatic at coronary heart, Maria enjoys gardening and making lattes.
Nick Biso
Nick is a Machine Studying Engineer at AWS Skilled Companies. He solves complicated organizational and technical challenges utilizing information science and engineering. As well as, he builds and deploys AI/ML fashions on the AWS Cloud. His ardour extends to his proclivity for journey and numerous cultural experiences.
Laurent Mombaerts
Laurent is a Senior Utilized Scientist on the Science and Economics workforce inside AWS Worldwide Gross sales and Advertising and marketing. His analysis spans LLM post-training, multimodal agentic methods, and search and data retrieval, with an emphasis on translating advances in AI into sensible options for AWS clients. He holds a PhD in Engineering from the College of Luxembourg, with doctoral analysis performed in collaboration with the College of Cambridge.