As organizations embrace AI-powered analytics, the worth of a pure language (Text2SQL) reply is barely nearly as good because the enterprise context behind it. We’re getting into a section the place semantic richness (desk and column descriptions, and relationships) should move immediately from the place it’s authored in upstream knowledge catalogs and semantic instruments into the AI merchandise that serve finish customers. Merchandise like Amazon Fast can now not function in isolation. They should natively devour and motive over the definitions, relationships, and governance metadata that knowledge groups curate in techniques like AWS Glue Knowledge Catalog and Databricks Unity Catalog. This shift from siloed metadata to linked, catalog-aware AI is what permits clever analytics at scale.
The problem: Bridging the final mile
The funding is finished
Enterprise knowledge groups have achieved the laborious work. They’ve invested closely in upstream catalog platforms equivalent to AWS Glue, Databricks Unity Catalog, Snowflake Horizon, Collibra, and dbt. On these platforms, they meticulously outline desk descriptions, column semantics, major and international key relationships, glossary phrases, and metric definitions.
But in the case of enabling finish customers (equivalent to gross sales managers, advertising administrators, and finance leads) for production-ready AI and trusted dashboards, a big hole stays.
Three compounding challenges
When knowledge curators (enterprise intelligence engineers, analytics leads, and senior analysts) have to allow their enterprise customers in Amazon Fast, they face three compounding challenges:
Restricted discoverability: With 1000’s of tables in enterprise catalogs, discovering the fitting upstream property which are curated and authorized for reporting is a needle-in-a-haystack downside. There’s no strategy to describe what you want and have the system discover it.
Semantic fragmentation and handbook recreation: Wealthy metadata that already exists upstream (enterprise descriptions on tables and columns, and first and international key relationships) doesn’t move by way of. Curators should recreate property from scratch, redefine descriptions, and reconcile definitions manually. Does “income” imply gross or internet? Does “energetic buyer” imply a purchase order inside 30 days or 90 days? These definitions exist upstream however require handbook re-entry.
Time to perception in weeks, not hours: The mix of handbook discovery and handbook recreation signifies that the time from knowledge to actionable insights stretches from hours to weeks. Worse, when upstream definitions change, manually created semantics in Fast Datasets change into stale, inflicting semantic drift that erodes belief in AI solutions and dashboards over time.
The hole
The issue isn’t upstream. The metadata exists. The governance is outlined. The relationships are mapped.
The issue is the final mile: translating that wealthy catalog context right into a curated, consumable expertise that delivers grounded AI solutions and deterministic dashboards finish customers can belief.
Introducing the Agentic Catalog Expertise in Amazon Fast
Right this moment, we’re saying the Agentic Catalog Expertise in Amazon Fast, an AI-powered workflow that helps knowledge curators quickly outline their context boundary, inherit upstream semantics, and allow finish customers for grounded Q&A and trusted dashboards at scale.
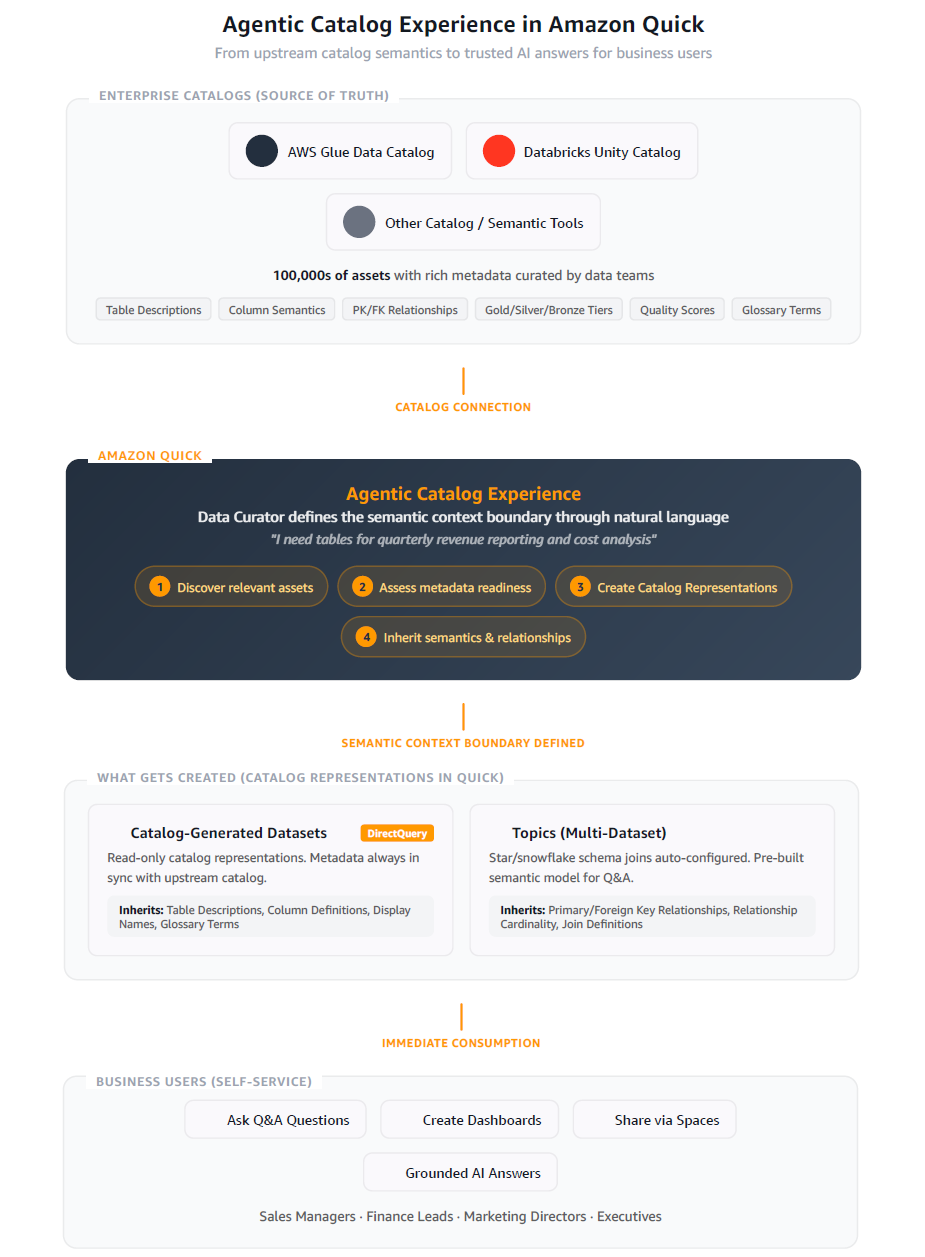
On the coronary heart of this expertise is the Fast Agent, scoped to discovery, creation, and inheritance duties throughout the catalog context. It makes use of the semantic context from the catalog connection to summarize your complete catalog at a look, interact the shopper in pure language dialog, floor probably the most related tables and relationships based mostly on the shopper’s use case, and assess metadata readiness. Then, with a single conversational affirmation, it auto-creates Catalog-Generated Datasets and Matters with focused metadata inherited from the upstream catalog.
No handbook configuration. No context-switching. No weeks of setup.
The way it works
Pure language asset discovery
As a substitute of scrolling by way of 1000’s of tables to search out the fitting ones, curators use pure language. With the Agentic Catalog Expertise, curators describe what they want:
Curator: “I’m a Senior Analyst on the Finance crew. I would like tables for quarterly income reporting and price evaluation.”
The Fast Agent searches throughout your whole catalog to floor probably the most related tables immediately, utilizing all obtainable metadata together with enterprise descriptions, tags, Gold/Silver/Bronze classifications, high quality scores, desk well being scores, and glossary phrases. No extra handbook looking. No extra guessing.
Bulk agentic dataset creation
After the curator selects their tables, the Fast Agent creates catalog representations (Datasets) at scale in a single guided workflow. Your upstream catalog stays the supply of fact as a result of the default creation path is Direct Question. Datasets with inherited semantics are flagged with a transparent “Semantics Inherited” badge, and their metadata is read-only. Authors can refresh inherited metadata on demand by selecting the sync button to remain aligned with their catalog.
Fast Agent: “Creating 6 Catalog-Generated Datasets now: revenue_by_region created (DirectQuery, read-only metadata), cost_centers created, and gl_transactions created.”
Semantic and relationship inheritance
The Fast Agent carries ahead focused metadata out of your catalog into the property it creates. Right this moment, inheritance is intentionally targeted on two key areas to keep away from noise and preserve Datasets clear:
Desk and column definitions to Datasets: Enterprise descriptions and column definitions are inherited immediately into the created Datasets, in order that curators and finish customers have the semantic context they want.
Main and international key relationships to Matters: The Agent detects relationships and makes use of them to recommend and create multi-dataset constructs (Matters) with star and snowflake schema joins preconfigured.
Word: Whereas all obtainable metadata (Gold/Silver classifications, high quality scores, tags, and well being scores) is used throughout discovery to search out the fitting tables, inheritance into Datasets is deliberately scoped to desk and column definitions right now. We plan so as to add extra metadata sorts to Datasets over time.
Fast Agent: “I detected 3 relationships between these tables and created a Subject referred to as ‘Finance Income Mannequin’ with the star schema joins preconfigured. Desk and column definitions have been inherited from the upstream catalog.”
Fast consumption
The curated Datasets and Matters are prepared to be used instantly:
Ask questions: Begin a Q&A dialog together with your new Datasets. The AI agent makes use of inherited enterprise descriptions, glossary phrases, and high quality scores to ship grounded solutions.
Create dashboards: Construct deterministic visualizations with full semantic context already in place.
Share with finish customers: Add Datasets to a Area and share them with enterprise customers for self-service Q&A.
After creation, the metadata tied to those Datasets and Matters feeds into the Amazon Fast semantic retailer, which powers re-ranking and unified context for AI-powered Q&A. Getting from catalog connection to the primary enterprise query takes minutes, not weeks.
Structure: Shopper, not catalog
A key design precept underpins this expertise: Amazon Fast is a client of upstream catalog metadata, not a devoted catalog itself. This implies:
No knowledge duplication: Catalog-Generated Datasets use DirectQuery. No knowledge is copied or moved.
Metadata consumed for context: Inherited semantics are read-only in Amazon Fast and move into the semantic retailer to energy re-ranking and AI reply grounding. Your upstream catalog stays the authoritative supply.
Handbook semantic sync: Authors can refresh inherited metadata on demand by selecting the sync button. Scheduled automated sync is on the roadmap.
Extensibility with transparency: Catalog-Generated Datasets present inherited semantics as read-only (marked as catalog representations). If an Creator chooses to edit a Dataset, Amazon Fast supplies a transparent notification that enhancing creates a customized Dataset and that semantic sync now not applies. This provides Authors full management whereas preserving catalog integrity by default.
Supported catalogs right now
Catalog platform
Authentication
AWS Glue Knowledge Catalog
AWS Id and Entry Administration (IAM) Position ARN
Databricks Unity Catalog
OAuth 2.0 / Private Entry Token
Help for added catalog platforms is coming quickly.
What will get inherited
Metadata inheritance is deliberately targeted to maintain Datasets clear and production-ready:
Into Datasets (desk and column definitions)
Desk enterprise and technical descriptions.
Column descriptions and show names.
Knowledge sorts and nullability.
Glossary phrases and synonyms.
Into Matters (relationships)
Main and international key relationships.
Relationship definitions and cardinality.
Star and snowflake schema fashions.
The tip-user expertise
Right here’s what this implies for the enterprise customers downstream:
A gross sales supervisor asks: “What have been our This autumn gross sales by area?”
Behind the scenes, the AI agent:
Searches Catalog-Generated Datasets utilizing enterprise descriptions and glossary phrases.
Identifies the gross sales.revenue_by_product desk (Gold, 98 % high quality).
Applies preconfigured joins from the Subject to mix related dimensions.
Respects personally identifiable info (PII) masking guidelines from catalog metadata.
Returns a grounded, trusted reply in seconds.
No handbook dataset configuration required. The curator outlined the context boundary as soon as with the Fast Agent, and each finish consumer advantages instantly.
Unified enterprise context
The Agentic Catalog Expertise doesn’t exist in isolation. Mixed with the broader platform capabilities of Amazon Fast (together with integration with Slack, Outlook, paperwork, and information bases), finish customers get the complete enterprise context:
Structured knowledge from catalogs by way of Catalog-Generated Datasets.
Unstructured context from paperwork, e-mail messages, and conversations.
Enterprise guidelines from glossary phrases and metric definitions.
This unified context permits production-ready AI solutions, grounded in your group’s particular knowledge and semantics.
Connecting to AWS Glue Knowledge Catalog
To get began with the Agentic Catalog Expertise, create an information supply connection to your AWS Glue Knowledge Catalog in Amazon Fast. After you identify the connection, the Fast Agent guides you thru discovery, schema exploration, and Subject creation in a single conversational workflow. On this walkthrough, we hook up with a Glue Knowledge Catalog and construct a Monetary Analytics Subject.
In Amazon Fast, create a brand new knowledge supply. From the listing of connection sorts, choose Glue Knowledge Catalog (obtainable in preview), after which select Subsequent. This connection is for the metadata. With it, Amazon Fast can devour the desk and column definitions and the relationships your groups have already curated in AWS Glue.
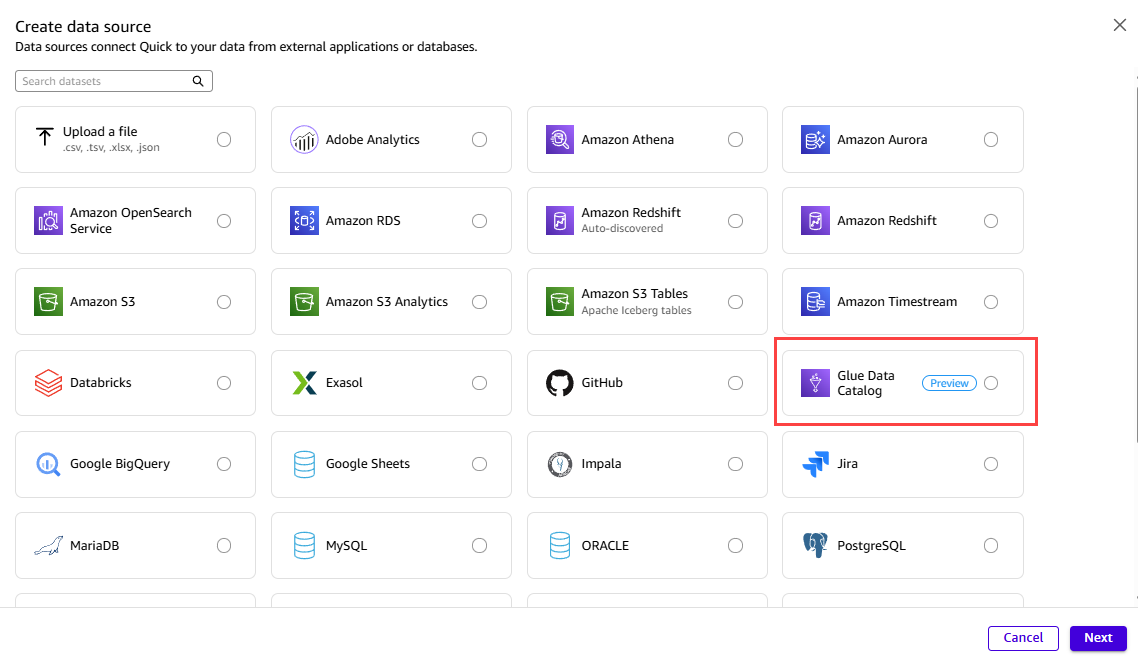
Determine 1: Choosing the Glue Knowledge Catalog connection kind in Amazon Fast
A Glue Knowledge Catalog connection works along with an Amazon Athena connection. Glue supplies the metadata, and Athena supplies the question path to the information itself in Amazon Easy Storage Service (Amazon S3). Create the Athena knowledge supply as effectively, in order that Amazon Fast can run queries towards the underlying knowledge. After you create each, the Knowledge sources web page reveals the 2 entries aspect by aspect: the Glue Knowledge Catalog supply for the metadata and the Athena supply for the information.
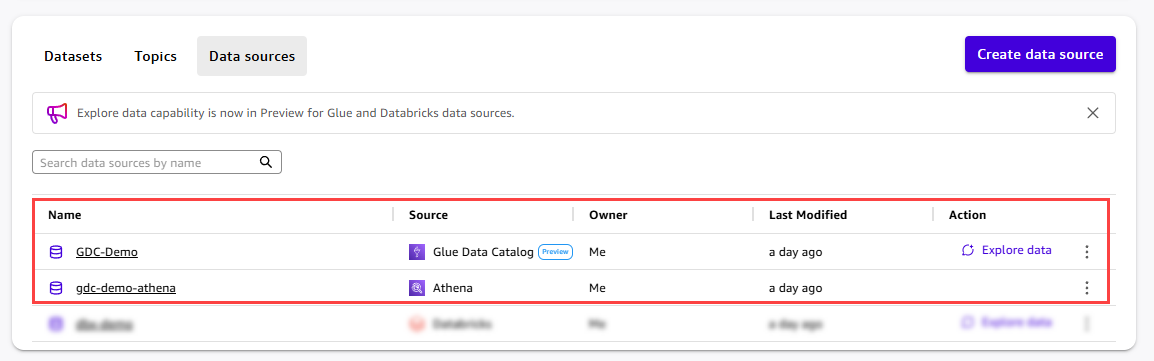
Determine 2: The Glue Knowledge Catalog and Athena knowledge sources listed collectively
Open the GDC-Demo knowledge supply element web page. Beneath Knowledge connections, you possibly can see the linked Athena knowledge supply that Amazon Fast makes use of to question the information. Select Discover knowledge to launch the Fast Agent scoped to this knowledge supply.
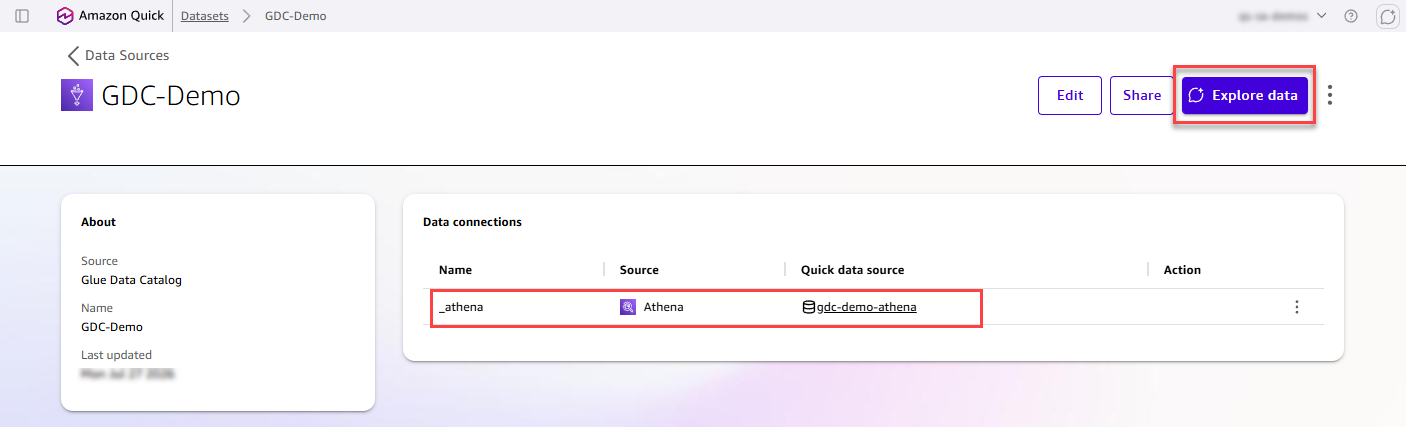
Determine 3: Launching the Fast Agent from the information supply element web page
The Fast Agent panel opens on the fitting aspect of the display screen, routinely scoped to the Glue Knowledge Catalog knowledge supply. The “Particular knowledge” mode is chosen, with “GDC-Demo” pinned because the context boundary. In consequence, the Agent surfaces solely metadata from this particular catalog connection.
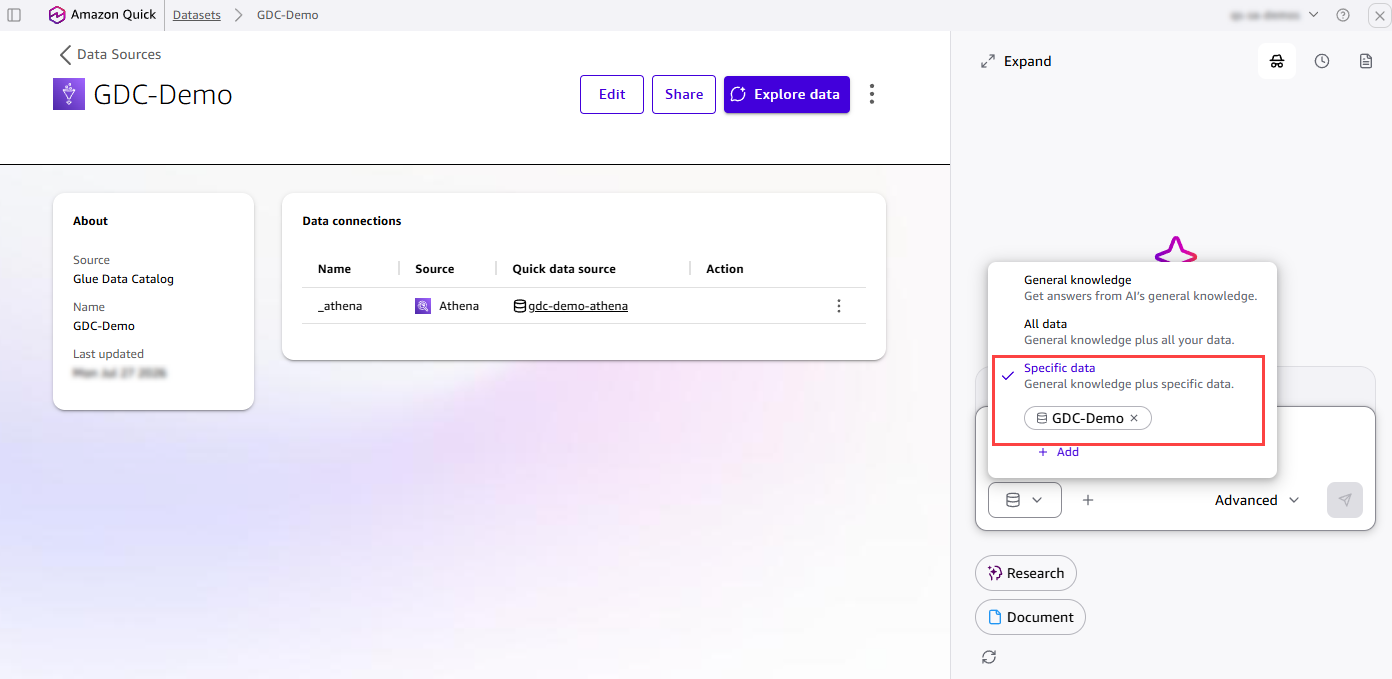
Determine 4: The Fast Agent scoped to a particular catalog connection
Ask the Agent to discover your catalog. The Agent summarizes the obtainable catalogs and databases at a look, so you possibly can shortly see what’s curated in your Glue Knowledge Catalog. For this publish, we use the “fa-demo” database as our instance, a Finance Analytics Demo star schema for banking analytics. This walkthrough illustrates how the characteristic works and isn’t an actual state of affairs, so you possibly can apply the identical steps to your individual catalog.
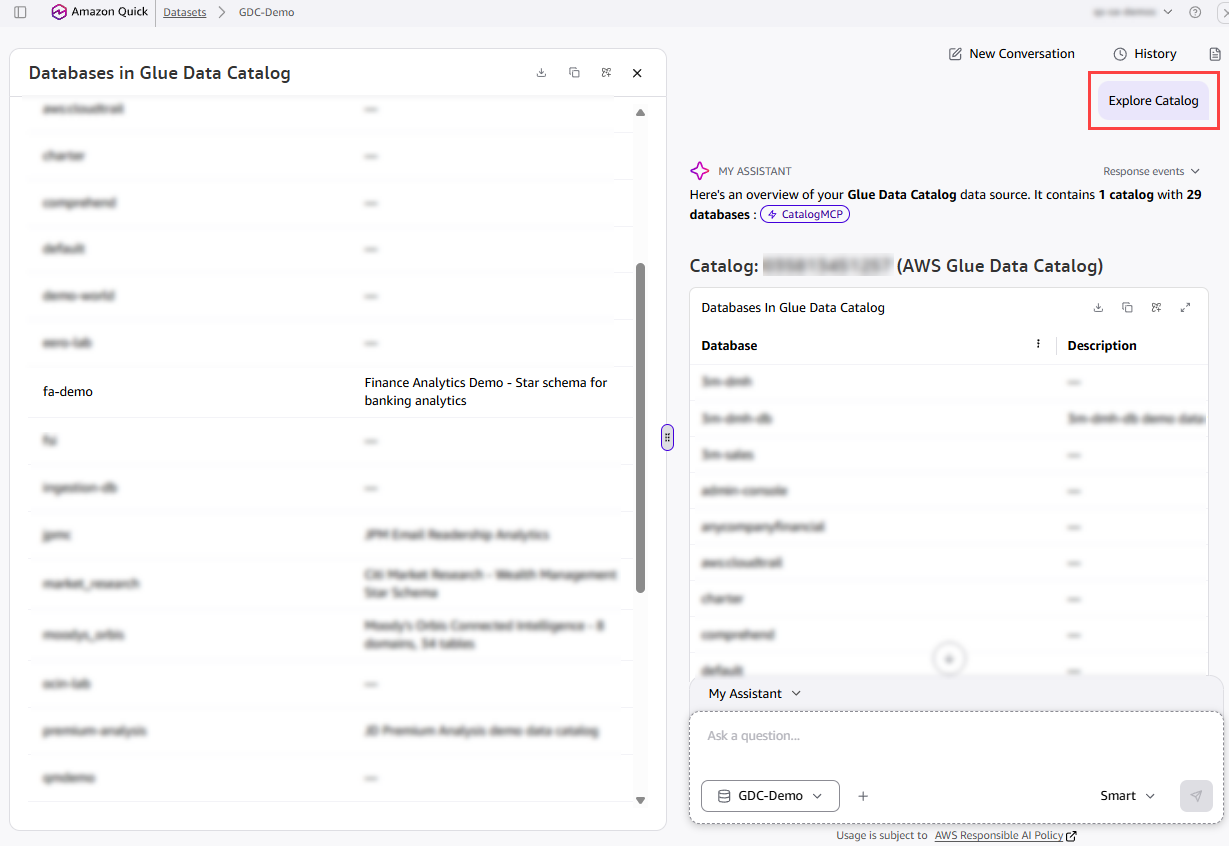
Determine 5: The Agent summarizing obtainable catalogs and databases
Ask the Agent to discover the fa-demo database. The Agent identifies a basic star schema with 7 tables: 2 reality tables (fact_transactions and fact_loans) and 5 dimension tables (dim_account, dim_date_transactions, dim_date_loans, dim_merchant, and dim_txn_category). All are saved as exterior tables in Amazon S3. The Agent acknowledges the schema as masking buyer account transactions and mortgage portfolios, with supporting dimensions for retailers, transaction classes, and date hierarchies.
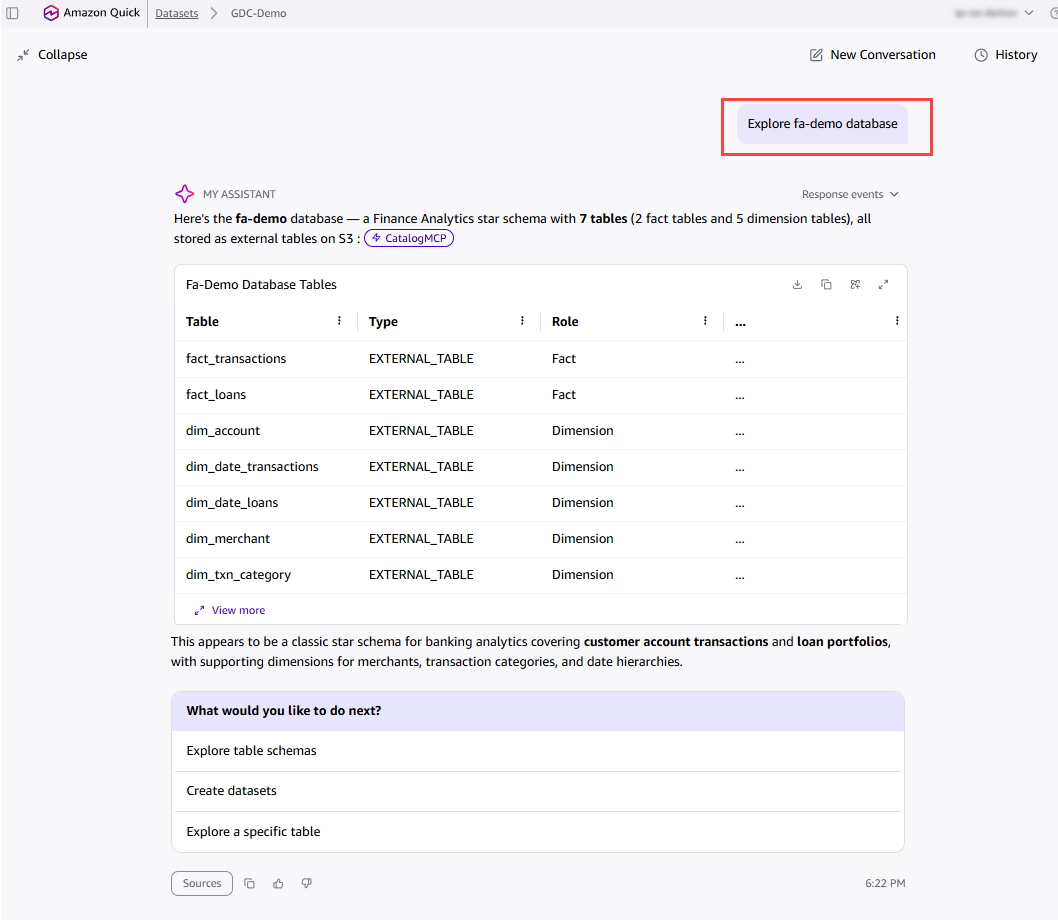
Determine 6: The Agent figuring out the actual fact and dimension tables within the fa-demo database
Ask the Agent to create a star schema diagram for fa-demo. The Agent analyzes the tables, identifies the first and international key relationships, and presents a whole logical knowledge mannequin with a schema abstract. It highlights that dim_account is the shared conformed dimension connecting each reality tables. Select Create datasets & Subject to let the Agent construct every part routinely.
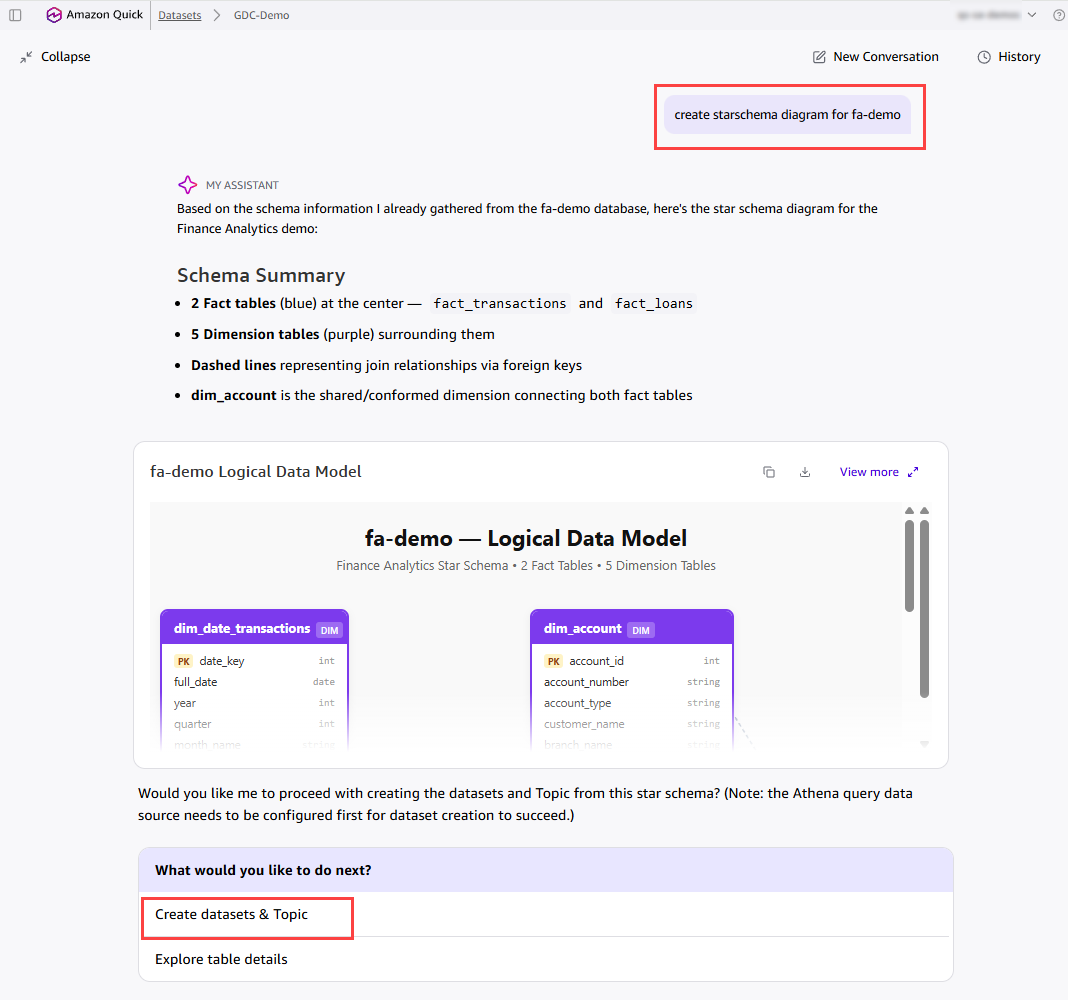
Determine 7: The generated logical knowledge mannequin for the fa-demo schema
The Agent creates a completely configured Subject with all Datasets and relationships in place. On this instance, it creates the “Monetary Analytics” Subject with all seven Datasets from the fa-demo database and 6 preconfigured star schema joins. Every Dataset carries its inherited enterprise description, and the be part of relationships between the actual fact and dimension tables are validated routinely. The Subject is instantly prepared for pure language Q&A, so you possibly can ask questions like “What’s the complete transaction quantity by service provider class?” or “Present me delinquent loans by threat ranking.”
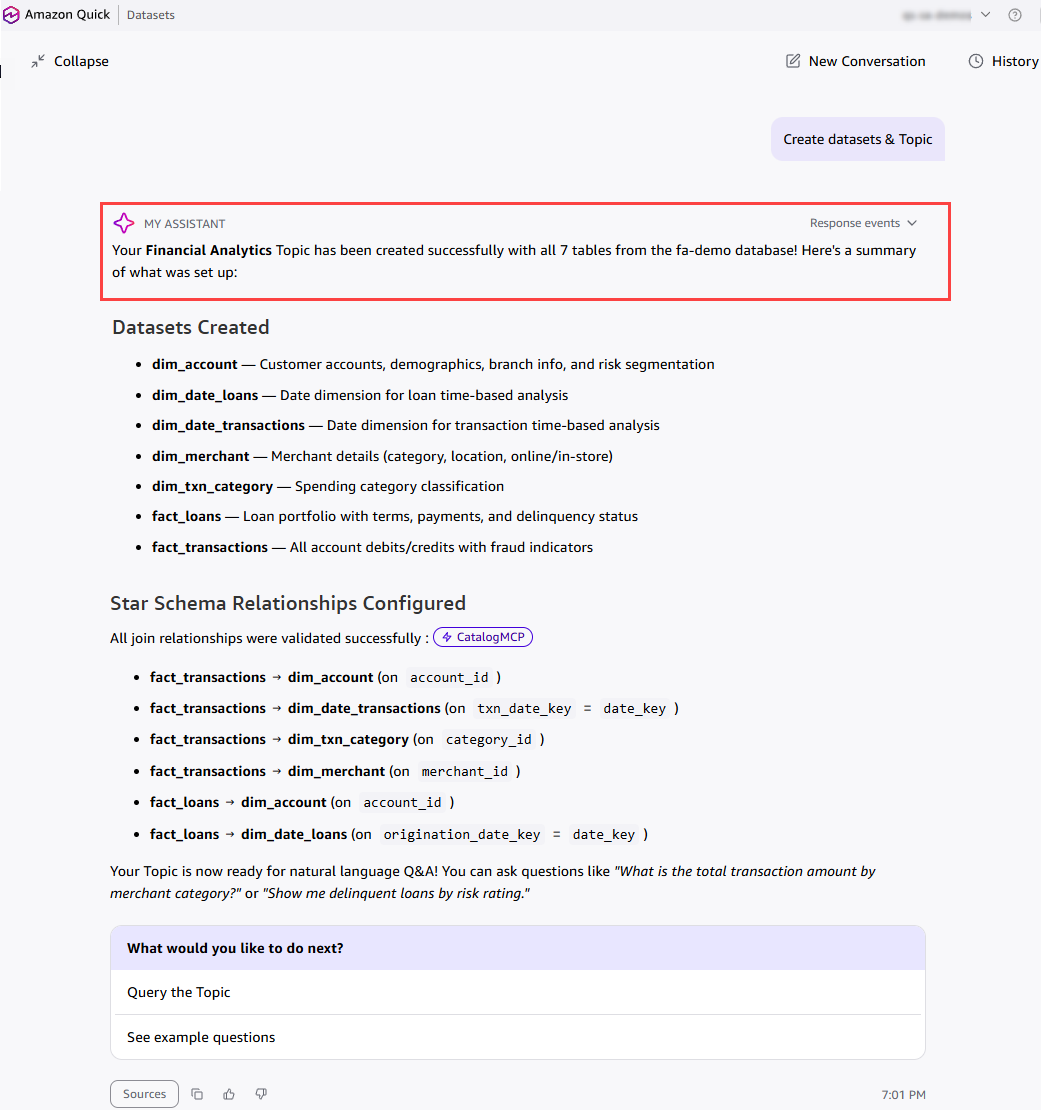
Determine 8: The absolutely configured Monetary Analytics Subject
Now, let’s see how the Monetary Analytics Subject created from the Glue Knowledge Catalog works in motion. With the Subject pinned as context, finish customers can ask questions in plain language and get grounded solutions immediately. For instance, a consumer can ask “Whole transaction quantity by service provider class” and the Agent returns a ranked breakdown with key highlights. The consumer can then comply with up with “Delinquent loans by threat ranking” to see a risk-level abstract with insights. As a result of the Datasets and relationships have been inherited from the catalog, each reply is backed by the trusted schema, joins, and enterprise definitions outlined upstream. That is the facility of the Agentic Catalog Expertise: curators outline the context boundary as soon as, and each finish consumer can discover the information conversationally from there.
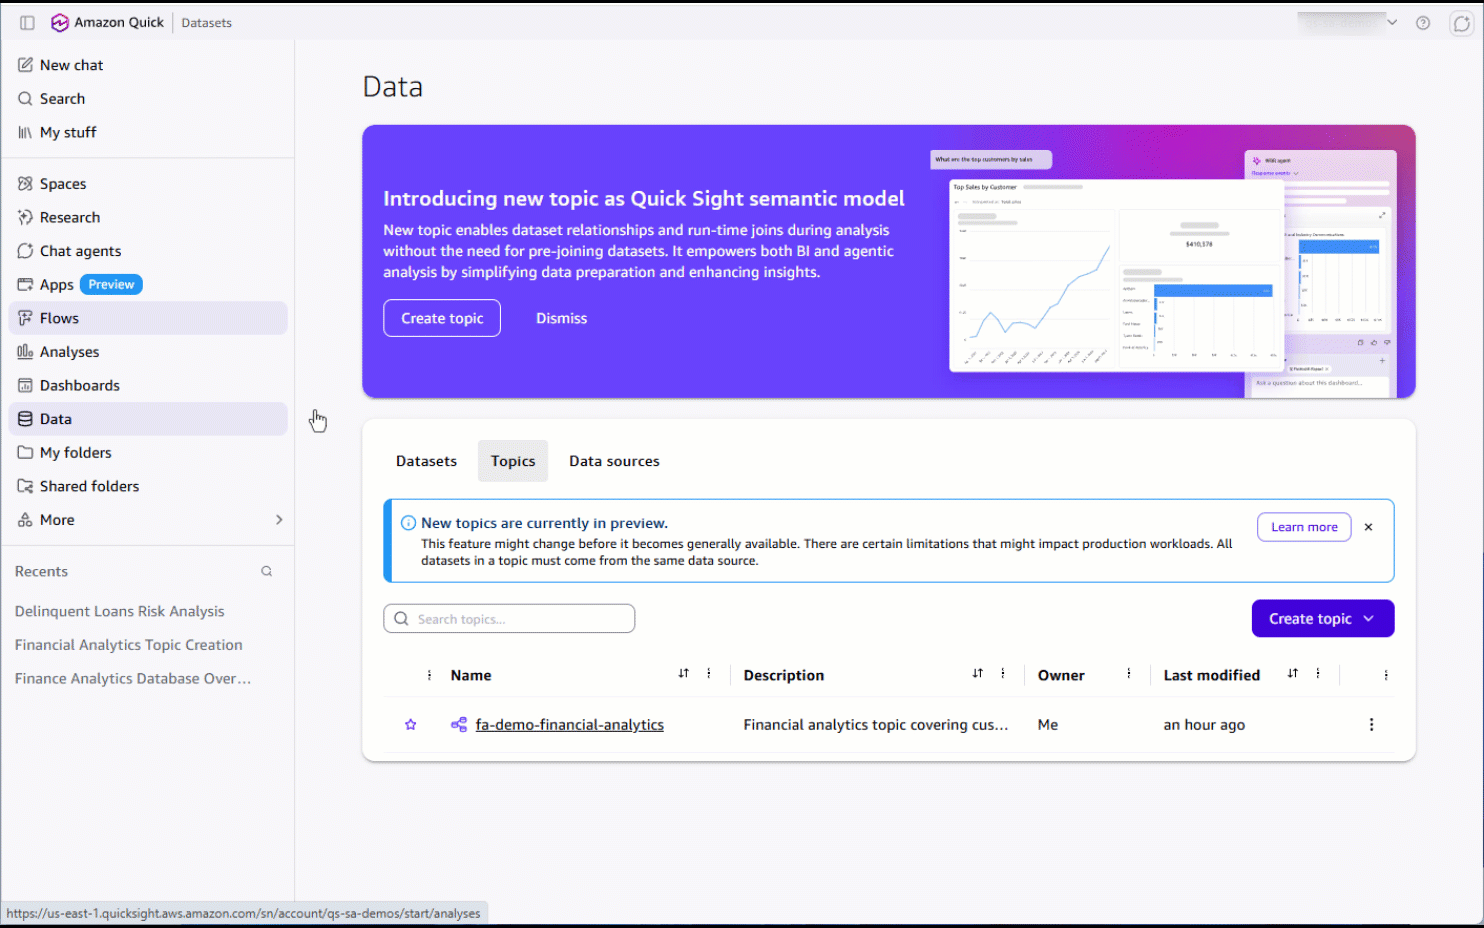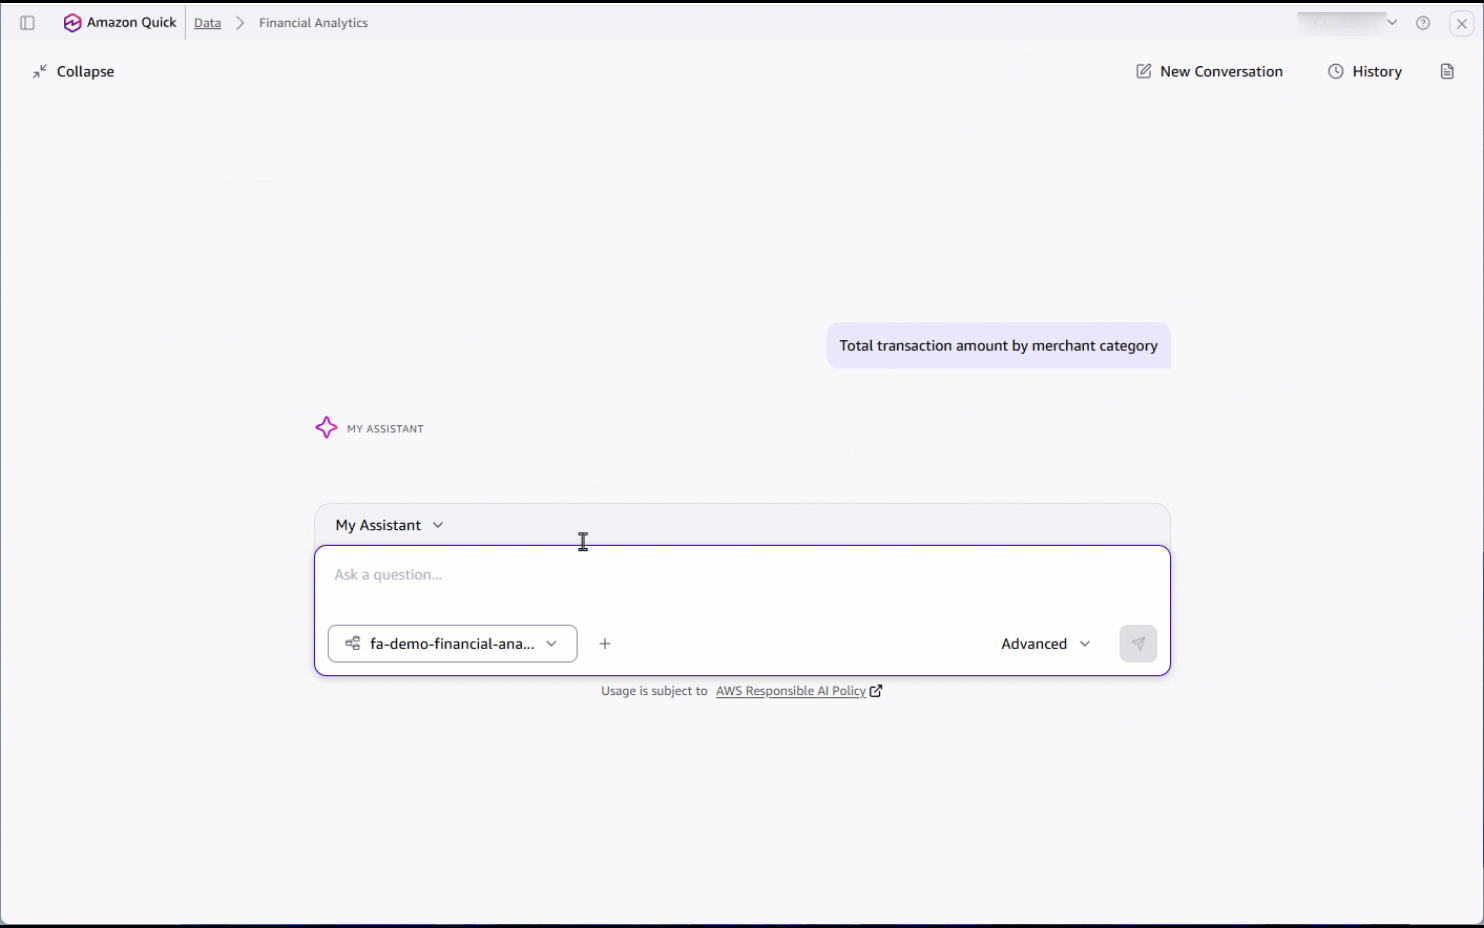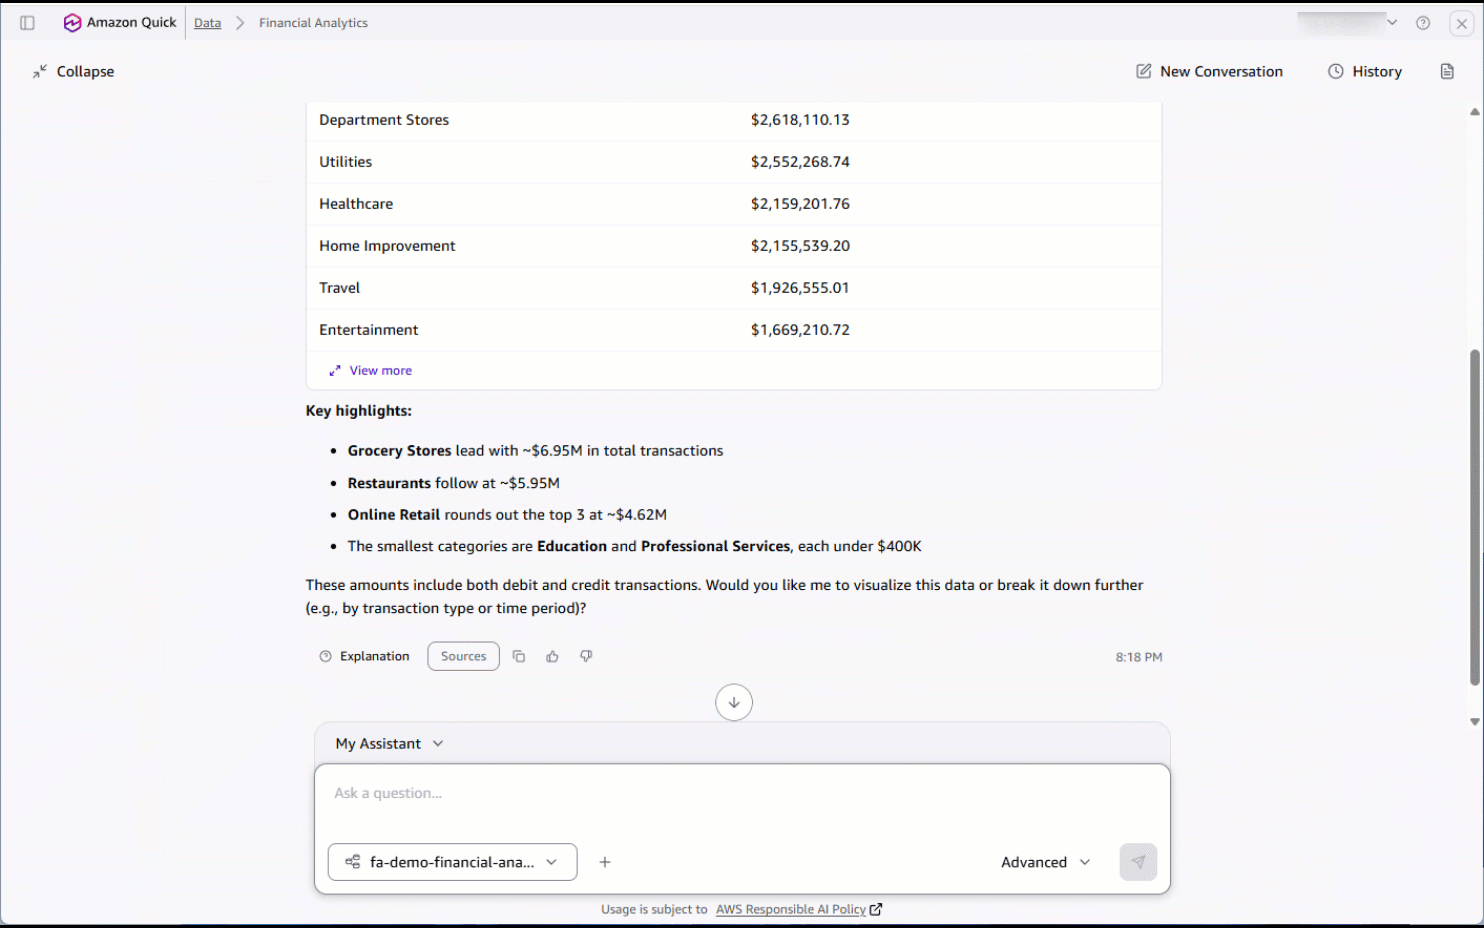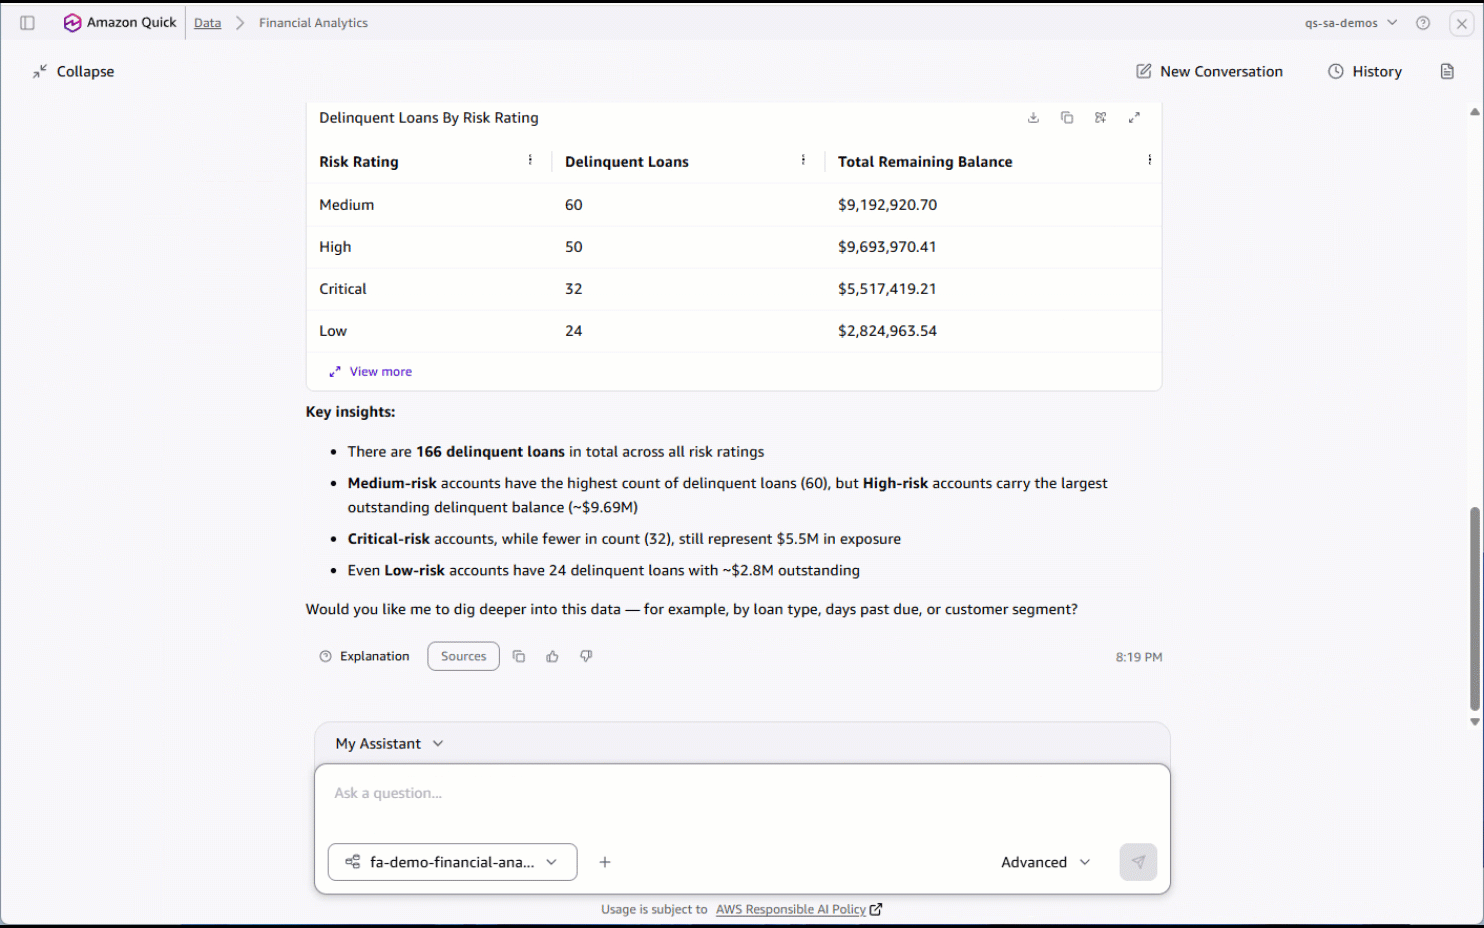
Determine 9: Asking pure language questions towards the Monetary Analytics Subject
Connecting to Databricks Unity Catalog
The identical expertise works with Databricks Unity Catalog. Here’s a fast instance that reveals the complete move, from configuring the connection to creating Datasets and a Subject.
Create a Databricks Unity Catalog knowledge supply, after which select Discover knowledge to launch the Fast Agent. The Agent summarizes the catalog, and with a single affirmation it creates the Datasets and a Subject with the star schema joins already configured.
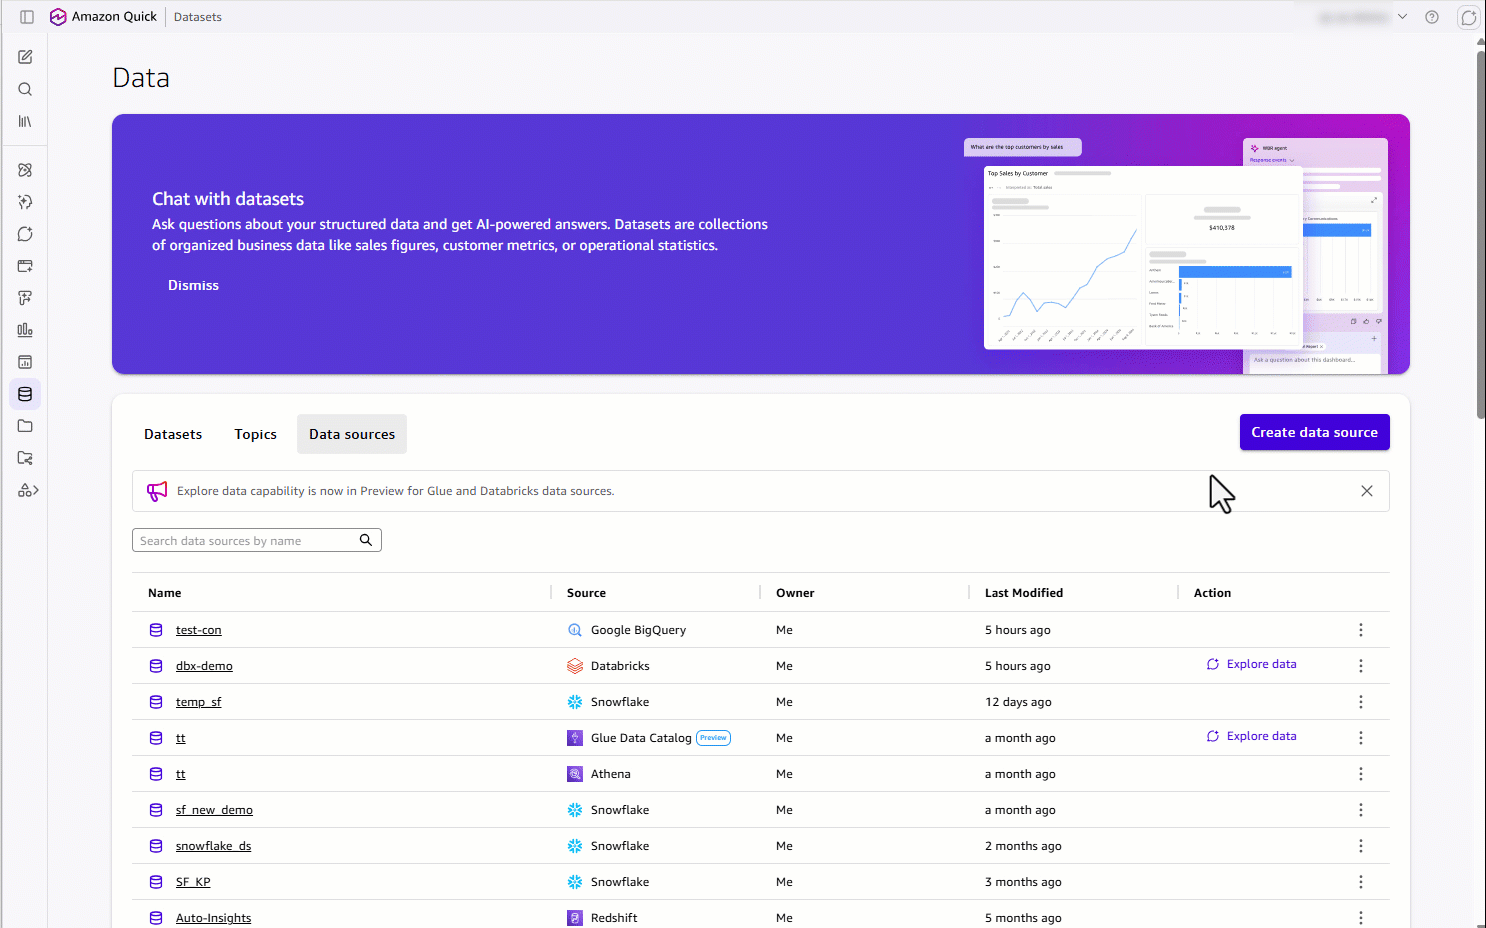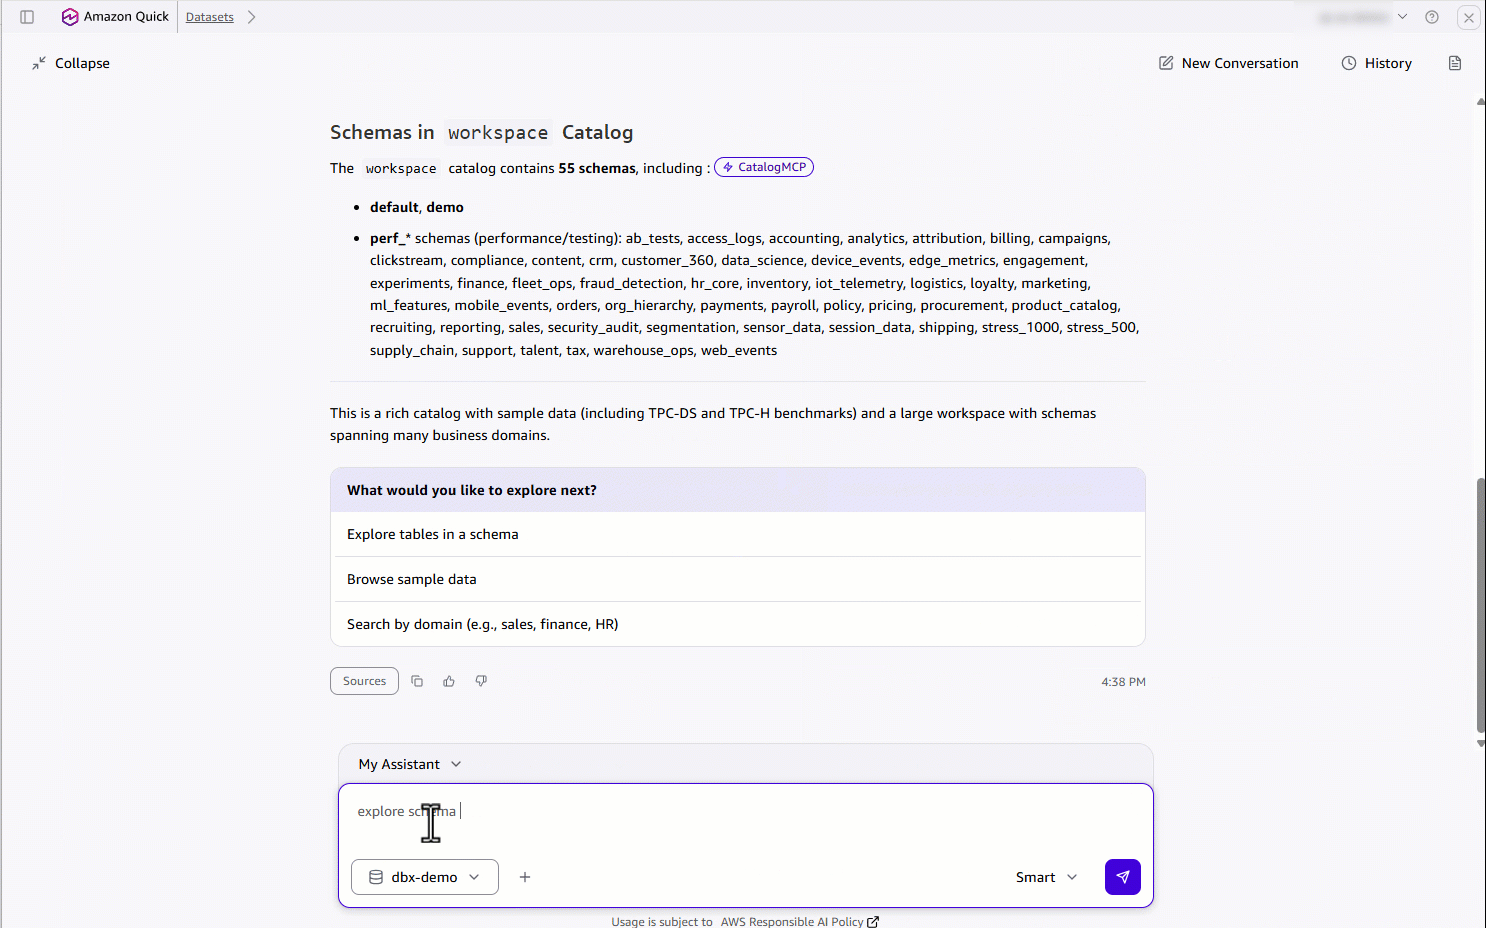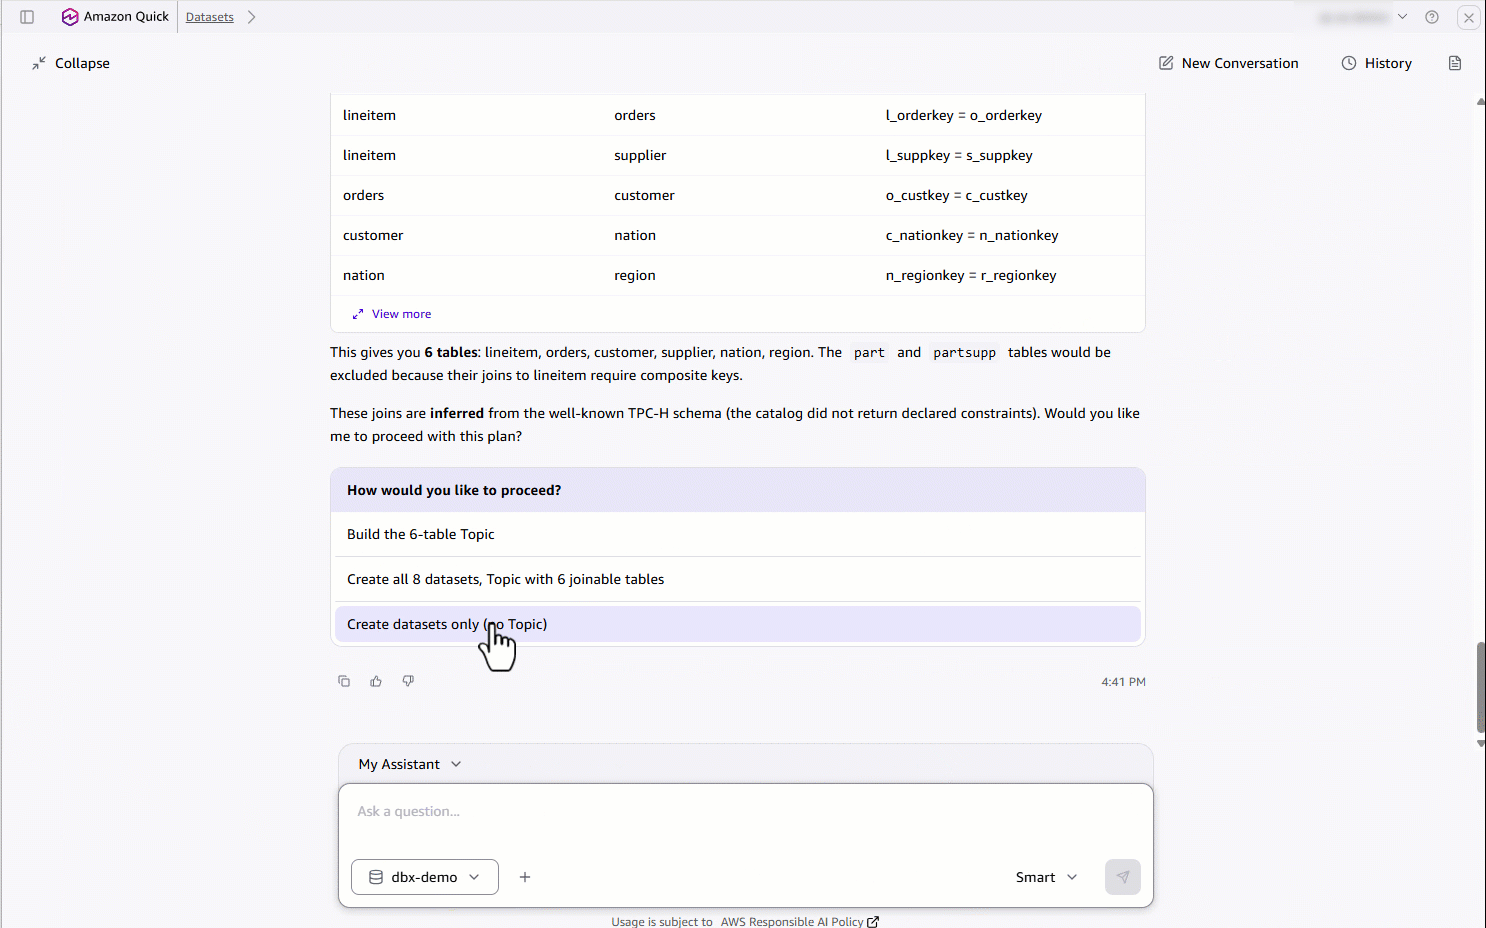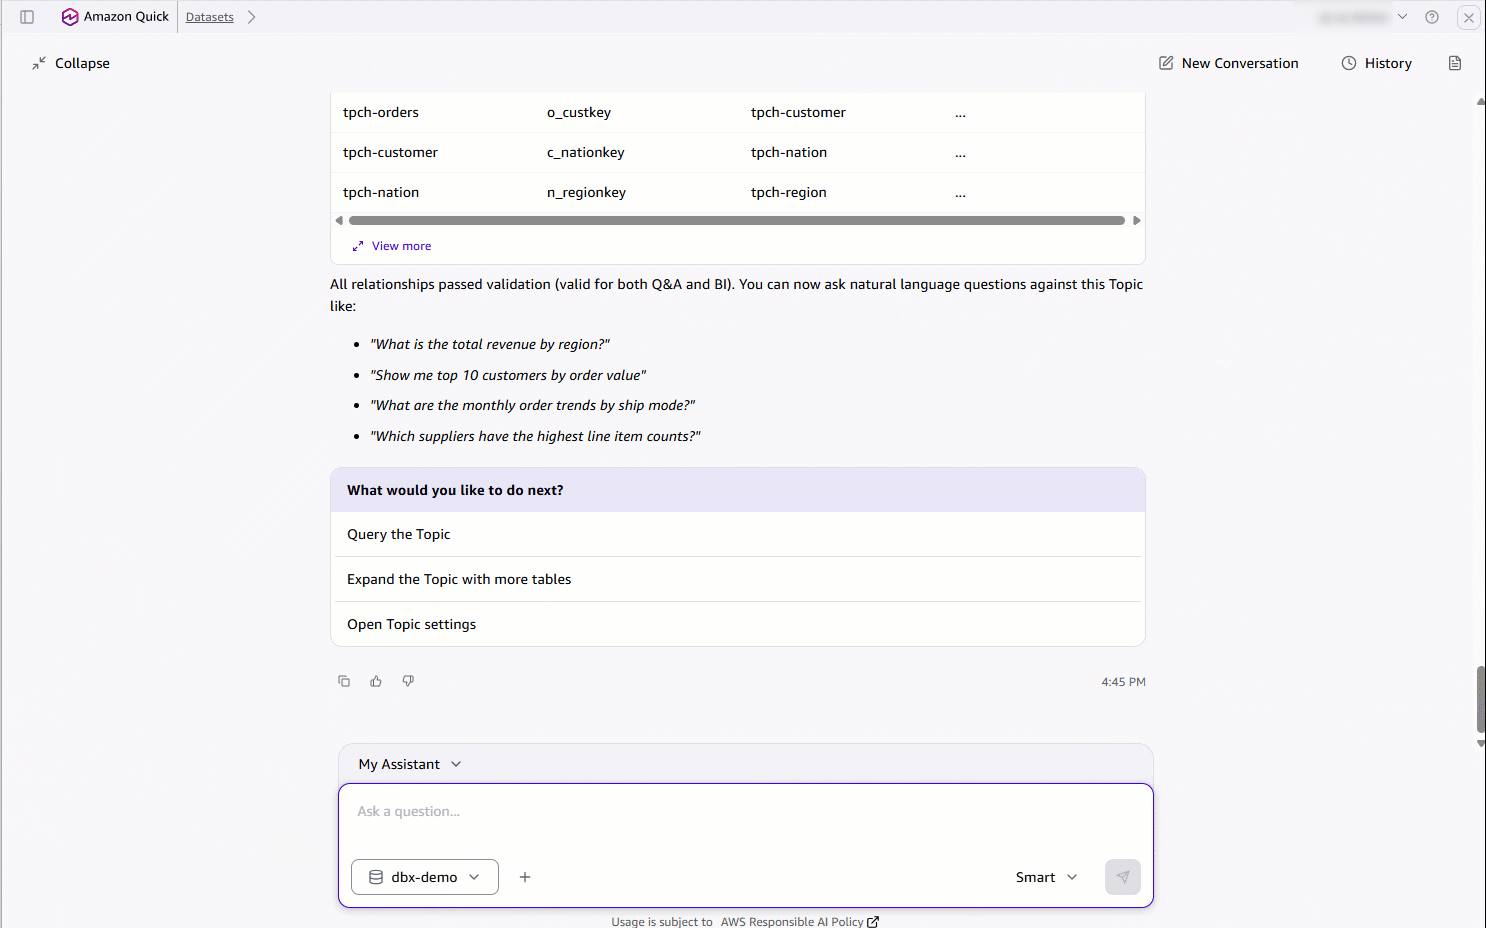
Determine 10: Creating Datasets and a Subject from Databricks Unity Catalog
After the Subject is prepared, finish customers can ask advanced questions that span a number of associated tables. On this instance, the Agent solutions “High 5 manufacturers by income per area” by becoming a member of throughout the Subject relationships, and returns a grounded, visible end result.
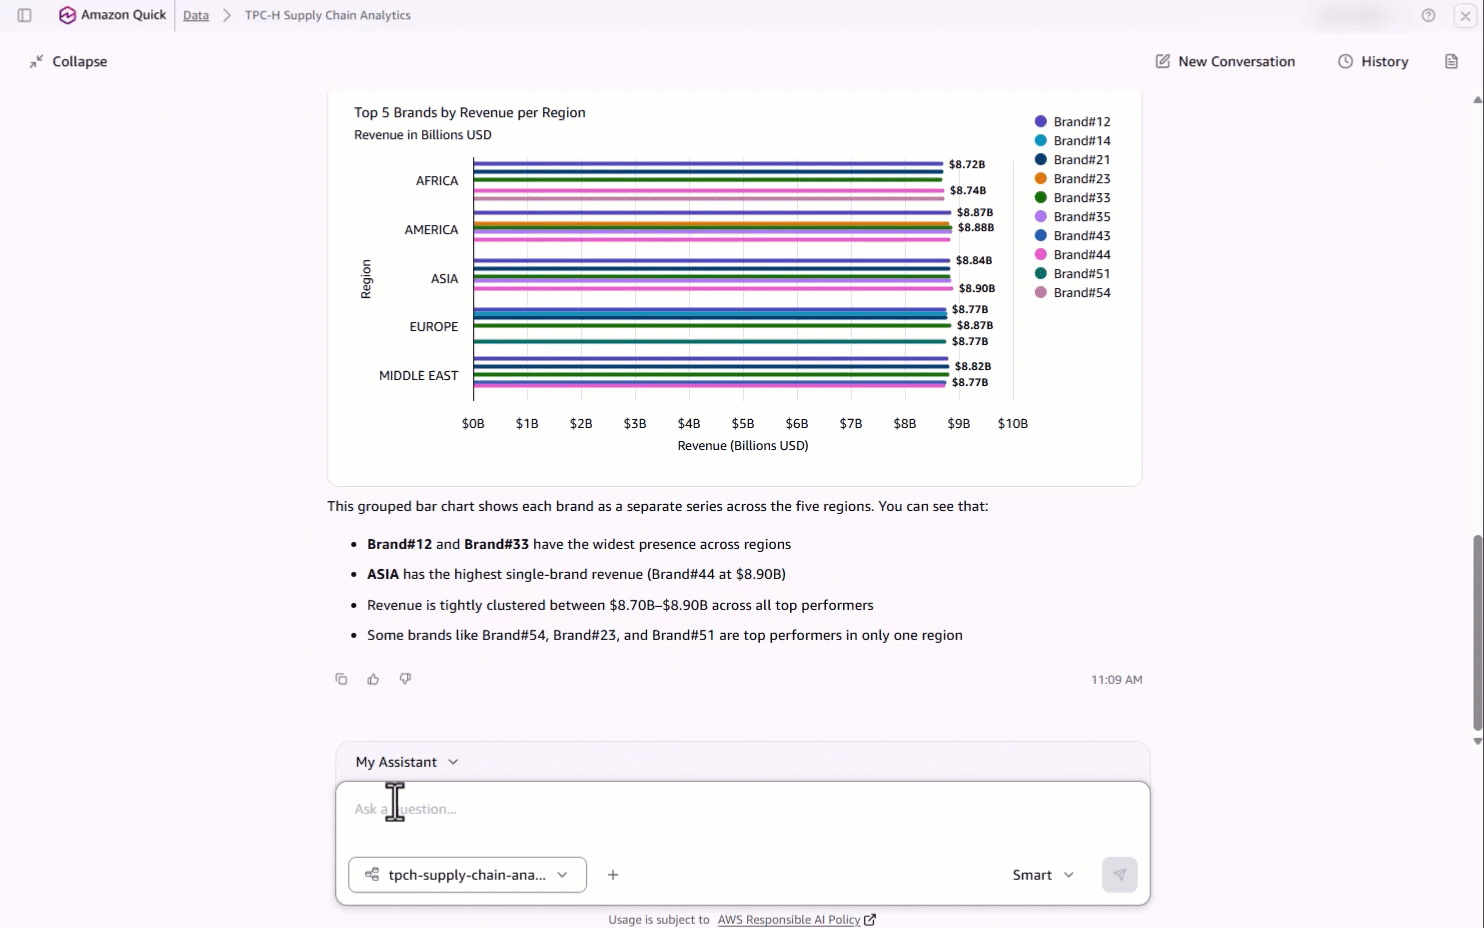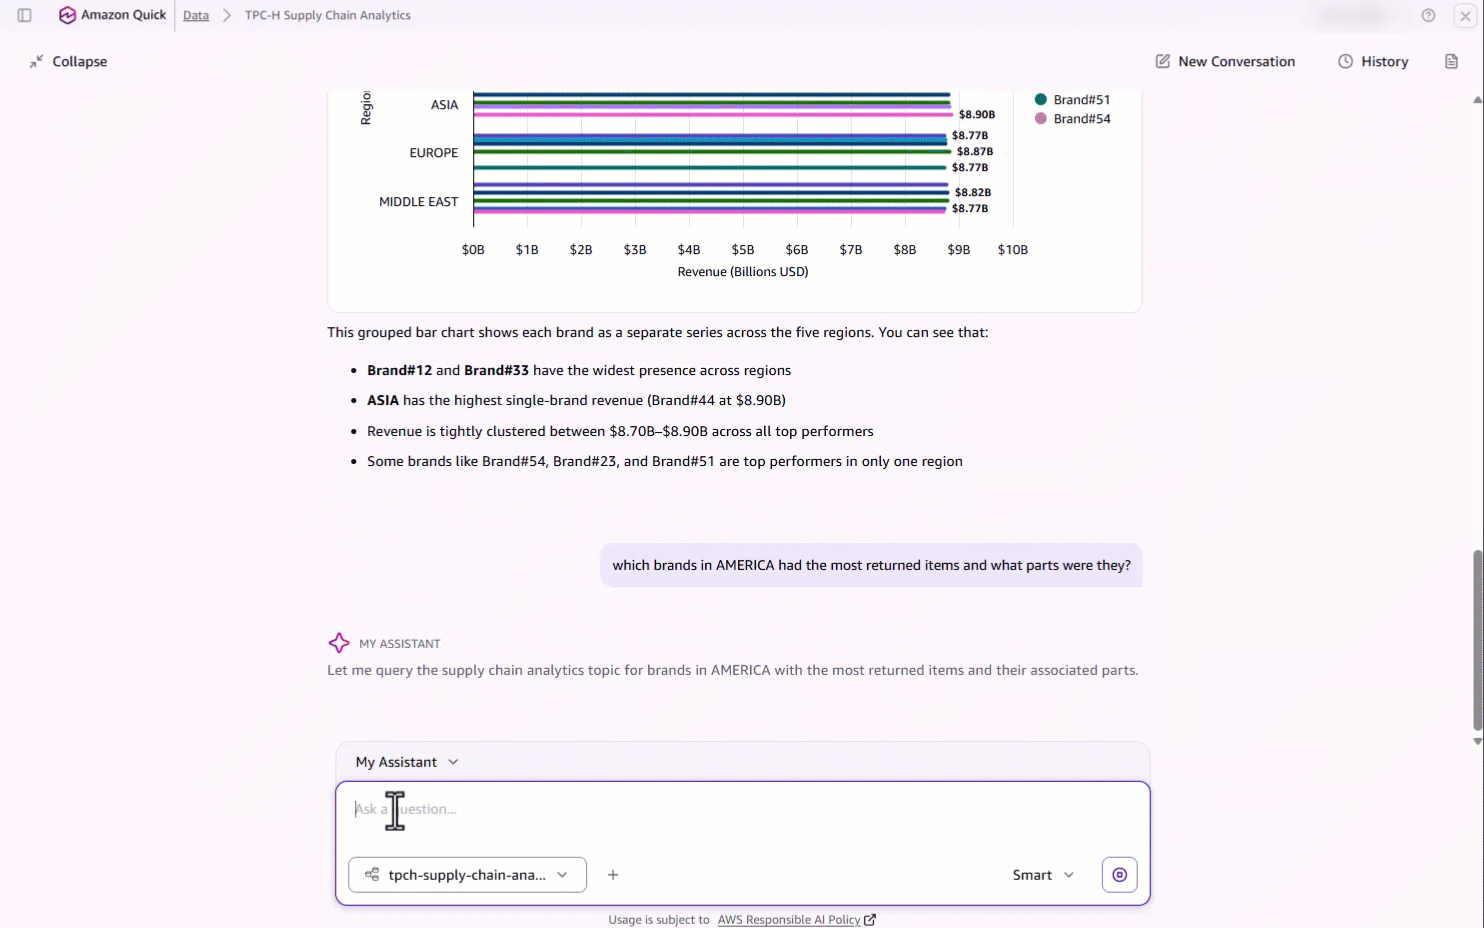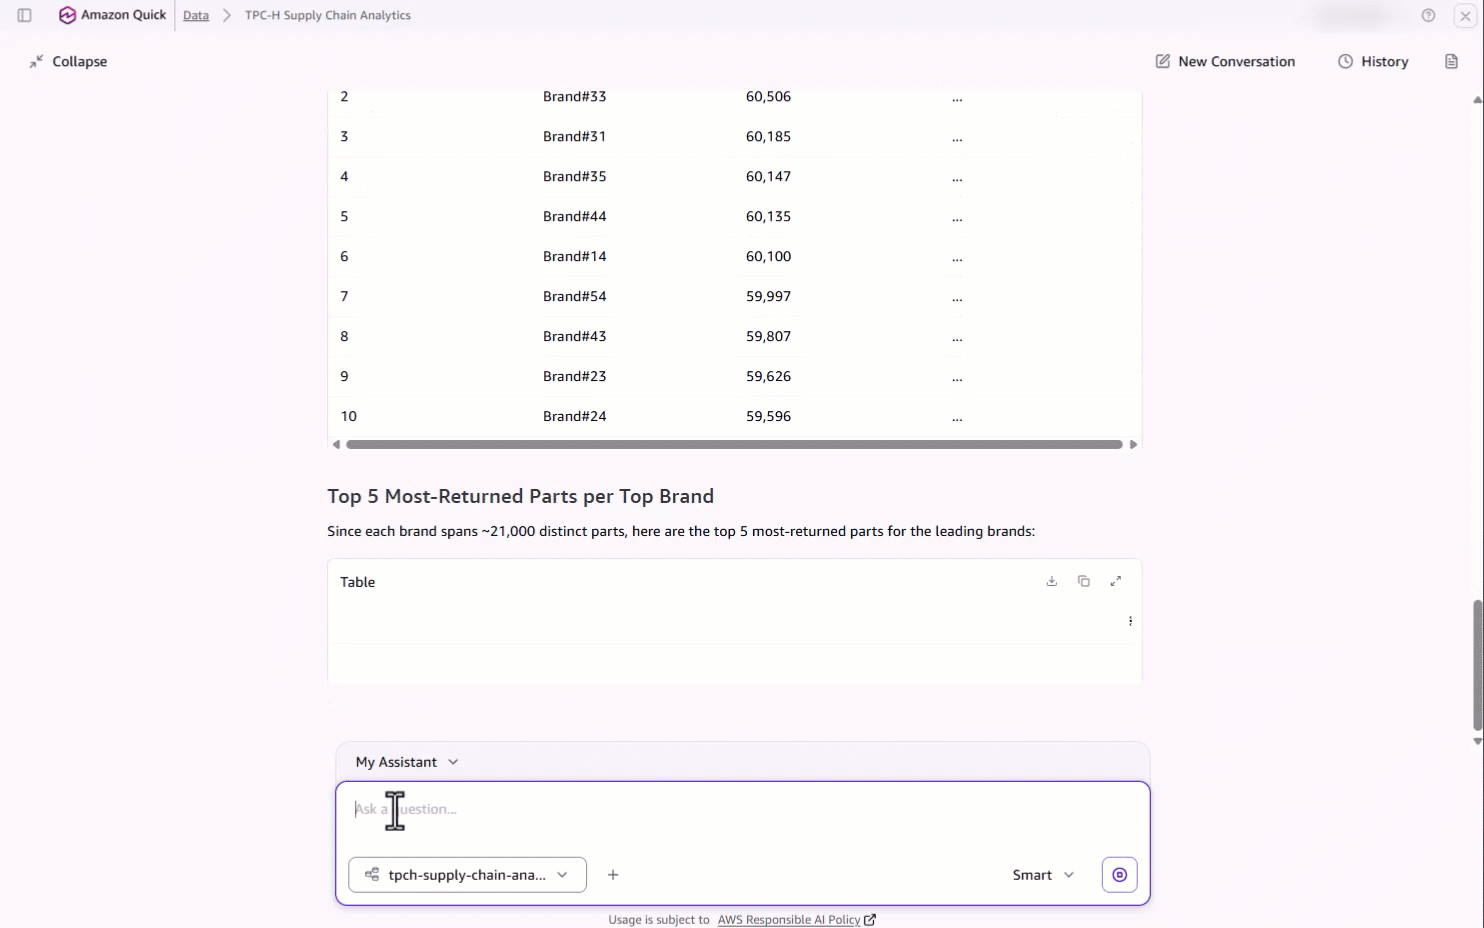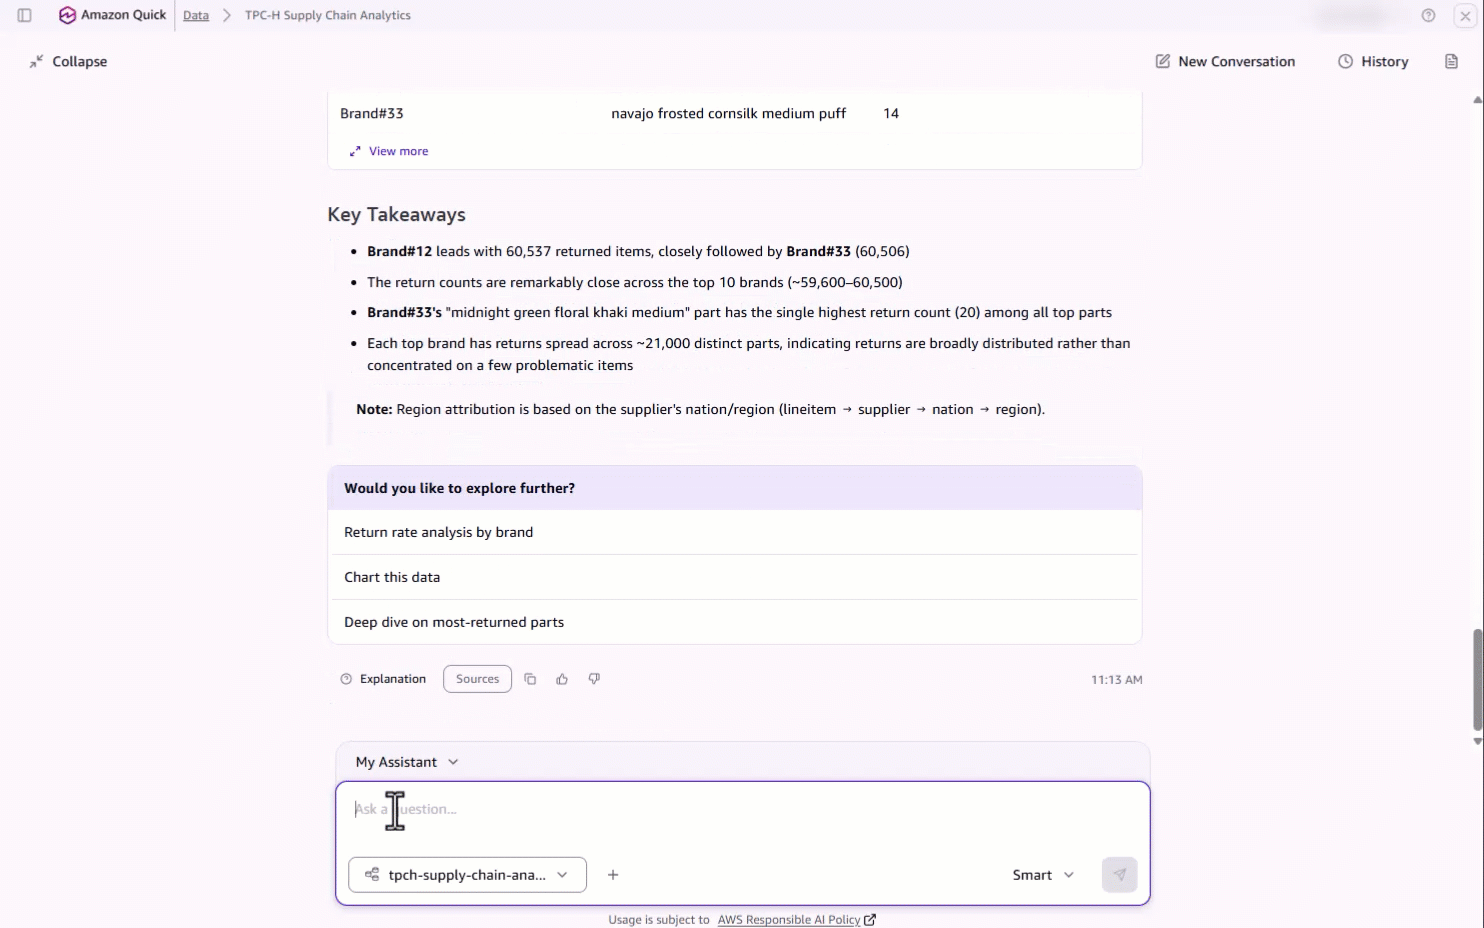
Determine 11: Answering a multi-table query throughout Subject relationships
The end result
Curators ship trusted knowledge, full enterprise context, and production-ready AI solutions and dashboards in a fraction of the time. Finish customers get grounded solutions they will belief, backed by Gold-standard knowledge with full semantic lineage.
From weeks of handbook configuration to minutes of guided dialog.
That’s the Agentic Catalog Expertise in Amazon Fast.
In regards to the authors
Srikanth Baheti
Srikanth is a Senior Supervisor for Amazon QuickSight. He began his profession as a marketing consultant and labored for a number of personal and authorities organizations. Later he labored for PerkinElmer Well being and Sciences & eResearch Expertise Inc, the place he was chargeable for designing and growing excessive visitors internet functions and extremely scalable and maintainable knowledge pipelines for reporting platforms utilizing AWS providers and serverless computing.
Vignessh Baskaran
Vignessh is a Sr. Technical Product Supervisor in Amazon Fast, the place he owns AI-powered knowledge merchandise for connectivity, catalog & semantics, and knowledge preparation. He has over a decade of expertise in growing large-scale knowledge and analytics options. Outdoors of labor, he enjoys watching Cricket, taking part in Racquetball and exploring completely different cuisines in Seattle.
Ashok Dasineni
Ashok is a Options Architect for Amazon Fast Suite. Earlier than becoming a member of AWS, Ashok labored with shoppers and organizations within the banking and monetary area, specializing in fraud analysis and prevention. He designed and applied revolutionary options to enhance enterprise course of, scale back value, and improve income, serving to corporations around the globe obtain their highest potential by way of knowledge.
Salim Khan
Salim is a Senior Worldwide Generative AI Options Architect for Amazon Fast at AWS. He has over 16 years of expertise implementing enterprise enterprise intelligence options. At AWS, Salim works with prospects globally to design and implement AI-powered BI and generative AI capabilities on Amazon Fast. Previous to AWS, he labored as a BI marketing consultant throughout business verticals together with Automotive, Healthcare, Leisure, Shopper, Publishing, and Monetary Companies, delivering enterprise intelligence, knowledge warehousing, knowledge integration, and grasp knowledge administration options.