


AI-agent improvement has progressed by way of overlapping phases: immediate engineering, context engineering, software use, autonomous loops, reminiscence programs, and multi-agent coordination. A more recent focus is graph engineering, which treats AI purposes as explicitly designed workflows moderately than a single autonomous agent.
Graph engineering defines how brokers, instruments, deterministic features, validators, knowledge sources, and people coordinate to finish duties. It’s broader than LangGraph, GraphRAG, or data graphs. On this article, we study graph engineering from an implementation perspective and construct a dependable LangGraph workflow.
What Is Graph Engineering?
Graph engineering is the observe of representing an AI utility as an executable graph containing brokers, instruments, features, insurance policies, knowledge programs, evaluators, and human selections.
A sensible definition is:
Graph engineering is the design of nodes, dependencies, state transitions, execution routes, validation gates, restoration paths, and management boundaries inside an agentic system.
Take into account an AI system that researches a technical subject, writes a report, verifies its claims, and sends it to a consumer.
A single-agent implementation would possibly appear to be this:
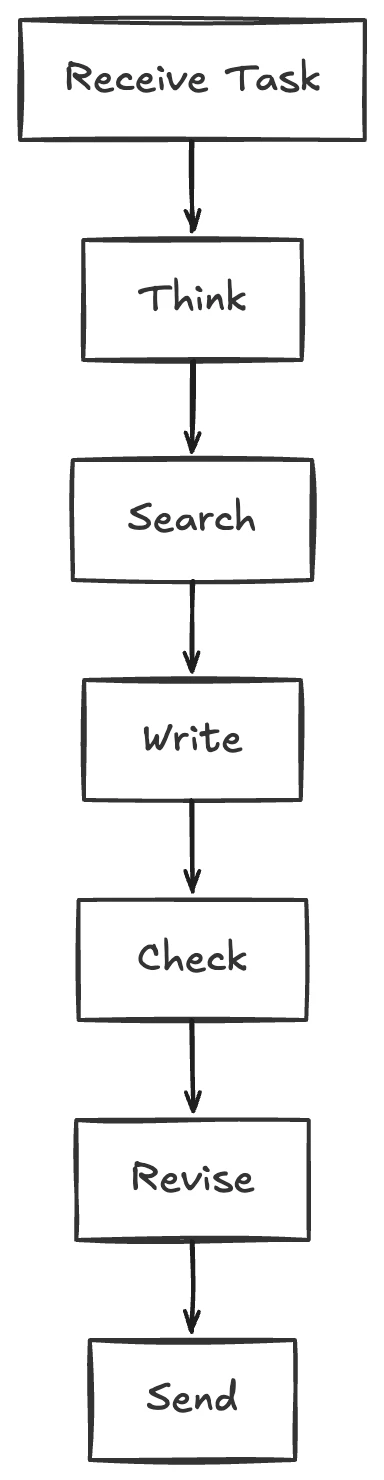
Most of these transitions are hidden contained in the mannequin’s context. The mannequin decides when to look, when sufficient proof has been collected, whether or not the output is appropriate, and when the duty is full.
A graph-engineered implementation makes these obligations express:
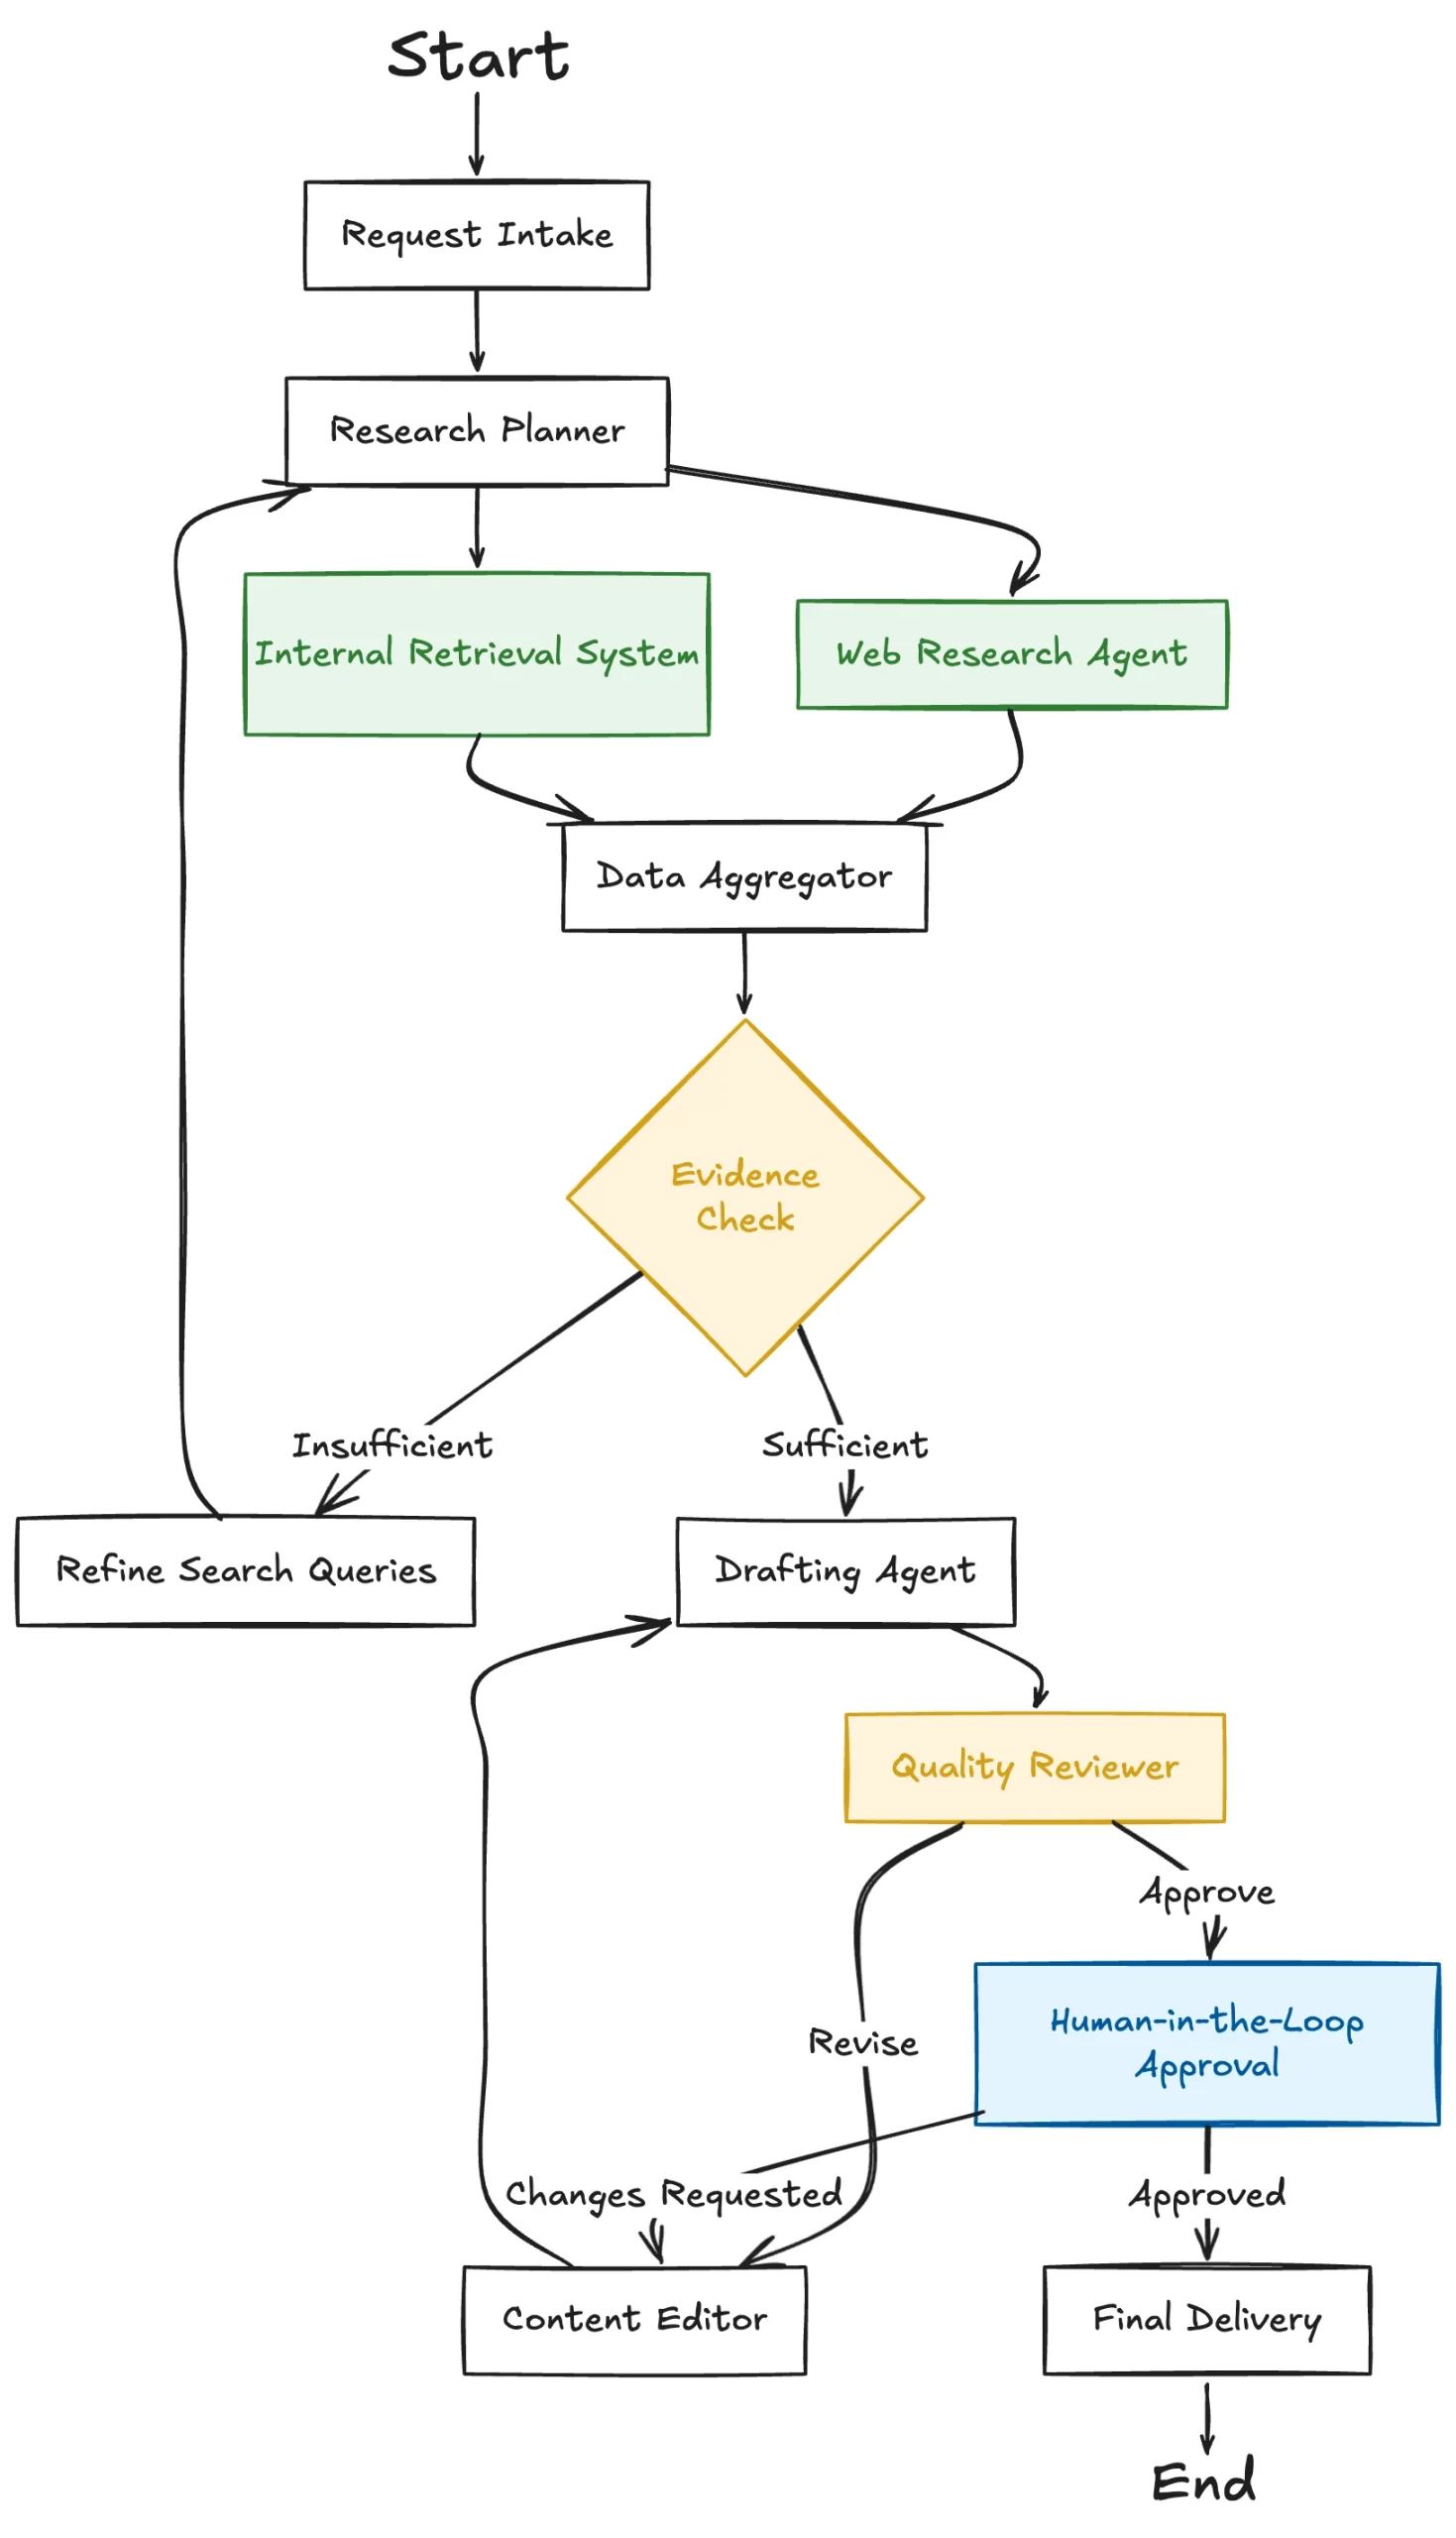
Right here, the graph defines which transitions are permitted. Particular person brokers can nonetheless cause autonomously inside their nodes, however they don’t management your complete system.
Core Parts of Graph Engineering
1. Nodes
A node is a bounded unit of execution.
A node could include:
An LLM name
A whole tool-using agent
A Python perform
A retrieval operation
A database question
An API request
A coverage examine
A take a look at suite
A human approval request
A subgraph
Not each node ought to be an AI agent.
Identified enterprise guidelines ought to usually stay deterministic. An LLM is helpful the place semantic interpretation, era, planning, or ambiguity is concerned.
For instance, calculating whether or not an bill exceeds an approval threshold doesn’t require an LLM. Understanding whether or not an e mail represents a refund request could require one.
2. Edges
Edges outline which nodes can execute after one other node.
Frequent edge varieties embrace:
Direct edges
Conditional edges
Parallel edges
Looping edges
Error edges
Human-controlled edges
Occasion-triggered edges
An edge represents a dependency or management rule.
For instance:
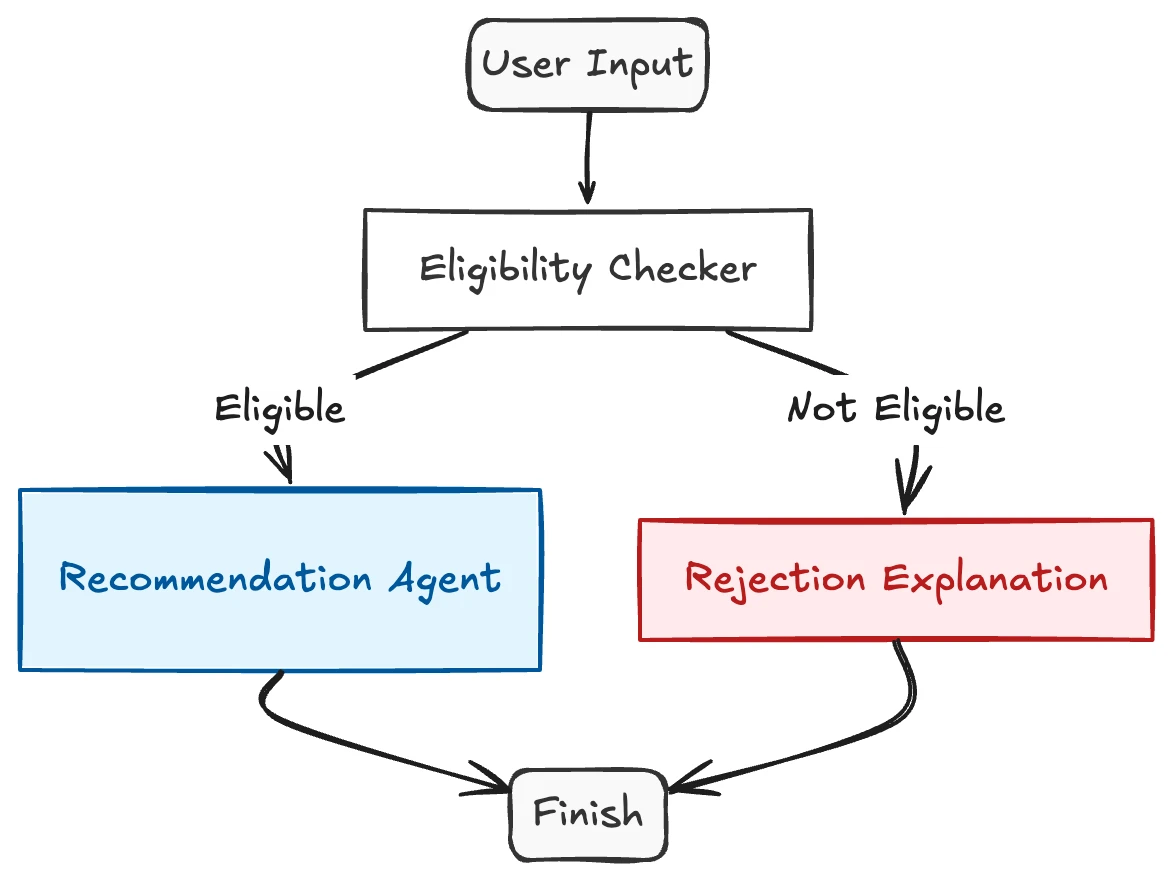
The routing situation could also be applied by way of deterministic Python logic or an LLM classifier.
3. State
State is the shared document carried by way of the graph.
It might include:
class WorkflowState(TypedDict):
user_request: str
task_plan: checklist[str]
retrieved_evidence: checklist[str]
draft: str
validation_result: dict
retry_count: int
approval_status: str
Typed state makes the inputs and outputs of nodes seen. It additionally reduces the necessity to cross an entire dialog transcript to each agent.
LangGraph makes use of stateful graphs to mix deterministic steps with LLM-driven steps. It additionally gives persistence, streaming, human-in-the-loop controls, and assist for long-running execution.
4. State Reducers
Parallel nodes could replace the identical state area.
Suppose three analysis brokers return proof concurrently:
{
“proof”: [“Source A”]
}
{
“proof”: [“Source B”]
}
{
“proof”: [“Source C”]
}
The graph wants a rule for combining these updates.
A reducer could append lists, merge dictionaries, choose the newest worth, or apply a customized conflict-resolution coverage.
And not using a clear reducer, parallel updates can overwrite each other or create inconsistent state.
5. Routes and Guard Circumstances
A route determines which edge ought to run.
A guard situation checks whether or not a transition is allowed.
def route_after_review(state):
if state[“grounding_score”] < 0.8:
return “research_again”
if state[“risk_level”] == “excessive”:
return “human_review”
return “finalize”
Arduous constraints shouldn’t be hidden inside prompts. They need to be enforced in routing code every time attainable.
6. Checkpoints
A checkpoint shops a snapshot of the graph state.
Checkpoints permit a workflow to:
Resume after interruption
Get better from failure
Await human suggestions
Examine earlier states
Replay a workflow
Help long-running duties
LangGraph separates thread-level checkpoints from long-term shops. Checkpointers protect graph state for a particular execution thread, whereas shops preserve utility knowledge throughout threads.
7. Interrupts
An interrupt pauses the graph and requests exterior enter.
Frequent makes use of embrace:
Approval earlier than sending an e mail
Evaluate earlier than publishing content material
Affirmation earlier than issuing a refund
Enhancing generated parameters
Offering lacking data
LangGraph interrupts save the present state and permit execution to renew later utilizing the identical thread identifier. The documentation additionally recommends making certain that uncomfortable side effects earlier than an interrupt are idempotent.
Necessary Agent Graph Patterns
LangGraph and Anthropic describe a number of recurring orchestration patterns for agentic purposes.
Immediate Chaining
Every node processes the output of the earlier node.
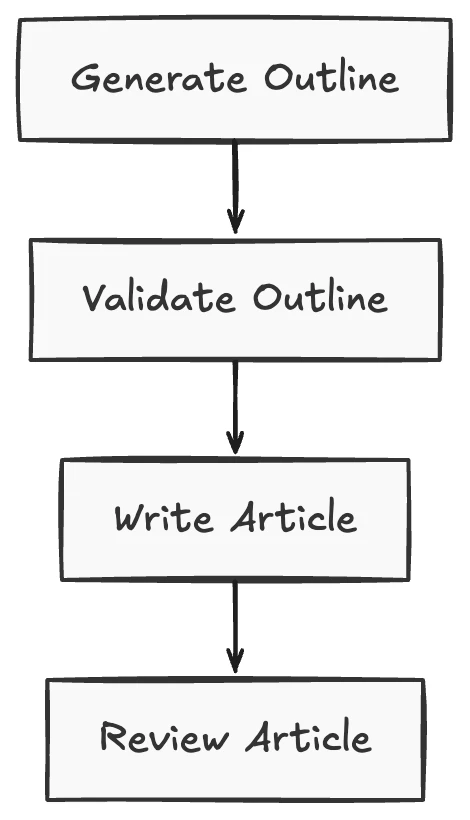
Use it when the duty will be divided into fastened, verifiable levels.
Routing
A router sends the request to a specialised department.
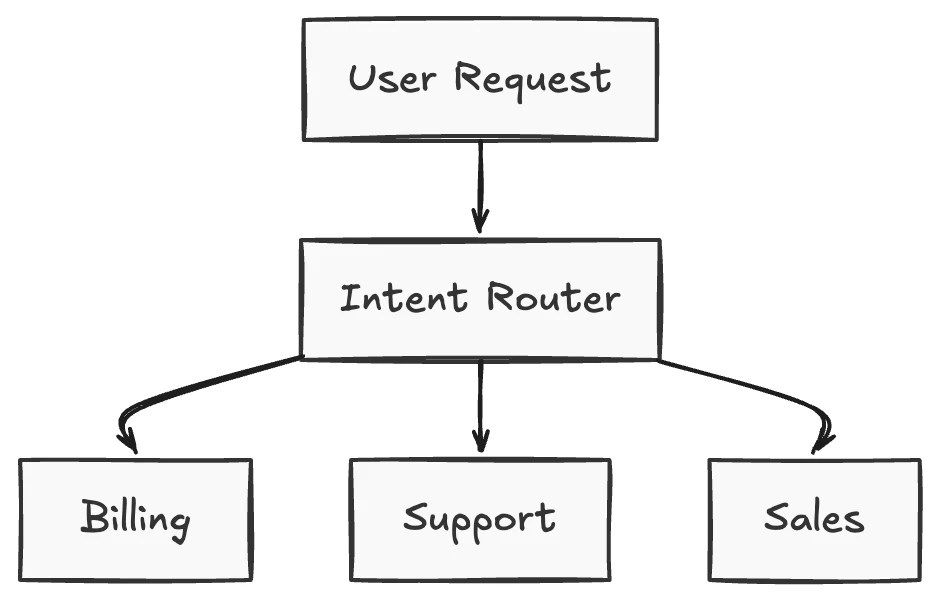
Use deterministic routing when classes are precise. Use model-based routing when classification requires semantic interpretation.
Parallelization
Unbiased duties execute concurrently.
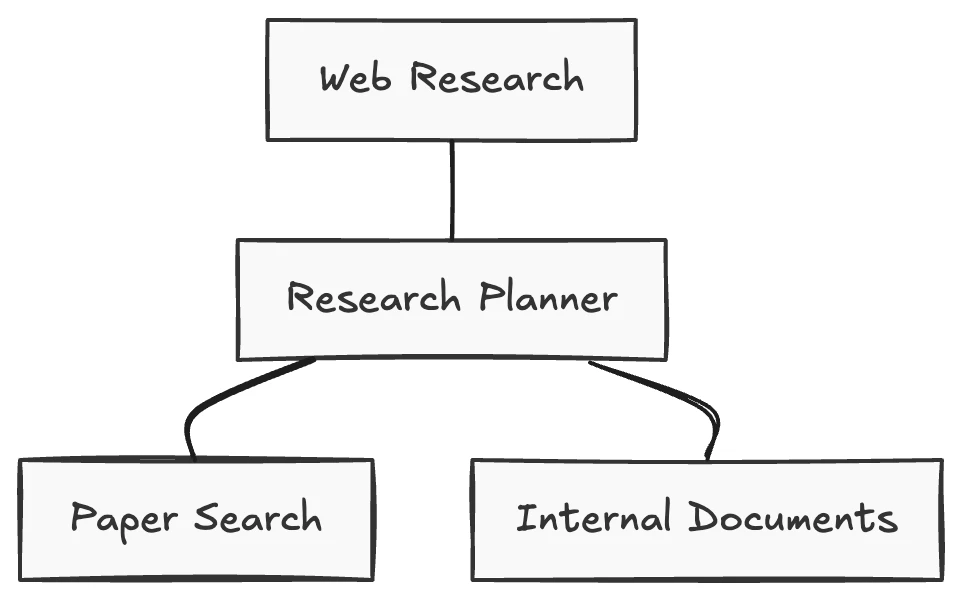
Parallelization can scale back latency and permit totally different brokers to look at separate dimensions of an issue.
Nonetheless, solely unbiased duties ought to run in parallel. Creating parallel branches that secretly rely upon each other produces incomplete or inconsistent outcomes.
Orchestrator-Employee
An orchestrator decomposes a process and delegates components to staff.
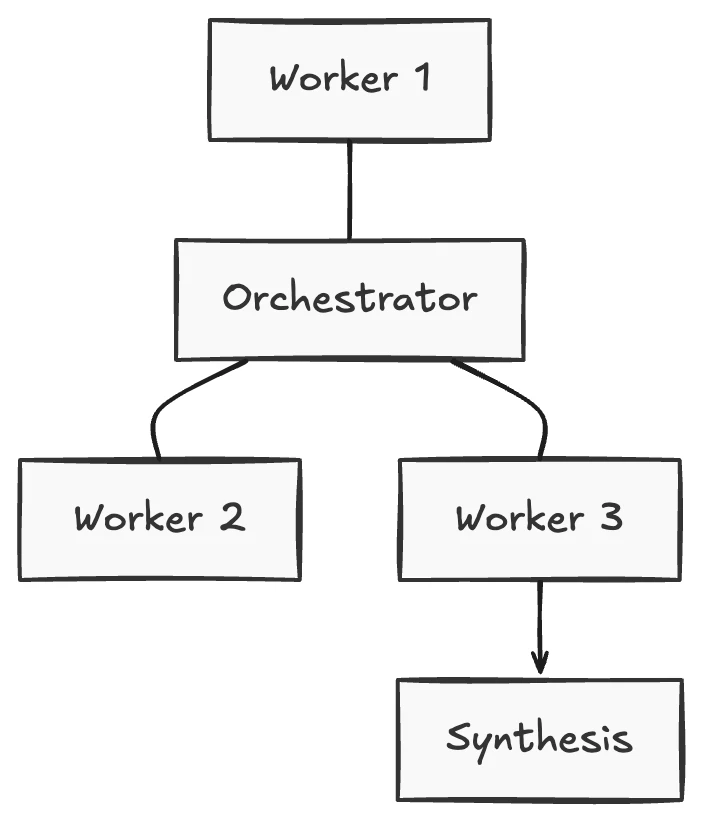
This sample is helpful when the quantity and kind of subtasks can’t be recognized earlier than the request arrives.
The orchestrator ought to primarily plan, assign, and combine. If it instantly performs each software name, the structure turns into one other monolithic agent.
Evaluator-Optimizer
One part generates an artifact whereas one other evaluates it.
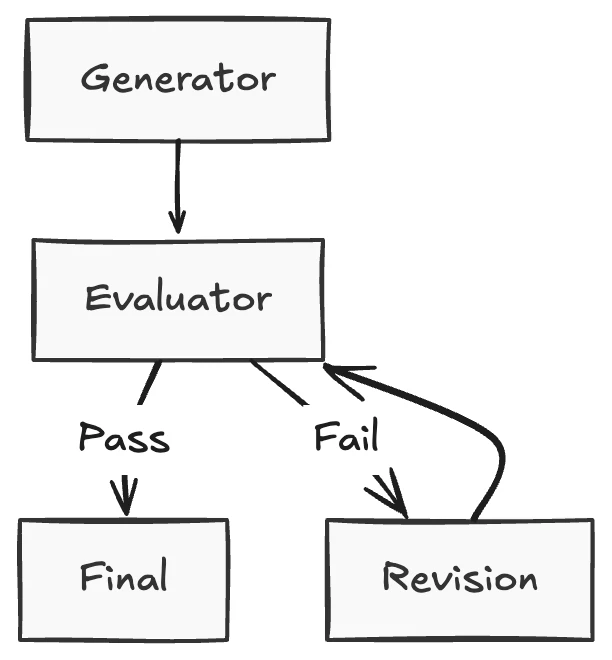
This sample works finest when the analysis standards are clear and revision produces measurable enchancment.
Human-in-the-Loop
A human opinions the workflow earlier than a consequential motion.
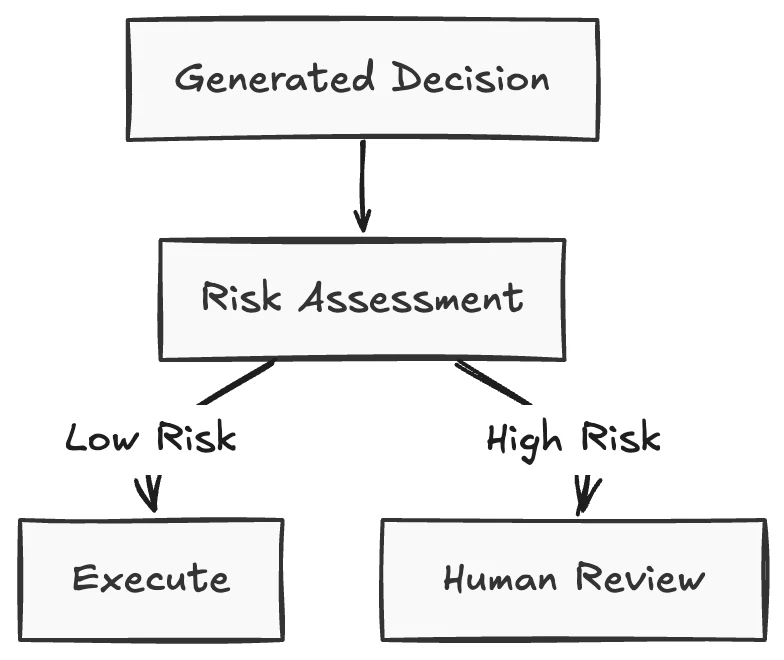
Human evaluate ought to be risk-based. Requiring approval for each innocent step makes the system sluggish with out bettering security.
Arms-On: Constructing a Graph-Engineered Analysis Workflow
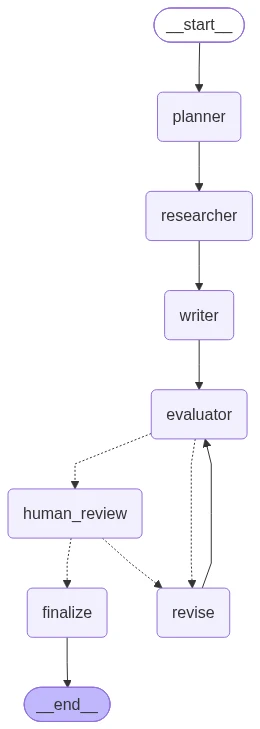
We’ll construct a graph that:
Plans the duty
Collects proof
Writes a draft
Evaluates the draft
Revises weak drafts
Requests human approval
Finalizes the output
Set up the Dependencies
pip set up -U langgraph langchain langchain-openai
Set up the combination package deal to your chosen mannequin supplier individually.
Set a supported mannequin within the surroundings:
model_name =”openai:gpt-4.1-mini”
Outline the State and Mannequin
import os
from typing import Literal, TypedDict
from pydantic import BaseModel, Discipline
from langchain.chat_models import init_chat_model
from langgraph.checkpoint.reminiscence import InMemorySaver
from langgraph.graph import END, START, StateGraph
from langgraph.varieties import Command, interrupt
from google.colab import userdata
os.environ[‘OPENAI_API_KEY’] = userdata.get(‘OPENAI_KEY’)
mannequin = init_chat_model(model_name)
class ResearchState(TypedDict, whole=False):
subject: str
plan: str
proof: str
draft: str
suggestions: str
evaluator_approved: bool
human_approved: bool
revision_count: int
class ReviewResult(BaseModel):
permitted: bool = Discipline(
description=”Whether or not the draft is correct and effectively grounded.”
)
suggestions: str = Discipline(
description=”Particular corrections required earlier than approval.”
)
review_model = mannequin.with_structured_output(ReviewResult)
The state is the interface shared by all nodes. Every node reads solely the values it wants and returns solely the fields it o wns.
Create the Nodes
def planner_node(state: ResearchState) -> ResearchState:
response = mannequin.invoke(
f”””
Create a concise analysis plan for the next subject:
{state[‘topic’]}
Embrace the questions that should be answered and the proof wanted.
“””
)
return {
“plan”: response.content material,
“revision_count”: 0,
}
def researcher_node(state: ResearchState) -> ResearchState:
response = mannequin.invoke(
f”””
Produce a grounded analysis temporary for this subject:
{state[‘topic’]}
Observe this plan:
{state[‘plan’]}
Clearly separate verified data, assumptions, and open questions.
“””
)
return {“proof”: response.content material}
def writer_node(state: ResearchState) -> ResearchState:
response = mannequin.invoke(
f”””
Write an expert technical article utilizing solely the proof beneath.
Matter:
{state[‘topic’]}
Proof:
{state[‘evidence’]}
Embrace an introduction, structure rationalization, implementation
issues, limitations, and conclusion.
“””
)
return {“draft”: response.content material}
def evaluator_node(state: ResearchState) -> ResearchState:
evaluate = review_model.invoke(
f”””
Consider the draft in opposition to the obtainable proof.
Proof:
{state[‘evidence’]}
Draft:
{state[‘draft’]}
Examine technical accuracy, grounding, completeness, and readability.
“””
)
return {
“evaluator_approved”: evaluate.permitted,
“suggestions”: evaluate.suggestions,
}
def revision_node(state: ResearchState) -> ResearchState:
response = mannequin.invoke(
f”””
Revise the next technical article.
Draft:
{state[‘draft’]}
Reviewer suggestions:
{state[‘feedback’]}
Protect appropriate sections and repair solely the recognized weaknesses.
“””
)
return {
“draft”: response.content material,
“revision_count”: state.get(“revision_count”, 0) + 1,
}
def human_review_node(state: ResearchState) -> ResearchState:
determination = interrupt(
{
“message”: “Evaluate this text earlier than finalization.”,
“draft”: state[“draft”],
“automated_feedback”: state.get(“suggestions”, “”),
“allowed_actions”: [“approve”, “reject”],
}
)
return {
“human_approved”: determination.get(“motion”) == “approve”,
“suggestions”: determination.get(
“suggestions”,
state.get(“suggestions”, “”),
),
}
def finalize_node(state: ResearchState) -> ResearchState:
return {“human_approved”: True}
Outline Conditional Routes
def route_after_evaluation(
state: ResearchState,
) -> Literal[“revise”, “human_review”]:
if state.get(“evaluator_approved”):
return “human_review”
if state.get(“revision_count”, 0) >= 2:
return “human_review”
return “revise”
def route_after_human_review(
state: ResearchState,
) -> Literal[“finalize”, “revise”]:
if state.get(“human_approved”):
return “finalize”
return “revise”
The evaluator doesn’t management the graph instantly. It updates the state. The routing perform reads that state and selects an allowed edge.
The revision restrict prevents an unbounded evaluator-optimizer loop.
Assemble the Graph
builder = StateGraph(ResearchState)
builder.add_node(“planner”, planner_node)
builder.add_node(“researcher”, researcher_node)
builder.add_node(“author”, writer_node)
builder.add_node(“evaluator”, evaluator_node)
builder.add_node(“revise”, revision_node)
builder.add_node(“human_review”, human_review_node)
builder.add_node(“finalize”, finalize_node)
builder.add_edge(START, “planner”)
builder.add_edge(“planner”, “researcher”)
builder.add_edge(“researcher”, “author”)
builder.add_edge(“author”, “evaluator”)
builder.add_conditional_edges(
“evaluator”,
route_after_evaluation,
{
“revise”: “revise”,
“human_review”: “human_review”,
},
)
builder.add_edge(“revise”, “evaluator”)
builder.add_conditional_edges(
“human_review”,
route_after_human_review,
{
“finalize”: “finalize”,
“revise”: “revise”,
},
)
builder.add_edge(“finalize”, END)
checkpointer = InMemorySaver()
graph = builder.compile(checkpointer=checkpointer)
Run the Graph
config = {
“configurable”: {
“thread_id”: “graph-engineering-article-001″
}
}
outcome = graph.invoke(
{
“subject”: “Graph engineering for dependable AI brokers”,
“revision_count”: 0,
},
config=config,
)
if “__interrupt__” in outcome:
print(“The workflow is ready for human approval.”)
Resume After Approval
final_state = graph.invoke(
Command(
resume={
“motion”: “approve”,
“suggestions”: “Authorized for publication.”,
}
),
config=config,
)
print(final_state[“draft”])
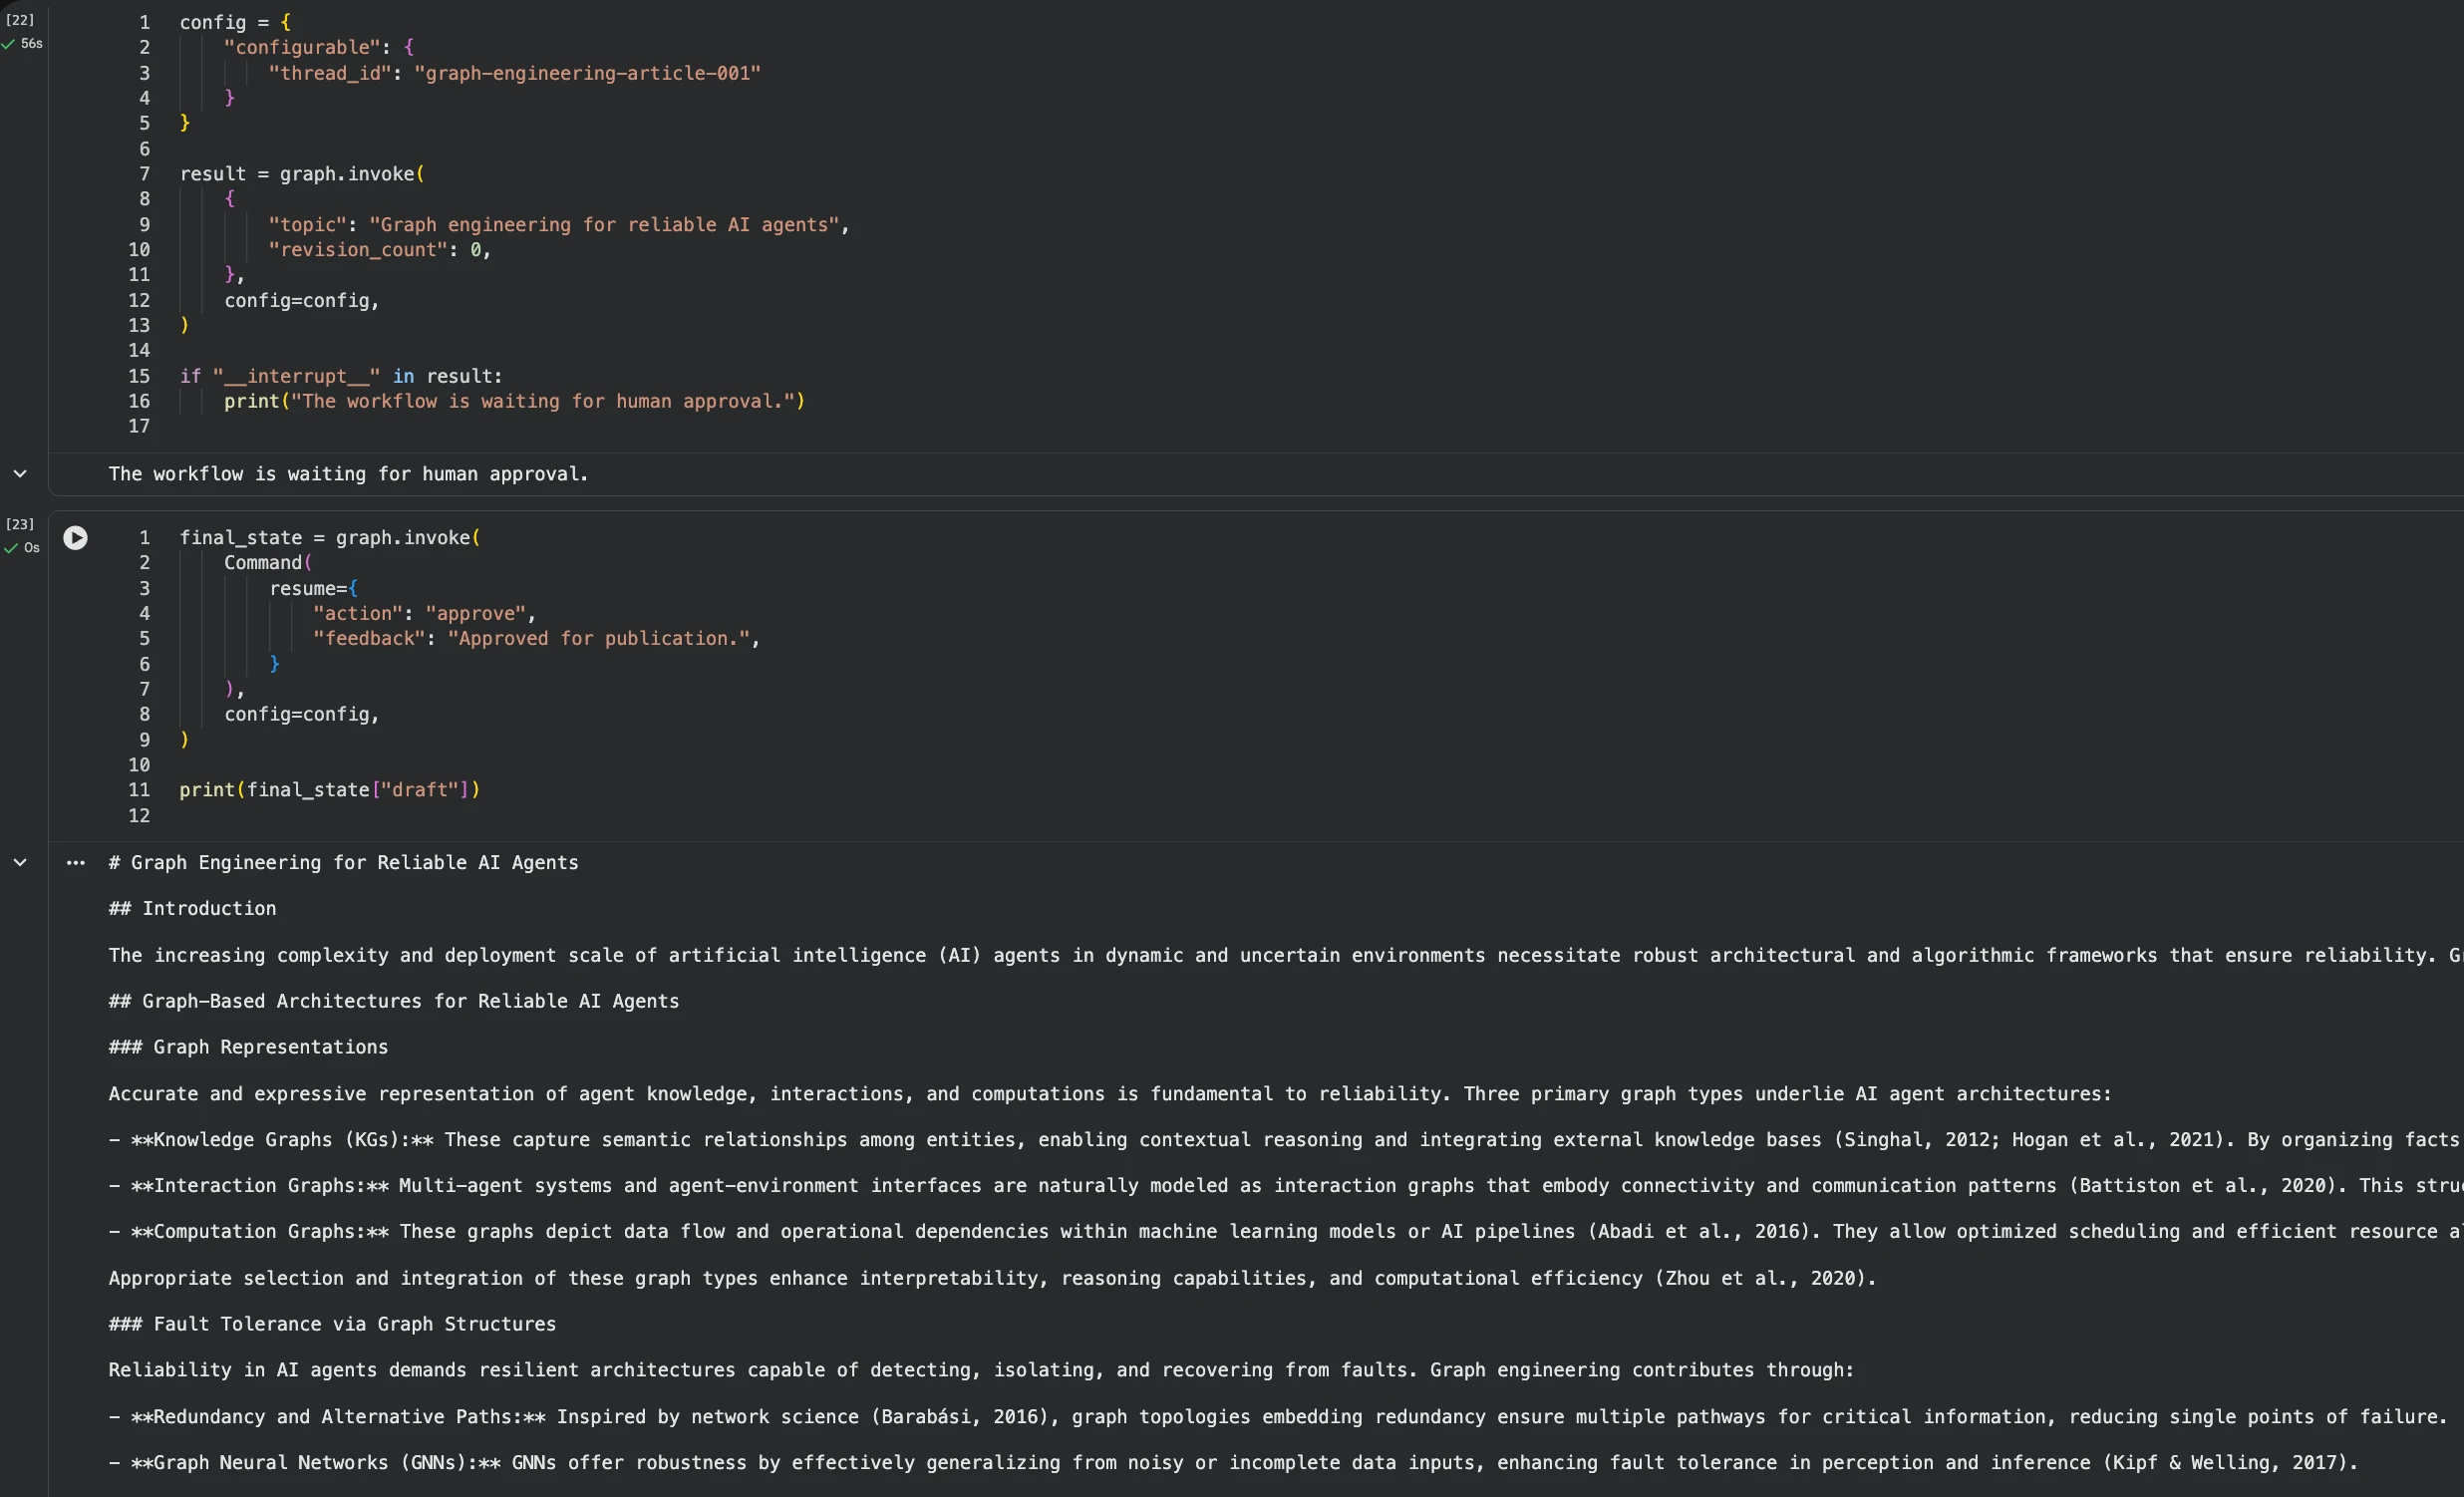
The identical thread_id is required as a result of it identifies the saved execution state.
InMemorySaver is appropriate for demonstration, but it surely loses all checkpoints when the method restarts. Manufacturing programs ought to use sturdy persistence backed by a database.
Manufacturing Necessities That Diagrams Typically Miss
A graph that runs in a pocket book just isn’t robotically production-ready.
Node Contracts
Each node ought to outline:
Required inputs
Produced outputs
Allowed instruments
Timeout
Retry coverage
Unwanted side effects
Failure classes
Validation guidelines
Possession
A node that accepts arbitrary state and returns unstructured textual content turns into troublesome to check.
Idempotency
A retry mustn’t repeat an irreversible motion.
For instance, retrying a fee node should not cost the shopper twice.
Use:
Idempotency keys
Transaction identifiers
Deduplication checks
Operation logs
Database constraints
Error Classification
Not each failure ought to be retried.
Non permanent community failure -> RetryRate restrict -> Wait and retryInvalid enter -> Return to validationMissing permission -> EscalatePolicy violation -> StopModel formatting failure -> Restore output
A generic retry loop can enhance price with out fixing the underlying difficulty.
Context Isolation
Don’t give each node the whole graph state.
A author might have proof and a top level view.
A safety reviewer might have code and deployment configuration.
A publication node might have solely the permitted artifact and vacation spot.
Context isolation reduces token utilization, unintentional knowledge publicity, and distraction from irrelevant historical past.
Observability
Hint no less than:
Node begin and completion
Chosen route
State fields modified
Software calls
Mannequin and immediate model
Token consumption
Latency
Retry rely
Validation outcomes
Human selections
Remaining final result
Microsoft Agent Framework additionally separates dynamic brokers from explicitly managed workflows. Its workflow system helps graph-based execution, typed message routing, conditional paths, parallel processing, checkpoints, and human-in-the-loop interactions.
Framework Choices
LangGraph
Greatest suited to groups that want low-level management over state, routes, persistence, subgraphs, interrupts, and blended deterministic-agentic execution.
Google ADK
Helpful for groups constructing within the Google ecosystem. It helps multi-agent workflows, template-based sequential, parallel, and loop execution, and newer graph-oriented workflows.
Microsoft Agent Framework
Appropriate for Python, .NET, and Go groups that require typed workflows, graph routing, checkpointing, human interplay, and integration with enterprise programs.
Plain Python and Current Workflow Engines
A specialised agent framework could also be pointless when a lot of the workflow is deterministic.
Python features, queues, databases, schedulers, and state-machine libraries can coordinate a small variety of LLM-powered steps successfully.
Limitations
Graph engineering additionally introduces:
Extra infrastructure
Extra state-management complexity
Increased testing necessities
Synchronization challenges
Elevated mannequin price when many brokers are used
Harder versioning and migrations
Potential latency at parallel be a part of factors
Overengineering for easy duties
A graph is helpful when its construction makes the system safer, sooner, simpler to judge, or simpler to take care of.
It’s not useful merely as a result of it incorporates extra containers.
Conclusion
Graph engineering just isn’t a alternative for immediate engineering, context engineering, harness engineering, or loop engineering.
It’s the layer that coordinates them.
Prompts management particular person mannequin calls.
Context engineering controls what every mannequin sees.
Agent loops management how an agent causes and makes use of instruments.
Graph engineering controls how a number of brokers, loops, features, validators, instruments, and people work collectively.
The broader lesson is straightforward:
Don’t start by asking what number of brokers the system wants.
Start by figuring out the work, dependencies, determination boundaries, parallel alternatives, validation necessities, failure paths, and human obligations.
The brokers fill the nodes.
The engineering lives within the edges.
Regularly Requested Questions
No. LangGraph is one framework for implementing graph-based agent workflows. Graph engineering is the broader architectural observe. Are data graphs required? No. Workflow graphs can function and not using a data graph. A data graph is helpful when the system must symbolize and traverse relationships between entities.
Sure. Revision cycles, tool-calling brokers, retries, and evaluator-optimizer patterns are loops inside a bigger graph.
No. Most manufacturing graphs ought to mix deterministic features, instruments, insurance policies, and chosen LLM-powered nodes.
Sure. A single agent is usually preferable for low-risk, open-ended duties with a restricted toolset and easy restoration necessities.

Harsh Mishra is an AI/ML Engineer who spends extra time speaking to Massive Language Fashions than precise people. Obsessed with GenAI, NLP, and making machines smarter (so that they don’t change him simply but). When not optimizing fashions, he’s in all probability optimizing his espresso consumption. 🚀☕
Login to proceed studying and luxuriate in expert-curated content material.
Maintain Studying for Free

