


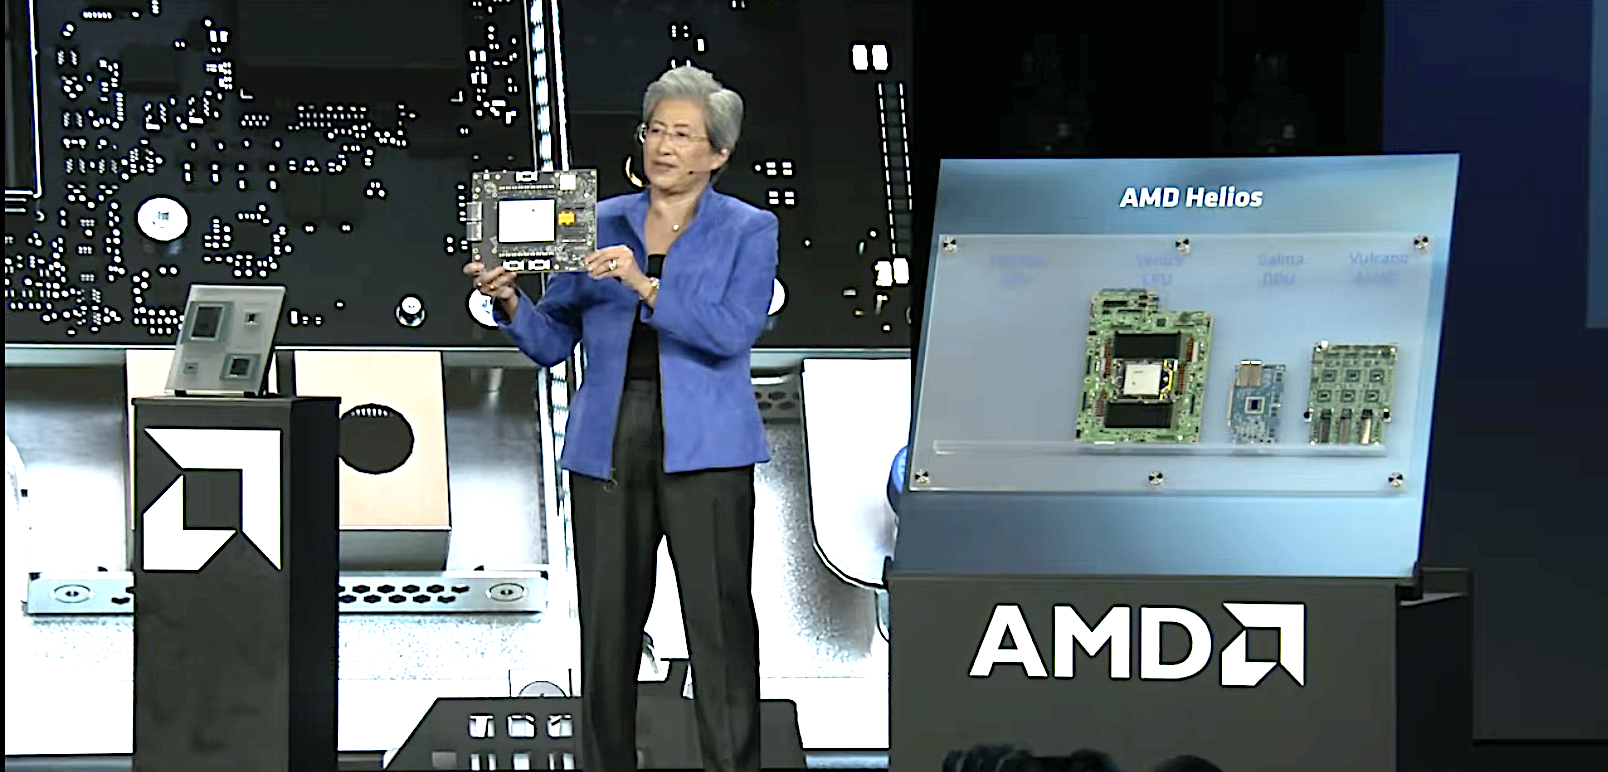
Superior Micro Gadgets Inc.’s Advancing AI 2026 keynote this week was Chief Govt Lisa Su’s bid to redefine the corporate from a “graphics processing unit different” to a full-stack synthetic intelligence infrastructure vendor and to make this the yr the central processing unit formally rebounds as a first-class AI platform.
The message from Su (pictured) was formidable and sometimes compelling, however it additionally sharpened the aggressive distinction with Nvidia Corp. and Intel Corp., elevating as many questions because it answered.
Although the apparent theme of the occasion was that AI is shifting from pilots to manufacturing, that has been the theme of each occasion I’ve attended this yr. Past that, there have been a number of different sub-themes. Listed here are the 5 most notable:
1. Helios and MI450: Lastly a reputable rack-scale different — with a catch
Su opened by turning Intuition MI450 and the Helios rack right into a single, rack-scale product story aimed squarely at Nvidia’s system-level dominance. In AMD’s benchmarks, Helios delivers “a median of 10% to fifteen% extra efficiency than the competitors” at mounted rack energy on “the very best throughput workloads” and “main inference modes,” and she or he translated that into “as much as 30% extra tokens per greenback than the competitors.” Although Nvidia has set the usual for the programs strategy, if AMD can ship on the financial savings it claims at comparable efficiency, it might probably use that to place itself as a reputable different.
The associate lineup was the strongest proof that these claims are actual. Su stated demand for Helios is “extraordinarily sturdy… from the biggest AI labs to hyperscalers,” and she or he highlighted OpenAI as “one in all our deepest and earliest companions deploying Helios,” noting that joint engineering groups are already operating GPT-class workloads. OpenAI’s infrastructure lead described AMD and OpenAI engineers “working facet by facet to optimize the software program stack” and stated they anticipate to deploy Helios “at huge scale, beginning in the direction of the tip of this yr, after which accelerating towards 2027.”
The catch is that “common of 10% to fifteen% extra efficiency” and “30% extra tokens per greenback” stay AMD-run numbers in opposition to unnamed “competitors” and unspecified mannequin mixes. Till cloud occasion specs, public benchmarks and buyer case research present comparable beneficial properties within the wild, Helios is just a robust narrative and a promising design, not but a confirmed market-share shift. Nvidia nonetheless owns software program mindshare and the incumbent put in base; AMD should convert a handful of flagship design wins right into a sturdy ecosystem.
2. CPU rebounds: Venice turns agentic AI right into a three-tier compute story
One of many extra fascinating and underappreciated components of the keynote was AMD’s aggressive effort to reset the CPU narrative in AI. For the previous few years, CPUs have been solid as glorified I/O controllers in GPU containers. Su pushed again exhausting on that, arguing that AI infrastructure is splitting into three CPU roles:
GPU servers the place “the CPU’s job is principally to drive the GPUs.”
Dense “agent servers or what we name agent sandboxes” the place “the precedence is definitely density and the highest-performing cores per watt to run 1000’s of brokers directly.”
Conventional genera-purpose servers the place it’s “all about effectivity” for databases, knowledge providers and enterprise apps.
Venice, AMD’s new Epyc household on Zen 6 and TSMC ‘s two-nanometer course of, is the corporate’s try to personal all three tiers. Su referred to as it “one of many largest generational beneficial properties within the historical past of Epyc,” claiming “as much as 1.8 occasions extra efficiency than Turin” and as much as 512 threads per socket. She then broke Venice right into a household: Venice HF for GPU host nodes at as much as 5 GHz; a 256-core Venice with “the very best compute density within the {industry}” for agent sandboxes; and a 128-core half tuned for enterprise efficiency per greenback, plus variants like Venice X and Verano for HPC and AI host interconnect.
Her punchiest line of the keynote, “Epyc is the one CPU portfolio that leads throughout all use instances,” was clearly aimed toward each Intel’s newest Xeons and the rising crop of Arm server CPUs. She claimed that Venice delivers greater than twice the brokers per watt for agent sandboxes versus x86 and as much as 3.3 occasions extra efficiency per watt on the rack than unnamed Arm rivals in a 100-kilowatt rack. She additionally identified that x86 software program compatibility nonetheless issues while you’re “including 1000’s of workers to your enterprise” within the type of brokers.
The vital angle: AMD is true that agentic AI provides CPUs a second life, however this area is now intensely contested. Intel shouldn’t be standing nonetheless on core depend, reminiscence bandwidth, or AI offload, and Arm distributors are pushing exhausting on effectivity and customized silicon for cloud suppliers. Venice’s generational beneficial properties are spectacular on paper, however AMD nonetheless has to win OEM designs, cloud footprints and unbiased software program vendor certifications at scale, all whereas prospects are additionally contemplating Arm and customized accelerators tailor-made to their agent workloads.
3. Jeetu Patel and Santosh Janardhan: CPUs and GPUs develop into ‘conjoined issues’
If Su offered the product narrative, Jeetu Patel from Cisco Programs Inc. and Santosh Janardhan from Meta Platforms Inc. offered the architectural actuality verify, and so they largely backed AMD’s thesis that CPUs are again within the highlight.
Patel argued that “it’s not only a GPU recreation anymore. It’s CPUs and GPUs. If something, I believe CPUs have gotten not less than as essential, if no more.” His view is grounded in enterprise data, which Cisco has extra of than all the opposite firms on stage mixed. Lengthy-running agent workflows, instruments, databases and networks all have to be orchestrated round frontier fashions.
He framed compute as a heterogeneous material the place “you should take into consideration CPUs and GPUs as conjoined issues. You hand off workloads relying on different workloads. You utilize the appropriate {hardware}.” That’s precisely the type of messaging AMD wants enterprise CIOs to listen to to develop into a extra strategic vendor.
Meta’s Janardhan pushed the identical concept on the knowledge middle scale. For him, the AI drawback is not about squeezing each proportion level out of a single chip; it’s about “the entire knowledge middle as one built-in system — servers, {hardware}, networking, cooling, energy.” He famous that knowledge facilities and silicon “take years to construct,” and argued that the {industry} must be “sitting down in a room, co-designing at this time for what we have to deploy in 2027 and 2028.” In different phrases, CPUs, GPUs, reminiscence, networking and energy at the moment are co-equal design levers.
It was nice to see these firms on stage with Su, as a result of they aren’t second-tier logos; they’re two of the biggest AI and networking gamers on the planet, validating AMD as a co-design associate, not a backup provider. For the established gamers, that’s a warning that their conventional lock-in on the CPU and GPU ranges might not survive an period by which hyperscalers need multi-vendor, co-designed programs to handle threat, value and energy.
4. ROCm.AI and Hyperloom: AMD tries to leapfrog on AI-native tooling
On software program, AMD went straight at its perceived weak spot, the software program hole versus Nvidia’s stack, with a special strategy: Let AI write and optimize extra of the GPU code.
Senior Vice President Vamsi Boppana launched ROCm.AI as “an agentic AI platform that brings the capabilities of AI-assisted GPU programming to builders.” Constructed on AMD’s open software program stack, ROCm.AI provides an AI optimization layer referred to as Hyperloom that may “analyze the workload, tune configurations, choose and tune kernels, alter parallelism methods and iterate in the direction of efficiency targets.”
Internally, AMD has already pushed “a collection of 14,000 fashions by means of Hyperloom,” producing optimizations that will have been “not possible even with a big workforce of engineers earlier than.” In a stay instance, an AI agent focusing on MiniMax M3 on MI355s with VLLM recognized a chance to put in writing a extra optimized Combination-of-Specialists GEMM kernel, delivering a 38 p.c enchancment in tokens per second. Engineers onstage admitted that some AI-generated kernels are “shockingly good, generally higher than essentially the most manually tuned variations.”
AMD’s aggressive guess is that an open stack plus AI-assisted optimization can shut the software-ecosystem hole with Nvidia sooner than conventional hand-tuning ever may. The danger is that that is nonetheless early-stage know-how: automated code technology have to be secure, reproducible and debuggable at scale, and prospects will need to see real-world workloads, not staged demos. Nvidia is not going to sit nonetheless right here both; it has each incentive to construct its personal AI-native tooling on prime of CUDA and its closed ecosystem.
5. Co-designed, open programs: AMD performs the lengthy recreation in opposition to lock-in
The ultimate by means of line in Su’s keynote was an embrace of co-design and openness as AMD’s strategic wedge in opposition to incumbents. OpenAI’s infrastructure chief, Sachin Katti, described a future the place AI turns into “an issue at an information middle scale,” not only a “rack-level drawback,” and harassed the necessity to co-design “from CPUs to GPUs to reminiscence, networking, storage, energy distribution and the cooling programs that go together with it.”
Cerebras CEO Andrew Feldman, asserting a joint resolution that marries AMD’s Helios racks with Cerebras’ wafer-scale engine, argued that prospects who used to decide on between “excessive throughput” and “extraordinary velocity” can now get each — “5 occasions the throughput whereas persevering with to ship this extraordinary velocity” for ultra-low-latency inference.
Su tied these threads collectively by leaning exhausting into open software program. As a result of AMD’s compiler stack and drivers are largely open, companions and even AI brokers can see all the best way right down to the ISA. OpenAI’s Philippe Tillet credited that openness with enabling “very, very vital efficiency beneficial properties” and sooner portability of GPT-class fashions to AMD {hardware}. In a world the place “recursion,” that’s AI serving to design the following technology of AI programs, is changing into a actuality, AMD is betting that openness will let it harness that flywheel extra successfully than a closed stack.
The aggressive implication is that whereas Nvidia nonetheless has the deepest, most entrenched software program ecosystem, AMD goals to be extra open to draw a broader base of companions and builders. Intel has the x86 incumbency however has struggled to transform it into AI mindshare. AMD is positioning itself because the third pole: not simply cheaper GPUs, however an open, co-designed CPU-plus-GPU platform tuned for the agentic, data-center-as-a-system future.
Whether or not that guess pays off will rely upon execution in silicon supply, software program high quality, and ecosystem traction, not simply on keynotes. But when Advancing AI 2026 is any indication, AMD has stopped speaking like a quick follower and began appearing like an organization that expects to set the phrases of the AI infrastructure debate.
Ultimate ideas
AMD used Advancing AI 2026 to make a press release: It’s not content material to be “the choice” to Nvidia, and it now has credible {hardware} on the rack degree, a resurgent CPU portfolio tuned for agentic AI, and a software program story that leans into AI-assisted optimization and open ecosystems. Helios plus MI450 provides hyperscalers and frontier labs a rack-scale possibility that may be argued on efficiency per watt and tokens per greenback, whereas the Venice Epyc household targets the rising three-tier AI compute stack, comprised of GPU hosts, dense agent sandboxes, and general-purpose enterprise, at a second when CPUs are quietly changing into the management airplane and workhorse for agentic workflows.
On software program, AMD has stopped pretending it might probably out-CUDA Nvidia head-on; as an alternative, it’s betting that an open stack plus AI-native instruments like ROCm.AI and Hyperloom can compress the time it takes to get actual workloads performant on its silicon.
The uncomfortable actuality for AMD is that none of this makes Nvidia “path” within the broader AI race. Nvidia nonetheless owns the dominant software program ecosystem, the majority of the deployed AI accelerator footprint, and a deeply built-in toolchain. In most giant AI outlets, AMD stays the second platform to be certified relatively than the assumed default.
Openness is AMD’s finest strategic device in opposition to that incumbency, decreasing switching prices and welcoming companions and, ultimately, AI brokers to co-design and tune all the best way right down to the instruction set, which differs from Nvidia’s mannequin. The query is whether or not that openness, mixed with aggressive efficiency and TCO, is sufficient to transfer AMD from “crucial diversification” to “first selection” for a significant share of latest deployments.
Proper now, openness seems to be crucial however not ample, and AMD will want a number of cycles of flawless execution on silicon, software program and the ecosystem to show this spectacular keynote positioning into sturdy market energy.
Zeus Kerravala is a principal analyst at ZK Analysis, a division of Kerravala Consulting. He wrote this text for SiliconANGLE.
Photograph: Zeus Kerravala
Help our mission to maintain content material open and free by participating with theCUBE group. Be part of theCUBE’s Alumni Belief Community, the place know-how leaders join, share intelligence and create alternatives.
15M+ viewers of theCUBE movies, powering conversations throughout AI, cloud, cybersecurity and extra
11.4k+ theCUBE alumni — Join with greater than 11,400 tech and enterprise leaders shaping the long run by means of a novel trusted-based community.
About SiliconANGLE Media
Based by tech visionaries John Furrier and Dave Vellante, SiliconANGLE Media has constructed a dynamic ecosystem of industry-leading digital media manufacturers that attain 15+ million elite tech professionals. Our new proprietary theCUBE AI Video Cloud is breaking floor in viewers interplay, leveraging theCUBEai.com neural community to assist know-how firms make data-driven choices and keep on the forefront of {industry} conversations.

