


This put up continues our sequence on greatest practices with Amazon Bedrock Guardrails. For the earlier put up, see Construct secure generative AI purposes like a professional: greatest practices with Amazon Bedrock Guardrails.
AI-powered coding assistants and code technology workflows, reminiscent of Claude Code, Kiro, and OpenAI Codex, are reworking how builders write software program. These instruments generate code in actual time via streaming responses, usually producing 1000’s of characters throughout prolonged periods. As organizations undertake generative AI workflows with code at scale utilizing these assistants, it’s important that unsafe code patterns are detected and blocked at any time when required. Amazon Bedrock Guardrails helps detect and filter unsafe and undesired code content material with safeguards reminiscent of content material filters for content material moderation, immediate assault prevention with jailbreaks, immediate injection, and immediate leakage, delicate data filters to redact and block personally identifiable data (PII), and extra.
Nonetheless, coding workflows together with agentic loops have distinctive throughput traits together with lengthy streaming outputs, concurrent developer periods, and repetitive context analysis. Making use of Amazon Bedrock Guardrails to workflows with these traits with out correct configuration may probably result in constraints reminiscent of throttling errors, elevated prices, and fewer than optimum latency. On this put up, we clarify how Amazon Bedrock Guardrails may be configured for code technology workflows with coding assistants to beat these constraints. With these greatest practices, you’ll be able to construct an environment friendly blueprint serving to you with efficient capability planning with strong security protection.
Why guardrails are essential for code technology workflows
Amazon Bedrock Guardrails gives complete safeguards that detect and filter dangerous and undesirable content material from each consumer inputs and mannequin responses, to assist construct secure generative AI purposes. Whereas these safeguards may be configured and carried out throughout quite a lot of purposes, there are particular safeguards that can be utilized to guard dangerous code patterns reminiscent of:
Detect immediate assaults – block makes an attempt to govern the mannequin into producing malicious code or bypassing directions.
Filter delicate data – will help block or masks delicate data reminiscent of personally identifiable data (PII), customized regex in consumer inputs and mannequin responses, catch hardcoded AWS entry keys, database connection strings, or non-public keys earlier than they seem in generated code.
Content material moderation – detect and filter dangerous content material in consumer prompts and mannequin responses, together with content material that violates your group’s acceptable use insurance policies.
Block denied matters – outline customized matters which are used as a foundation for blocking conversations associated to prohibited actions, reminiscent of producing code to bypass authentication mechanisms or helping with unauthorized entry patterns.
These safeguards are important when AI-generated code is utilized in manufacturing programs.
A state of affairs: When good guardrails go sideways
A buyer system staff has simply rolled out Claude Code on Amazon Bedrock to fifteen builders. They’ve configured a guardrail with three safeguards: immediate assault detection to assist stop injection, a delicate data filter to redact or block leaked credentials, and a content material filter to dam unsafe code patterns. Every part labored completely through the pilot with two builders. After a profitable pilot, all 15 builders begin their coding periods concurrently. Inside minutes, their staff begins reporting errors: ThrottlingException responses from Amazon Bedrock mannequin inference. Code completions stall mid-stream. Builders are annoyed, and their Slack channel lights up.
What occurred? Every developer’s session generates roughly 5,000 characters of code per perform on common. With the default streaming configuration, Amazon Bedrock evaluates guardrails for each 50 characters, triggering 100 API calls per perform, per developer. Multiply throughout 15 concurrent periods, and the system generates 1,500 analysis requests per second. Worse, as a result of they’ve 3 safeguards energetic, every analysis consumes 3 textual content items as a substitute of 1, tripling throughput consumption.
The foundation trigger wasn’t inadequate quota. It was an architectural mismatch. They utilized a sample designed for brief conversational exchanges to a high-throughput code technology pipeline. This put up offers architectural patterns to unravel this drawback.
Textual content items: The guardrails foreign money
Earlier than diving into structure, it’s essential to grasp how guardrail consumption is calculated, as a result of it’s the important thing to each optimization that follows.
A textual content unit is outlined as 1,000 characters within the textual content. An ApplyGuardrail API name with 1,000 characters of textual content evaluated in opposition to 3 safeguards generates 3 textual content items of consumption.
Critically, consumption is multiplicative. It scales with each content material size and the variety of energetic safeguards.
For code technology workflows the place outputs are usually verbose (1000’s of characters per perform), this multiplicative relationship is a important consider capability planning. A guardrail configured with content material filters, denied matters, and delicate data filters is metered based mostly on the variety of textual content items processed by every safeguard or filter.
Notice: Content material filters are charged as a single textual content unit per 1,000 characters no matter what number of classes (Hate, Insults, Sexual, Violence, Misconduct, Immediate Assault) are enabled inside the filter. For instance, in the event you allow all six content material filter classes, it nonetheless counts as one textual content unit, not six. The multiplicative relationship applies throughout distinct coverage sorts (content material filters, denied matters, delicate data filters), not throughout classes inside a single coverage sort.
The problem: Code technology workflows may set off throttling
Conventional conversational AI workflows contain quick, discrete consumer prompts and mannequin responses. Code technology workflows differ in ways in which straight influence guardrail structure:
The next desk reveals why code technology workflows are uniquely demanding:
Attribute
Conversational AI
Code Era
Output size
100-500 characters
5,000-50,000+ characters
Session length
Single flip or few turns
Prolonged multi-turn periods
Concurrent customers
Sometimes, asynchronous
Groups coding concurrently
Context reuse
Minimal
System prompts, instrument definitions, and prior code resent each flip
Intermediate output
Minimal
In depth chain-of-thought reasoning
These variations imply that an inline scanning method, the place guardrails consider each chunk of streamed output because it’s generated, creates a quantity of evaluations that’s disproportionate to the precise security worth delivered.
Greatest Practices: Structure Patterns for Code Era Workflows
To deal with these challenges, we advocate a set of structure patterns that optimize guardrail utilization for code technology workflows. Every sample targets a particular facet of the issue — from lowering analysis frequency to selectively scanning solely high-risk content material. You may apply these patterns individually or mix them based mostly in your workload traits and security necessities.
Structure sample 1: The pre-commit hook mannequin
Understanding inline scanning: the default method
Whenever you connect guardrails on to mannequin invocation utilizing guardrailConfig with the Converse or InvokeModel APIs, you’re utilizing what’s often known as inline scanning. On this mode, Amazon Bedrock Guardrails mechanically evaluates each the total enter immediate and the streaming output in opposition to energetic safeguards repeatedly, in actual time, as tokens are generated. For conventional conversational AI, this method works properly: prompts are quick, responses are concise, and the analysis overhead is negligible.
However for code technology workflows, inline scanning turns into inefficient overhead. It provides price and consumes quota with out meaningfully bettering your safety posture. A coding assistant doesn’t produce solely a quick response. It streams 1000’s of characters of code, interspersed with reasoning, feedback, and iterative refinements. With inline analysis energetic, each chunk of that output is scanned in opposition to each configured safeguard, together with the static system immediate and beforehand generated context that hasn’t modified because the final analysis. The result’s redundant work: the identical boilerplate directions, instrument definitions, and prior dialog historical past are re-evaluated flip after flip, consuming textual content items with out including security worth.
The core greatest observe is to shift from steady inline scanning to selective validation at strategic checkpoints, analogous to a pre-commit hook in a Git workflow. Quite than scanning each token because it streams, validate content material at well-defined boundaries the place the danger profile modifications.
Why “pre-commit hook” considering works
Software program builders don’t run linters, formatters, and safety scanners after each line they sort. They validate at commit time. They don’t validate each intermediate edit, each deleted line, or each half-written perform, however validate the completed outcome in the mean time it issues.
In a Git workflow, a pre-commit hook is a script that runs mechanically at a particular, well-defined boundary: the second you try and commit code to your repository. It’s the final gate earlier than your modifications change into a part of the shared code base. At this checkpoint, you run your validations and checks , in opposition to the ultimate artifact that’s about to be continued.
This sample works as a result of it balances two competing wants: thoroughness (each dedicated change is absolutely validated) and effectivity (validation solely occurs when the danger profile modifications, as code strikes from “draft in progress” to “artifact being continued”).
Making use of the sample to Amazon Bedrock Guardrails
The core greatest observe is to use this identical precept to Amazon Bedrock Guardrails: shift from steady inline scanning to selective validation at strategic checkpoints.
Consider your code technology pipeline as having pure commit factors, moments the place content material transitions from one belief degree to a different:
Consumer enter obtained – Content material enters your system from an untrusted supply (validate right here).
Closing code artifact assembled – The mannequin’s full response is able to be offered or saved (validate right here).
Code written to file or dedicated to repository – AI-generated content material is about to change into persistent and probably executable (validate right here).
Between these checkpoints, whereas the mannequin is reasoning, producing intermediate tokens, or producing chain-of-thought explanations, the content material is ephemeral. It hasn’t crossed a belief boundary. Scanning it repeatedly provides price and consumes quota with out meaningfully bettering your safety posture.
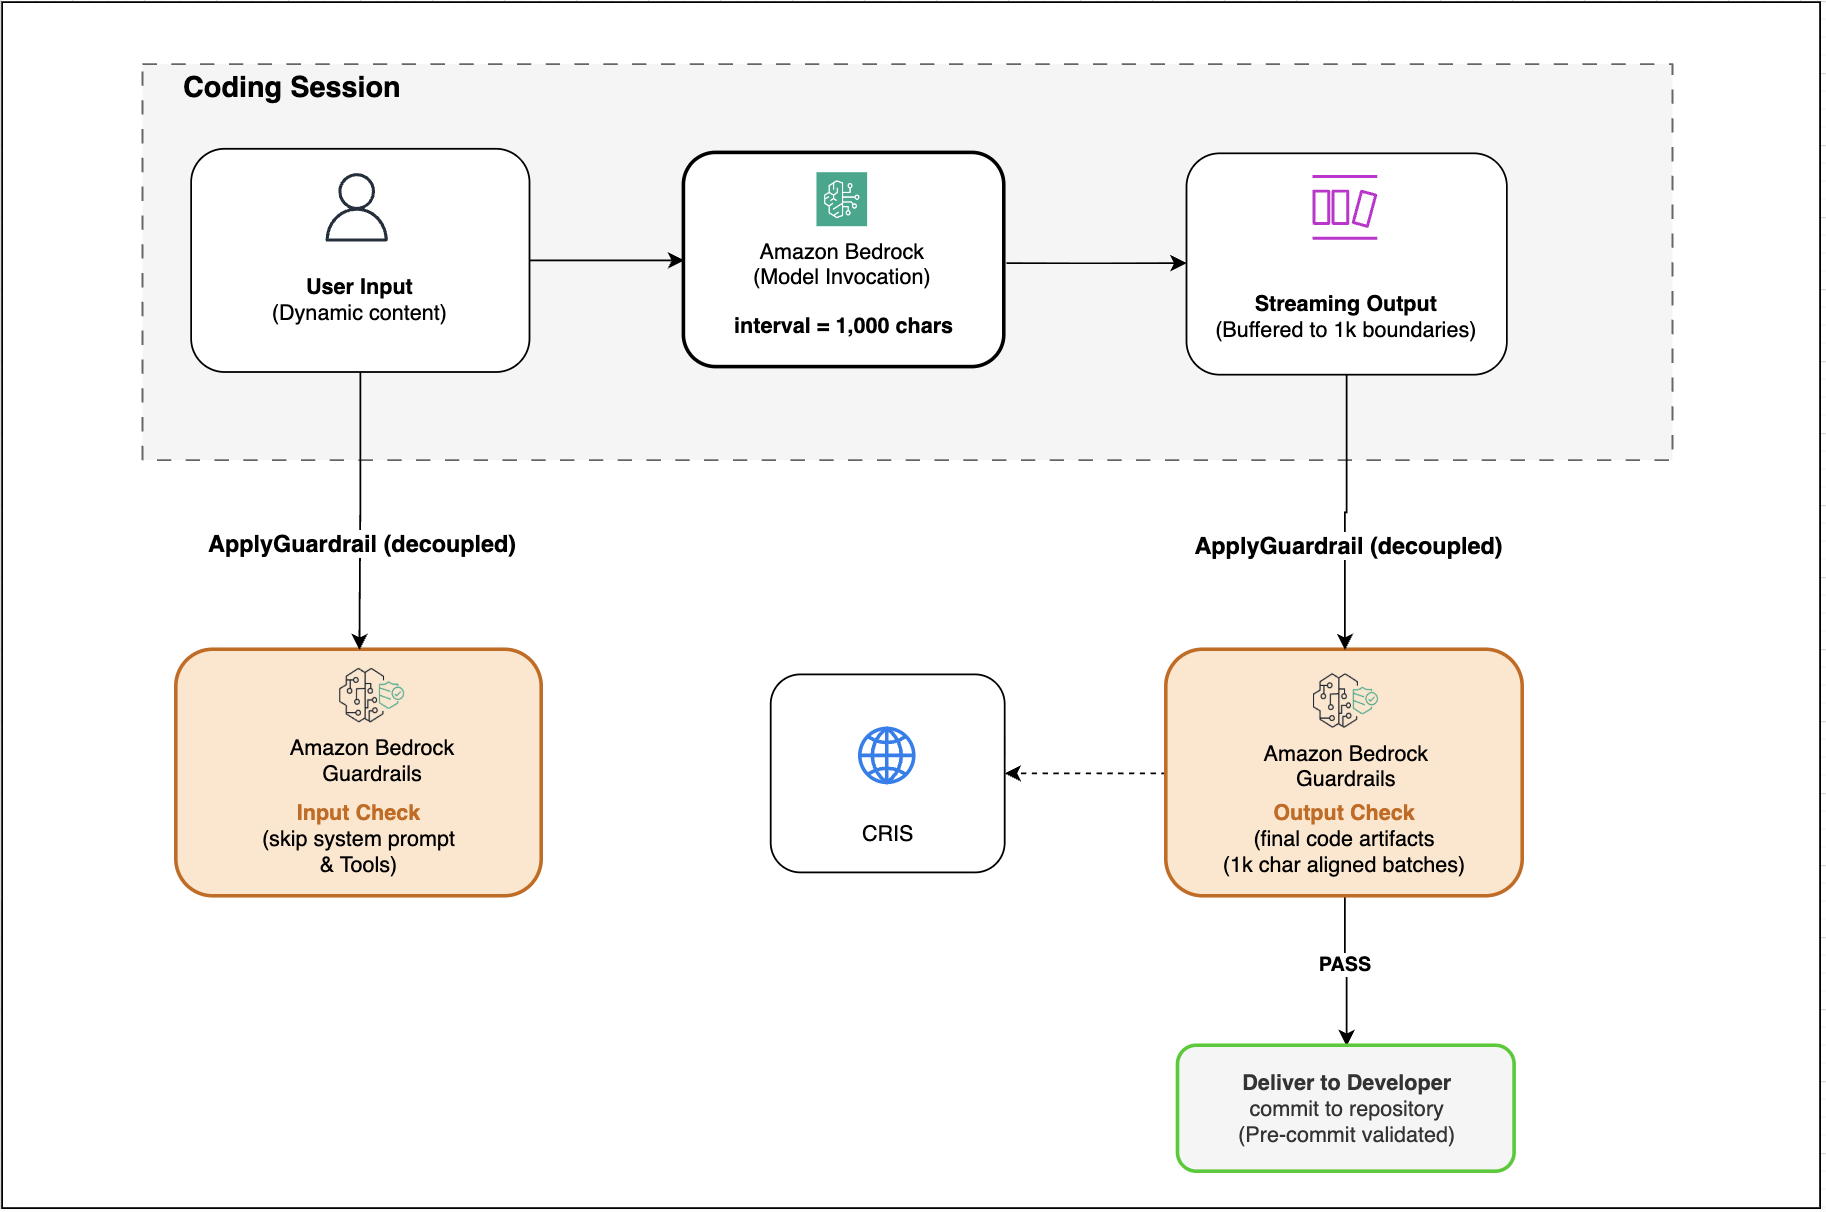
Key precept: Use the decoupled ApplyGuardrail API to guage user-supplied inputs earlier than they attain the mannequin, and validate aggregated remaining code artifacts earlier than they’re dedicated, not each intermediate reasoning token.
Implementation: pre-commit validation for file operations
For the highest-risk checkpoint, when AI-generated code is about to be written to a file or dedicated to a repository, carry out complete guardrail analysis. That is the pre-commit hook sample utilized straight:
Structure sample 2: Improve the streaming interval to 1,000 characters
Whenever you do want real-time streaming analysis, for instance interactive coding periods the place you need to halt technology instantly upon detecting a violation, optimize the streaming interval. Rising the guardrail interval from the default 50 characters to 1,000 characters can cut back your API name quantity by 20x. See the next configuration:
Affect: A 5,000-character perform goes from 100 evaluations to five. A 50,000-character file goes from 1,000 evaluations to 50.
Structure sample 3: Use the decoupled ApplyGuardrail API for selective analysis
With the standalone ApplyGuardrail API, you should use Amazon Bedrock Guardrails regardless of the muse mannequin. You may consider textual content with out invoking the muse mannequin.
Sample: Enter-only validation with unguarded inference
When your main concern is stopping immediate injection and blocking malicious inputs, validate solely the dynamic consumer content material earlier than it reaches the mannequin. In that case, invoke the mannequin with out inline guardrails:
Why this issues for coding workflows: In a typical coding session, the system immediate (usually 2,000-5,000 characters of instrument definitions and directions) and dialog historical past (rising with every flip) are resent on each invocation. With inline analysis, this static content material is re-scanned each single flip. With the decoupled method, you consider solely the ~200-character consumer message that truly modified.
Sample: Output-only validation at completion
When that you must scan generated code for delicate data (leaked credentials, hardcoded secrets and techniques) however belief that the consumer enter is benign (for instance, inside developer instruments behind authentication), validate solely the ultimate output:
Sample: Bidirectional validation with selective scope
For max protection, validate inputs for injection assaults and outputs for delicate content material whereas nonetheless avoiding the overhead of inline scanning:
Structure sample 4: Batch output to textual content unit aligned boundaries
Since a 600-character chunk nonetheless prices one full textual content unit (1,000 characters), at all times batch to multiples of 1,000 characters to keep away from partial-unit waste:
Structure sample 5: Threat-based analysis depth
Not all generated code carries the identical danger. Code that touches IAM insurance policies, secrets and techniques, or authentication deserves extra thorough scanning than UI format code. Implement adaptive analysis depth based mostly on content material indicators:
Structure sample 6: Multi-stage agent pipeline
Agentic coding workflows (the place the mannequin makes use of instruments, causes over a number of steps, and produces intermediate outputs) require a distinct analysis technique than single-turn technology:
The whole choice framework
The next desk reveals the choice framework for varied checkpoints:
Checkpoint
What to validate
How
Textual content unit influence
Consumer enter (every flip)
Dynamic consumer content material solely
ApplyGuardrail (supply=INPUT)
Low – solely new content material evaluated
Streaming output
Lively content material because it streams
Set interval to 1,000 chars
Potential 20x discount in comparison with default
Accomplished response
Closing aggregated code artifact
ApplyGuardrail (supply=OUTPUT)
One-time complete move
Pre-commit / file save
AI-generated code modifications
ApplyGuardrail (supply=OUTPUT)
Complete however rare
Agent instrument calls
Solely harmful instruments (write/execute)
ApplyGuardrail (supply=OUTPUT)
Focused – skip benign instruments
Intermediate reasoning
Skip fully
Don’t consider CoT tokens
Zero
Key takeaways
Shift from inline scanning to selective analysis – Use the decoupled ApplyGuardrail API to manage precisely what will get scanned and when. Consider at belief boundaries, not repeatedly.
Set the streaming interval to 1,000 characters – When streaming analysis is required, this single change can ship as much as a 20x discount in analysis frequency.
Consider solely dynamic content material – Don’t re-evaluate system prompts, instrument definitions, and dialog historical past each flip. Use hash-based caching for content material that should be re-evaluated.
Apply risk-based analysis depth – Scan IAM insurance policies and credential-handling code with the safeguards. Defer UI part scanning to commit time.
Skip intermediate reasoning tokens – In agentic workflows, consider solely when content material crosses a belief boundary (consumer enter, harmful instrument calls, remaining output).
Batch to 1,000-character boundaries – A 600-character chunk prices the identical as 1,000 characters. Align your evaluations to textual content unit boundaries to cut back waste.
Guard on the commit boundary – Like a Git pre-commit hook, carry out complete validation when AI-generated code is about to change into persistent and executable.
Conclusion
On this put up, we proposed greatest practices to optimize AI-assisted code technology workflows with Amazon Bedrock Guardrails. Right here is the general abstract on how one can successfully implement Guardrails on your coding workflows.
Audit your present configuration: Open the Amazon Bedrock console and overview your current guardrails. Verify your streaming interval setting. If you happen to haven’t modified it from the default 50 characters, you’re leaving a possible 20x effectivity acquire on the desk.
Verify your account quotas: Earlier than scaling your coding workflows, confirm your precise allotted limits within the AWS Service Quotas console. Don’t assume revealed defaults apply, particularly for newer accounts. Confer with the Amazon Bedrock endpoints and quotas documentation for the newest regional limits.
Implement the decoupled ApplyGuardrail API: Shift from inline analysis to selective validation utilizing the ApplyGuardrail API. Evaluate the Configure streaming response conduct documentation to fine-tune your streaming interval.
Discover the total Guardrails characteristic set: Dive into the Amazon Bedrock Guardrails documentation to find out about content material filters, denied matters, delicate data detection, and learn how to create and modify guardrails on your use case.
Concerning the authors
Sandeep Singh
Sandeep is a Senior Generative AI Knowledge Scientist at AWS, serving to massive enterprises innovate with generative AI. He focuses on generative AI, Agentic AI, machine studying, and system design, delivering AI/ML-powered options to unravel complicated enterprise issues throughout numerous industries.
Denis Batalov
As a 21-year Amazon veteran and a PhD in Machine Studying, Denis labored on thrilling initiatives reminiscent of Search Contained in the E-book, Amazon Cell apps and Kindle Direct Publishing. Since 2013 he has helped AWS prospects undertake AI/ML expertise as a Options Architect. At the moment, Denis is main a staff that helps prospects construct Gen AI purposes with Amazon Bedrock and can be personally specializing in advancing the observe of Accountable AI by contributing to ISO and EU standardization efforts in that house. Denis is a frequent public speaker; you’ll be able to comply with him on LinkedIn.
Shyam Srinivasan
Shyam Srinivasan is a Principal Product Supervisor with the Amazon Bedrock staff. He cares about making the world a greater place via expertise and loves being a part of this journey. In his spare time, Shyam likes to run lengthy distances, journey around the globe, and expertise new cultures with household and mates.

Antonio Rodriguez
Antonio is a Principal Generative AI Specialist Options Architect at Amazon Internet Providers. He helps firms of all sizes remedy their challenges, embrace innovation, and create new enterprise alternatives with Amazon Bedrock. Other than work, he likes to spend time along with his household and play sports activities along with his mates.

