The nameless blogger Gwern lately accomplished a 13 thousand phrase put up referred to as Human-like Neural Nets by Catapulting, wherein he presents a idea about why LLMs don’t possess really versatile human-like intelligence, and the way we would practice LLMs that do. Theories like this are solely unremarkable: each crank researcher on the web has a idea about the way to crack AI. However Gwern is outstanding. Exterior of OpenAI itself, Gwern is the earliest individual to anticipate the potential of enormous language fashions, and the scaling arms-race concerned in making them bigger and extra highly effective nonetheless. I usually cite Leopold Aschenbrenner’s Situational Consciousness for example of somebody appropriately predicting the way forward for AI. Written in 2024, simply after the discharge of GPT-4, Aschenbrenner will get a number of issues proper: the frenzy to construct billion or trillion-dollar GPU clusters, the significance of the code across the LLM (what he calls “unhobbling”), and the truth that scaling would proceed via the last decade. Gwern’s essay The Scaling Speculation anticipated the broad strokes in 2020, instantly on the discharge of GPT-3 (two years earlier than the discharge of ChatGPT and the start of the AI increase).
And but, so far as I can inform, Human-like Neural Nets by Catapulting hasn’t but obtained a lot public consideration: one current Hacker Information thread with twelve feedback, all of that are about whether or not human brains are something like neural networks. A part of the reason being that (a) it’s such a protracted put up, (b) the potted abstract describes Gwern’s declare, however not the explanations for it, and (c) a lot of the start of the put up appears like it’s certainly arguing from analogy with human brains. Nevertheless, I don’t assume that analogy is load-bearing. Let me try to clarify what I believe Gwern is saying.
What’s grokking?
First, let’s speak about “grokking”. In 2022, OpenAI revealed a paper displaying that for those who practice a mannequin on a easy dataset (for example, a easy mathematical operation like division), and preserve coaching it lengthy after the coaching appears prefer it’s stalled out, the mannequin will out of the blue make a large leap in functionality. Why does this work? The primary stage of coaching is like rote memorization: the mannequin has to compress as a lot of the coaching information as potential into its weights. However for those who preserve going, then regularization methods (such because the stress on the mannequin to make use of smaller weight values) will inspire the mannequin to search out less complicated and less complicated methods of compressing the info. This doesn’t appear to be a lot at first (the coaching loss stays at zero), till the mannequin notices you can categorical the info by way of merely performing the underlying mathematical operation, at which level it immediately will get massively smarter. In different phrases, over-training a mannequin can stress it into truly understanding its coaching information. OpenAI named this course of “grokking” after Robert Heinlein’s neologism, which for Heinlein means one thing like “gaining a deep, intuitive and elementary understanding”.
Gwern’s argument goes one thing like this:
Trendy LLMs are worse generalizers than people as a result of they haven’t grokked their core domains
Grokking requires overtraining an over-parameterized mannequin on a (comparatively) small dataset, which is the precise reverse of what frontier labs do
Nevertheless, (2) is mainly how human brains be taught
Any individual ought to spend a a couple of tens of billions of {dollars} on attempting it, since it would instantly usher in really human-like LLMs
I’ll skip (3), since I believe the argument continues to be compelling with out the analogy to human brains.
Are LLMs unhealthy as a result of they will’t grok?
I believe his first level is difficult to dispute. LLMs are very sensible in particular areas, however they routinely make errors that people wouldn’t make. Extra to the purpose, they routinely make errors that any human as sensible because the LLM would by no means make. This gorgeous clearly factors to a failure of generalization: LLMs are as robust as sensible people in particular areas, however can’t generalize that intelligence to as many duties as people can.
Do LLMs not grok? I learn via this paper that argues they do. In case you graph “how a lot information has the LLM memorized” in opposition to benchmark efficiency, you may see a small preliminary spike in benchmark efficiency, adopted by a giant drop, adopted lastly by a giant leap in benchmark efficiency. This sample doesn’t observe memorization in any respect: memorization will increase easily within the background the entire time.
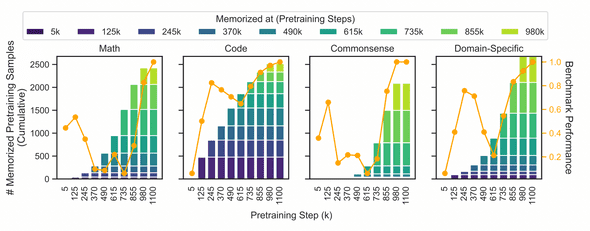
I believe this paper highlights the issue of distinguishing grokking from generalization. Clearly LLMs be taught to generalize throughout coaching, and it’s believable that studying to generalize would require a sure baseline degree of memorization (in order that the LLM has the uncooked materials to generalize from). So it’s going to appear to be grokking.
When Gwern (and others) say that LLMs don’t grok, I believe what they imply is that there’s a minimum of yet another large generalization leap ready to be made. Is that this believable? As an existence proof, people are clearly able to higher generalization than LLMs. After all, it’s potential that this degree of human generalization comes from options of our mind that neural networks can’t replicate, however that appears form of ad-hoc: if neural networks can generalize in any respect, why would they solely have the ability to generalize this far, and no additional?
The straightforward examples of grokking depend on domains with a easy rule ready to be found (e.g. a mathematical operation). Does human language have guidelines this deep? I believe that is an open query, however there’s good cause to assume the reply is sure. Language has deep, delicate construction: not simply inner construction, however construction that reaches all the way in which all the way down to the way in which the world is and the way in which human minds work.
AI labs practice small-ish fashions on oceans of information
For the previous few years, many AI researchers have been saying that information is a very powerful factor: that no matter mannequin structure you select, with sufficient dimension and coaching time the mannequin will converge to its dataset. Whether or not that is true or not, AI labs have spent a lot of their appreciable assets on buying extra, higher-quality information: from scanning bodily books, paying specialists to provide and label information, or partnering with firms which have a number of information already.
AI labs have additionally been coaching comparatively small fashions. Even the most important frontier fashions are most likely MoEs with a few trillion parameters and possibly a tenth of that in lively parameters. After all, estimates of frontier mannequin dimension are principally guesswork, however open-source fashions present baseline: they’re most likely within the ballpark of Kimi-K3, which has slightly below three trillion parameters and fifty billion lively parameters. That feels like rather a lot, however it’s one thing you may most likely pre-train in a few days within the largest frontier cluster.
Grokking requires coaching an enormous mannequin on a small dataset
Gwern’s prediction is that AI labs ought to attempt doing the precise reverse of what they’ve been doing. As a substitute of coaching a bunch of trillion-parameter fashions on huge quantities of information, attempt coaching one hundred-trillion-parameter mannequin on a small dataset.
This sounds fairly foolish on the face of it. The extra information the mannequin has entry to, the smarter it will likely be, proper? Why waste a complete coaching cluster on a hobbled coaching run? As a result of if Gwern is true, grokking is extra prone to happen when the dataset is constrained. In case you feed the mannequin all the info on the planet, it could actually proceed to enhance just by memorizing extra new issues or drawing easy connections. If the mannequin has to ruminate on a small set of information, it’ll be pressured to maintain on the lookout for deeper generalizations. You need a very massive mannequin for this so it could actually memorize as a lot of the info as potential. Every bit of memorized information can function uncooked materials for generalizing.
The large labs most likely haven’t achieved this already. Plausibly Gwern himself is sufficient of an insider that he would know, and so him penning this put up is proof that the labs haven’t tried it. Additionally, the engineering issues concerned in coaching a hundred-trillion-parameter mannequin have seemingly not been solved but: the most important current mannequin might be Claude Mythos, which is certainly not that massive. However they’ve the assets and engineering expertise to provide it a reasonably good shot.
Apparently, the political obstacles is perhaps as laborious to unravel because the technical ones. This coaching run goes to appear to be it failed till the second it succeeds: coaching loss will drop to zero comparatively shortly, then sit there for weeks or months apparently doing nothing in any respect to enhance take a look at loss, chewing up billions of {dollars}. Do any of the highest gamers have the danger urge for food or braveness to maintain funding this experiment all that point?
Conclusion
Gwern’s put up has an prolonged argument that human mind improvement works in the identical means: that human brains have way more “parameters” than frontier LLMs, and are educated on far much less information, which inspires us to make deeper generalizations in early childhood. I don’t have the background in biology or neuroscience to guage these claims, so I’ve expressed the case for grokking solely irrespective of it.
In 2024, it turned clear to everybody that “pure scaling” — the concept you may merely practice bigger and bigger variations of GPT-3.5 — didn’t work. OpenAI’s “even larger model” of GPT-4 was merely not adequate, and was ultimately launched as GPT-4.5 as an alternative of GPT-5. The largest advances since then have been reasoning, which produced one other nice leap ahead in functionality, and a lot better automated RL, which has ushered within the present period of dependable brokers. Neither of those appear to be a believable path to synthetic superintelligence.
I don’t know if I agree with Gwern or not, however forcing very massive LLMs to grok is a minimum of an concept that might usher within the machine god. I can’t bear in mind the final time I examine a easy concept this bold. I hope one of many massive labs tries it out.
Here is a preview of a associated put up that shares tags with this one.