


On this article, you’ll learn the way scikit-ollama bridges the scikit-learn interface with regionally operating Ollama fashions to carry out zero-shot textual content classification; no cloud API required.
Matters we’ll cowl embrace:
What scikit-ollama is and the way it pertains to scikit-llm and the scikit-learn ecosystem.
The right way to load a film evaluate sentiment dataset and instantiate a zero-shot classifier backed by an area Llama 3 mannequin.
How the match/predict sample works within the context of zero-shot LLM-driven classification, and what it really does below the hood.
Let’s not waste any extra time.
Introduction
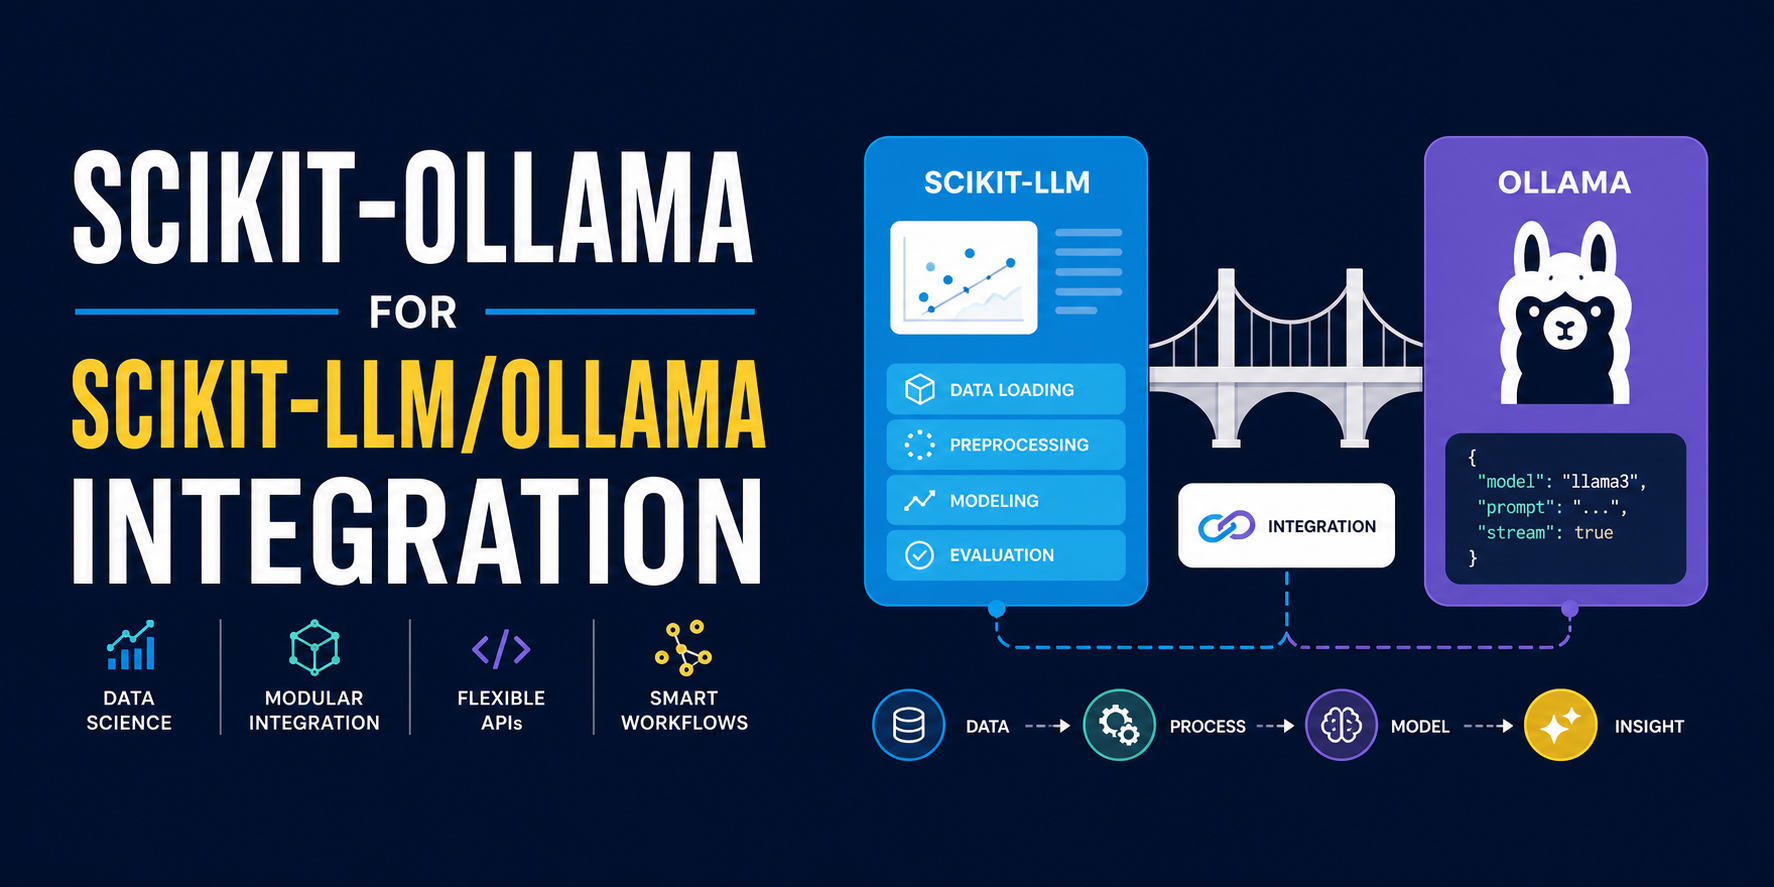
Massive language mannequin (LLM) integration into conventional machine studying workflows just isn’t solely potential these days, but in addition remodeling the best way we work with these fashions, when it comes to each price and safety. Relying solely on industrial cloud APIs with quota and site visitors bottlenecks — in addition to knowledge privateness considerations — is not the one go-to strategy, and scikit-ollama has quite a bit to say on this. This library, largely primarily based on scikit-llm, bridges the hole between the pleasant scikit-learn syntax used to coach and use classical machine studying fashions, and the facility of LLMs — particularly free, regionally put in fashions operating on Ollama.
This text explores find out how to arrange this integration to construct a extremely sensible zero-shot classifier for sentiment prediction on film opinions, utilizing an area Llama 3 mannequin operating in your machine.
Step-by-Step Walkthrough
First, since scikit-ollama is simply suitable with Python 3.9 or greater, test the Python model at present put in in your native or digital growth surroundings; mine is a digital surroundings arrange inside Visible Studio Code:
If in case you have Python 3.8 or decrease, be sure to set up or change to a more recent Python model earlier than continuing. Then set up scikit-ollama:
pip set up scikit-ollama
pip set up scikit–ollama
As soon as put in, we will start coding.
Scikit-LLM offers its personal dataset catalog in its datasets module. We are going to use a type of text-based datasets, particularly one for sentiment classification of film opinions. That is the code wanted to load the info and show an instance evaluate alongside its related sentiment label:
from skllm.datasets import get_classification_dataset
# Loading a demo sentiment evaluation dataset containing film opinions
# The anticipated labels are: “constructive”, “destructive”, “impartial”
X, y = get_classification_dataset()
print(f”Pattern textual content: {X[0]} nLabel: {y[0]}”)
from skllm.datasets import get_classification_dataset
# Loading a demo sentiment evaluation dataset containing film opinions
# The anticipated labels are: “constructive”, “destructive”, “impartial”
X, y = get_classification_dataset()
print(f“Pattern textual content: {X[0]} nLabel: {y[0]}”)
Output:
Pattern textual content: I used to be completely blown away by the performances in ‘Summer season’s Finish’. The appearing was top-notch, and the plot had me gripped from begin to end. A really charming cinematic expertise that I’d extremely suggest.
Label: constructive
Pattern textual content: I was completely blown away by the performances in ‘Summer season’s Finish‘. The appearing was high–notch, and the plot had me gripped from begin to end. A really charming cinematic expertise that I would extremely suggest.
Label: constructive
Now for scikit-ollama itself. You will want to have Ollama regionally put in in your machine. Observe the directions on this article to take action, and be sure to set up the mannequin you need to use for this information. To tug a mannequin, run the next command in your terminal:
The code under imports scikit-ollama’s ZeroShotOllamaClassifier class to instantiate a suitable sentiment classifier backed by an area Ollama mannequin — llama3:newest. Be sure you have this mannequin put in in your machine earlier than persevering with:
from skollama.fashions.ollama.classification.zero_shot import ZeroShotOllamaClassifier
# Initializing the classifier with our native Ollama mannequin: llama3:newest
clf = ZeroShotOllamaClassifier(mannequin=”llama3:newest”)
from skollama.fashions.ollama.classification.zero_shot import ZeroShotOllamaClassifier
# Initializing the classifier with our native Ollama mannequin: llama3:newest
clf = ZeroShotOllamaClassifier(mannequin=“llama3:newest”)
An important clarification about what we simply did. llama3:newest is a general-purpose LLM, initially constructed to do far more than classify textual content: you may chat with it, brainstorm concepts, and extra. So why are we utilizing it to instantiate a zero-shot classifier? By doing so, scikit-ollama — together with scikit-llm below the hood — reformulates our supposed classification activity right into a text-generation immediate that’s syntactically constrained, in order that the native mannequin outputs solely what is required, appearing as a classical machine studying mannequin would when it comes to output format, whereas nonetheless making use of the highly effective language-based reasoning it was constructed for.
That is the core of scikit-ollama and scikit-llm’s worth: bridging the facility of LLMs with the simplicity of the scikit-learn interface for predictive duties like classification.
Time to use the normal machine studying two-stage ritual: match and predict. Whereas becoming a mannequin usually entails updating weights on a labeled dataset, within the context of zero-shot LLM-driven classification there is no such thing as a precise weight updating. The match() name is used solely to register the candidate classification labels, guiding the mannequin for in-context studying:
# “Becoming” the mannequin boils down to only offering the record of candidate labels
clf.match(None, [“positive”, “negative”, “neutral”])
# “Becoming” the mannequin boils down to only offering the record of candidate labels
clf.match(None, [“positive”, “negative”, “neutral”])
When calling the predict() technique and passing a set of textual content opinions, the native Ollama occasion processes every enter as a immediate and parses the output to make sure it maps to one of many zero-shot classification labels, all below the hood.
The code under generates predictions on the dataset and prints the primary three outcomes. Observe that on the primary run, a brief loading delay is anticipated whereas the mannequin initializes, accompanied by a progress bar:
# Producing and displaying predictions on our dataset
predictions = clf.predict(X)
for textual content, prediction in zip(X[:3], predictions[:3]):
print(f”Textual content: ‘{textual content}'”)
print(f”Predicted Sentiment: {prediction}n”)
# Producing and displaying predictions on our dataset
predictions = clf.predict(X)
for textual content, prediction in zip(X[:3], predictions[:3]):
print(f“Textual content: ‘{textual content}'”)
print(f“Predicted Sentiment: {prediction}n”)
Output:
Textual content: ‘I used to be completely blown away by the performances in ‘Summer season’s Finish’. The appearing was top-notch, and the plot had me gripped from begin to end. A really charming cinematic expertise that I’d extremely suggest.’
Predicted Sentiment: constructive
Textual content: ‘The particular results in ‘Star Battles: Nebula Battle’ had been out of this world. I felt like I used to be really in house. The storyline was extremely participating and left me wanting extra. Glorious movie.’
Predicted Sentiment: constructive
Textual content: ”The Misplaced Symphony’ was a masterclass in character growth and storytelling. The rating was hauntingly lovely and complemented the extreme, emotional scenes completely. Kudos to the director and solid for creating such a masterpiece.’
Predicted Sentiment: constructive
Textual content: ‘I used to be completely blown away by the performances in ‘Summer season‘s Finish’. The appearing was high–notch, and the plot had me gripped from begin to end. A really charming cinematic expertise that I would extremely suggest.‘
Predicted Sentiment: constructive
Textual content: ‘The particular results in ‘Star Battles: Nebula Battle’ had been out of this world. I felt like I was really in house. The storyline was extremely participating and left me wanting extra. Glorious movie.‘
Predicted Sentiment: constructive
Textual content: ‘‘The Misplaced Symphony’ was a masterclass in character growth and storytelling. The rating was hauntingly lovely and complemented the intense, emotional scenes completely. Kudos to the director and solid for creating such a masterpiece.‘
Predicted Sentiment: constructive
The native mannequin outputs solely what it’s meant to, appearing as a classical machine studying mannequin would when it comes to output format, whereas nonetheless making use of the highly effective, language-based interior reasoning it was constructed for.
You’ve got simply leveraged an area Ollama mannequin to carry out a particular inference activity, textual content classification, totally inside the boundaries of your individual machine.
Wrapping Up
This text confirmed find out how to swap out cloud-based LLM APIs for native Ollama fashions to carry out inference duties with out subscription charges or delicate textual content knowledge leaving your machine. The important thing ingredient: the scikit-ollama library, which elegantly encapsulates this native integration and makes it accessible as simply one other scikit-learn pipeline.

