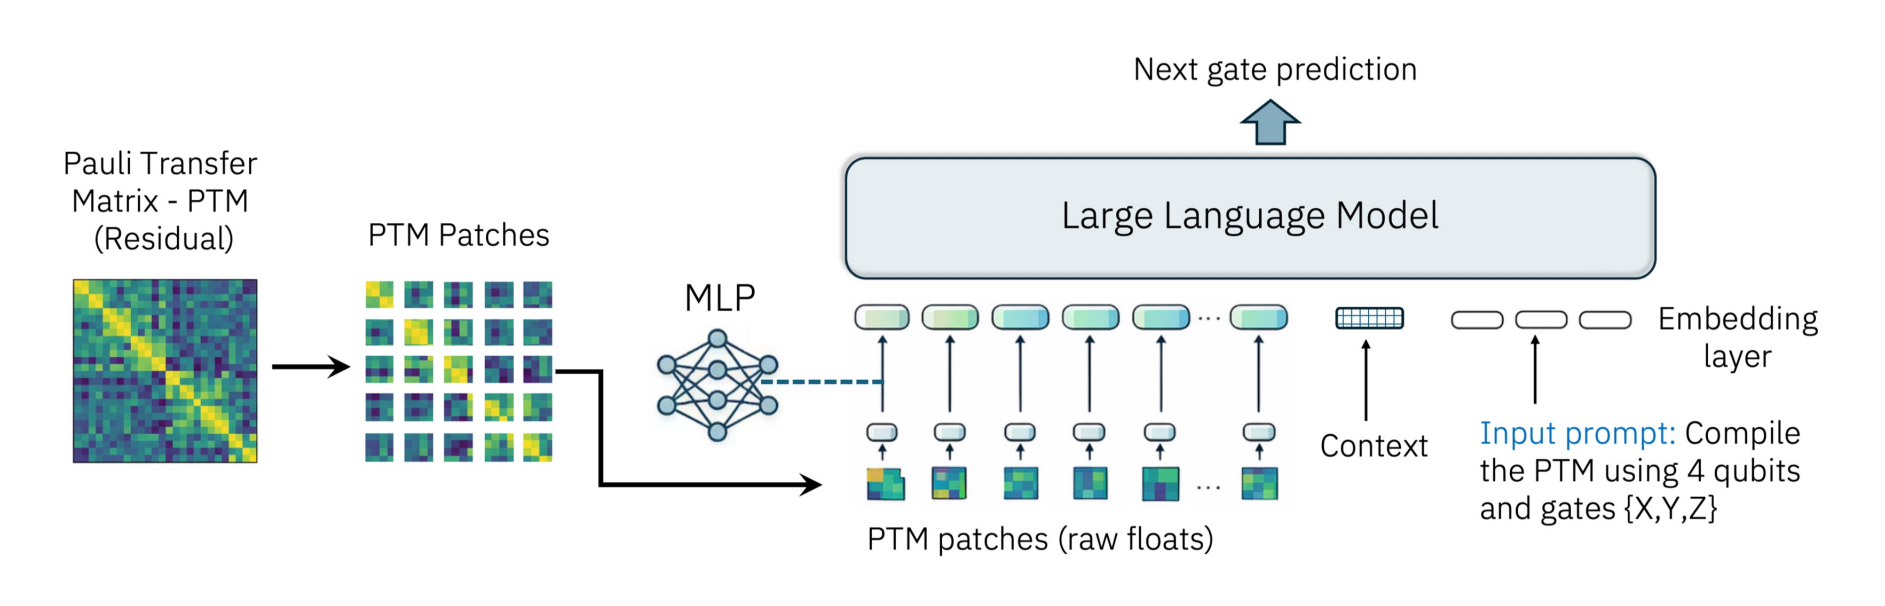
Researchers from the MIT-IBM Computing Analysis Lab and IBM Quantum have developed a multimodal alignment framework that maps quantum unitary operators instantly into the latent house of a giant language mannequin (LLM). Printed as an IEEE QCE 2026 convention paper (“Aligning Quantum Operators with Giant Language Fashions“), the structure treats mathematical quantum operations as “visible inputs.” By translating these steady numeric matrices into native phrase embeddings, the system allows an autoregressive LLM spine to cause over, compile, and manipulate quantum states alongside pure language directions.
[ IBM-MIT Quantum-Language Model ]
Core Spine ──► Granite 4.0 Micro (3B parameters) using an SFT next-token loss pipeline.
Quantum Modality ──► Actual-valued 256×256 Pauli Switch Matrices (PTM) mapped as patched picture grids.
Goal Surroundings ──► 4-qubit Clifford+T unitary synthesis inside a 256-way Pauli-rotation foundation.
Operational Utility ──► 99.4% compilation success (Finest-of-80); 91% zero-shot text-constraint compliance.
Cross-Modal Alignment of Pauli Switch Matrices
Earlier makes an attempt to leverage generative AI in quantum info science have operated solely on symbolic, text-based proxies equivalent to OpenQASM scripts, gate names, or Qiskit code repositories. These programs stay blind to the uncooked complex-valued matrices that outline bodily quantum transformations. The MIT-IBM framework bypasses this symbolic limitation by translating a goal unitary matrix (U) right into a real-valued Pauli Switch Matrix (PTM). For a 4-qubit system, the PTM is a 256×256 actual matrix that’s invariant to international section and composes multiplicatively.
The framework processes this matrix by treating it as a single-channel picture layer:
PTM Patch Tokenization: The 256×256 grid is partitioned into 16×16 non-overlapping patches, yielding 256 discrete visible patch vectors.
Latent House Projection: A linear layer compresses every patch right into a hidden dimension (hv=768), which is then mapped into the LLM’s token embedding house through a two-layer multi-layer perceptron (MLP) projector.
Stepwise Autoregressive “Peeling”: Somewhat than trying to output a whole quantum circuit format in a single go, the mannequin reads the re-encoded residual PTM at every inference step. It predicts precisely one π/8-Pauli rotation gate at a time in reverse execution order, left-multiplying the inverse PTM of its personal prediction again onto the residual matrix till the channel constancy (F=Tr(P)/4n) approaches 1.0.
Efficiency Scaling and Language-Conditioned Controls
The system was instantiated utilizing a Granite 4.0 Micro 3-billion parameter mannequin spine and validated in opposition to precise 4-qubit Clifford+T compilation targets. The supervised fine-tuning (SFT) pipeline demonstrated regular scaling metrics, with synthesis success charges leaping from 23.4% to 71.0% because the coaching dataset expanded to 9.2 million artificial circuits. When pre-trained fashions had been expanded to handle longer 30-gate depths and augmented with inference-time Finest-of-N stochastic sampling, the structure achieved a 99.4% total synthesis success fee. This efficiency outperformed classical simulated-annealing solvers (SynthetiQ) and specialised reinforcement studying fashions (Gumbel AlphaZero), which generally expertise sharp accuracy drops on gate depths exceeding 11 gates.
Past uncooked compilation, anchoring quantum operations inside an LLM latent house allows language-conditioned circuit synthesis. By introducing pure language textual content prompts instantly into the mannequin’s token sequence (e.g., specifying token constraints like “Allowed T(q0, q2)”), operators can prohibit which bodily qubits a gate can work together with throughout compilation.
Examined in opposition to an out-of-distribution benchmark that includes constraint mixtures totally blacklisted throughout coaching, the pre-trained Granite mannequin achieved 91% gate-level constraint compliance. When the constraint textual content was omitted, compliance dropped to 53%, confirming that the mannequin actively circumstances its mathematical matrix operations on plain language directions. This dual-modality token house supplies a foundational design pathway towards quantum-aware neural networks able to translating summary pure language necessities instantly into bodily {hardware} compilation layers.
Evaluation the official analysis briefing through the Rogerio Feris LinkedIn replace right here. The entire preprint detailing the patch ablation metrics, cross-modal loss features, and inference token architectures will be reviewed on the arXiv right here.
July 10, 2026