


Give an agent higher instruments and it ought to do higher work. That’s the intuition, anyway.
Once you open a pull request, Copilot code evaluate reads the diff and explores the encompassing code to seek out the issues that matter earlier than they ship. To do this, it used its personal code exploration instruments. So once we swapped within the better-maintained, shared instruments that energy the Copilot CLI, grep, glob, and think about, we anticipated a clear improve.
As an alternative, in our benchmarks, we discovered that the price of evaluations was increased and fewer points had been being caught.
However the instruments weren’t the issue. The directions had been. As soon as we rewrote them for the best way a reviewer really reads a pull request, the regression flipped right into a win: roughly 20% decrease common evaluate price, whereas sustaining the identical evaluate high quality.
That is the story of how adjusting the workflows across the instruments led us to a repair.
In the event you’ve constructed on high of an agent framework, you’ve in all probability inherited its instruments too. They work, so you retain them, till the day your use case drifts far sufficient from what they had been designed for that they quietly begin working towards you. That’s the scenario we had been in. Earlier than attempting to make use of the shared CLI instruments, Copilot code evaluate used its personal code exploration instruments. That software layer was impressed by earlier agentic techniques, together with concepts from SWE-agent-style repository navigation and GitHub Copilot Autofix: listing directories, search recordsdata, search directories, and browse code. These instruments labored, however they had been particular to Copilot code evaluate, and so they had been designed for the way fashions behaved on the time. Earlier agentic coding fashions made fewer software calls and had been worse at mechanically pulling in essential context. This meant it was extra vital to incorporate all related data within the few software calls that the mannequin made.
In the meantime, the Copilot CLI harness has a shared set of Unix-inspired code exploration instruments: grep, glob, and think about. That harness can be utilized by a rising variety of Copilot agent merchandise, together with GitHub Copilot cloud agent, so harness enhancements can profit multiple product. We wished to wash up and share infrastructure the place attainable, so we experimented with utilizing the instruments from the Copilot CLI harness in Copilot code evaluate. The objective was to cut back duplicated software implementations, create one shared place to enhance code exploration instruments, and make it simpler to hold these enhancements throughout Copilot merchandise.
On paper, the migration appeared easy:
The prevailing evaluate instruments weren’t skinny wrappers. When looking for a listing or studying a code vary, they may return the matched or requested strains plus additional surrounding code context. That added token price, nevertheless it additionally matched how earlier fashions typically benefited from having close by context included mechanically.
Initially, we hoped this could be a easy migration: swap one set of instruments for an additional. However once we examined the shared instruments in offline benchmarks, the evaluate agent turned much less environment friendly and fewer efficient. Common price elevated, and the variety of helpful feedback dropped.
The hint revealed a searching loop
Our inner Copilot code evaluate benchmarks had been helpful as a result of they present greater than a last rating. They present the trail the agent took, together with which instruments it referred to as, how a lot output got here again, the place errors occurred, and whether or not it was narrowing towards proof or widening the search.
Once we first tried the shared Copilot CLI instruments in offline benchmarks, the agent typically behaved as if it was searching a repository as a substitute of investigating a pull request. It will search broadly, guess seemingly paths, learn broadly, discover extra issues to go looking, and carry that additional context ahead.
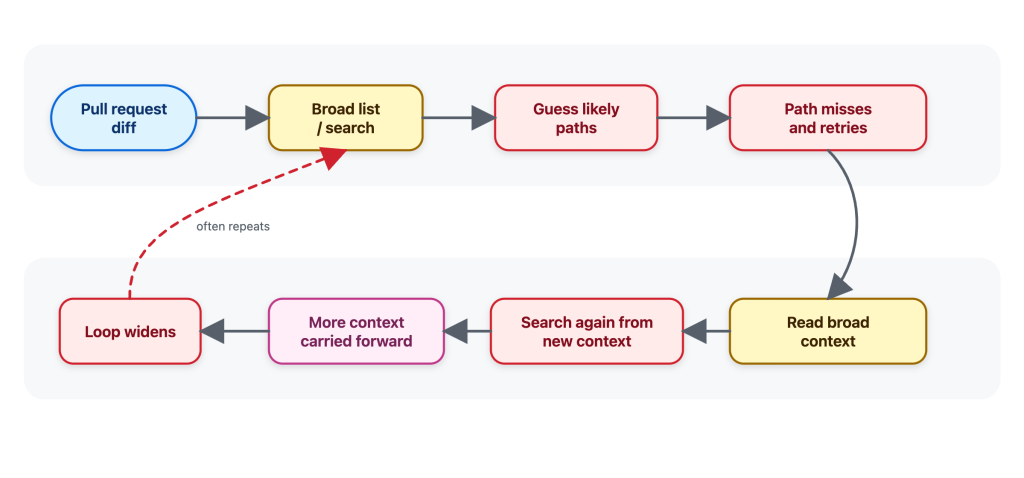
That sample is comprehensible. Broad exploration may be helpful when the duty is “perceive this repo.” But it surely’s not how a reviewer would normally evaluate a pull request.
Once I evaluate a pull request, I begin from the diff and ask focused questions:
The place is that this perform referred to as?
Is that this config key used wherever else?
Is there a take a look at or helper with the identical sample?
What’s the smallest close by code vary that explains this habits?
I don’t wish to open a big a part of the repository earlier than I do know what I’m searching for. I would like the minimal context wanted to reply the query, with out overloading the evaluate with unrelated code.
That issues as a result of each software outcome turns into a part of the agent’s working context. Further file contents may be carried ahead into later reasoning, growing price and typically making the evaluate much less targeted. A software outcome shouldn’t be a disposable printout; for an agent, it’s additional tokens that keep within the context window.
The traces made that distinction seen. The shared instruments weren’t the issue. The directions had been giving the agent the incorrect instincts to do an environment friendly and efficient evaluate.
The instruments themselves labored, however their directions had been tuned for his or her use throughout the Copilot CLI and implied the incorrect workflow: the agent used grep, glob, and think about like a broad coding assistant as a substitute of a reviewer. A coding assistant might map a complete space earlier than making a change to make sure it doesn’t break another nook of the code. Then again, a reviewer normally begins from the diff, asks whether or not the change launched an issue, after which seems for the narrowest close by proof required to verify or dismiss it.
Normal coding-assistant software directions, like those utilized by Copilot CLI or Copilot cloud agent, make sense for an interactive assistant. A developer might ask it to know a repository, plan a change, edit recordsdata, and proceed over a number of turns.
Copilot code evaluate has a narrower job: begin from a pull request diff, collect sufficient surrounding proof to resolve whether or not a change introduces an actual problem, and keep away from loading context that’s not wanted for that evaluate query.
It was due to this fact clear that we couldn’t merely change the earlier Copilot code evaluate instruments with the instruments from the Copilot CLI with out further prompting work. The issue turned: how will we design software directions that use these shared instruments successfully in a code evaluate setting?
The subsequent iterations made the steering particular to code evaluate. The workflow we wished Copilot code evaluate to comply with was:
Begin from the diff and kind particular evaluate questions.
Use glob when the trail is unsure and grep to seek out candidate recordsdata, symbols, and name websites.
Batch low cost discovery earlier than studying recordsdata.
Use view solely when the agent is aware of which file or line vary it wants.
Batch targeted reads as a substitute of alternating between one search and one learn.
In oversimplified kind, this was the habits we encoded:
Generic posture: Use the obtainable instruments to examine repository context which may be related.
Overview-shaped steering: Begin from the diff. Slim first with grep and glob; learn precise proof with view. If grep fails to seek out related context, retry with a less complicated escaped search. If a path is incorrect, pivot to glob as a substitute of guessing close by paths.
For instance, think about the diff adjustments an authorization helper that decides whether or not an operation is allowed. A related evaluate query shouldn’t be “present me the complete contents of each file that calls this helper.” It might as a substitute be the narrower: “are any request-handling callers counting on the previous habits?”
The supposed path is brief:
grep for callers of that helper
glob for seemingly route, handler, or controller recordsdata
view probably the most related caller ranges
resolve whether or not any caller adjustments the chance
The steering additionally modified how the agent recovered from failed searches. If an enter made grep fail, the higher subsequent step was one easier, corrected search. If a path was incorrect, the higher subsequent step was glob, not guessing neighboring paths and studying no matter occurred to exist. That nudged the agent away from letting a small software failure flip into a bigger exploration loop.
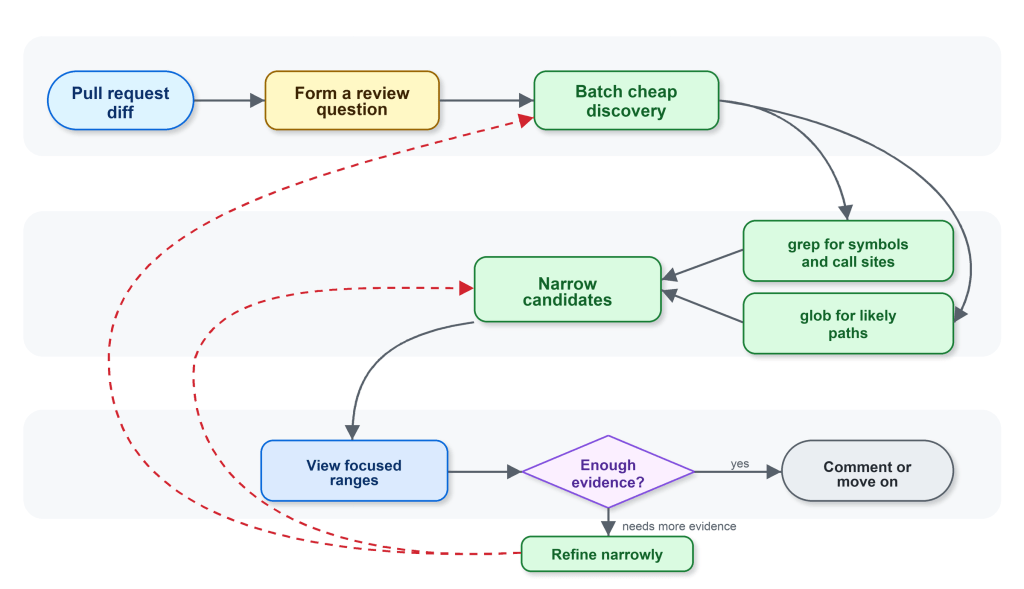
The change was small in wording and enormous in impact. It modified the rhythm of the agent from “browse, learn, search once more” to “ask, slim, learn, resolve.”
Benchmarks allow us to debug habits, not simply scores
The shared harness gave us the instruments. The inner Copilot code evaluate benchmarks gave us the suggestions loop.
We might run the identical evaluate examples, evaluate software traces, replace the directions, and run once more. That permit us ask concrete questions:
Did the agent slim first, or learn broadly first?
Did it batch impartial searches?
Did it name view solely when it had a motive?
Did a tool-instruction change scale back software errors, or simply transfer them elsewhere?
Did the hint keep targeted on proof from the diff?
Did the evaluate nonetheless protect the standard metrics we cared about?
Essentially the most helpful sign was not “the directions are higher.” It was extra concrete. The agent was making the same variety of software calls, however spending extra of them on related proof as a substitute of repeatedly increasing the search.
That related product-level outcomes to comprehensible engineering habits. As an alternative of guessing why a rating moved, we might examine the workflow that produced it.
The outcome: roughly 20% decrease common evaluate price
In manufacturing, the tuned habits confirmed roughly 20% decrease common evaluate price in contrast with the management. Importantly, it didn’t present a high quality sign that would block transport.
The discount didn’t come from the instruments by themselves, it got here from the workflow round them. Shared code exploration instruments, Copilot code evaluate customized software directions, and inner benchmarks made the agent’s habits seen sufficient to tune.
That framing issues when constructing with brokers. It may be tempting to deal with instruments as implementation particulars by swapping one software for an additional, then evaluating the ultimate reply. However for an agent, the software floor is a part of the product expertise. It adjustments what the agent notices, the way it searches, how a lot context it carries ahead, and when it decides it has sufficient proof.
Instrument descriptions and system directions are nearer to API documentation. Unclear API docs can go away a developer confused and result in inefficient or incorrect selections. Unclear software prompting can do the identical for an LLM; a small wording change can have an effect on price, high quality, and the form of the investigation as a result of it adjustments how the agent spends its consideration.
We additionally tried to use the identical sort of targeted software directions within the CLI, the place it didn’t produce the identical sort of win. That may be a helpful counterexample, and an vital guardrail for the lesson.
Copilot code evaluate is anchored to a diff and a evaluate query. Copilot CLI handles broader, interactive coding duties the place exploration may be a part of the job. There could also be no single diff anchor, the consumer might change course over a number of turns, and the correct context is probably not apparent in the beginning. The identical grep, glob, and think about instruments can assist each merchandise, however the workflow round these instruments has to match the product.
The takeaway is that shared instruments scale when the directions and benchmarks match the job.
Attempt it out your self utilizing GitHub Copilot code evaluate.
Written by


