On this article, you’ll study why agent accuracy degrades as a instrument catalog grows, and 6 sensible methods for retaining instrument choice correct and environment friendly at scale.
Matters we’ll cowl embody:
Why including extra instruments to an agent causes instrument hallucination and accuracy loss, not simply slower responses.
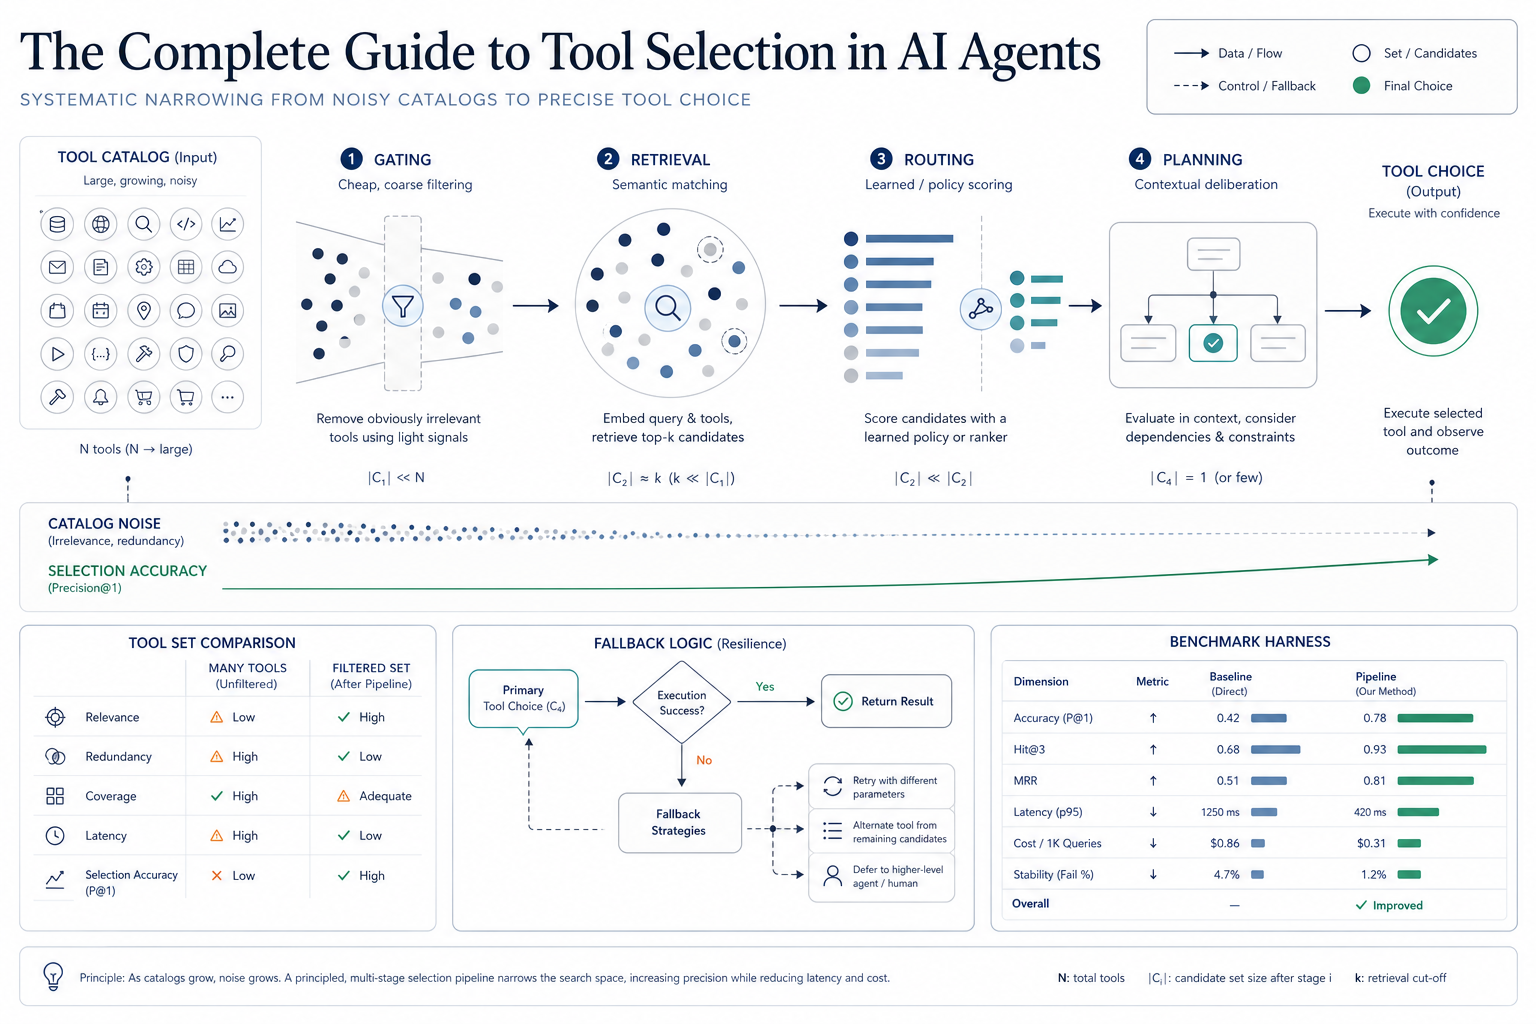
How gating, retrieval, routing, and planning every slim down what the mannequin sees earlier than it has to decide on a instrument.
How one can construct fallback logic and a benchmark harness so you’ll be able to measure whether or not any of those fixes really labored.
None of this requires an even bigger mannequin, only a smarter view of what the mannequin sees earlier than it acts.
Introduction
You construct an agent with 5 instruments. It really works flawlessly within the demo. Three months later, it has 40 file operations, CRM entry, Slack, a calendar, and three totally different search APIs you bolted on for various groups. The identical agent that nailed each demo now calls the mistaken instrument, hallucinates parameters borrowed from a special instrument’s schema, or stalls mid-task ready on a name that ought to by no means have been made.
Nothing concerning the mannequin modified. The instrument checklist did. This isn’t an edge case you’ll ultimately run into. It’s the default trajectory of each agent that ships after which grows. Analysis analyzing MCP instrument descriptions throughout the ecosystem has discovered {that a} excessive quantity comprise at the very least one high quality problem, and manufacturing benchmarks present agent accuracy degrading measurably as soon as instrument counts cross roughly 10 to fifteen. The RAG-MCP paper, printed in Could 2025, put laborious numbers on the repair: retrieval-based instrument choice greater than tripled instrument choice accuracy from 13.62% to 43.13% whereas reducing immediate tokens by over half on the identical benchmark duties.
Software choice isn’t a minor implementation element you patch later. It’s the architectural resolution that determines whether or not an agent survives contact with an actual instrument catalog. This information covers six methods that resolve it, within the order you’d really deploy them: gating, retrieval, routing, planning, fallback logic, and the benchmark that tells you whether or not any of it labored.
Why Software Choice Breaks at Scale
Each instrument definition — its title, description, and parameter schema — will get despatched to the mannequin on each single request, whether or not that instrument will get used or not. With 50-plus instruments, this may eat 5 to 7% of the mannequin’s context earlier than the consumer’s precise message arrives, crowding out the dialog historical past and reasoning house the duty really wants.
The “misplaced within the center” impact compounds this. Fashions recall info initially and finish of a context window way more reliably than info buried within the center. With dozens of near-identical instrument definitions stacked in sequence, the one instrument that’s really proper for the job usually sits precisely in that useless zone, ignored not as a result of the mannequin can’t motive about it, however as a result of consideration is structurally pulled elsewhere.
The second failure mode is worse: instrument hallucination. When an LLM’s consideration spreads throughout too many similar-sounding instruments, it both invents instrument names that don’t exist or calls the right instrument whereas filling in arguments borrowed from a special instrument’s schema. This can be a laborious failure. There’s no “barely mistaken” option to name a nonexistent operate.
OpenAI paperwork a tough ceiling of 128 instruments per agent, however actual degradation exhibits up effectively earlier than that restrict; most manufacturing groups see accuracy drop noticeably as soon as they cross 15 to twenty instruments in lively rotation. The repair isn’t an even bigger context window. It’s controlling what the mannequin sees within the first place.
Gating: Deciding Whether or not a Software Is Wanted at All
Earlier than you optimize which instrument to select, ask a less expensive query first: does this flip want a instrument in any respect? A significant fraction of agent turns are purely conversational: “thanks,” “what do you imply by that,” a follow-up clarification. Operating full retrieval and tool-selection reasoning on each single flip means paying the complete agentic overhead even when the reply is “no instrument wanted.”
A gate is a quick, low cost classifier — generally a small mannequin name, generally simply sample matching — that runs earlier than something costly does.
# gate.py
# Stipulations: none past Python’s normal library (re)
# Run: python gate.py
import re
CONVERSATIONAL_PATTERNS = [
r”^s*(thanks|thank you|thx|ok|okay|cool|got it|sounds good|sure|great)b”,
r”^s*(hi|hello|hey|good morning|good evening)b”,
r”^s*what do you meanb”,
r”^s*can you (clarify|explain that)b”,
]
ACTION_KEYWORDS = [
“send”, “create”, “search”, “find”, “look up”, “schedule”, “book”,
“read”, “write”, “query”, “summarize”, “translate”, “check”,
]
def gate(question: str) -> dict:
“””
Low-cost pre-filter that decides whether or not the complete tool-selection pipeline
must run in any respect. Quick-circuits conversational turns earlier than
retrieval, routing, or planning ever fires.
“””
q_lower = question.strip().decrease()
# Tier 1: regex match in opposition to identified conversational patterns — near-zero price
for sample in CONVERSATIONAL_PATTERNS:
if re.match(sample, q_lower):
return {“tool_needed”: False, “motive”: “conversational_pattern”, “tier”: 1}
# Tier 2: if there is no motion verb and the message is brief, seemingly no instrument wanted
has_action_keyword = any(kw in q_lower for kw in ACTION_KEYWORDS)
if not has_action_keyword and len(q_lower.break up()) < 5:
return {“tool_needed”: False, “motive”: “short_with_no_action_keyword”, “tier”: 2}
return {“tool_needed”: True, “motive”: “action_keyword_or_long_query”, “tier”: 2}
if __name__ == “__main__”:
test_queries = [
“thanks!”,
“What’s the weather like in Lagos today?”,
“ok”,
“Can you send an email to the sales team about the delay?”,
]
for q in test_queries:
end result = gate(q)
print(f”‘{q}’ -> tool_needed={end result[‘tool_needed’]} ({end result[‘reason’]})”)
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
# gate.py
# Stipulations: none past Python’s normal library (re)
# Run: python gate.py
import re
CONVERSATIONAL_PATTERNS = [
r“^s*(thanks|thank you|thx|ok|okay|cool|got it|sounds good|sure|great)b”,
r“^s*(hi|hello|hey|good morning|good evening)b”,
r“^s*what do you meanb”,
r“^s*can you (clarify|explain that)b”,
]
ACTION_KEYWORDS = [
“send”, “create”, “search”, “find”, “look up”, “schedule”, “book”,
“read”, “write”, “query”, “summarize”, “translate”, “check”,
]
def gate(question: str) -> dict:
“”“
Low-cost pre-filter that decides whether or not the complete tool-selection pipeline
must run in any respect. Quick-circuits conversational turns earlier than
retrieval, routing, or planning ever fires.
““”
q_lower = question.strip().decrease()
# Tier 1: regex match in opposition to identified conversational patterns — near-zero price
for sample in CONVERSATIONAL_PATTERNS:
if re.match(sample, q_lower):
return {“tool_needed”: False, “motive”: “conversational_pattern”, “tier”: 1}
# Tier 2: if there is no motion verb and the message is brief, seemingly no instrument wanted
has_action_keyword = any(kw in q_lower for kw in ACTION_KEYWORDS)
if not has_action_keyword and len(q_lower.break up()) < 5:
return {“tool_needed”: False, “motive”: “short_with_no_action_keyword”, “tier”: 2}
return {“tool_needed”: True, “motive”: “action_keyword_or_long_query”, “tier”: 2}
if __name__ == “__main__”:
test_queries = [
“thanks!”,
“What’s the weather like in Lagos today?”,
“ok”,
“Can you send an email to the sales team about the delay?”,
]
for q in test_queries:
end result = gate(q)
print(f“‘{q}’ -> tool_needed={end result[‘tool_needed’]} ({end result[‘reason’]})”)
How one can run (no dependencies required):
This prices virtually nothing and catches a significant share of turns earlier than they attain the costly a part of the pipeline. The edge for “is that this price constructing” is low: if even 20–30% of your turns are conversational, gating pays for itself instantly in each latency and token price.
Retrieval-Based mostly Software Choice
That is the approach with the strongest printed proof behind it. As an alternative of sending each instrument definition on each name, you index instrument descriptions in a vector retailer, embed the incoming question, retrieve solely the top-Ok most related instruments, and ship simply these to the mannequin.
The RAG-MCP framework is the reference implementation of this concept, utilizing semantic retrieval to determine probably the most related MCP instruments for a question earlier than the LLM ever sees the complete catalog. The reported numbers aren’t delicate: instrument choice accuracy rose from 13.62% with the complete catalog uncovered to 43.13% with retrieval-filtered choice, greater than tripling accuracy, whereas reducing immediate tokens by over 50% on the identical benchmark duties.
# retriever.py
# Stipulations: pip set up sentence-transformers faiss-cpu numpy
# Run: python retriever.py
import numpy as np
from sentence_transformers import SentenceTransformer
import faiss
TOOL_CATALOG = [
{“name”: “search_web”, “description”: “Search the web for current information on any topic”},
{“name”: “read_file”, “description”: “Read the contents of a file given its path”},
{“name”: “write_file”, “description”: “Write or overwrite content to a file at a given path”},
{“name”: “send_email”, “description”: “Send an email to a recipient with subject and body”},
{“name”: “create_calendar_event”, “description”: “Create a new calendar event with a title, date, and time”},
{“name”: “query_database”, “description”: “Run a SQL query against the company database”},
{“name”: “list_github_issues”, “description”: “List open issues in a GitHub repository”},
{“name”: “create_github_pr”, “description”: “Create a pull request on a GitHub repository”},
{“name”: “send_slack_message”, “description”: “Send a message to a Slack channel or user”},
{“name”: “get_weather”, “description”: “Get current weather conditions for a city”},
{“name”: “translate_text”, “description”: “Translate text from one language to another”},
{“name”: “summarize_document”, “description”: “Summarize a long document into key points”},
{“name”: “lookup_stock_price”, “description”: “Get the current stock price for a ticker symbol”},
{“name”: “book_flight”, “description”: “Search and book a flight between two cities”},
{“name”: “create_invoice”, “description”: “Generate an invoice for a customer with line items”},
]
class ToolRetriever:
“””
Embeds instrument descriptions as soon as at startup and indexes them in FAISS.
At runtime, embeds the incoming question and returns solely the top-Ok
most related instruments — not the complete catalog.
“””
def __init__(self, instruments: checklist[dict], model_name: str = “all-MiniLM-L6-v2″):
self.instruments = instruments
self.mannequin = SentenceTransformer(model_name)
descriptions = [f”{t[‘name’]}: {t[‘description’]}” for t in instruments]
embeddings = self.mannequin.encode(descriptions, normalize_embeddings=True)
# IndexFlatIP = internal product search, which equals cosine similarity
# when vectors are normalized — the usual setup for this use case.
self.index = faiss.IndexFlatIP(embeddings.form[1])
self.index.add(np.array(embeddings, dtype=np.float32))
def retrieve(self, question: str, top_k: int = 3) -> checklist[dict]:
query_emb = self.mannequin.encode([query], normalize_embeddings=True)
scores, indices = self.index.search(np.array(query_emb, dtype=np.float32), top_k)
return [
{**self.tools[idx], “rating”: float(rating)}
for rating, idx in zip(scores[0], indices[0])
]
if __name__ == “__main__”:
retriever = ToolRetriever(TOOL_CATALOG)
queries = [
“What’s the weather like in Lagos today?”,
“Can you check if there are any open bugs in our repo?”,
“Send a message to the engineering channel about the deploy”,
]
for q in queries:
outcomes = retriever.retrieve(q, top_k=3)
print(f”nQuery: ‘{q}'”)
for r in outcomes:
print(f” {r[‘name’]} (rating={r[‘score’]:.3f})”)
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
# retriever.py
# Stipulations: pip set up sentence-transformers faiss-cpu numpy
# Run: python retriever.py
import numpy as np
from sentence_transformers import SentenceTransformer
import faiss
TOOL_CATALOG = [
{“name”: “search_web”, “description”: “Search the web for current information on any topic”},
{“name”: “read_file”, “description”: “Read the contents of a file given its path”},
{“name”: “write_file”, “description”: “Write or overwrite content to a file at a given path”},
{“name”: “send_email”, “description”: “Send an email to a recipient with subject and body”},
{“name”: “create_calendar_event”, “description”: “Create a new calendar event with a title, date, and time”},
{“name”: “query_database”, “description”: “Run a SQL query against the company database”},
{“name”: “list_github_issues”, “description”: “List open issues in a GitHub repository”},
{“name”: “create_github_pr”, “description”: “Create a pull request on a GitHub repository”},
{“name”: “send_slack_message”, “description”: “Send a message to a Slack channel or user”},
{“name”: “get_weather”, “description”: “Get current weather conditions for a city”},
{“name”: “translate_text”, “description”: “Translate text from one language to another”},
{“name”: “summarize_document”, “description”: “Summarize a long document into key points”},
{“name”: “lookup_stock_price”, “description”: “Get the current stock price for a ticker symbol”},
{“name”: “book_flight”, “description”: “Search and book a flight between two cities”},
{“name”: “create_invoice”, “description”: “Generate an invoice for a customer with line items”},
]
class ToolRetriever:
“”“
Embeds instrument descriptions as soon as at startup and indexes them in FAISS.
At runtime, embeds the incoming question and returns solely the top-Ok
most related instruments — not the complete catalog.
““”
def __init__(self, instruments: checklist[dict], model_name: str = “all-MiniLM-L6-v2”):
self.instruments = instruments
self.mannequin = SentenceTransformer(model_name)
descriptions = [f“{t[‘name’]}: {t[‘description’]}” for t in instruments]
embeddings = self.mannequin.encode(descriptions, normalize_embeddings=True)
# IndexFlatIP = internal product search, which equals cosine similarity
# when vectors are normalized — the usual setup for this use case.
self.index = faiss.IndexFlatIP(embeddings.form[1])
self.index.add(np.array(embeddings, dtype=np.float32))
def retrieve(self, question: str, top_k: int = 3) -> checklist[dict]:
query_emb = self.mannequin.encode([query], normalize_embeddings=True)
scores, indices = self.index.search(np.array(query_emb, dtype=np.float32), top_k)
return [
{**self.tools[idx], “rating”: float(rating)}
for rating, idx in zip(scores[0], indices[0])
]
if __name__ == “__main__”:
retriever = ToolRetriever(TOOL_CATALOG)
queries = [
“What’s the weather like in Lagos today?”,
“Can you check if there are any open bugs in our repo?”,
“Send a message to the engineering channel about the deploy”,
]
for q in queries:
outcomes = retriever.retrieve(q, top_k=3)
print(f“nQuery: ‘{q}'”)
for r in outcomes:
print(f” {r[‘name’]} (rating={r[‘score’]:.3f})”)
How one can run:
pip set up sentence-transformers faiss-cpu numpy
python retriever.py
pip set up sentence–transformers faiss–cpu numpy
python retriever.py
Solely the top-3 instruments out of a 15-tool catalog get despatched to the mannequin per question, an 80% discount in instrument definitions on each name, and the accuracy raise compounds as a result of the mannequin is now selecting between a handful of genuinely related candidates as a substitute of scanning previous a dozen near-misses.
Semantic Routing
Routing is retrieval’s lighter cousin, and it suits a special form of downside. Retrieval solutions “which particular instrument” out of a flat checklist. Routing solutions “which toolbox” — helpful when your instruments cluster naturally into classes (knowledge, communication, scheduling) and also you wish to load solely the related class’s instruments relatively than re-ranking the complete catalog each time.
# router.py
# Stipulations: pip set up scikit-learn numpy
# Run: python router.py
import numpy as np
from sklearn.feature_extraction.textual content import TfidfVectorizer
from sklearn.metrics.pairwise import cosine_similarity
CATEGORIES = {
“knowledge”: [“query the database”, “read a file”, “write data to storage”, “run a SQL query”],
“communication”: [“send an email”, “post a slack message”, “notify the team”, “send a message”],
“scheduling”: [“create a calendar event”, “book a meeting”, “schedule an appointment”],
}
class SemanticRouter:
“””
Routes a question to a instrument class utilizing similarity in opposition to class
centroid embeddings. Falls again to ‘basic’ when no class clears
the boldness threshold — by no means guesses on a low-confidence match.
“””
def __init__(self, classes: dict[str, list[str]], confidence_threshold: float = 0.15):
self.threshold = confidence_threshold
self.vectorizer = TfidfVectorizer()
all_examples = [ex for exs in categories.values() for ex in exs]
self.vectorizer.match(all_examples)
# Construct one centroid vector per class by averaging its instance embeddings
self.centroids = {}
for cat, examples in classes.objects():
vecs = self.vectorizer.rework(examples).toarray()
self.centroids[cat] = vecs.imply(axis=0)
def route(self, question: str) -> dict:
query_vec = self.vectorizer.rework([query]).toarray()[0]
scores = {
cat: float(cosine_similarity([query_vec], [centroid])[0][0])
for cat, centroid in self.centroids.objects()
}
best_cat = max(scores, key=scores.get)
best_score = scores[best_cat]
if best_score < self.threshold:
return {“class”: “basic”, “confidence”: best_score}
return {“class”: best_cat, “confidence”: best_score}
if __name__ == “__main__”:
router = SemanticRouter(CATEGORIES)
test_queries = [
“Can you post a message in the sales Slack channel?”,
“I need to run a query against our production database”,
“Schedule a meeting with the design team for tomorrow”,
“asdkj qpwoe zxcv nonsense”,
]
for q in test_queries:
end result = router.route(q)
print(f”‘{q}’ -> {end result[‘category’]} (confidence={end result[‘confidence’]:.3f})”)
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
# router.py
# Stipulations: pip set up scikit-learn numpy
# Run: python router.py
import numpy as np
from sklearn.feature_extraction.textual content import TfidfVectorizer
from sklearn.metrics.pairwise import cosine_similarity
CATEGORIES = {
“knowledge”: [“query the database”, “read a file”, “write data to storage”, “run a SQL query”],
“communication”: [“send an email”, “post a slack message”, “notify the team”, “send a message”],
“scheduling”: [“create a calendar event”, “book a meeting”, “schedule an appointment”],
}
class SemanticRouter:
“”“
Routes a question to a instrument class utilizing similarity in opposition to class
centroid embeddings. Falls again to ‘basic’ when no class clears
the boldness threshold — by no means guesses on a low-confidence match.
““”
def __init__(self, classes: dict[str, list[str]], confidence_threshold: float = 0.15):
self.threshold = confidence_threshold
self.vectorizer = TfidfVectorizer()
all_examples = [ex for exs in categories.values() for ex in exs]
self.vectorizer.match(all_examples)
# Construct one centroid vector per class by averaging its instance embeddings
self.centroids = {}
for cat, examples in classes.objects():
vecs = self.vectorizer.rework(examples).toarray()
self.centroids[cat] = vecs.imply(axis=0)
def route(self, question: str) -> dict:
query_vec = self.vectorizer.rework([query]).toarray()[0]
scores = {
cat: float(cosine_similarity([query_vec], [centroid])[0][0])
for cat, centroid in self.centroids.objects()
}
best_cat = max(scores, key=scores.get)
best_score = scores[best_cat]
if best_score < self.threshold:
return {“class”: “basic”, “confidence”: best_score}
return {“class”: best_cat, “confidence”: best_score}
if __name__ == “__main__”:
router = SemanticRouter(CATEGORIES)
test_queries = [
“Can you post a message in the sales Slack channel?”,
“I need to run a query against our production database”,
“Schedule a meeting with the design team for tomorrow”,
“asdkj qpwoe zxcv nonsense”,
]
for q in test_queries:
end result = router.route(q)
print(f“‘{q}’ -> {end result[‘category’]} (confidence={end result[‘confidence’]:.3f})”)
How one can run:
pip set up scikit-learn numpy
python router.py
pip set up scikit–study numpy
python router.py
The fallback to “basic” on the gibberish question issues as a lot as the right routes do. A router that at all times picks one thing, even on a question it has no actual sign for, is extra harmful than one which admits it doesn’t know.
Planner-Based mostly Software Choice
Retrieval and routing each reply “what’s related to this single flip.” Multi-step duties want one thing totally different: a sequence of instrument calls deliberate upfront, with every step scoped to solely the instruments it particularly wants. That is the structure that avoids what’s generally referred to as the God Agent anti-pattern — a single agent holding 20 instruments in context with no plan construction — the place a failure anyplace corrupts the entire activity.
The sample: ask the mannequin to output a structured plan first, an ordered checklist of subtasks, every tagged with the aptitude it requires, earlier than any instrument executes. Then retrieve instruments per step, scoped to that step’s tag.
# planner.py
# Stipulations: none past Python’s normal library (json)
# Run: python planner.py
import json
from dataclasses import dataclass
@dataclass
class PlanStep:
step_number: int
description: str
required_capability: str
def parse_plan(raw_plan_json: str) -> checklist[PlanStep]:
“””Parse a planner LLM’s JSON output into structured PlanStep objects.”””
knowledge = json.hundreds(raw_plan_json)
return [
PlanStep(s[“step_number”], s[“description”], s[“required_capability”])
for s in knowledge[“steps”]
]
# Functionality -> tool-name mapping. In manufacturing this feeds the retriever
# from the earlier part, scoped to solely the instruments tagged for this functionality.
CAPABILITY_TOOLS = {
“search”: [“search_web”, “query_database”],
“file_io”: [“read_file”, “write_file”],
“communication”: [“send_email”, “send_slack_message”],
“synthesis”: [“summarize_document”],
}
def get_scoped_tools(step: PlanStep) -> checklist[str]:
“””Return solely the instruments related to this step — not the complete catalog.”””
return CAPABILITY_TOOLS.get(step.required_capability, [])
if __name__ == “__main__”:
# This JSON would usually come from an LLM name asking it to decompose
# the duty into steps, every tagged with the aptitude it wants.
mock_plan = json.dumps({
“steps”: [
{“step_number”: 1, “description”: “Search for the latest sales report file”, “required_capability”: “search”},
{“step_number”: 2, “description”: “Read the contents of the report file”, “required_capability”: “file_io”},
{“step_number”: 3, “description”: “Summarize the key findings”, “required_capability”: “synthesis”},
{“step_number”: 4, “description”: “Email the summary to the sales lead”, “required_capability”: “communication”},
]
})
plan = parse_plan(mock_plan)
for step in plan:
scoped = get_scoped_tools(step)
print(f”Step {step.step_number}: {step.description}”)
print(f” Functionality: {step.required_capability} -> instruments accessible: {scoped}”)
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
# planner.py
# Stipulations: none past Python’s normal library (json)
# Run: python planner.py
import json
from dataclasses import dataclass
@dataclass
class PlanStep:
step_number: int
description: str
required_capability: str
def parse_plan(raw_plan_json: str) -> checklist[PlanStep]:
“”“Parse a planner LLM’s JSON output into structured PlanStep objects.”“”
knowledge = json.hundreds(raw_plan_json)
return [
PlanStep(s[“step_number”], s[“description”], s[“required_capability”])
for s in knowledge[“steps”]
]
# Functionality -> tool-name mapping. In manufacturing this feeds the retriever
# from the earlier part, scoped to solely the instruments tagged for this functionality.
CAPABILITY_TOOLS = {
“search”: [“search_web”, “query_database”],
“file_io”: [“read_file”, “write_file”],
“communication”: [“send_email”, “send_slack_message”],
“synthesis”: [“summarize_document”],
}
def get_scoped_tools(step: PlanStep) -> checklist[str]:
“”“Return solely the instruments related to this step — not the complete catalog.”“”
return CAPABILITY_TOOLS.get(step.required_capability, [])
if __name__ == “__main__”:
# This JSON would usually come from an LLM name asking it to decompose
# the duty into steps, every tagged with the aptitude it wants.
mock_plan = json.dumps({
“steps”: [
{“step_number”: 1, “description”: “Search for the latest sales report file”, “required_capability”: “search”},
{“step_number”: 2, “description”: “Read the contents of the report file”, “required_capability”: “file_io”},
{“step_number”: 3, “description”: “Summarize the key findings”, “required_capability”: “synthesis”},
{“step_number”: 4, “description”: “Email the summary to the sales lead”, “required_capability”: “communication”},
]
})
plan = parse_plan(mock_plan)
for step in plan:
scoped = get_scoped_tools(step)
print(f“Step {step.step_number}: {step.description}”)
print(f” Functionality: {step.required_capability} -> instruments accessible: {scoped}”)
How one can run (no dependencies required):
Every step on this instance sees one or two instruments, by no means the complete set. That’s the precise mechanism behind why planning helps: it’s not that the mannequin causes higher when it has a plan; it’s that the plan enables you to legitimately slim the instrument checklist per step, which is identical lever retrieval pulls, utilized at a finer grain.
Fallback Logic
Retrieval and routing each fail generally, not as a result of the structure is mistaken, however as a result of actual queries are ambiguous, underspecified, or genuinely outdoors the instrument catalog’s protection. What you do when the highest match’s confidence is low determines whether or not your agent degrades gracefully or begins guessing.
A 3-tier fallback chain handles this with out resorting to a attempt/besides that simply crashes the dialog: resolve instantly when confidence is excessive, retry with a reformulated question when it isn’t, and escalate to an specific clarification request relatively than forcing a instrument name when even the retry comes up brief.
# fallback.py
# Stipulations: pip set up scikit-learn numpy
# Run: python fallback.py
import numpy as np
from sklearn.feature_extraction.textual content import TfidfVectorizer
from sklearn.metrics.pairwise import cosine_similarity
TOOL_CATALOG = [
{“name”: “search_web”, “description”: “Search the web for current information on any topic”},
{“name”: “get_weather”, “description”: “Get the current weather forecast for a city”},
{“name”: “send_email”, “description”: “Send an email to a recipient with subject and body”},
{“name”: “list_github_issues”, “description”: “List open issues and bugs in a GitHub repository”},
]
class RetrieverWithFallback:
“””
Wraps retrieval with a three-tier fallback chain:
1. Excessive confidence -> use the highest end result instantly
2. Low confidence -> retry with a reformulated question
3. Nonetheless low -> escalate to a clarification request, by no means guess
“””
def __init__(self, instruments, confidence_threshold: float = 0.12):
self.instruments = instruments
self.threshold = confidence_threshold
self.vectorizer = TfidfVectorizer()
descs = [f”{t[‘name’]}: {t[‘description’]}” for t in instruments]
self.tool_vectors = self.vectorizer.fit_transform(descs)
def _raw_retrieve(self, question: str):
query_vec = self.vectorizer.rework([query])
sims = cosine_similarity(query_vec, self.tool_vectors)[0]
top_idx = int(np.argmax(sims))
return self.instruments[top_idx], float(sims[top_idx])
def retrieve_with_fallback(self, question: str) -> dict:
instrument, rating = self._raw_retrieve(question)
if rating >= self.threshold:
return {“standing”: “resolved”, “instrument”: instrument[“name”], “confidence”: rating, “makes an attempt”: 1}
# Reformulate by stripping filler phrases. In manufacturing, this step would
# be an LLM name asking it to restate the question when it comes to intent/functionality.
reformulated = question.exchange(“are you able to”, “”).exchange(“please”, “”).exchange(“?”, “”).strip()
tool2, score2 = self._raw_retrieve(reformulated)
if score2 >= self.threshold:
return {“standing”: “resolved”, “instrument”: tool2[“name”], “confidence”: score2, “makes an attempt”: 2}
return {
“standing”: “escalated”, “instrument”: None,
“confidence”: max(rating, score2), “makes an attempt”: 2,
“clarification_request”: (
f”I am not assured which instrument suits ‘{question}’. “
f”Might you make clear what you need me to do?”
),
}
if __name__ == “__main__”:
retriever = RetrieverWithFallback(TOOL_CATALOG)
for q in [“What’s the weather forecast in Lagos?”, “xyzzy plugh random nonsense”]:
end result = retriever.retrieve_with_fallback(q)
print(f”Question: ‘{q}'”)
print(f” Standing: {end result[‘status’]}”)
if end result[“status”] == “resolved”:
print(f” Software: {end result[‘tool’]} (confidence={end result[‘confidence’]:.3f})”)
else:
print(f” {end result[‘clarification_request’]}”)
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
# fallback.py
# Stipulations: pip set up scikit-learn numpy
# Run: python fallback.py
import numpy as np
from sklearn.feature_extraction.textual content import TfidfVectorizer
from sklearn.metrics.pairwise import cosine_similarity
TOOL_CATALOG = [
{“name”: “search_web”, “description”: “Search the web for current information on any topic”},
{“name”: “get_weather”, “description”: “Get the current weather forecast for a city”},
{“name”: “send_email”, “description”: “Send an email to a recipient with subject and body”},
{“name”: “list_github_issues”, “description”: “List open issues and bugs in a GitHub repository”},
]
class RetrieverWithFallback:
“”“
Wraps retrieval with a three-tier fallback chain:
1. Excessive confidence -> use the highest end result instantly
2. Low confidence -> retry with a reformulated question
3. Nonetheless low -> escalate to a clarification request, by no means guess
““”
def __init__(self, instruments, confidence_threshold: float = 0.12):
self.instruments = instruments
self.threshold = confidence_threshold
self.vectorizer = TfidfVectorizer()
descs = [f“{t[‘name’]}: {t[‘description’]}” for t in instruments]
self.tool_vectors = self.vectorizer.fit_transform(descs)
def _raw_retrieve(self, question: str):
query_vec = self.vectorizer.rework([query])
sims = cosine_similarity(query_vec, self.tool_vectors)[0]
top_idx = int(np.argmax(sims))
return self.instruments[top_idx], float(sims[top_idx])
def retrieve_with_fallback(self, question: str) -> dict:
instrument, rating = self._raw_retrieve(question)
if rating >= self.threshold:
return {“standing”: “resolved”, “instrument”: instrument[“name”], “confidence”: rating, “makes an attempt”: 1}
# Reformulate by stripping filler phrases. In manufacturing, this step would
# be an LLM name asking it to restate the question when it comes to intent/functionality.
reformulated = question.exchange(“are you able to”, “”).exchange(“please”, “”).exchange(“?”, “”).strip()
tool2, score2 = self._raw_retrieve(reformulated)
if score2 >= self.threshold:
return {“standing”: “resolved”, “instrument”: tool2[“name”], “confidence”: score2, “makes an attempt”: 2}
return {
“standing”: “escalated”, “instrument”: None,
“confidence”: max(rating, score2), “makes an attempt”: 2,
“clarification_request”: (
f“I am not assured which instrument suits ‘{question}’. “
f“Might you make clear what you need me to do?”
),
}
if __name__ == “__main__”:
retriever = RetrieverWithFallback(TOOL_CATALOG)
for q in [“What’s the weather forecast in Lagos?”, “xyzzy plugh random nonsense”]:
end result = retriever.retrieve_with_fallback(q)
print(f“Question: ‘{q}'”)
print(f” Standing: {end result[‘status’]}”)
if end result[“status”] == “resolved”:
print(f” Software: {end result[‘tool’]} (confidence={end result[‘confidence’]:.3f})”)
else:
print(f” {end result[‘clarification_request’]}”)
How one can run:
pip set up scikit-learn numpy
python fallback.py
pip set up scikit–study numpy
python fallback.py
The escalation path is the one most groups skip after they first construct this, and it’s the one which issues most in manufacturing. A confidently mistaken instrument name is worse than a system that asks, “I’m unsure, might you make clear?” The second failure mode is recoverable in a single flip. The primary one often isn’t.
Benchmarking Your Software Choice System
All the pieces above is a speculation till you measure it. The methodology is simple: construct a labeled set of (question, right instrument) pairs, run your pipeline in opposition to it, and measure accuracy, token price, and latency, evaluating your filtered pipeline in opposition to the naive full-catalog baseline. MCPToolBench++, a large-scale benchmark constructed from over 4,000 actual MCP servers throughout 40-plus classes, is the reference for the way rigorously this needs to be structured at scale, however the core concept works at any dimension.
# benchmark.py
# Stipulations: pip set up scikit-learn numpy
# Run: python benchmark.py
import time
import numpy as np
from sklearn.feature_extraction.textual content import TfidfVectorizer
from sklearn.metrics.pairwise import cosine_similarity
TOOL_CATALOG = [
{“name”: “search_web”, “description”: “Search the web for current information on any topic”},
{“name”: “read_file”, “description”: “Read the contents of a file given its path”},
{“name”: “write_file”, “description”: “Write or overwrite content to a file at a given path”},
{“name”: “send_email”, “description”: “Send an email to a recipient with subject and body”},
{“name”: “create_calendar_event”, “description”: “Create a new calendar event with a title and time”},
{“name”: “query_database”, “description”: “Run a SQL query against the company database”},
{“name”: “list_github_issues”, “description”: “List open issues and bugs in a GitHub repository”},
{“name”: “send_slack_message”, “description”: “Send a message to a Slack channel or user”},
{“name”: “get_weather”, “description”: “Get current weather conditions for a city”},
{“name”: “book_flight”, “description”: “Search and book a flight between two cities”},
]
# Labeled benchmark set: (question, expected_tool). Construct yours from actual
# logged queries after getting manufacturing visitors — it is a seed set.
BENCHMARK_SET = [
(“What’s the weather in Abuja right now?”, “get_weather”),
(“Send an email to the finance team”, “send_email”),
(“List the open issues on our main repo”, “list_github_issues”),
(“Book me a flight from Lagos to London”, “book_flight”),
(“Query the database for last week’s signups”, “query_database”),
(“Post an update in the team Slack channel”, “send_slack_message”),
(“Search the web for the latest interest rates”, “search_web”),
(“Read the contents of config.yaml”, “read_file”),
]
def estimate_tokens(textual content: str) -> int:
“””Tough token estimate (1 token ~ 4 characters) — ok for relative comparability.”””
return len(textual content) // 4
class BenchmarkHarness:
“””Runs a labeled question set by way of a retriever and studies accuracy, token price, and latency.”””
def __init__(self, instruments: checklist[dict], top_k: int = 3):
self.instruments = instruments
self.top_k = top_k
self.vectorizer = TfidfVectorizer()
descs = [f”{t[‘name’]}: {t[‘description’]}” for t in instruments]
self.tool_vectors = self.vectorizer.fit_transform(descs)
self.full_catalog_tokens = sum(estimate_tokens(d) for d in descs)
def _retrieve(self, question: str, top_k: int) -> checklist[dict]:
query_vec = self.vectorizer.rework([query])
sims = cosine_similarity(query_vec, self.tool_vectors)[0]
top_indices = np.argsort(sims)[::-1][:top_k]
return [self.tools[i] for i in top_indices]
def run(self, benchmark_set: checklist[tuple], use_retrieval: bool = True) -> dict:
right, total_tokens, latencies = 0, 0, []
for question, expected_tool in benchmark_set:
t0 = time.perf_counter()
if use_retrieval:
candidates = self._retrieve(question, top_k=self.top_k)
tokens_this_query = sum(
estimate_tokens(f”{t[‘name’]}: {t[‘description’]}”) for t in candidates
)
else:
# Baseline: ship the complete, unfiltered catalog each time
candidates = self.instruments
tokens_this_query = self.full_catalog_tokens
if expected_tool in [c[“name”] for c in candidates]:
right += 1
total_tokens += tokens_this_query
latencies.append(time.perf_counter() – t0)
n = len(benchmark_set)
latencies_sorted = sorted(latencies)
return {
“accuracy”: spherical(right / n, 4),
“avg_tokens”: spherical(total_tokens / n, 1),
“p50_latency_ms”: spherical(latencies_sorted[len(latencies_sorted) // 2] * 1000, 3),
“p95_latency_ms”: spherical(latencies_sorted[int(len(latencies_sorted) * 0.95)] * 1000, 3),
}
if __name__ == “__main__”:
harness = BenchmarkHarness(TOOL_CATALOG, top_k=3)
baseline = harness.run(BENCHMARK_SET, use_retrieval=False)
retrieval = harness.run(BENCHMARK_SET, use_retrieval=True)
print(“Baseline (full catalog each time):”)
print(f” Accuracy: {baseline[‘accuracy’]*100:.1f}%”)
print(f” Avg tokens/question: {baseline[‘avg_tokens’]}”)
print(“nRetrieval-filtered (top-3):”)
print(f” Accuracy: {retrieval[‘accuracy’]*100:.1f}%”)
print(f” Avg tokens/question: {retrieval[‘avg_tokens’]}”)
discount = (1 – retrieval[“avg_tokens”] / baseline[“avg_tokens”]) * 100
print(f”nToken discount with retrieval: {discount:.1f}%”)
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
87
88
89
90
91
92
93
94
95
96
97
98
99
100
101
102
103
# benchmark.py
# Stipulations: pip set up scikit-learn numpy
# Run: python benchmark.py
import time
import numpy as np
from sklearn.feature_extraction.textual content import TfidfVectorizer
from sklearn.metrics.pairwise import cosine_similarity
TOOL_CATALOG = [
{“name”: “search_web”, “description”: “Search the web for current information on any topic”},
{“name”: “read_file”, “description”: “Read the contents of a file given its path”},
{“name”: “write_file”, “description”: “Write or overwrite content to a file at a given path”},
{“name”: “send_email”, “description”: “Send an email to a recipient with subject and body”},
{“name”: “create_calendar_event”, “description”: “Create a new calendar event with a title and time”},
{“name”: “query_database”, “description”: “Run a SQL query against the company database”},
{“name”: “list_github_issues”, “description”: “List open issues and bugs in a GitHub repository”},
{“name”: “send_slack_message”, “description”: “Send a message to a Slack channel or user”},
{“name”: “get_weather”, “description”: “Get current weather conditions for a city”},
{“name”: “book_flight”, “description”: “Search and book a flight between two cities”},
]
# Labeled benchmark set: (question, expected_tool). Construct yours from actual
# logged queries after getting manufacturing visitors — it is a seed set.
BENCHMARK_SET = [
(“What’s the weather in Abuja right now?”, “get_weather”),
(“Send an email to the finance team”, “send_email”),
(“List the open issues on our main repo”, “list_github_issues”),
(“Book me a flight from Lagos to London”, “book_flight”),
(“Query the database for last week’s signups”, “query_database”),
(“Post an update in the team Slack channel”, “send_slack_message”),
(“Search the web for the latest interest rates”, “search_web”),
(“Read the contents of config.yaml”, “read_file”),
]
def estimate_tokens(textual content: str) -> int:
“”“Tough token estimate (1 token ~ 4 characters) — ok for relative comparability.”“”
return len(textual content) // 4
class BenchmarkHarness:
“”“Runs a labeled question set by way of a retriever and studies accuracy, token price, and latency.”“”
def __init__(self, instruments: checklist[dict], top_k: int = 3):
self.instruments = instruments
self.top_k = top_k
self.vectorizer = TfidfVectorizer()
descs = [f“{t[‘name’]}: {t[‘description’]}” for t in instruments]
self.tool_vectors = self.vectorizer.fit_transform(descs)
self.full_catalog_tokens = sum(estimate_tokens(d) for d in descs)
def _retrieve(self, question: str, top_k: int) -> checklist[dict]:
query_vec = self.vectorizer.rework([query])
sims = cosine_similarity(query_vec, self.tool_vectors)[0]
top_indices = np.argsort(sims)[::–1][:top_k]
return [self.tools[i] for i in top_indices]
def run(self, benchmark_set: checklist[tuple], use_retrieval: bool = True) -> dict:
right, total_tokens, latencies = 0, 0, []
for question, expected_tool in benchmark_set:
t0 = time.perf_counter()
if use_retrieval:
candidates = self._retrieve(question, top_k=self.top_k)
tokens_this_query = sum(
estimate_tokens(f“{t[‘name’]}: {t[‘description’]}”) for t in candidates
)
else:
# Baseline: ship the complete, unfiltered catalog each time
candidates = self.instruments
tokens_this_query = self.full_catalog_tokens
if expected_tool in [c[“name”] for c in candidates]:
right += 1
total_tokens += tokens_this_query
latencies.append(time.perf_counter() – t0)
n = len(benchmark_set)
latencies_sorted = sorted(latencies)
return {
“accuracy”: spherical(right / n, 4),
“avg_tokens”: spherical(total_tokens / n, 1),
“p50_latency_ms”: spherical(latencies_sorted[len(latencies_sorted) // 2] * 1000, 3),
“p95_latency_ms”: spherical(latencies_sorted[int(len(latencies_sorted) * 0.95)] * 1000, 3),
}
if __name__ == “__main__”:
harness = BenchmarkHarness(TOOL_CATALOG, top_k=3)
baseline = harness.run(BENCHMARK_SET, use_retrieval=False)
retrieval = harness.run(BENCHMARK_SET, use_retrieval=True)
print(“Baseline (full catalog each time):”)
print(f” Accuracy: {baseline[‘accuracy’]*100:.1f}%”)
print(f” Avg tokens/question: {baseline[‘avg_tokens’]}”)
print(“nRetrieval-filtered (top-3):”)
print(f” Accuracy: {retrieval[‘accuracy’]*100:.1f}%”)
print(f” Avg tokens/question: {retrieval[‘avg_tokens’]}”)
discount = (1 – retrieval[“avg_tokens”] / baseline[“avg_tokens”]) * 100
print(f“nToken discount with retrieval: {discount:.1f}%”)
How one can run:
pip set up scikit-learn numpy
python benchmark.py
pip set up scikit–study numpy
python benchmark.py
On this 10-tool catalog with an 8-query benchmark set, retrieval-filtering held accuracy regular whereas reducing common tokens per question by roughly 70%. The precise numbers will shift along with your catalog and question set, however the comparability construction is what issues: you now have a repeatable option to reply “did this alteration really assist” as a substitute of counting on a handful of handbook spot checks.
Wrapping up
These six methods aren’t competing choices; they’re layers. Gating filters out turns that want no instrument in any respect, cheaply, earlier than the rest runs. Retrieval or routing narrows the catalog right down to what’s really related for the turns that stay. Planning sequences of multi-step duties so every step solely sees the instruments it wants. Fallback logic catches the instances the place the primary try doesn’t land cleanly. Benchmarking is how you already know whether or not any of the above made a measurable distinction, relatively than simply feeling higher.
The RAG-MCP end result, with accuracy greater than tripling and tokens lower by half, isn’t an outlier. It’s what occurs predictably when you cease asking a mannequin to learn by way of a full cellphone e book earlier than each resolution. None of those methods requires an even bigger mannequin or an extended context window. They require treating the instrument checklist itself as one thing to be designed, not simply appended to.
Assets: