


After I began my PhD at UC Berkeley 16 years in the past, my advisor informed me: “OLTP databases are a solved downside. They work. Give attention to analytics.” We have been on the early innings of with the ability to acquire way more information, structured and unstructured, and apply machine studying (which we now name “AI”). So I took the recommendation and joined my cofounders on the analysis undertaking that grew to become Apache Spark, and in a while we began Databricks.
As we constructed Databricks, we began utilizing numerous databases on the market, and we realized OLTP databases have been removed from a solved downside: they have been clunky, troublesome to scale, and extremely fragile. We have been pissed off sufficient in some unspecified time in the future that we requested ourselves what an OLTP database would appear like if we have been to design it at this time. That query led to Lakebase, our serverless Postgres database.
This submit takes a deep dive into the Lakebase OLTP structure. We begin on the storage layer of a conventional monolithic database to see the place the ache comes from, then we have a look at how Lakebase rearranges those self same items into unbiased, externalized companies. Lastly, we flip to LTAP, the place that very same structure lets transactions and analytics run on a single copy of the info, in actual time, with out the delays and additional price of CDC or “mirroring.”
The database as a monolith
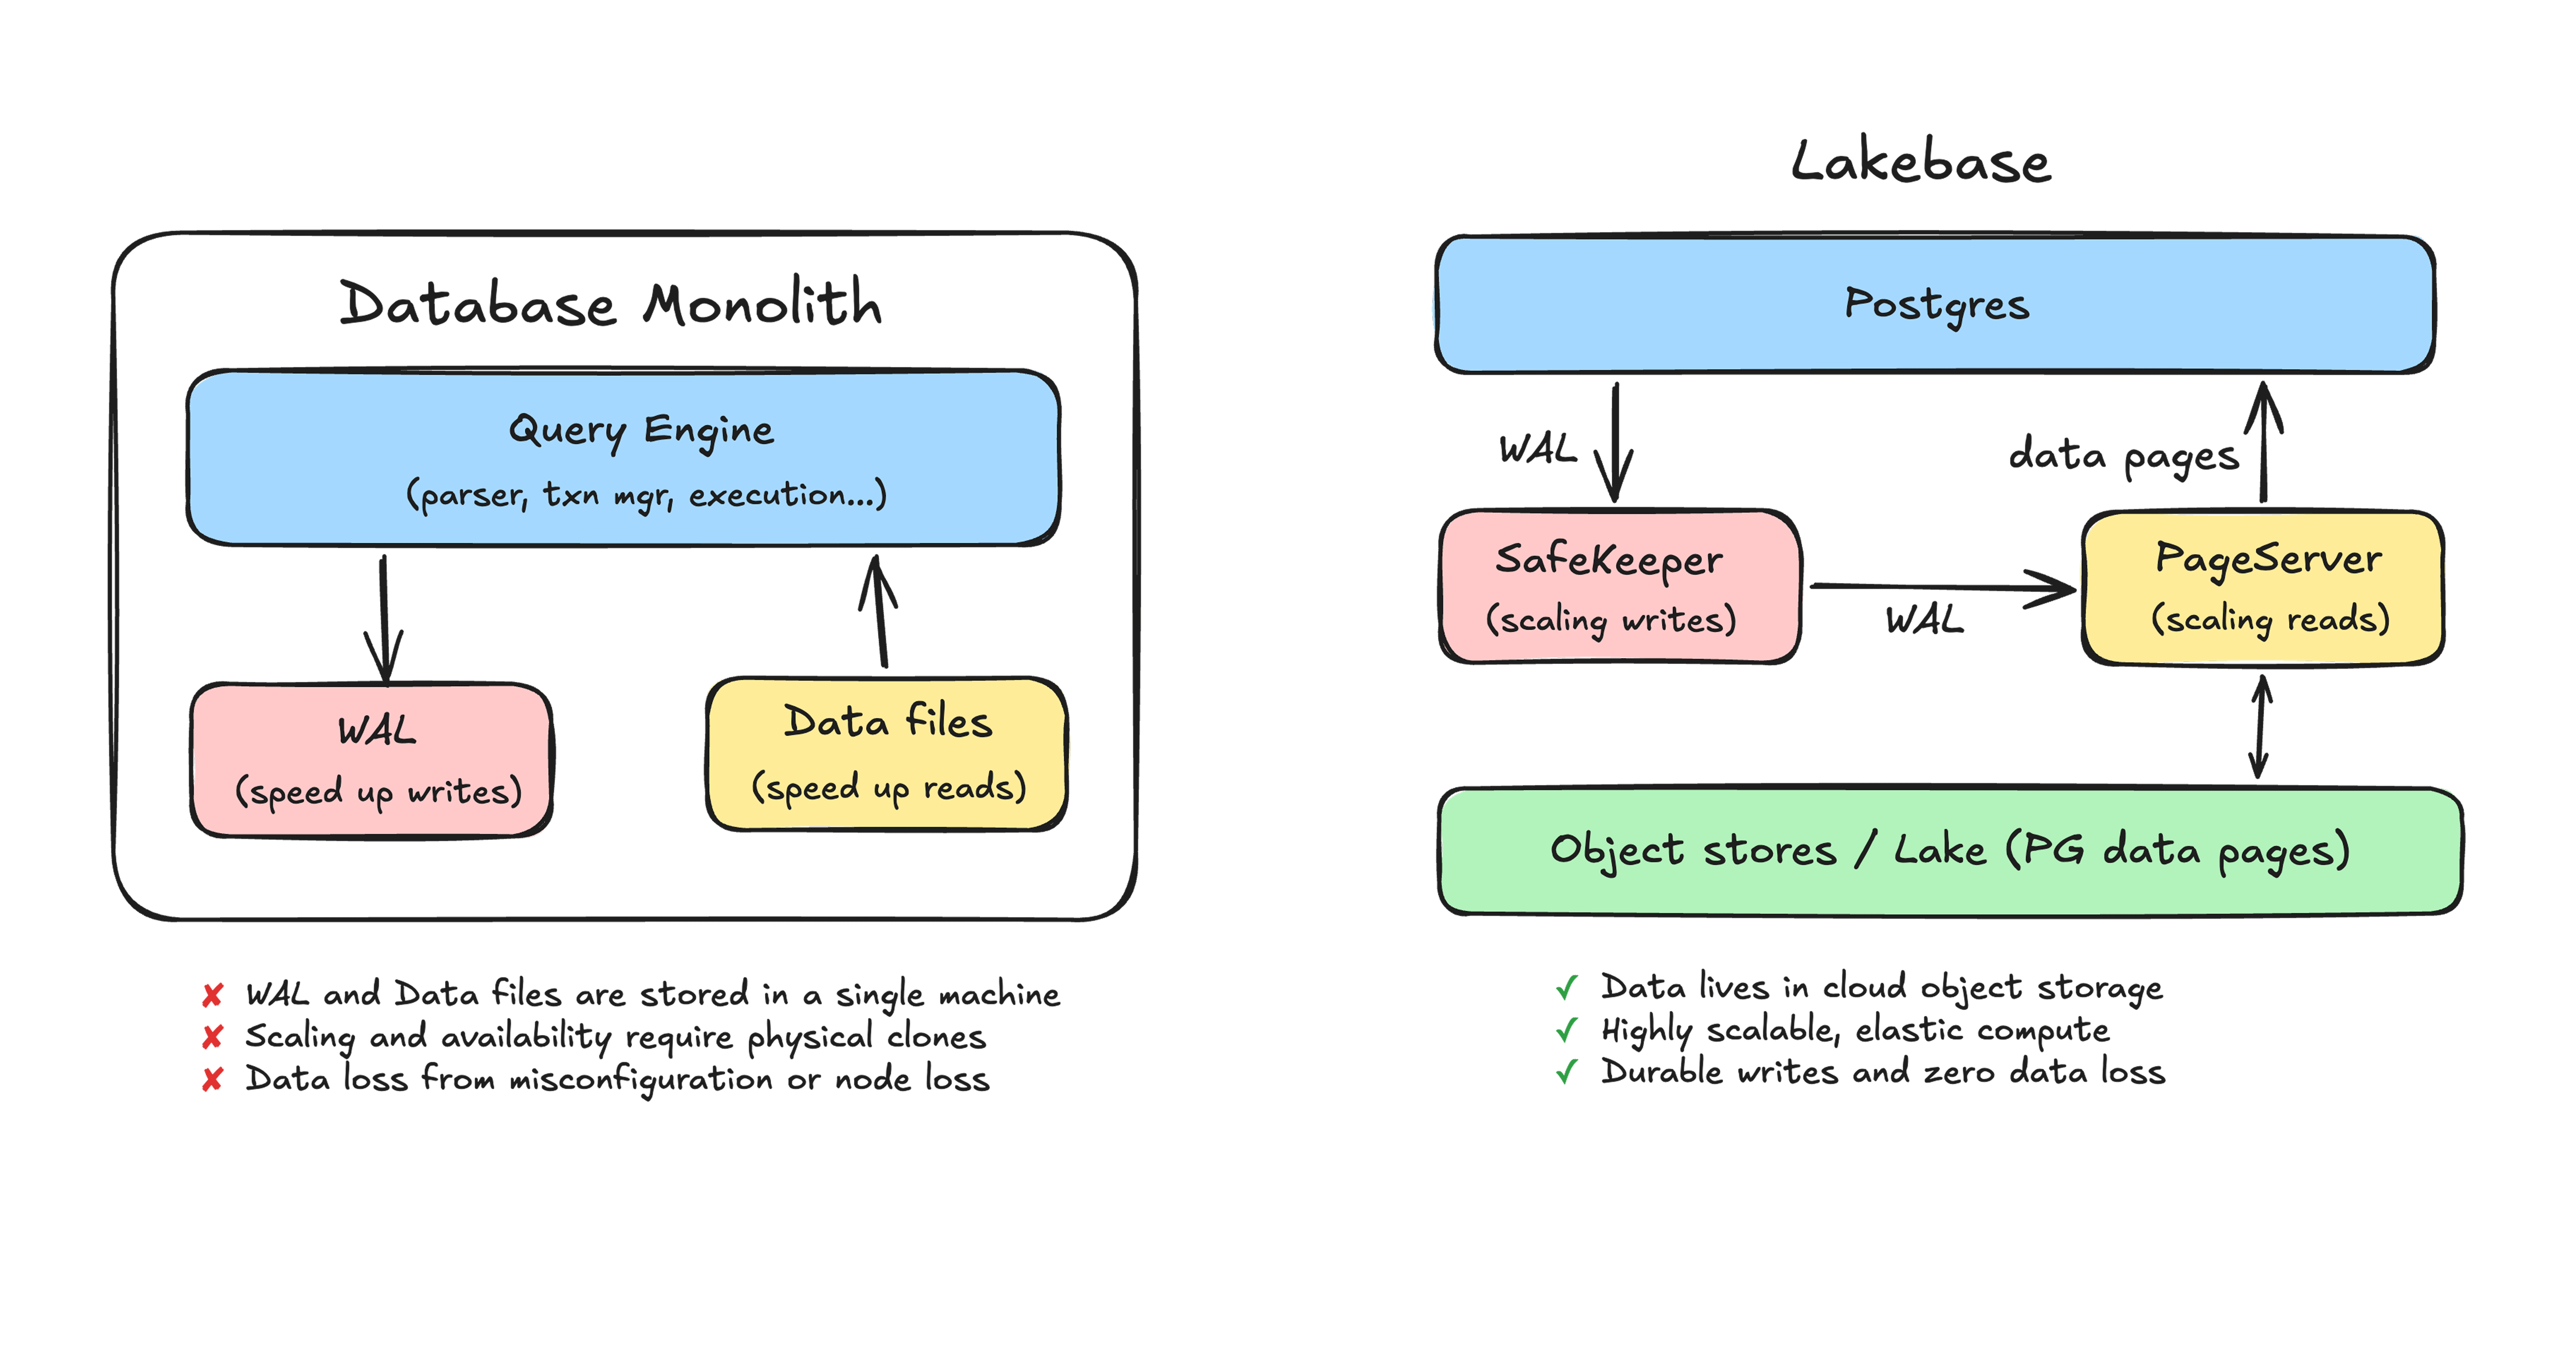
The overwhelming majority of databases operating on the planet at this time are monoliths. This consists of MySQL, Postgres, basic Oracle. Lakebase is constructed on Postgres (because it occurs, was additionally born at Berkeley), so we might be utilizing Postgres as the first instance right here, however most databases work equally: You provision one machine that runs the database engine and the storage. In these database methods, there are two issues on disk that matter probably the most: the write forward log (WAL) and the information information.
While you commit a transaction, the database doesn’t instantly go and rewrite the info information. That may be sluggish, as a result of the rows you’re touching are scattered throughout the file in locations that require random I/O. As an alternative, the database first appends an outline of the change to the WAL, which is a sequential go browsing disk. A transaction is taken into account dedicated the second that log entry is durably written. Solely later, asynchronously, does the database return and replace the precise information information to replicate the change.
One easy method to consider this: the WAL exists to make writes quick (and secure), and the info information exist to make reads quick. The log permits you to commit a transaction with a single sequential append as a substitute of a scattering of random I/O. The information information allow you to reply a question by studying the present state instantly, as a substitute of replaying your complete historical past of the database from the start of time. (If you wish to perceive all of the intricate particulars of this design, learn the 69-page lengthy ARIES paper. Be warned that this is among the most advanced papers in pc science.)
As this design has grow to be the inspiration for nearly all databases on the market, the monolithic structure additionally creates loads of challenges:
Knowledge loss from misconfiguration. A commit is just as sturdy because the disk flush behind it. If the database, the working system, or the storage layer is configured such {that a} write to the WAL is acknowledged to the shopper earlier than it has truly been flushed to sturdy media, then a commit can vanish in an influence loss or kernel panic. These settings are delicate, simple to get mistaken, and the failure is commonly silent. The working system would possibly even determine to misinform you about flushing!
Knowledge loss from node loss. Even with flushes configured appropriately, the WAL and the info information stay on one machine. If that machine’s disk dies, the info on it dies too. Word that community connected storage or redundancy methods like RAID-1/RAID-10 can enhance sturdiness however don’t essentially resolve this difficulty. If the storage mount dies, so does your information entry.
Scaling reads requires a bodily clone. When one field can now not serve your visitors, the usual reply is so as to add a learn reproduction. However a learn reproduction is a full bodily copy of your complete database, streaming the WAL from the first and replaying it. Provisioning one means copying the entire dataset after which catching up on the log. For a big database, that’s not a fast operation and would possibly even carry down the database.
Excessive availability additionally requires a bodily clone. Surviving the lack of the first means operating no less than one extra standby node, which is itself an entire bodily copy of the database saved in sync from the WAL. You pay for no less than twice the infrastructure, you wait a very long time to carry a standby on-line, and you must arrange synchronous replication to keep away from dropping any information when the first goes down. (In observe, many suggest 3 or extra nodes.)
Analytics contend together with your transactional visitors. A heavy analytical question runs in opposition to the identical {hardware} sources as your latency-sensitive transactional workload. One massive reporting question or one GDPR cleanup can degrade your primary OLTP queries. You possibly can run the analytical queries in a separate reproduction, however you find yourself paying for the reproduction and nonetheless don’t get optimum efficiency because of the row oriented nature of OLTP storage (analytics requires column-oriented storage for top efficiency).
Virtually each considered one of these issues traces again to the identical root trigger from the monolithic structure: the WAL and the info information are saved inside a single machine. Sturdiness is tied to that machine’s disk. Scaling and availability require bodily cloning that machine. Workloads intrude as a result of they share that machine.
Lakebase structure
In the event you have been to revamp an OLTP database at this time, you’d begin with the parts of the fashionable cloud: low-cost and extremely sturdy cloud object storage paired with elastic compute. That is the trail the Neon workforce took on and the inspiration of what grew to become Lakebase.
The core transfer is to make the Postgres compute cases stateless. We do that by externalizing the WAL and the info information on native disks into purpose-built, independently scalable companies. The compute layer turns into a stateless Postgres engine that may be began, stopped, and replicated freely, as a result of it now not owns the info.
Let’s see how these two storage companies can work collectively to resolve the aforementioned challenges with out sacrificing efficiency.
Scaling writes: WAL turns into SafeKeeper
In a monolith, a write is made sturdy by flushing it to the native disk. In a Lakebase, the WAL is externalized to a distributed storage service referred to as the SafeKeeper. As an alternative of counting on disk flush for sturdiness, a commit is made sturdy by replicating the log report throughout a quorum of SafeKeeper nodes utilizing Paxos-based community replication. There isn’t a longer a disk whose failure loses your information, and there’s no longer a misconfigured flush quietly undermining your sturdiness assure.
It’s pure to ask at this level: does transferring commits from WAL on native disk to WAL on SafeKeeper enhance the write latency because of the further community hop? The reply is not any. For any critical Postgres deployment that cares about sturdiness and availability, you’d must arrange synchronous replication which requires the additional community hop, so externalizing the WAL into SafeKeeper doesn’t incur extra overhead. As a matter of truth, attributable to how Postgres works internally, the mix of SafeKeeper and PageServer can result in 5X larger write throughput and 2X decrease learn latency.
Scaling reads: information information grow to be PageServer
The information information transfer to a different distributed storage service referred to as the PageServer. The WAL is streamed from the SafeKeeper into the PageServer, and the PageServer asynchronously applies these adjustments to its model of the info, materializing pages into low-cost cloud object storage (the lake). You possibly can consider the PageServer as a write by cache for the underlying object storage.
That is much like the WAL-then-data-files relationship from the monolith, besides the 2 halves now stay in separate, independently scalable companies related by the community as a substitute of sitting on the identical disk. When a web page is requested from the PageServer, and if the PageServer doesn’t but have the newest model but (have in mind adjustments are written to the SafeKeeper first earlier than making their strategy to the PageServer), the PageServer applies the logs from the SafeKeeper to reconstruct the newest state.
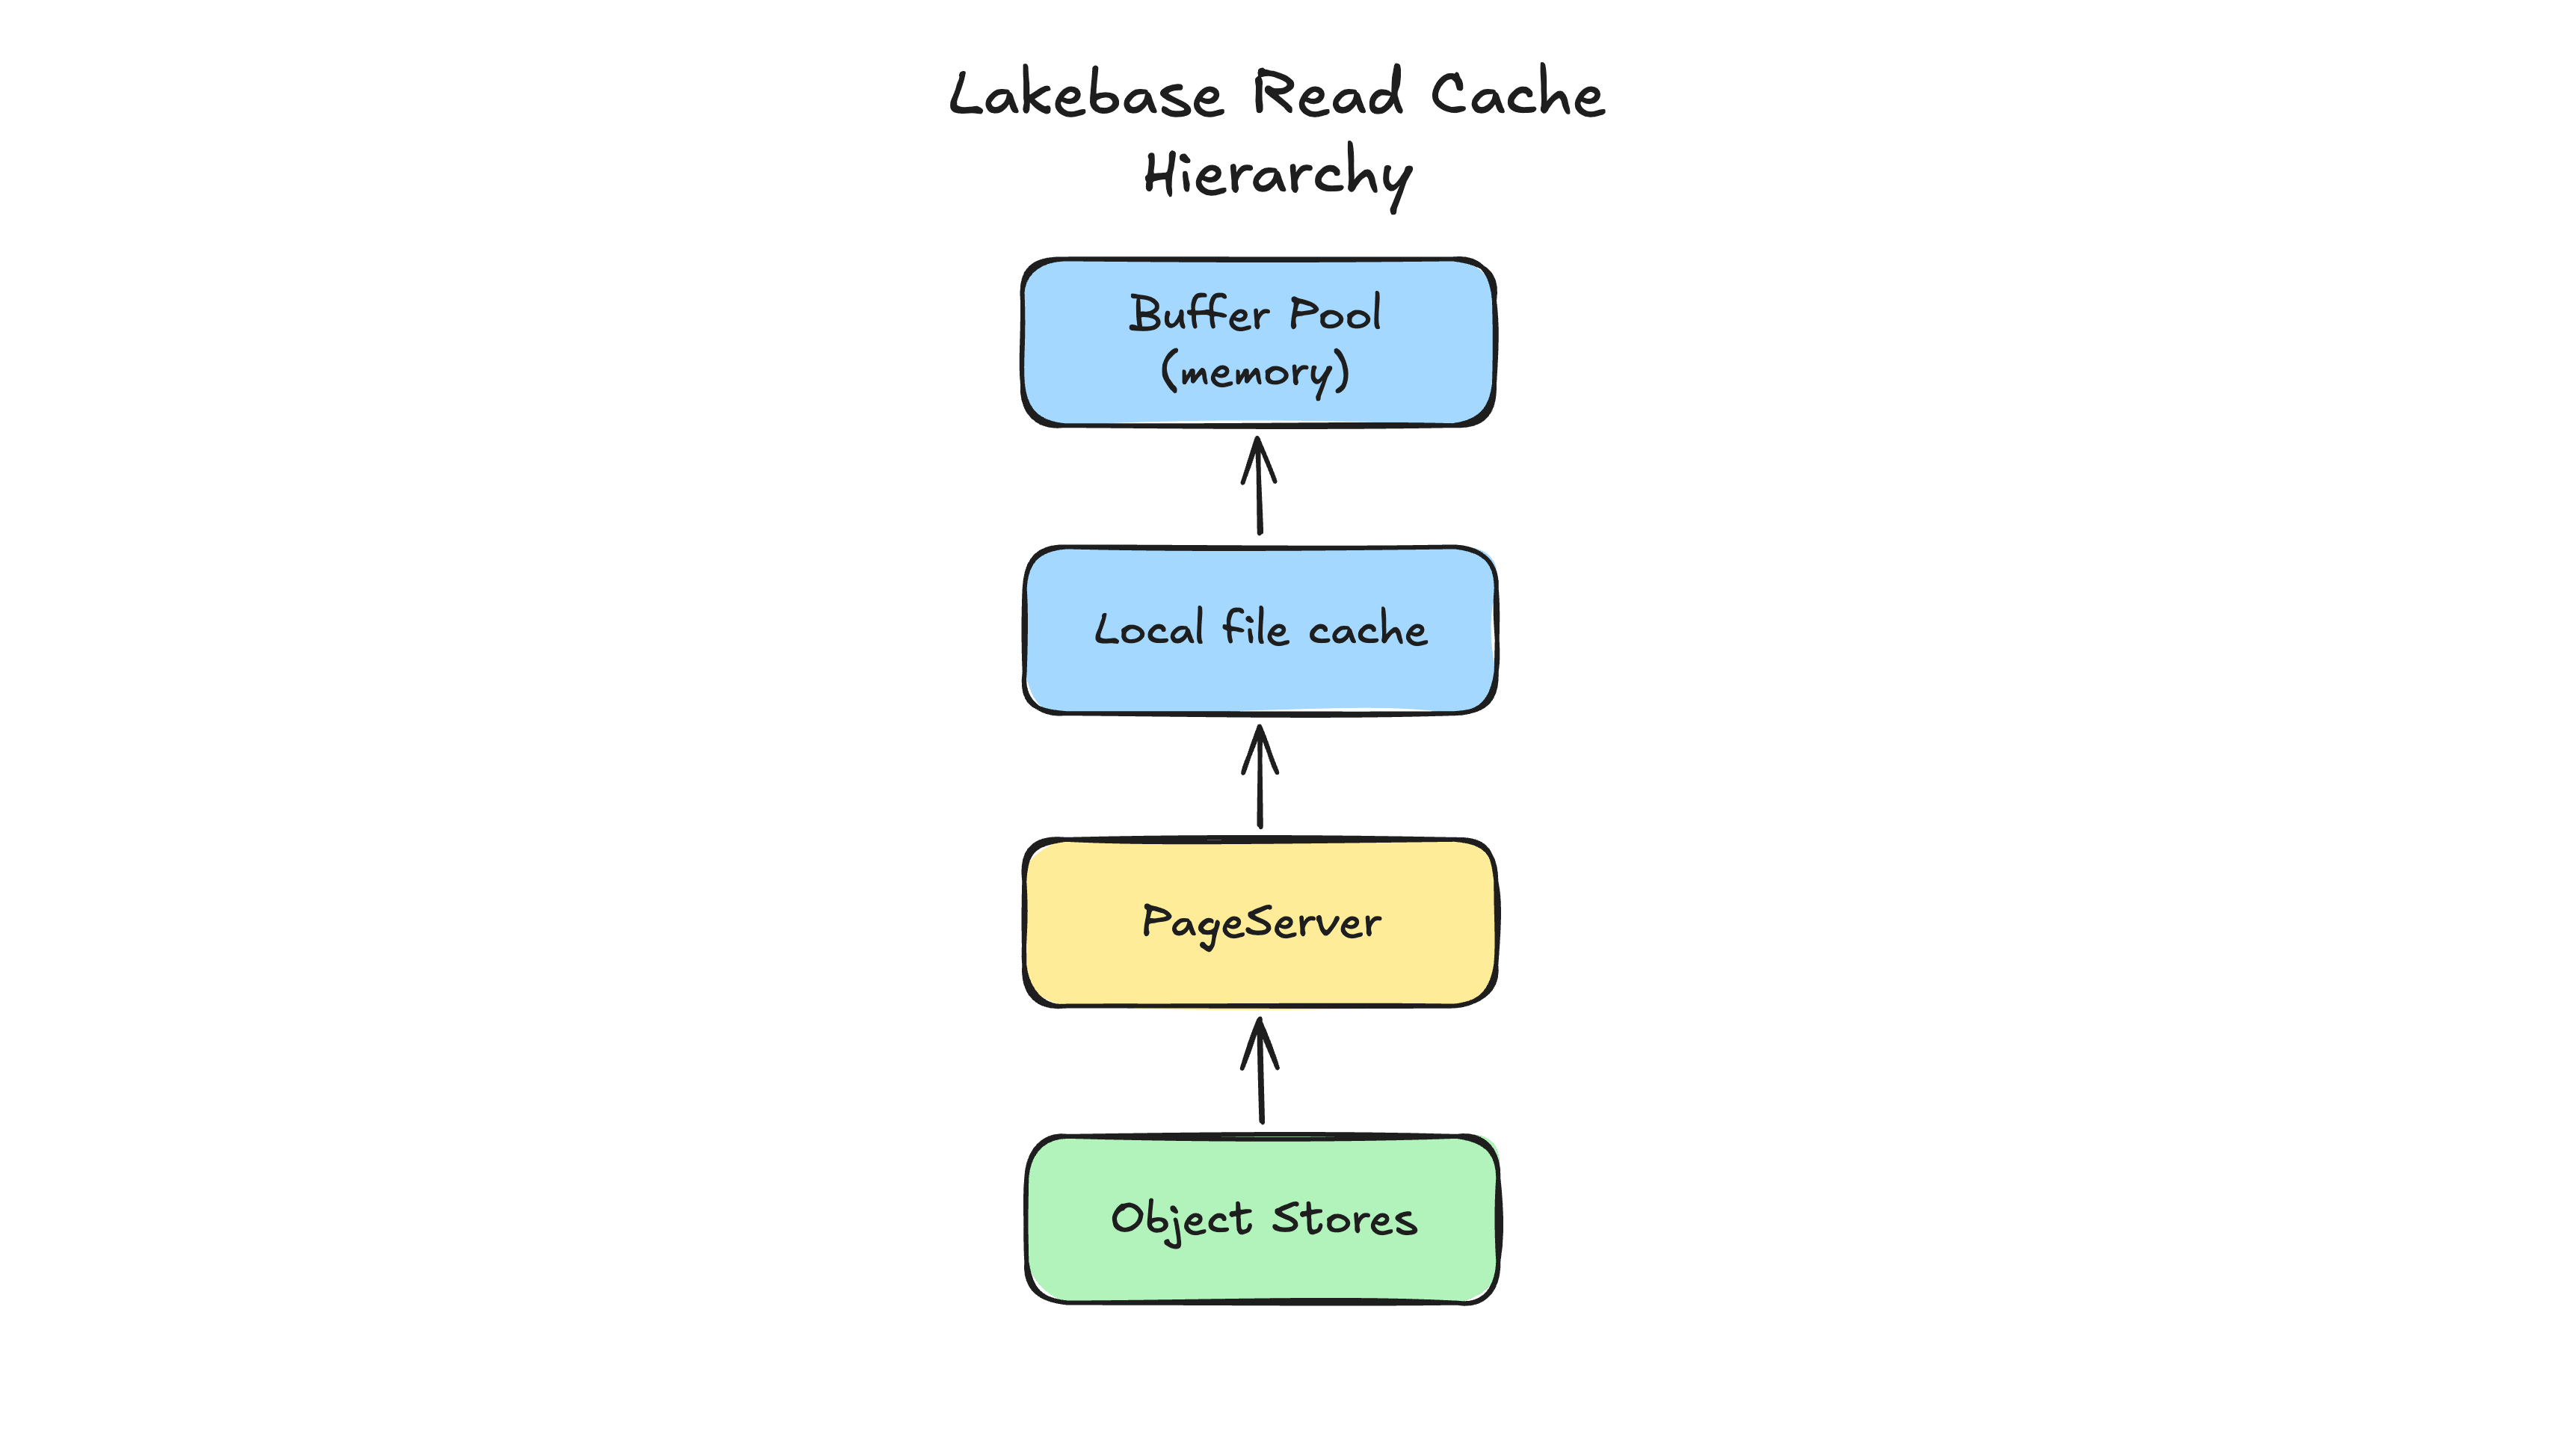
The same query: does transferring information information from native disks to PageServer enhance the learn latency because of the further community hop? The reply can also be no for all sensible functions. The system is designed to isolate and reduce the latency impression by aggressive, multi-layered caching. To fetch a web page, Postgres first seems up its buffer pool, which is within the node’s native reminiscence. When the web page will not be current, it seems up an area disk cache. It solely must go to the PageServer if there’s a cache miss. As a result of a compute node will be configured with native reminiscence and disk capacities an identical to a monolithic setup, your native cache hit charge stays unchanged. For the overwhelming majority of operations, learn latency is indistinguishable from a monolith, however you achieve the advantage of decoupled, nearly infinite storage.
What this unlocks
As soon as the WAL lives within the SafeKeeper and the info information stay within the PageServer, a protracted checklist of capabilities that have been exhausting or unimaginable within the monolith grow to be pure penalties of the structure. The next are already broadly obtainable as a part of the Lakebase product on each Databricks and Neon:
Nonetheless Postgres. That is actual Postgres, so the wire protocol, SQL, drivers, and extensions all work as-is.
Limitless storage. Knowledge lives in cloud object storage quite than on a provisioned native disk. You’re now not sizing a field to a capability ceiling. Storage is, for sensible functions, infinite.
Serverless, elastic compute. As a result of compute is stateless, it could actually scale up immediately below load and scale all the best way all the way down to zero when idle. You cease paying for a big machine to take a seat there ready for visitors.
Sturdy writes and 0 information loss. A commit is sturdy as soon as it’s replicated throughout SafeKeeper nodes through Paxos, not when a single native disk claims to have flushed it. The lack of any particular person node doesn’t lose dedicated information.
Easier excessive availability. Within the monolith, HA meant sustaining a second full bodily clone, paying twice, and nonetheless risking information loss at cutover. Right here, the sturdy state already lives in a replicated storage layer that’s unbiased of any single compute occasion. Failing over now not means selling a separate bodily copy of the database and hoping the final phase of the log made it throughout.
Prompt branching, cloning, and restoration. That is my favourite. For code, making a department is a sub-second, totally remoted copy of your complete codebase, and we do it dozens of instances a day with out fascinated by it. For a monolithic database, cloning means bodily copying the entire dataset, which is sluggish, costly, and dangerous to the manufacturing system. When the info lives in an externalized, versioned storage layer, a department or a clone is a metadata operation quite than a bodily copy. You possibly can department a big manufacturing database in seconds, run an experiment or a dangerous migration in opposition to the department, and throw it away. Restoration to some extent in time works the identical method. The database lastly strikes as quick as your code.
Separating compute from storage will not be itself new. The earlier submit mentioned the era 2 cloud databases that had finished this. Nonetheless, the important thing with Lakebase is that we retailer operational information on commodity object storage in an open format. With this, we open up the alternatives for different engines to learn it instantly, which results in LTAP.
LTAP: one copy for transactions and analytics
Every part thus far has been about making a single operational database higher: extra sturdy, extra elastic, cheaper to run, quicker to department. However as soon as the info lives in an externalized storage layer, one thing extra attention-grabbing turns into attainable. We are able to cease treating the transactional database and the analytical system as two separate worlds.
Return to the PageServer for a second. It already takes the stream of adjustments from the WAL and asynchronously materializes pages into object storage. That materialization step, the second information lands within the lake, seems to be precisely the appropriate place to resolve a a lot older downside…
Even with a Lakebase, the info in object storage was nonetheless written in Postgres’s native web page format, laid out row by row. That format is nice for transactions and poor for analytics, so any analytical engine that needed to learn it needed to both pay a conversion price on each learn or, extra generally, depend on a separate copy of the info saved in sync by a pipeline. The pipeline will be brittle, and the 2 copies of the info can grow to be a governance nightmare with diverged permissions.
We not too long ago introduced LTAP, for Lake Transactional/Analytical Processing, that removes the two-copies-of-data downside. The important thing thought is to unify the 2 worlds on the storage layer quite than on the engine layer. We don’t attempt to construct one engine that’s someway nice at each transactions and analytics. We preserve one of the best software for every job: Postgres, with full ACID semantics for transactions, and the Lakehouse engines for analytics. What adjustments is the info beneath them. As an alternative of two copies in two codecs, there may be one sturdy copy, open columnar codecs like Delta and Iceberg, saved as Parquet, that either side learn (and with numerous ranges of caches for higher efficiency).
Materializing in columnar kind
Word: this part requires extra Postgres inside information to grasp than different sections.
Because the PageServer materializes pages into object storage, it transcodes Postgres information from a row format into Parquet’s columnar structure because it lands within the lake. We protect the precise Postgres illustration of each worth, all the way down to the bits, so any Postgres-compatible engine can reinterpret it with out dropping info. That is totally different from CDC based mostly strategy as CDC ships a stream of logical change occasions right into a overseas schema and leaves Postgres’s bodily and transactional semantics behind; right here we preserve them. With a hyperoptimized engine, the spare CPU within the PageServer layer does the row-to-columnar transcoding as a part of materializing the info into object storage, so it provides no burden to the Postgres compute serving your transactions. To serve transactional reads effectively, the PageServer nonetheless materializes conventional row-based pages in an area cache, however that is strictly a efficiency cache. The underlying sturdy retailer stays unified within the lake, accessible by either side.
Preserving Postgres semantics in columnar kind comes down to 2 issues: the kind system and multi-versioning.
Kind system. The vast majority of Postgres varieties map instantly onto native Parquet varieties. The handful of values with no lossless columnar counterpart, e.g. NaN and ±Infinity, NUMERICs past the decimal vary, unique or extension varieties, usually are not dropped or coerced. They’re carried alongside the unique columns in a structured overflow discipline inside the similar desk, holding the canonical Postgres textual content for these values. That discipline is each instantly queryable by any engine and ample to reconstruct the unique Postgres bytes precisely on the best way again.
Multi-versioning. In Postgres, each row model that some transaction may observe is retained, which is precisely what makes snapshot isolation and point-in-time restoration attainable. In distinction, open desk codecs expose table-wide constant snapshots with none intermediate row variations. We get the advantages of each approaches by separating sturdiness from visibility. Each row materialized to columnar carries its bodily heap tackle (block and offset), so heap pages stay totally reconstructable. The basic Postgres heap web page turns into a cache that accelerates level reads, whereas the sturdy supply of reality lives within the columnar information in object storage. Postgres indexes aren’t transcoded into columns; they’re served and rebuilt from that sizzling cache tier. Intermediate row variations are retained to protect Postgres’s MVCC semantics and PITR, however they aren’t seen to Iceberg/Delta readers and are finally garbage-collected. The web end result: analytical engines see clear, snapshot-consistent tables, whereas the Postgres system beneath nonetheless sees a full, time-travelable model historical past.
There’s additionally a pleasing facet impact. Columnar information compresses much better than row information, typically by greater than ten instances, so changing to columnar storage considerably cuts the quantity of knowledge crossing the community between the caching layer and the item retailer to the purpose that it’s typically negligible. The format that makes analytics quick additionally makes the storage path cheaper. We even reap the benefits of this to twin write each row format and columnar format in object shops for information verification through the transitional rollout stage of LTAP (since we need to be extraordinarily cautious with storage adjustments).
Studying the newest information with out affecting Postgres
One large problem is freshness. If analytics reads from a duplicate within the lake, how does it see information that was dedicated a second in the past and has not been materialized within the object retailer but? That is the query that sinks most “simply level analytics on the lake” designs, so it’s value strolling by how LTAP solutions it.
When an analytical question begins (e.g. from the Lakehouse//RT product we simply introduced), it first asks Postgres for the present LSN, the log sequence quantity that marks the precise place within the WAL to learn as of. This can be a low-cost metadata lookup. With that LSN, the analytical engine reads the overwhelming majority of the info, together with the whole lot already materialized as much as that time, instantly from object storage. The one factor left is the small set of very latest adjustments that haven’t but been materialized to the lake, and people it fetches from the PageServer and merges on high.
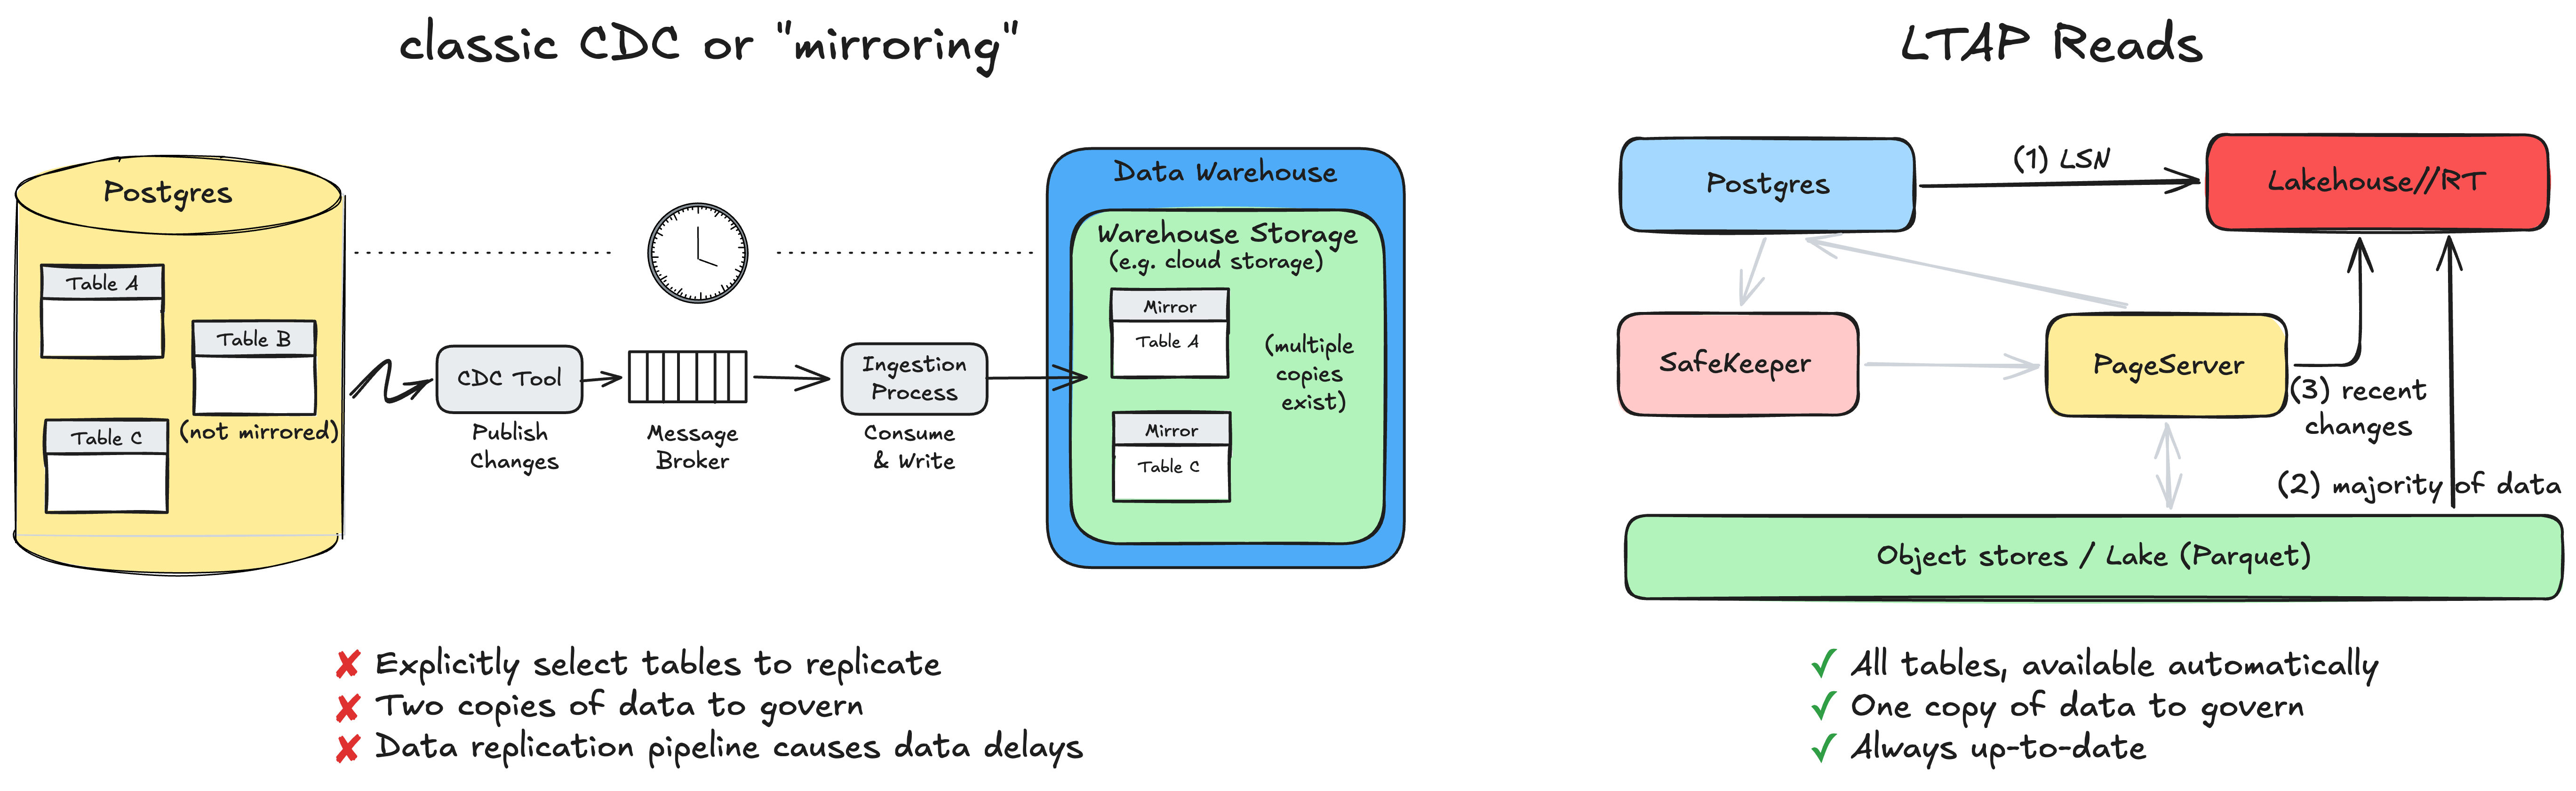
The result’s a constant, totally up-to-date learn of your information as of that LSN. Virtually the entire work lands on low-cost, scalable object storage. And critically, Postgres itself serves not one of the analytical learn visitors aside from returning a single quantity (LSN). Your transactional workload doesn’t decelerate as a result of somebody kicked off a big analytical question.
There’s one sensible optimization value mentioning right here: For very small tables, those holding a handful of rows, we don’t hassle changing them to columnar kind and creating the related Iceberg metadata. The bookkeeping would price greater than it saves, and a desk that tiny has no measurable impact on analytical efficiency no matter how it’s laid out. These tables are nonetheless current and nonetheless queryable as a part of the one copy.
Each desk, mechanically
Due to how essential this downside is, there was a lot of noise out there about integrating OLTP and analytics. A basic strategy is CDC, successfully replicating information from the OLTP storage right into a separate analytics storage tier. You would possibly’ve heard of its different names equivalent to “mirroring” or “zero CDC” or “zero ETL”.
In CDC or “mirroring”, as a result of the info replication pipeline prices one thing, it can’t be utilized to all of the tables. You’d must explicitly choose which tables you care about, and this replication usually comes with a delay.
LTAP has nothing to choose into. A desk that exists is, by building, already within the lake and already queryable. There isn’t a checklist of replicated or mirrored tables, as a result of there isn’t a replication. There’s a single ruled copy of the info in open codecs, with no ETL pipeline to construct, monitor, or unbreak (both by our prospects or us). The transactional and analytical engines scale independently, every sized to its personal workload. And since there isn’t a information motion and no second copy, the 2 views can by no means drift: analytics is at all times studying the identical information the applying simply wrote.
For one more have a look at how LTAP comes collectively, try this demo from Knowledge and AI Summit.
What about HTAP?
If you recognize the sector, you could have already seen that LTAP is a deliberate play on HTAP: hybrid transactional/analytical processing. HTAP has been the holy grail of database engineering, specializing in making a single engine that is able to doing each transactional and analytical workloads.
In observe, there has not been a single broadly adopted HTAP database system on the market. Why is that the case? For my part, HTAP methods endure from a number of of the next:
Incomplete characteristic set. Designing a brand new proprietary engine from scratch to do a single job is a multi-year funding. Attempting to construct a single engine that may do the job of a number of engines compounds the funding required to achieve the characteristic set engineers take with no consideration in a mature database. These methods typically lag on issues individuals assume are at all times there, from the breadth of SQL help (e.g. overseas key help) to the maturity of the question optimizer.
No ecosystem. Postgres and Spark every sit on the middle of an enormous ecosystem: drivers, extensions, instruments, and a long time of gathered operational information. A brand-new engine begins exterior all of it, and an engine is just as helpful because the ecosystem a workforce can truly construct on.
No efficiency isolation. Many HTAP methods run transactions and analytics on the identical {hardware}, so the 2 workloads contend for a similar CPU and reminiscence. This is identical failure we began with within the monolith, with an analytical question ravenous the transactional workload.
All three hint again to the identical choice to unify the 2 workloads into one engine. Lakebase and LTAP circumvents these challenges by unifying on the storage layer, whereas utilizing totally different compute engines for the totally different workloads, tapping into their full characteristic units and ecosystem help, with full efficiency isolation.
Closing thought
After we first put ahead the Lakebase structure final 12 months, we already knew that it might unlock limitless storage, elastic compute, sturdy writes, less complicated HA, and on the spot branching, based mostly on what we’ve seen with the Neon platform. These adopted virtually mechanically as soon as the WAL lived within the SafeKeeper and the info information lived within the PageServer.
The LTAP thought got here later, after the Neon and Databricks groups got here collectively to resolve the decades-old downside of operating analytics in opposition to the freshest transactional information. As we iron out the kinks of LTAP and roll it out within the coming months, your whole Lakebase tables will simply be obtainable for analytics as excessive efficiency because the Lakehouse information.
What excites me most is what’s forward. Whereas LTAP is a pure subsequent step, the identical design additionally opens up a lot of optimization alternatives to separate different heavyweight upkeep operations and the core transactional workloads. We’re simply starting to discover what this structure makes attainable, and we’re wanting ahead to sharing what comes subsequent.
Acknowledgement: I’d wish to thank the Lakebase workforce for making the whole lot we mentioned on this weblog actual, reviewing this weblog, and maintaining me trustworthy with the technical particulars.

