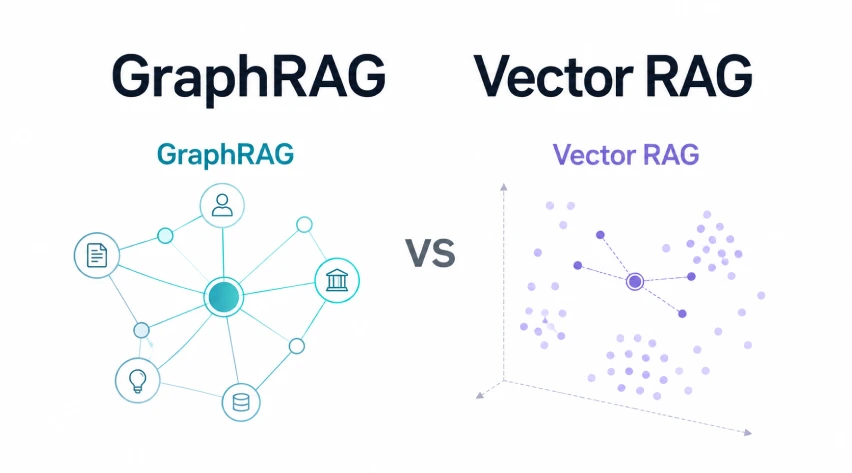
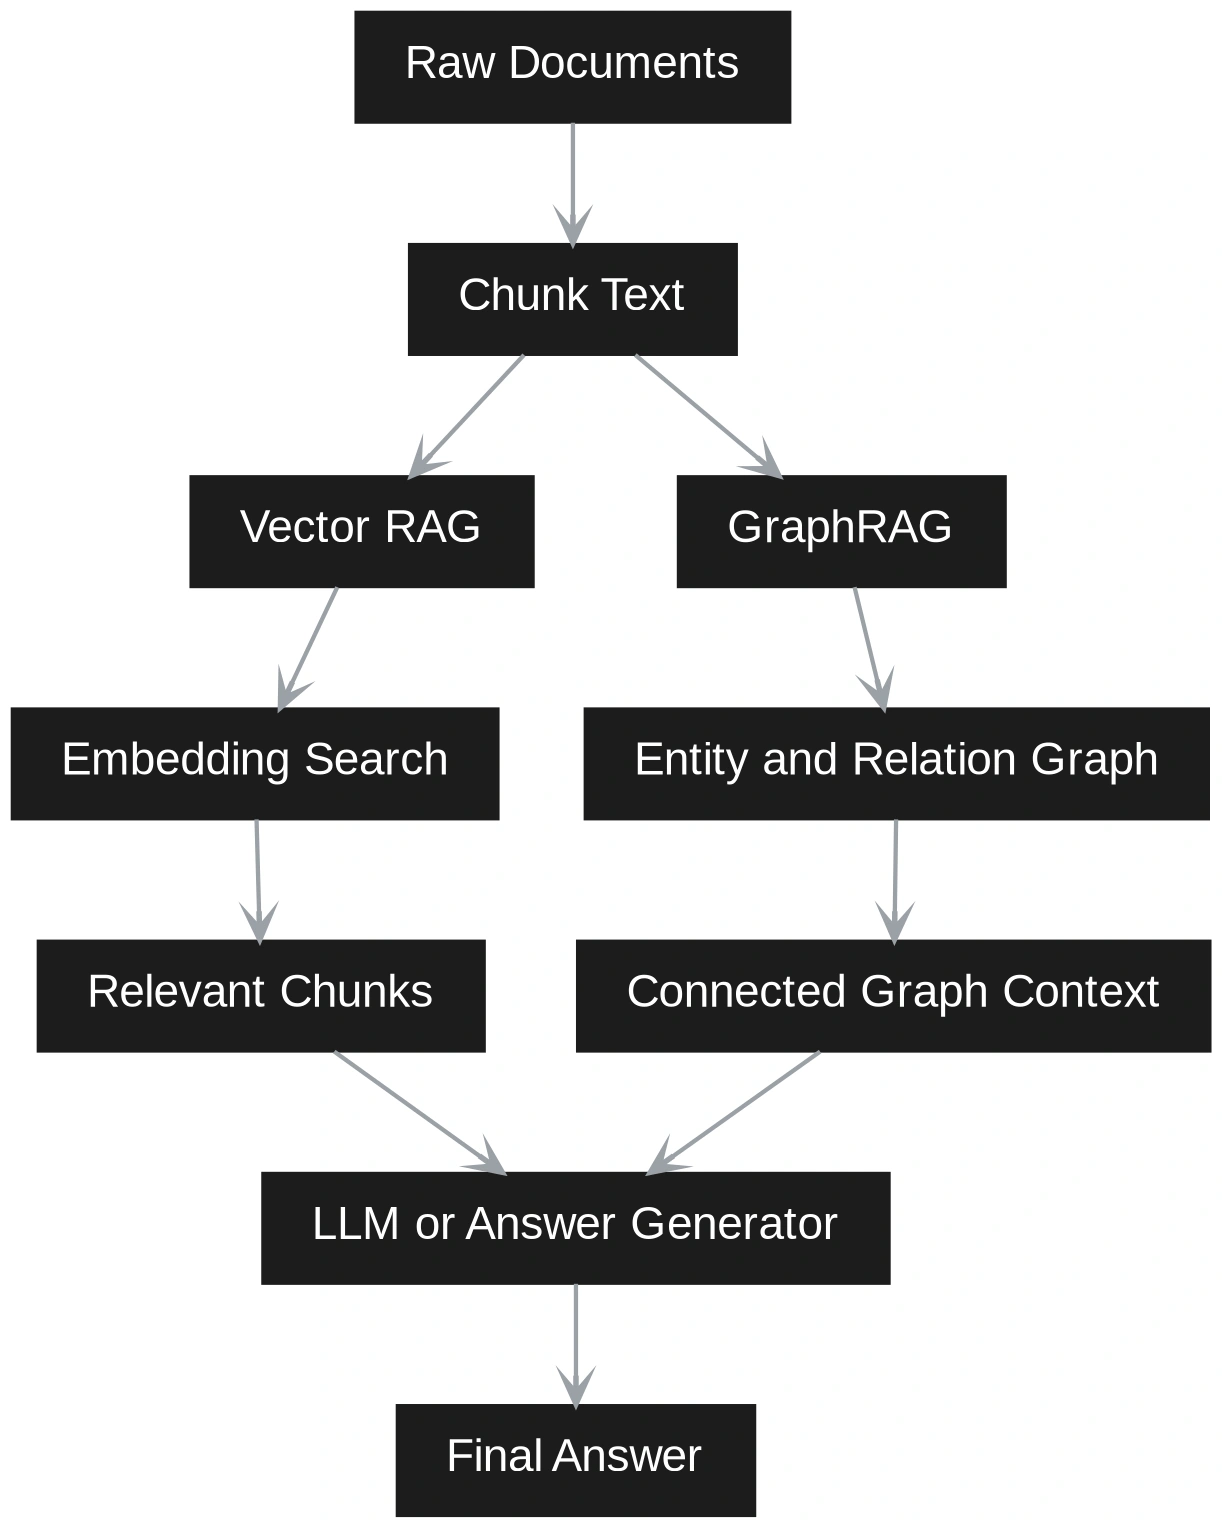
GraphRAG and Vector RAG tackle completely different retrieval wants. Vector RAG splits paperwork into chunks, embeds them, retrieves semantically comparable passages, and sends them to an LLM. It’s easy, quick to construct, and works finest when solutions sit inside one or two related chunks.
GraphRAG provides construction by extracting entities, relationships, and communities, making it stronger for multi-hop reasoning, explainability, and corpus-wide synthesis throughout linked concepts. On this article, a sensible comparability of GraphRAG and Vector RAG, we’ll break down the place every method matches finest.
Definitions and Structure
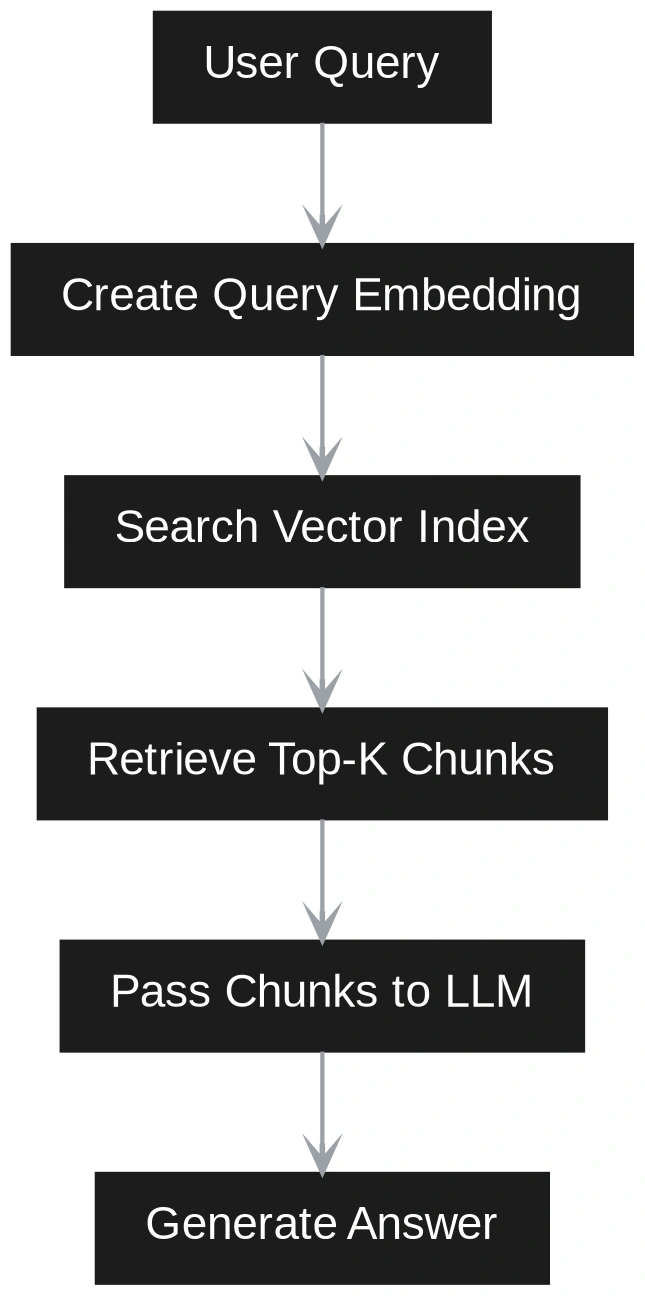
Vector RAG works by splitting paperwork into small textual content chunks. Every chunk is transformed into an embedding and saved in a vector database. When a person asks a query, the query can be transformed into an embedding. The system then finds essentially the most comparable chunks and sends them to the LLM to generate a solution.
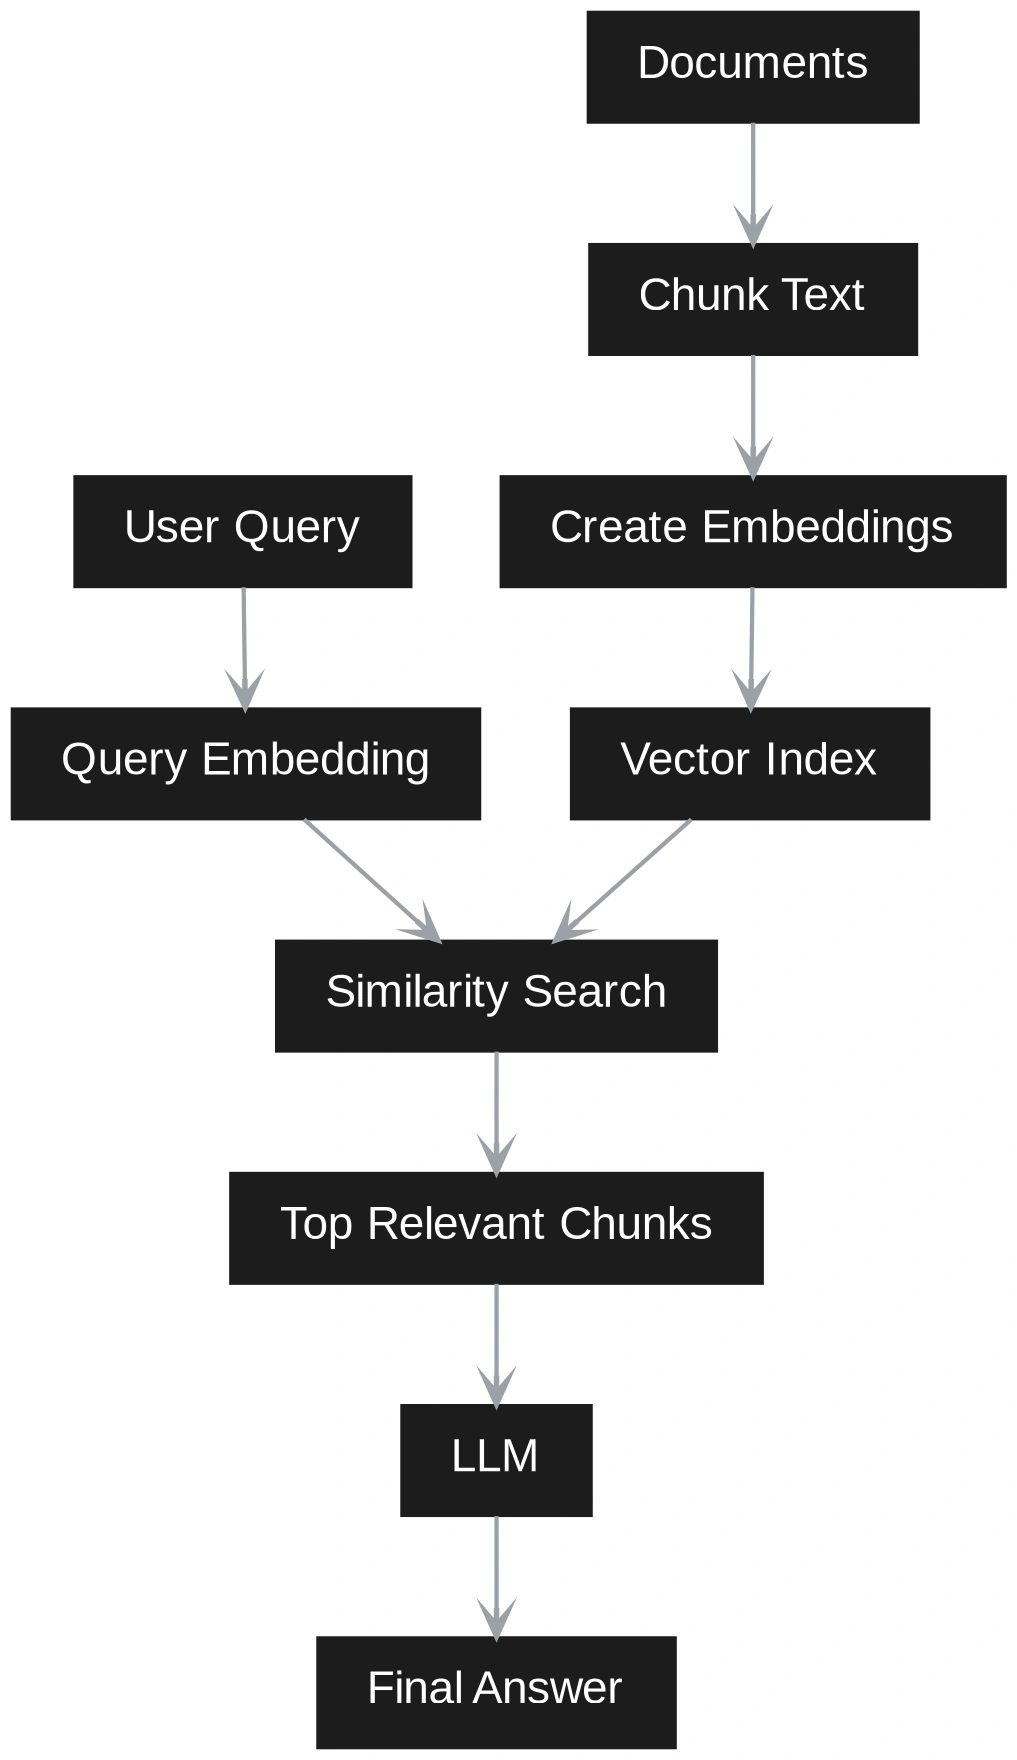
Vector RAG is straightforward, quick, and straightforward to replace. It really works nicely for direct factual questions. Nevertheless it shops that means largely via embeddings and textual content, not via specific entities or relationships. Due to this, it may possibly battle with questions that want connections throughout a number of chunks.
GraphRAG provides extra construction. It extracts entities, relationships, claims, and communities from the paperwork. It then builds a graph that reveals how completely different items of knowledge are linked.
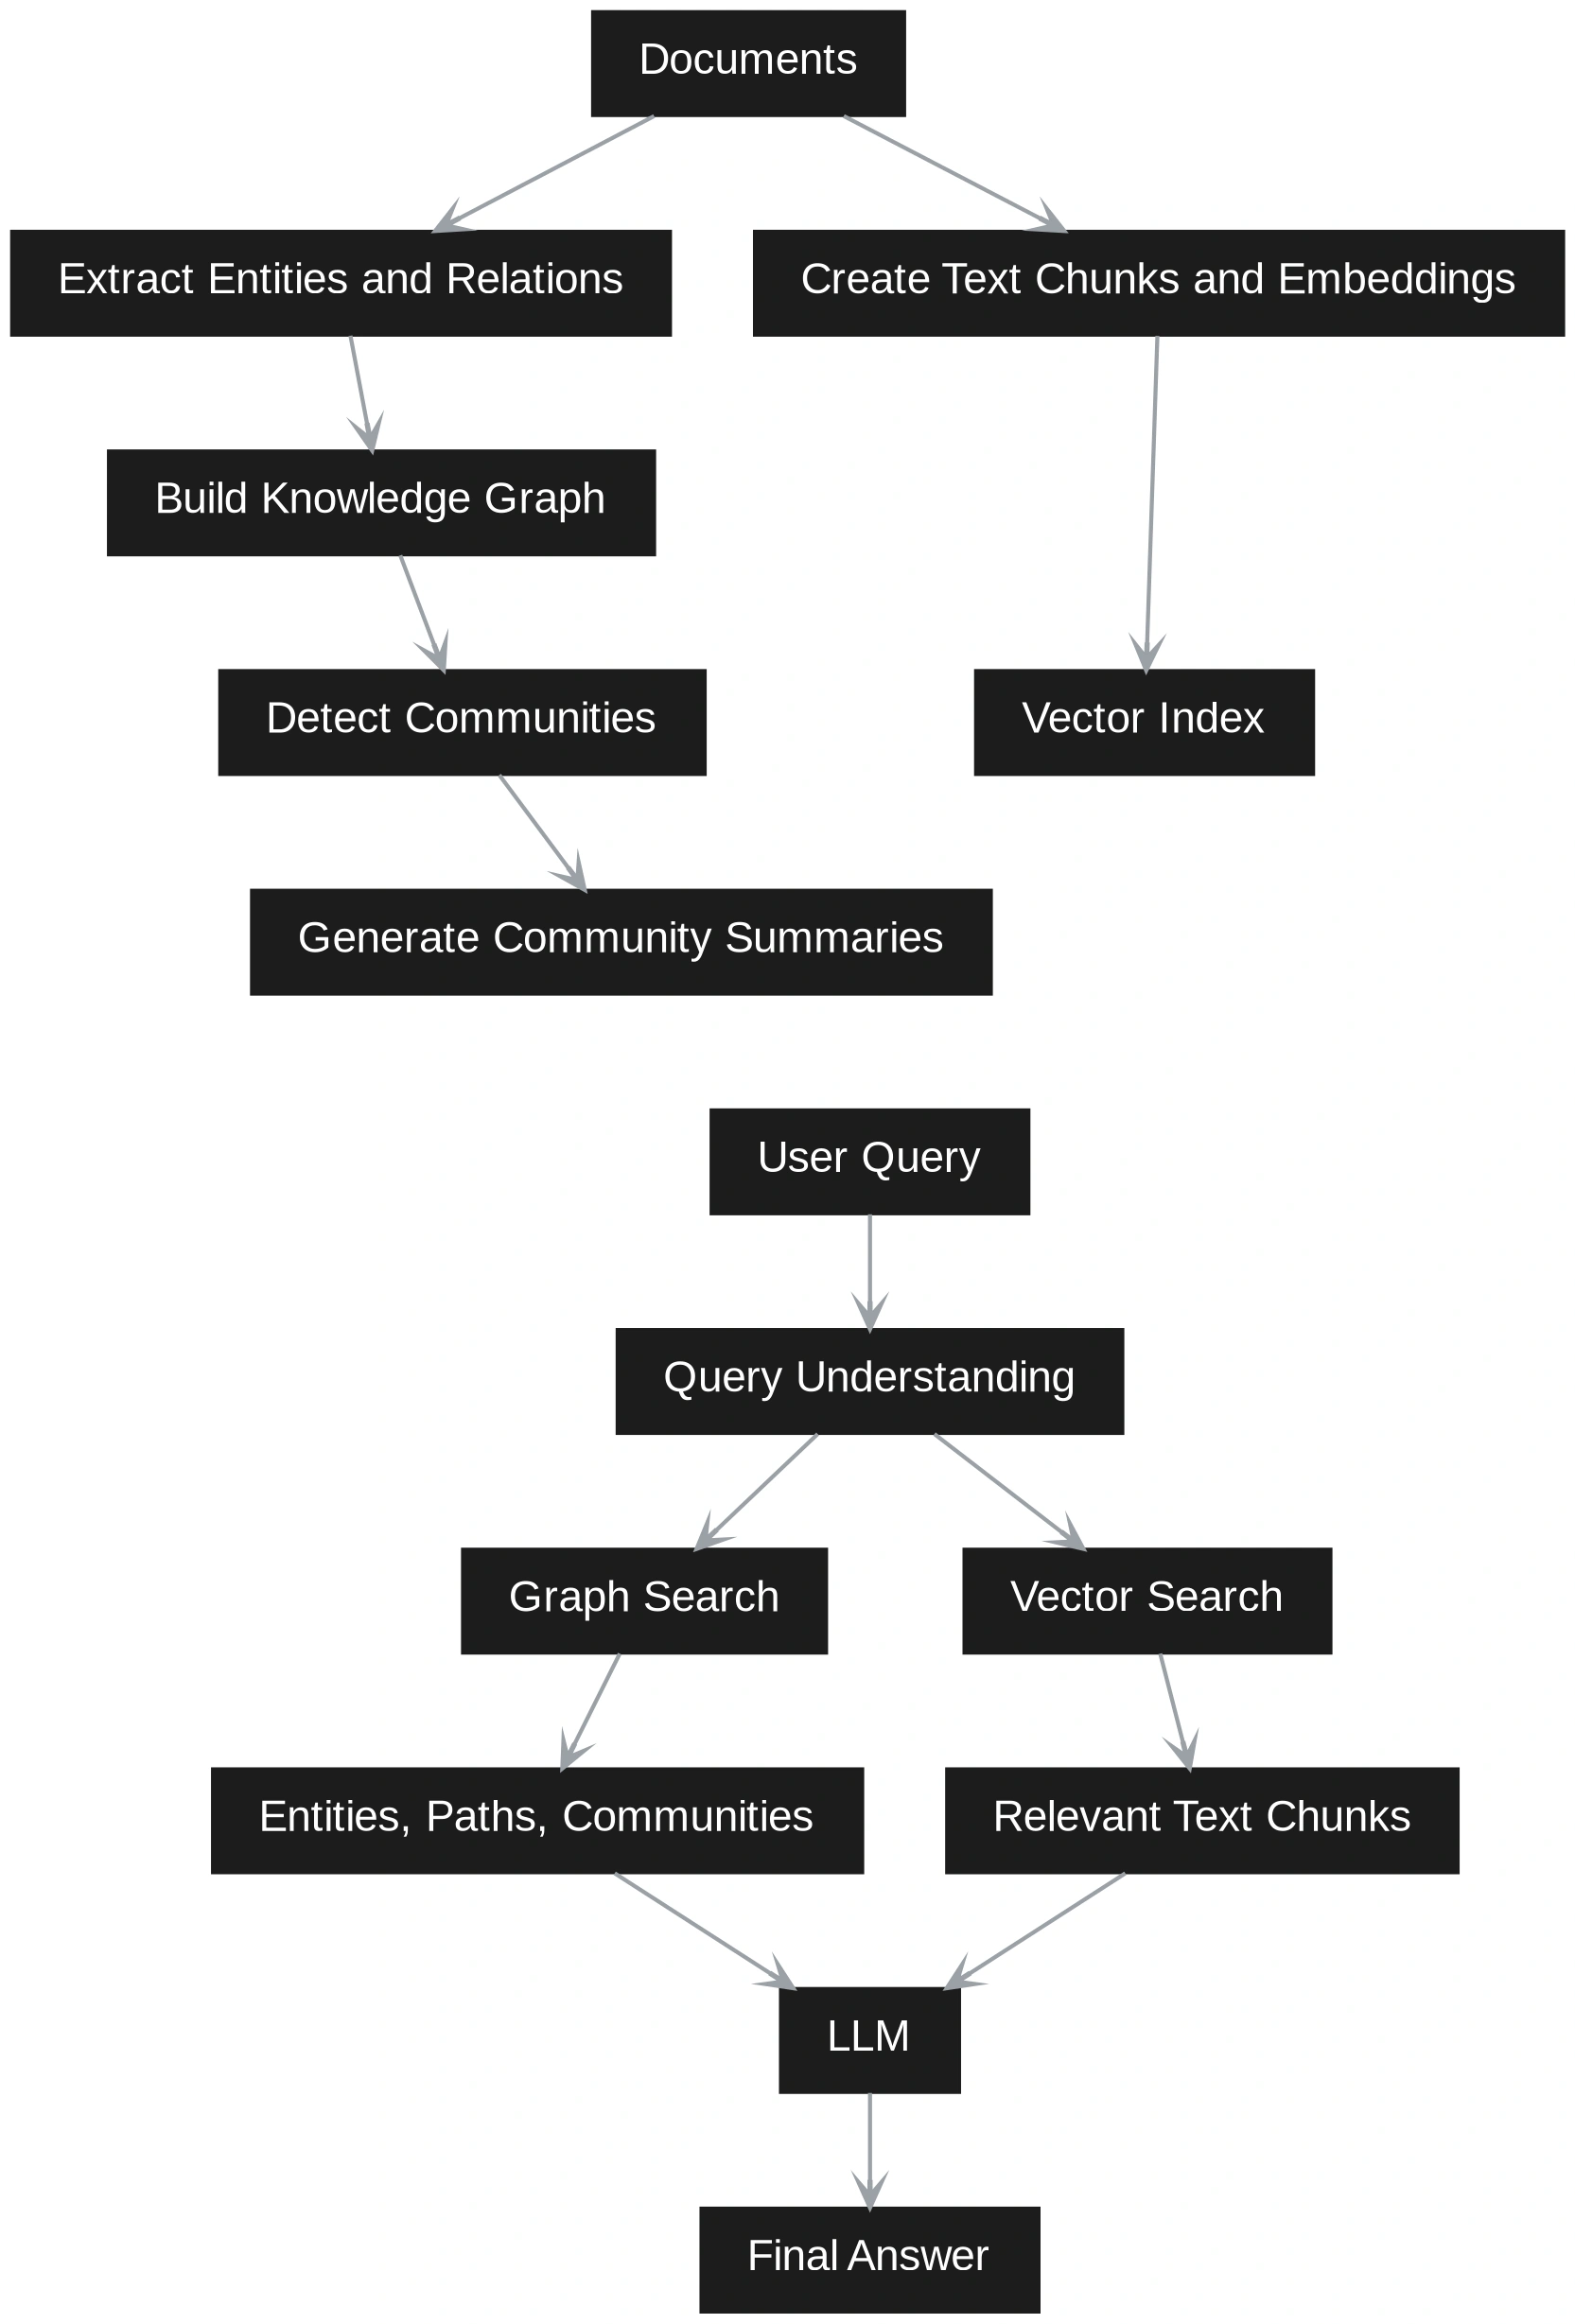
This makes GraphRAG higher for relationship-based questions, multi-step reasoning, and broad understanding throughout a big set of paperwork. The tradeoff is that it takes extra effort and value to construct as a result of it wants graph building, neighborhood detection, and summarization.
In observe, many programs use each. Vector search shortly finds related textual content, whereas graph retrieval provides linked context and higher reasoning.
How Retrieval Works at Question Time
The most important distinction between Vector RAG and GraphRAG turns into clear at question time. In Vector RAG, the question is handled as a semantic search drawback. The person query is transformed into an embedding. The system compares this question embedding with saved chunk embeddings. It retrieves the closest chunks and sends them to the LLM. The LLM then solutions utilizing solely these chunks as context. This works nicely when the reply is immediately obtainable in a small set of comparable passages.
GraphRAG handles the question in a different way. It first tries to know whether or not the query is native or international. A neighborhood query is a few particular entity, occasion, buyer, product, or doc. A world query asks for themes, patterns, dangers, summaries, or relationships throughout the corpus.
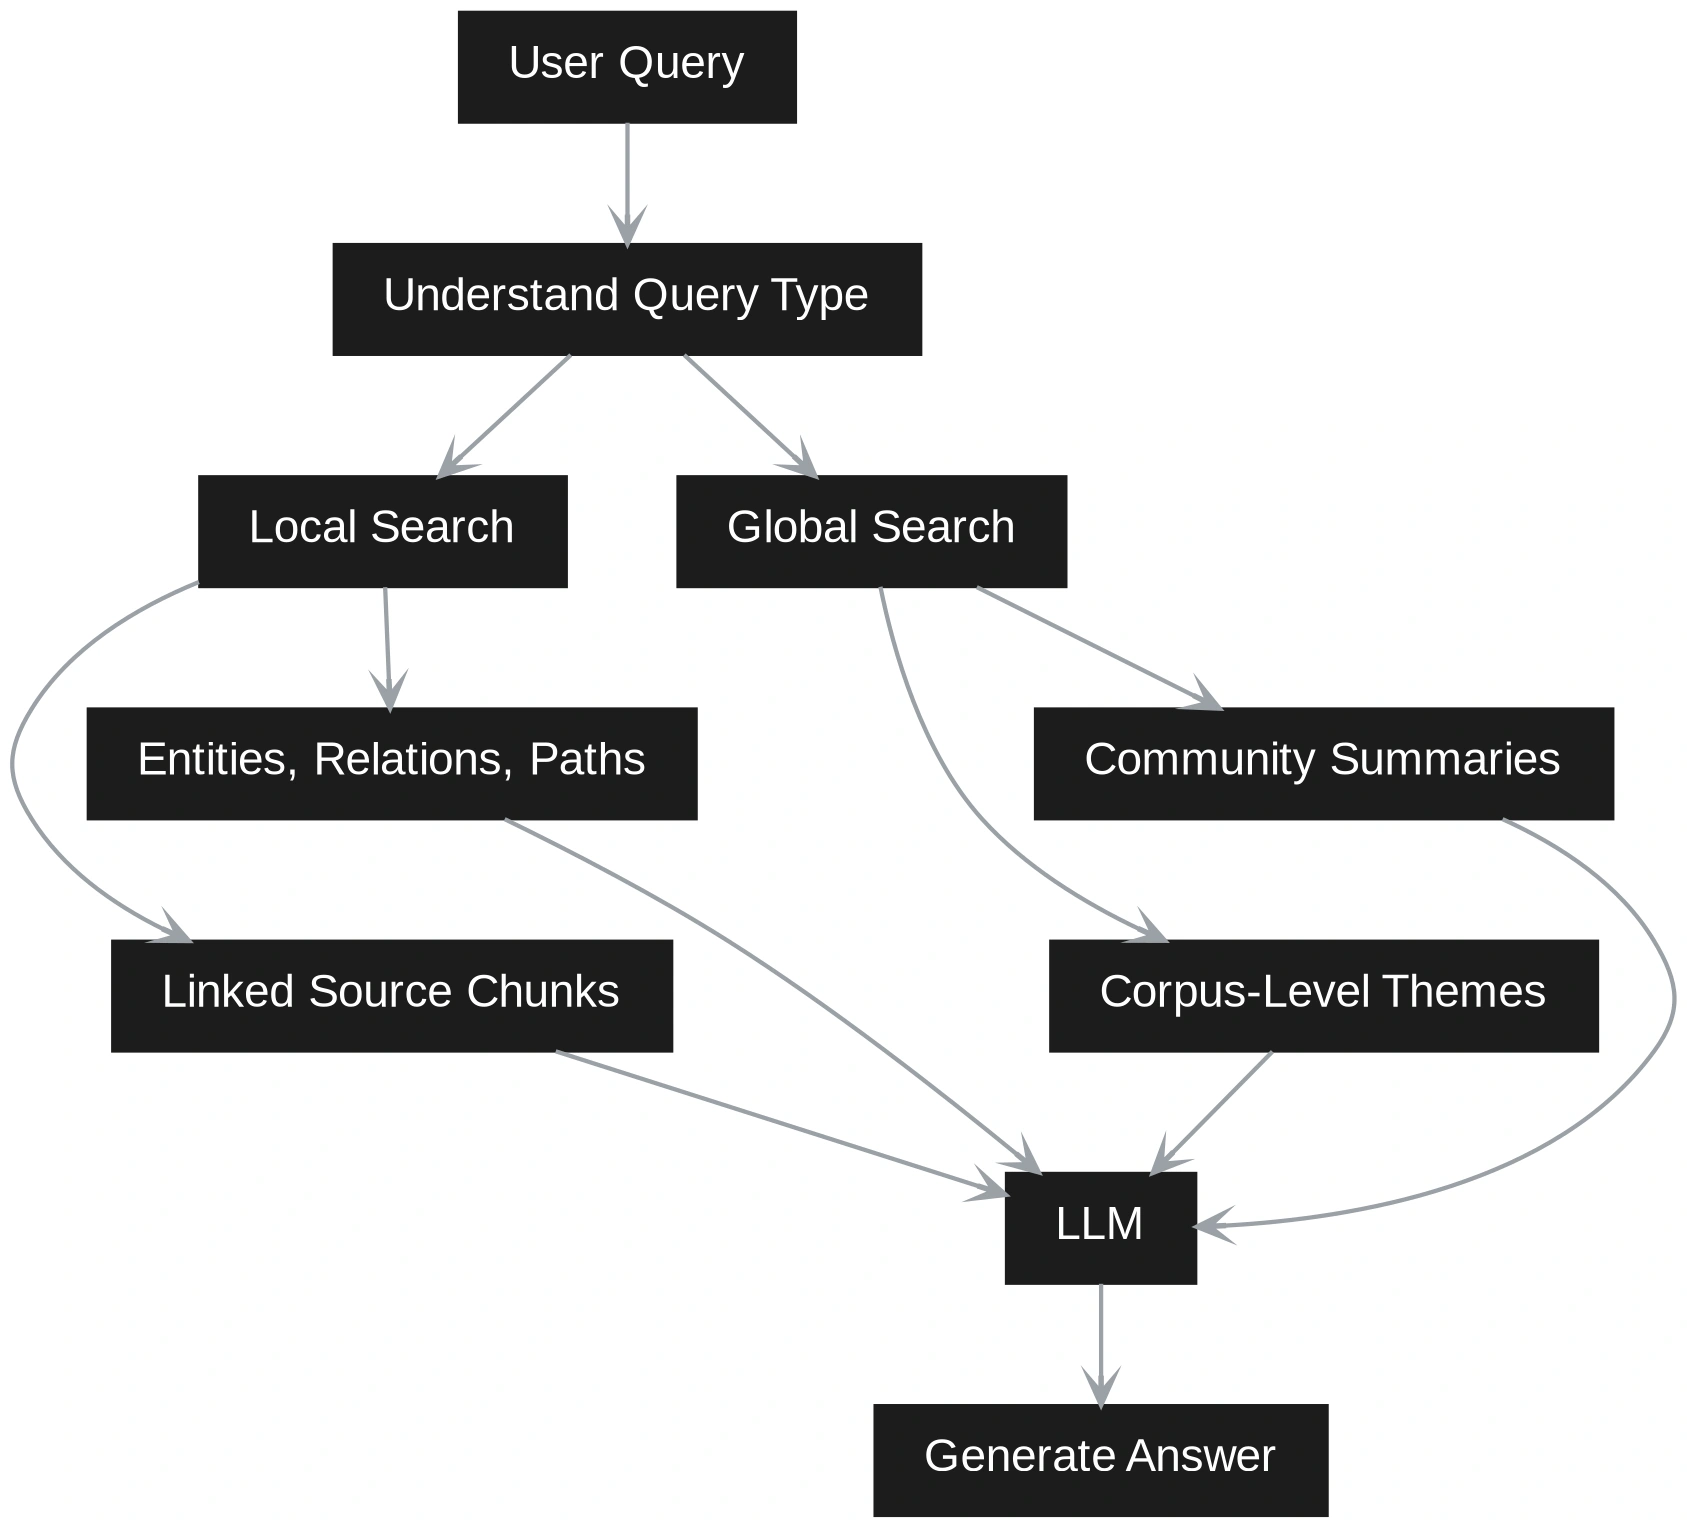
This implies Vector RAG retrieves by similarity, whereas GraphRAG retrieves by construction and that means collectively. Vector RAG is quicker and simpler when the query is slender. GraphRAG is stronger when the reply is determined by connections throughout many paperwork. A hybrid system can use each paths. It could actually first retrieve related chunks via vector search, then develop the context utilizing graph relationships. This offers the LLM each textual proof and structured grounding.
Palms-on: Construct Vector RAG and GraphRAG from Begin to Finish
On this hands-on part, we are going to construct each Vector RAG and GraphRAG on the identical small corpus. The objective is straightforward. We wish to present how Vector RAG retrieves comparable textual content chunks, whereas GraphRAG retrieves entities, relationships, and linked context. We are going to use Python, SentenceTransformers for embeddings, FAISS for vector search, and NetworkX for graph storage and traversal. SentenceTransformers helps encoding textual content into embeddings, FAISS is constructed for environment friendly vector similarity search, and NetworkX shops graphs as nodes and edges with attributes.
First, set up the required libraries.
pip set up sentence-transformers faiss-cpu networkx pandas numpy
Now create a small demo corpus. This corpus is deliberately small so the distinction is straightforward to indicate.
docs = [
{
“id”: “doc1”,
“text”: “NourishCo is facing rising logistics costs in its North region. The operations team believes the issue is linked to poor demand forecasting.”,
},
{
“id”: “doc2”,
“text”: “The North region uses Vendor A for cold chain delivery. Vendor A has repeated delivery delays during high-demand weeks.”,
},
{
“id”: “doc3”,
“text”: “The analytics team proposed a machine learning forecasting model to reduce stockouts and improve supply planning.”,
},
{
“id”: “doc4”,
“text”: “The finance team is concerned that Vendor A delays are increasing working capital pressure because inventory buffers are rising.”,
},
{
“id”: “doc5”,
“text”: “The leadership team wants an AI roadmap that connects demand forecasting, logistics optimization, and vendor performance monitoring.”,
},
]
Now outline a easy chunking operate. On this demo, every doc is already quick, so we are going to deal with every doc as one chunk.
chunks = []
for doc in docs:
chunks.append({
“chunk_id”: doc[“id”],
“textual content”: doc[“text”],
})
print(chunks)
Now construct the Vector RAG index.
from sentence_transformers import SentenceTransformer
import faiss
import numpy as np
mannequin = SentenceTransformer(“all-MiniLM-L6-v2”)
texts = [chunk[“text”] for chunk in chunks]
embeddings = mannequin.encode(texts, convert_to_numpy=True)
dimension = embeddings.form[1]
index = faiss.IndexFlatL2(dimension)
index.add(embeddings)
print(“Vector index created with”, index.ntotal, “chunks”)

Now create a Vector RAG retrieval operate.
def vector_rag_search(question, top_k=3):
query_embedding = mannequin.encode([query], convert_to_numpy=True)
distances, indices = index.search(query_embedding, top_k)
outcomes = []
for idx in indices[0]:
outcomes.append(chunks[idx])
return outcomes
# Check the Vector RAG pipeline
question = “Why are logistics prices rising within the North area?”
vector_results = vector_rag_search(question)
for lead to vector_results:
print(consequence[“chunk_id”], “:”, consequence[“text”])

This retrieves chunks which are semantically near the query. It ought to return paperwork about North area, logistics prices, Vendor A, and delays. That is helpful when the reply is current in a single or two comparable chunks.
Now allow us to construct the GraphRAG model. In a manufacturing system, entities and relationships are normally extracted with an LLM or an data extraction mannequin. For this hands-on demo, we are going to manually outline them so the circulation is straightforward to know and clarify.
import networkx as nx
G = nx.Graph()
entities = [
“NourishCo”,
“North Region”,
“Logistics Costs”,
“Demand Forecasting”,
“Vendor A”,
“Delivery Delays”,
“Analytics Team”,
“ML Forecasting Model”,
“Stockouts”,
“Supply Planning”,
“Finance Team”,
“Working Capital Pressure”,
“Inventory Buffers”,
“Leadership Team”,
“AI Roadmap”,
“Logistics Optimization”,
“Vendor Performance Monitoring”,
]
G.add_nodes_from(entities)
relationships = [
(“NourishCo”, “North Region”, “operates in”),
(“North Region”, “Logistics Costs”, “has issue”),
(“Logistics Costs”, “Demand Forecasting”, “linked to”),
(“North Region”, “Vendor A”, “uses”),
(“Vendor A”, “Delivery Delays”, “causes”),
(“Delivery Delays”, “Logistics Costs”, “increases”),
(“Analytics Team”, “ML Forecasting Model”, “proposed”),
(“ML Forecasting Model”, “Demand Forecasting”, “improves”),
(“ML Forecasting Model”, “Stockouts”, “reduces”),
(“ML Forecasting Model”, “Supply Planning”, “improves”),
(“Finance Team”, “Working Capital Pressure”, “concerned about”),
(“Vendor A”, “Working Capital Pressure”, “contributes to”),
(“Inventory Buffers”, “Working Capital Pressure”, “increase”),
(“Delivery Delays”, “Inventory Buffers”, “increase”),
(“Leadership Team”, “AI Roadmap”, “wants”),
(“AI Roadmap”, “Demand Forecasting”, “includes”),
(“AI Roadmap”, “Logistics Optimization”, “includes”),
(“AI Roadmap”, “Vendor Performance Monitoring”, “includes”),
]
for supply, goal, relation in relationships:
G.add_edge(supply, goal, relation=relation)
print(
“Graph created with”,
G.number_of_nodes(),
“nodes and”,
G.number_of_edges(),
“edges”,
)

Now create a operate to examine graph neighbors.
def get_graph_context(entity, depth=1):
if entity not in G:
return []
context = []
visited = set([entity])
frontier = [entity]
for _ in vary(depth):
next_frontier = []
for node in frontier:
for neighbor in G.neighbors(node):
edge_data = G.get_edge_data(node, neighbor)
relation = edge_data[“relation”]
context.append({
“supply”: node,
“relation”: relation,
“goal”: neighbor,
})
if neighbor not in visited:
visited.add(neighbor)
next_frontier.append(neighbor)
frontier = next_frontier
return context
# Check the graph retrieval
graph_results = get_graph_context(“Vendor A”, depth=2)
for merchandise in graph_results:
print(merchandise[“source”], “–“, merchandise[“relation”], “–“, merchandise[“target”])
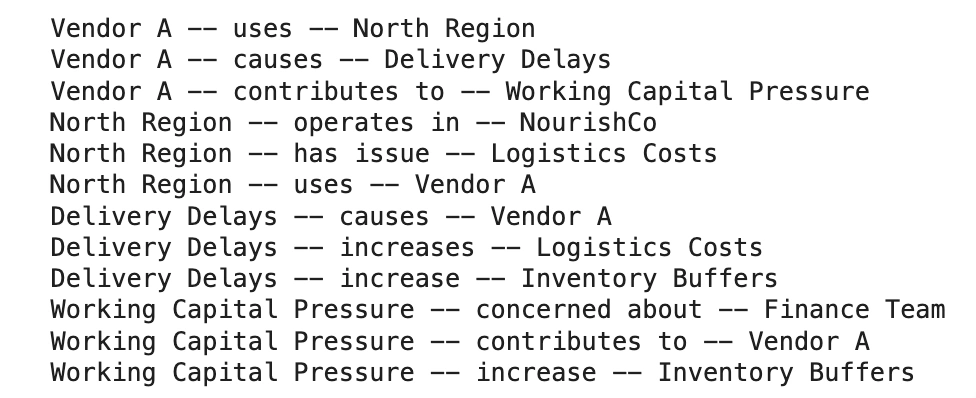
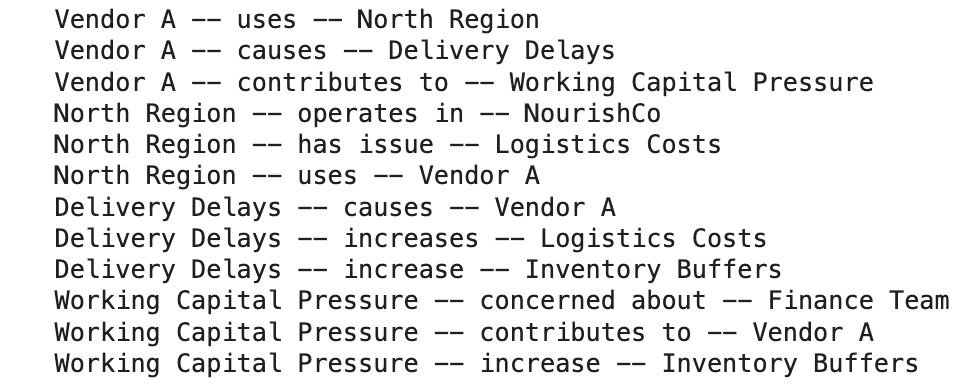
This offers linked context. It doesn’t simply retrieve comparable chunks. It reveals how Vendor A connects to supply delays, logistics prices, stock buffers, and dealing capital strain.
Now we create a easy GraphRAG question operate. For the demo, we are going to map question key phrases to entities.
def detect_entity(question):
query_lower = question.decrease()
entity_map = {
“vendor”: “Vendor A”,
“logistics”: “Logistics Prices”,
“north”: “North Area”,
“forecasting”: “Demand Forecasting”,
“working capital”: “Working Capital Stress”,
“monetary strain”: “Working Capital Stress”,
“roadmap”: “AI Roadmap”,
}
for key phrase, entity in entity_map.objects():
if key phrase in query_lower:
return entity
return None
def graph_rag_search(question, depth=2):
entity = detect_entity(question)
if not entity:
return []
return get_graph_context(entity, depth=depth)
# Check GraphRAG
question = “How is Vendor A linked to monetary strain?”
graph_context = graph_rag_search(question)
for merchandise in graph_context:
print(merchandise[“source”], “–“, merchandise[“relation”], “–“, merchandise[“target”])
Now evaluate each strategies on the identical question.
question = “How is Vendor A linked to monetary strain?”
print(“VECTOR RAG RESULTS”)
vector_results = vector_rag_search(question)
for lead to vector_results:
print(“-“, consequence[“text”])

print(“nGRAPHRAG RESULTS”)
graph_context = graph_rag_search(question)
for merchandise in graph_context:
print(“-“, merchandise[“source”], merchandise[“relation”], merchandise[“target”])
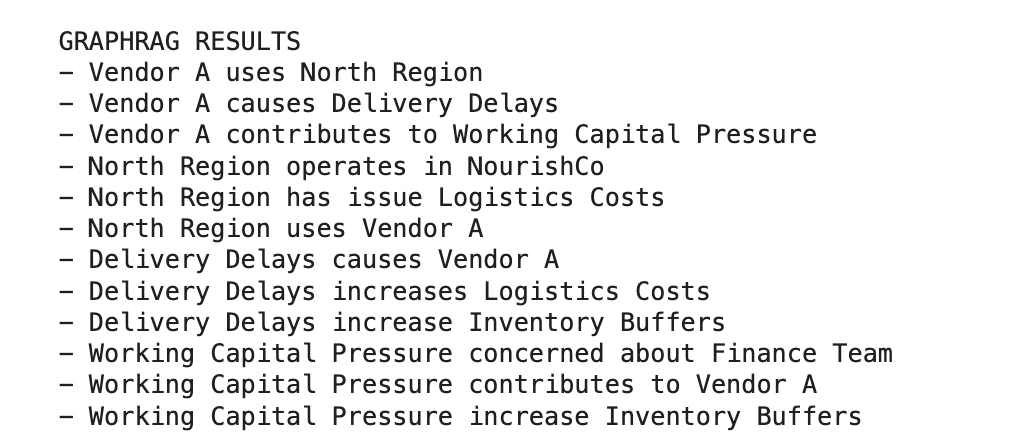
The Vector RAG output will return essentially the most comparable textual content chunks. It could discover the finance doc and the Vendor A doc. GraphRAG will present the connection chain extra clearly. It could actually present that Vendor A causes supply delays, supply delays improve stock buffers, and stock buffers improve working capital strain.
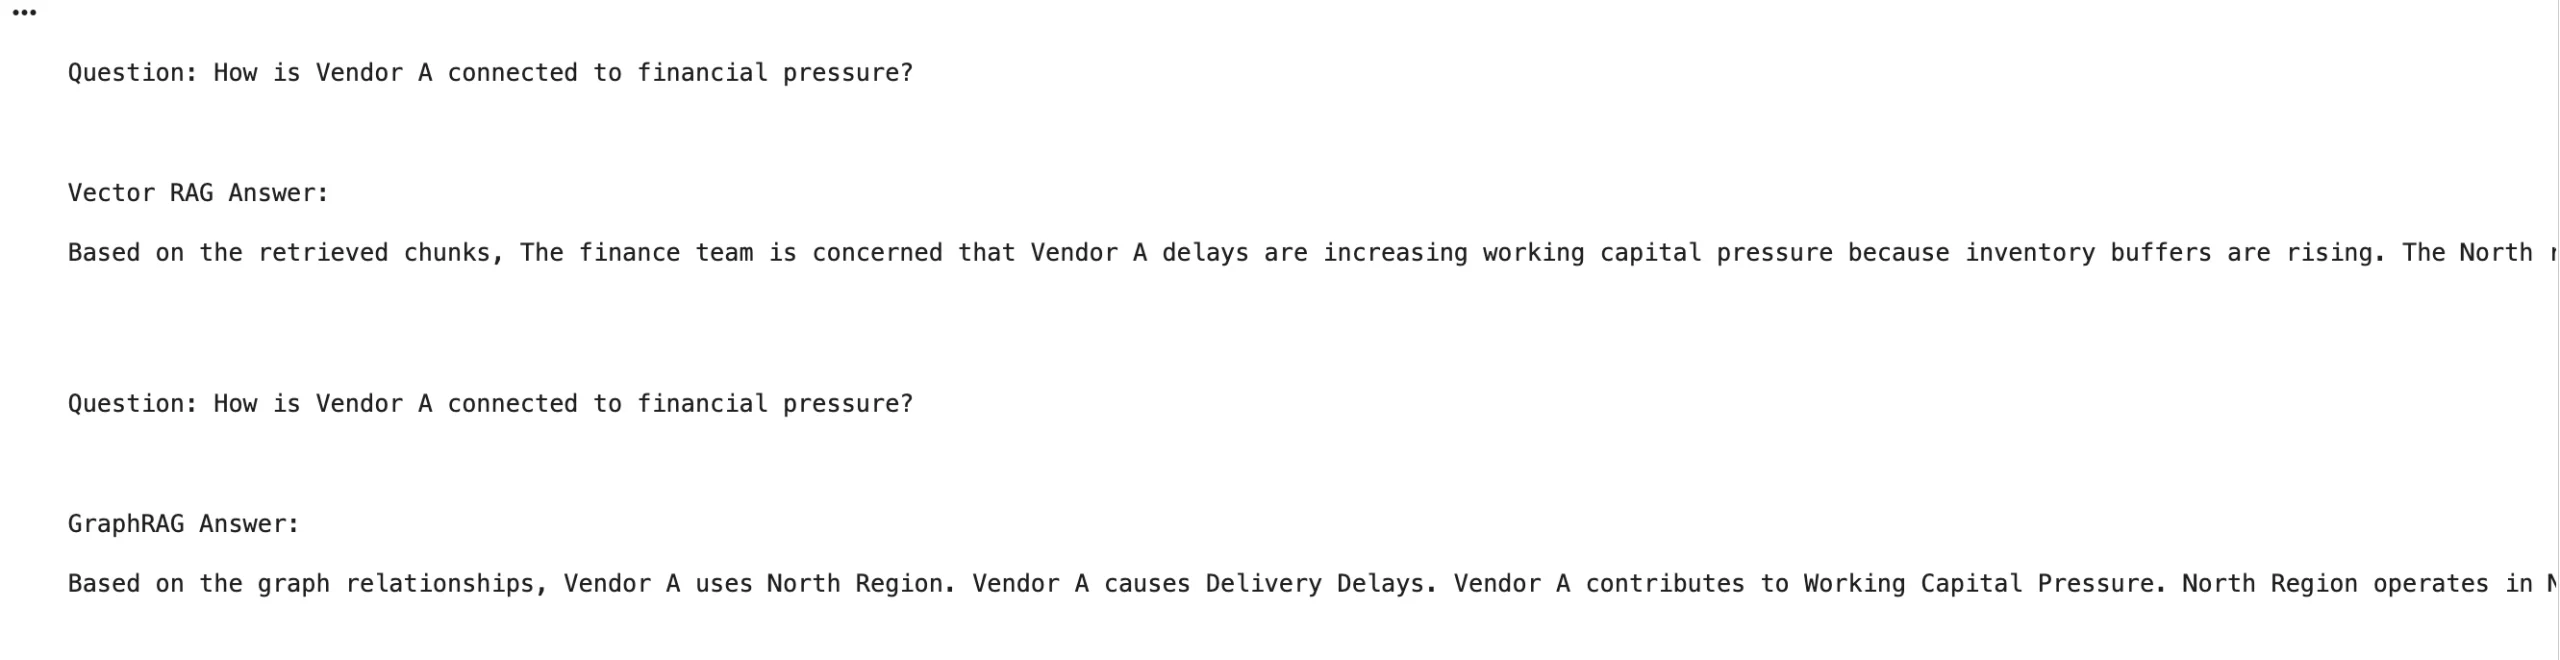
Now add a easy reply generator. This model doesn’t require an LLM API. It creates a readable reply from the retrieved context.
def generate_vector_answer(question, retrieved_chunks):
context = ” “.be a part of([chunk[“text”] for chunk in retrieved_chunks])
reply = f”””
Query: {question}
Vector RAG Reply:
Primarily based on the retrieved chunks, {context}
“””
return reply
def generate_graph_answer(question, graph_context):
details = []
for merchandise in graph_context:
details.append(
f”{merchandise[‘source’]} {merchandise[‘relation’]} {merchandise[‘target’]}”
)
joined_facts = “. “.be a part of(details)
reply = f”””
Query: {question}
GraphRAG Reply:
Primarily based on the graph relationships, {joined_facts}.
“””
return reply
# Run each reply turbines
question = “How is Vendor A linked to monetary strain?”
vector_context = vector_rag_search(question)
graph_context = graph_rag_search(question)
print(generate_vector_answer(question, vector_context))
print(generate_graph_answer(question, graph_context))
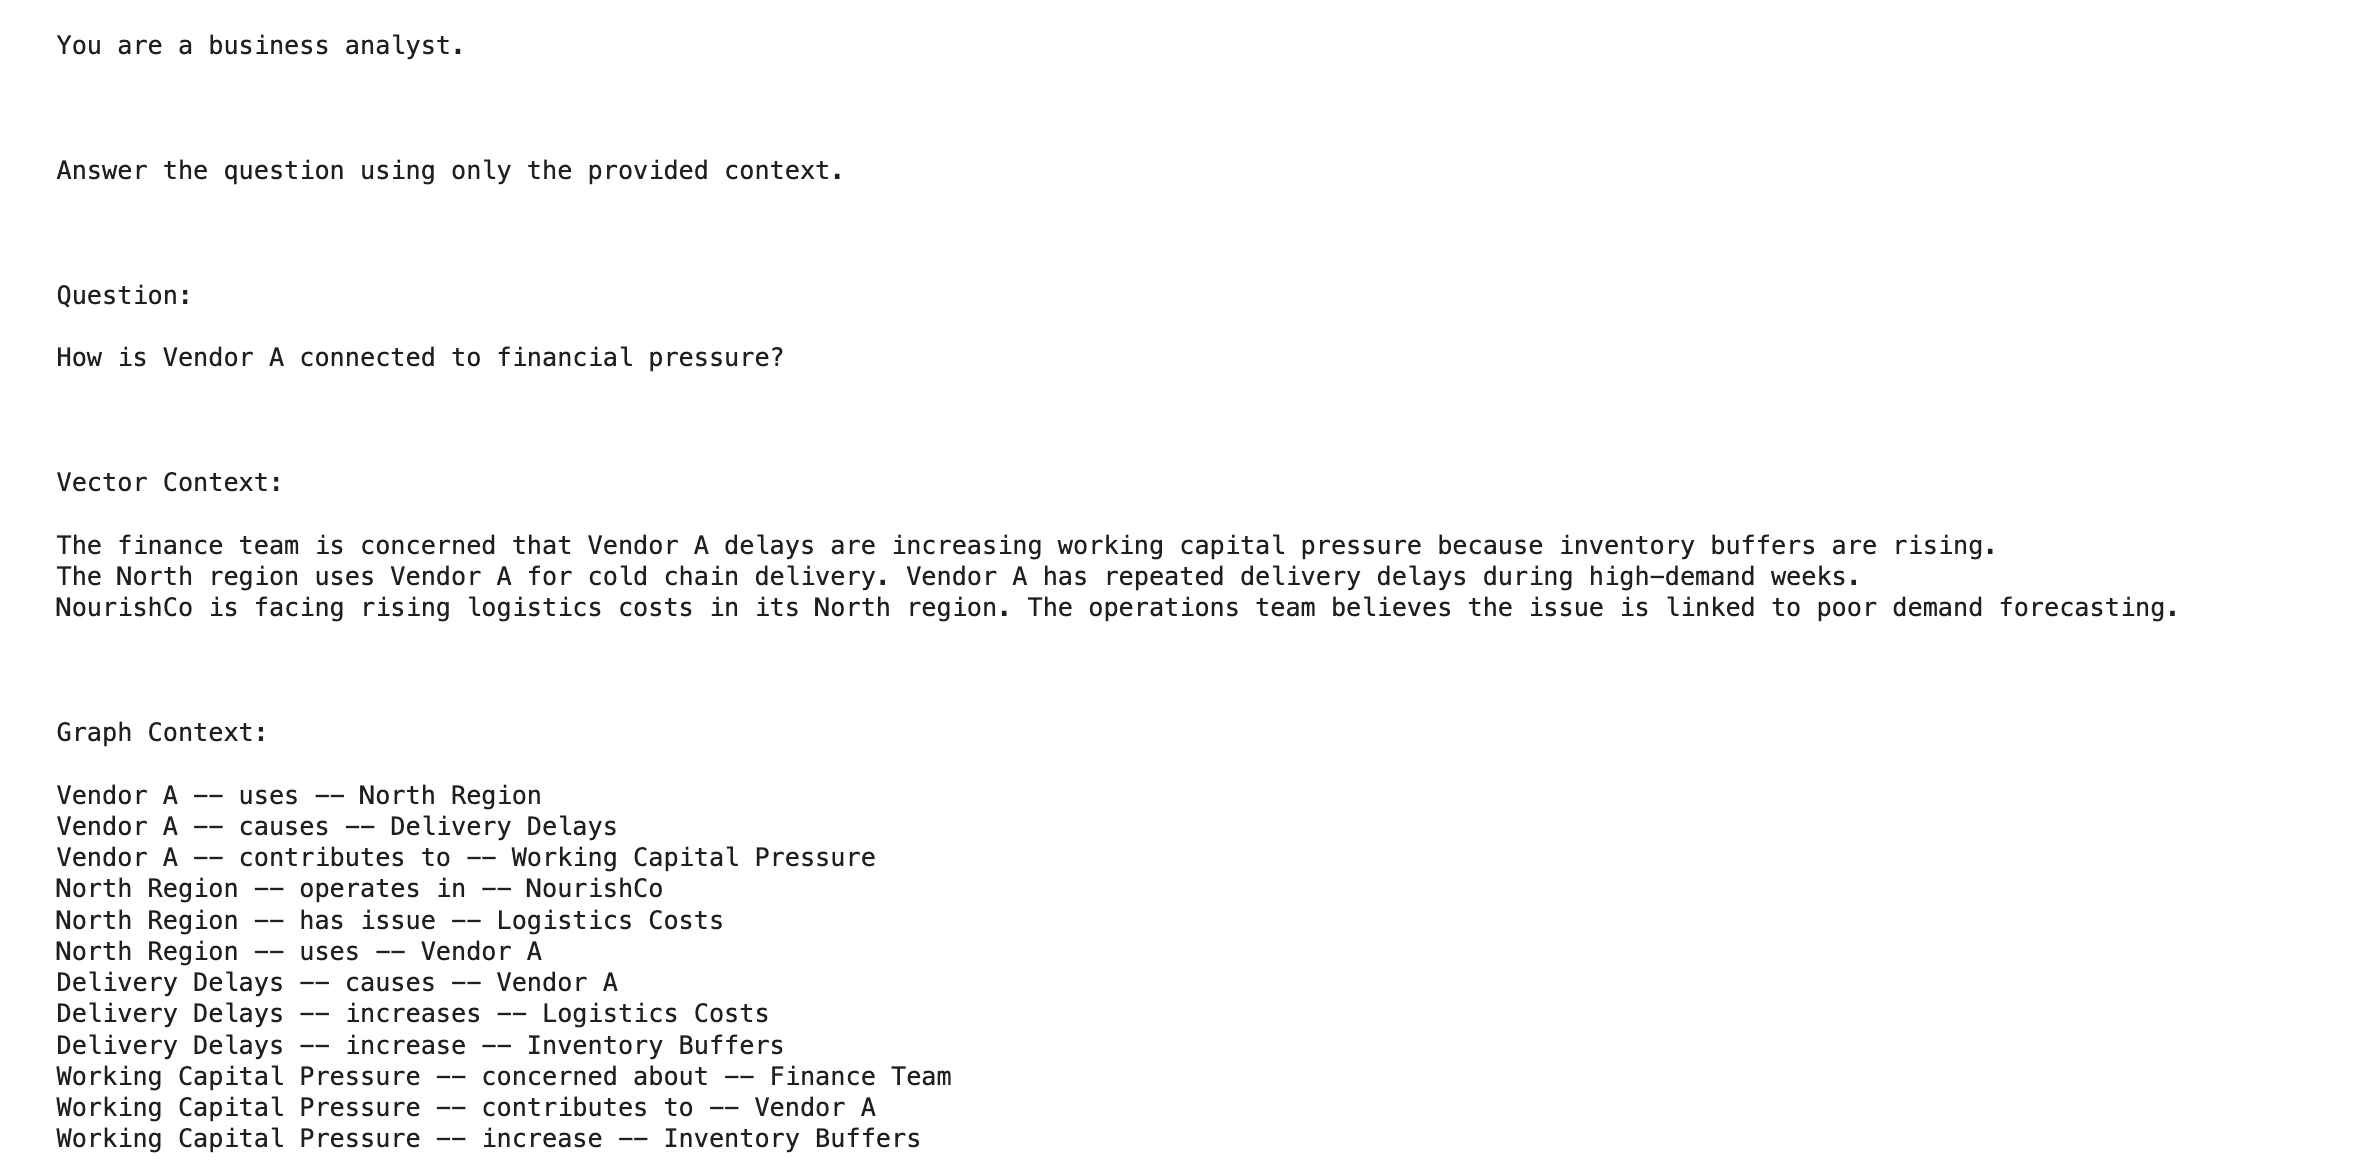
For a extra practical demo, you possibly can join this retrieval output to an LLM. The LLM immediate might be stored easy.
def build_llm_prompt(question, vector_context, graph_context):
vector_text = “n”.be a part of([chunk[“text”] for chunk in vector_context])
graph_text = “n”.be a part of([
f”{item[‘source’]} — {merchandise[‘relation’]} — {merchandise[‘target’]}”
for merchandise in graph_context
])
immediate = f”””
You’re a enterprise analyst.
Reply the query utilizing solely the offered context.
Query:
{question}
Vector Context:
{vector_text}
Graph Context:
{graph_text}
Ultimate Reply:
“””
return immediate
immediate = build_llm_prompt(question, vector_context, graph_context)
print(immediate)
When to Use Vector RAG, GraphRAG, or Hybrid RAG
Use Vector RAG when the reply is probably going current in a single or a couple of textual content chunks. It’s easy, quick, and works nicely for direct lookup questions.
Frequent use circumstances embrace:
FAQs
Coverage paperwork
Product manuals
Assist articles
Doc search
Fundamental data assistants
A typical Vector RAG query seems to be like:
“What does the refund coverage say?”
Use GraphRAG when the reply is determined by relationships throughout the corpus. It’s higher at connecting entities, occasions, dangers, groups, distributors, and enterprise processes.
Frequent use circumstances embrace:
Root-cause evaluation
Compliance assessment
Investigations
Threat evaluation
Vendor evaluation
Strategic synthesis
Information discovery
A typical GraphRAG query seems to be like:
“How is Vendor A linked to monetary strain within the North area?”
Use Hybrid RAG when the system wants each quick retrieval and deeper reasoning. Vector search can shortly discover related textual content, whereas graph retrieval provides linked context.
That is typically the very best manufacturing setup as a result of actual customers ask blended questions. Some questions are easy lookups. Others want multi-hop reasoning. Some want each.
A easy routing rule:
Direct factual query → Vector RAG
Relationship-heavy query → GraphRAG
Combined or strategic query → Hybrid RAG
The sensible rule is straightforward: begin with Vector RAG. Add GraphRAG when similarity search misses essential connections. Use Hybrid RAG when the appliance wants each velocity and construction.
Efficiency, Value, and Upkeep Commerce-offs
Dimension
Vector RAG
GraphRAG
Indexing course of
Paperwork are chunked, embedded, and saved in a vector index.
Paperwork are processed to extract entities, relationships, claims, communities, and summaries.
Indexing price
Decrease price as a result of the pipeline is straightforward.
Greater price as a result of graph building and summarization add additional steps.
Replace effort
Simpler to replace. New paperwork might be chunked and embedded incrementally.
More durable to replace. New content material could require entity extraction, relationship updates, and graph refresh.
Retrieval velocity
Normally sooner as a result of it makes use of similarity search.
Will be slower as a result of it could contain graph traversal, entity growth, and abstract retrieval.
Greatest use case
Direct factual questions and semantic lookup.
Relationship-heavy questions, multi-hop reasoning, and corpus-wide synthesis.
Explainability
Explains solutions primarily via retrieved chunks.
Explains solutions via chunks, entities, relationships, paths, and summaries.
Upkeep complexity
Simpler to keep up in fast-changing data bases.
Wants extra high quality checks as a result of mistaken entities or relationships can have an effect on solutions.
Sensible trade-off
Greatest when velocity, simplicity, and value matter most.
Greatest when construction, explainability, and deeper reasoning matter extra.
Limitations and Failure Modes
It’s all good till issues come to a standstill. Right here’s the way it can occur:
The place Vector RAG can fail
Vector RAG can battle when the suitable reply will not be contained in a single clear chunk.
It could retrieve textual content that sounds semantically comparable however doesn’t totally reply the query.
That is widespread when the question requires reasoning throughout a number of paperwork.
Since Vector RAG doesn’t explicitly perceive entities, paths, or dependencies, it may possibly miss hidden relationships between ideas.
The place GraphRAG can fail
GraphRAG can fail when the underlying graph is weak or incomplete.
If entity extraction is inaccurate, these errors get carried ahead into the graph.
If essential relationships are lacking, the system could produce an incomplete or deceptive reply.
GraphRAG additionally requires extra preprocessing than Vector RAG.
For easy lookup duties, the added price and complexity could not at all times be value it.
The freshness problem
Vector RAG is normally simpler to replace when supply paperwork change.
GraphRAG could require graph updates, refreshed summaries, and relationship validation.
This makes upkeep extra advanced over time.
Choosing the proper method
Consider each programs on actual person questions.
Begin with Vector RAG because the baseline.
Add GraphRAG solely when the baseline fails on relationship-heavy or corpus-wide questions.
Use Hybrid RAG when the identical software wants each direct lookup and deeper reasoning.
Conclusion
Vector RAG and GraphRAG are each helpful, however they resolve completely different issues. Vector RAG is the very best first step. It’s quick, easy, and powerful for direct questions. GraphRAG is beneficial when solutions rely on entities, relationships, paths, and themes throughout many paperwork. It provides construction, however it additionally provides price and upkeep effort. In actual initiatives, the very best method is commonly hybrid. Use Vector RAG for fast proof. Use GraphRAG for linked reasoning. The objective is to not construct essentially the most advanced system. The objective is to retrieve the suitable context and generate dependable solutions.
Incessantly Requested Questions
A. Vector RAG depends on semantic similarity; it chunks textual content, converts it to embeddings, and retrieves paragraphs that sound most just like the person’s question. GraphRAG depends on construction; it extracts entities (like individuals, locations, or firms) and the relationships between them to construct a data graph, retrieving data based mostly on how ideas are explicitly linked.
A. Vector RAG is the only option for direct, factual questions the place the reply is probably going contained inside a single paragraph or doc (e.g., “What’s the firm’s distant work coverage?”). It’s sooner to construct, cheaper to run, and far simpler to replace than GraphRAG.
A. GraphRAG excels at “multi-hop reasoning” and international questions that require connecting data throughout many alternative paperwork. For instance, answering “How did the provision chain delay in Asia impression Q3 income in Europe?” requires understanding the connection between the delay, the area, and the monetary final result, which a data graph handles significantly better than a easy vector search.

Hello, I’m Janvi, a passionate information science fanatic at the moment working at Analytics Vidhya. My journey into the world of knowledge started with a deep curiosity about how we will extract significant insights from advanced datasets.
Login to proceed studying and luxuriate in expert-curated content material.
Preserve Studying for Free