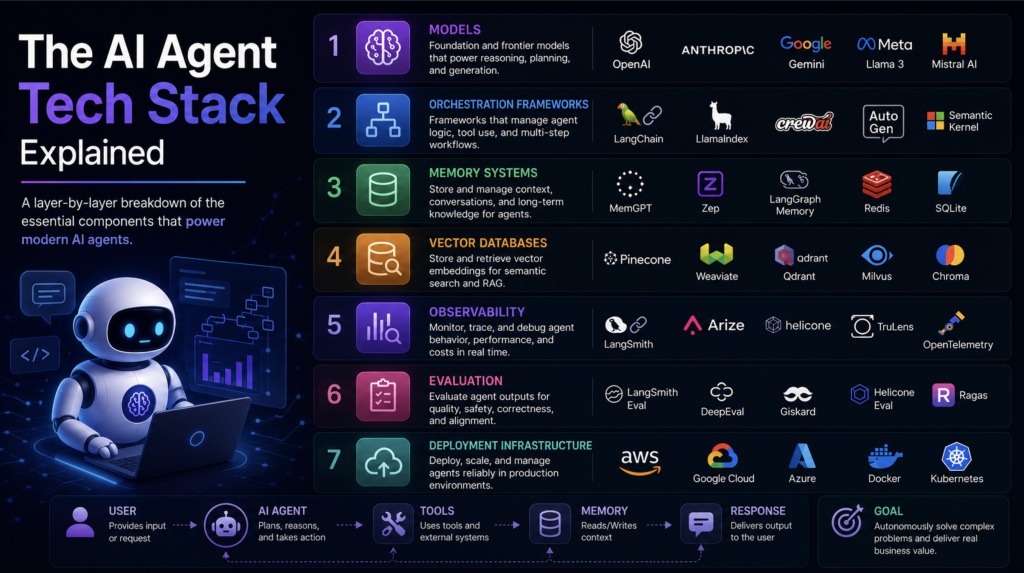
On this article, you’ll find out how the seven layers of a manufacturing AI agent stack match collectively, from the inspiration mannequin right down to deployment infrastructure.
Matters we’ll cowl embrace:
What every layer of the stack does, from the inspiration mannequin and orchestration framework by way of reminiscence, retrieval, instruments, observability, and deployment.
Find out how to implement every layer with working code, together with a stateful agent, a reminiscence system, a RAG pipeline, customized instruments, and tracing.
Which mixture of applied sciences to make use of at every layer relying on whether or not you might be prototyping, scaling a startup, or working in an enterprise atmosphere.
Introduction
Image this: you ask an AI agent to analysis three opponents, pull the pricing knowledge from every of their web sites, summarize the findings right into a structured report, and drop it in a Slack channel by 9am. You hit enter. Thirty seconds later, the report is there.
What simply occurred beneath the hood will not be magic, and it isn’t one factor. It’s seven distinct layers of expertise working in sequence, every one dealing with a selected job, every one able to breaking in its personal particular manner. The mannequin on the prime will get all the eye. The six layers beneath it are what decide whether or not the agent truly works.
In accordance with Gartner, 40% of enterprise purposes will likely be built-in with task-specific AI brokers by the tip of 2026, up from lower than 5% in 2025. That isn’t a gradual curve. That may be a near-vertical adoption line, and the engineers and technical leads chargeable for these deployments want to know the complete stack, not simply the layer they occur to personal.
This text goes by way of every layer so as, from the inspiration mannequin right down to deployment infrastructure. By the tip, you’ll know what every bit is, why it exists, how the layers join to one another, and what to really use at every degree.
Layer 1: The Basis Mannequin
The inspiration mannequin is the cognitive core of an agent. It’s the place reasoning occurs, language is known, and choices about what to do subsequent are made. Every thing else within the stack is both feeding context into it or appearing on what it produces.
In sensible phrases, your principal choices in 2026 are OpenAI’s GPT-5.5, Anthropic’s Claude Sonnet 4.6 (or Claude Opus 4.8 for tougher reasoning), Google’s Gemini 3.1 Professional, and open-weight fashions like Meta’s Llama 4 and Mistral Massive 3. Every has trade-offs value understanding earlier than you commit.
GPT-5.5 is quick for on a regular basis calls and dependable at tool-calling, and it has probably the most mature ecosystem of integrations and the widest group of builders who’ve already run into and solved the sting circumstances you’ll encounter. Claude Sonnet 4.6 handles lengthy paperwork and nuanced instruction-following nicely at a lower cost level than Anthropic’s Opus tier, which issues in document-heavy workflows; attain for Claude Opus 4.8 when a process wants deeper, longer-horizon reasoning. Gemini 3.1 Professional has a 1 million token context window, which is related in case your agent must course of massive codebases or prolonged data bases in a single cross. Open-weight fashions like Llama 4 offer you full management over deployment and knowledge residency, at the price of the infrastructure overhead of working them your self.
There isn’t a longer a tough break up between “commonplace” and “reasoning” mannequin households, the best way there was in 2025; OpenAI, Anthropic, and Google have every folded reasoning right into a single mannequin that decides how lengthy to suppose. GPT-5.5 ships with adjustable reasoning effort ranges (from none as much as xhigh), and the identical applies to Claude’s effort parameter and Gemini’s pondering ranges. For many agent workflows, the default or low-effort setting is the precise selection: quick and low-cost. For duties that require cautious planning or mathematical reasoning, dialling the hassle degree up earns again its value in correctness.
Layer 2: The Orchestration Framework
If the inspiration mannequin is the mind, the orchestration framework is the nervous system. It handles the management stream: deciding what the agent ought to do subsequent, when it ought to name a software, the way it ought to deal with the consequence, and the way the entire reasoning loop stays coherent throughout a number of steps.
The sample that almost all frameworks implement is known as ReAct (Reasoning and Appearing). The agent produces a thought, decides on an motion, executes the motion by way of a software, observes the consequence, after which thinks once more. This loop repeats till the agent produces a closing reply. It sounds easy. In apply, it’s the place most manufacturing failures happen: the agent calls the flawed software, will get caught in a loop, or fails to recognise when it has sufficient info to cease.
LangChain is probably the most extensively adopted framework. It provides a big ecosystem of integrations and good documentation. The criticism that it provides an excessive amount of abstraction is truthful on the prototype stage, however much less related when you want the options that abstraction gives. LangGraph, constructed by the identical crew, is best fitted to stateful multi-agent workflows the place you want fine-grained management over the execution graph. In case your agent entails a number of specialists coordinating on a process, LangGraph is the cleaner selection.
CrewAI is designed particularly for multi-agent coordination. It allows you to outline brokers with roles, assign them duties, and have them collaborate inside a structured workflow. It’s higher-level than LangGraph and quicker to get working, however provides you much less management over the execution particulars. AutoGen, from Microsoft, takes a conversational method to multi-agent techniques. Brokers work together with one another by way of a message-passing interface, which makes the interplay logic very readable.
Semantic Kernel is Microsoft’s enterprise-focused choice, with production-ready help for C#, Python, and Java. If you’re working in an enterprise atmosphere already working on the Microsoft stack, it suits naturally. LlamaIndex began as a doc ingestion and retrieval framework and has since grown right into a full agent framework, with significantly robust help for RAG-heavy workflows.
The precise selection relies on what your agent must do. For a single-agent process runner: LangGraph or LangChain. For a coordinated crew of specialised brokers: CrewAI or AutoGen. For enterprise environments: Semantic Kernel. For document-heavy retrieval workflows: LlamaIndex.
Here’s a minimal working agent in LangGraph that handles software use and maintains state.
Stipulations:
pip set up langgraph langchain-openai langchain-community python-dotenv
pip set up langgraph langchain–openai langchain–group python–dotenv
Find out how to run: Save as agent.py, add your OPENAI_API_KEY to a .env file, then run python agent.py
# agent.py
# Minimal stateful agent with software use constructed on LangGraph
# Python 3.10+ | LangGraph 0.2+ | LangChain 0.3+
import os
from dotenv import load_dotenv
from langchain_openai import ChatOpenAI
from langchain_community.instruments import DuckDuckGoSearchRun
from langchain_core.messages import HumanMessage
from langgraph.prebuilt import create_react_agent
# Load API key from .env file
load_dotenv()
# Initialize the language mannequin
# temperature=0 for deterministic, targeted responses in agentic duties
llm = ChatOpenAI(
mannequin=”gpt-5.5″,
temperature=0,
api_key=os.getenv(“OPENAI_API_KEY”)
)
# Register the instruments the agent can use
# DuckDuckGoSearchRun requires no API key — good for improvement
instruments = [DuckDuckGoSearchRun()]
# create_react_agent from LangGraph wires collectively the LLM,
# instruments, and a built-in ReAct loop — no boilerplate required
agent = create_react_agent(llm, instruments)
# Run the agent with a pattern question
# The agent will resolve whether or not to make use of a software primarily based on the query
consequence = agent.invoke({
“messages”: [HumanMessage(content=”What is the current market cap of Nvidia?”)]
})
# The ultimate response is the final message within the messages checklist
print(consequence[“messages”][-1].content material)
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
# agent.py
# Minimal stateful agent with software use constructed on LangGraph
# Python 3.10+ | LangGraph 0.2+ | LangChain 0.3+
import os
from dotenv import load_dotenv
from langchain_openai import ChatOpenAI
from langchain_community.instruments import DuckDuckGoSearchRun
from langchain_core.messages import HumanMessage
from langgraph.prebuilt import create_react_agent
# Load API key from .env file
load_dotenv()
# Initialize the language mannequin
# temperature=0 for deterministic, targeted responses in agentic duties
llm = ChatOpenAI(
mannequin=“gpt-5.5”,
temperature=0,
api_key=os.getenv(“OPENAI_API_KEY”)
)
# Register the instruments the agent can use
# DuckDuckGoSearchRun requires no API key — good for improvement
instruments = [DuckDuckGoSearchRun()]
# create_react_agent from LangGraph wires collectively the LLM,
# instruments, and a built-in ReAct loop — no boilerplate required
agent = create_react_agent(llm, instruments)
# Run the agent with a pattern question
# The agent will resolve whether or not to make use of a software primarily based on the query
consequence = agent.invoke({
“messages”: [HumanMessage(content=“What is the current market cap of Nvidia?”)]
})
# The ultimate response is the final message within the messages checklist
print(consequence[“messages”][–1].content material)
What this does: create_react_agent handles the complete ReAct loop routinely. The agent receives the query, decides it wants present knowledge, calls the DuckDuckGo search software, reads the consequence, and synthesizes a closing reply. The messages checklist within the output accommodates the complete hint of that reasoning course of.
Layer 3: Reminiscence Methods
Statelessness is the default habits of any LLM. Each name begins from scratch, with no data of what got here earlier than except you explicitly cross that context in. For a one-shot query, that’s superb. For an agent that should observe a dialog, keep in mind a person’s preferences, or construct on work it did yesterday, it’s a basic drawback.
In accordance with Atlan’s analysis on AI agent reminiscence, 95% of enterprise generative AI pilots delivered zero measurable ROI in 2025, with failure attributed to context readiness fairly than mannequin high quality. Brokers are failing not as a result of the mannequin is flawed, however as a result of the reminiscence layer will not be there.
There are 4 varieties of reminiscence in a manufacturing agent, and every one handles a unique job:
Working reminiscence (in-context) is the energetic context window. It holds the present dialog, any paperwork you’ve handed in, and the outcomes of current software calls. It’s quick and requires no infrastructure, however it’s session-bound. When the session ends, it’s gone.
Episodic reminiscence is a log of prior interactions. As described within the analysis on reminiscence varieties, episodic reminiscence shops what occurred: timestamp, process, actions taken, final result. That is what permits an agent to reply “What did we work on final Tuesday?” or “What did the person say about this undertaking three periods in the past?“
Semantic reminiscence is factual data saved externally, together with definitions, entity relationships, and domain-specific information that the mannequin was not skilled on. That is the place your RAG pipeline feeds in (extra on that within the subsequent layer).
Procedural reminiscence encodes workflows and tool-use patterns, repeatable behaviors the agent ought to all the time comply with. This lives within the system immediate or a version-controlled instruction file, and it shapes each response the agent produces.
Right here is implement working and episodic reminiscence collectively utilizing LangChain’s really helpful sample for LangChain 0.3+:
Stipulations:
pip set up langchain langchain-openai python-dotenv
pip set up langchain langchain–openai python–dotenv
Find out how to run: Save as reminiscence.py, guarantee your .env has OPENAI_API_KEY, then run python reminiscence.py
# reminiscence.py
# Working reminiscence + episodic reminiscence for persistent agent context
# Makes use of the present LangChain 0.3+ sample (legacy ConversationBufferMemory is deprecated)
import os
import json
from datetime import datetime
from dotenv import load_dotenv
from langchain_openai import ChatOpenAI
from langchain_core.messages import HumanMessage, AIMessage, SystemMessage, trim_messages
load_dotenv()
llm = ChatOpenAI(
mannequin=”gpt-5.5″,
temperature=0.2,
api_key=os.getenv(“OPENAI_API_KEY”)
)
# ── EPISODIC MEMORY STORE ─────────────────────────────────────────────────────
# In manufacturing, exchange this checklist with a database (SQLite, Postgres, Redis).
# The construction right here: every episode is a dict with timestamp, person enter, and agent response.
episodic_store: checklist[dict] = []
def save_episode(user_input: str, agent_response: str) -> None:
“””Save a dialog flip to the episodic retailer.”””
episodic_store.append({
“timestamp”: datetime.now().isoformat(),
“person”: user_input,
“agent”: agent_response
})
def load_recent_episodes(n: int = 5) -> str:
“””Retrieve the final N episodes as a formatted string for injection into context.”””
if not episodic_store:
return “No prior dialog historical past.”
current = episodic_store[-n:]
return “n”.be part of(
f”[{ep[‘timestamp’]}] Person: {ep[‘user’]} | Agent: {ep[‘agent’]}”
for ep in current
)
# ── WORKING MEMORY (IN-CONTEXT) ───────────────────────────────────────────────
# We handle the message checklist ourselves and cross it by way of trim_messages
# earlier than every LLM name to remain throughout the mannequin’s context restrict.
# max_tokens=4000 leaves headroom for the mannequin’s response.
working_memory: checklist = []
def chat(user_input: str) -> str:
“””
Ship a message to the agent.
Episodic historical past is injected into the system immediate.
Working reminiscence is trimmed earlier than every name to forestall context overflow.
“””
# Inject episodic reminiscence into the system immediate so the mannequin has long-term context
system = SystemMessage(content material=(
“You’re a useful, context-aware assistant.nn”
“Latest dialog historical past:n”
f”{load_recent_episodes()}”
))
# Add the brand new person message to working reminiscence
working_memory.append(HumanMessage(content material=user_input))
# Trim working reminiscence to remain throughout the context window
# This compresses older messages fairly than dropping them totally
trimmed = trim_messages(
working_memory,
max_tokens=4000,
technique=”final”, # Hold the latest messages
token_counter=llm, # Use the mannequin’s tokenizer for correct counts
include_system=True,
allow_partial=False
)
# Name the mannequin with system context + trimmed working reminiscence
response = llm.invoke([system] + trimmed)
reply = response.content material
# Save the trade to episodic reminiscence and add the reply to working reminiscence
save_episode(user_input, reply)
working_memory.append(AIMessage(content material=reply))
return reply
# ── DEMO ──────────────────────────────────────────────────────────────────────
if __name__ == “__main__”:
print(chat(“My identify is Alex and I am constructing a RAG pipeline for authorized paperwork.”))
print(chat(“What’s one of the best vector database for my use case?”))
print(chat(“What did I let you know I used to be constructing?”)) # Assessments episodic recall
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
87
88
89
90
91
# reminiscence.py
# Working reminiscence + episodic reminiscence for persistent agent context
# Makes use of the present LangChain 0.3+ sample (legacy ConversationBufferMemory is deprecated)
import os
import json
from datetime import datetime
from dotenv import load_dotenv
from langchain_openai import ChatOpenAI
from langchain_core.messages import HumanMessage, AIMessage, SystemMessage, trim_messages
load_dotenv()
llm = ChatOpenAI(
mannequin=“gpt-5.5”,
temperature=0.2,
api_key=os.getenv(“OPENAI_API_KEY”)
)
# ── EPISODIC MEMORY STORE ─────────────────────────────────────────────────────
# In manufacturing, exchange this checklist with a database (SQLite, Postgres, Redis).
# The construction right here: every episode is a dict with timestamp, person enter, and agent response.
episodic_store: checklist[dict] = []
def save_episode(user_input: str, agent_response: str) -> None:
“”“Save a dialog flip to the episodic retailer.”“”
episodic_store.append({
“timestamp”: datetime.now().isoformat(),
“person”: user_input,
“agent”: agent_response
})
def load_recent_episodes(n: int = 5) -> str:
“”“Retrieve the final N episodes as a formatted string for injection into context.”“”
if not episodic_store:
return “No prior dialog historical past.”
current = episodic_store[–n:]
return “n”.be part of(
f“[{ep[‘timestamp’]}] Person: {ep[‘user’]} | Agent: {ep[‘agent’]}”
for ep in current
)
# ── WORKING MEMORY (IN-CONTEXT) ───────────────────────────────────────────────
# We handle the message checklist ourselves and cross it by way of trim_messages
# earlier than every LLM name to remain throughout the mannequin’s context restrict.
# max_tokens=4000 leaves headroom for the mannequin’s response.
working_memory: checklist = []
def chat(user_input: str) -> str:
“”“
Ship a message to the agent.
Episodic historical past is injected into the system immediate.
Working reminiscence is trimmed earlier than every name to forestall context overflow.
““”
# Inject episodic reminiscence into the system immediate so the mannequin has long-term context
system = SystemMessage(content material=(
“You’re a useful, context-aware assistant.nn”
“Latest dialog historical past:n”
f“{load_recent_episodes()}”
))
# Add the brand new person message to working reminiscence
working_memory.append(HumanMessage(content material=user_input))
# Trim working reminiscence to remain throughout the context window
# This compresses older messages fairly than dropping them totally
trimmed = trim_messages(
working_memory,
max_tokens=4000,
technique=“final”, # Hold the latest messages
token_counter=llm, # Use the mannequin’s tokenizer for correct counts
include_system=True,
allow_partial=False
)
# Name the mannequin with system context + trimmed working reminiscence
response = llm.invoke([system] + trimmed)
reply = response.content material
# Save the trade to episodic reminiscence and add the reply to working reminiscence
save_episode(user_input, reply)
working_memory.append(AIMessage(content material=reply))
return reply
# ── DEMO ──────────────────────────────────────────────────────────────────────
if __name__ == “__main__”:
print(chat(“My identify is Alex and I am constructing a RAG pipeline for authorized paperwork.”))
print(chat(“What’s one of the best vector database for my use case?”))
print(chat(“What did I let you know I used to be constructing?”)) # Assessments episodic recall
What this does: The episodic_store acts as a light-weight persistent log that will get summarized into the system immediate on each name. The working_memory checklist holds the in-session message historical past and will get trimmed by trim_messages earlier than every LLM name to forestall token overflow. The ultimate take a look at query, “What did I let you know I used to be constructing?” verifies that episodic recall is working appropriately even after the context window has moved on.
Layer 4: Vector Databases and Retrieval (RAG)
Basis fashions know loads, however they have no idea your paperwork. They weren’t skilled in your inner data base, your buyer help historical past, your proprietary analysis, or something that has occurred since their coaching cutoff. Retrieval-Augmented Technology (RAG) is the way you repair that.
The idea is easy: as an alternative of attempting to suit a complete data base into the context window, you change your paperwork into numerical representations (embeddings), retailer them in a vector database, and retrieve solely probably the most related chunks at question time. The agent will get a context window filled with exactly the precise info fairly than every little thing you’ve ever written.
The worldwide vector database market reached $3.2 billion in 2025 and is rising at 24% yearly, which displays how central retrieval has develop into to manufacturing AI techniques.
The main choices every serve a unique use case:
Pinecone is totally managed with zero infrastructure overhead. You pay for it, push vectors to it, and question it. At 100 million vectors, it maintains recall with out tuning. The precise selection once you need to ship and never take into consideration infrastructure.
Weaviate is open-source with a managed cloud choice, and it leads the sector on hybrid search combining vector similarity, key phrase matching (BM25), and metadata filtering in a single question. In case your retrieval wants require greater than pure semantic search, Weaviate handles it natively.
Chroma is developer-first and runs regionally with no infrastructure. The 2025 Rust rewrite made it considerably quicker. It’s the proper selection for prototyping and small-to-medium manufacturing workloads the place developer expertise issues greater than scale.
pgvector is a PostgreSQL extension that provides vector search to a database you might already be working. In case your crew already runs Postgres, pgvector is the lowest-friction path to manufacturing RAG. It handles hundreds of thousands of vectors with HNSW indexing and stays inside single-node PostgreSQL limits for many manufacturing workloads.
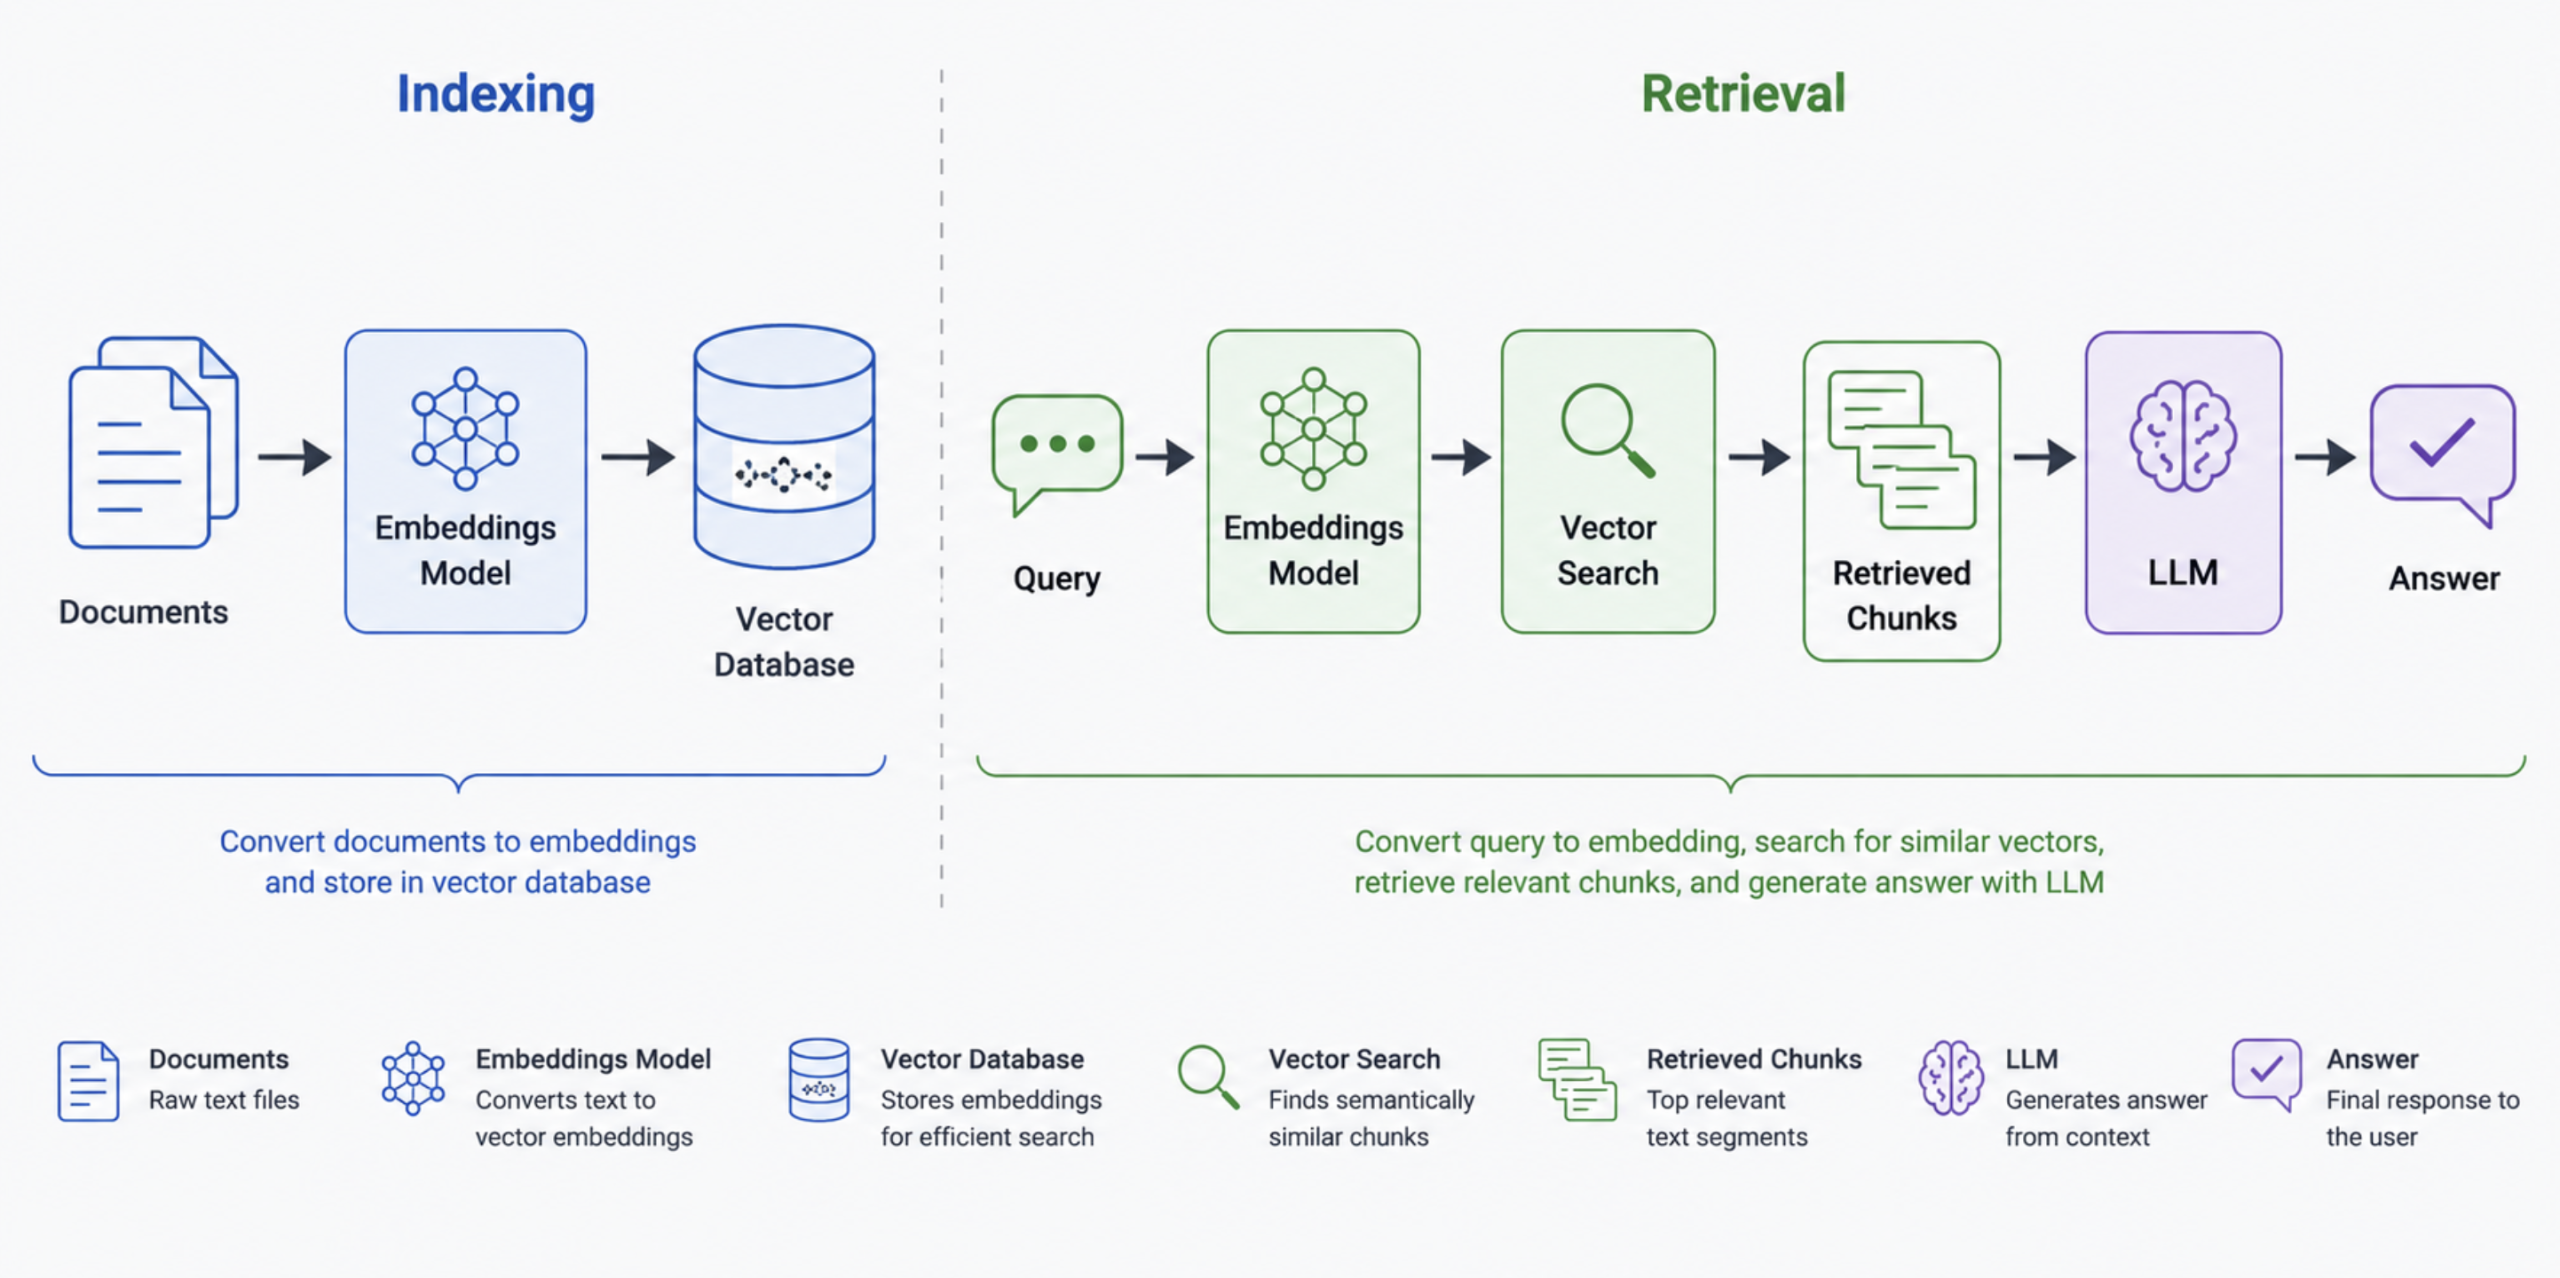
A horizontal three-step stream diagram displaying the RAG pipeline: Paperwork → Embeddings Mannequin → Vector Database (click on to enlarge)
Here’s a working RAG pipeline utilizing Chroma and OpenAI embeddings.
Stipulations:
pip set up langchain langchain-openai langchain-chroma langchain-text-splitters chromadb python-dotenv
pip set up langchain langchain–openai langchain–chroma langchain–textual content–splitters chromadb python–dotenv
Find out how to run: Save as rag_pipeline.py, add OPENAI_API_KEY to your .env, then run python rag_pipeline.py.
# rag_pipeline.py
# Minimal RAG pipeline: ingest paperwork → embed → retailer in Chroma → retrieve and reply
# Python 3.10+ | ChromaDB 0.5+ | LangChain 0.3+
import os
from dotenv import load_dotenv
from langchain_openai import ChatOpenAI, OpenAIEmbeddings
from langchain_chroma import Chroma
from langchain_text_splitters import RecursiveCharacterTextSplitter
from langchain_core.paperwork import Doc
from langchain_core.prompts import ChatPromptTemplate
load_dotenv()
# ── STEP 1: SAMPLE DOCUMENTS ──────────────────────────────────────────────────
# Change this checklist with actual paperwork out of your data base.
# In manufacturing, load from PDFs, databases, APIs, or file techniques.
paperwork = [
Document(page_content=”Pinecone is a managed vector database optimized for fast, “
“low-latency similarity search at scale. It handles infrastructure automatically “
“and is best for production RAG when you don’t want to manage servers.”,
metadata={“source”: “vector_db_guide”, “topic”: “pinecone”}),
Document(page_content=”Weaviate is an open-source vector database with native hybrid search “
“support, combining BM25 keyword search with dense vector search in a single query. “
“It can be self-hosted or used via Weaviate Cloud.”,
metadata={“source”: “vector_db_guide”, “topic”: “weaviate”}),
Document(page_content=”Chroma is a developer-friendly, local-first vector database ideal for “
“prototyping. The 2025 Rust rewrite significantly improved performance. “
“Best for small-to-medium production workloads and local development.”,
metadata={“source”: “vector_db_guide”, “topic”: “chroma”}),
Document(page_content=”pgvector is a PostgreSQL extension that adds vector similarity search “
“to an existing Postgres database. With HNSW indexing, it handles millions of vectors “
“at low latency. Best choice if your team already runs PostgreSQL in production.”,
metadata={“source”: “vector_db_guide”, “topic”: “pgvector”}),
]
# ── STEP 2: CHUNK THE DOCUMENTS ───────────────────────────────────────────────
# Massive paperwork are break up into smaller chunks earlier than embedding.
# chunk_size=500 characters; chunk_overlap=50 preserves context throughout chunk boundaries.
splitter = RecursiveCharacterTextSplitter(chunk_size=500, chunk_overlap=50)
chunks = splitter.split_documents(paperwork)
# ── STEP 3: EMBED AND STORE IN CHROMA ────────────────────────────────────────
# OpenAIEmbeddings converts every chunk right into a high-dimensional vector.
# Chroma shops these vectors regionally within the ./chroma_db listing.
# On subsequent runs, the prevailing retailer is loaded fairly than rebuilt.
embeddings = OpenAIEmbeddings(
mannequin=”text-embedding-3-small”, # Quick and cost-effective for many RAG duties
api_key=os.getenv(“OPENAI_API_KEY”)
)
vectorstore = Chroma.from_documents(
paperwork=chunks,
embedding=embeddings,
persist_directory=”./chroma_db” # Persist to disk so you do not re-embed on each run
)
# ── STEP 4: RETRIEVAL ──────────────────────────────────────────────────────────
# Converts the question into an embedding and finds probably the most comparable chunks.
# okay=3 returns the highest 3 most related chunks.
retriever = vectorstore.as_retriever(search_kwargs={“okay”: 3})
# ── STEP 5: GENERATION ────────────────────────────────────────────────────────
llm = ChatOpenAI(
mannequin=”gpt-5.5″,
temperature=0,
api_key=os.getenv(“OPENAI_API_KEY”)
)
# The immediate tells the mannequin to make use of solely the retrieved context.
# This prevents the mannequin from hallucinating information not in your data base.
rag_prompt = ChatPromptTemplate.from_messages([
(“system”,
“Answer the question using only the provided context. “
“If the answer isn’t in the context, say so clearly.nn”
“Context:n{context}”),
(“human”, “{question}”)
])
def reply(query: str) -> str:
“””Retrieve related chunks and generate a grounded reply.”””
# Retrieve probably the most related doc chunks for this query
retrieved_docs = retriever.invoke(query)
# Mix the retrieved chunks right into a single context block
context = “nn”.be part of(doc.page_content for doc in retrieved_docs)
# Construct and invoke the immediate with the query and retrieved context
immediate = rag_prompt.invoke({“context”: context, “query”: query})
response = llm.invoke(immediate)
return response.content material
# ── DEMO ──────────────────────────────────────────────────────────────────────
if __name__ == “__main__”:
q = “Which vector database ought to I exploit if I already run PostgreSQL?”
print(f”Q: {q}nA: {reply(q)}”)
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
87
88
89
90
91
92
93
94
95
96
97
98
99
100
# rag_pipeline.py
# Minimal RAG pipeline: ingest paperwork → embed → retailer in Chroma → retrieve and reply
# Python 3.10+ | ChromaDB 0.5+ | LangChain 0.3+
import os
from dotenv import load_dotenv
from langchain_openai import ChatOpenAI, OpenAIEmbeddings
from langchain_chroma import Chroma
from langchain_text_splitters import RecursiveCharacterTextSplitter
from langchain_core.paperwork import Doc
from langchain_core.prompts import ChatPromptTemplate
load_dotenv()
# ── STEP 1: SAMPLE DOCUMENTS ──────────────────────────────────────────────────
# Change this checklist with actual paperwork out of your data base.
# In manufacturing, load from PDFs, databases, APIs, or file techniques.
paperwork = [
Document(page_content=“Pinecone is a managed vector database optimized for fast, “
“low-latency similarity search at scale. It handles infrastructure automatically “
“and is best for production RAG when you don’t want to manage servers.”,
metadata={“source”: “vector_db_guide”, “topic”: “pinecone”}),
Document(page_content=“Weaviate is an open-source vector database with native hybrid search “
“support, combining BM25 keyword search with dense vector search in a single query. “
“It can be self-hosted or used via Weaviate Cloud.”,
metadata={“source”: “vector_db_guide”, “topic”: “weaviate”}),
Document(page_content=“Chroma is a developer-friendly, local-first vector database ideal for “
“prototyping. The 2025 Rust rewrite significantly improved performance. “
“Best for small-to-medium production workloads and local development.”,
metadata={“source”: “vector_db_guide”, “topic”: “chroma”}),
Document(page_content=“pgvector is a PostgreSQL extension that adds vector similarity search “
“to an existing Postgres database. With HNSW indexing, it handles millions of vectors “
“at low latency. Best choice if your team already runs PostgreSQL in production.”,
metadata={“source”: “vector_db_guide”, “topic”: “pgvector”}),
]
# ── STEP 2: CHUNK THE DOCUMENTS ───────────────────────────────────────────────
# Massive paperwork are break up into smaller chunks earlier than embedding.
# chunk_size=500 characters; chunk_overlap=50 preserves context throughout chunk boundaries.
splitter = RecursiveCharacterTextSplitter(chunk_size=500, chunk_overlap=50)
chunks = splitter.split_documents(paperwork)
# ── STEP 3: EMBED AND STORE IN CHROMA ────────────────────────────────────────
# OpenAIEmbeddings converts every chunk right into a high-dimensional vector.
# Chroma shops these vectors regionally within the ./chroma_db listing.
# On subsequent runs, the prevailing retailer is loaded fairly than rebuilt.
embeddings = OpenAIEmbeddings(
mannequin=“text-embedding-3-small”, # Quick and cost-effective for many RAG duties
api_key=os.getenv(“OPENAI_API_KEY”)
)
vectorstore = Chroma.from_documents(
paperwork=chunks,
embedding=embeddings,
persist_directory=“./chroma_db” # Persist to disk so you do not re-embed on each run
)
# ── STEP 4: RETRIEVAL ──────────────────────────────────────────────────────────
# Converts the question into an embedding and finds probably the most comparable chunks.
# okay=3 returns the highest 3 most related chunks.
retriever = vectorstore.as_retriever(search_kwargs={“okay”: 3})
# ── STEP 5: GENERATION ────────────────────────────────────────────────────────
llm = ChatOpenAI(
mannequin=“gpt-5.5”,
temperature=0,
api_key=os.getenv(“OPENAI_API_KEY”)
)
# The immediate tells the mannequin to make use of solely the retrieved context.
# This prevents the mannequin from hallucinating information not in your data base.
rag_prompt = ChatPromptTemplate.from_messages([
(“system”,
“Answer the question using only the provided context. “
“If the answer isn’t in the context, say so clearly.nn”
“Context:n{context}”),
(“human”, “{question}”)
])
def reply(query: str) -> str:
“”“Retrieve related chunks and generate a grounded reply.”“”
# Retrieve probably the most related doc chunks for this query
retrieved_docs = retriever.invoke(query)
# Mix the retrieved chunks right into a single context block
context = “nn”.be part of(doc.page_content for doc in retrieved_docs)
# Construct and invoke the immediate with the query and retrieved context
immediate = rag_prompt.invoke({“context”: context, “query”: query})
response = llm.invoke(immediate)
return response.content material
# ── DEMO ──────────────────────────────────────────────────────────────────────
if __name__ == “__main__”:
q = “Which vector database ought to I exploit if I already run PostgreSQL?”
print(f“Q: {q}nA: {reply(q)}”)
What this does: The pipeline has two phases. Throughout indexing, paperwork are chunked, transformed to embeddings by way of OpenAI’s text-embedding-3-small mannequin, and saved in an area Chroma database. Throughout retrieval, the question is embedded utilizing the identical mannequin, the three most comparable chunks are pulled from Chroma, and the LLM makes use of these chunks and solely these chunks to reply. The persist_directory parameter means Chroma saves the vectors to disk, so you don’t pay to re-embed your paperwork on each run.
Layer 5: Instruments and Exterior Integrations
An agent with out instruments is a really costly textual content predictor. Instruments are what give brokers the power to behave on the world fairly than simply speak about it.
In technical phrases, a software is a operate that the mannequin can select to name. You describe what the operate does in pure language, outline its enter parameters with a schema, and the mannequin decides when calling that operate would assist it reply the query. The mannequin doesn’t execute the operate; your code does. The mannequin simply decides when and with what arguments.
The classes of instruments that matter most in manufacturing brokers are: net search (for present info), code execution (for calculation and knowledge processing), file I/O (for studying and writing paperwork), API calls (for connecting to exterior providers), and browser use (for interacting with net interfaces that wouldn’t have APIs).
One improvement value understanding is the Mannequin Context Protocol (MCP), launched by Anthropic in late 2024. MCP is a standardized manner for fashions to speak with exterior instruments and knowledge sources. Quite than each crew writing customized integration code for each software, MCP gives a shared protocol. Amazon Bedrock Brokers added native MCP help in 2025, and adoption throughout the ecosystem is rising quick.
The one most vital factor about software design is the schema. The mannequin decides whether or not to make use of a software primarily based on its description and decides what arguments to cross primarily based on the parameter schema. A obscure description produces flawed software calls. A well-typed schema with clear parameter descriptions produces dependable ones.
Stipulations:
pip set up langchain langchain-openai langchain-community python-dotenv
pip set up langchain langchain–openai langchain–group python–dotenv
Find out how to run: Save as instruments.py, add OPENAI_API_KEY to your .env, then run python instruments.py
# instruments.py
# Defining, registering, and utilizing instruments with a LangChain agent
# Python 3.10+ | LangChain 0.3+
import os
import json
import requests
from dotenv import load_dotenv
from langchain_openai import ChatOpenAI
from langchain.instruments import software
from langchain_community.instruments import DuckDuckGoSearchRun
from langchain_core.messages import HumanMessage
from langgraph.prebuilt import create_react_agent
load_dotenv()
llm = ChatOpenAI(mannequin=”gpt-5.5″, temperature=0, api_key=os.getenv(“OPENAI_API_KEY”))
# ── TOOL 1: WEB SEARCH ────────────────────────────────────────────────────────
# Constructed-in DuckDuckGo software — no API key wanted.
search = DuckDuckGoSearchRun()
# ── TOOL 2: WEATHER LOOKUP ────────────────────────────────────────────────────
# The @software decorator does three issues:
# 1. Registers the operate as a callable software
# 2. Makes use of the operate identify because the software identify
# 3. Makes use of the docstring because the software description (that is what the mannequin reads)
# The outline is important — obscure descriptions trigger flawed software calls.
@software
def get_weather(metropolis: str) -> str:
“””
Fetch the present climate for a given metropolis.
Use this when the person asks about climate situations, temperature, or forecasts.
Enter: metropolis identify as a string (e.g., ‘London’, ‘Tokyo’, ‘New York’).
“””
attempt:
# Utilizing open-meteo (free, no API key) for geocoding and climate
geo_url = f”https://geocoding-api.open-meteo.com/v1/search?identify={metropolis}&rely=1″
geo = requests.get(geo_url, timeout=5).json()
if not geo.get(“outcomes”):
return f”Couldn’t discover location knowledge for ‘{metropolis}’.”
lat = geo[“results”][0][“latitude”]
lon = geo[“results”][0][“longitude”]
weather_url = (
f”https://api.open-meteo.com/v1/forecast”
f”?latitude={lat}&longitude={lon}”
f”¤t_weather=true”
)
climate = requests.get(weather_url, timeout=5).json()
present = climate.get(“current_weather”, {})
return (
f”Climate in {metropolis}: “
f”{present.get(‘temperature’, ‘N/A’)}°C, “
f”wind pace {present.get(‘windspeed’, ‘N/A’)} km/h.”
)
besides Exception as e:
# At all times return a string from instruments, even on failure.
# Elevating exceptions from instruments can crash the agent loop.
return f”Climate lookup failed for ‘{metropolis}’: {str(e)}”
# ── TOOL 3: JSON CALCULATOR ───────────────────────────────────────────────────
@software
def calculate(expression: str) -> str:
“””
Consider a mathematical expression and return the consequence.
Use this for arithmetic, proportion calculations, or any numerical computation.
Enter: a sound Python mathematical expression as a string (e.g., ‘(150 * 1.08) / 12’).
Do NOT use for advanced code execution — solely simple arithmetic expressions.
“””
attempt:
# eval is scoped to solely permit math — no builtins, no imports
consequence = eval(expression, {“__builtins__”: {}}, {})
return f”Consequence: {consequence}”
besides Exception as e:
return f”Calculation error: {str(e)}”
# ── REGISTER TOOLS AND BUILD AGENT ────────────────────────────────────────────
instruments = [search, get_weather, calculate]
agent = create_react_agent(llm, instruments)
# ── DEMO ──────────────────────────────────────────────────────────────────────
if __name__ == “__main__”:
queries = [
“What is the weather in Lagos right now?”,
“If I earn $85,000 a year, what is my monthly gross salary?”,
“Who won the most recent FIFA World Cup?”
]
for question in queries:
print(f”nQuery: {question}”)
consequence = agent.invoke({“messages”: [HumanMessage(content=query)]})
print(f”Reply: {consequence[‘messages’][-1].content material}”)
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
87
88
89
90
91
92
93
94
95
96
97
98
# instruments.py
# Defining, registering, and utilizing instruments with a LangChain agent
# Python 3.10+ | LangChain 0.3+
import os
import json
import requests
from dotenv import load_dotenv
from langchain_openai import ChatOpenAI
from langchain.instruments import software
from langchain_community.instruments import DuckDuckGoSearchRun
from langchain_core.messages import HumanMessage
from langgraph.prebuilt import create_react_agent
load_dotenv()
llm = ChatOpenAI(mannequin=“gpt-5.5”, temperature=0, api_key=os.getenv(“OPENAI_API_KEY”))
# ── TOOL 1: WEB SEARCH ────────────────────────────────────────────────────────
# Constructed-in DuckDuckGo software — no API key wanted.
search = DuckDuckGoSearchRun()
# ── TOOL 2: WEATHER LOOKUP ────────────────────────────────────────────────────
# The @software decorator does three issues:
# 1. Registers the operate as a callable software
# 2. Makes use of the operate identify because the software identify
# 3. Makes use of the docstring because the software description (that is what the mannequin reads)
# The outline is important — obscure descriptions trigger flawed software calls.
@software
def get_weather(metropolis: str) -> str:
“”“
Fetch the present climate for a given metropolis.
Use this when the person asks about climate situations, temperature, or forecasts.
Enter: metropolis identify as a string (e.g., ‘London’, ‘Tokyo’, ‘New York’).
““”
attempt:
# Utilizing open-meteo (free, no API key) for geocoding and climate
geo_url = f“https://geocoding-api.open-meteo.com/v1/search?identify={metropolis}&rely=1”
geo = requests.get(geo_url, timeout=5).json()
if not geo.get(“outcomes”):
return f“Couldn’t discover location knowledge for ‘{metropolis}’.”
lat = geo[“results”][0][“latitude”]
lon = geo[“results”][0][“longitude”]
weather_url = (
f“https://api.open-meteo.com/v1/forecast”
f“?latitude={lat}&longitude={lon}”
f“¤t_weather=true”
)
climate = requests.get(weather_url, timeout=5).json()
present = climate.get(“current_weather”, {})
return (
f“Climate in {metropolis}: “
f“{present.get(‘temperature’, ‘N/A’)}°C, “
f“wind pace {present.get(‘windspeed’, ‘N/A’)} km/h.”
)
besides Exception as e:
# At all times return a string from instruments, even on failure.
# Elevating exceptions from instruments can crash the agent loop.
return f“Climate lookup failed for ‘{metropolis}’: {str(e)}”
# ── TOOL 3: JSON CALCULATOR ───────────────────────────────────────────────────
@software
def calculate(expression: str) -> str:
“”“
Consider a mathematical expression and return the consequence.
Use this for arithmetic, proportion calculations, or any numerical computation.
Enter: a sound Python mathematical expression as a string (e.g., ‘(150 * 1.08) / 12’).
Do NOT use for advanced code execution — solely simple arithmetic expressions.
““”
attempt:
# eval is scoped to solely permit math — no builtins, no imports
consequence = eval(expression, {“__builtins__”: {}}, {})
return f“Consequence: {consequence}”
besides Exception as e:
return f“Calculation error: {str(e)}”
# ── REGISTER TOOLS AND BUILD AGENT ────────────────────────────────────────────
instruments = [search, get_weather, calculate]
agent = create_react_agent(llm, instruments)
# ── DEMO ──────────────────────────────────────────────────────────────────────
if __name__ == “__main__”:
queries = [
“What is the weather in Lagos right now?”,
“If I earn $85,000 a year, what is my monthly gross salary?”,
“Who won the most recent FIFA World Cup?”
]
for question in queries:
print(f“nQuery: {question}”)
consequence = agent.invoke({“messages”: [HumanMessage(content=query)]})
print(f“Reply: {consequence[‘messages’][-1].content material}”)
What this does: Three instruments are registered: an online search software for present occasions, a climate software that calls a free API with no key required, and a calculator that safely evaluates mathematical expressions. The agent receives every question, causes about which software to make use of, calls it, and synthesizes a solution from the consequence. The important thing design element to note is within the docstrings; every software description is exact about what the software does, when to make use of it, and what format the enter ought to take.
Layer 6: Observability and Analysis
Here’s a manufacturing reality that doesn’t get stated sufficient: LLMs fail silently. Because the crew at Kanerika put it, a hallucinated reply nonetheless returns HTTP 200. A regular infrastructure monitoring software sees a profitable request. You see nothing uncommon. In the meantime, your agent has been confidently giving flawed solutions for 3 days.
Conventional monitoring was constructed for a world the place “appropriate” is binary: the operate returned the precise sort, the API returned 200, the question accomplished in beneath 100ms. LLM correctness is semantic. The response may be structurally legitimate, grammatically fluent, and utterly flawed. That requires a unique observability layer totally.
There are three issues a very good LLM observability setup tracks. Tracing follows each step of the agent’s execution: the LLM calls, the software invocations, the retrieval queries, the intermediate reasoning steps, and the way lengthy every one took. Analysis scores the output in opposition to metrics that matter: faithfulness (did it keep grounded within the retrieved context?), relevance (did it reply the query requested?), and hallucination price. Monitoring tracks behavioral drift over time, whether or not the agent’s efficiency on a given class of inputs is getting higher or worse because the mannequin and prompts evolve.
The main platforms every have a unique power. LangSmith gives the deepest integration with LangChain and LangGraph. If you’re already in that ecosystem, it’s the quickest path to working traces. Langfuse is open-source with over 19,000 GitHub stars and an MIT license, self-hostable, and works with any framework. Arize Phoenix brings ML-grade analysis rigor and ships with over 50 research-backed metrics overlaying faithfulness, relevance, security, and hallucination detection.
In accordance with MLflow’s evaluation of observability platforms, the precise selection typically comes right down to your framework: LangChain groups get probably the most from LangSmith, whereas groups on LlamaIndex or uncooked API calls are higher served by Phoenix or Langfuse.
Right here is add Langfuse tracing to an current agent with minimal modifications.
Stipulations:
pip set up langfuse langchain langchain-openai python-dotenv
pip set up langfuse langchain langchain–openai python–dotenv
Join at langfuse.com for a free account and add LANGFUSE_PUBLIC_KEY and LANGFUSE_SECRET_KEY to your .env. Self-hosting can be accessible in the event you desire to maintain knowledge by yourself infrastructure.
Find out how to run: Save as observability.py and run python observability.py. Open your Langfuse dashboard to see the hint.
# observability.py
# Including Langfuse tracing to a LangChain agent
# Langfuse captures each LLM name, software invocation, and token rely routinely.
import os
from dotenv import load_dotenv
from langchain_openai import ChatOpenAI
from langchain_community.instruments import DuckDuckGoSearchRun
from langchain_core.messages import HumanMessage
from langgraph.prebuilt import create_react_agent
# Langfuse integrates by way of the CallbackHandler sample.
# It intercepts each LangChain occasion and sends it to your Langfuse dashboard.
from langfuse.langchain import CallbackHandler
load_dotenv()
# ── LANGFUSE SETUP ─────────────────────────────────────────────────────────────
# CallbackHandler reads LANGFUSE_PUBLIC_KEY and LANGFUSE_SECRET_KEY from the atmosphere.
# session_id teams all associated traces into one session — helpful for debugging conversations.
# user_id ties traces to a selected person for per-user efficiency evaluation.
langfuse_handler = CallbackHandler(
session_id=”demo_session_001″,
user_id=”demo_user”
)
# ── AGENT SETUP ────────────────────────────────────────────────────────────────
llm = ChatOpenAI(
mannequin=”gpt-5.5″,
temperature=0,
api_key=os.getenv(“OPENAI_API_KEY”),
callbacks=[langfuse_handler] # Connect the handler right here — that is the one change
)
instruments = [DuckDuckGoSearchRun()]
agent = create_react_agent(llm, instruments)
# ── RUN WITH TRACING ──────────────────────────────────────────────────────────
# Move the handler in config so it traces software calls in addition to LLM calls.
# With out this, solely the LLM calls are traced — software invocations are invisible.
consequence = agent.invoke(
{“messages”: [HumanMessage(content=”What is the latest version of Python?”)]},
config={“callbacks”: [langfuse_handler]}
)
print(consequence[“messages”][-1].content material)
# Flush ensures all traces are despatched to Langfuse earlier than the script exits.
# In a long-running server, that is dealt with routinely.
langfuse_handler.flush()
print(“nTrace despatched to Langfuse. Verify your dashboard at https://cloud.langfuse.com”)
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
# observability.py
# Including Langfuse tracing to a LangChain agent
# Langfuse captures each LLM name, software invocation, and token rely routinely.
import os
from dotenv import load_dotenv
from langchain_openai import ChatOpenAI
from langchain_community.instruments import DuckDuckGoSearchRun
from langchain_core.messages import HumanMessage
from langgraph.prebuilt import create_react_agent
# Langfuse integrates by way of the CallbackHandler sample.
# It intercepts each LangChain occasion and sends it to your Langfuse dashboard.
from langfuse.langchain import CallbackHandler
load_dotenv()
# ── LANGFUSE SETUP ─────────────────────────────────────────────────────────────
# CallbackHandler reads LANGFUSE_PUBLIC_KEY and LANGFUSE_SECRET_KEY from the atmosphere.
# session_id teams all associated traces into one session — helpful for debugging conversations.
# user_id ties traces to a selected person for per-user efficiency evaluation.
langfuse_handler = CallbackHandler(
session_id=“demo_session_001”,
user_id=“demo_user”
)
# ── AGENT SETUP ────────────────────────────────────────────────────────────────
llm = ChatOpenAI(
mannequin=“gpt-5.5”,
temperature=0,
api_key=os.getenv(“OPENAI_API_KEY”),
callbacks=[langfuse_handler] # Connect the handler right here — that is the one change
)
instruments = [DuckDuckGoSearchRun()]
agent = create_react_agent(llm, instruments)
# ── RUN WITH TRACING ──────────────────────────────────────────────────────────
# Move the handler in config so it traces software calls in addition to LLM calls.
# With out this, solely the LLM calls are traced — software invocations are invisible.
consequence = agent.invoke(
{“messages”: [HumanMessage(content=“What is the latest version of Python?”)]},
config={“callbacks”: [langfuse_handler]}
)
print(consequence[“messages”][–1].content material)
# Flush ensures all traces are despatched to Langfuse earlier than the script exits.
# In a long-running server, that is dealt with routinely.
langfuse_handler.flush()
print(“nTrace despatched to Langfuse. Verify your dashboard at https://cloud.langfuse.com”)
What this does: Two modifications from a typical agent setup: the CallbackHandler is initialized with a session and person ID, and it’s connected to each the LLM and the agent.invoke config. That’s sufficient for Langfuse to seize the complete hint of each LLM name, each software invocation, token counts, latency, and the entire enter/output at every step. Every thing you must debug a manufacturing failure or observe high quality drift over time.
Layer 7: Deployment Infrastructure
You possibly can have a flawless agent in improvement that turns right into a upkeep drawback in manufacturing. The infrastructure layer is the place that hole lives.
At a minimal, your agent must be containerized with Docker. Containers offer you constant habits throughout environments, simple dependency administration, and a clear path to any cloud deployment goal. The choice — transport Python scripts with a necessities.txt and hoping the atmosphere matches — creates a category of bugs that wastes engineering time disproportionate to the hassle containerization would have taken.
For many manufacturing brokers, you’ve two architectural choices for the serving layer: a synchronous API or an async queue. A synchronous API (Flask or FastAPI) works when your agent completes in beneath a number of seconds, and you may afford to carry the HTTP connection open.
When your agent entails a number of software calls, lengthy retrieval pipelines, or doc processing that may take 30 to 60 seconds, an async queue (Celery, AWS SQS, or Google Pub/Sub) is the higher selection. The consumer submits a job, will get a process ID again instantly, and polls for the consequence.
On the cloud aspect, all three main platforms now have managed agent infrastructure. Amazon’s AgentCore, which grew to become usually accessible in October 2025, gives devoted agentic infrastructure on AWS for reminiscence administration, software execution, and session dealing with with out provisioning servers. Google Vertex AI Agent Builder is the pure selection for groups already within the GCP ecosystem, with native Gemini integration and built-in observability. Azure OpenAI Service with Semantic Kernel is the enterprise default for Microsoft retailers.
For value administration, three practices make the most important distinction: caching (returning saved responses for repeated equivalent queries fairly than calling the mannequin once more), request batching (grouping non-urgent duties to cut back per-call overhead), and setting max_iterations in your agent executor to forestall runaway loops from consuming tokens with out certain.
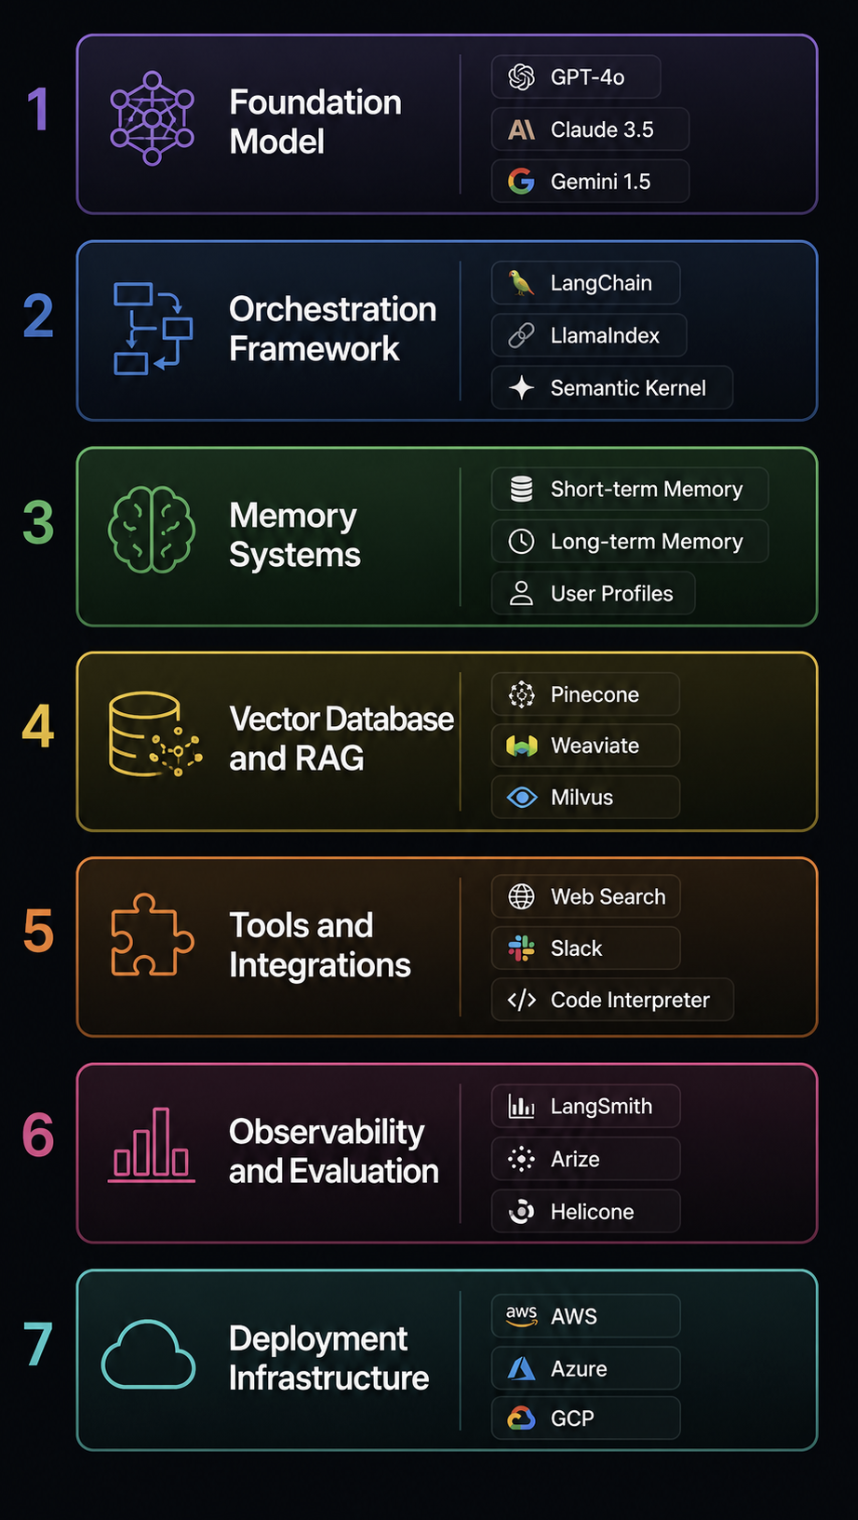
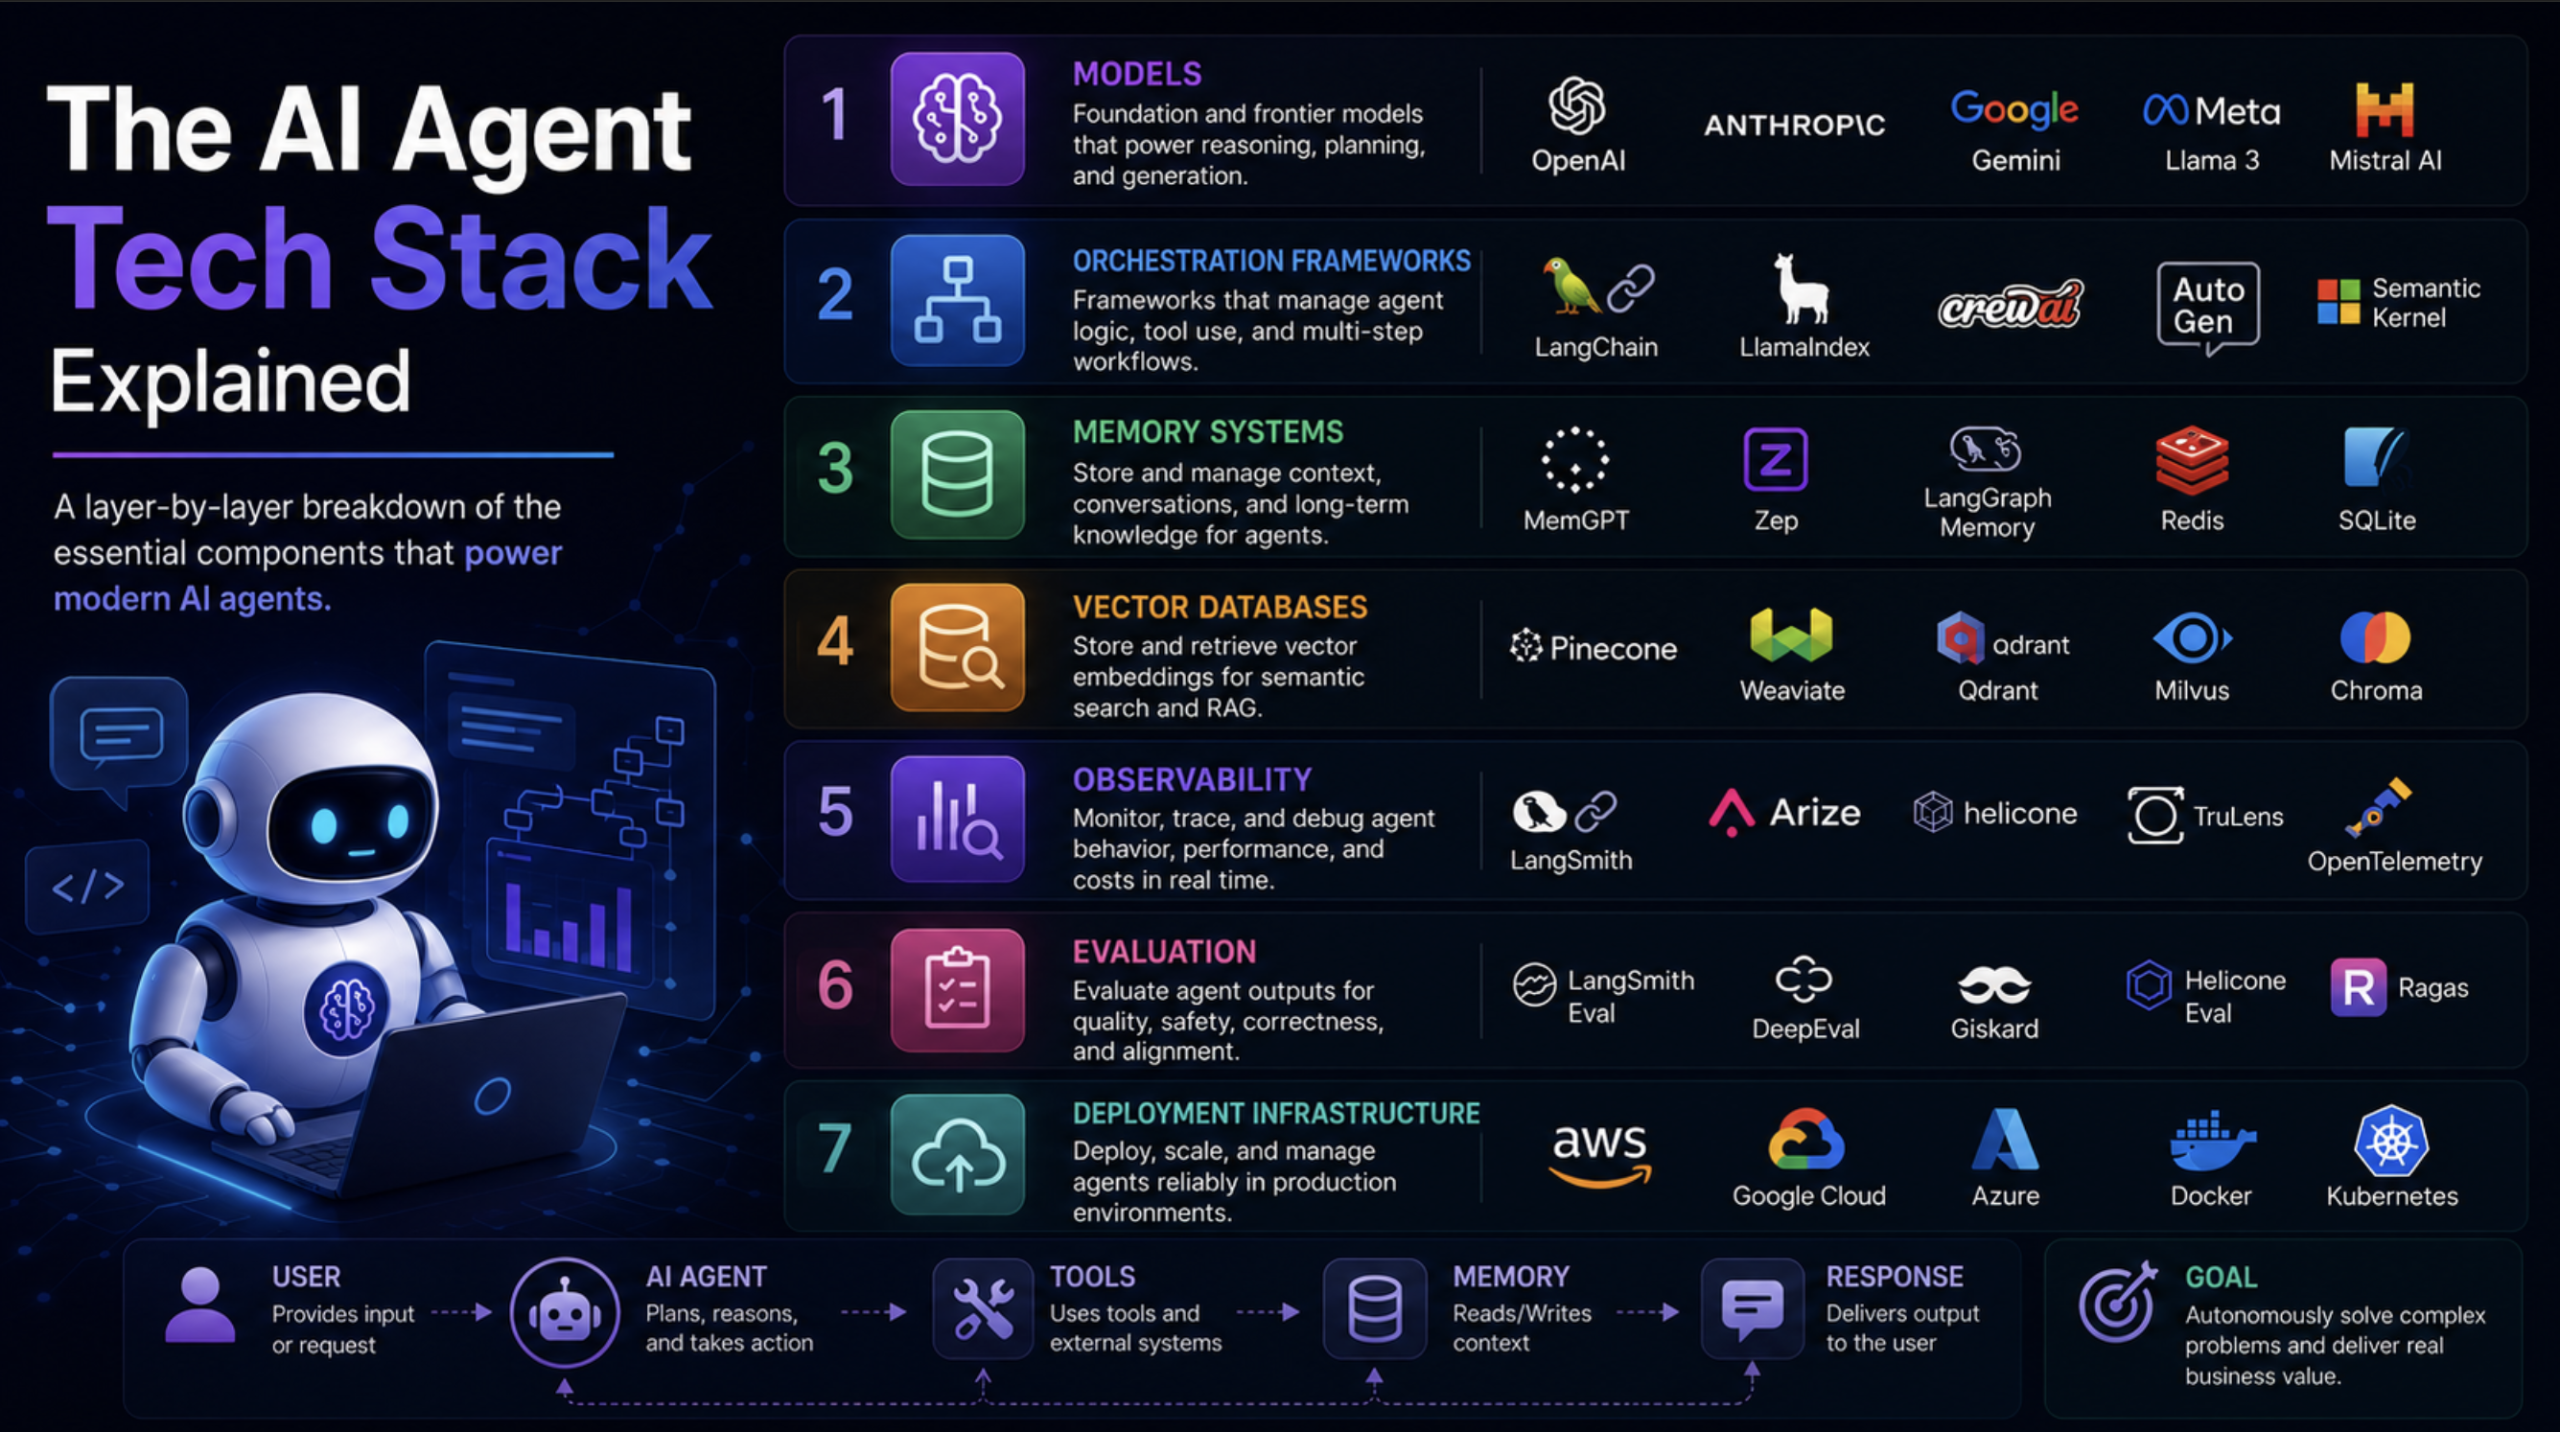
A vertical stack diagram displaying all 7 layers labeled prime to backside: Basis Mannequin, Orchestration Framework, Reminiscence Methods, Vector Database and RAG, Instruments and Integrations, Observability and Analysis, Deployment Infrastructure (click on to enlarge)
Placing It All Collectively
The precise selections at every layer rely on the place you might be within the undertaking lifecycle. Here’s a sensible reference that displays the analysis and trade-offs mentioned above.
Prototype (transfer quick, minimal infrastructure):
Layer
Selection
Motive
Basis Mannequin
GPT-5.5
Dependable tool-calling, mature ecosystem
Orchestration
LangGraph
Quick setup, good documentation
Reminiscence
In-context solely
No infrastructure wanted
Vector DB
Chroma
Native, no ops, good developer expertise
Instruments
DuckDuckGo + customized @software features
Zero API keys required
Observability
Langfuse (cloud free tier)
One-line setup
Deployment
Native / Docker
Ship quick
Manufacturing Startup (scale with management):
Layer
Selection
Motive
Basis Mannequin
GPT-5.5 + Claude Sonnet 4.6 fallback
Reliability with redundancy
Orchestration
LangGraph or CrewAI
State administration and multi-agent help
Reminiscence
Episodic (Postgres) + Semantic (RAG)
Full persistent context
Vector DB
Weaviate or Pinecone
Scale and hybrid search
Instruments
Full software suite with MCP
Standardized integrations
Observability
Langfuse self-hosted or Arize Phoenix
Information management + ML-grade evals
Deployment
Docker + Kubernetes + async queue
Manufacturing-grade, cost-controlled
Enterprise:
Layer
Selection
Motive
Basis Mannequin
Azure OpenAI or AWS Bedrock
Compliance, knowledge residency, SLA
Orchestration
Semantic Kernel or LangGraph
Enterprise language help, governance
Reminiscence
Managed reminiscence with audit path
Regulatory necessities
Vector DB
Weaviate or pgvector
Self-hostable, compliance-ready
Instruments
MCP-based, internally permitted
Safety evaluate and entry management
Observability
Langfuse self-hosted or Datadog LLM module
Present infrastructure integration
Deployment
AWS AgentCore / Vertex AI Agent Builder
Absolutely managed, ruled, auditable
Conclusion
The inspiration mannequin is the a part of this stack that will get written about. The opposite six layers are the components that decide whether or not what you constructed truly works in manufacturing.
An agent fails on the orchestration layer when the ReAct loop will get caught. It fails on the reminiscence layer when it forgets the context it wants. It fails on the retrieval layer when the flawed chunks are returned, and the mannequin hallucinates a grounded-sounding reply. It fails on the instruments layer when a schema is simply too obscure, and the mannequin calls the flawed operate. It fails on the observability layer when you don’t have any solution to know that any of that is taking place. And it fails on the deployment layer when the infrastructure can not deal with the latency or value necessities of actual site visitors.
Gartner estimates that over 40% of agentic AI initiatives are prone to cancellation by 2027 attributable to unclear worth, rising prices, and weak governance. Most of these failures will hint again to not a foul mannequin selection however to a stack that was constructed layer by layer with no clear image of how the layers join.
Understanding the complete stack doesn’t imply it’s a must to construct all of it. It means what choices you make and what you might be buying and selling off once you make them. That’s the distinction between an agent that works in a demo and one which ships.