


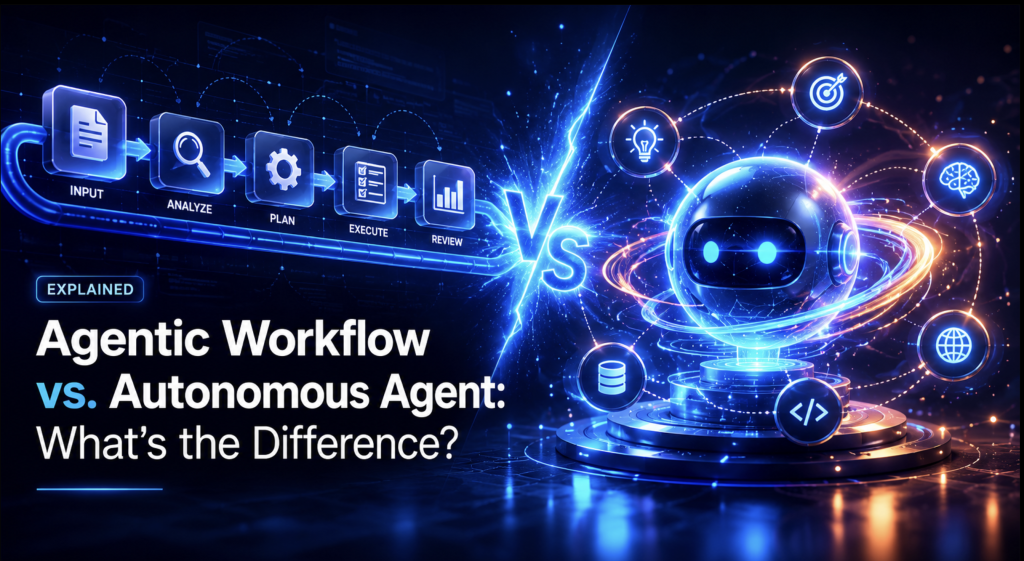
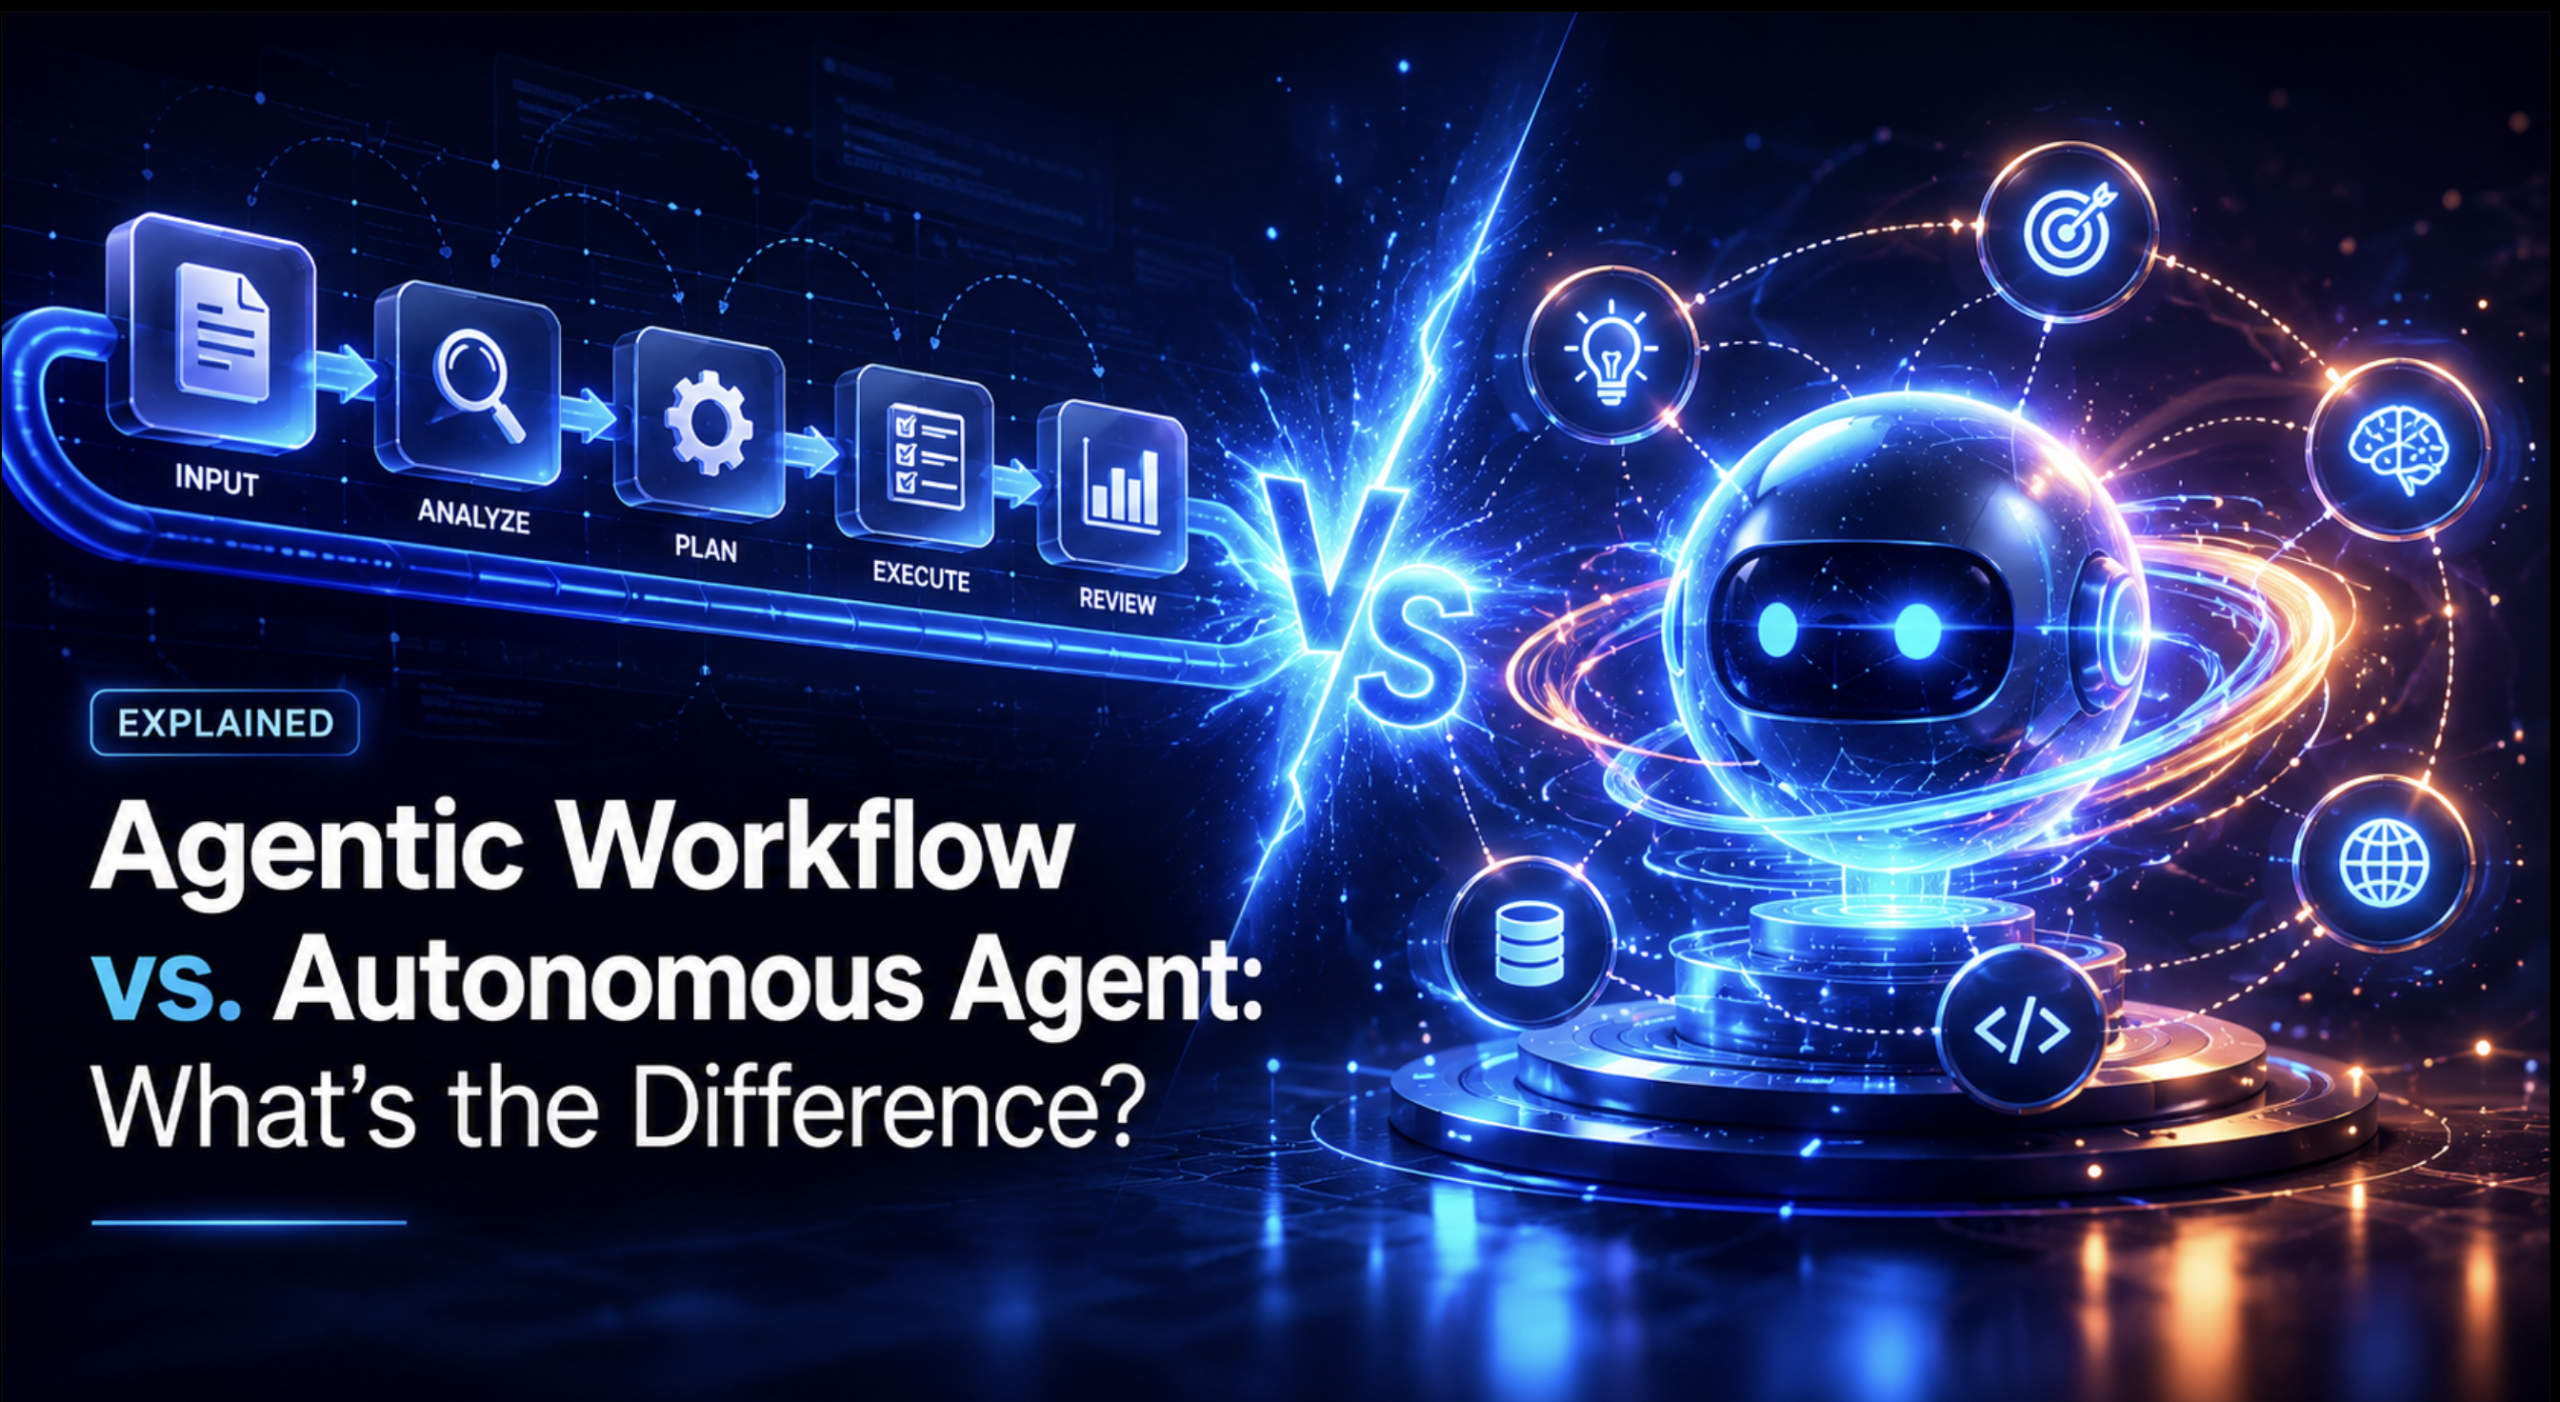
On this article, you’ll discover ways to distinguish agentic workflows from autonomous brokers by specializing in who owns management circulation — a human writing code upfront, or a mannequin reasoning at runtime.
Matters we are going to cowl embody:
Why the actual axis separating these techniques is predictability versus autonomy, not whether or not an LLM is concerned.
How deterministic workflows, orchestrated workflows, reactive brokers, and autonomous multi-agent techniques differ, with runnable code that makes the control-flow distinction concrete.
Why workflows, not totally autonomous brokers, dominate manufacturing right now, and why hybrid architectures are the sample that holds up.
Introduction
Deloitte initiatives that by 2027, as much as 50% of firms utilizing generative AI can have launched agentic AI pilots or proofs of idea. That’s a wave of adoption large enough that the phrase “agentic” has began protecting virtually something with an LLM name in it, from a set five-step pipeline the place step three occurs to name GPT for a abstract to a totally self-directing system that plans its personal path with no script in any respect.
These aren’t the identical factor. Treating them as interchangeable results in one among two errors: over-engineering a easy, well-understood process with pointless autonomy, or under-engineering a genuinely open-ended drawback by forcing it right into a inflexible pipeline that breaks the second actuality deviates from the plan.
Anthropic attracts the foundational line of their broadly cited “Constructing Efficient Brokers” piece: workflows are techniques the place LLMs and instruments are orchestrated by way of predefined code paths. Brokers are techniques the place LLMs dynamically direct their very own course of and gear utilization, sustaining management over how they accomplish a process. Every little thing on this article is detailed beneath that one distinction.
This piece maps the complete spectrum of deterministic workflows, orchestrated techniques, reactive single brokers, and autonomous multi-agent techniques, with code at every stage that makes the control-flow distinction concrete fairly than summary. The code right here illustrates structure, not a deployable system; the purpose of every snippet is to indicate who decides what occurs subsequent, to not ship a characteristic.
The Actual Axis Isn’t “AI vs. No AI”: It’s Predictability vs. Autonomy
Earlier than evaluating architectures, it’s price changing the mistaken query. The query isn’t “does this technique use an LLM.” Virtually all the things does now. The 2 questions that really matter, borrowing a framing that’s gained actual traction in structure circles, are: does this course of should be repeatable, auditable, and explainable step-by-step? And: is the proper path even recognized upfront, or does the system want to find it at runtime?
A system can lean closely on an LLM and nonetheless be totally deterministic in construction — a set pipeline the place one step occurs to name a mannequin for textual content technology, however the subsequent step is hardcoded no matter what comes again. A system can be “agentic” with little or no actual autonomy: a tightly scripted loop with solely two allowed actions and a tough step restrict. The presence of an LLM name will not be the sign. Possession of management circulation is.
Google Cloud’s personal design-pattern documentation attracts this precise line operationally: deterministic workflows embody duties with a clearly outlined path recognized upfront, the place the steps don’t change a lot from one run to the subsequent. Workflows that require dynamic orchestration contain issues the place the agent should decide one of the simplest ways to proceed, with no predefined script. That’s the spectrum this text walks by way of, one stage at a time.
Deterministic Workflows
That is the baseline. A deterministic workflow has a recognized sequence of steps determined at design time, by a human, in code. An LLM can sit inside any step — producing textual content, classifying enter, drafting a abstract — nevertheless it doesn’t select what occurs after its personal step runs. The orchestrating code does that, no matter what the mannequin returns.
# deterministic_pipeline.py
# Stipulations: none past Python’s commonplace library
# Run: python deterministic_pipeline.py
def mock_llm_classify(textual content: str) -> str:
“””
Mock LLM name — stands in for an actual API name to maintain this instance
runnable with out an API key. The purpose is structural: no matter this
returns, the NEXT operate that runs is already determined under.
“””
if “refund” in textual content.decrease() or “cost” in textual content.decrease():
return “billing”
return “common”
def extract(raw_input: str) -> str:
“””Step 1 — all the time runs, all the time results in step 2. No branching right here.”””
return raw_input.strip()
def classify(cleaned_text: str) -> str:
“””
Step 2 — calls an LLM to provide a label, however the label has no impact
on which operate runs subsequent. That is the deterministic half: the mannequin
fills in a chunk of information, it would not affect the route.
“””
label = mock_llm_classify(cleaned_text)
print(f” [classify] LLM returned label=”{label}” (informational solely)”)
return cleaned_text
def summarize(cleaned_text: str) -> str:
“””Step 3 — all the time runs after step 2, whatever the label from step 2.”””
return f”Abstract: {cleaned_text[:40]}…”
def notify(abstract: str) -> str:
“””Step 4 — all the time runs final. The trail is mounted at design time.”””
return f”Notification despatched: {abstract}”
def run_deterministic_pipeline(raw_input: str) -> str:
“””
The management circulation right here is written solely by a human, upfront.
Each run takes the an identical path: extract -> classify -> summarize -> notify.
The LLM name inside classify() produces a label, however that label is rarely
used to resolve what operate runs subsequent — it is information flowing by way of a set pipe.
“””
step1 = extract(raw_input)
step2 = classify(step1)
step3 = summarize(step2)
step4 = notify(step3)
return step4
if __name__ == “__main__”:
# Two inputs that the LLM would classify utterly in another way
result_1 = run_deterministic_pipeline(“I desire a refund for my final cost”)
result_2 = run_deterministic_pipeline(“What are your corporation hours?”)
print(f”nResult 1: {result_1}”)
print(f”End result 2: {result_2}”)
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
# deterministic_pipeline.py
# Stipulations: none past Python’s commonplace library
# Run: python deterministic_pipeline.py
def mock_llm_classify(textual content: str) -> str:
“”“
Mock LLM name — stands in for an actual API name to maintain this instance
runnable with out an API key. The purpose is structural: no matter this
returns, the NEXT operate that runs is already determined under.
““”
if “refund” in textual content.decrease() or “cost” in textual content.decrease():
return “billing”
return “common”
def extract(raw_input: str) -> str:
“”“Step 1 — all the time runs, all the time results in step 2. No branching right here.”“”
return raw_input.strip()
def classify(cleaned_text: str) -> str:
“”“
Step 2 — calls an LLM to provide a label, however the label has no impact
on which operate runs subsequent. That is the deterministic half: the mannequin
fills in a chunk of information, it would not affect the route.
““”
label = mock_llm_classify(cleaned_text)
print(f” [classify] LLM returned label=”{label}” (informational solely)”)
return cleaned_text
def summarize(cleaned_text: str) -> str:
“”“Step 3 — all the time runs after step 2, whatever the label from step 2.”“”
return f“Abstract: {cleaned_text[:40]}…”
def notify(abstract: str) -> str:
“”“Step 4 — all the time runs final. The trail is mounted at design time.”“”
return f“Notification despatched: {abstract}”
def run_deterministic_pipeline(raw_input: str) -> str:
“”“
The management circulation right here is written solely by a human, upfront.
Each run takes the an identical path: extract -> classify -> summarize -> notify.
The LLM name inside classify() produces a label, however that label is rarely
used to resolve what operate runs subsequent — it is information flowing by way of a set pipe.
““”
step1 = extract(raw_input)
step2 = classify(step1)
step3 = summarize(step2)
step4 = notify(step3)
return step4
if __name__ == “__main__”:
# Two inputs that the LLM would classify utterly in another way
result_1 = run_deterministic_pipeline(“I desire a refund for my final cost”)
result_2 = run_deterministic_pipeline(“What are your corporation hours?”)
print(f“nResult 1: {result_1}”)
print(f“End result 2: {result_2}”)
Easy methods to run: python deterministic_pipeline.py, no dependencies required.
Output:
[classify] LLM returned label=”billing” (informational solely)
[classify] LLM returned label=”common” (informational solely)
End result 1: Notification despatched: Abstract: I desire a refund for my final cost…
End result 2: Notification despatched: Abstract: What are your corporation hours?…
[classify] LLM returned label=‘billing’ (informational solely)
[classify] LLM returned label=‘common’ (informational solely)
End result 1: Notification despatched: Abstract: I need a refund for my final cost...
End result 2: Notification despatched: Abstract: What are your enterprise hours?...
Discover what occurred: the mock LLM categorized the 2 inputs utterly in another way, billing versus common, and it made zero distinction to the trail both enter took. Each went by way of the very same 4 capabilities in the identical order. That’s all the definition of deterministic: the route is mounted, even when an LLM is doing actual work inside one of many steps.
Orchestrated Workflows
That is the center floor that will get mislabeled most frequently as “agentic,” and it’s price slowing down right here as a result of it’s the road most individuals truly cross once they begin utilizing that phrase loosely.
An orchestrated workflow nonetheless has a graph of potential paths outlined solely upfront, however which path will get taken now depends upon a runtime choice, steadily made by an LLM name. That is nonetheless a workflow. Each department that could possibly be taken was anticipated and written into code by a human earlier than the system ever ran. The LLM picks a department off a menu another person wrote. It doesn’t invent a brand new merchandise on that menu.
That is exactly the “dynamic orchestration” class Google Cloud separates from real brokers — the system must plan and route, however inside a construction {that a} human nonetheless totally designed.
# orchestrated_pipeline.py
# Stipulations: none past Python’s commonplace library
# Run: python orchestrated_pipeline.py
def mock_llm_classify(textual content: str) -> str:
“””Mock LLM classification name.”””
text_lower = textual content.decrease()
if “refund” in text_lower or “cost” in text_lower:
return “billing”
if “crash” in text_lower or “error” in text_lower or “bug” in text_lower:
return “technical”
return “common”
def extract(raw_input: str) -> str:
return raw_input.strip()
# Three pre-defined downstream handlers. A human wrote all three of those
# upfront. The LLM doesn’t invent a fourth path — it might solely choose
# amongst branches that exist already on this code.
def handle_billing(textual content: str) -> str:
return f”[BILLING TEAM] Routed: {textual content[:50]}”
def handle_technical(textual content: str) -> str:
return f”[TECH SUPPORT] Routed: {textual content[:50]}”
def handle_general(textual content: str) -> str:
return f”[GENERAL QUEUE] Routed: {textual content[:50]}”
# The department map IS all the choice house. Each key right here was written
# by a human forward of time. The LLM’s job is to select a key — not outline one.
ROUTE_MAP = {
“billing”: handle_billing,
“technical”: handle_technical,
“common”: handle_general,
}
def run_orchestrated_pipeline(raw_input: str) -> str:
“””
Nonetheless a workflow, not an agent: each potential path was anticipated
and coded by a human forward of time, sitting in ROUTE_MAP. The LLM name
decides WHICH pre-built department executes for this particular enter, however
it can not invent a department that is not already a key in ROUTE_MAP.
“””
cleaned = extract(raw_input)
label = mock_llm_classify(cleaned)
print(f” [route] LLM categorized as ‘{label}’ -> dispatching to handle_{label}()”)
handler = ROUTE_MAP.get(label, handle_general)
return handler(cleaned)
if __name__ == “__main__”:
test_inputs = [
“I was charged twice for my refund request”,
“The app keeps crashing with an error on startup”,
“What are your business hours?”,
]
for inp in test_inputs:
outcome = run_orchestrated_pipeline(inp)
print(f” End result: {outcome}n”)
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
# orchestrated_pipeline.py
# Stipulations: none past Python’s commonplace library
# Run: python orchestrated_pipeline.py
def mock_llm_classify(textual content: str) -> str:
“”“Mock LLM classification name.”“”
text_lower = textual content.decrease()
if “refund” in text_lower or “cost” in text_lower:
return “billing”
if “crash” in text_lower or “error” in text_lower or “bug” in text_lower:
return “technical”
return “common”
def extract(raw_input: str) -> str:
return raw_input.strip()
# Three pre-defined downstream handlers. A human wrote all three of those
# upfront. The LLM doesn’t invent a fourth path — it might solely choose
# amongst branches that exist already on this code.
def handle_billing(textual content: str) -> str:
return f“[BILLING TEAM] Routed: {textual content[:50]}”
def handle_technical(textual content: str) -> str:
return f“[TECH SUPPORT] Routed: {textual content[:50]}”
def handle_general(textual content: str) -> str:
return f“[GENERAL QUEUE] Routed: {textual content[:50]}”
# The department map IS all the choice house. Each key right here was written
# by a human forward of time. The LLM’s job is to select a key — not outline one.
ROUTE_MAP = {
“billing”: handle_billing,
“technical”: handle_technical,
“common”: handle_general,
}
def run_orchestrated_pipeline(raw_input: str) -> str:
“”“
Nonetheless a workflow, not an agent: each potential path was anticipated
and coded by a human forward of time, sitting in ROUTE_MAP. The LLM name
decides WHICH pre-built department executes for this particular enter, however
it can not invent a department that is not already a key in ROUTE_MAP.
““”
cleaned = extract(raw_input)
label = mock_llm_classify(cleaned)
print(f” [route] LLM categorized as ‘{label}’ -> dispatching to handle_{label}()”)
handler = ROUTE_MAP.get(label, handle_general)
return handler(cleaned)
if __name__ == “__main__”:
test_inputs = [
“I was charged twice for my refund request”,
“The app keeps crashing with an error on startup”,
“What are your business hours?”,
]
for inp in test_inputs:
outcome = run_orchestrated_pipeline(inp)
print(f” End result: {outcome}n”)
Easy methods to run: python orchestrated_pipeline.py, no dependencies required.
Output:
[route] LLM categorized as ‘billing’ -> dispatching to handle_billing()
End result: [BILLING TEAM] Routed: I used to be charged twice for my refund request
[route] LLM categorized as ‘technical’ -> dispatching to handle_technical()
End result: [TECH SUPPORT] Routed: The app retains crashing with an error on startup
[route] LLM categorized as ‘common’ -> dispatching to handle_general()
End result: [GENERAL QUEUE] Routed: What are your corporation hours?
[route] LLM categorized as ‘billing’ -> dispatching to handle_billing()
End result: [BILLING TEAM] Routed: I was charged twice for my refund request
[route] LLM categorized as ‘technical’ -> dispatching to handle_technical()
End result: [TECH SUPPORT] Routed: The app retains crashing with an error on startup
[route] LLM categorized as ‘common’ -> dispatching to handle_general()
End result: [GENERAL QUEUE] Routed: What are your enterprise hours?
Three totally different inputs took three totally different paths this time — that’s new in comparison with the earlier part. However take a look at ROUTE_MAP: each potential vacation spot was already written into the code earlier than any of those inputs arrived. The LLM exercised judgment about which key to make use of. It by no means had the choice to create a key that wasn’t there. That distinction — a set set of potential paths versus a path that will get invented at runtime — is precisely the place the subsequent part picks up.
Reactive Brokers: The ReAct Loop and a Genuinely Open Path
That is the place actual autonomy begins. The ReAct sample — Reasoning plus Performing, launched by Yao et al. in 2022 — lets the mannequin itself resolve, at every step, what motion to take subsequent based mostly on what it noticed from the earlier motion. There is no such thing as a pre-written department protecting each case. The agent operates in an iterative loop of thought, motion, and remark till an exit situation is met, and the sequence itself — what number of steps, in what order, and which instruments — will not be knowable upfront. Solely the obtainable actions are mounted; the trail by way of them will not be.
That is the architectural threshold the earlier two sections had been constructing towards. Within the orchestrated workflow, a human wrote each potential department into ROUTE_MAP earlier than the system ran. Right here, the mannequin decides each the trail and the sequence size at runtime, despite the fact that the toolset itself continues to be mounted.
# react_loop.py
# Stipulations: none past Python’s commonplace library
# Run: python react_loop.py
def search_knowledge_base(question: str) -> str:
“””A instrument the agent can name. Whether or not and when it will get referred to as will not be
determined right here — it is determined by the mannequin, at runtime.”””
mock_kb = {
“refund coverage”: “Refunds can be found inside 30 days of buy.”,
“transport time”: “Normal transport takes 5-7 enterprise days.”,
}
for key, worth in mock_kb.objects():
if key in question.decrease():
return worth
return “No matching data present in data base.”
def escalate_to_human(cause: str) -> str:
“””A second instrument the agent can name — once more, the choice to name this
as an alternative of the search instrument is made by the mannequin, not by this code.”””
return f”Escalated to human agent. Purpose: {cause}”
AVAILABLE_TOOLS = {
“search_knowledge_base”: search_knowledge_base,
“escalate_to_human”: escalate_to_human,
}
def mock_llm_decide_next_step(observations: checklist[str], user_query: str) -> dict:
“””
Mock LLM name standing in for the REASONING step of ReAct.
In an actual system, that is an precise mannequin name that reads the complete
Thought -> Motion -> Remark historical past and decides what occurs subsequent.
Critically: this operate — not the calling loop under — decides which
instrument to name and when to cease. There is no such thing as a “if question comprises X, name Y”
department written anyplace in run_react_loop(). The choice is made contemporary,
from accrued context, on each single iteration.
“””
if not observations:
return {
“thought”: “I have to search for the coverage earlier than I can reply.”,
“motion”: “search_knowledge_base”,
“action_input”: user_query,
}
last_observation = observations[-1]
if “No matching data” in last_observation:
# This department was by no means written by a human upfront — the mannequin
# determined, based mostly on what it simply noticed, that escalation was wanted.
return {
“thought”: “The data base has no reply. I ought to escalate this.”,
“motion”: “escalate_to_human”,
“action_input”: “No KB match for: ” + user_query,
}
return {
“thought”: “I discovered the reply. Activity full.”,
“motion”: “end”,
“action_input”: last_observation,
}
def run_react_loop(user_query: str, max_steps: int = 5) -> str:
“””
Thought -> Motion -> Remark, repeated till the mannequin itself decides
to cease. Examine this straight towards run_orchestrated_pipeline() within the
earlier part: there isn’t any ROUTE_MAP right here. There is no such thing as a human-written
department saying “if X occurred, name Y.” Each choice about what occurs
subsequent is made by the mannequin, at runtime, based mostly on what it has noticed to this point.
“””
observations: checklist[str] = []
for step in vary(max_steps):
choice = mock_llm_decide_next_step(observations, user_query)
print(f” Step {step + 1} — Thought: {choice[‘thought’]}”)
if choice[“action”] == “end”:
return f”Ultimate reply: {choice[‘action_input’]}”
tool_fn = AVAILABLE_TOOLS.get(choice[“action”])
if tool_fn is None:
return f”Error: mannequin requested unknown instrument ‘{choice[‘action’]}'”
remark = tool_fn(choice[“action_input”])
print(f” Step {step + 1} — Motion: {choice[‘action’]}({choice[‘action_input’]!r})”)
print(f” Step {step + 1} — Remark: {remark}n”)
observations.append(remark)
return “Max steps reached with out decision.”
if __name__ == “__main__”:
print(“=== Question A: answerable from the data base ===”)
result_a = run_react_loop(“What’s the refund coverage?”)
print(f”End result: {result_a}n”)
print(“=== Question B: not within the data base, ought to set off escalation ===”)
result_b = run_react_loop(“Are you able to course of my worldwide tax refund in crypto?”)
print(f”End result: {result_b}”)
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
87
88
89
90
91
92
93
94
# react_loop.py
# Stipulations: none past Python’s commonplace library
# Run: python react_loop.py
def search_knowledge_base(question: str) -> str:
“”“A instrument the agent can name. Whether or not and when it will get referred to as will not be
determined right here — it is determined by the mannequin, at runtime.”“”
mock_kb = {
“refund coverage”: “Refunds can be found inside 30 days of buy.”,
“transport time”: “Normal transport takes 5-7 enterprise days.”,
}
for key, worth in mock_kb.objects():
if key in question.decrease():
return worth
return “No matching data present in data base.”
def escalate_to_human(cause: str) -> str:
“”“A second instrument the agent can name — once more, the choice to name this
as an alternative of the search instrument is made by the mannequin, not by this code.”“”
return f“Escalated to human agent. Purpose: {cause}”
AVAILABLE_TOOLS = {
“search_knowledge_base”: search_knowledge_base,
“escalate_to_human”: escalate_to_human,
}
def mock_llm_decide_next_step(observations: checklist[str], user_query: str) -> dict:
“”“
Mock LLM name standing in for the REASONING step of ReAct.
In an actual system, that is an precise mannequin name that reads the complete
Thought -> Motion -> Remark historical past and decides what occurs subsequent.
Critically: this operate — not the calling loop under — decides which
instrument to name and when to cease. There is no such thing as a “if question comprises X, name Y“
department written anyplace in run_react_loop(). The choice is made contemporary,
from accrued context, on each single iteration.
““”
if not observations:
return {
“thought”: “I have to search for the coverage earlier than I can reply.”,
“motion”: “search_knowledge_base”,
“action_input”: user_query,
}
last_observation = observations[–1]
if “No matching data” in last_observation:
# This department was by no means written by a human upfront — the mannequin
# determined, based mostly on what it simply noticed, that escalation was wanted.
return {
“thought”: “The data base has no reply. I ought to escalate this.”,
“motion”: “escalate_to_human”,
“action_input”: “No KB match for: “ + user_query,
}
return {
“thought”: “I discovered the reply. Activity full.”,
“motion”: “end”,
“action_input”: last_observation,
}
def run_react_loop(user_query: str, max_steps: int = 5) -> str:
“”“
Thought -> Motion -> Remark, repeated till the mannequin itself decides
to cease. Examine this straight towards run_orchestrated_pipeline() within the
earlier part: there isn’t any ROUTE_MAP right here. There is no such thing as a human-written
department saying “if X occurred, name Y.” Each choice about what occurs
subsequent is made by the mannequin, at runtime, based mostly on what it has noticed to this point.
““”
observations: checklist[str] = []
for step in vary(max_steps):
choice = mock_llm_decide_next_step(observations, user_query)
print(f” Step {step + 1} — Thought: {choice[‘thought’]}”)
if choice[“action”] == “end”:
return f“Ultimate reply: {choice[‘action_input’]}”
tool_fn = AVAILABLE_TOOLS.get(choice[“action”])
if tool_fn is None:
return f“Error: mannequin requested unknown instrument ‘{choice[‘action’]}'”
remark = tool_fn(choice[“action_input”])
print(f” Step {step + 1} — Motion: {choice[‘action’]}({choice[‘action_input’]!r})”)
print(f” Step {step + 1} — Remark: {remark}n”)
observations.append(remark)
return “Max steps reached with out decision.”
if __name__ == “__main__”:
print(“=== Question A: answerable from the data base ===”)
result_a = run_react_loop(“What’s the refund coverage?”)
print(f“End result: {result_a}n”)
print(“=== Question B: not within the data base, ought to set off escalation ===”)
result_b = run_react_loop(“Are you able to course of my worldwide tax refund in crypto?”)
print(f“End result: {result_b}”)
Easy methods to run: python react_loop.py, no dependencies required.
Output:
=== Question A: answerable from the data base ===
Step 1 — Thought: I have to search for the coverage earlier than I can reply.
Step 1 — Motion: search_knowledge_base(‘What’s the refund coverage?’)
Step 1 — Remark: Refunds can be found inside 30 days of buy.
Step 2 — Thought: I discovered the reply. Activity full.
End result: Ultimate reply: Refunds can be found inside 30 days of buy.
=== Question B: not within the data base, ought to set off escalation ===
Step 1 — Thought: I have to search for the coverage earlier than I can reply.
Step 1 — Motion: search_knowledge_base(‘Are you able to course of my worldwide tax refund in crypto?’)
Step 1 — Remark: No matching data present in data base.
Step 2 — Thought: The data base has no reply. I ought to escalate this.
Step 2 — Motion: escalate_to_human(‘No KB match for: Are you able to course of my worldwide tax refund in crypto?’)
Step 2 — Remark: Escalated to human agent. Purpose: No KB match for: Are you able to course of my worldwide tax refund in crypto?
Step 3 — Thought: I discovered the reply. Activity full.
End result: Ultimate reply: Escalated to human agent. Purpose: No KB match for: Are you able to course of my worldwide tax refund in crypto?
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
=== Question A: answerable from the data base ===
Step 1 — Thought: I want to look up the coverage earlier than I can reply.
Step 1 — Motion: search_knowledge_base(‘What’s the refund coverage?’)
Step 1 — Remark: Refunds are obtainable inside 30 days of buy.
Step 2 — Thought: I discovered the reply. Activity full.
End result: Ultimate reply: Refunds are obtainable inside 30 days of buy.
=== Question B: not in the data base, ought to set off escalation ===
Step 1 — Thought: I want to look up the coverage earlier than I can reply.
Step 1 — Motion: search_knowledge_base(‘Are you able to course of my worldwide tax refund in crypto?’)
Step 1 — Remark: No matching data discovered in data base.
Step 2 — Thought: The data base has no reply. I ought to escalate this.
Step 2 — Motion: escalate_to_human(‘No KB match for: Are you able to course of my worldwide tax refund in crypto?’)
Step 2 — Remark: Escalated to human agent. Purpose: No KB match for: Can you course of my worldwide tax refund in crypto?
Step 3 — Thought: I discovered the reply. Activity full.
End result: Ultimate reply: Escalated to human agent. Purpose: No KB match for: Can you course of my worldwide tax refund in crypto?
Take a look at what differs between the 2 runs: question A completed in two steps, question B took three, and question B took an motion — escalation — that was by no means hardcoded as “what occurs when refund queries point out crypto.” The identical loop, the identical code, produced two genuinely totally different step counts and sequences as a result of the mannequin determined the trail at runtime based mostly on what it noticed. That’s the precise, concrete which means of “no predefined code path” — not a slogan, however a measurable distinction in what number of steps had been run and what they had been.
Manufacturing implementations of this sample usually wrap the accrued thought/remark historical past in a “scratchpad” and summarize instrument outputs earlier than feeding them again into the loop, since dumping uncooked error logs or giant API responses again into context tends to confuse the subsequent reasoning step fairly than assist it.
Autonomous Multi-Agent Techniques
The far finish of the spectrum builds straight on the ReAct loop above, simply nested. In a multi-agent setup, an orchestrator runs its personal ReAct loop, the place a few of its obtainable “actions” are calls to different brokers, every of which runs its personal full ReAct loop inside. The orchestrator causes about what to delegate, delegates it, observes the outcome, and continues — precisely just like the single-agent loop within the earlier part, besides a few of its “instruments” are total brokers fairly than easy capabilities.
Image the AVAILABLE_TOOLS dictionary from the earlier instance, besides as an alternative of search_knowledge_base and escalate_to_human, the entries are research_agent, finance_agent, and coding_agent — and calling one among them doesn’t return a easy string; it kicks off that sub-agent’s personal unbiased Thought-Motion-Remark loop, which could run for a number of steps earlier than returning something to the orchestrator. No one wrote down upfront which sub-agent will get referred to as, in what order, or what number of occasions any of them run.
Google Cloud’s documentation labels probably the most excessive model of this the “swarm” sample — a collaborative crew of brokers with no central orchestrator in any respect, able to producing exceptionally high-quality, inventive options exactly as a result of nothing is constraining how they work together. That very same lack of construction can also be the danger: with no human-designed sure on the interplay, a swarm can fall into unproductive loops or just fail to converge, and the price of working many brokers by way of many turns compounds rapidly.
That is the purpose on the spectrum the place the predictability axis from the primary part swings hardest within the different path. A deterministic pipeline provides you an identical output construction each time, by building. A swarm of autonomous brokers provides you the flexibleness to deal with an issue no one anticipated, at the price of with the ability to predict, upfront, what it can do or how lengthy it can take to do it.
Why This Distinction Really Issues in Manufacturing
This isn’t an educational distinction. It has a direct, measurable impact on what groups truly ship. Regardless of the amount of hype round autonomous brokers, AI workflows — not totally autonomous brokers — received the manufacturing battle in 2025: workflows stay the dominant sample behind profitable generative AI deployments, whereas totally autonomous multi-agent techniques are nonetheless largely exploratory exterior of slim domains.
The explanation maps straight again to the predictability axis from the beginning of this text. Agentic techniques are non-deterministic by nature; an identical inputs can produce totally different outputs throughout separate runs, which is a critical legal responsibility in regulated, auditable, or in any other case high-stakes processes. If a course of have to be explainable step-by-step to a compliance crew or a regulator, that’s not agent territory by default; it wants guardrails and human-in-the-loop checkpoints layered on prime earlier than it may be trusted with actual penalties.
The sample that’s truly rising in mature techniques is hybrid, not a pick-one choice. A better-level agent units objectives and orchestrates the general process, whereas crucial, well-understood computations nonetheless run inside deterministic modules {that a} human has totally specified. A medical diagnostics system, for instance, may use an agent to interpret ambiguous signs and resolve which checks to order — real autonomy, as a result of the appropriate sequence of checks isn’t knowable upfront — whereas every take a look at itself runs by way of a validated, deterministic pipeline, as a result of that a part of the issue has a recognized right path and no cause to introduce variability into it.
Conclusion
“Agentic workflow” and “autonomous agent” describe two ends of 1 spectrum, not two competing applied sciences, and the 4 levels walked by way of right here — deterministic, orchestrated, reactive, and autonomous multi-agent — aren’t a rating from worse to raised. They’re totally different solutions to the identical query: who decides what occurs subsequent, and was that call made by a human writing code upfront, or by a mannequin reasoning at runtime?
Deterministic workflows offer you auditability and repeatability by building; the identical enter takes the identical path each time, full cease. Reactive and multi-agent techniques hand over that assure in change for the flexibility to deal with issues whose form genuinely can’t be anticipated forward of time. Neither property is free, and neither structure is right by default.
The techniques that maintain up properly in manufacturing don’t choose one excessive of this spectrum and apply it all over the place. They place every bit of the issue on the level on the spectrum that piece truly requires — a set construction wherever a recognized right path exists and repeatability issues, with actual autonomy reserved for the elements of the issue that haven’t any predefined right path to comply with within the first place.

