# Introduction
I do know that when inexperienced persons begin studying machine studying, issues appear straightforward at first. You observe a tutorial that asks you to load a dataset, practice a mannequin, and then you definitely see one thing like this: loss = “mse” or criterion = nn.CrossEntropyLoss().
And similar to that, the tutorial begins speaking about equations, gradients, optimization, and Greek letters. When you have ever nodded alongside with out actually understanding what a loss perform does, you aren’t alone. Loss capabilities are sometimes defined backward. Most tutorials begin with the system when they need to begin with the concept. This text is a part of my noob sequence, the place I’ll make issues simpler so that you can perceive. So, let’s get began.
# What Is a Loss Operate?
A loss perform is how a machine studying mannequin is aware of how flawed it’s. That’s actually the entire idea. The mannequin makes a prediction. The loss perform compares that prediction with the right reply. Then it provides the mannequin a quantity that claims, “That is how unhealthy your mistake was.”
A excessive loss means the mannequin was very flawed.
A low loss means the mannequin was shut.
Throughout coaching, the mannequin retains adjusting itself to make the loss smaller.
That’s how studying occurs. When you have performed a dart recreation, it is vitally comparable. You throw the dart. To enhance, you want suggestions. It’s good to know whether or not your dart was barely off, distant, too excessive, or too far left. With out that suggestions, you can’t enhance. So, the bullseye is mainly the right reply and the dart is the prediction. You measure the gap between the dart and the bullseye. The loss perform measures how distant the dart landed. That distance turns into the mannequin’s suggestions sign. Here is how it could look in case you want a visualization.
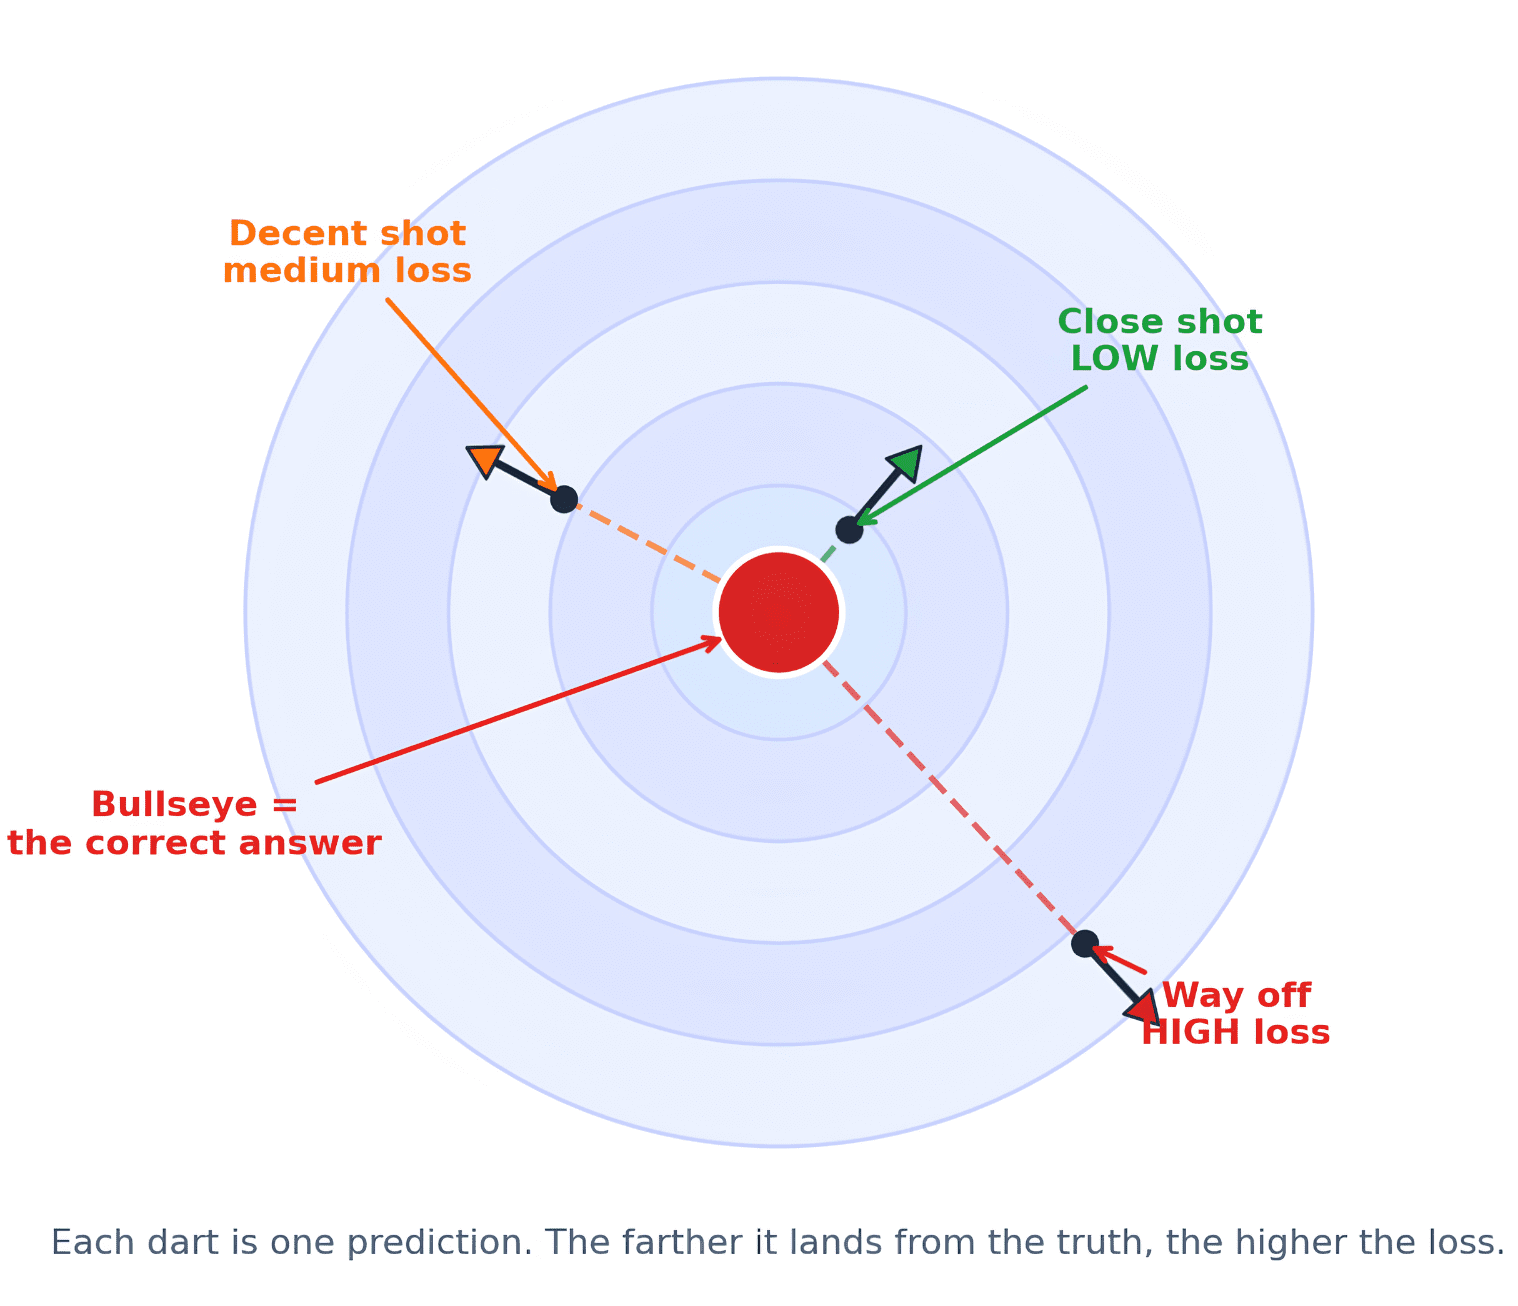
Identical to the gap from the middle issues, throwing too shut is just not the identical as being means off. Equally, for fashions, simply figuring out that the reply is flawed is just not sufficient. The mannequin must understand how badly it failed to be able to enhance.
Now that we’ve an understanding of what a loss perform is and why we’d like it, let us take a look at among the frequent loss capabilities utilized in machine studying.
# Imply Squared Error
The most typical loss for predicting numbers is imply squared error (MSE). It’s typically used when the mannequin is predicting numbers like home costs, temperatures, or supply instances. The thought could be very easy.
Error: For every prediction, take the hole between the guess and the reality.
Squared: Multiply every hole by itself.
Imply: Common all these squared gaps.
You’ll be able to write it in Python like this:
squared_errors = [(p – a) ** 2 for p, a in zip(predictions, actuals)]
return sum(squared_errors) / len(squared_errors)
Now, I do know that taking the errors after which averaging over the predictions is smart intuitively, however understanding why we sq. them will be complicated. That is accomplished for 2 causes:
Squaring makes each error optimistic. An error of +3 and an error of -3 are equally unhealthy, and squaring turns each into 9, in order that they cease cancelling one another out.
Squaring punishes large errors much more harshly than small ones. That is good for many use instances. For instance, if you’re predicting home costs, being flawed by $1,000 versus $200,000 ought to be punished accordingly.
# Imply Absolute Error
One other frequent loss perform is imply absolute error (MAE). MAE additionally measures the hole between predictions and precise values, but it surely doesn’t sq. the error. As a substitute, it merely takes absolutely the worth.
Here is the Python perform to write down it:
absolute_errors = [abs(p – a) for p, a in zip(predictions, actuals)]
return sum(absolute_errors) / len(absolute_errors)
So, it punishes giant errors, however not as harshly as MSE does.
An error of 10 prices 10 and an error of 20 prices 20.
In case your knowledge naturally has some outliers and you do not need your mannequin to overreact, MAE is an efficient alternative.
Let me present a fast graph that compares the MSE and MAE curves.

# Cross-Entropy Loss
To this point, we’ve talked about predicting numbers. However many machine studying issues are about predicting classes.
Is that this e mail spam or not?
Is that this an image of a cat, canine, or fish?
Is a sure transaction fraudulent or not?
For classification duties, fashions often output possibilities like:
Cat: 20%
Fish: 10%
If the picture actually is a canine, that could be a good prediction. But when it’s a cat, then the mannequin must be penalized for assigning a decrease likelihood to the right reply.
So, the instinct is:
Appropriate and assured — low loss
Appropriate however uncertain — medium loss
Incorrect and assured — excessive loss
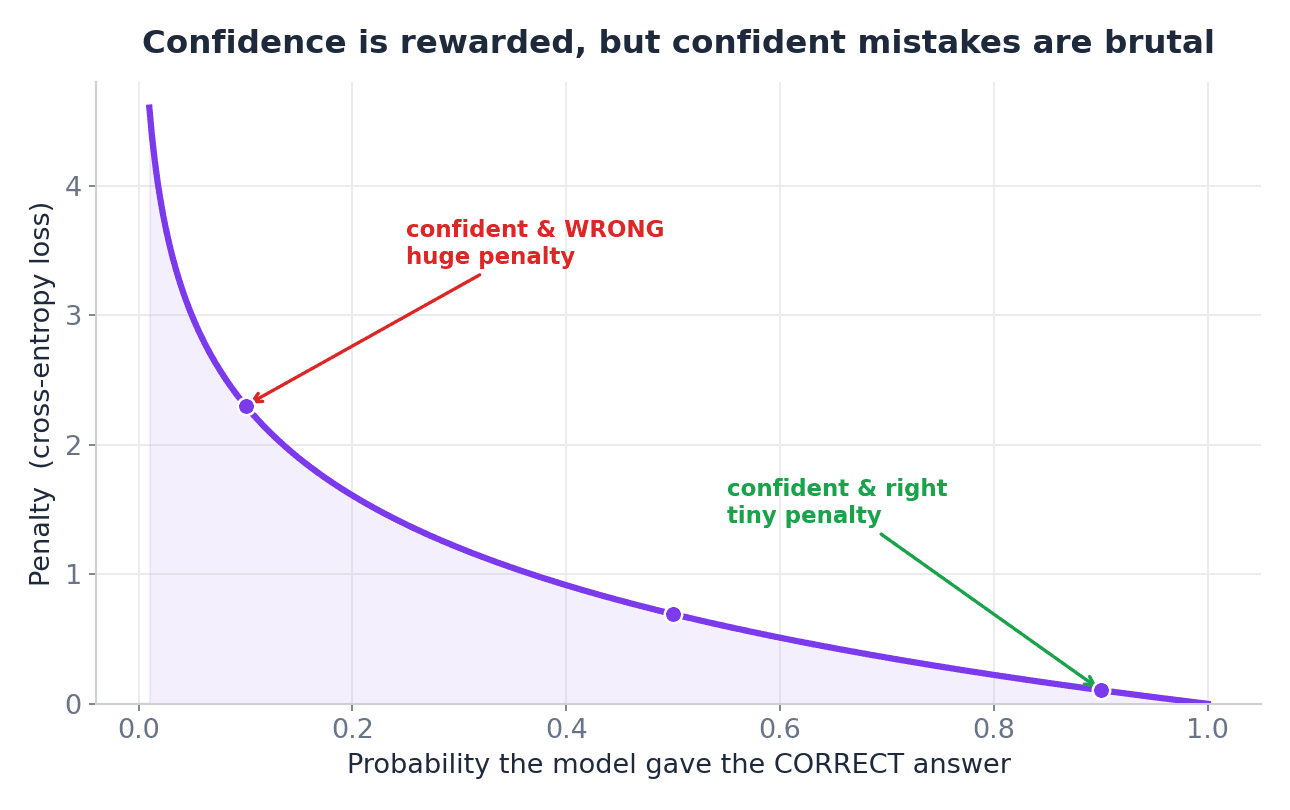
For this reason cross-entropy is so broadly used for classification. It doesn’t simply care about whether or not the mannequin was proper. It additionally cares about how assured the mannequin was.
# Loss vs. Accuracy
Now that we’ve gone by way of totally different loss capabilities, I additionally wish to make clear the distinction between loss and accuracy. They aren’t the identical factor.
Accuracy tells you what number of predictions had been appropriate.
However loss tells you the way unhealthy the mannequin’s errors had been.
When you have two fashions — Mannequin A and Mannequin B — and each get 90 out of 100 predictions appropriate, they’ll have the identical accuracy. However one mannequin could also be very assured on the suitable solutions and solely barely flawed on the wrong ones, whereas the opposite could also be barely appropriate on many examples and intensely assured when flawed.
In that case, the accuracy can be the identical, however the loss can be totally different.
# The Coaching Loop
As soon as the mannequin has a loss quantity, it could possibly enhance. The coaching loop appears to be like like this:
The mannequin makes predictions.
The loss perform measures the errors.
The optimizer updates the mannequin.
The mannequin tries once more.
The loss hopefully will get smaller.
When coaching a mannequin, we additionally plot the loss over time. To start with, the mannequin makes many errors and is poor at making predictions, so the loss is excessive. However as coaching progresses, the loss decreases and the mannequin will get higher at making predictions.
A wholesome coaching curve typically appears to be like like this:
Excessive loss firstly → sharp drop → gradual flattening
as you possibly can see within the determine beneath.

The flattening is regular. It means the mannequin has discovered the simple patterns and is now making smaller enhancements. But when the coaching loss goes down whereas the validation loss begins going up, that may be a warning signal of overfitting — which implies the mannequin could also be memorizing the coaching knowledge as a substitute of studying patterns that generalize.
# Last Ideas
A loss perform is the mannequin’s mistake rating.
It tells the mannequin how flawed its predictions are, and it provides coaching a transparent aim: make that quantity smaller.
When you perceive loss capabilities, many different machine studying concepts turn into simpler to know — together with gradient descent, backpropagation, optimization, overfitting, and analysis metrics.
You don’t want to begin with scary equations. Begin with the concept:
The mannequin guesses.
The loss perform scores the guess.
The mannequin updates itself to cut back the rating.
That’s the coronary heart of machine studying.
Loss is how a mannequin is aware of it’s flawed.
Coaching is the way it learns to be much less flawed.
This brings us to the tip of this text. We are going to proceed to cowl some fascinating ideas all through our noob sequence.
Kanwal Mehreen is a machine studying engineer and a technical author with a profound ardour for knowledge science and the intersection of AI with medication. She co-authored the e-book “Maximizing Productiveness with ChatGPT”. As a Google Technology Scholar 2022 for APAC, she champions range and educational excellence. She’s additionally acknowledged as a Teradata Variety in Tech Scholar, Mitacs Globalink Analysis Scholar, and Harvard WeCode Scholar. Kanwal is an ardent advocate for change, having based FEMCodes to empower girls in STEM fields.