



The issue with multilingual speech recognition right this moment
For those who’ve ever constructed a product that should transcribe speech, you have in all probability hit considered one of these partitions:
The polyglot tax. You need to assist a number of languages, so that you sew collectively 40 totally different fashions — or 40 totally different vendor APIs — every with its personal quirks, latency profile, and billing. Your infrastructure turns into a museum of one-off integrations.
The streaming-vs-accuracy tradeoff. Actual-time captioning wants low latency, however most “streaming” ASR programs faux it by re-processing overlapping home windows of audio again and again. That burns compute and provides delay. Flip down the latency and accuracy falls off a cliff.
The post-processing pipeline. Uncooked ASR output is usually an unpunctuated, lowercase wall of textual content. You bolt on a second mannequin for punctuation and capitalization, including one more shifting half.
The “recognized language” assumption. Many programs require you to inform them the language up entrance. However what a few customer-support line the place callers change between English and Spanish mid-sentence?
Nemotron 3.5 ASR was constructed to break down all 4 of these issues into one mannequin.
What it does
One mannequin, 40 language-locales. A single 600M-parameter checkpoint transcribes English (US/GB), Spanish (US/ES), German, French (FR/CA), Italian, Arabic, Japanese, Korean, Portuguese (BR/PT), Russian, Hindi, Turkish, Vietnamese, Dutch, Ukrainian, Polish, Finnish, Mandarin, Czech, Bulgarian, Slovak, Swedish, Croatian, Romanian, Estonian, Danish, Hungarian, Norwegian Bokmål, Norwegian Nynorsk, Hebrew, Greek, Lithuanian, Latvian, Maltese, Slovenian, and Thai. No per-language deployment, no model-swapping.
Actual-time streaming, completed proper. The mannequin is constructed on a Cache-Conscious FastConformer encoder. Conventional “buffered” streaming re-processes overlapping chunks of audio at each step, doing the identical work many instances over. This mannequin as an alternative caches the encoder’s inner state and reuses it — each audio body is processed precisely as soon as, with no overlap. The result’s dramatically decrease compute and end-to-end latency, with no accuracy penalty.
Punctuation and capitalization, natively. The output is production-ready textual content — correct casing, commas, durations, query marks — straight from the mannequin. No separate punctuation-restoration step.
Language conditioning, your alternative. You’ll be able to run it two methods:
Inform the mannequin the enter language (target_lang=en-US) when you understand it — sometimes the very best accuracy.
Let the mannequin detect the language (target_lang=auto) when you do not — the mannequin detects the language and transcribes accordingly.
The way it works (the 2-minute model)
The mannequin has two fundamental items:
A Cache-Conscious FastConformer encoder (24 layers). FastConformer is an environment friendly evolution of the Conformer structure with linearly scalable consideration. The “cache-aware” half is the streaming magic: the encoder retains a cache of its self-attention and convolution activations from earlier frames, in order new audio arrives it solely computes what’s genuinely new. Nothing is recomputed.
An RNNT (Recurrent Neural Community Transducer) decoder. RNNT is the workhorse decoder for streaming ASR — it emits textual content as audio streams in, body by body, which is precisely what you need for reside transcription.
On prime of this, the mannequin provides prompt-based language-ID conditioning: a language sign is fed alongside the audio, which lets one set of weights specialize its output to the goal language — or, in auto mode, infer the language itself.
It was educated on an enormous speech knowledge spanning all supported languages, utilizing a mix of public and proprietary knowledge normalized to punctuated, properly-cased textual content.
A knob value figuring out: att_context_size
Streaming ASR is essentially a tradeoff between how quickly you emit textual content and the way a lot future audio the mannequin will get to “peek at” earlier than committing. Nemotron ASR exposes this immediately by way of the eye context measurement:
Consideration Context
Chunk Dimension (Latency)
Use Case
[56, 0]
80ms (Extremely-Low)
Extremely low latency Voice Brokers
[56, 1]
160ms (Low)
Interactive Voice Brokers, Conversational AI
[56, 3]
320ms (Balanced)
Conversational AI, Dwell caption
[56, 6]
560ms (Medium)
Excessive accuracy with affordable latency
[56, 13]
1.12s (Excessive)
Highest accuracy with excessive latency
The identical checkpoint covers the entire spectrum — you select the working level at inference time, no retraining required.
Attempt it in minutes
The mannequin ships as a NeMo checkpoint. Clone the NeMo department and level the streaming inference script at your audio:
git clone https://github.com/NVIDIA-NeMo/NeMo.git
Transcribe with a recognized language:
python ${NEMO_ROOT}/examples/asr/asr_cache_aware_streaming/speech_to_text_cache_aware_streaming_infer.py
model_path=${MODEL_PATH}
dataset_manifest=${MANIFEST_PATH}
output_path=${OUTPUT_FOLDER}
target_lang=es-ES
att_context_size=”[56,3]”
strip_lang_tags=true
Or let the mannequin detect the language:
python ${NEMO_ROOT}/examples/asr/asr_cache_aware_streaming/speech_to_text_cache_aware_streaming_infer.py
model_path=${MODEL_PATH}
dataset_manifest=${MANIFEST_PATH}
output_path=${OUTPUT_FOLDER}
target_lang=auto
att_context_size=”[56,3]”
strip_lang_tags=true
Audio ought to be mono-channel .wav. The manifest is an ordinary NeMo JSON-lines file:
{“audio_filepath”: “/path/to/clip.wav”, “length”: 4.27, “textual content”: “reference transcript”}
Mannequin robotically predicts language_tag on the finish of every accomplished sentence, i.e. “It is a check pattern. ”. “strip_lang_tags=True” removes the language tag for higher readability.
Nemotron 3.5 ASR is powerful out of the field — nevertheless it was educated on a combination the place some languages have way more knowledge than others. The long-tail locales have headroom, and some hours of in-domain audio plus the suitable recipe closes a shocking quantity of it.
To make this concrete, we ran a labored instance: take the bottom mannequin and sharpen it on two mid-resource European languages — Greek, and Bulgarian — then measure actually on held-out knowledge. The outcomes beneath are from that run. This part is a high-level overview and the coding instance lives within the companion GitHub repo. Once we publish an agentic SKILL.md protecting the entire course of, this weblog can be up to date accordingly.
Why fine-tune?
A number of conditions the place it pays off:
Sharpening a long-tail locale. Languages with much less pretraining knowledge have probably the most to realize.
Area experience or specialised vocabulary Medical, authorized, monetary, or technical vocabulary the bottom mannequin hardly ever noticed.
Accent, dialect, and acoustics. Telephony, far-field, in-car, or a selected speaker inhabitants.
New languages. Bootstrapping a locale that is not but lined.
A Preview of the Energy of Fantastic-Tuning
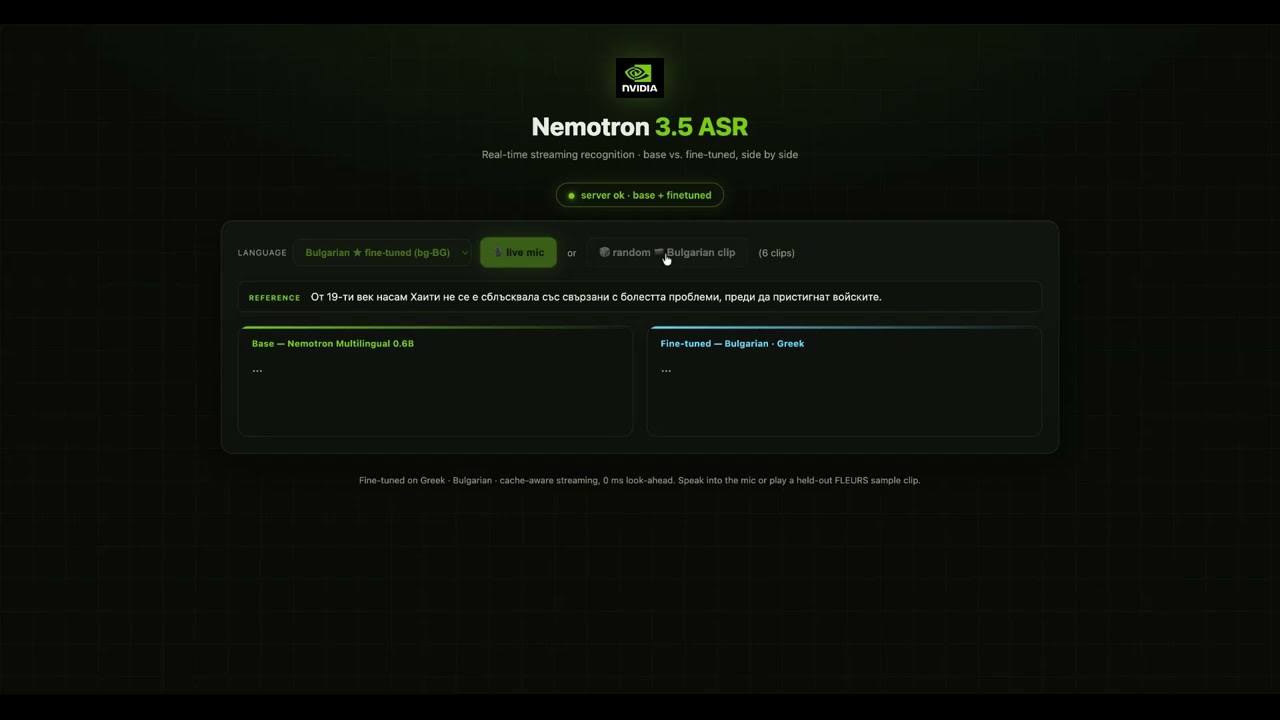
🎥 Video Walkthrough: Watch on YouTube
This walkthrough demonstrates multilingual streaming inference, latency/accuracy tradeoffs, deployment choices, and the fine-tuning workflow described beneath.
The recipe at a look
The entire workflow is 5 strikes:
Level the coach at tarred speech knowledge for the goal languages — no per-file unpacking, streamed effectively by NeMo/Lhotse.
Fantastic-tune from the bottom checkpoint (init_from_nemo_model) utilizing the identical Cache-Conscious FastConformer-RNNT recipe, conditioned on every clip’s language tag.
Consider on a held-out set the mannequin by no means noticed — on the identical low-latency streaming setting you may deploy (e.g. att_context_size=[56,0], 80ms chunk; 0ms lookahead).
Add extra knowledge the place the language is weak and retrain.
Export and deploy the fine-tuned checkpoint.
Step 1 — Knowledge
We assembled a balanced, ~2000-hour combine throughout the 2 languages (Greek and Bulgarian) from public multilingual corpora (Granary, Widespread Voice, FLEURS), saved as tarred NeMo/Lhotse shards. The 2 particulars that matter most:
Each clip carries a target_lang tag — that is what drives the mannequin’s prompt-based language conditioning, so getting the tag proper (and utilizing a worth the mannequin acknowledges) is crucial.
Match the bottom mannequin’s textual content type — punctuated, properly-cased transcripts, since that is what the mannequin produces.
Held-out FLEURS check splits (which weren’t in coaching) gave us an sincere, in-the-wild benchmark per language.
Step 2 — Practice
A simple full fine-tune of the streaming RNNT mannequin, pushed by a set step price range (the suitable strategy to schedule with streaming/iterable knowledge). It runs on a single GPU for a fast move and scales cleanly to multi-GPU for a fuller run. On a small dataset like this, an epoch is minutes, not hours.
Step 3 — Consider
We measured Phrase Error Fee on the held-out FLEURS check set, in streaming mode with 80ms chunk — probably the most demanding situation, with no future-audio “peeking.” The advance over the bottom mannequin is massive, particularly for the languages that started off weakest:
Language
Base mannequin
Fantastic-tuned
Relative Enchancment in WER
🇬🇷 Greek
35
24
32%
🇧🇬 Bulgarian
22
15
31%
Uncooked WER (%) on held-out FLEURS check, lowest-latency streaming. Similar analysis for each the bottom and the fine-tuned fashions.
Languages with increased error charges within the base mannequin grew to become genuinely helpful after a brief fine-tune — Bulgarian error charges greater than halved.
Step 4 — Scale the information the place it helps
To check how way more knowledge goes, we then blended in ~2,000 further hours of parliamentary speech (MOSEL/VoxPopuli) a part of the Granary Dataset, taking the coaching pool from ~290 hours to ~2,300 hours. Even partway by way of that longer run, the weakest languages improved additional (e.g. Bulgarian dropping into the high-20s), confirming the apparent lever: extra in-language knowledge retains serving to — although positive factors are uneven throughout languages and domains, so measure relatively than assume.
Step 5 — Deploy
The fine-tuned mannequin is identical structure as the bottom, so it drops straight into the identical serving path and also you decide your latency/accuracy working level at inference time through att_context_size, precisely as in Half 1.
What we realized
Fantastic-tuning is transformative for under-resourced languages — the most important wins got here the place the bottom mannequin was weakest.
Consider at deployment latency, on held-out knowledge. Coaching-set scores flatter you; a separate check set at 0 ms look-ahead tells the reality.
Get the language tag proper. The immediate conditioning is highly effective however unforgiving of mismatched language labels.
Defend the opposite languages. When specializing in a multilingual mannequin, mix in a slice of the mannequin’s different languages (“replay”) and re-check them, so that you sharpen your goal locales with out eroding the remainder.
Extra knowledge helps, erratically. Including hours reliably moved most languages; one plateaued — a reminder that area match issues as a lot as uncooked amount.
📦 The complete walkthrough — knowledge prep scripts, coaching configs, the precise instructions, and the whole benchmark numbers — is within the companion GitHub repo. This part is the overview; the repo is the construct.
For manufacturing serving, look out for the NIM launch later this month, offering gRPC streaming, and assist throughout NVIDIA Ampere, Hopper, Blackwell, Lovelace, Turing, Volta, and Jetson.
What you possibly can construct with it
A number of of the use instances this mannequin unlocks:
Sub-second voice brokers — ASR → LLM → TTS loops the place the speech-to-text leg is not the bottleneck.
Dwell multilingual assembly captions — one stream, individuals in numerous languages, captions in actual time.
Name-center analytics at international scale — one ASR backend as an alternative of a per-language vendor sprawl.
Actual-time captioning + translation for livestreams and occasions.
On-device transcription on Jetson for privacy-sensitive or disconnected environments.
Get Began
Able to construct multilingual speech purposes with a single streaming ASR mannequin?
🤗 Attempt Nemotron 3.5 ASR: nvidia/nemotron-3.5-asr-streaming-0.6b🧠 Run and fine-tune with NVIDIA NeMo: github.com/NVIDIA-NeMo/NeMo📚 Discover the coaching instance: Fantastic-Tuning Pocket book
Whether or not you are constructing voice brokers, multilingual captioning programs, contact-center analytics, or on-device speech purposes, Nemotron 3.5 ASR supplies a single multilingual mannequin that may be deployed, personalized, and fine-tuned on your use case.
We might like to see what you construct. Share your benchmarks, fine-tuning outcomes, and language variations on the mannequin dialogue web page:
💬 Mannequin Discussions: https://huggingface.co/nvidia/nemotron-3.5-asr-streaming-0.6b/discussions
Mannequin: https://huggingface.co/nvidia/nemotron-3.5-asr-streaming-0.6b
License: OpenMDW-1.1
Runtime: NeMo 26.06+

