In April final 12 months, Kelsey Piper found that OpenAI’s o3 mannequin was surprisingly good at determining the place a photograph was taken from. Like human “geoguessr” professionals, o3 may typically take a nondescript picture of a seashore and inform you precisely the place it’s. Right here’s the instance Kelsey gave:
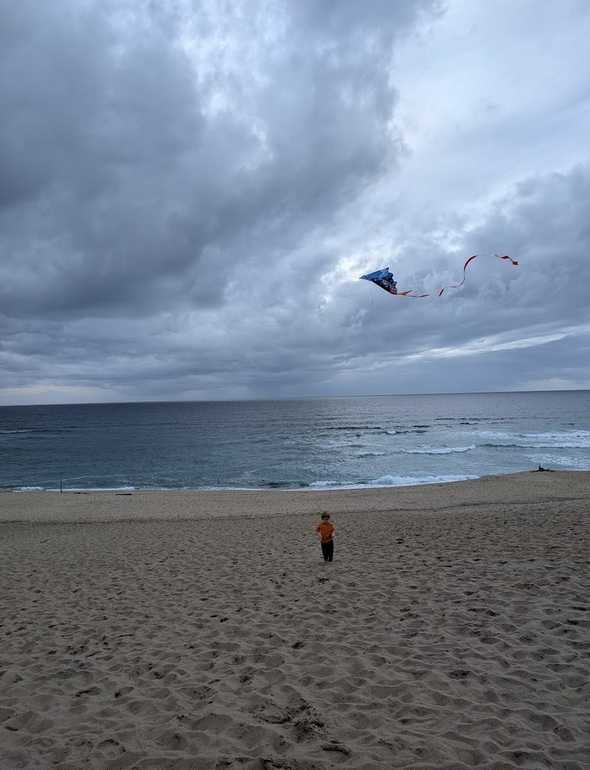
A number of individuals reproduced this with good outcomes: not a 100% success price, however clearly much better than you’d do with a random human guess. The lesson right here is that mannequin capabilities can shock us. The o3 mannequin had been launched for 2 weeks earlier than Kelsey’s tweet with out anybody noticing how good it was at geolocation. What obscure capabilities did we by no means discover? What capabilities of present fashions are we lacking at present?
Some individuals drew one other lesson from this: that “immediate engineering” can unlock brand-new capabilities. It is because Kelsey had a magic immediate that she constructed over time. When o3 obtained one thing flawed, she would ask it the way it may have averted the error, after which included that within the immediate. Right here’s the primary 10% of that immediate, so that you get the concept:
You might be taking part in a one-round sport of GeoGuessr. Your job: from a single nonetheless picture, infer the most definitely real-world location. Word that not like within the GeoGuessr sport, there isn’t any assure that these pictures are taken someplace Google’s Streetview automobile can attain: they’re consumer submissions to check your image-finding savvy. Non-public land, somebody’s yard, or an offroad journey are all actual potentialities (although many pictures are findable on streetview). Pay attention to your individual strengths and weaknesses: following this protocol, you normally nail the continent and nation…
This immediate impressed lots of people, who tried it out and reported that it accurately recognized plenty of pictures. However in fact, o3 accurately recognized plenty of pictures with only a fundamental “consider carefully about the place this image was taken?” immediate. Did the immediate truly assist? It’d be robust to determine that out simply from taking part in round in ChatGPT. You’d must construct an analysis set of pictures and run o3 in opposition to them twice: as soon as with the flamboyant immediate and as soon as with out it.
In order that’s what I did. I pulled 200 pictures from Wikimedia Commons, Geograph Britain and Eire, and iNaturalist for the benchmark. You’ll be able to learn the AI-generated abstract right here, however right here’s the important thing desk:
Immediate
n
Median km
Imply km
P25 km
P75 km
<=25 km
<=100 km
<=500 km
<=1000 km
Default
200
83.2
440.7
16.4
221.9
58
109
176
182
GeoGuessr immediate
200
102.3
481.9
18.5
277.8
59
99
172
180
Usually, the essential immediate did higher on common. It persistently guessed nearer to the precise location. Each prompts did fairly nicely, truly. Regardless of the flamboyant immediate being 10x bigger, it solely prompted o3 to assume for barely longer (about one second on common, although the max was about double, at 10 minutes as a substitute of 5 minutes). The pictures in my benchmark had been pretty generic geoguessr-style out of doors pictures, with twelve indoor pictures thrown in for an additional problem (the flamboyant immediate additionally did barely worse on these).
What’s occurring? I believe this reveals how straightforward it’s to idiot your self concerning the high quality of prompting. When the mannequin is already fairly good at a job, you may give it a really elaborate immediate with out impacting efficiency. It’ll nonetheless be fairly good, besides this time it’s good due to what you probably did. That is significantly true when you’re iterating with the mannequin and asking it “what ought to I add to the immediate” for every mistake. Fashions will fortunately make up tales for you about their very own reasoning processes, and can nearly at all times say “sure, that helped loads!” if you ask them if a selected immediate tweak made issues higher. The one strategy to truly know is by setting up some type of benchmark.
It’s additionally attention-grabbing to me that no person checked this on the time. It took me about six hours of fairly-distracted work and about $15 to assemble and run this benchmark. Why didn’t anybody do that once they had been writing articles about how good the o3 immediate was?
One charitable cause is perhaps that the story was extra about o3’s actual geolocation potential than concerning the magic immediate. The pricing for o3 additionally was once about 5 occasions costlier (although a benchmark of 40 pictures as a substitute of 200 would nonetheless have thrown doubt on how a lot water the immediate was carrying). Additionally, AI simply strikes so quick. Geolocation was solely the story for a few week: after that, GPT-4o’s sycophancy was what individuals had been speaking about. Another excuse is that AI tooling wasn’t pretty much as good then. The benchmark was really easy for me to run as a result of GPT-5.5 did many of the heavy lifting. Previous to sturdy brokers, you’ll have needed to write the (easy) benchmark your self. I can’t level the finger too exhausting: I didn’t hassle on the time both.
Possibly my benchmark isn’t superb? The pictures look cheap sufficient: all kinds of geoguessr-like pictures of roads and landscapes, principally. I may have tried to collect just a few thousand pictures as a substitute of some hundred, but when the magic immediate actually was an enormous enchancment you’d nonetheless count on to see that manifest on a benchmark this dimension. If somebody desires to go and construct a hundred-dollar geolocation benchmark as a substitute of my fifteen-dollar one, I believe that’d be an attention-grabbing challenge.
Lastly, let’s use the benchmark to reply a query I’ve had for some time: do gpt-5.4 and gpt-5.5 have o3’s geolocation talents? The reply, apparently, isn’t any.
Run
Median km
Imply km
<=25 km
<=100 km
<=500 km
o3 default
83.2
440.7
58
109
176
o3 GeoGuessr
102.3
481.9
59
99
172
gpt-5.4 default
163.3
638.9
26
74
148
gpt-5.5 default
156.5
645.9
39
77
161
No matter o3 had that made it good at this job hasn’t transferred to newer fashions.
edit: This submit obtained some feedback on Hacker Information. The highest remark nervous that the fashions already knew the photographs, since they’re public area. I thought of this however didn’t assume it was price sourcing model new pictures: first, if the picture/location pairs had been within the coaching information, the fashions would have completed higher; second, even when they’re within the coaching information it nonetheless provides us helpful comparability information from the immediate and for different fashions. I did affirm the photographs didn’t have EXIF metadata, so we’re not testing whether or not the immediate makes the mannequin roughly prone to cheat.
This is a preview of a associated submit that shares tags with this one.