Mannequin customization transforms general-purpose AI fashions into specialised enterprise property. By fine-tuning basis fashions (FMs) on domain-specific knowledge, companies train AI their distinctive workflows, terminology, and deep area specialization, together with strict adherence to model voice and fewer hallucinations. For enterprises, that is greater than an optimization. It’s the creation of proprietary mental property. A fine-tuned mannequin encodes a corporation’s distinctive intelligence and finest practices into its structure. This builds a aggressive benefit that’s tough to copy with off-the-shelf public frontier fashions. On the similar time, fine-tuning smaller, open-weight fashions on focused duties typically matches or exceeds the efficiency of a lot bigger proprietary fashions. This method delivers vital value financial savings whereas retaining delicate knowledge inside safe, personal infrastructure.
Amazon SageMaker AI presents a big selection of open supply fashions and fine-tuning strategies to assist organizations tailor basis fashions to their distinctive wants. Now, SageMaker AI introduces serverless mannequin customization for NVIDIA Nemotron 3 fashions, beginning with Nemotron 3 Nano (30B whole parameters, 3B energetic) and Nemotron 3 Tremendous (120B whole parameters, 12B energetic). With supervised fine-tuning (SFT), reinforcement studying with verifiable rewards (RLVR), and reinforcement studying with AI suggestions (RLAIF), you may adapt these high-performance open-weight fashions to your particular domains and workflows with out provisioning or managing any infrastructure. For a whole listing of open fashions accessible for serverless mannequin customization, see Customise open weight fashions within the Amazon SageMaker AI documentation.
On this submit, we discover what makes the Nemotron 3 structure distinctive, stroll by means of the fine-tuning strategies accessible, and present you step-by-step the way to get began with serverless customization utilizing SageMaker Studio.
Overview of NVIDIA Nemotron 3 fashions on Amazon SageMaker AI
NVIDIA Nemotron 3 is a household of open-weight massive language fashions (LLMs) constructed on a hybrid Mamba-Transformer Combination-of-Specialists (MoE) structure with native assist for as much as 1M-token context lengths. The structure interleaves three complementary layer varieties: Mamba-2 layers for environment friendly linear-time sequence processing, Transformer consideration layers for exact associative recall, and Latent Combination-of-Specialists (LatentMoE) layers that compress tokens earlier than routing to specialised specialists. This design prompts solely a fraction of whole parameters per ahead cross (for instance, 12B of 120B within the Tremendous variant), delivering excessive throughput and powerful accuracy at considerably decrease compute value. The fashions use multi-environment reinforcement studying by means of NeMo Gymnasium, which aligns them to real-world, multi-step agentic duties throughout domains resembling coding, reasoning, and long-context evaluation.
Nemotron 3 Nano 30B
Nemotron 3 Nano is a small language mannequin optimized for top compute effectivity whereas sustaining robust accuracy on specialised duties. Nemotron 3 Nano performs strongly on coding and reasoning duties amongst open language fashions in its measurement class. Skilled utilizing multi-environment reinforcement studying by means of NeMo Gymnasium, the mannequin achieves 4x greater throughput than its predecessor Nemotron 2 Nano. Its environment friendly 3B energetic parameter footprint makes it excellent for high-volume, multi-agent workloads the place value and latency matter. For a deeper have a look at the structure and coaching strategies, see the NVIDIA developer weblog.
Nemotron 3 Tremendous 120B
Nemotron 3 Tremendous is a bigger mannequin designed for high-efficiency multi-agent AI and complicated reasoning duties that require extra capability than Nano whereas sustaining value effectivity. Nemotron 3 Tremendous delivers excessive compute effectivity, throughput, and accuracy for advanced multi-agent purposes resembling software program growth and cybersecurity triaging. The mannequin performs nicely at reasoning, coding, and long-context evaluation, whereas remaining environment friendly sufficient to run repeatedly at scale. This makes it match for IT ticket automation, enterprise workflow orchestration, and autonomous agent methods that require sustained multi-step reasoning. For extra particulars, see the NVIDIA developer weblog on Nemotron 3 Tremendous.
SageMaker AI serverless mannequin customization
Amazon SageMaker AI serverless mannequin customization removes the undifferentiated heavy lifting of fine-tuning. You don’t must provision GPU clusters, configure distributed coaching frameworks, or handle checkpointing and fault tolerance. SageMaker AI handles infrastructure provisioning and coaching orchestration, so you may focus in your knowledge, enterprise use case, and analysis, and pay just for what you utilize. You’ll be able to be taught extra about SageMaker AI serverless mannequin customization within the AWS documentation.
For Nemotron 3 fashions, SageMaker AI serverless mannequin customization helps the Supervised Nice-Tuning (SFT), Reinforcement Studying with Verifiable Rewards (RLVR) and Reinforcement Studying from AI Suggestions (RLAIF) fine-tuning strategies.
Method
Description
Finest For
Supervised Nice-Tuning (SFT)
Present labeled input-output pairs to show the mannequin new behaviors.
Excessive-quality examples of the habits you need: area Q&A pairs, formatted device calls, style-aligned responses, or task-specific instruction completions
Reinforcement Nice-Tuning (RFT / RLVR)
Use Reinforcement Studying with Verifiable Rewards (RLVR) to optimize mannequin habits in opposition to a reward sign. The mannequin generates a number of candidate responses per immediate, a reward perform scores them, and the mannequin updates its coverage to favor what works.
Duties with naturally verifiable goals like device calling accuracy, code correctness, or format compliance
Reinforcement Studying from AI Suggestions (RLAIF)
Use a separate AI mannequin to information the mannequin optimization. An AI mannequin evaluates mannequin outputs and gives suggestions alerts, which helps iterative coverage enchancment with out human-labeled reward knowledge.
Aligning mannequin tone, helpfulness, and security; enhancing response high quality when human analysis is dear or subjective; refining open-ended era duties
Let’s stroll by means of the way to get began with serverless mannequin customization for Nemotron 3 fashions. Whereas the bottom Nemotron 3 fashions ship robust general-purpose efficiency, enterprise use instances want domain-specific habits that base fashions alone can not obtain. With mannequin customization, you may adapt these fashions for industry-specific terminology and determination patterns, prepare dependable device calling together with your group’s APIs, align outputs together with your model voice, refine multi-step agentic reasoning to your architectures, and optimize value by specializing the smaller Nano mannequin to match bigger mannequin efficiency on focused duties.
Getting began with SageMaker AI serverless mannequin customization
You will get began with serverless mannequin customization by means of the Amazon SageMaker Studio console or programmatically utilizing the SageMaker Python SDK. On the console, navigate to the Fashions web page, choose your Nemotron 3 mannequin, and comply with the guided workflow to configure your coaching knowledge and launch a customization job. Alternatively, should you’re already working inside SageMaker AI, you need to use the agentic performance with agent expertise to speed up your mannequin customization workflow. The next sections stroll you thru the conditions, knowledge preparation, and step-by-step directions utilizing the SageMaker Studio console. For an in depth programmatic instance with the SageMaker Python SDK for customizing an open-source mannequin, see the AWS samples GitHub repository.
Conditions
Earlier than you start, confirm that you’ve:
An AWS account with AWS Id and Entry Administration (IAM) permissions for Amazon SageMaker AI.
A SageMaker AI area with Studio entry.
Your coaching knowledge within the required construction and format.
Put together your coaching knowledge for SageMaker AI serverless mannequin customization
Excessive-quality coaching knowledge is the inspiration of any profitable fine-tuning job. For serverless mannequin customization on SageMaker AI, your knowledge should be formatted as JSONL (JSON Traces), the place every line represents a single coaching instance. The particular schema is determined by the method you select: SFT requires conversation-format examples with labeled input-output pairs, whereas RFT (RLVR) requires prompts paired with floor reality values to your reward perform. Correctly structured knowledge ensures the mannequin learns the behaviors you plan with out introducing noise or formatting errors. For a hands-on walkthrough of making ready your coaching knowledge, see the Information Preparation module within the SageMaker AI serverless mannequin customization workshop. Alternatively, if you’re working with SageMaker AI, you need to use the built-in coding agent with agent expertise to mechanically put together and validate your knowledge formatting, decreasing handbook effort and serving to you get to coaching sooner.
Mannequin customization in SageMaker AI Studio
Observe these steps to customise a Nemotron 3 mannequin utilizing the SageMaker AI Studio console.
Open Amazon SageMaker AI Studio and within the left navigation pane, select Fashions.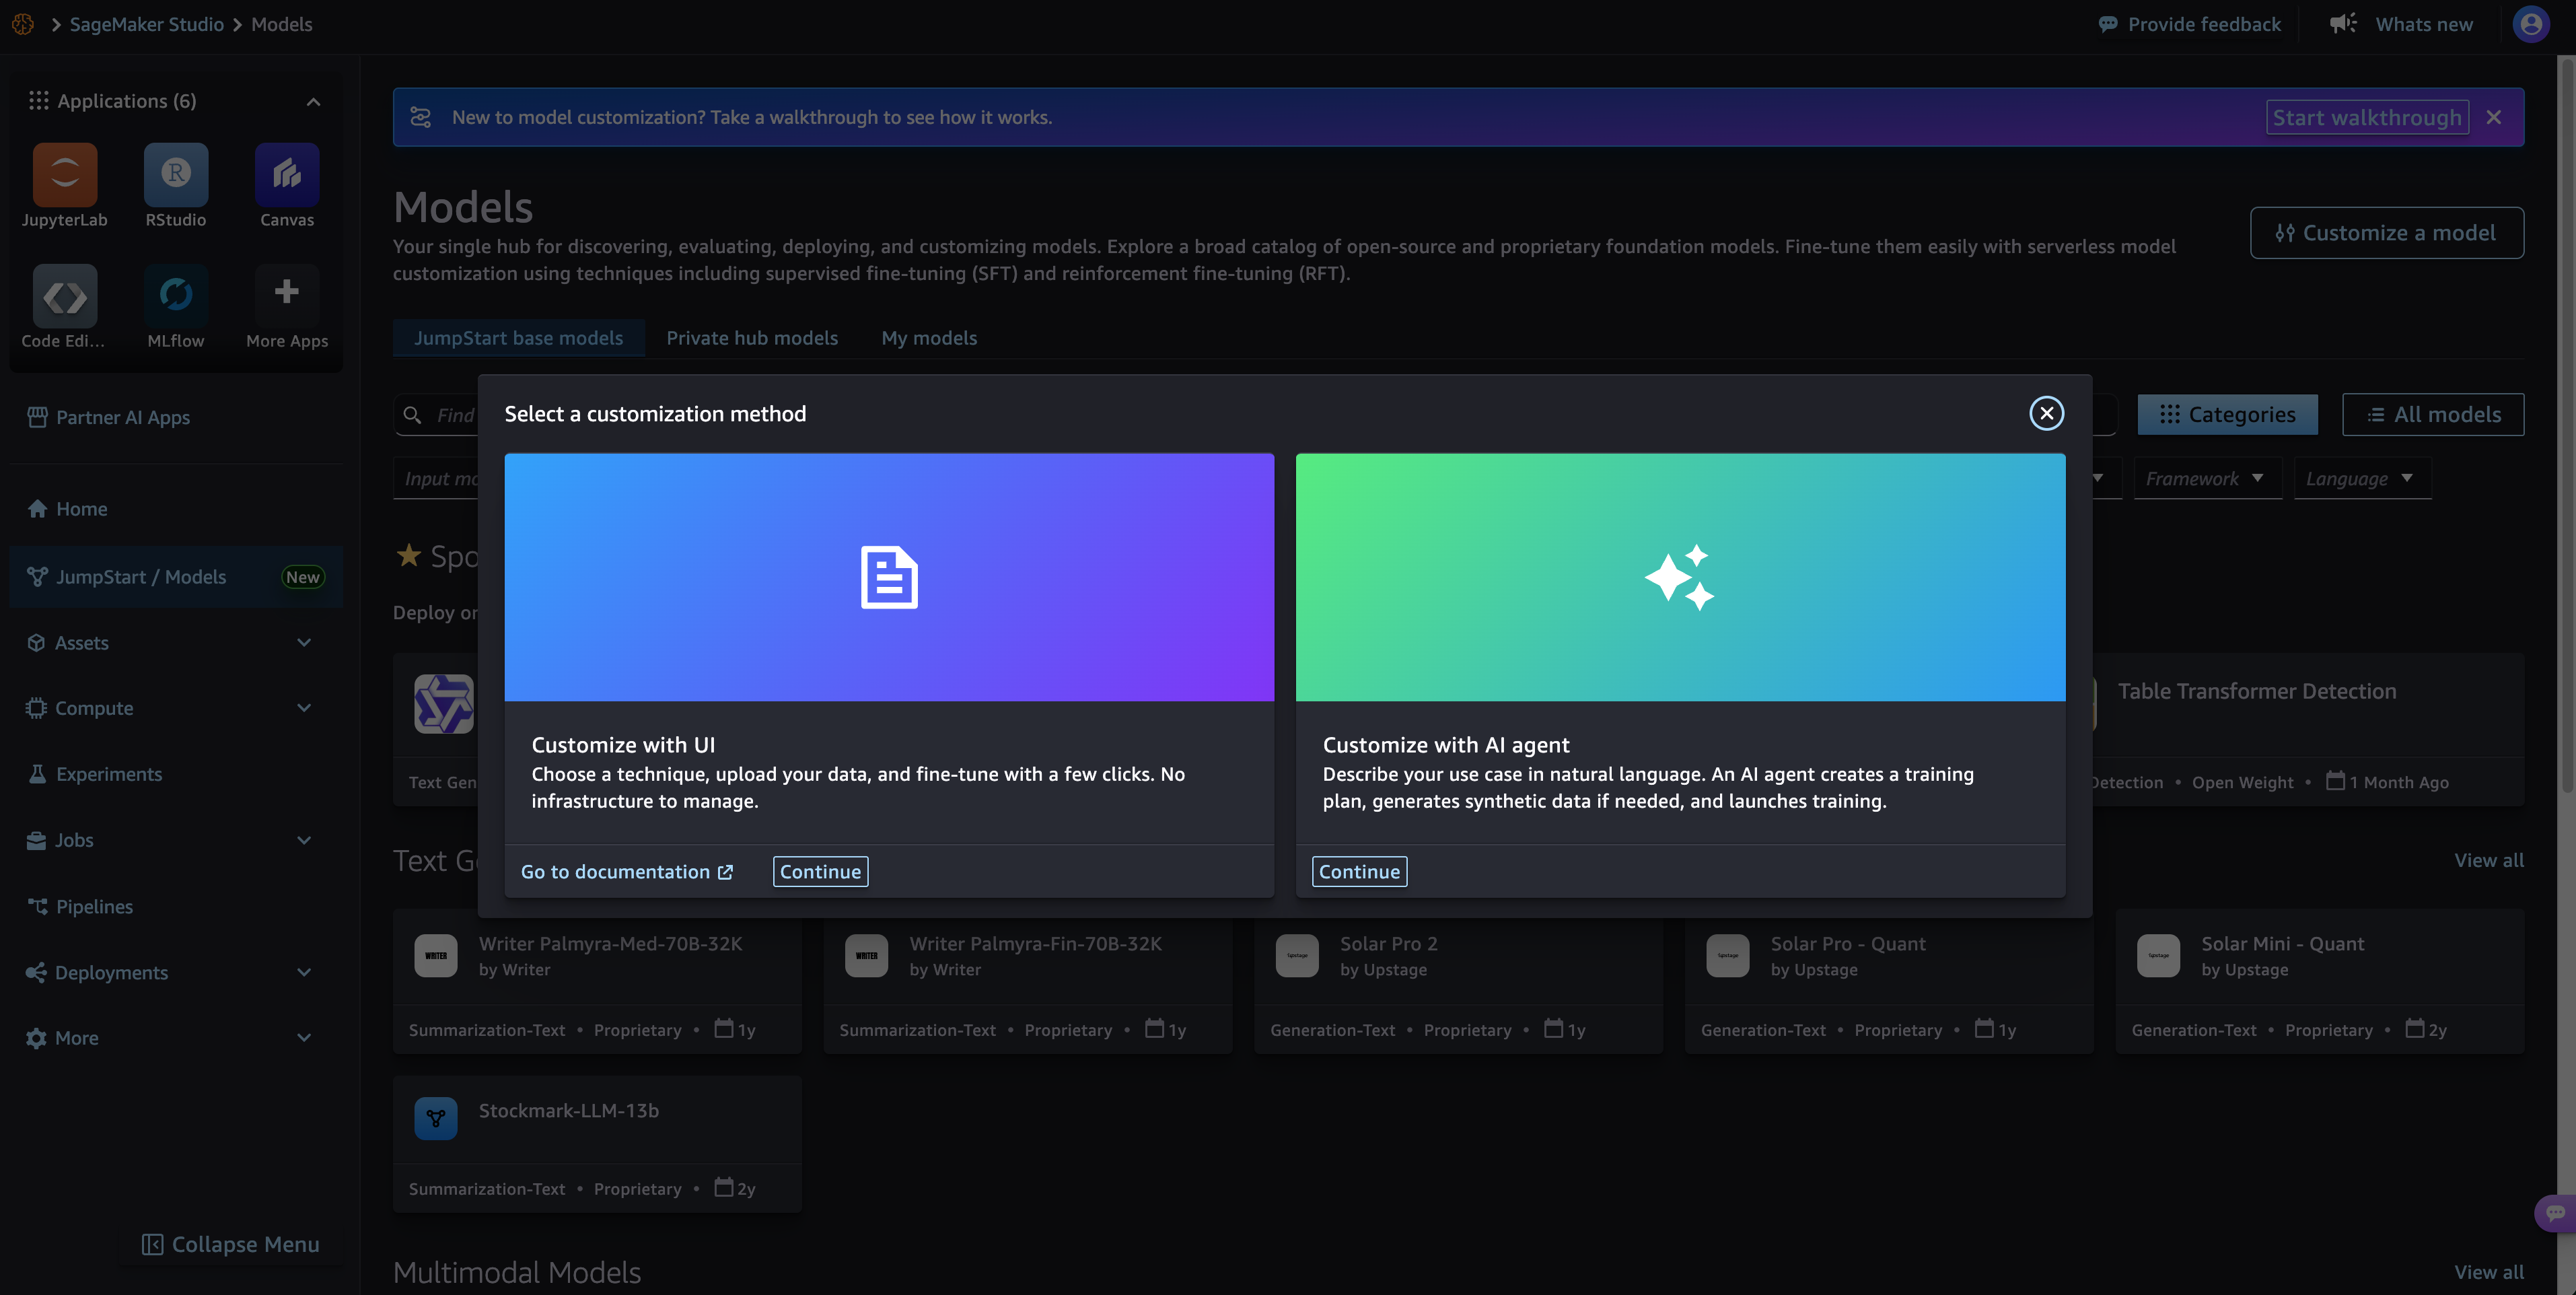
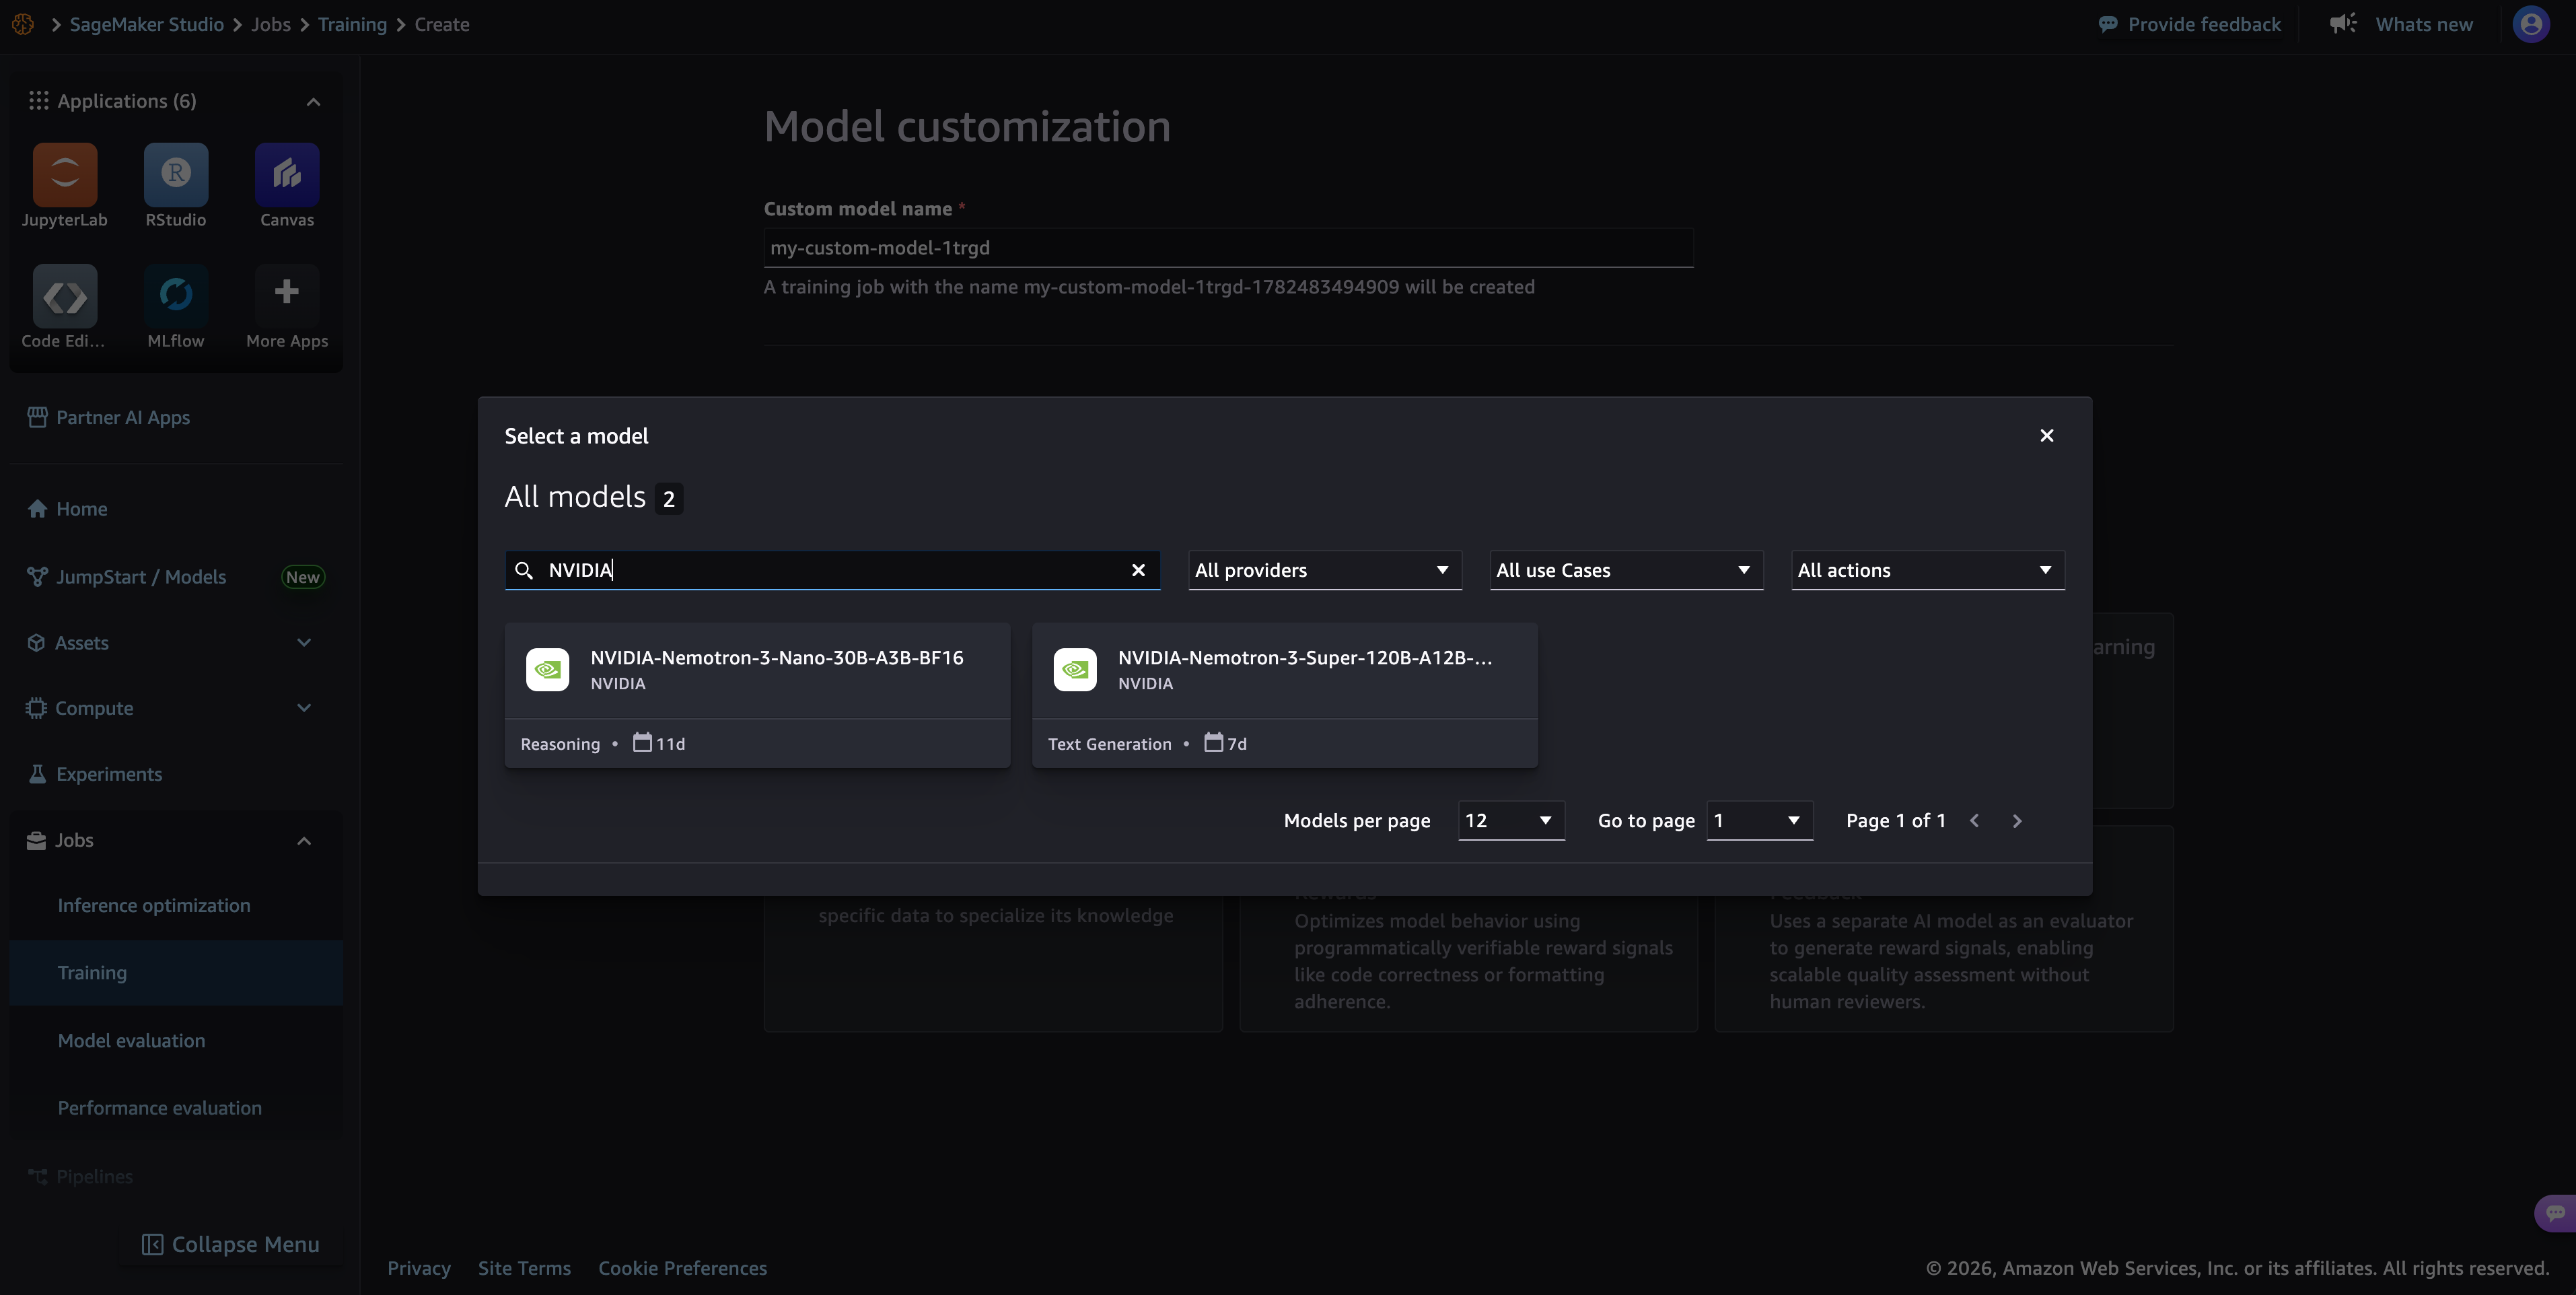
Navigate to the mannequin you wish to customise within the UI. Seek for “NVIDIA” to search out the Nemotron 3 household of fashions, and choose the NVIDIA mannequin that you really want (NVIDIA-Nemotron-3-Nano-30B-* or NVIDIA-Nemotron-3-Tremendous-120B-*) for the following step.
Choose your mannequin customization method from the supported Supervised Nice-Tuning (SFT), Reinforcement Studying with Verifiable Rewards (RLVR) and Reinforcement Studying from AI Suggestions (RLAIF) fine-tuning strategies.
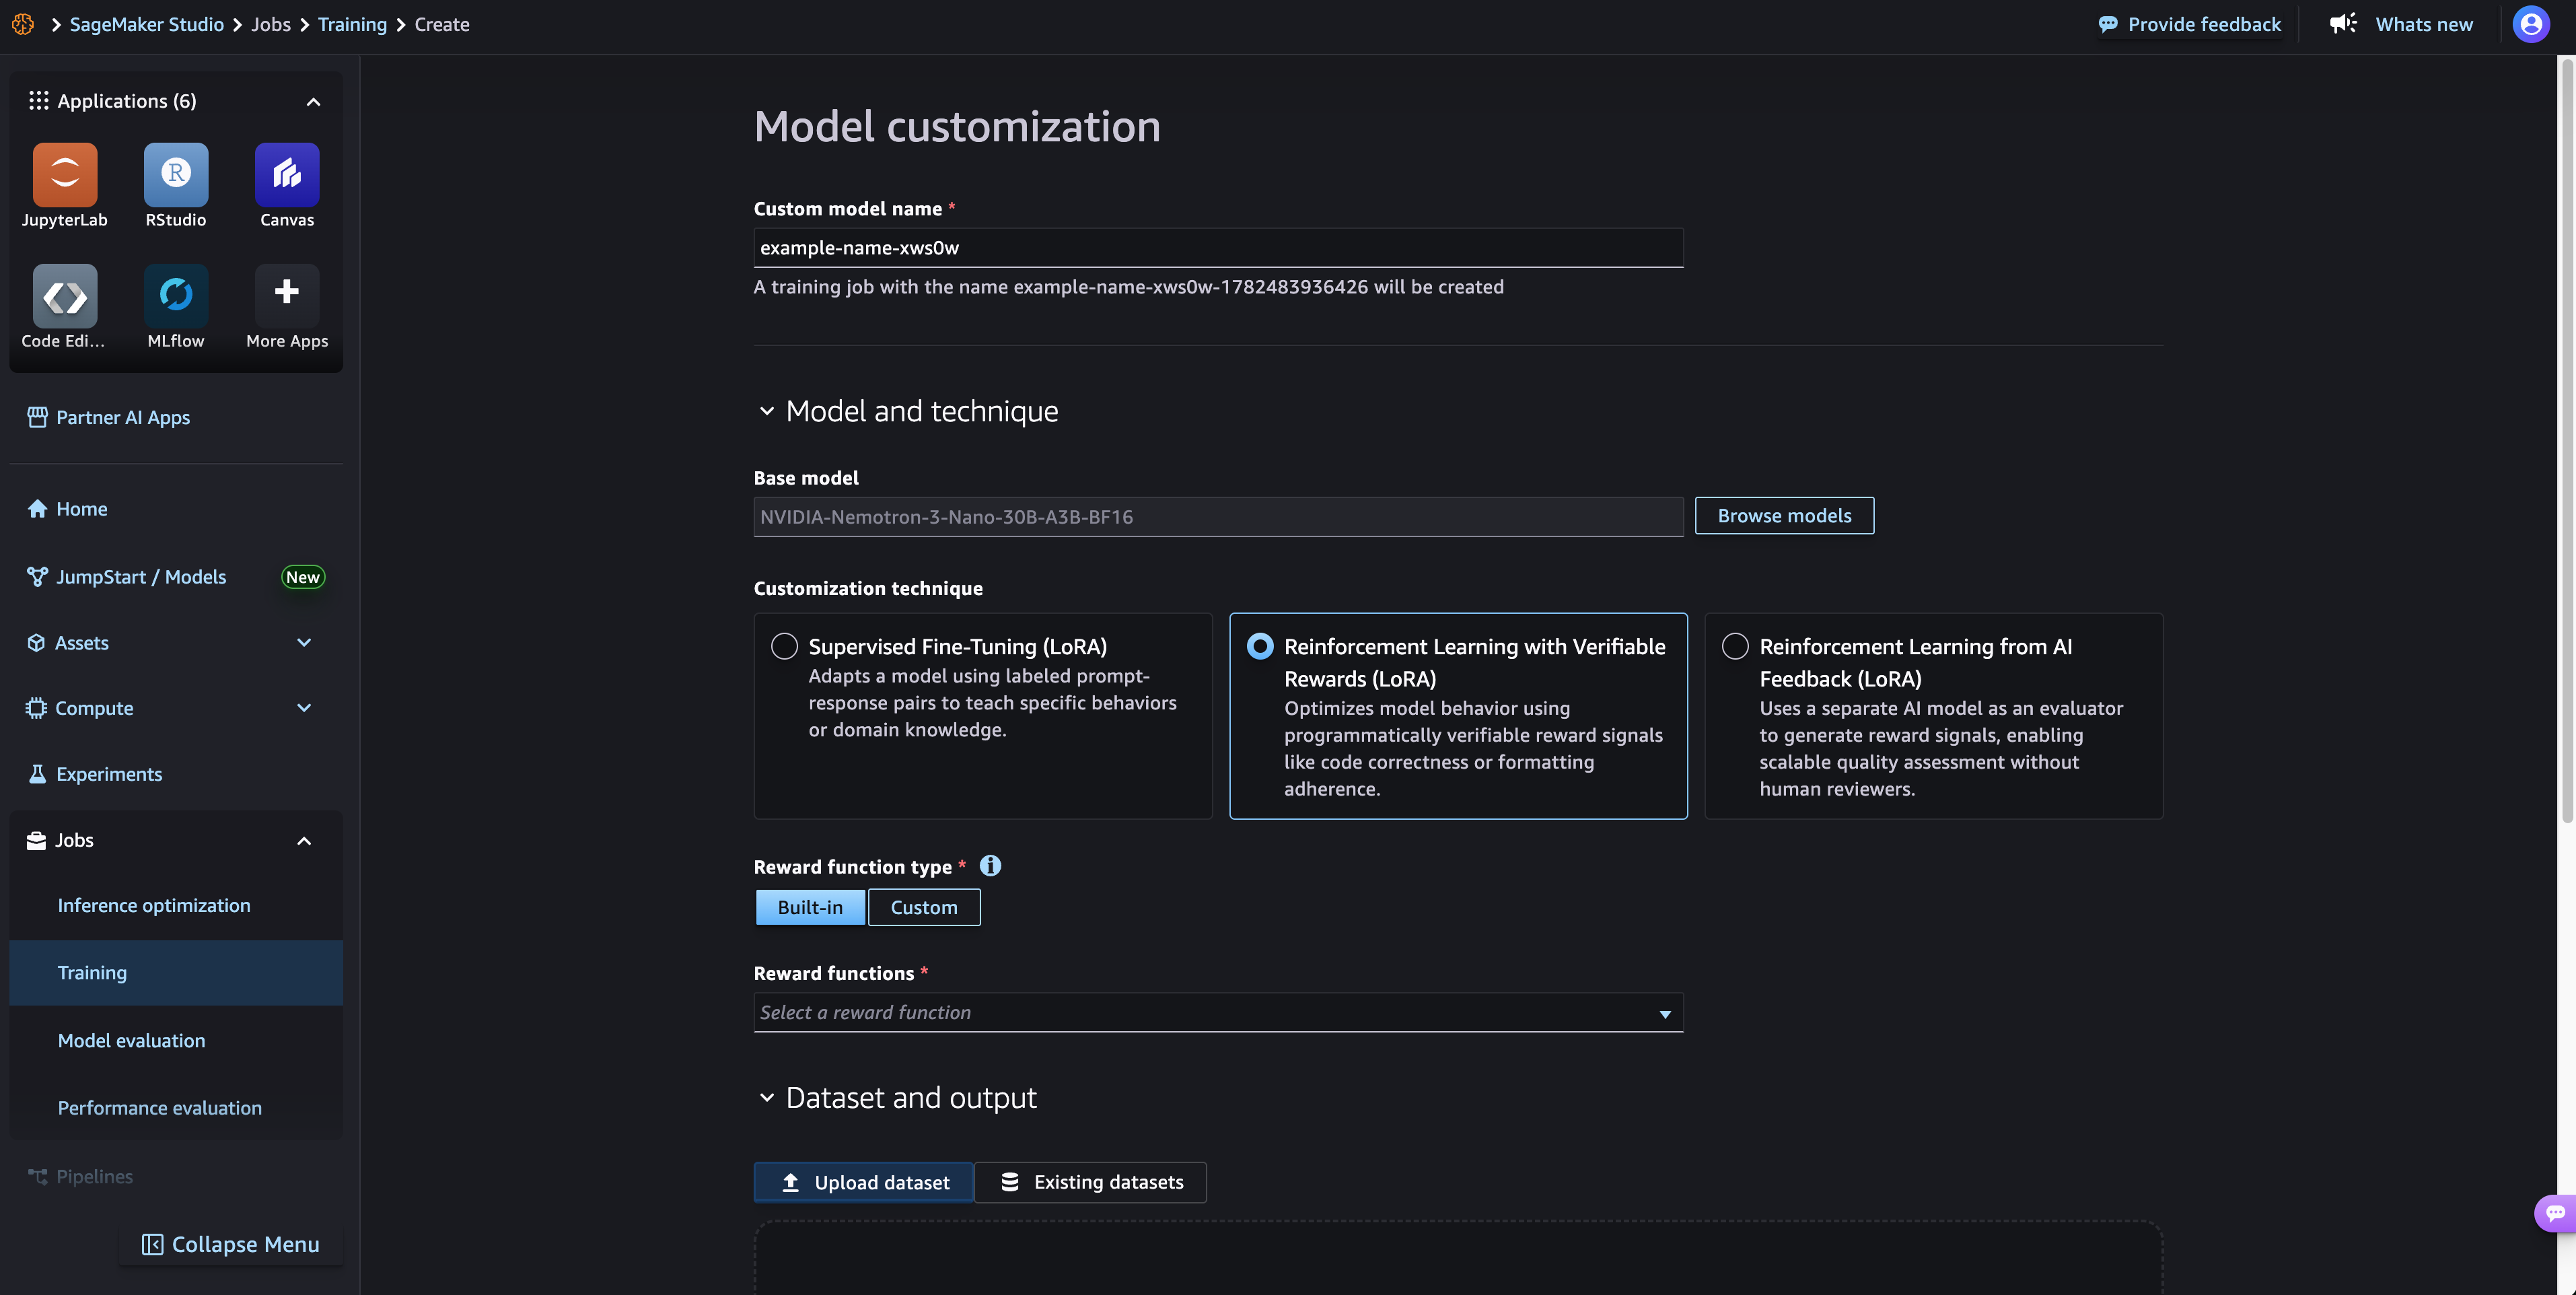 When selecting a reward perform kind for RLVR, contemplate your activity necessities. The built-in reward perform (Precise Match, Code Execution, Math Solutions) works nicely for duties with single, objectively appropriate solutions, requiring no further code. Select a customized reward perform when your activity wants richer scoring logic, resembling partial credit score, format checks, reasoning high quality analysis, or domain-specific guidelines. With customized reward features, you may rating on a number of alerts, form rewards to keep away from all-zero gradients on early rollouts, emit observability metrics, and encode the Python verification logic your activity requires. For detailed steering on authoring and registering a customized reward perform, see the RLVR workshop documentation.
Configure your coaching knowledge by deciding on an present dataset (if accessible) or creating a brand new dataset (see the previous part for details about making ready your dataset).
Set the customization hyperparameters or use advisable defaults.
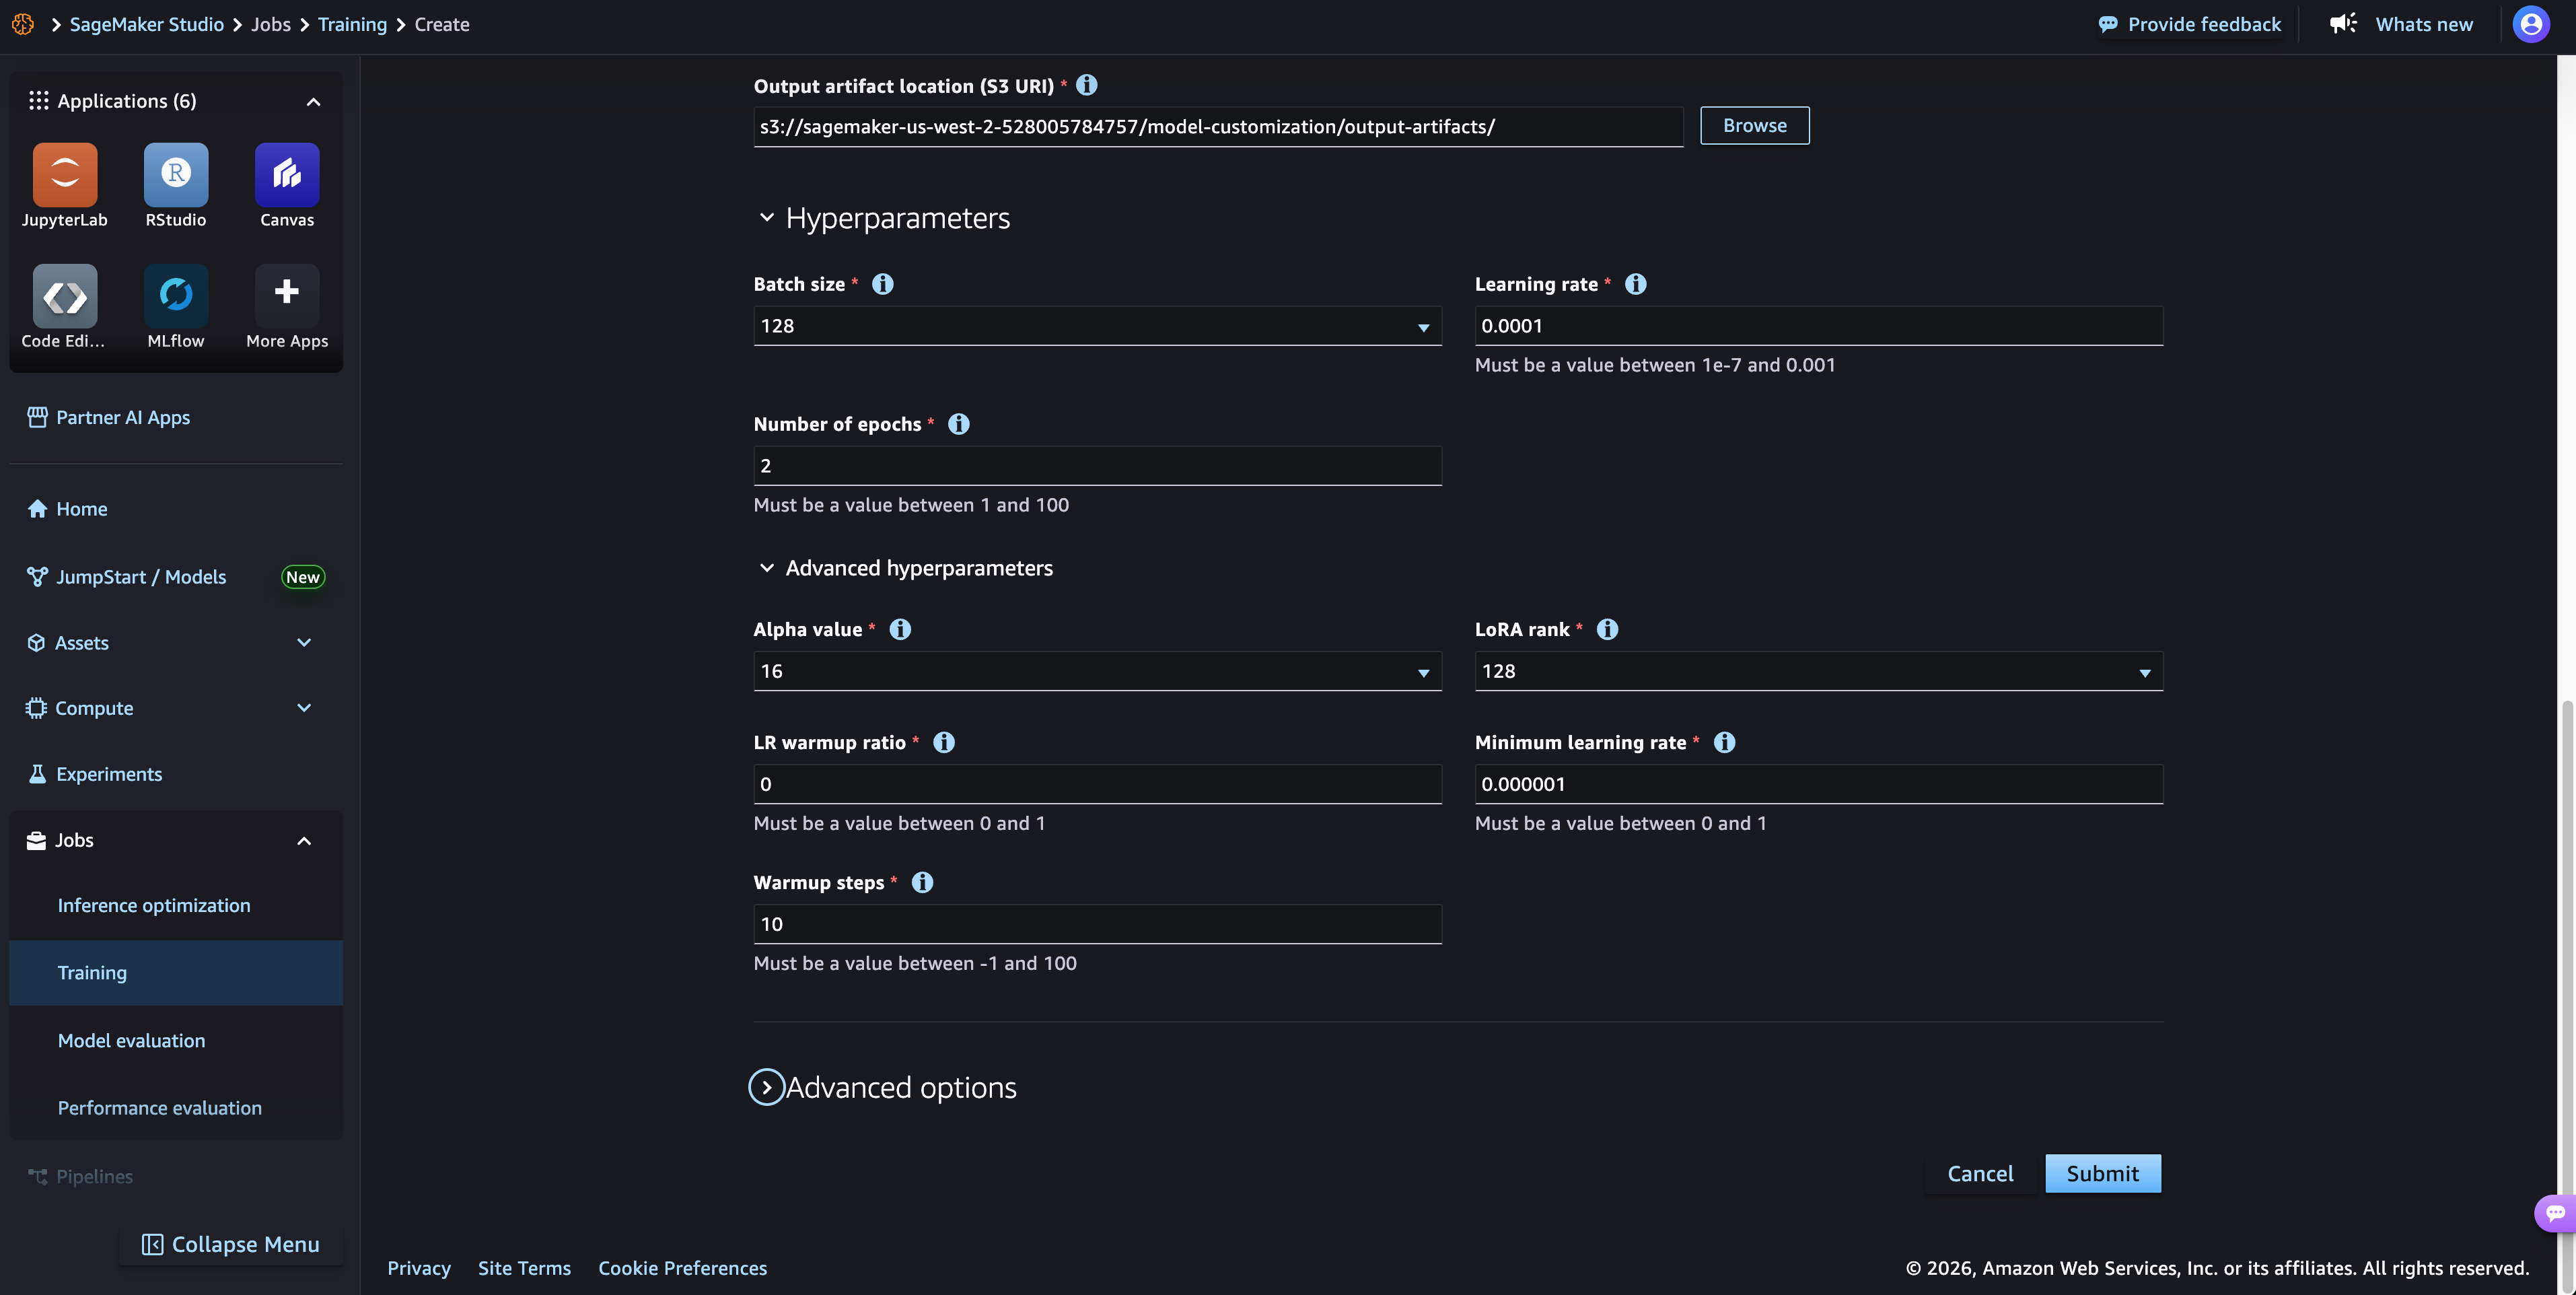
Select Undergo launch the mannequin customization job.
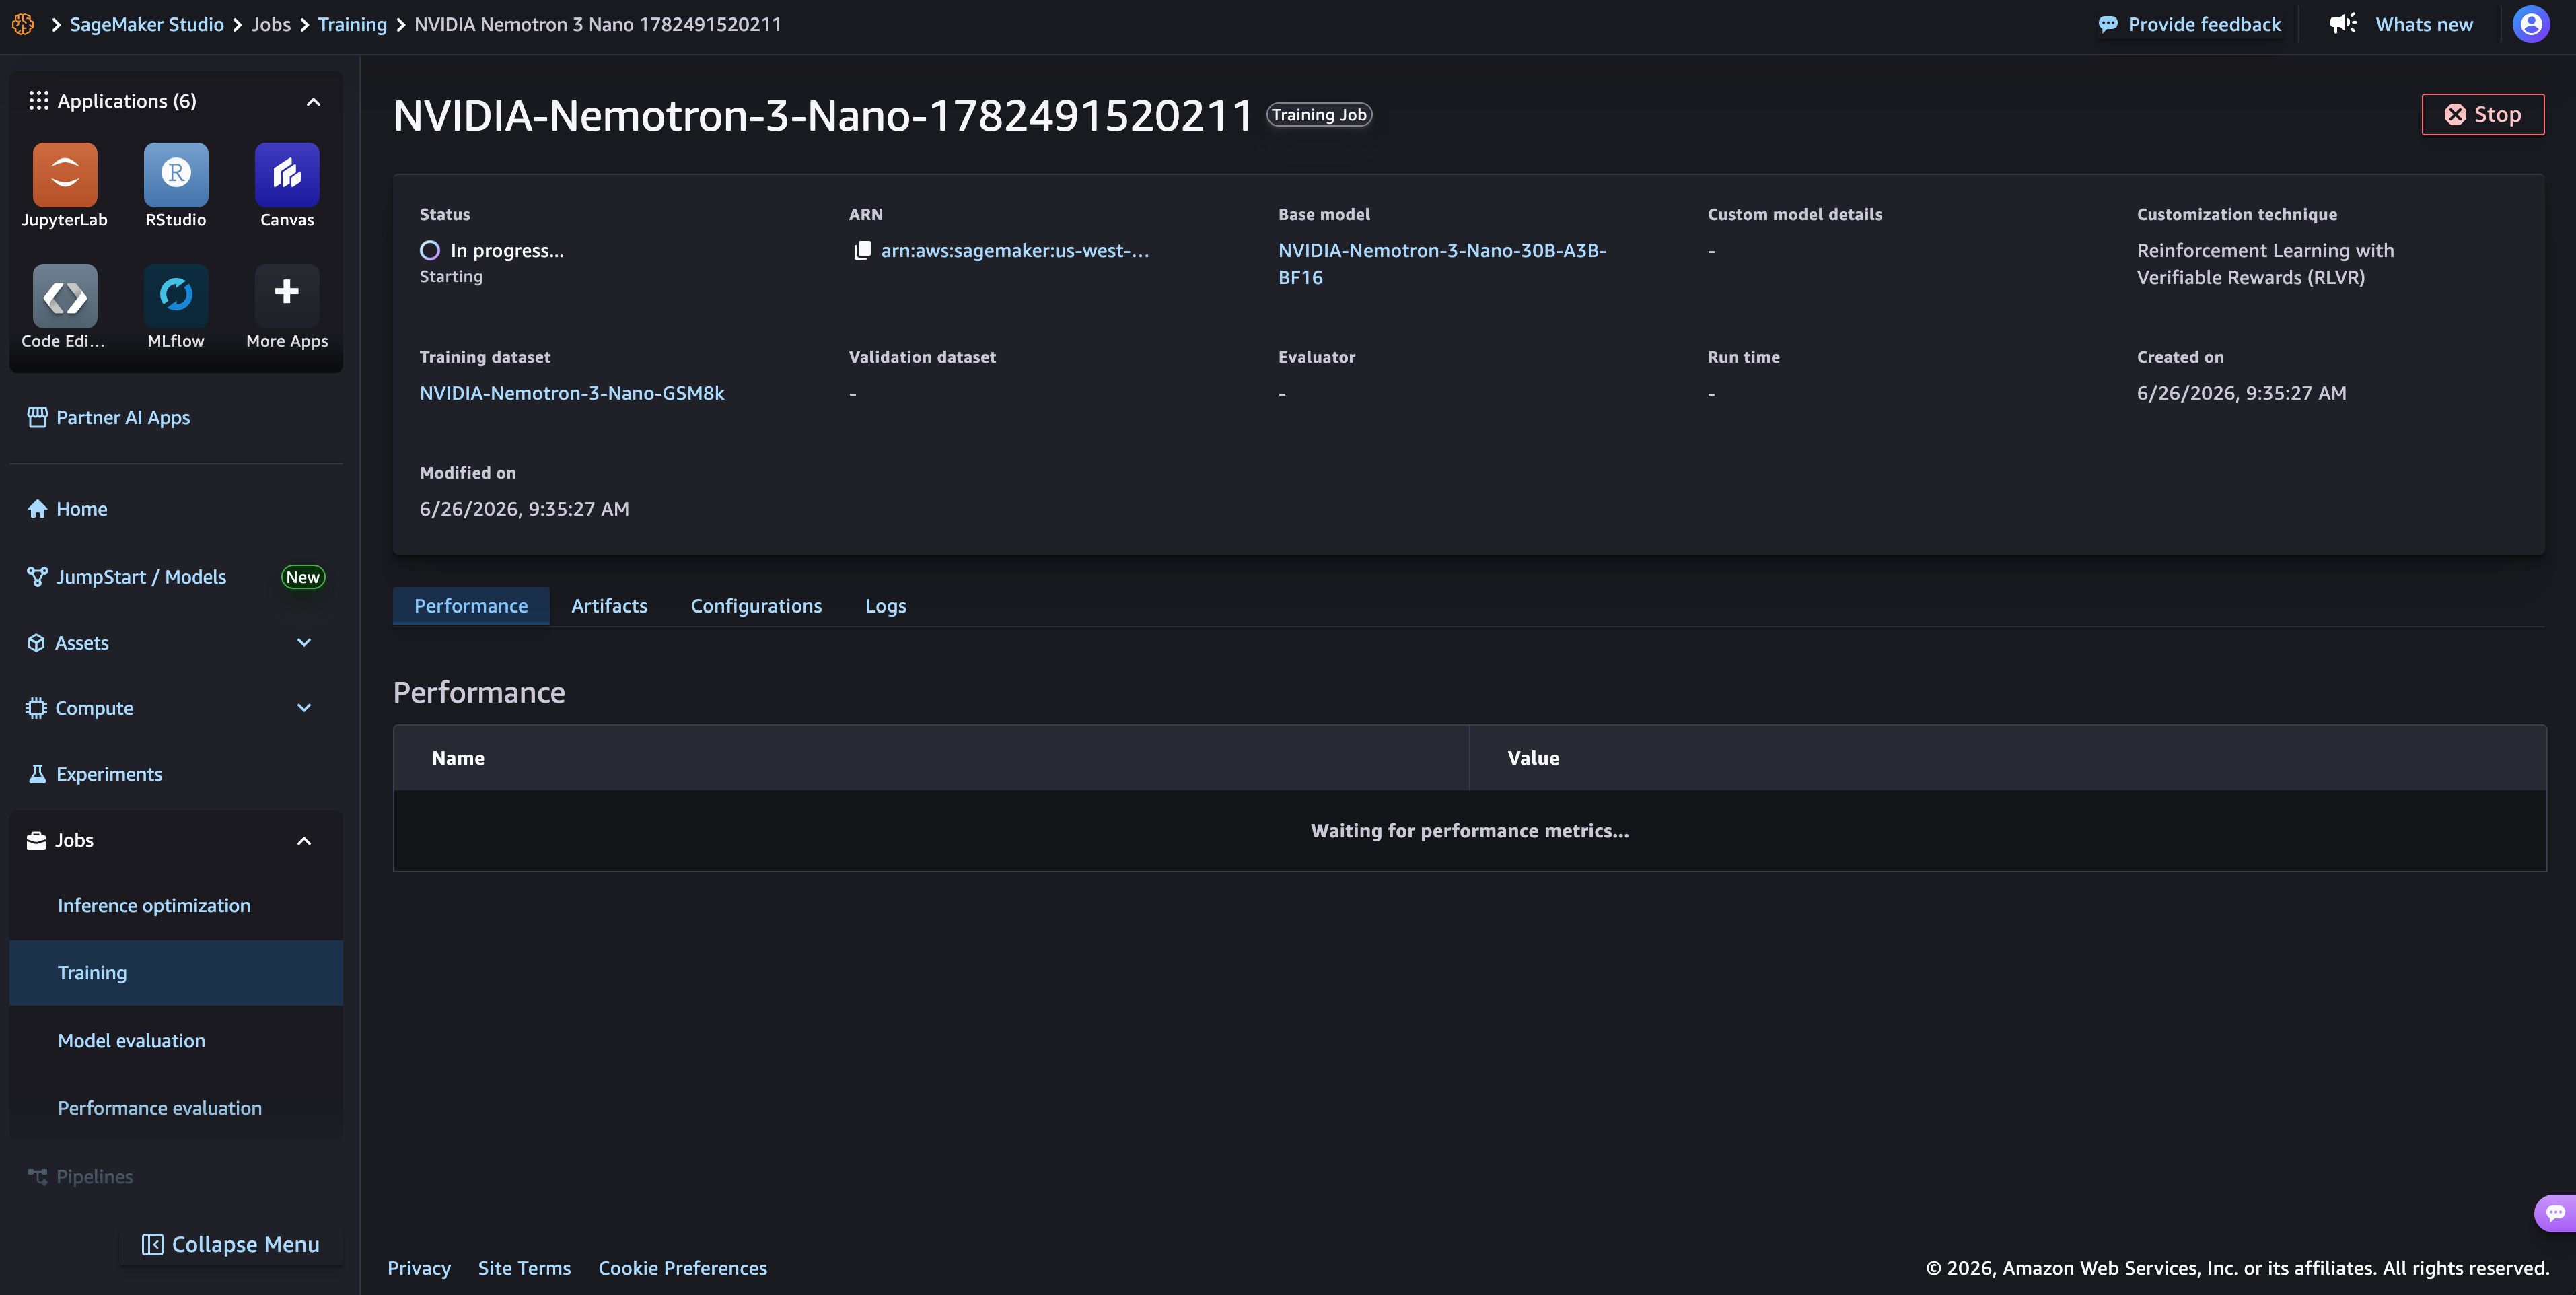
SageMaker AI mechanically provisions the required compute, executes the coaching job, and captures steady logs. The coaching metrics are mechanically logged to the SageMaker MLflow App by default for coaching monitoring.
Monitor coaching progress
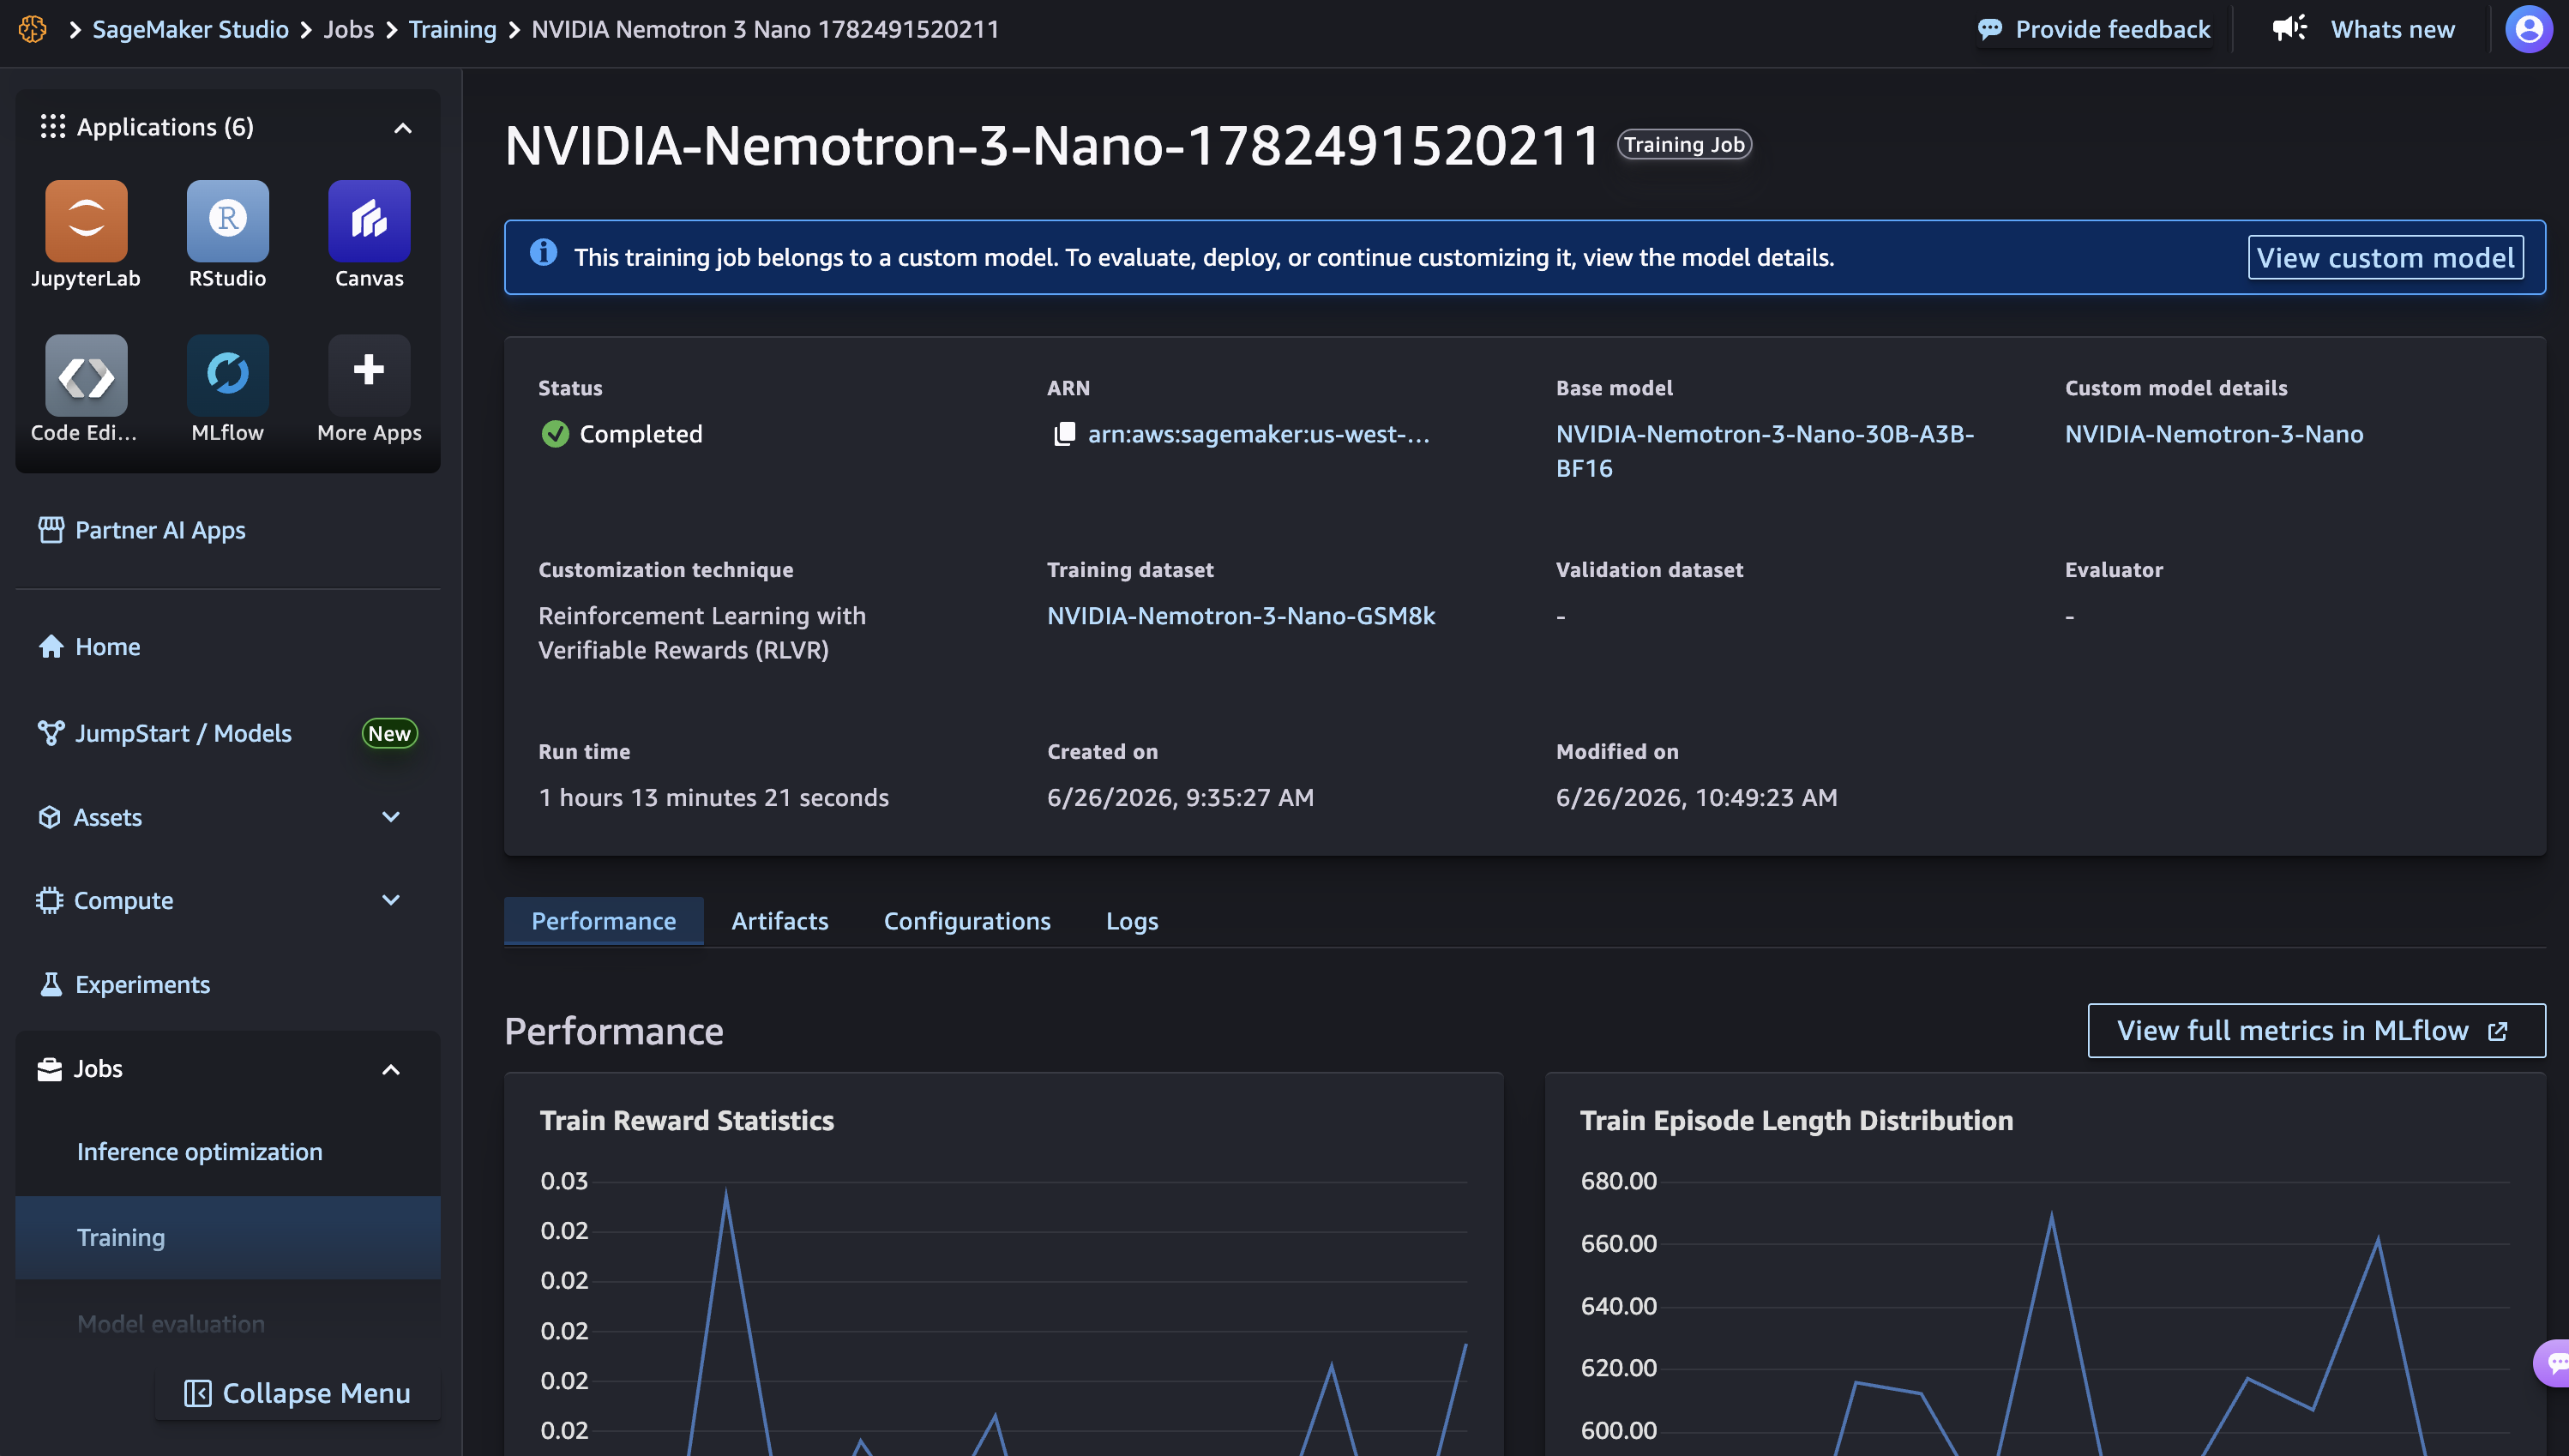
You’ll be able to monitor the standing on the mannequin residence web page, which shows coaching efficiency, as proven within the following screenshot. A number of high-level metrics are value monitoring. Prepare Reward (for RLVR) ought to enhance steadily. Coaching Loss and Validation Loss ought to lower and monitor generalization, respectively. Coverage Entropy (for RLVR) decreases because the mannequin features confidence. Gradient Norm ought to stabilize to point convergence.
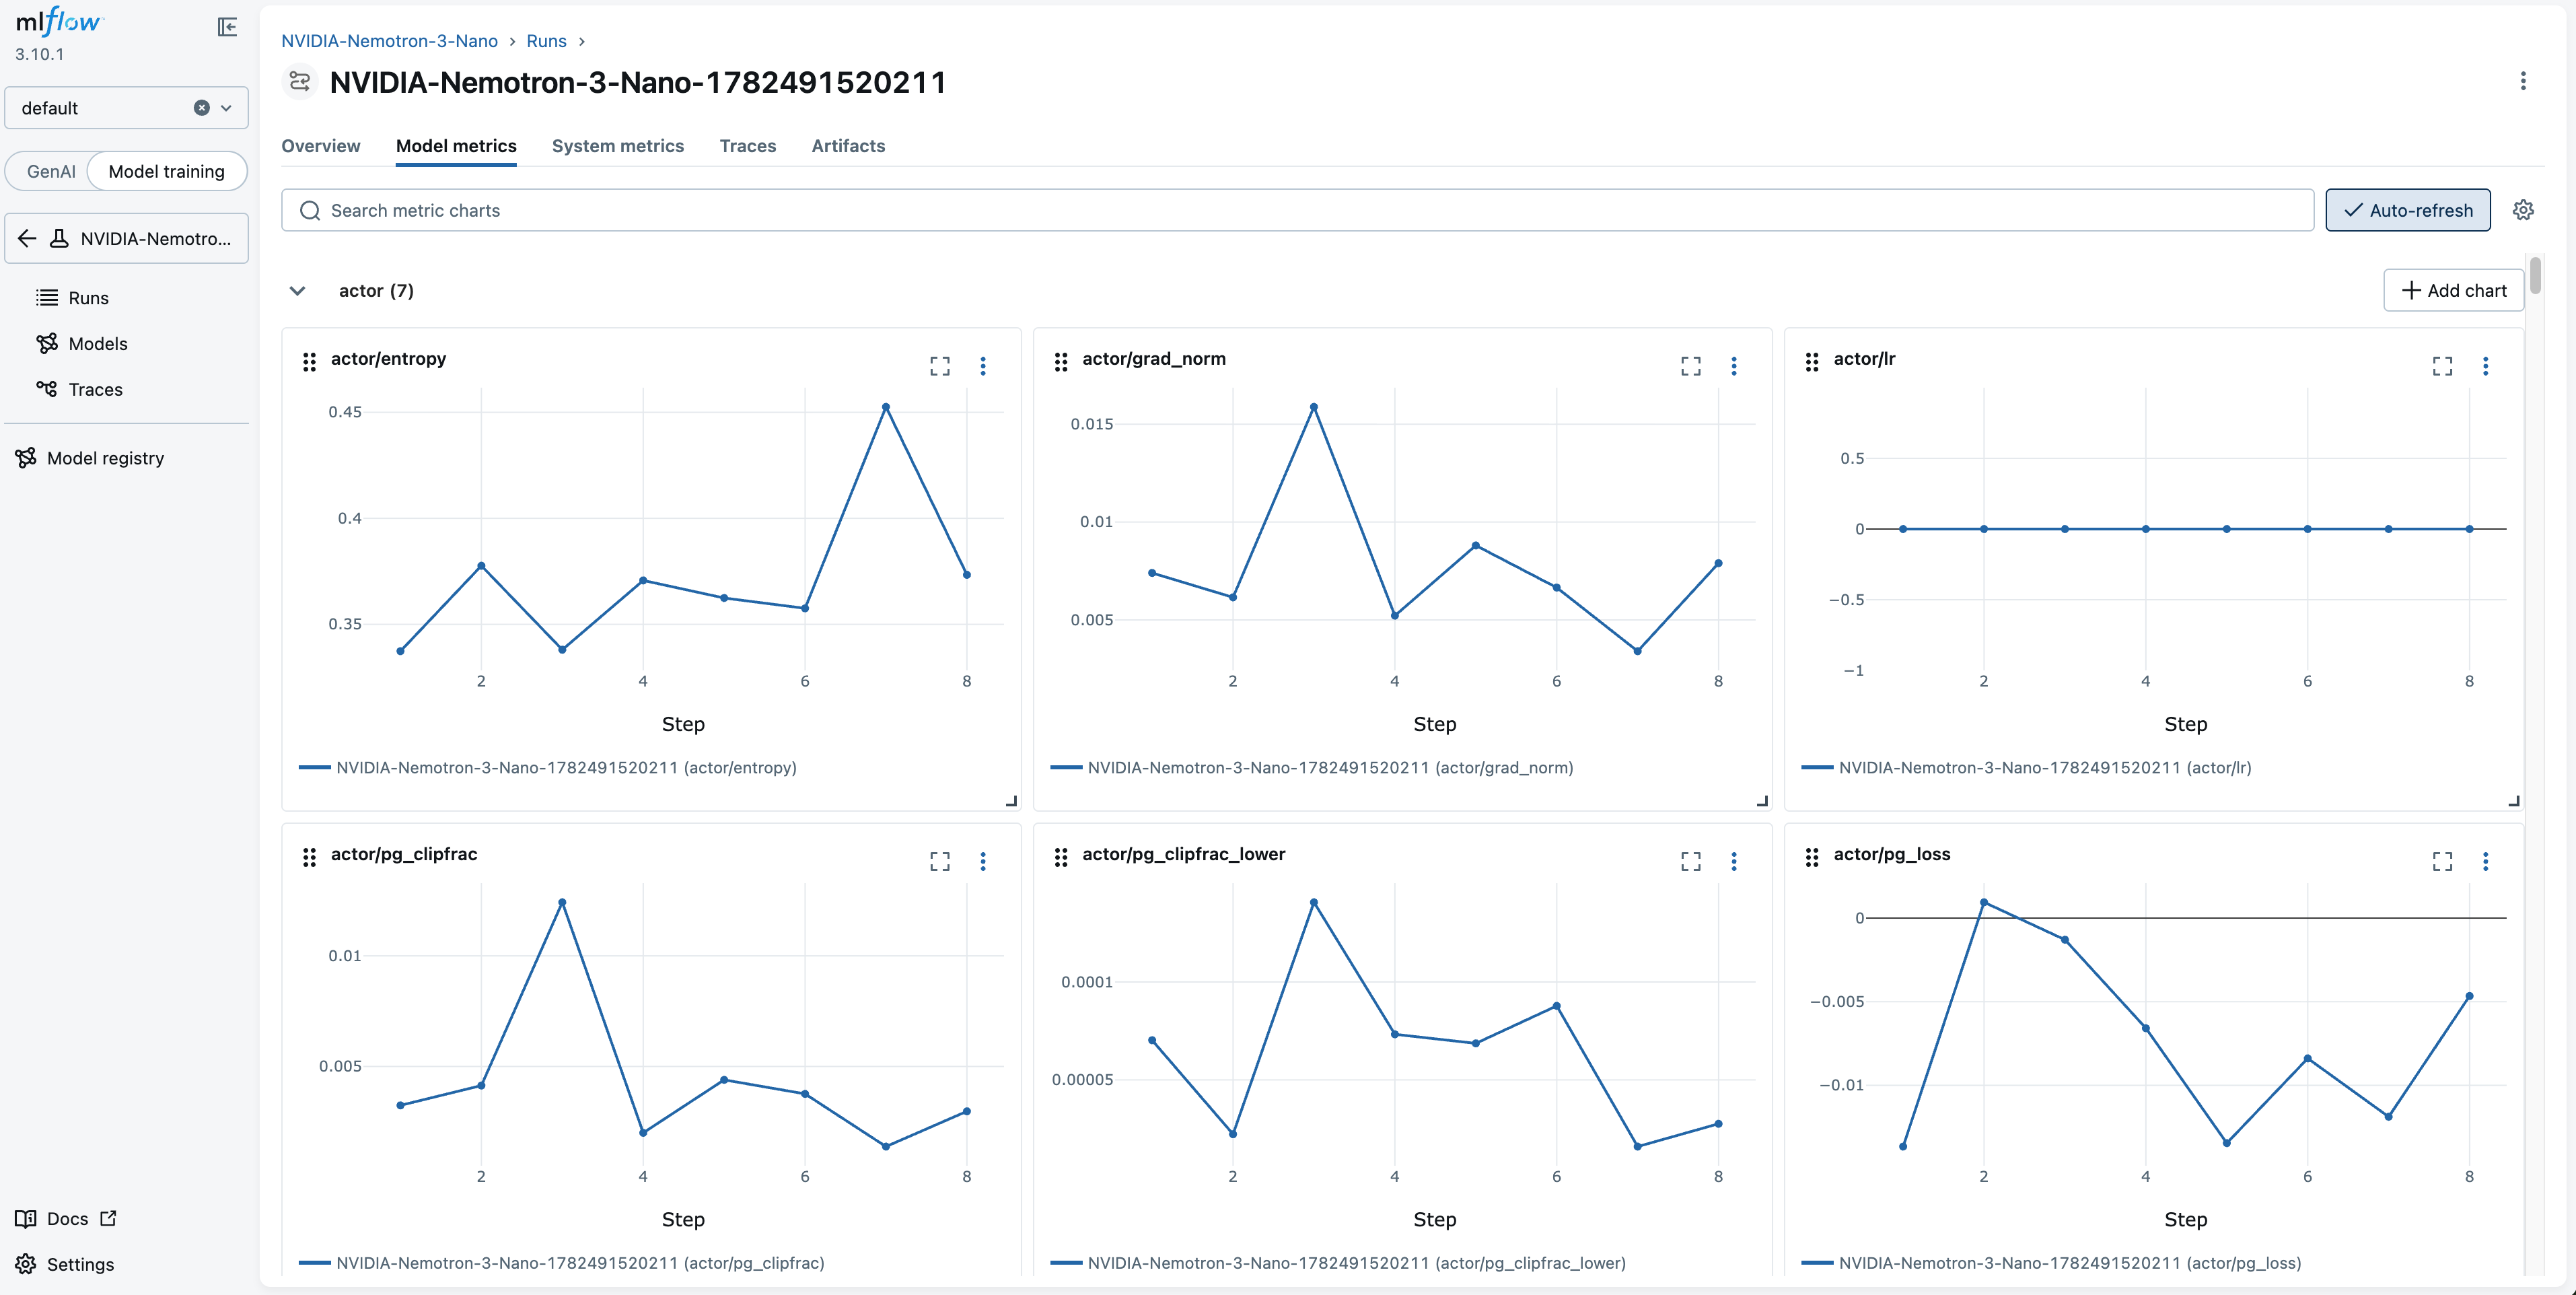
The detailed coaching and validation metrics are additionally logged to the related SageMaker AI MLflow App, as proven within the following screenshot. This captures a complete set of metrics and parameters that monitor coaching progress, and mannequin habits. Within the MLflow monitoring UI, these metrics are organized by the part they measure (actor, critic, rollout, efficiency), so you may diagnose coaching well being at a look.
Consider your fine-tuned mannequin
After coaching completes, you may consider the fine-tuned mannequin utilizing the built-in analysis options of SageMaker AI serverless mannequin customization. It gives three strategies to evaluate the standard of your personalized mannequin, as proven within the following screenshot. LLM-as-a-Choose makes use of an Amazon Bedrock frontier mannequin to grade responses in opposition to high quality metrics with out requiring ground-truth labels. Customized Scorer applies your personal reward features or built-in scorers to supply normal pure language processing (NLP) metrics resembling F1, ROUGE, and BLEU. Benchmarks scores your mannequin on standardized tutorial benchmarks (MMLU, BBH, GPQA, MATH, IFEval) for broad functionality evaluation throughout reasoning, data, and instruction-following.
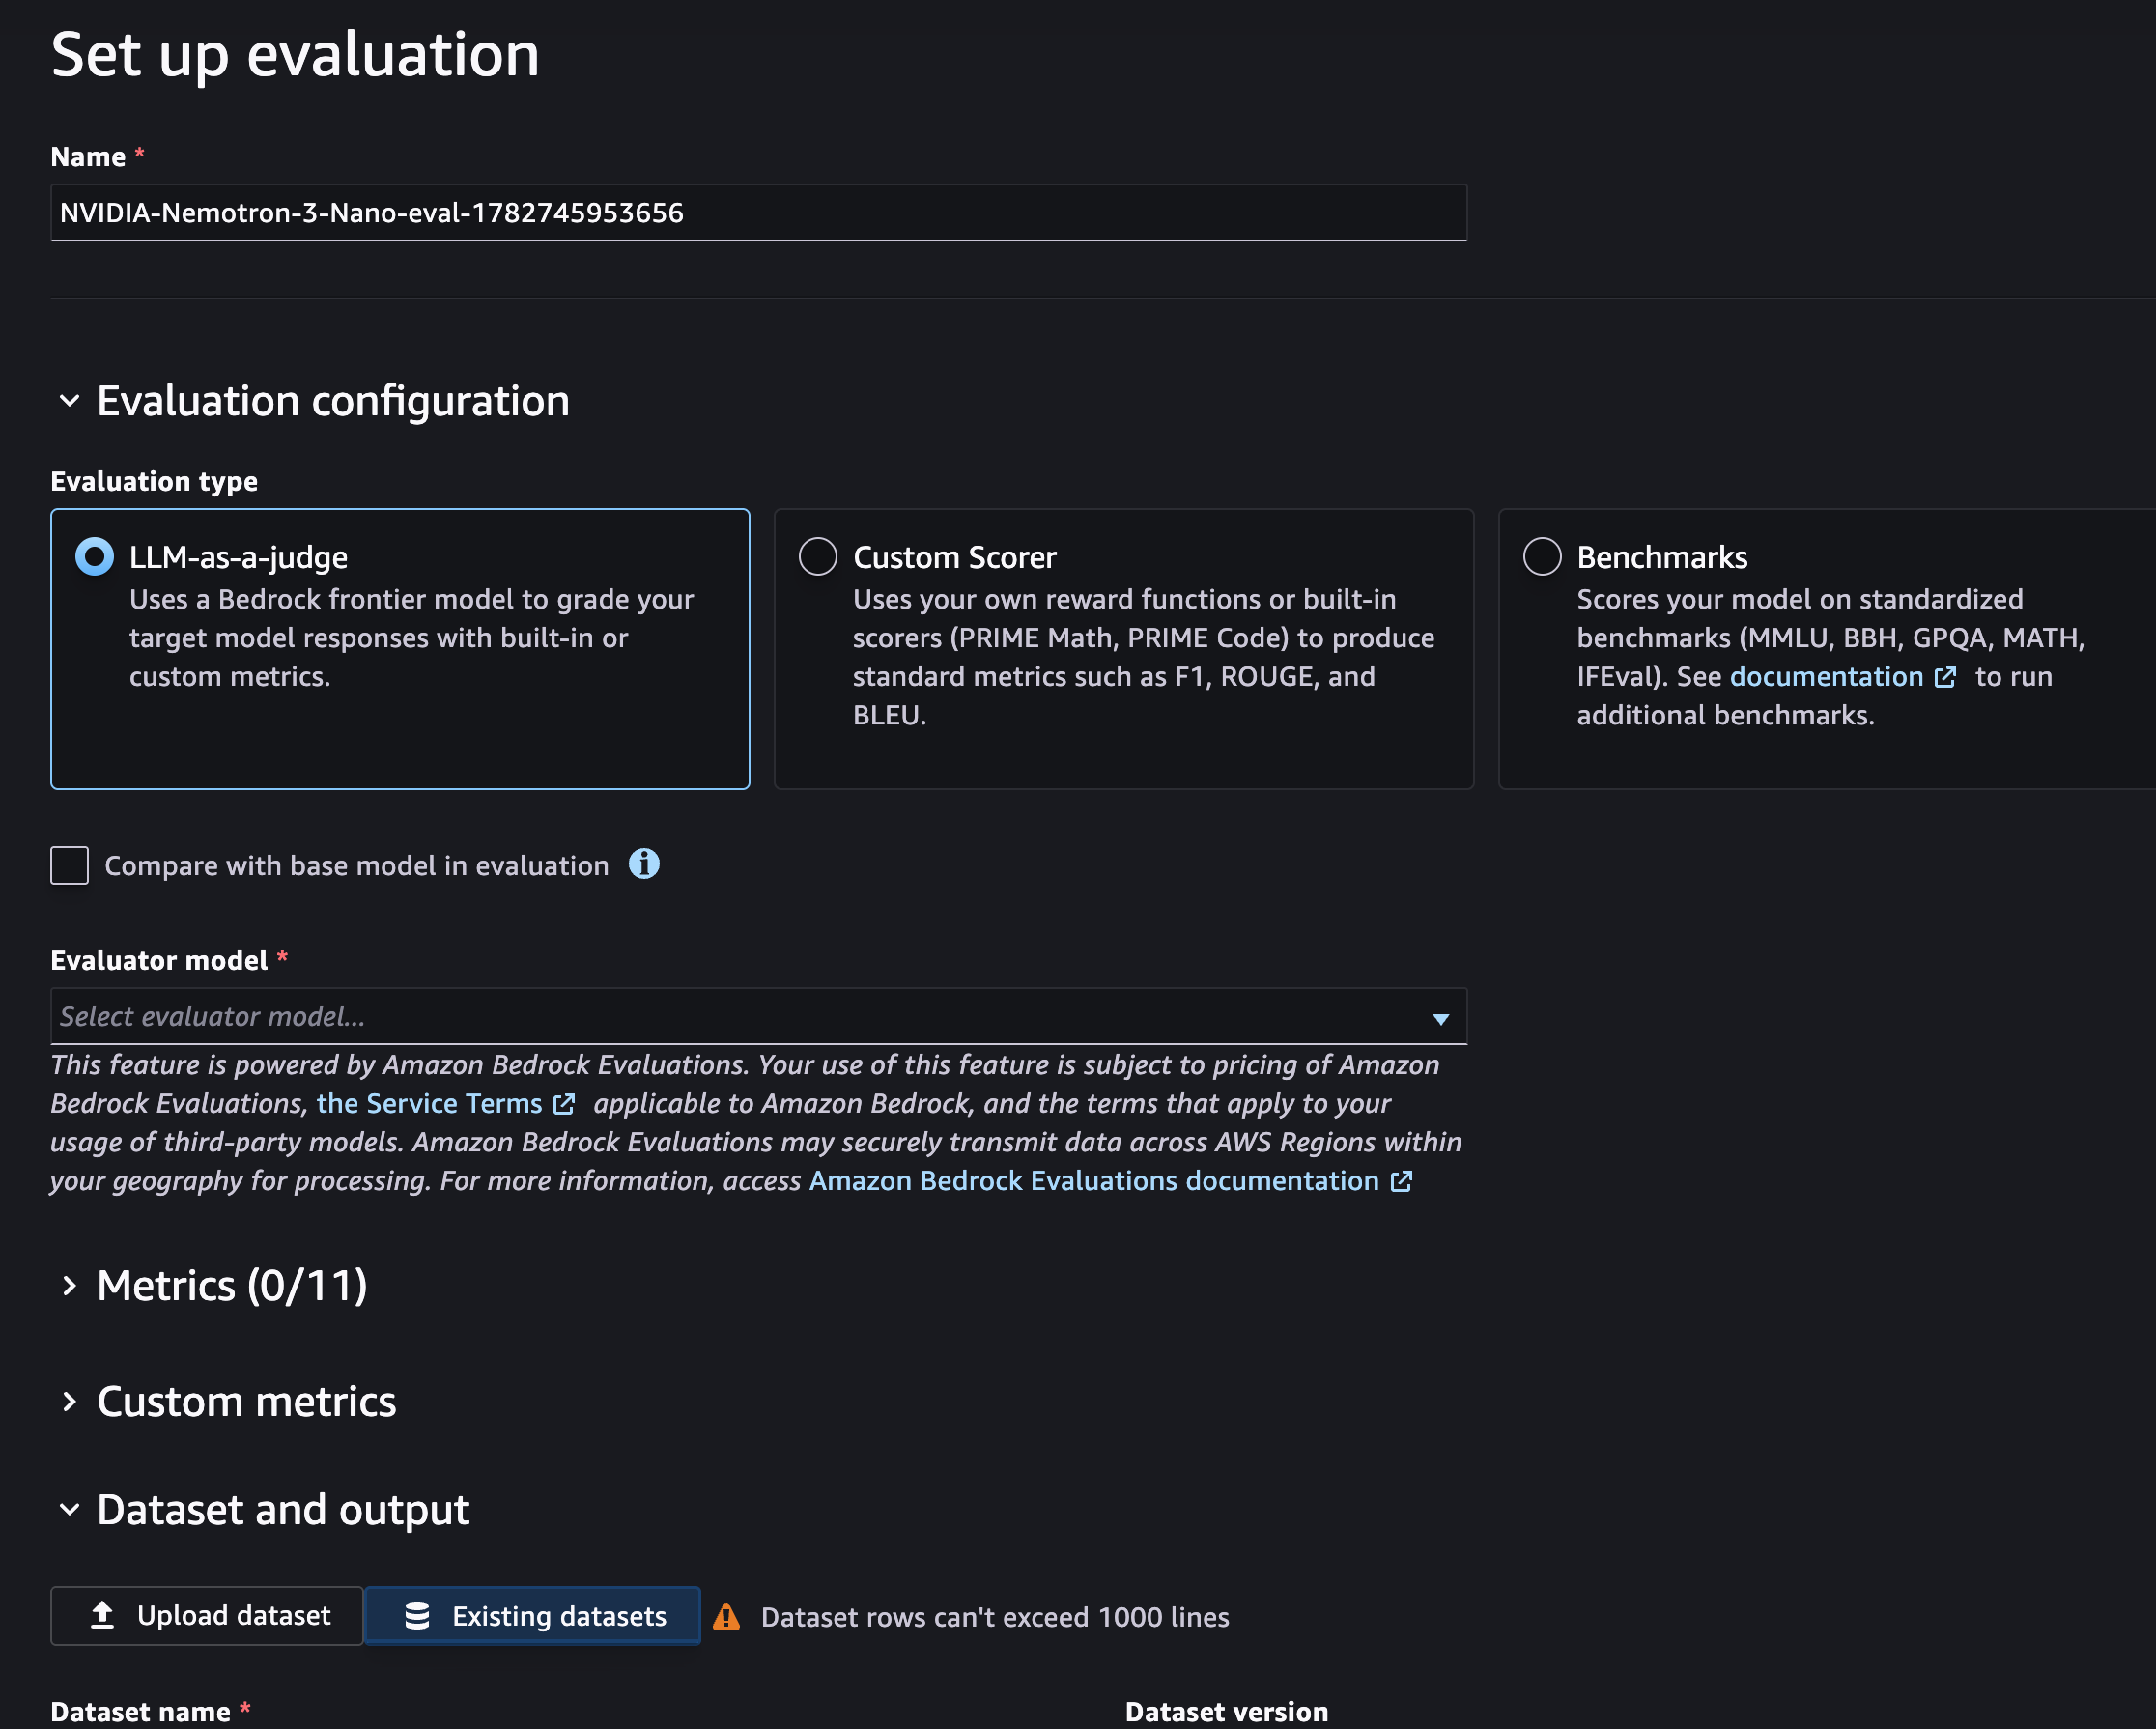
You can even activate Evaluate with base mannequin in analysis to straight measure how your post-trained mannequin performs relative to the bottom mannequin. Along with the earlier coaching metrics, MLflow tracks the coaching dynamics (rewards, KL divergence, loss). The analysis measures output high quality from an end-user perspective, providing you with an entire image of the mannequin fine-tuning effectiveness.
Deploy the fine-tuned mannequin
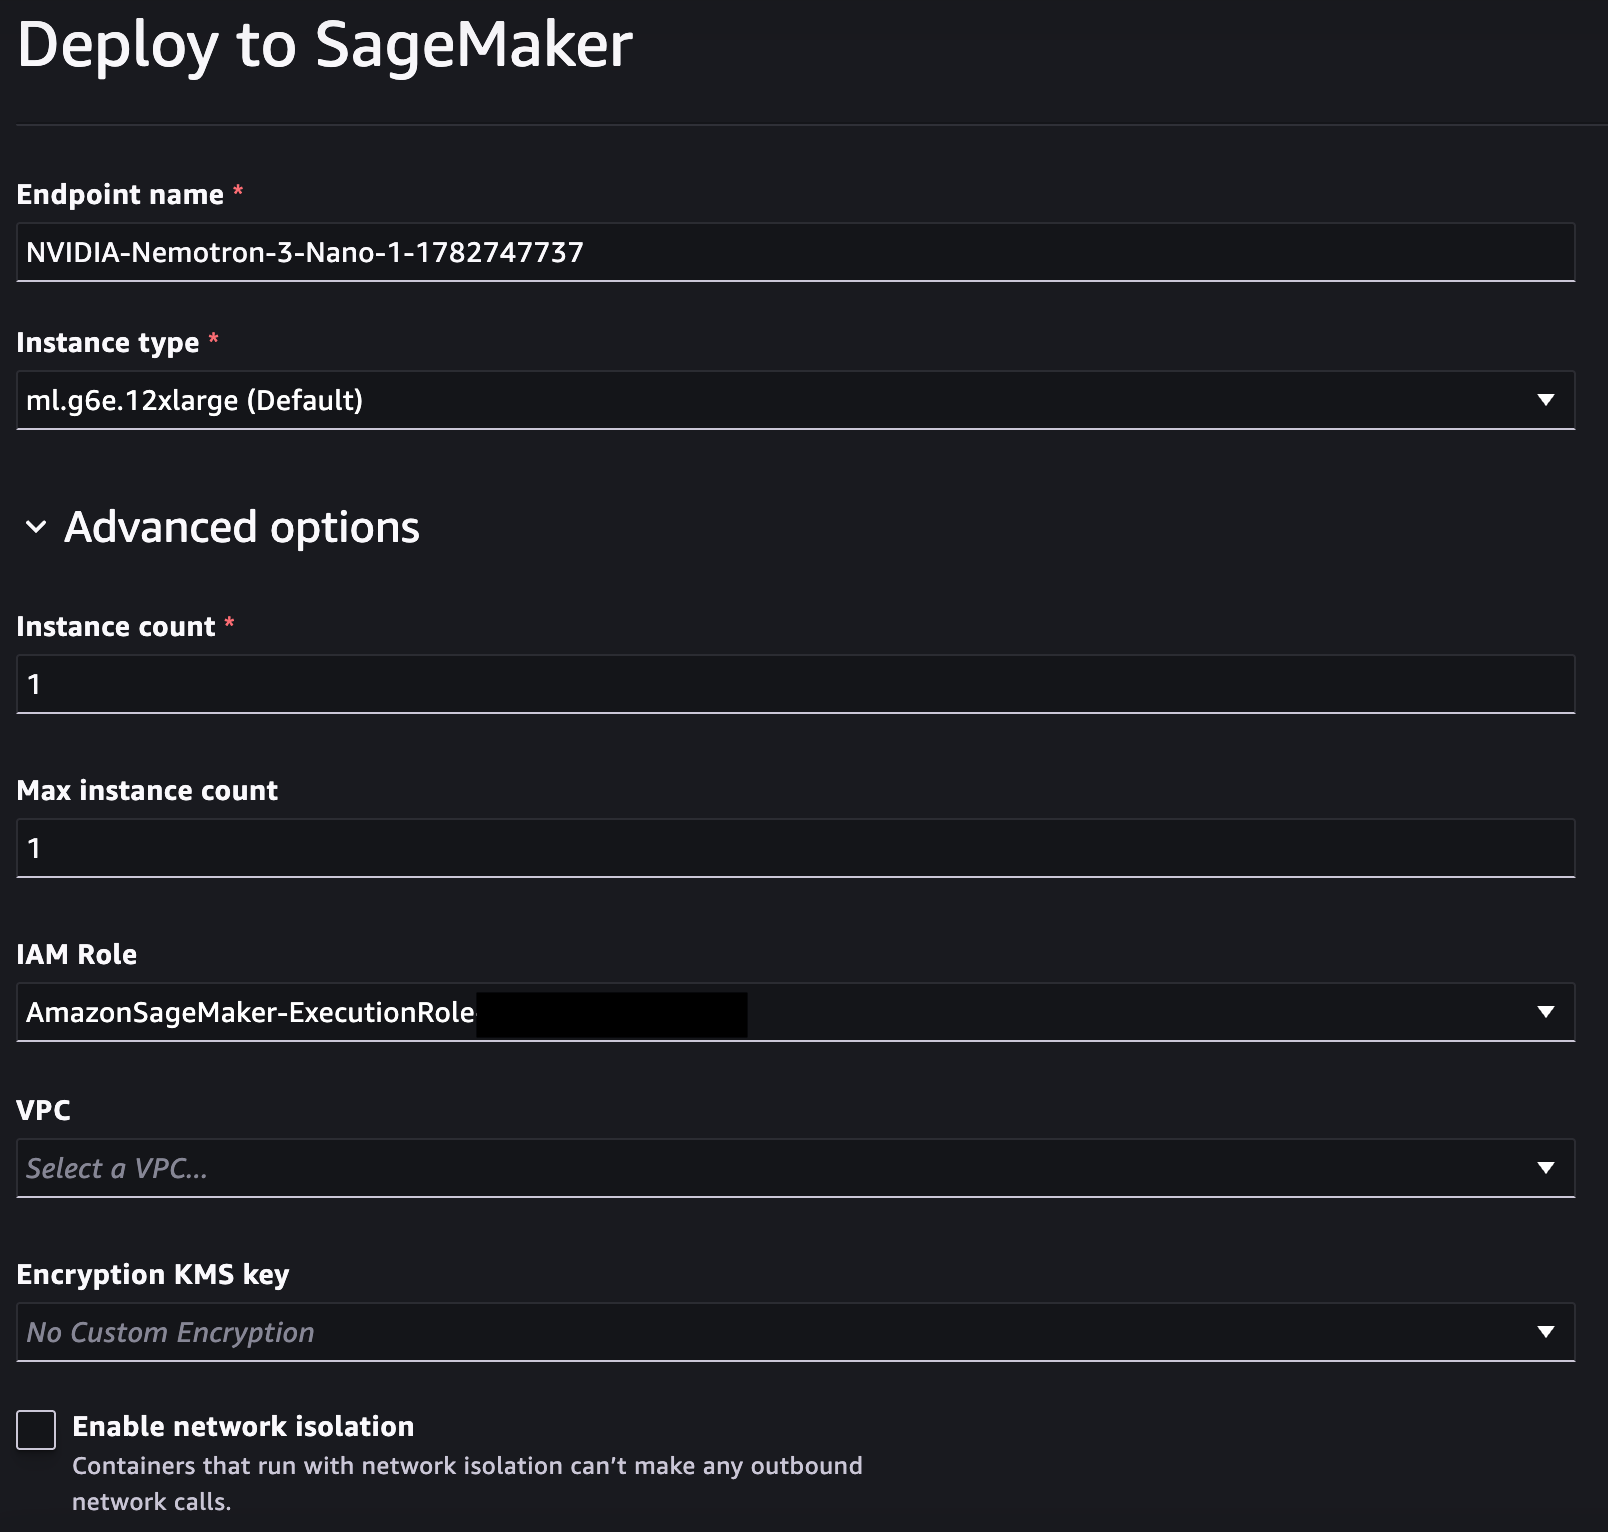
Deploy your personalized mannequin straight from the mannequin particulars web page on the console. You can even deploy to SageMaker Inference endpoints, or you may obtain mannequin weights from an Amazon Easy Storage Service (Amazon S3) bucket for self-managed deployment. The deployment choices auto-populate defaults, providing you with full flexibility over compute and scaling based mostly in your visitors and throughput necessities. The next screenshot reveals the deployment of the fine-tuned NVIDIA Nemotron Nano 30B utilizing an ml.g6e occasion powered by NVIDIA L40S Tensor Core GPUs. The deployment makes use of SageMaker inference elements and, by default, serves the merged mannequin weights, the place the bottom mannequin and LoRA adapter are mixed right into a single set of weights for optimized inference. As a result of this can be a LoRA fine-tune, you can even self-host and serve the unmerged LoRA adapter individually, as a result of you’ve got entry to each the bottom weights and the adapter weights in your S3 bucket. After deployment, you invoke the endpoint utilizing the invoke technique with the AWS Command Line Interface (AWS CLI) or SDK.
Clear up
To keep away from incurring pointless costs, we suggest deleting your SageMaker AI Studio area, SageMaker Endpoints, and every other assets that you simply created after you’re carried out utilizing them. The particular value of utilizing SageMaker AI serverless mannequin customization is determined by the bottom mannequin you select and the customization stage. See the Amazon SageMaker AI pricing web page for the fee breakdown and particulars.
Conclusion
With serverless mannequin customization for NVIDIA Nemotron 3 fashions on Amazon SageMaker AI, now you can adapt these high-performance open-weight fashions to your particular domains and workflows. Whether or not you’re fine-tuning Nemotron 3 Nano for cost-efficient agentic activity execution or customizing Nemotron 3 Tremendous for advanced multi-agent orchestration, SageMaker AI handles compute provisioning, coaching orchestration, and metric monitoring so you may focus in your knowledge, analysis, and deployment.
Get began in the present day with serverless Mannequin Customization on Amazon SageMaker AI. For detailed examples of customizing open-source fashions, see the AWS samples GitHub repository. To be taught extra, see the Amazon SageMaker AI mannequin customization documentation.
Concerning the authors
Sandeep Raveesh-Babu
Sandeep is a GenAI GTM Specialist Options Architect at AWS. He works with prospects by means of their LLM coaching, LLM inference, and GenAI observability. He focuses on product growth serving to AWS construct and remedy {industry} challenges within the generative AI house. You’ll be able to join with Sandeep on LinkedIn to find out about generative AI options.
Abdullahi Olaoye
Abdullahi is a Senior AI Options Architect at NVIDIA, specializing in integrating NVIDIA AI libraries, frameworks, and merchandise with cloud AI providers and open supply instruments to optimize AI mannequin deployment, inference, and generative AI workflows. He collaborates with cloud suppliers to boost AI workload efficiency and drive adoption of NVIDIA-powered AI and generative AI options.