Just a few years in the past, selecting an AI mannequin was comparatively easy. You in all probability didn’t even know the time period AI mannequin as ChatGPT was used synonymously with it. It was the apparent (and possibly the one) selection on the time.
However occasions have modified. ChatGPT is now not the one-stop for AI fashions. Claude, Grok, Gemini, Deepseek, Qwen, Kimi, Llama… and plenty of extra can be found to make use of. This selection was speculated to empower the customers. However that is actuality has had the alternative impact!
It’s because these fashions appear and feel the identical (the identical chatbot interface) and are evolving at a comparable tempo. So the actual query is now not “Which mannequin is the perfect?”
It’s: Which mannequin is the perfect for me?
And based mostly on what I’ve seen, that is the place most individuals get it flawed.
The Drawback
ChatGPT can write polished emails for you. However so can Claude, DeepSeek, Gemini, and nearly each different AI mannequin right now.
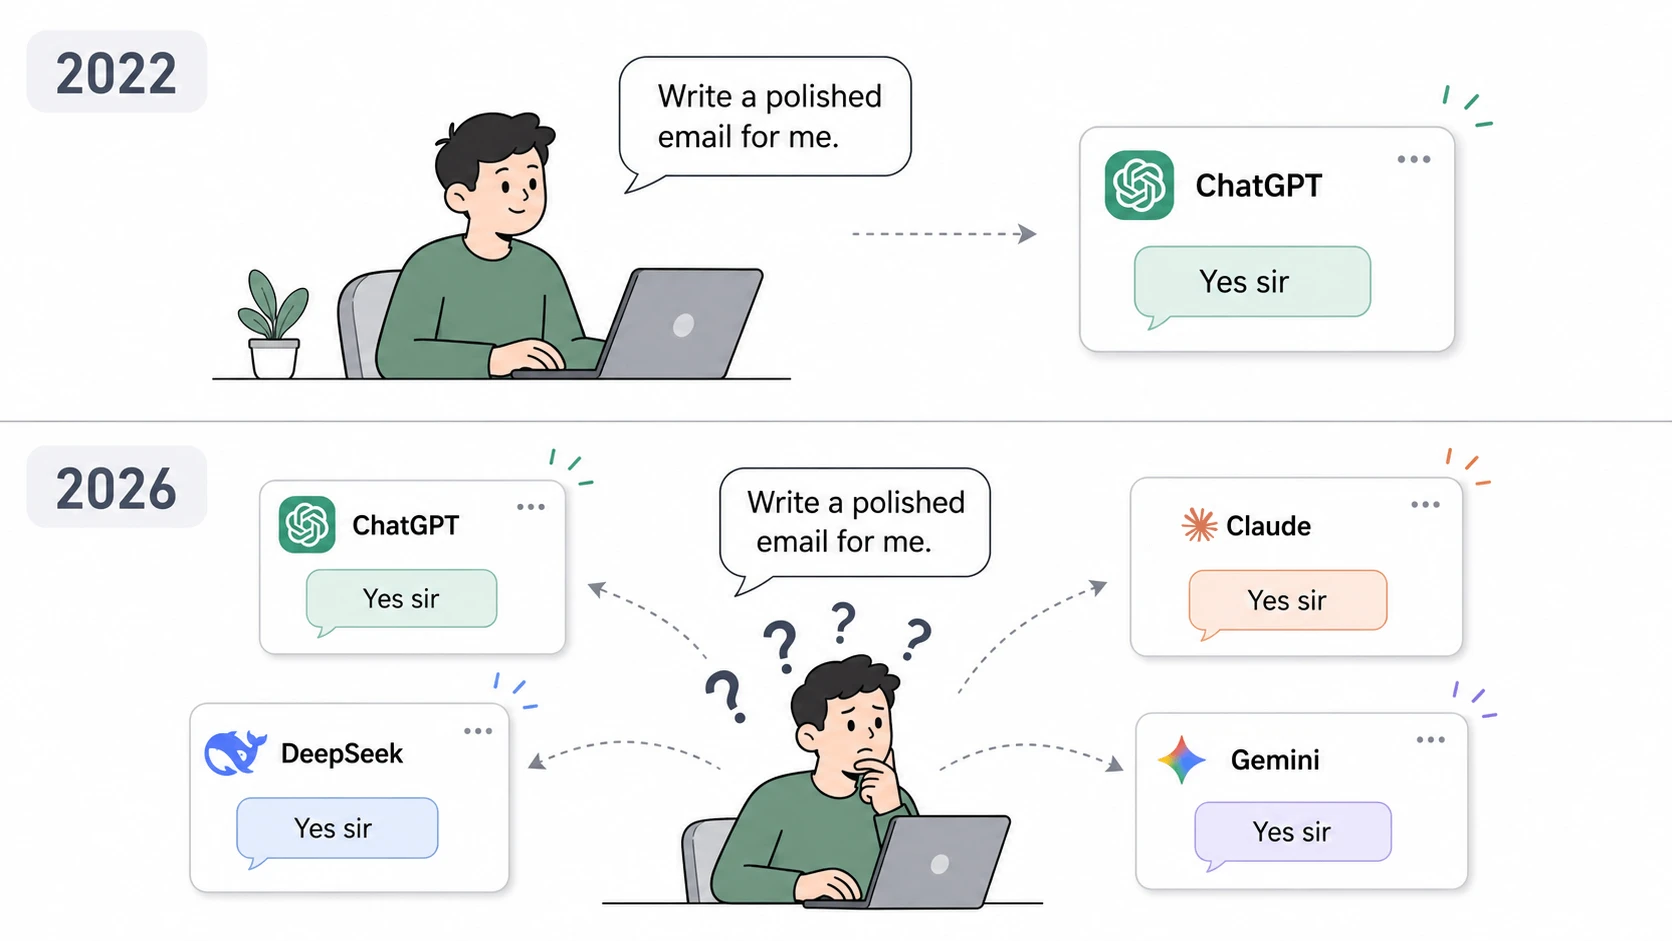
That’s the drawback.
On the floor stage, these fashions are interchangeable. They’ll all summarize paperwork, clarify ideas, write code, and reply questions. For the common consumer, the variations will not be instantly apparent.
So folks begin selecting fashions for the flawed causes:
Their pal really useful it.
It went viral on social media final week.
It topped an AI benchmark (which isn’t at all times a very good indicator)
It was the primary mannequin they tried.
It occurs to be the default choice in an app they already use.
None of those are horrible causes. However they don’t seem to be notably considerate ones both.
The higher approach to decide on an AI mannequin is to cease asking which one is finest general and begin asking what you really need the mannequin to do. However earlier than going over what to do when selecting a mannequin, let’s check out just a few issues to not do.
Benchmarks: The Smoke Display
Most individuals begin utilizing a chatbot for one main motive. Possibly they need assistance writing, coding, researching, or brainstorming.
And should you’re right here for better of the perfect in a particular area you should utilize this desk as a information for choosing your mannequin:
Job
Greatest Picks
Why
Normal chat and on a regular basis assist
Claude Opus 4.6 / 4.7 Considering
Ranked on the prime of LMArena’s textual content leaderboard, which makes use of blind human desire votes throughout open-ended duties.
(Enviornment AI)
Coding
Claude Opus 4.7
GPT-5.5
SWE-bench and SWE-bench Professional are among the many strongest public alerts for actual software program engineering potential.
(SWEbench)
Reasoning and complicated problem-solving
Claude Opus 4.8
Gemini 3.1 Professional
Synthetic Evaluation ranks Claude Opus 4.8 highest amongst reasoning fashions; Gemini fashions additionally carry out strongly on reasoning-focused leaderboards.
(Synthetic Evaluation)
Actual-world work duties
Claude Opus 4.1
GPT-5.2
GDPval evaluates economically helpful duties throughout 44 occupations, making it nearer to precise office utilization than older tutorial benchmarks.
(OpenAI)
Picture technology and enhancing
GPT Picture 2
GPT Picture 1.5
Synthetic Evaluation ranks GPT Picture 2 highest for text-to-image and GPT Picture 1.5 highest for picture enhancing based mostly on blind desire votes.
(Synthetic Evaluation)
Now if the earlier desk was capable of affect your mannequin selection, that is the precise drawback I used to be referring to.
As a result of, these outcomes had been obtained utilizing the flagship model of the listed fashions, that are all paid. This may not be an issue for many who have a subscription of those fashions, however for these with out, right here is how the equation modifications:
Claude Opus: Can’t be accessed with no paid subscription.
GPT-5.5 Considering: Free customers get 10 GPT-5.5 messages each 5 hours, then chats change to the mini mannequin: Considering entry is rather more restricted than paid tiers.
Gemini 3.1 Professional: Google makes use of compute-based limits that refresh each 5 hours till a weekly cap is reached: increased entry to Gemini 3.1 Professional is tied to Google AI Professional/Extremely plans.
GPT Picture 2: ChatGPT Free consists of picture technology, however OpenAI lists it as restricted and slower.
You’ll be able to clearly see how these fashions are now not a selection should you’re are missing a subscription.
Contemplating that many of the customers of an AI mannequin are utilizing the free tier, the disparity within the service mannequin is noteworthy.
Notice: This could warn you for any benchmark or metric for a mannequin. It’s because most of those are obtained utilizing the SOTA variants of the fashions that are normally paid. Their free variants — depart lots to be desired.
The Perspective: What works for Us?
Selecting a mannequin based mostly solely on benchmark rankings is lots like selecting a automotive based mostly solely on its prime pace. The quantity could also be right, however you is perhaps in search of security and luxury (making it sort of pointless).
In apply, components like pricing, fee limits, context home windows, ecosystem integrations, and even response type desire typically have a much bigger impression on the consumer expertise than just a few proportion factors on a leaderboard.
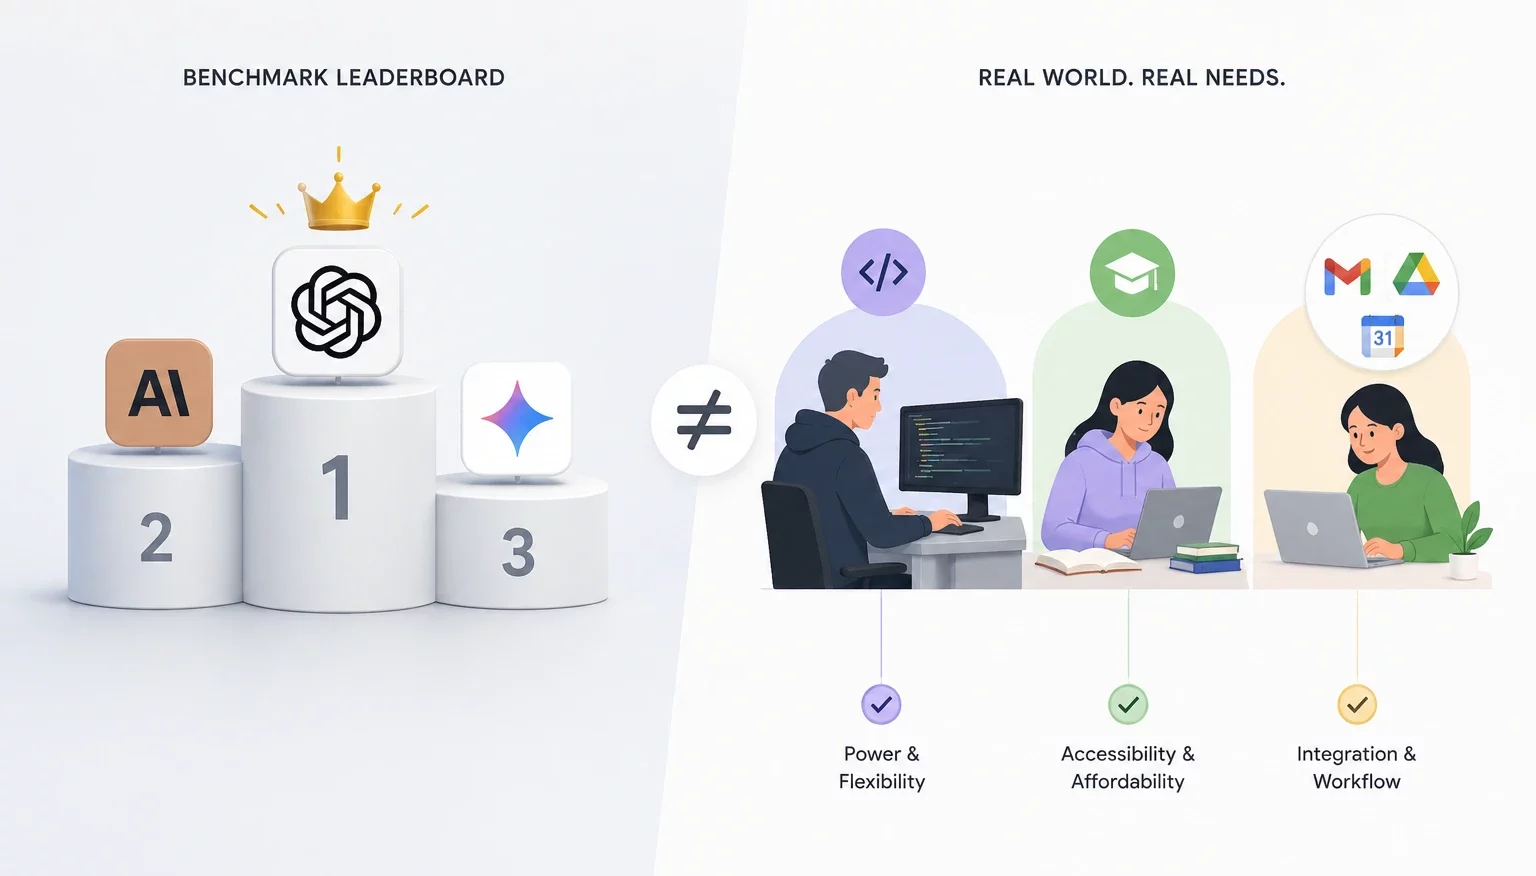
Because of this two folks can have a look at the very same benchmark outcomes and nonetheless arrive at fully totally different mannequin selections.
A software program engineer with a AI mannequin subscription
A scholar utilizing free-tier instruments
A marketer already embedded in Google’s ecosystem
These are fixing totally different issues below totally different constraints.
So earlier than deciding which mannequin to make use of, it helps to zoom out from the leaderboards and think about the components that truly form your day-to-day expertise.
The Selection: Your Personal Framework
As an alternative of counting on a benchmark or a framework somebody posted on-line, we’ll construct our personal analysis metric.
Begin with one thing easy: listing the three most typical duties you employ a chatbot for.
Your precise duties.
For me, that will be:
Writing a primary draft of an article.
Evaluating a number of choices (on Amazon) and recommending one.
Studying one thing new by a back-and-forth dialog.
The purpose is to floor the analysis in our personal actuality.
You don’t care if a mannequin tops a benchmark leaderboard if it fails on the belongings you really need it to do.
Claude is perhaps the neatest mannequin on paper, however should you want picture technology and it may possibly’t create photographs, it’s ineffective.
Gemini would possibly rating exceptionally properly on coding benchmarks whereas being horrible at making buying selections makes it a horrible selection.
So as an alternative of asking “Which mannequin is the perfect?”, we’re asking a a lot narrower query:
Which mannequin is the perfect for me?
When you’ve picked your duties, create a easy scoring rubric.
For every job, fee the mannequin on a scale of 1 to five. The precise standards don’t matter. Possibly you care about accuracy. About pace, or possibly you care about how typically the mannequin misunderstands directions.
Simply be sure to’re measuring the identical issues throughout each mannequin. Then run every job by each chatbot you’re evaluating.
My Selection
In my case upon analysis the highest 3 fashions proper now on my workload gave me the next outcomes:
Job
GPT
Claude
Gemini
Writing
★★★★★
★★★★☆
★★☆☆☆
Analysis
★★★★★
★★★★☆
★★★★☆
Studying
★★★★☆
★★★★☆
★★★★☆
Remaining Rating
14/15
Winner
12/15
10/15
GPT-5.5 got here out forward for my workload as a result of it was persistently helpful throughout all three duties.
Conclusion
There isn’t a universally finest AI mannequin. The appropriate selection relies on your desire and work. Benchmarks can information you, however they can not make that call for you.
The most secure strategy is straightforward: take a look at just a few fashions on three duties you often carry out, rating them persistently, and choose the one which wins to your use case. That retains your resolution grounded in proof, not hype.

I specialise in reviewing and refining AI-driven analysis, technical documentation, and content material associated to rising AI applied sciences. My expertise spans AI mannequin coaching, information evaluation, and data retrieval, permitting me to craft content material that’s each technically correct and accessible.
Login to proceed studying and revel in expert-curated content material.
Hold Studying for Free