


# Introduction
Most groups uncover they want a characteristic retailer the exhausting approach. A fraud mannequin works within the pocket book and quietly breaks in manufacturing. A help agent offers a generic reply as a result of it has no thought who the person is. A recommender pipeline duplicates the identical “30-day spend” calculation throughout three jobs, and two of them disagree.
A characteristic retailer is the piece of infrastructure that fixes these issues. It defines options as soon as, shops them in two shapes (one for coaching, one for serving), and retains each in sync. We’re going to construct a minimal one from scratch in Python, utilizing DuckDB, Parquet, Redis, and FastAPI. Then we’ll take a look at how AI functions change what we really use it for.
The total code is brief sufficient that we are going to stroll by each element.
# What a Function Retailer Truly Solves
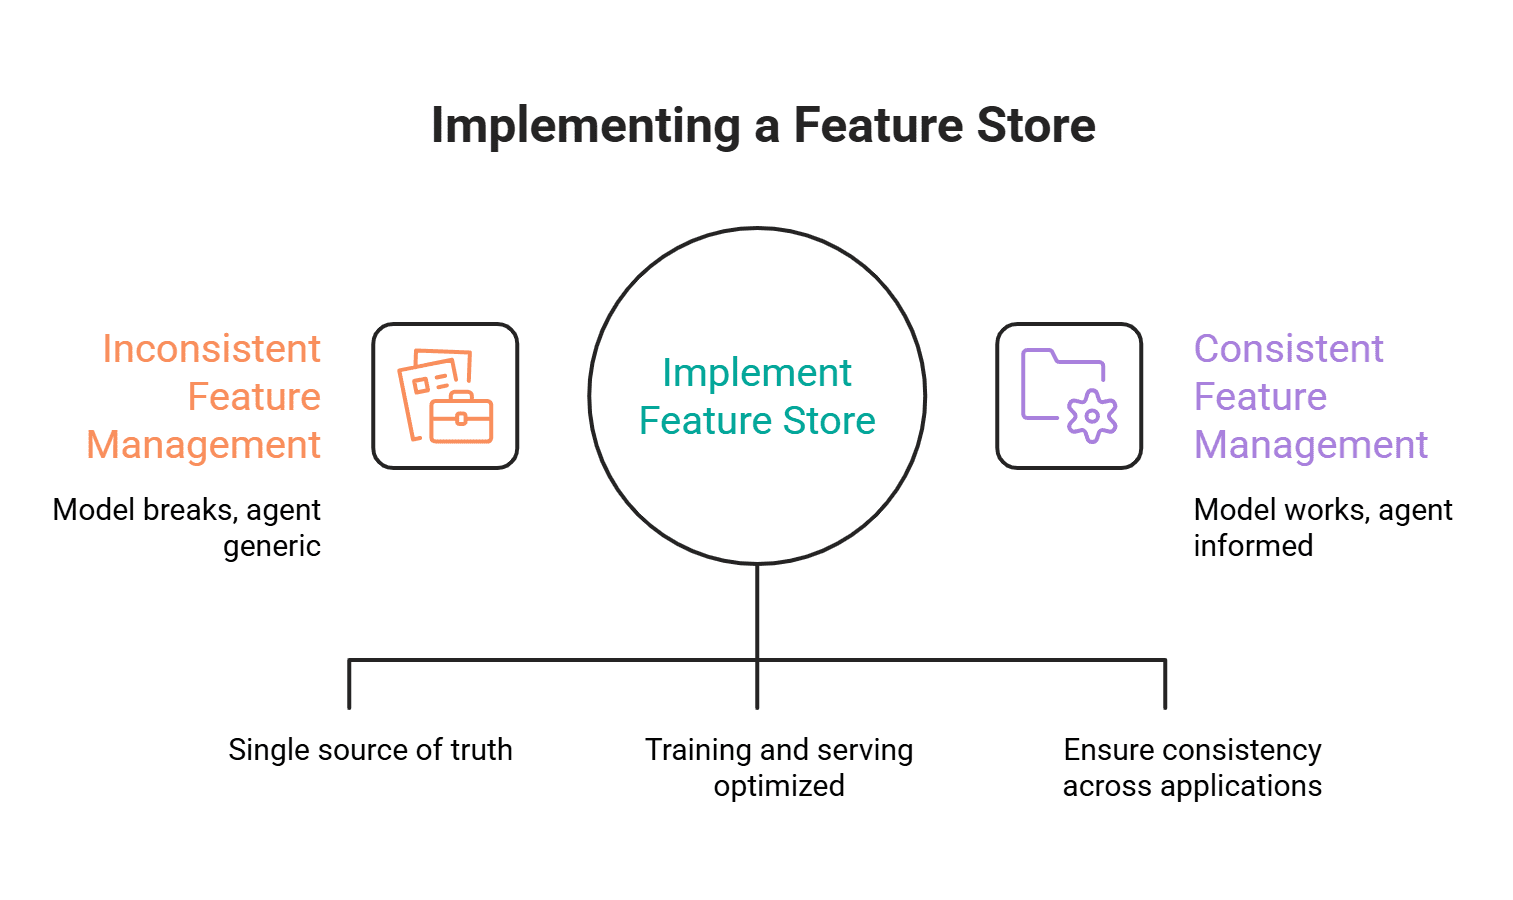
The traditional pitch is training-serving skew: the SQL that constructed your coaching set shouldn’t be the identical code path that runs at inference, so the values drift. That downside is actual, and the offline plus on-line break up is the usual repair.
The trendy pitch is broader. Giant language mannequin (LLM) brokers and retrieval-augmented technology (RAG) pipelines want structured person context at inference time, on each request, in underneath 10ms. An LLM has no reminiscence of who the person is. If we wish personalised output, we’ve got to inject the person’s plan tier, current exercise, and account state into the immediate, and we’d like a system that may return these values quick and persistently. That’s precisely what a characteristic retailer’s on-line retailer and retrieval API give us.
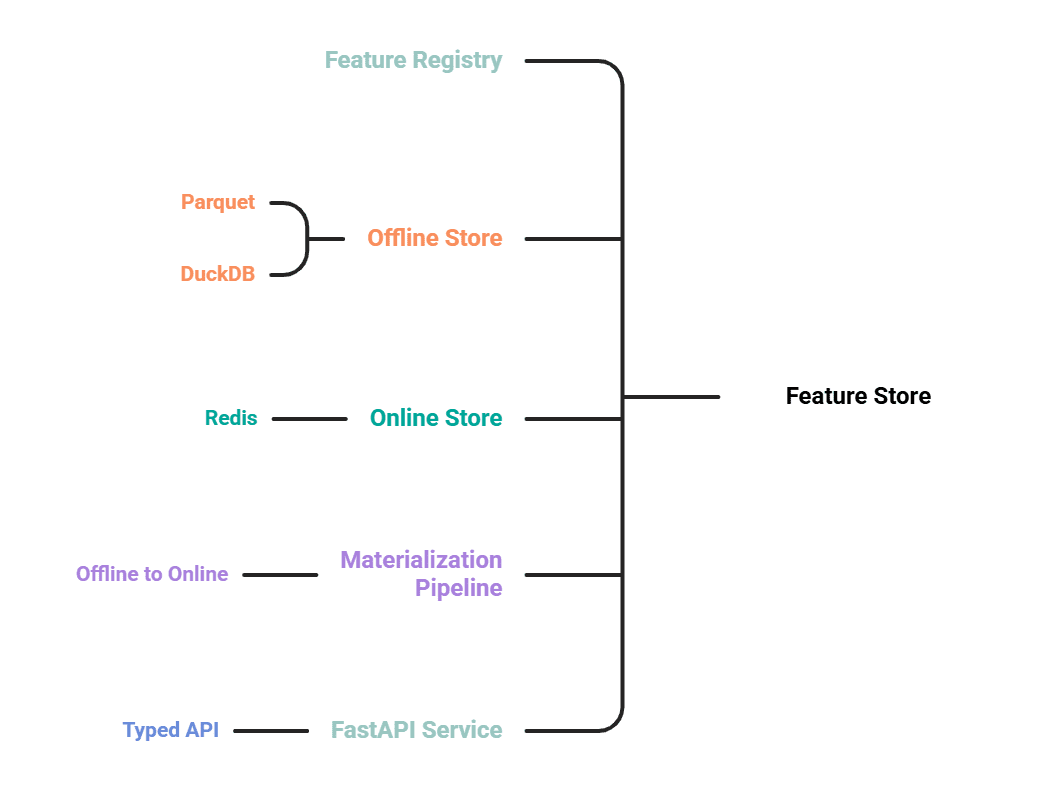
So we construct for each. The identical 5 parts deal with the predictive machine studying use case and the LLM context use case.
# The 5 Parts
A characteristic registry that defines options as code.
An offline retailer on Parquet, queried with DuckDB, for coaching and backfills.
A web based retailer on Redis for low-latency lookups at inference.
A materialization pipeline that pushes the most recent values from offline to on-line.
A FastAPI service that exposes a typed retrieval API.
# Working Instance: A Customized LLM Recommender
We’re working a streaming service. When a person opens the app, an LLM generates a brief, personalised “what to look at subsequent” message. The LLM wants three issues in regards to the person:
Function
Kind
Freshness
user_segment
string
every day
watch_count_30d
int
hourly
last_genre
string
per-event
The entity is user_id. We are going to register these three options, materialize them, and serve them to the LLM at request time.
// 1. Defining the Function Registry
A registry is only a place the place options are declared as soon as, with their entity, dtype, and supply. We use a dataclass.
from typing import Literal
@dataclass(frozen=True)
class Function:
identify: str
entity: str
dtype: Literal[“int”, “float”, “str”]
supply: str # path to a Parquet file or a SQL view
REGISTRY: dict[str, Feature] = {
“user_segment”: Function(“user_segment”, “user_id”, “str”, “knowledge/user_segment.parquet”),
“watch_count_30d”: Function(“watch_count_30d”, “user_id”, “int”, “knowledge/watch_count_30d.parquet”),
“last_genre”: Function(“last_genre”, “user_id”, “str”, “knowledge/last_genre.parquet”),
}
The total code might be discovered right here.
If you run it, the output exhibits:
user_segment entity=user_id dtype=str supply=knowledge/user_segment.parquet
watch_count_30d entity=user_id dtype=int supply=knowledge/watch_count_30d.parquet
last_genre entity=user_id dtype=str supply=knowledge/last_genre.parquet
That is the contract. Each different element reads from REGISTRY, so renaming a characteristic, altering its dtype, or pointing it at a brand new supply occurs in a single place. In manufacturing programs, this might be YAML or a Python module checked right into a Git repo, with code evaluation on each change.
// 2. Constructing the Offline Retailer with DuckDB and Parquet
The offline retailer holds the total historical past of each characteristic worth. We use Parquet recordsdata because the storage layer and DuckDB because the question engine. DuckDB reads Parquet immediately, which implies no separate database to run.
Here’s a pattern of the code:
import pandas as pd
def get_historical_features(
entity_df: pd.DataFrame, options: checklist[str]
) -> pd.DataFrame:
con = duckdb.join()
con.register(“entities”, entity_df)
base = “SELECT * FROM entities”
for fname in options:
f = REGISTRY[fname]
src = f.supply.exchange(“‘”, “””)
con.execute(f”CREATE VIEW {fname}_src AS SELECT * FROM ‘{src}'”)
base = f”””
SELECT t.*, s.{fname}
FROM ({base}) t
ASOF LEFT JOIN {fname}_src s
ON t.user_id = s.user_id
AND t.event_timestamp >= s.event_timestamp
“””
return con.execute(base).df()
The total code might be discovered right here.
If you run it, the output exhibits:
user_id
event_timestamp
user_segment
watch_count_30d
last_genre
8a2f
2026-05-05 12:00:00
informal
22
NaN
b13c
2026-05-07 20:00:00
informal
5
thriller
8a2f
2026-05-07 22:00:00
power_user
47
documentary
The AsOf be part of is the point-in-time be part of. For each entity row, it picks the latest characteristic worth the place the characteristic’s timestamp is at or earlier than the occasion timestamp. That’s what prevents leakage — the place a coaching row is constructed with a characteristic worth that didn’t exist but in the intervening time we’re predicting for.
Level-in-time joins are nonetheless the correct reply for any mannequin we plan to coach or fine-tune. For a pure inference-time LLM use case, we might by no means name this operate. We nonetheless need the offline retailer, since it’s the place backfills, analysis datasets, and audits come from.
// 3. Setting Up the On-line Retailer on Redis
The web retailer retains solely the most recent worth per entity. Redis is the usual alternative as a result of hash lookups are sub-millisecond.
import fakeredis # use redis.Redis() towards an actual server in manufacturing
r = fakeredis.FakeRedis(decode_responses=True)
def write_online(entity: str, entity_id: str, values: dict) -> None:
r.hset(
f”{entity}:{entity_id}”,
mapping={ok: json.dumps(v) for ok, v in values.gadgets()},
)
def read_online(entity: str, entity_id: str, options: checklist[str]) -> dict:
uncooked = r.hmget(f”{entity}:{entity_id}”, options)
return {f: json.masses(v) if v else None for f, v in zip(options, uncooked)}
The total code might be discovered right here.
If you run it, the output exhibits:
lacking key -> {‘user_segment’: None}
The important thing form is entity:entity_id. The worth is a hash with one discipline per characteristic. A single HMGET returns all of the options we requested for in a single spherical journey. On an area Redis occasion with three options, this finishes in effectively underneath 1ms.
// 4. Working the Materialization Pipeline
Materialization strikes values from offline to on-line. In an actual system this runs on a schedule (Airflow, cron, a streaming job). Right here it’s a operate.
by_entity: dict[str, dict] = {}
for fname in options:
f = REGISTRY[fname]
src = f.supply.exchange(“‘”, “””)
df = duckdb.sql(f”””
SELECT {f.entity}, {fname}
FROM ‘{src}’
QUALIFY ROW_NUMBER() OVER (
PARTITION BY {f.entity}
ORDER BY event_timestamp DESC
) = 1
“””).df()
for _, row in df.iterrows():
by_entity.setdefault(row[f.entity], {})[fname] = row[fname]
for entity_id, values in by_entity.gadgets():
write_online(“user_id”, entity_id, values)
The total code might be discovered right here.
If you run it, the output exhibits:
user_id:b13c -> {‘user_segment’: ‘informal’, ‘watch_count_30d’: 5, ‘last_genre’: ‘thriller’}
The QUALIFY clause retains the most recent row per entity. We group all options for a similar person into one Redis write to chop spherical journeys. Run this on the cadence every characteristic wants: hourly for watch_count_30d, near-real-time for last_genre, every day for user_segment. The registry is the correct place to encode that cadence in an actual implementation.
// 5. Exposing the FastAPI Retrieval Service
The retrieval service is the manufacturing floor. It’s what the LLM utility calls.
print(“nPrompt the LLM would obtain:”)
print(
f” System: You advocate exhibits for a streaming service.n”
f” Consumer context: phase={f[‘user_segment’]}, “
f”watched {f[‘watch_count_30d’]} titles in final 30 days, “
f”final style watched: {f[‘last_genre’]}.n”
f” Activity: counsel 3 titles in a pleasant, quick message.”
)
The total code might be discovered right here.
If you run it, the output exhibits:
physique: {‘user_id’: ‘8a2f’, ‘options’: {‘user_segment’: ‘power_user’, ‘watch_count_30d’: 47, ‘last_genre’: ‘documentary’}}
Immediate the LLM would obtain:
System: You advocate exhibits for a streaming service.
Consumer context: phase=power_user, watched 47 titles in final 30 days, final style watched: documentary.
Activity: counsel 3 titles in a pleasant, quick message.
The characteristic retailer is the piece that turns “person 8a2f” right into a structured context the LLM can use.
# The place the Function Retailer Ends and the Vector Database Begins
A vector database (Pinecone, Weaviate, pgvector) shouldn’t be a characteristic retailer, despite the fact that each sit in entrance of a mannequin at inference. They clear up totally different retrieval issues.
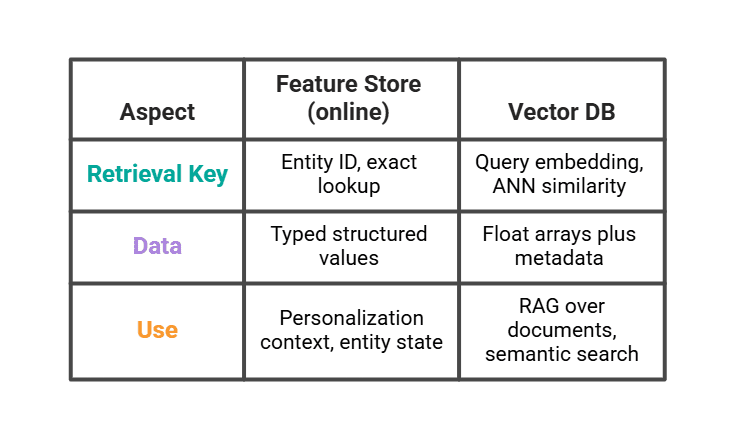
An actual LLM stack makes use of each. The vector database returns the three most related previous viewing periods. The characteristic retailer returns the person’s phase and up to date counts. The immediate combines them.
# Widespread Anti-Patterns
Just a few patterns that we hold seeing fail:
Computing options contained in the mannequin service. The identical logic leads to the coaching pocket book and the API, and the 2 definitions drift inside 1 / 4.
Treating the web retailer because the supply of fact. Redis loses knowledge on a foul restart. The offline retailer is canonical; the web retailer is a cache.
Skipping the registry. Three groups independently outline active_user and the dashboards cease matching the mannequin.
Calling a vector database a characteristic retailer. It can’t do entity-keyed structured lookups, and a immediate that wants each will find yourself wired to 2 programs anyway.
Backfilling with out point-in-time joins. The coaching set seems to be nice, the manufacturing mannequin seems to be damaged, and the hole is the leakage.
# Evaluating This to Feast, Tecton, and Databricks
Our ~200 strains do the identical job in miniature.
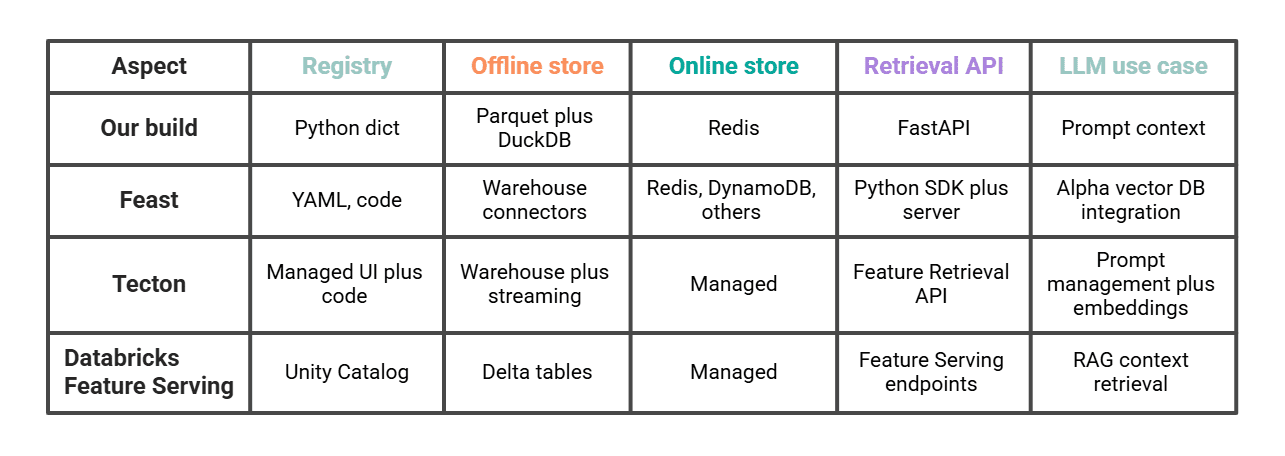
Feast is the closest comparability if we wish to go additional on the identical sample, self-hosted. Tecton and Databricks are the managed paths and have specific LLM options (Tecton’s Function Retrieval API for LLMs, Databricks Function Serving for compound generative AI programs). Selecting between them is generally a query of how a lot we wish to function ourselves and whether or not the remainder of our stack already lives in Databricks.
# Conclusion
A working characteristic retailer matches in 5 parts: a registry, an offline retailer, an internet retailer, a materialization step, and a retrieval API. Constructing it as soon as teaches us why the manufacturing programs look the best way they do. It additionally exhibits the place the design modifications for AI: the web retrieval path is the floor the LLM hits, point-in-time joins matter after we prepare or consider, and the vector database sits subsequent to the characteristic retailer, not inside it.
As soon as we’ve got these items, swapping our minimal model for Feast, Tecton, or Databricks is generally a migration of the registry. The form of the system stays the identical.
Nate Rosidi is an information scientist and in product technique. He is additionally an adjunct professor educating analytics, and is the founding father of StrataScratch, a platform serving to knowledge scientists put together for his or her interviews with actual interview questions from prime firms. Nate writes on the most recent developments within the profession market, offers interview recommendation, shares knowledge science tasks, and covers every thing SQL.

