


On June 3, 2026, Google launched Gemma 4 12B Unified, an open-source multimodal mannequin designed to grasp textual content, pictures, audio, and video inside a single structure. It combines a 256K context window with an environment friendly, laptop-friendly design geared toward agentic workflows and native deployment.
The discharge additionally raises attention-grabbing questions on Google’s broader AI technique, notably the hole between the fashions emphasised in public APIs and people made broadly out there by way of open-source tooling. On this article, we’ll look at Gemma 4 12B Unified’s structure, capabilities, and what its launch means for builders.
What’s Gemma 4 12B?
Gemma 4 12B Unified is Google DeepMind’s mid-sized open supply mannequin within the Gemma 4 household. Google describes it as a dense multimodal mannequin constructed to carry agentic multimodal intelligence on to laptops. It bridges the hole between the smaller Gemma 4 E4B edge mannequin and the bigger Gemma 4 26B A4B Combination-of-Specialists mannequin.
The general public mannequin card lists Gemma 4 fashions in 5 sizes: E2B, E4B, 12B Unified, 26B A4B, and 31B. Gemma 4 12B Unified has 11.95B parameters, 48 layers, 1024-token sliding window consideration, a 256K context window, a 262K vocabulary, and help for textual content, picture, and audio inputs.
Key Options
Gemma 4 12B helps:
Textual content era and chat
Lengthy-context reasoning as much as 256K tokens
Coding, code completion, and code correction
Perform calling for agentic workflows
Video understanding by processing video as frames
Audio speech recognition and speech-to-translated-text translation
Multilingual use, with out-of-the-box help for 35+ languages and pre-training over 140+ languages
Google additionally highlights computerized speech recognition, diarization, video understanding, coding, and agentic reasoning within the Gemma 4 12B developer information.
Why Google Wanted a Mid-sized Unified Mannequin?
The unique Gemma 4 household launched on March 31, 2026 with E2B, E4B, 31B, and 26B A4B variants. Google then launched Gemma 4 MTP drafters on April 16, 2026, adopted by Gemma 4 12B Unified on June 3, 2026. This makes the 12B launch a follow-up growth of the household quite than the unique Gemma 4 launch.
The discharge fills a sensible deployment hole. E2B and E4B are designed for edge and mobile-class use instances, whereas 26B A4B and 31B goal higher-end workstations and servers. Gemma 4 12B is positioned as a laptop-ready mannequin that gives stronger reasoning and multimodal functionality than the sting fashions whereas utilizing much less reminiscence than the bigger 26B MoE mannequin.
Foremost Adjustments from Earlier Gemma 4 Fashions
Space
Earlier Gemma 4 fashions
Gemma 4 12B Unified
Mannequin measurement
E2B, E4B, 26B A4B, 31B initially
Provides a mid-sized 12B dense possibility
Multimodal design
Different fashions use devoted imaginative and prescient and audio encoders relying on measurement
Encoder-free projection of picture and audio into the LLM
Audio
E2B and E4B had native audio; 31B and 26B A4B don’t record audio help
First mid-sized Gemma 4 mannequin with native audio
Context
128K for E2B/E4B, 256K for bigger fashions
256K
Deployment goal
Edge fashions for cell, bigger fashions for workstations and servers
Laptop computer-first native multimodal brokers
Tremendous-tuning
Separate encoders can add complexity
Unified token loop could be tuned in a single cross
Benchmarks
E4B is lighter, 26B A4B is stronger
12B sits between them in most official scores
Structure Overview
1. Unified encoder-free design
An important technical change in Gemma 4 12B is its encoder-free multimodal structure. Conventional multimodal fashions typically use separate encoders for picture and audio inputs earlier than passing representations into the language mannequin. Google says Gemma 4 12B removes these separate multimodal encoders and tasks uncooked picture patches and audio waveforms straight into the LLM embedding area. (weblog.google)
2. Imaginative and prescient processing
For imaginative and prescient, the developer information says Gemma 4 12B replaces the multi-layer imaginative and prescient encoder utilized in different medium-sized Gemma 4 fashions with a 35M parameter imaginative and prescient embedder. Uncooked 48×48 pixel patches are projected into the LLM hidden dimension with a single matrix multiplication, and spatial data is hooked up by way of factorized coordinate lookup matrices.
3. Audio processing
For audio, Gemma 4 12B removes the separate conformer-based audio encoder utilized in smaller Gemma 4 variants. It slices uncooked 16 kHz audio into 40 ms frames and linearly tasks these frames into the LLM enter area.
4. Decoder and a focus
The mannequin card states that Gemma 4 makes use of a hybrid consideration mechanism that interleaves native sliding window consideration with full international consideration, with the ultimate layer all the time international. It additionally makes use of unified keys and values in international layers and Proportional RoPE for long-context effectivity.
5. MTP drafters for decrease latency
Gemma 4 12B is “drafter-ready,” that means it helps Multi-Token Prediction drafters for speculative decoding. Google’s MTP documentation explains {that a} smaller draft mannequin predicts a number of future tokens, whereas the goal mannequin verifies them in parallel, enhancing decoding pace with out altering the ultimate verified output high quality.
Availability and Entry
Gemma 4 12B is obtainable as open weights in pre-trained and instruction-tuned variants by way of Hugging Face and Kaggle. Google’s launch put up additionally lists LM Studio, Ollama, Google AI Edge Gallery, Google AI Edge Eloquent, LiteRT-LM, Hugging Face Transformers, llama.cpp, MLX, SGLang, vLLM, and Unsloth as supported ecosystem paths.
Arms-on: Run Gemma 4 12B with Ollama
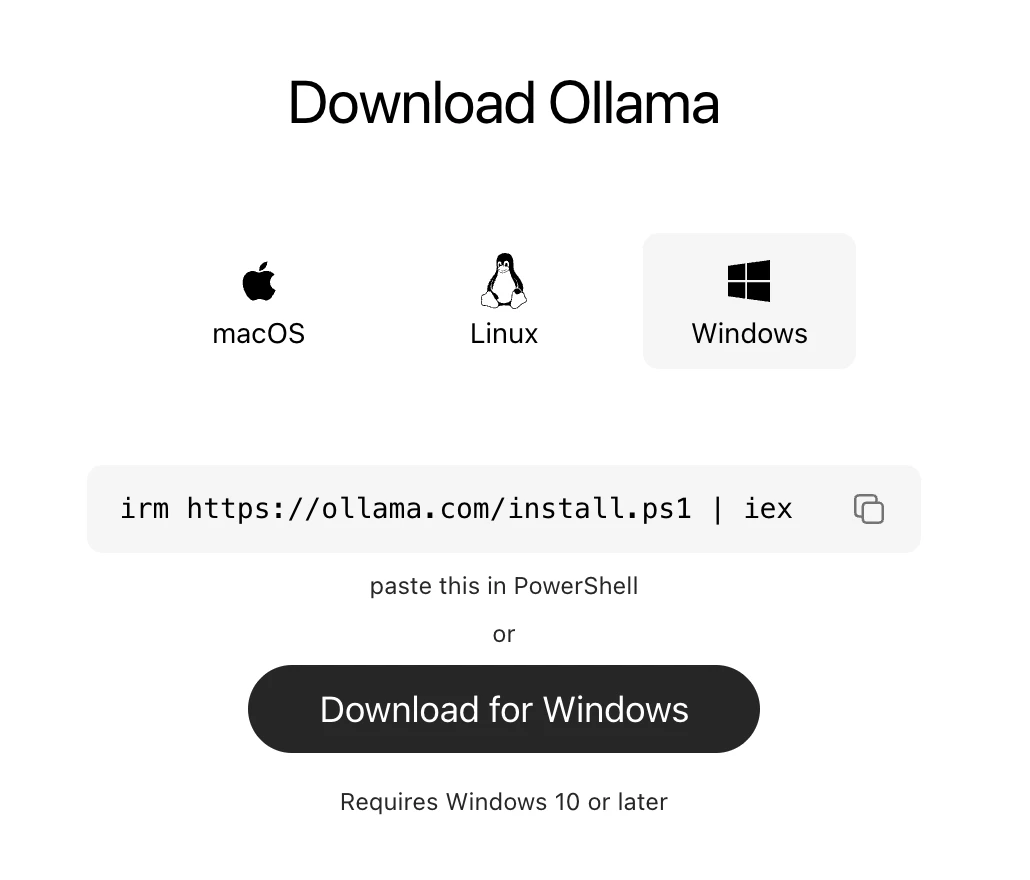
Obtain Ollama from https://ollama.com/obtain/
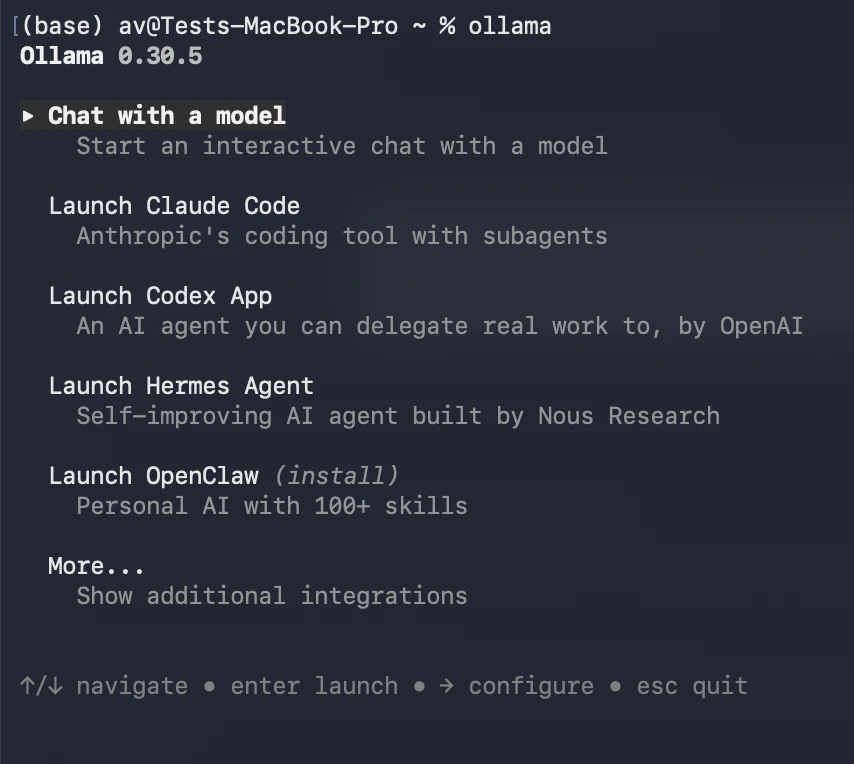
Set up it in your system and kind ollama in terminal to confirm the set up:
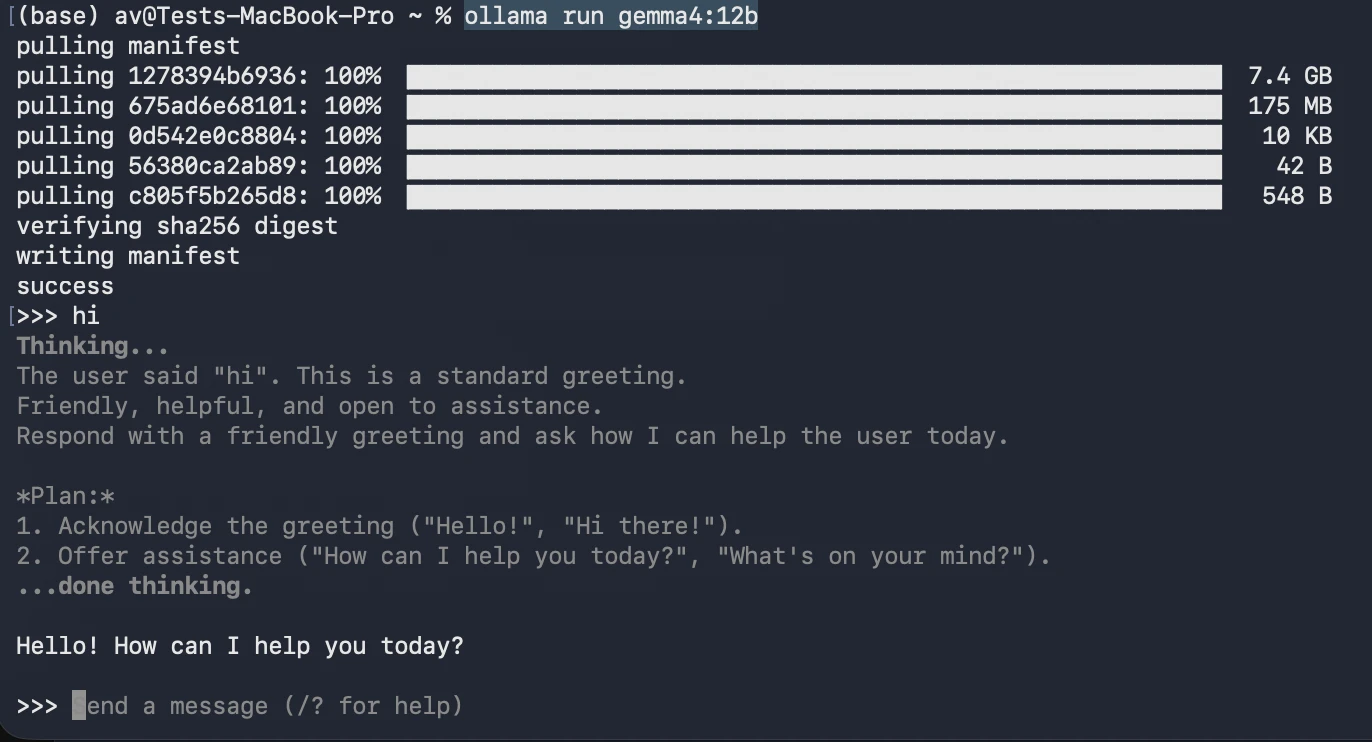
In a recent terminal window, paste ollama run gemma4:12b and press Enter
This may obtain gemma4 12b in your PC and you may work together with it straight
Arms-on: Picture Understanding
Let’s check Gemma4 12B for picture understanding for which this mannequin is understood for.
We’ll be utilizing Ollama right here however not in terminal however by way of code
For utilizing this set up the ollama python sdk:
!pip set up ollama
import ollama
# Outline the mannequin ID
MODEL_ID = “gemma4:12b” # Guarantee this matches your native Ollama mannequin identify
# Arms-on: Picture Understanding
# Word: Google recommends putting picture content material earlier than textual content in multimodal prompts.
# For native information, cross the trail string. For URLs, obtain the picture first.
image_messages = [
{
“role”: “user”,
“content”: “Extract the key trends from this table.”,
“images”: [“financia_table.png”],
}
]
image_response = ollama.chat(mannequin=MODEL_ID, messages=image_messages)
print(image_response[“message”][“content”])
Output:
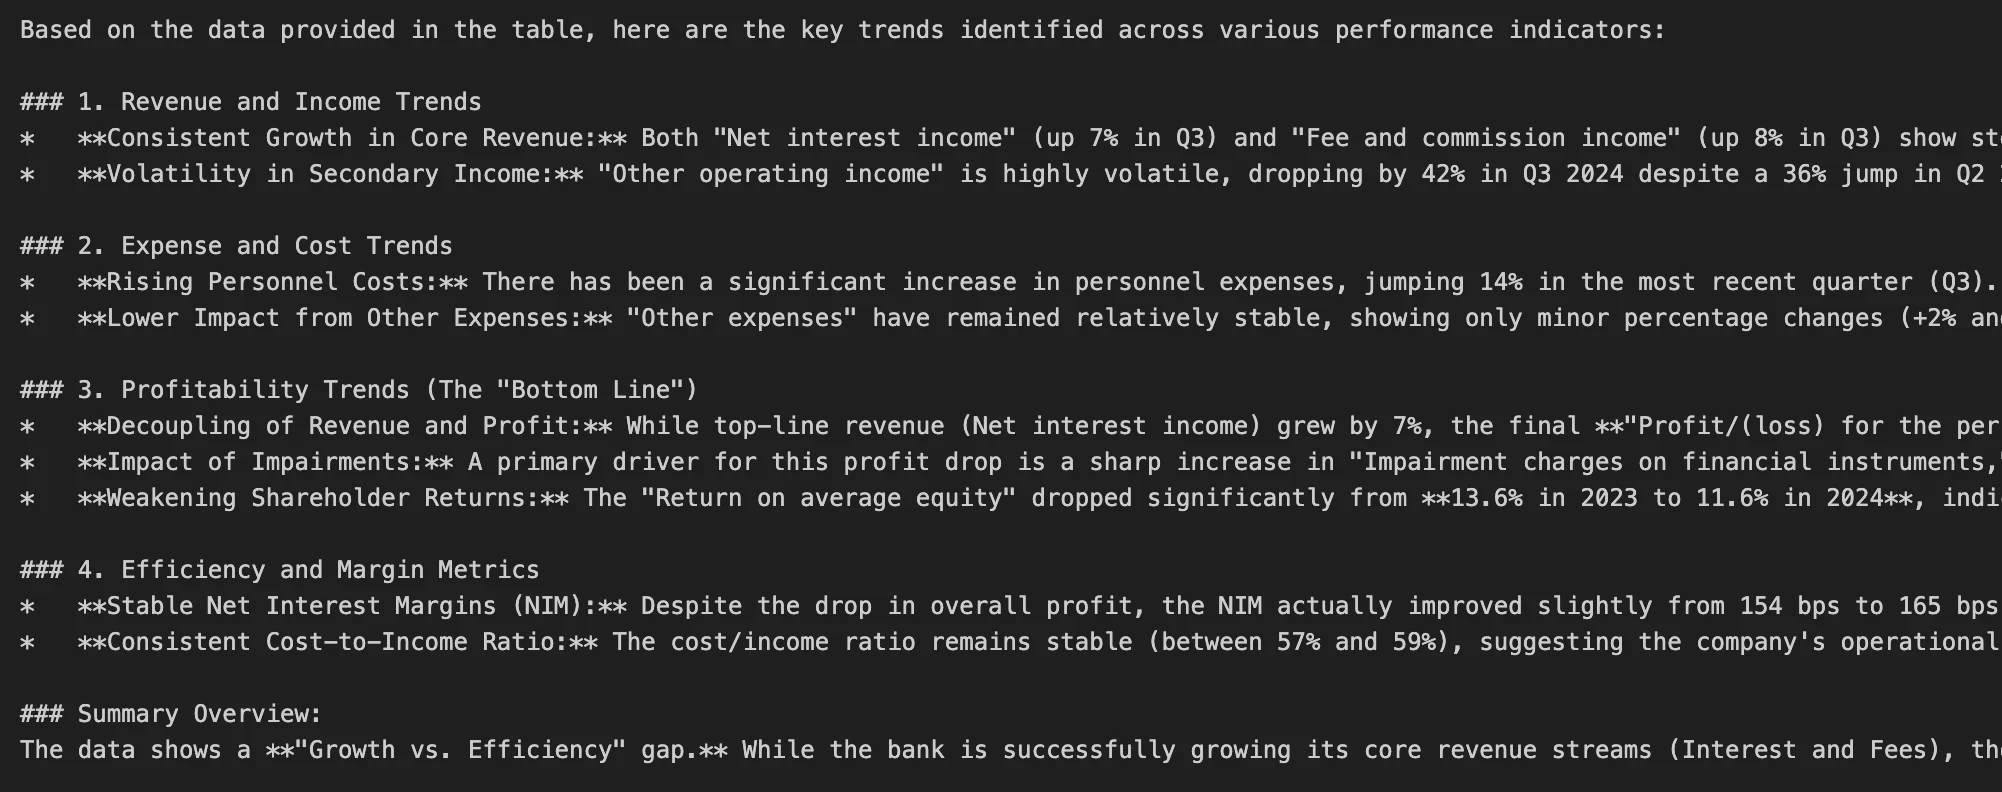
We are able to see Gemma4 12B is ready to analyse the picture efficiently. Google recommends putting picture content material earlier than textual content in multimodal prompts.
Benchmarks and Comparability
The official mannequin card experiences the next instruction-tuned benchmark outcomes:
Benchmark
Gemma 4 31B
Gemma 4 26B A4B
Gemma 4 12B Unified
Gemma 4 E4B
Gemma 4 E2B
Gemma 3 27B
MMLU Professional
85.2%
82.6%
77.2%
69.4%
60.0%
67.6%
AIME 2026, no instruments
89.2%
88.3%
77.5%
42.5%
37.5%
20.8%
LiveCodeBench v6
80.0%
77.1%
72.0%
52.0%
44.0%
29.1%
Codeforces ELO
2150
1718
1659
940
633
110
GPQA Diamond
84.3%
82.3%
78.8%
58.6%
43.4%
42.4%
MMMU Professional
76.9%
73.8%
69.1%
52.6%
44.2%
49.7%
MATH-Imaginative and prescient
85.6%
82.4%
79.7%
59.5%
52.4%
46.0%
FLEURS, decrease is best
unavailable
unavailable
0.069
0.08
0.09
unavailable
Gemma 4 12B sits between E4B and 26B A4B, providing a sensible center floor for native reasoning, coding, imaginative and prescient, and audio workloads.
Conclusion
Gemma 4 12B isn’t simply an incremental replace; it’s Google’s blueprint for bringing extremely succesful multimodal, agentic AI on to on a regular basis developer machines. By routing textual content, picture, and audio right into a single, encoder-free decoder transformer, it utterly eliminates pipeline complexity for native voice, coding, and doc workflows.
In the end, this mannequin provides technical leaders the proper center floor between tiny edge fashions and large cloud infrastructure. The good play is obvious: deploy it as a robust native open-weight mannequin, confirm API availability earlier than scaling, and anchor your deployment round measurable latency, security, and compliance necessities.

Harsh Mishra is an AI/ML Engineer who spends extra time speaking to Giant Language Fashions than precise people. Enthusiastic about GenAI, NLP, and making machines smarter (so that they don’t substitute him simply but). When not optimizing fashions, he’s most likely optimizing his espresso consumption. 🚀☕
Login to proceed studying and luxuriate in expert-curated content material.
Preserve Studying for Free

