Most individuals who reconcile messy identifiers attain for a similar method: take an edit-distance metric, choose a threshold, and merge something shut sufficient. Damerau-Levenshtein is the apparent improve over plain edit distance. The reasoning for selecting it’s sound. It treats a transposition (two swapped characters sds1001 and sds011) as one mistake as a substitute of two.
In a pull of 719 environmental sensor stations I used to be working with, one confirmed misspelling was sds1001 for sds011. Two digits had been swapped — a slip anybody might make on a keyboard. Plain edit distance treats this as two edits, the identical value it might cost for 2 completely completely different merchandise. Damerau-Levenshtein then again is aware of it is a single mistake and from the get-go, scores it as distance 1. So it’s a greater mannequin of how typos occur, and it actually prices nothing to undertake, making it the obvious selection.
Nevertheless, there’s an often-overlooked draw back to the metric. Right here’s an instance: hdc1008 and hdc1080 are two actual Texas Devices humidity sensors bought on the identical time, documented on separate datasheets. Whereas plain edit distance places them at 2, Damerau-Levenshtein pulls them right down to 1 into the identical vary because the aforementioned typos. Be aware how the identical property that makes it higher at recognizing human errors additionally causes it to merge two totally completely different merchandise that the producer purposely numbered a digit aside.
That is Half 2 of my deep-dive sequence on entity key drift that begins with normalization. If you have not learn Half 1 but, it is value a glance first because it covers the deterministic cleanup that this piece picks up from. The code and knowledge for each are on GitHub and Zenodo, in case you need to verify any of the numbers your self.
On this piece, I’ll stroll by way of what occurred after I measured 5 string-similarity metrics in opposition to the bottom fact I verified from producer datasheets, why none of them may very well be tuned to separate typos from actual merchandise — and what that failure means for the way the system needs to be constructed as a substitute.
That is related to anyone reconciling quick alphanumeric identifiers — half numbers, SKUs, mannequin codes — from a couple of supply, and fewer so if yours come from a single supply. Additionally, it is value saying upfront that it is a destructive end result. For those who’re searching for a matcher to repeat, I haven’t got one, and the explanation I do not seems to matter greater than a matcher would have.
What normalization left behind
Step 1 dealt with the simple instances. Throughout 719 stations, 114 distinct sensorType strings collapsed right down to 99 pure keys as soon as NFKC normalization, case folding, and separator stripping had been utilized. SDS 011, SDS011 and sds011 all converged to grow to be sds011. The merge carried no threat in any respect because the variations had been purely stylistic and the operate doing the collapsing was deterministic.
99 keys continues to be much more than what the area truly accommodates. My greatest estimate is that there are round two dozen actual {hardware} fashions represented right here (though that’s solely an estimate). Pinning down the precise quantity would require a components catalog which the dataset would not carry (extra on that later).
The form of that hole issues earlier than you attempt to shut it. 52 of the 99 keys are part-number codes like bme280 and sds011, and collectively they account for 94 p.c of the 4,301 observations, with a median size of six characters. The remaining is a mixture of descriptive phrases like gps and regenmesser, one literal “???”, and one key that jams two half numbers collectively as “tsl45315&veml6070”.
That inhabitants issues greater than it appears to be like. Approximate string matching wasn’t actually constructed for it. Cohen, Ravikumar, and Fienberg’s 2003 comparability of string metrics benchmarks in opposition to identify matching, the place a shared prefix is proof: “Jonathan” and “Jonathon” look alike as a result of a human transcribed the identical particular person. Gadget identifiers do not work that means. bme280 and bmp280 share 5 of the six characters and are nonetheless two completely different merchandise.
I went forward and constructed the matcher anyway, and tried to do it conservatively. It compares identifiers in two phases: the digit core of every key has to match precisely earlier than the alphabetic the rest will get judged on similarity in any respect. That offers the benefit of the numeric half not getting smoothed away by a tolerance setting; bme280 and bme680 keep aside by development moderately than by a threshold {that a} tuning go might loosen later. This fashion no matter security it has is constructed into the logic moderately than sitting in a weighted setting.
That construction nevertheless would not resolve the comparability that it nonetheless lets by way of. As soon as two keys share a digit core, the letters get judged by similarity, and similarity wants a threshold. So the entire design comes down to 1 query: is there a threshold on any affordable metric that catches each typo with out additionally merging two genuinely completely different merchandise?
Constructing a floor fact you may truly verify
That query cannot be answered with the info readily available. The snapshot tells us how typically every string exhibits up, nevertheless it would not inform us which strings truly identify an actual delivery half, and that query wants answering.
So I constructed the column manually earlier than operating a single similarity rating. That order was deliberate as a result of when you classify strings after you’ve got already seen how they rating, you are likely to classify them to suit the scores with out even which means to.
For every of the 16 strings, I appeared up the producer’s datasheet and recorded a verdict, the official half identify, supply URL, lifecycle standing, and entry date. All of that lives within the repo as ground_truth_catalog.csv, so none of it’s taken on belief.
Doing this by hand turned up three issues I did not count on that had been notably extra attention-grabbing than the matcher outcomes.
First, one of many assumptions I had turned out to be flawed. I might assumed bmp200 was a typo of bmp280. Bosch’s stress sensor line runs BMP085, BMP180, BMP280, BMP388 — there is not any BMP200 in it. However upon additional investigation, I came upon that BMP200 is a PM10 particulate analyzer from Centered Photonics, a wholly completely different producer, though I could not find a spec sheet or proof of actual distribution for it. In order that pair would possibly both be actually a typo or a collision between a Bosch stress sensor and a Chinese language air-quality analyzer; I could not inform which even after spending appreciable time on it. So I dropped the pair, which is value flagging as a result of it weakens my outcomes (taking the confirmed-typo rely from 4 pairs down to 3 makes the sample tougher to show), nevertheless it held up anyway.
Second, an early affirmation turned out to be incorrect. An earlier go by way of the info had recorded SDS 011 with an area as canonical and marked CONFIRMED, sourced from a third-party mirror web site. However Nova Health’ personal documentation reads SDS011 with out area on the duvet and in web page headers. The mirror had it flawed, and that error had been sitting there masked with a CONFIRMED label. Mirrors aren’t producers, and that distinction ought to have been handled extra rigorously from the beginning.
Lastly, one half wasn’t named what everybody calls it. The dataset makes use of dht22, however Aosong’s personal technical guide says it not as soon as. DHT22 exhibits up on each storefront and reseller mirror on-line, however within the producer’s personal paperwork it’s AM2302. The half itself is actual, so the row stands, however the identify the complete subject makes use of for it is not what the producer makes use of. That is the third sort of failure beneath the 2 I used to be truly attempting to measure.
In spite of everything that verification, what was left? 12 strings naming actual components, 3 naming nothing, and 1 excluded — which comes out to 10 scored pairs: 3 actual typos (the explanation I used to be constructing the matcher within the first place) and seven pairs the place each side are actual merchandise {that a} merge would silently common collectively.
5 metrics, and never one in all them separates
A metric works if some threshold on it merges all 3 typo pairs and not one of the 7 real-product pairs. I examined 5 spanning the principle households: plain edit distance, transposition-aware (Damerau-Levenshtein), prefix-weighted (Jaro-Winkler), set-based (q-gram Jaccard), and my two-stage digit-core matcher.
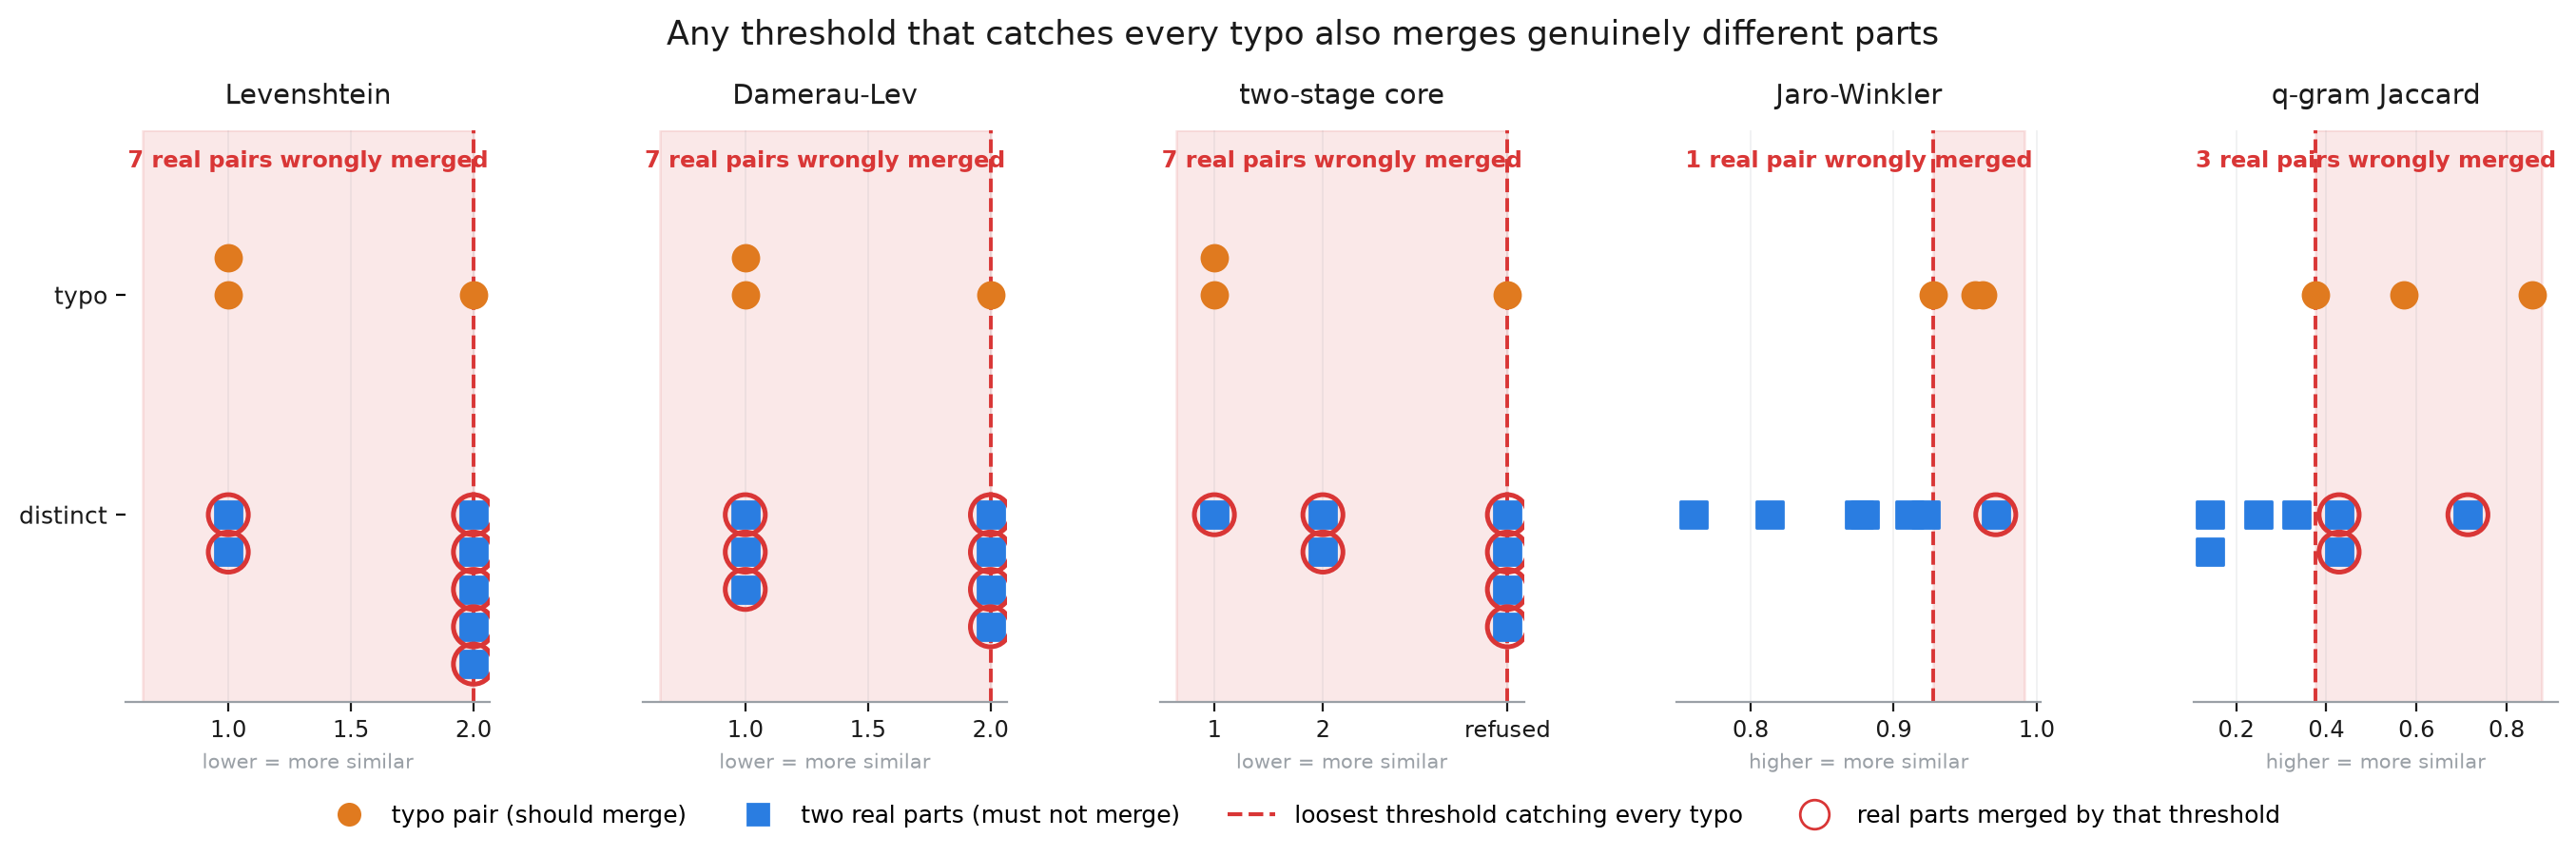
Set the brink free sufficient to catch all three misspellings, then rely what comes with it. Plain edit distance merges all seven actual pairs. Damerau-Levenshtein: seven. Two-stage: seven. q-gram Jaccard: three. Jaro-Winkler, the most effective of the 5, merges one.
Not one in all them merges none.
The pair that settles the query is hdc1008/hdc1080, the 2 actual Texas Devices components talked about earlier. They don’t seem to be variants of one another: completely different packages, completely different provide ranges, and ±4 %RH accuracy in opposition to ±2 %RH. Due to this fact, merging them would fold a sensor with twice the error into one with half of it. Jaro-Winkler scores this pair 0.971, larger than the most effective real typo scored at 0.963. q-gram Jaccard places it at 0.714, above two of the three. On plain edit distance and on the two-stage matcher, it ties the worst-scoring typo. On each metric examined, this pair of genuinely completely different merchandise scored in the identical band as at the very least one actual misspelling.
pair
Lev
D-L
two-stage
J-W
q-gram
fact
sds011 / sds1001
2
2
refused
0.928
0.375
typo
hdc1080 / hhdc1080
1
1
1
0.963
0.857
typo
hdc1080 / hc1080
1
1
1
0.957
0.571
typo
bme280 / bmp280
1
1
1
0.911
0.429
distinct
bme280 / bme680
1
1
refused
0.922
0.429
distinct
bmp085 / bmp280
2
2
refused
0.876
0.250
distinct
hdc1008 / hdc1080
2
1
refused
0.971
0.714
distinct
dht11 / dht22
2
2
refused
0.813
0.333
distinct
scd30 / sgp30
2
2
2
0.760
0.143
distinct
sgp30 / sps30
2
2
2
0.880
0.143
distinct
Desk 1. Each scored pair below all 5 metrics, in opposition to datasheet-verified floor fact. Daring marks the row that defeats the board. Pairs use the info as-is as a substitute of the official half names: dht22 is what the info accommodates, although the producer calls that half AM2302. A matcher solely ever sees the left column, and that hole is the actual drawback.
It is value being exact that one pair is sufficient right here. The pure objection that n=10 pairs is just too small a pattern applies to a unique sort of declare than the one made right here. If the objective was to show {that a} metric works, a big pattern would have been required to sure its error charge with any confidence. However proving that no threshold can separate the 2 teams solely requires a single pair that scores within the typo vary with the other floor fact. There are a number of such pairs right here, throughout each metric examined. Accumulating extra knowledge might add extra counterexamples, however not take away those already there.
The 2-stage matcher deserves truthful accounting as nicely. Its digit-core rule refuses to think about sds011 and sds1001 in any respect as a result of 011 and 1001 are completely different digit strings, so it by no means even will get an opportunity to catch the typo it was constructed for. And it nonetheless merges bme280 with bmp280 at a distance of 1, as a result of they share the digit core 280. The structural security I constructed into it held the place I aimed it however failed elsewhere. It missed the typo it was designed to catch, and made the collision it was designed to forestall.
Why a sixth metric doesn’t save this
Full disclosure: there’s a model of this argument that is not falsifiable, and that model is not value a lot. I did not check each attainable matcher — no one might — and it is totally attainable some untested metric would have appeared prefer it labored on this explicit pattern. However the declare I need to make is not empirical in that sense. It is structural — the truth that decides id right here is not contained within the string in any respect.
Take into account the pair I scrapped earlier. If Bosch ships a BMP200 subsequent yr, the connection between bmp280 and bmp200 flips from typo to distinct, and neither string modifications by a single character. What does is a call made inside an organization that has nothing to do with both string’s characters.
This isn’t only a hypothetical designed for impact — it is the precise motive that pair is not there. I could not rule out {that a} BMP200 exists, and that is precisely why I set the pair apart as a substitute of scoring it. The state of affairs turned out to be the explanation why I ended up with three confirmed typo pairs as a substitute of 4.
No operate of two strings can learn a producer’s catalog. Not the 5 metrics I examined, or a sixth one I did not attempt, and never a discovered mannequin both. Realized entity matching is genuinely good at what it does — Konda’s Magellan from 2016, or the pre-trained language mannequin method from Li et al. in 2020 — however each assume you have got labeled coaching knowledge and a few tolerance for fashions whose reasoning you may’t absolutely interrogate. A educated mannequin would fail right here for a similar motive the hand-built ones do: the sign it might want simply is not within the enter. For those who hand it the catalog straight, you’ve got principally rebuilt the structure described under, simply with much less transparency and no audit path, which solutions “did you attempt X” for each worth of X, as soon as and for all.
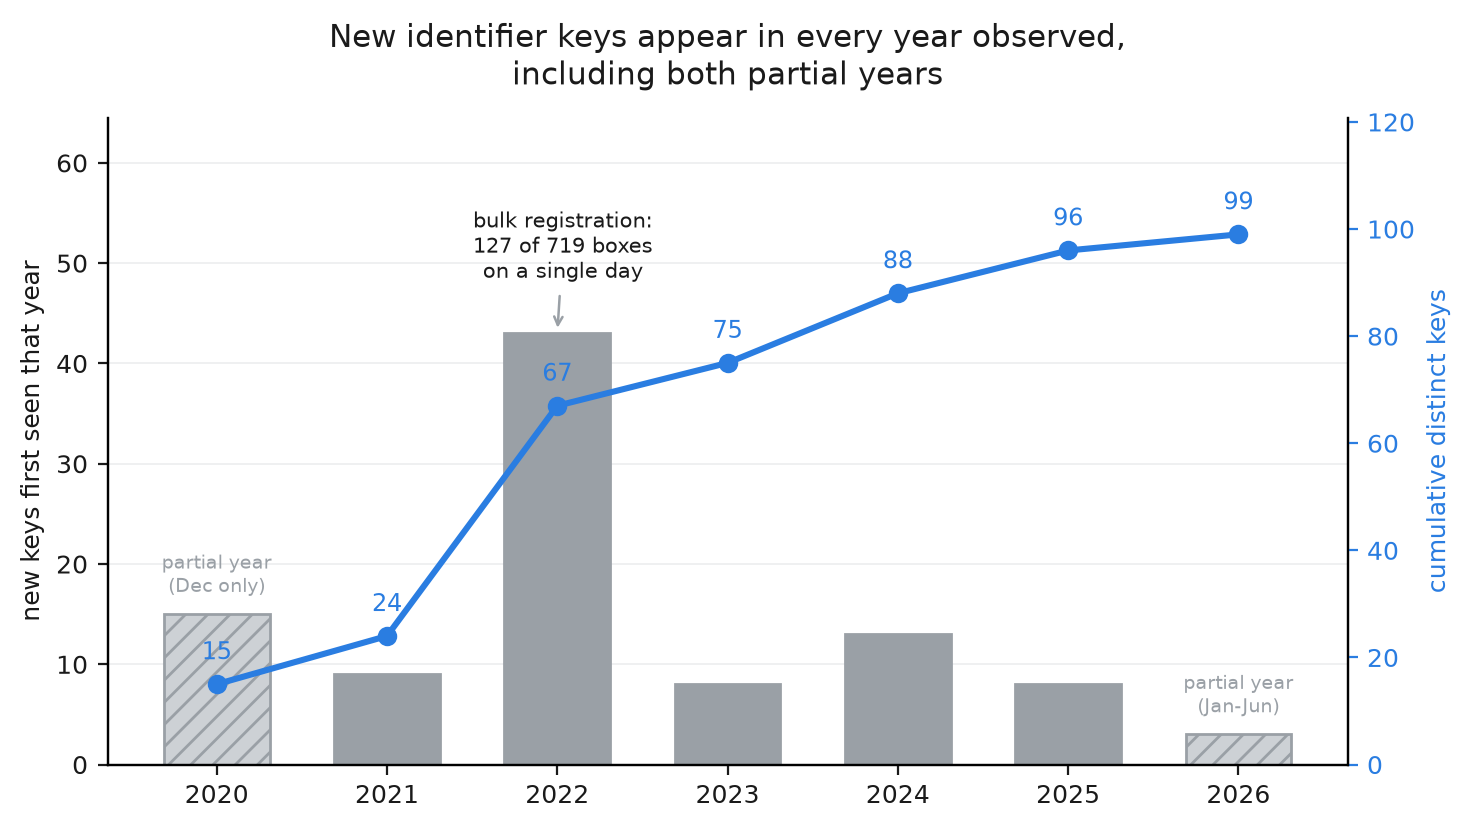
A catalog isn’t a set reference both. New keys entered in yearly of the window, 15 within the first and three within the final, accumulating to 99 (Determine 2 under). So the declare that this string would not identify something actual is in a selected second in time, and a component that ships subsequent quarter can flip that with out a single saved byte altering.
Yet one more admission, and it’s maybe the strongest level in the entire piece: to construct the ground-truth column, I needed to seek the advice of the producer datasheets — an exterior catalog checked by hand — exactly as a result of the dataset itself could not reply the query. Organising the experiment required conceding its personal conclusion earlier than I might even run it.
None of that is information to the record-linkage literature. Fellegi and Sunter formalized probabilistic linkage again in 1969; Christen’s 2012 remedy lays out the bounds of approximate matching. That string similarity alone is inadequate is established reality for names and addresses. What this piece provides to that’s that practitioners nonetheless attain for fuzzy matching on quick alphanumeric machine codes the place the failure is of form moderately than diploma. Id isn’t within the codes in any respect, and the catalog holding it’s exterior and modifications over time.
The structure that survives
When you strip out what the measurement dominated out, here’s what stays.
1. Merge solely what normalization proves similar. The one sound automated merge, and Step 1 already does it, is 114 keys to 99, zero threat, zero threshold.
2. Fuzzy auto-merge is rejected by proof, not warning. Conservatism implies {that a} bolder possibility exists for the risk-tolerant. There truly isn’t one: the knowledge required is absent.
3. Every little thing else defers to a human, who consults the catalog the strings don’t carry. A human can take a look at hdc1008 and hdc1080 and appropriately inform them aside and file that call as a label — one thing utilized at question time, so the id saved within the knowledge stays a pure operate of what was truly noticed.
Extra than simply being a comfort for edge instances, the label layer is crucial, as a result of if a matcher might safely do that work, labels would not have to exist in any respect. Three issues should be true of them for the system to carry collectively.
Labels should be effective-dated
Every model carries a validity interval, and a question resolves in opposition to the model legitimate as of its declared time. Whether or not one thing is an actual half is genuinely time-varying. The catalog picked up new keys in yearly of the window, which suggests a label might be overturned by an occasion on this planet moderately than by new knowledge arriving within the dataset. For those who edit a label in place as a substitute, you silently regroup historical past. Aggregates from final quarter cease reproducing, and a file that was right when it was written finally ends up trying prefer it at all times mentioned one thing completely different. The decision is to not right the previous however so far it.
The price of that’s charged to all people, and it is easy to let the mechanism’s tidiness disguise it. As soon as labels are dated, a query like “what number of sds011 models are deployed?” would not have one fact anymore; it has a solution as of a given date, which the caller has to produce. Interfaces that by no means wanted a temporal parameter now want one. That’s the value of reproducibility.
Labels by no means return into the matcher as coaching sign
There are three separate causes for this, and any one in all them can be sufficient by itself. Id wants to remain a operate of the file’s personal content material. If a matcher will get tuned on previous labeling choices, id turns into a operate of processing historical past as a substitute, and the identical enter can cease producing the identical key over time. A matcher like that additionally stops being one thing you may level to in an audit and clarify. And a system that consumes its personal labels to enhance matching has, with out actually which means to, constructed the discovered matcher that was already dominated out above.
Labels are knowledge too, and knowledge drifts
That may be a genuinely awkward end result for a chunk about identifier drift if the layer meant to repair it introduces its personal model of the identical drawback. With the intention to sidestep that, labels should come from a managed vocabulary, get natural-keyed and normalized with the identical Step 1 operate, and carry a file of who made the choice, when, and on what proof. A label with out an creator hooked up is only a declare with out a proof.
To make certain, I examined this rule whereas writing. My ground-truth CSV has a verdict column {that a} validation script reads as a managed vocabulary. At one level, I “improved” a row by altering it to CONFIRMED REAL, PART NAME CORRECTED. It was legitimate CSV, parsed effective, and it silently dropped that row out of the confirmed set as a result of the brand new string wasn’t within the vocabulary. So the rule caught its personal creator inside roughly 4 hours of being written.
What the deferral truly prices
Deferring every little thing else to a human is sensible, supplied the ensuing queue stays small. On measuring it, right here’s what I discovered. Evaluating all 99 keys pairwise comes out to 4,851 comparisons, however no one is reviewing that many by hand. Blocking cuts that additional right down to 30 candidate pairs, which is just 0.62 p.c of the total area, and after the preliminary go, it settles into roughly 4 new pairs a yr as new keys enter the catalog. So primarily it quantities to a morning of labor upfront, and a handful of choices yearly.
Blocking itself is not new; sorted-neighborhood blocking goes again to Hernández and Stolfo in 1995, cover clustering to McCallum et al. in 2000, locality-sensitive hashing to Broder in 1997. What’s much less customary — at the very least in my expertise — is selecting amongst these guidelines by truly measuring their tradeoffs moderately than simply selecting the one which feels acquainted.
How briskly that recurring queue grows relies on how briskly the catalog itself grows.
Which particular rule to dam on is itself a factor to measure moderately than inherit.
blocking rule
candidates
% of all pairs
typos surfaced
edit distance ≤ 1
12
0.25%
2 of three
edit distance ≤ 2
46
0.95%
3 of three
edit distance ≤ 2, size ≥ 4 (chosen)
30
0.62%
3 of three
q-gram Jaccard ≥ 0.5
15
0.31%
2 of three
identical digit signature
18
0.37%
2 of three
Desk 2. Blocking guidelines measured in opposition to the three verified misspellings. Three of the cheaper guidelines miss an actual typo.
Three of the foundations I examined are cheaper than the one I ended up utilizing. All three of them miss sds011/sds1001. It’s not a tuning accident; it follows straight from how digit-signature blocking works. 011 and 1001 are completely different digit strings, so these two keys by no means land in the identical block within the first place, which is the very same property that appropriately retains bme280 and bme680 aside. The takeaway: the property that protects you from one sort of mistake is identical one which blinds you to a different.
The quantity triage lure
There’s an optimization that can most likely happen to anybody this setup, and it is extra a lure than a shortcut. You can evaluation solely pairs the place each keys carry significant statement quantity on the reasoning {that a} pair affecting two observations would not deserve a lot consideration. That cuts the queue from 30 down to six, and on the floor, it appears to be like like a free win.
It additionally removes each single verified typo from consideration.
Misspellings are uncommon virtually by definition. They’re errors sure contributors occurred to make, not one thing most individuals typed. The minority facet of my three confirmed typo pairs exhibits up 1, 2, and a pair of occasions respectively. So any quantity threshold set at 5 or above would have discarded all three earlier than a human ever noticed them.
The overall model of that is value protecting in thoughts outdoors of sensors too. A frequency filter will systematically take away no matter inhabitants one is definitely looking for, any time that inhabitants is uncommon by development. On this explicit case, the queue was already sufficiently small that the shortcut wasn’t wanted anyway.
What the evaluation truly buys
Right here is the uncomfortable reality. Working all 30 pairs by hand strikes a complete of 5 observations out of 4,301 — about 0.12 p.c of the info.
That naturally invitations a shortcut: why not simply merge all 30 candidates robotically and skip the evaluation? Besides that may transfer 217 observations as a substitute of 5, as a result of a lot of the 30 pairs grow to be actual merchandise that simply occur to look alike. scd30 and sps30 differ by two characters and measure fully various things. The queue is generally made up of pairs that resolve to no merge. That’s the reason it wants an individual it moderately than a threshold deciding robotically.
So the evaluation is affordable relative to what it protects in opposition to, and it is necessary as a result of there is not any solution to discover the 5 observations that do want fixing with out all 30.
This reframes what the evaluation is definitely shopping for. Earlier than it, 2,430 observations (56 p.c of the dataset) sit on a key that has an unresolved neighbor, which suggests there is not any solution to say with confidence whether or not the counts for that key are full. Following the evaluation, that query has a solution.
What you get out of this course of is not corrected knowledge precisely. It is figuring out that the info is right.
The trustworthy limits
This structure would not shut the hole it opened with. 99 keys went in, the area most likely has round two dozen actual fashions, and the evaluation course of resolves 30 pairs and confirms three typos. These numbers do not reconcile, and it might be straightforward to let a reader come away considering in any other case.
The reason being per every little thing else right here. Blocking solely ever surfaces pairs which are already shut collectively in string area. Each rule in Desk 2 is a few model of a distance or overlap rule, so every one finds near-duplicates and nothing past that. Two keys that identify the identical half however share no characters in any respect by no means make it into the queue within the first place.
My very own floor fact affords an instance of this. dht22 and AM2302 identify the identical sensor below two fully completely different names, sharing nothing as strings — an edit distance of 5, zero bigrams in frequent, and completely different digit signatures totally. Run each by way of each rule in Desk 2 and none of them proposes the pair. So the one that might resolve it in a second by no means will get requested the query.
Precision issues right here, since that’s the entire level. AM2302 by no means truly seems on this explicit snapshot, whereas dht22 exhibits up 22 occasions. This isn’t an noticed miss. It’s what the foundations do when handed each spellings, which is what occurs the second a second gateway reviews the producer’s identify as a substitute of the market one. On this dataset, the pair is not simply failing to get flagged; it’s lacking totally from the all-pairs comparability area. There are two unbiased causes {that a} human reviewer by no means will get requested, and no threshold adjustment fixes them both. The alias drawback is genuinely tougher than the typo drawback, and this structure would not resolve it. It declines to guess — which is healthier than guessing flawed — nevertheless it is not the identical as being completed. Closing that hole would want a catalog with alias tables in it, not a greater blocking rule.
Two smaller limitations value naming listed here are: the scope is identifier fields solely, not the free-text descriptions of what a sensor measures, which is a associated however separate drawback; and that is one snapshot of 1 crowdsourced community whose open submission type most likely produces extra variations than a managed schema would. The mechanism ought to generalize moderately nicely. The precise percentages most likely should not be handled as a benchmark.
Six issues to remove
Construct floor fact from outdoors the info, earlier than you rating. For those who classify after scoring, you are likely to classify to suit the scores you have already got. Mine ended up killing one in all my very own claims and correcting two others, which is the strategy working moderately than a setback
The subtle metric is the extra harmful one. Damerau-Levenshtein’s consciousness of transpositions is precisely the sort of tolerance actual product households exploit as a result of producers typically quantity associated merchandise by permuting a digit.
For brief alphanumeric codes, the deciding reality is outdoors the string. Whether or not two codes identify the identical product is settled by a producer’s catalog, which is exterior, modifications over time, and is not reachable from the characters themselves. No metric, and no discovered mannequin both will get round that.
A frequency filter tends to delete the precise uncommon inhabitants you’re looking for. Typos are uncommon, so quantity triage appears to be like like an apparent win and it finally ends up eradicating each actual one.
Date your labels; don’t retrofit them. Whether or not one thing is actual is usually solely true as of a selected second. So efficient relationship lets a label change over time with out a sealed historic file quietly turning into false. The tradeoff is that each downstream shopper of that label now has to supply an as-of date.
The deliverable isn’t corrected knowledge. It’s figuring out that the info is right. The evaluation moved 5 observations out of 4,301, and took 56% of the info from presumably fragmented to verifiably entire. The second is what’s value paying an individual for.
Abstract
This matcher was initially constructed with the intention to complete what normalization began. Nevertheless, the measurement says that it can not exist in a protected type. 5 completely different metrics overlap as soon as checked in opposition to the datasheet-verified floor fact and one pair of actual TI components ended up trying extra like a typo than precise typos do. The underlying motive is structural: the truth that decides id right here lives in a producer’s catalog, as a substitute of the characters of the string. What’s left? Automated merging solely the place normalization proves it protected, plus a human-adjudicated, effective-dated label layer that stays out of the mannequin totally — at 30 pairs upfront and roughly 4 a yr afterward.
Half 3 covers dynamic cadence and noise filtering — how briskly new identifiers present as much as be judged. Following that, Half 4 covers idempotent storage and immutable snapshots, the place versioned labels meet sealed data.
The reference implementation is anchorkey, Apache-2.0, sitting beneath device-identity layers like Eclipse Ditto and Eclipse Hono, each of which assume {that a} secure machine id already exists.
If in case you have fought this in your individual pipelines — particularly when you discovered a matcher that did maintain up on quick codes — I’d genuinely like to listen to about it.
Reproducing the info
Each quantity comes from one re-runnable seize of the general public openSenseMap API, launched below the Public Area Dedication and License 1.0:
The seize is 719 bins taken at 2026-06-26 UTC, yielding 114 distinct sensorType strings and 4,301 observations. Reside counts drift, which is the topic of this sequence; so each determine derives from the archived snapshot, deposited at DOI 10.5281/zenodo.20989076.
4 scripts regenerate each quantity quoted above, every cross-checking its output in opposition to the values asserted right here and exiting non-zero on a mismatch: collapse_sample.py (the 114 → 99 discount), keyshape_sample.py (inhabitants figures), separability_sample.py (each rating in Desk 1), and review_queue_sample.py (queue, blocking, value, and the alias blind spot). A fifth, make_figures.py, attracts Figures 1 and a pair of.
The bottom fact is a checked-in artifact, not an appendix declare. ground_truth_catalog.csv data for every of the 16 strings — the producer, official half identify, datasheet URL, lifecycle standing, entry date and verdict — together with the string I couldn’t resolve, and the three rows whose solely obtainable datasheet is a mirror moderately than a manufacturer-hosted copy. These limits are recorded per row moderately than smoothed over as a result of a catalog assertion sourced from a mirror is precisely the error this text is about.
References
Each entry is cited at a selected declare above, with the part bracketed.
I. Fellegi and A. Sunter, A Idea for Document Linkage, JASA 64(328), 1969. [Why a sixth metric doesn’t save this]
W. Cohen et al., A Comparability of String Distance Metrics for Identify-Matching Duties, IIWeb, 2003. [What normalization left behind]
P. Christen, Knowledge Matching, Springer, 2012. [Why a sixth metric doesn’t save this]
P. Konda et al., Magellan: Towards Constructing Entity Matching Administration Methods, PVLDB 9(12), 2016. [Why a sixth metric doesn’t save this]
Y. Li et al., Deep Entity Matching with Pre-Educated Language Fashions, PVLDB 14(1), 2020. [Why a sixth metric doesn’t save this] Additionally referred to as Ditto; unrelated to Eclipse Ditto under.
M. Hernández and S. Stolfo, The Merge/Purge Drawback for Giant Databases, SIGMOD, 1995. [What the deferral actually costs]
A. McCallum et al., Environment friendly Clustering of Excessive-Dimensional Knowledge Units with Software to Reference Matching, KDD, 2000. [What the deferral actually costs]
A. Broder, On the Resemblance and Containment of Paperwork, SEQUENCES, 1997. [What the deferral actually costs]
Unicode Commonplace Annex #15, Unicode Normalization Types [What normalization left behind]
Eclipse Ditto · Eclipse Hono [Summary]
Producer datasheets for the categorized components (Bosch Sensortec, TI, Sensirion, Aosong, Nova Health), per row in ground_truth_catalog.csv. [Building a ground truth]
openSenseMap, public citizen-science sensor community. [Reproducing the data]
Internet sources accessed 2026-08-14. Producer datasheets carry per-row entry dates in ground_truth_catalog.csv.