



Benchmarks determine what will get constructed. A mannequin that scores nicely on the Open ASR Leaderboard will get adopted and iterated on, whereas capabilities the leaderboard doesn’t measure have a tendency to not enhance. A lot of the latest work on the leaderboard has gone into making the analysis metrics extra reliable:
Held-out personal splits.
Benchmark-fitting evaluation to quantify how a lot fashions are reproducing reference transcripts slightly than transcribing solely on the audio.
Closing the gaps in normalisers to make sure right predictions/variants usually are not penalized.
All of that makes one quantity (WER) tougher to sport. It’s nonetheless one quantity. An extended line of labor has proven that ASR error charges usually are not evenly distributed throughout the individuals utilizing them. Racial disparities in automated speech recognition discovered business programs roughly twice as dangerous for Black audio system as for white audio system, and Quantifying Bias in Automated Speech Recognition discovered additional variations by gender, age and accent. None of that’s seen on a leaderboard, and never as a result of the leaderboard is hiding it. The take a look at units it runs on document what was stated and virtually nothing about who stated it.
To handle this hole, we introduce two analysis units to the Open ASR Leaderboard: Monsoon en-IN and Monsoon hi-IN. Hindi, spoken by greater than half a billion individuals, is the primary Indic language on a multilingual tab that at the moment covers solely European languages. Every set is launched as a public break up, accessible for self-scoring, and a non-public break up withheld to restrict benchmark-specific optimisation. The 4 splits are speaker-disjoint, comprising 4,888 audio system, with 12 speaker attributes recorded for every.
Design of the gathering
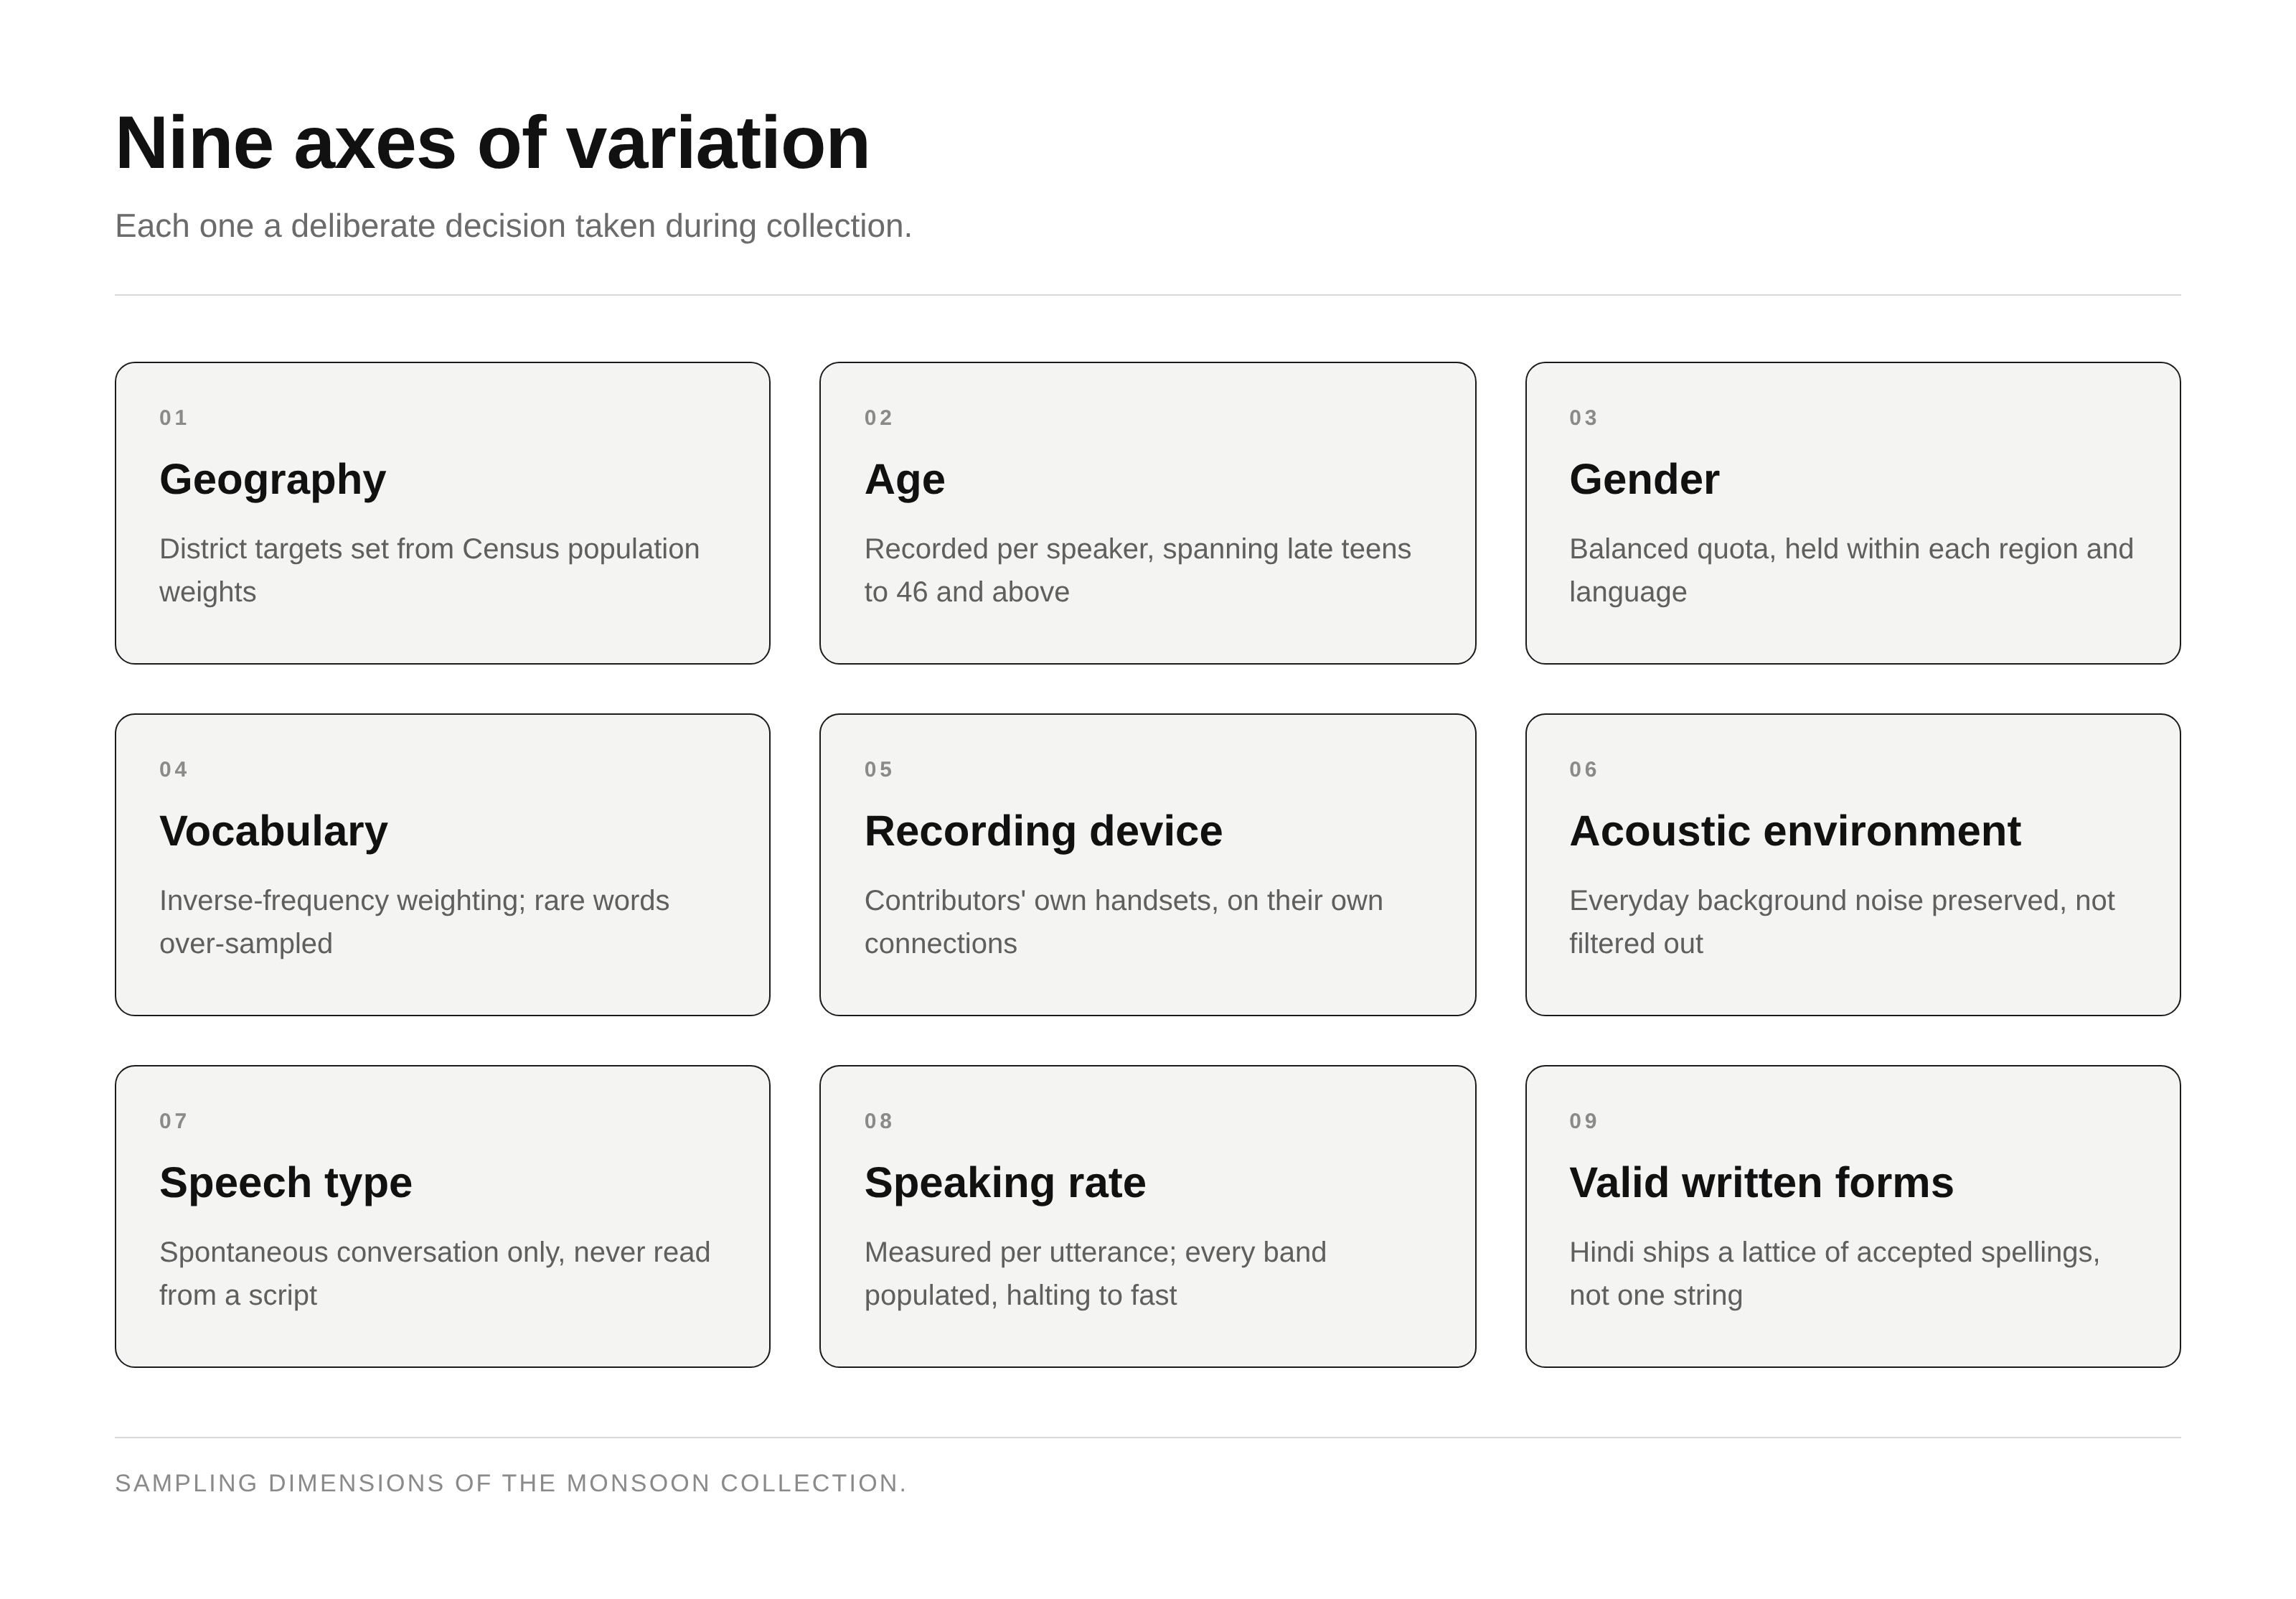
A take a look at set can solely expose a failure mode it varies alongside. Most benchmarks are constructed from no matter audio was available. Monsoon was constructed to fluctuate alongside 9 axes: geography, age, gender, vocabulary, gadgets, acoustic environments, speech kind, speech fee, and the existence of a number of legitimate transcripts for a similar audio. Every is a manner an mixture WER may be proper on common and flawed for a specific inhabitants.
The gathering technique follows from that.
Geography comes from recruiting throughout lots of of districts slightly than recording longer periods in fewer locations.
Gadgets and acoustic situations come from contributors utilizing their very own handsets and connections, indoors and out, slightly than equipped {hardware} in a quiet room.
Vocabulary, speech kind and speech fee come from the prompts: on a regular basis subjects that push contributors towards opinion, disagreement, narration and recall, which is the place named entities, numbers and unrehearsed phrasing seem.
Age and gender are recorded per speaker and verified.
A number of legitimate transcripts is a property of the reference slightly than the audio, and it’s the topic of a later part.
Dataset composition
4 splits, two languages, collected by way of one pipeline.
Set
Language
Period
Audio system
Clip size (imply / median)
M/F
Districts
States/UTs
Gadgets
Fashion
Transcription
Monsoon en-IN public
Indian English
5.62 h
1,444
9.6s / 10.4s
50/50
428
24/6
556
Conversational, spontaneous
Normalised, disfluencies
Monsoon en-IN personal
Indian English
5.58 h
1,405
9.6s / 10.4s
45/55
420
24/6
560
Conversational, spontaneous
Normalised, disfluencies
Monsoon hi-IN public
Hindi
1.33 h
468
6.4s / 5.0s
54/46
202
11/3
315
Conversational, spontaneous
Lattice (accepted orthographic variants)
Monsoon hi-IN personal
Hindi
4.47 h
1,571
6.6s / 5.3s
55/45
295
12/3
582
Conversational, spontaneous
Lattice (accepted orthographic variants)
The info is sourced from unscripted dual-channel spontaneous conversations, with clips segmented from a single channel so that every clip carries one speaker. Together with the fields reported within the desk, every clip additionally data occupation, training, marital standing, earnings band, handset model, present metropolis and years within the present district.
5 clips from the general public Indian English break up, with the metadata every one carries:
29-year-old lady, West Tripura, Tripura. Pupil, samsung SM-G781B.
32-year-old lady, Satna, Madhya Pradesh. Unemployed, samsung SM-E146B.
22-year-old man, Rohtas, Bihar. Pupil, motorola moto g54 5G.
27-year-old lady, Warangal, Telangana. Unemployed, vivo V2247.
57-year-old man, Puducherry. Personal job, Xiaomi M2006C3LI.
The English units use commonplace string references, the place the leaderboard’s normaliser collapses most spelling variation. Hindi has way more of it, and no normaliser can resolve it, as a result of the variants usually are not a hard and fast mapping between two conventions. The Hindi units subsequently ship a lattice: for every span of the transcript, a listing of the spellings which are accepted as right.
Speaker protection
Monsoon is small measured in hours and enormous measured in audio system. That’s the design, and it’s the place a lot of the worth sits.
Speaker focus and variety past the fields above.
Monsoon hi-IN public
Monsoon hi-IN personal
Monsoon en-IN public
Monsoon en-IN personal
Segments per speaker (imply)
1.61
1.56
1.46
1.48
Audio system with a single phase
261
994
956
924
Audio per speaker (median)
8.34 s
8.28 s
12.36 s
12.39 s
Share held by prime 10 audio system
6.8%
3.1%
2.8%
2.9%
Present cities
289
814
641
584
Gadget producers
18
25
23
20
Three properties comply with, and every is a declare about variance slightly than quantity.
No voice carries the rating: The ten largest contributors account for between 2.8% and 6.8% of whole period, and greater than half of all audio system seem precisely as soon as. A consequence on Monsoon is a median over lots of of distinct voices, not a small variety of talkers recorded at size. Check units of comparable period are often constructed the opposite manner.
No area or handset carries it both: The Indian English public set attracts on 428 native districts throughout 30 states and union territories; the Hindi units, being a Hindi-belt language, focus extra tightly however nonetheless span 202 and 295 districts. Recordings come from 315 to 582 distinct gadget fashions, with no single mannequin exceeding 2.1% of segments in any subset. Corpora collected on standardised {hardware} overfit to at least one microphone response; this one can’t.
Indian English right here will not be one accent: That is English as it’s spoken throughout the nation, not the English of 1 area. All six zones are represented: within the public set, 35% of segments are contributed by southern audio system, 18% from the East, 18% from Central, 16% from the North and 11% from the West. The accent variation that follows from that unfold is recorded within the metadata slightly than asserted.
Metadata fields
Monsoon ships 18 columns per phase, of which 12 are metadata, the place most public ASR take a look at units ship an identifier, a transcript and a period. Demographic fields are full or near-complete; contributors consented to this use.
Group
Fields
Phase
id, audio, audio_length_s, language
Reference
lattice (Hindi) or textual content (Indian English)
Speaker
speaker_id, gender, date_of_birth
Background
occupation, educational_background, marital_status, earnings
Geography
native_district, native_state, current_city, years_spent_in_current_district
Recording
device_manufacturer, device_model
The 2 languages have totally different geographic shapes, and the form is informative. The Hindi units focus within the Hindi belt, with Uttar Pradesh accounting for roughly 40% of audio system, which is what a Hindi corpus sampled by inhabitants ought to appear to be. The Indian English units are a lot flatter: no state exceeds 13%, and a 3rd of audio system come from outdoors the eight largest. Private and non-private halves match intently on each.
Indian state boundaries had been drawn alongside linguistic strains, so district and state carry actual accent sign, which is why these fields are launched slightly than summarised away. Evaluation of this sort has been reported at scale for Indian ASR: district-level error charges spanning roughly 4% to 44%, with underrepresented areas nicely behind the Hindi belt and the metros, plus disaggregation by audio high quality, talking fee, utterance period, gender, age and gadget. These runs had been on a closed benchmark. Monsoon makes the identical class of study attainable on a public leaderboard take a look at set.
Assortment and high quality management
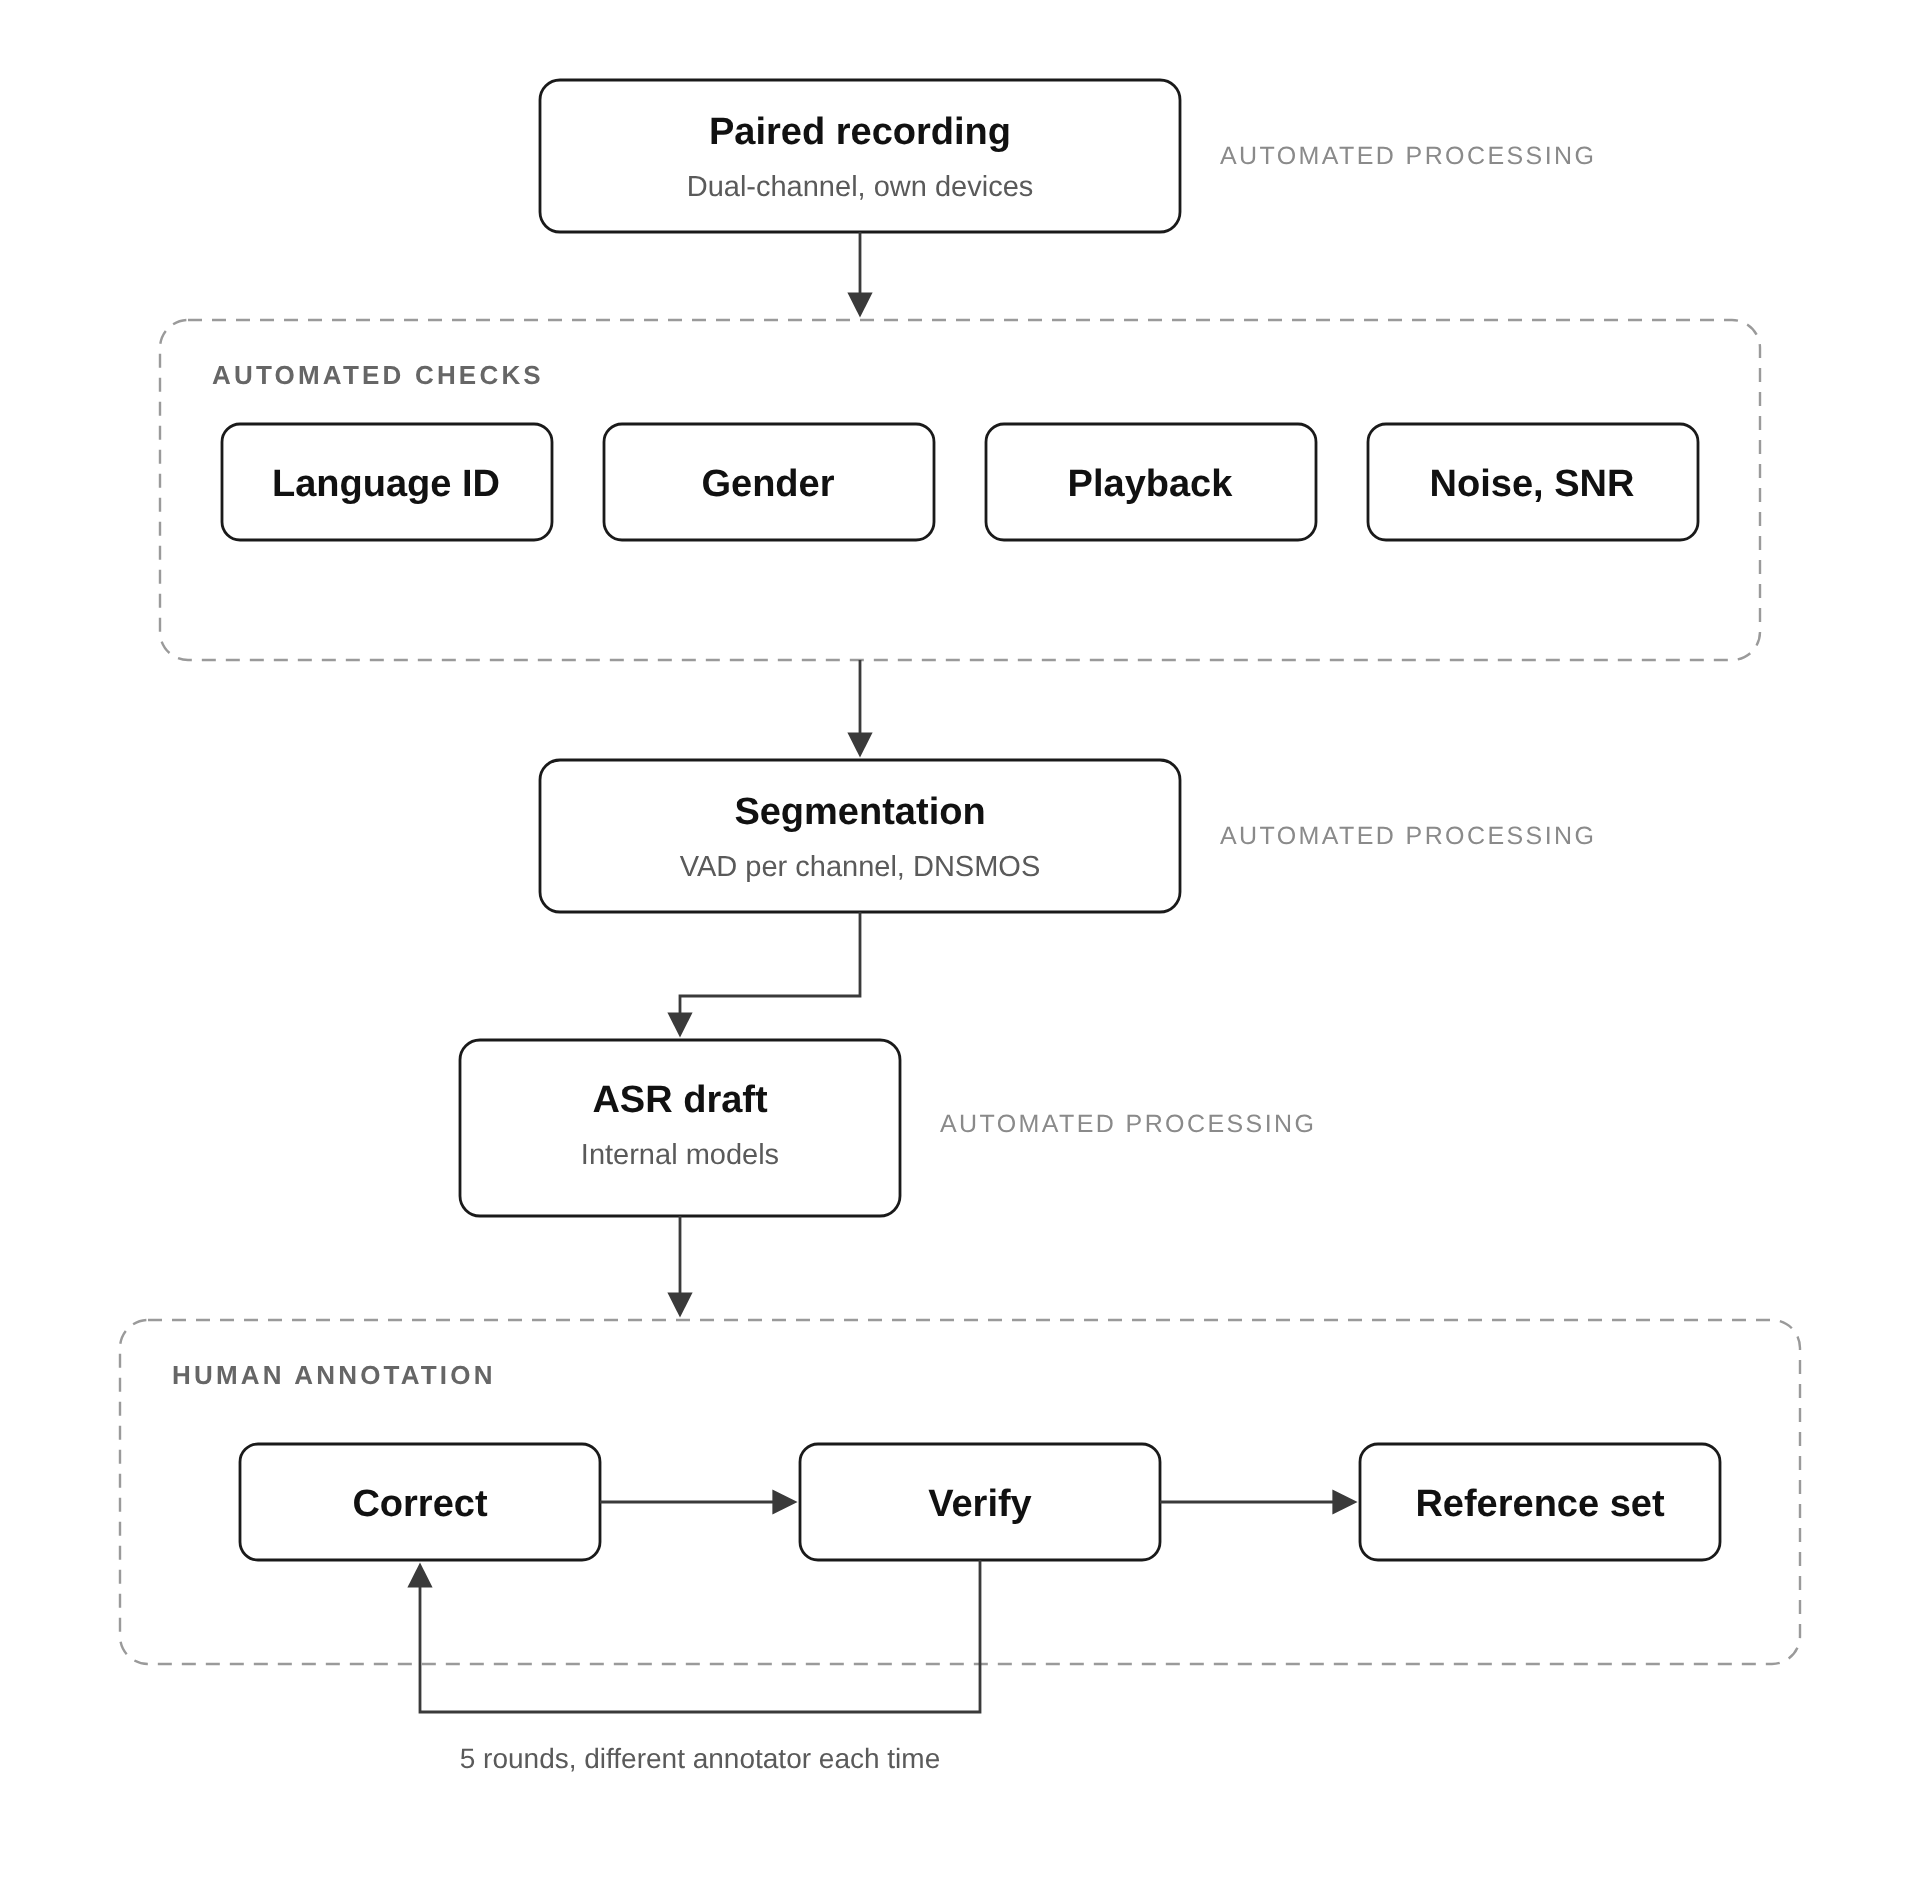
Broad geographic protection requires recruitment throughout lots of of districts slightly than longer periods from fewer audio system, and distributed recruitment at this scale introduces failure modes {that a} smaller assortment doesn’t face: contributors gaming the duty, played-back audio submitted as dwell speech, and inattentive annotation. Every is addressed by an specific test.
Recruitment and recording: Contributors had been recruited by way of the Voice Area neighborhood, a worldwide digital platform whose attain extends into the agricultural and semi-urban districts that speech corpora hardly ever cowl. Pairs then recorded two-person conversations over a peer-to-peer interface, dual-channel, on assigned on a regular basis subjects. Contributors used their very own handsets and their very own connections. Lots of these are low-end gadgets on unstable bandwidth, which is why that situation is current within the launched audio slightly than filtered out of it. Potential contributors accomplished a language proficiency screening earlier than being granted recording entry, had been compensated, and supplied knowledgeable consent overlaying use in coaching and distribution. A per-speaker period cap, calibrated per language to the inhabitants measurement and geographic distribution of its audio system, prevented a small variety of prolific contributors from dominating a language or area; greater than half of the audio system in these units contribute precisely one phase.
Elicitation: Eliciting spontaneous speech at scale presents its personal issue, as contributors have a tendency to provide quick and sparse responses with out structured steerage. Every dialog was subsequently seeded with an open-ended narrative cue and progressively revealed follow-up questions, spanning domains together with journey, healthcare, agriculture, training and digital providers, guiding the trade towards prolonged description with out scripting it. Candidate subjects had been generated with massive language fashions, then reviewed and localised by native-speaker linguists.
High quality management: Each recording handed a set of gating checks previous to transcription. The spoken language was verified in opposition to the assigned language utilizing language identification fashions educated on human-annotated information throughout greater than 30 languages. Speaker gender was confirmed in opposition to the self-reported label utilizing a devoted classifier, utilized as corroboration of the self-report slightly than as a alternative for it. An extra mannequin distinguished real spontaneous dialog from pre-recorded or played-back audio. Sign-to-noise ratio estimation eliminated recordings degraded past intelligibility, whereas pure environmental background noise was intentionally preserved in order that the acoustic realism of in-the-wild speech is retained. Recordings clearing these checks had been segmented by voice exercise detection, break up at two seconds of steady silence or at a fifteen-second tender cap closed on the subsequent detected silence. Segmentation was utilized independently per channel, so each phase is single-speaker and single-channel. Segments then handed a DNSMOS P.808 test.
Transcription: Reference transcripts are human work. A primary draft was generated by inner ASR fashions educated on in-domain information, none of which seem on any public leaderboard, so no system evaluated on these units contributed to the references it’s scored in opposition to. Each subsequent stage was carried out by native-speaking linguists beneath a five-level protocol constructed on a strict separation of labour, by which every correction spherical is adopted by an impartial verification spherical carried out by a distinct annotator, so no linguist audits their very own output. A linguist first corrects the draft phase by phase in opposition to the acoustic sign; a second re-verifies it and flags residual disagreements. Subsequent ranges iterate this cycle with recent annotators, progressively resolving ambiguous phonetic realisations, code-switching boundaries, named entities, and orthographic consistency throughout spelling variants. Numerals are written as phrases, in order that the transcript corresponds on to what was spoken. Segments nonetheless flagged on the closing stage had been returned for re-transcription earlier than admission. Annotator behaviour was monitored mechanically all through, flagging submissions containing characters outdoors the goal script, unnatural character or phrase repetitions, and unusually low or excessive edit counts.
Regional variation
What follows is one instance, run on the general public Indian English break up, to indicate the form of analysis the metadata makes attainable. It isn’t the discovering the units exist to ship; it’s an illustration of what turns into answerable as soon as each clip carries a speaker.
Eight fashions on the leaderboard land between 4.81 and 4.99 WER on this set. That’s 0.18 factors from finest to worst, inside what 5 hours can resolve. Ranked on the corpus, they’re the identical mannequin.
Grouping audio system by area tells a distinct story. Every speaker’s native district is rolled as much as its zonal council, the Ministry of Residence Affairs grouping of Indian states, giving 5 well-sampled zones. openai/whisper-large-v3-turbo varies by 0.46 factors throughout them. mistralai/Voxtral-Mini-3B-2507, fourteen hundredths of a degree behind it on the corpus, varies by 1.68, working 4.38 within the Central zone in opposition to 6.06 within the East. Two programs which are indistinguishable on the leaderboard differ virtually fourfold in how a lot their accuracy is determined by the place the speaker is from.

Which zone is hardest will not be mounted both. ibm-granite/granite-speech-3.3-2b is worst within the North, microsoft/VibeVoice-ASR-HF within the South, mistralai/Voxtral-Mini-3B-2507 within the East. If a single area had been merely tougher to transcribe, each mannequin would rank the zones the identical manner. They don’t, which factors on the fashions slightly than the audio.
Area is one among twelve recorded attributes, and the zones above are a rough rollup of 428 districts. The identical breakdown runs on age, training, occupation and handset, and the launched information carry the whole lot wanted to breed it. None of it’s accessible for a take a look at set that data solely what was stated.
Orthographic variation in Hindi
English orthographic variation is bounded. British in opposition to American spelling, punctuation, casing, digits in opposition to phrases: a normaliser can map most of it to a single type, and the leaderboard’s does. Hindi will not be bounded in the identical manner. On a regular basis speech is closely code-mixed, English-origin phrases haven’t any settled Devanagari spelling, and compound kinds are written joined or separated in accordance with choice. A single phrase can have ten or extra legitimate written kinds, and no mounted mapping collapses them, as a result of there is no such thing as a canonical facet to map to.
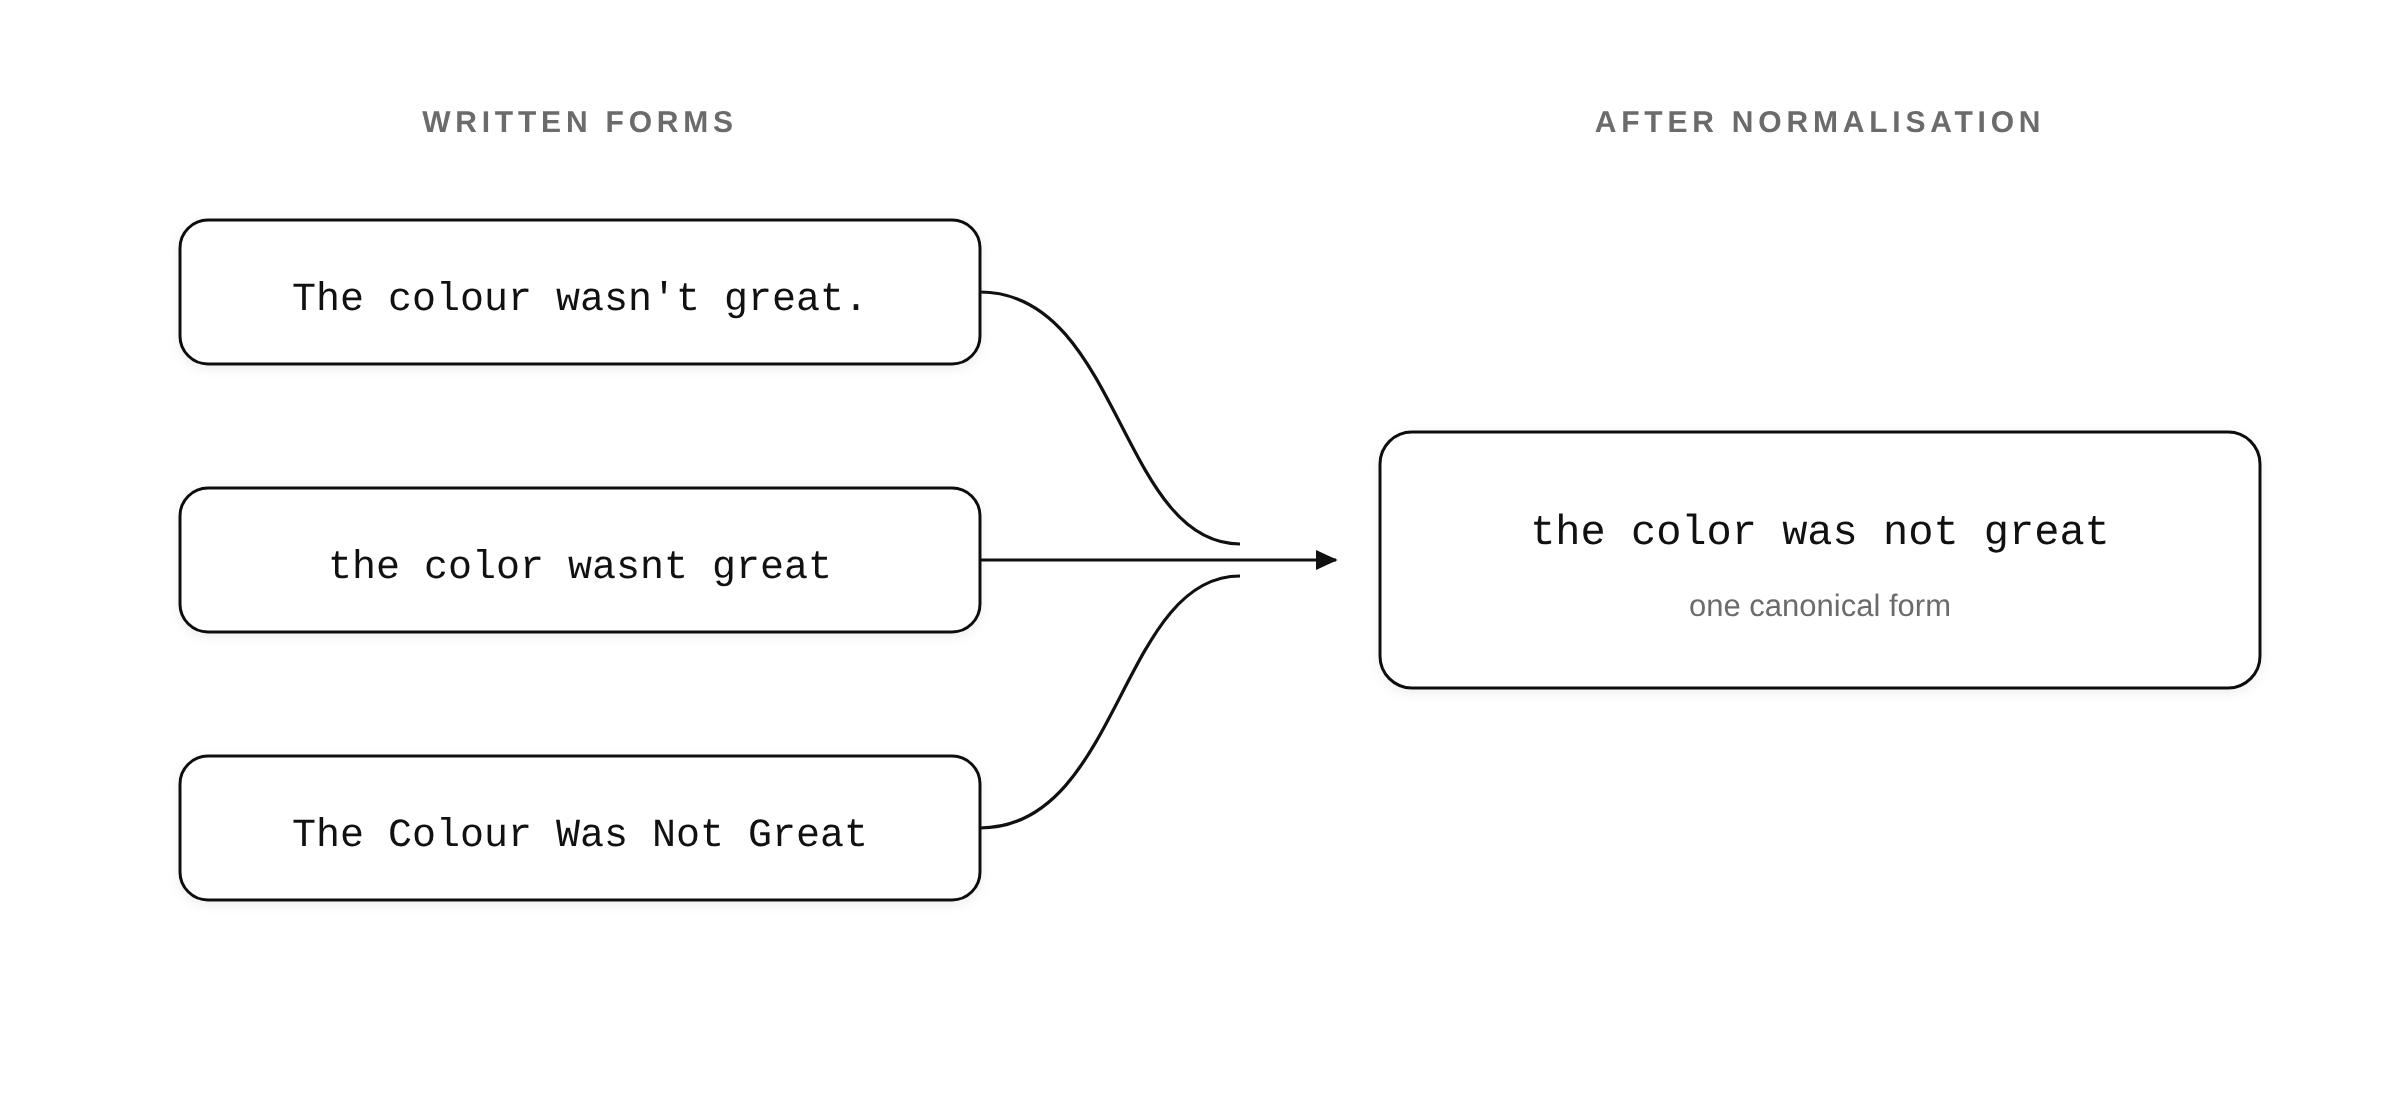
Scored with a single reference, WER rewards a system for producing the spelling the annotator occurred to decide on. Two programs that recognised the audio equally nicely can differ by a number of factors on orthography alone.
The Hindi units subsequently ship a lattice: for every span of the transcript, the set of written kinds accepted as right. Constructing it’s guide work. Candidate variants are drawn from a number of ASR transcripts of the identical audio and expanded with language fashions, then native-speaker linguists determine that are legitimate for that utterance and prune the remaining, so solely kinds per what was stated are admitted.
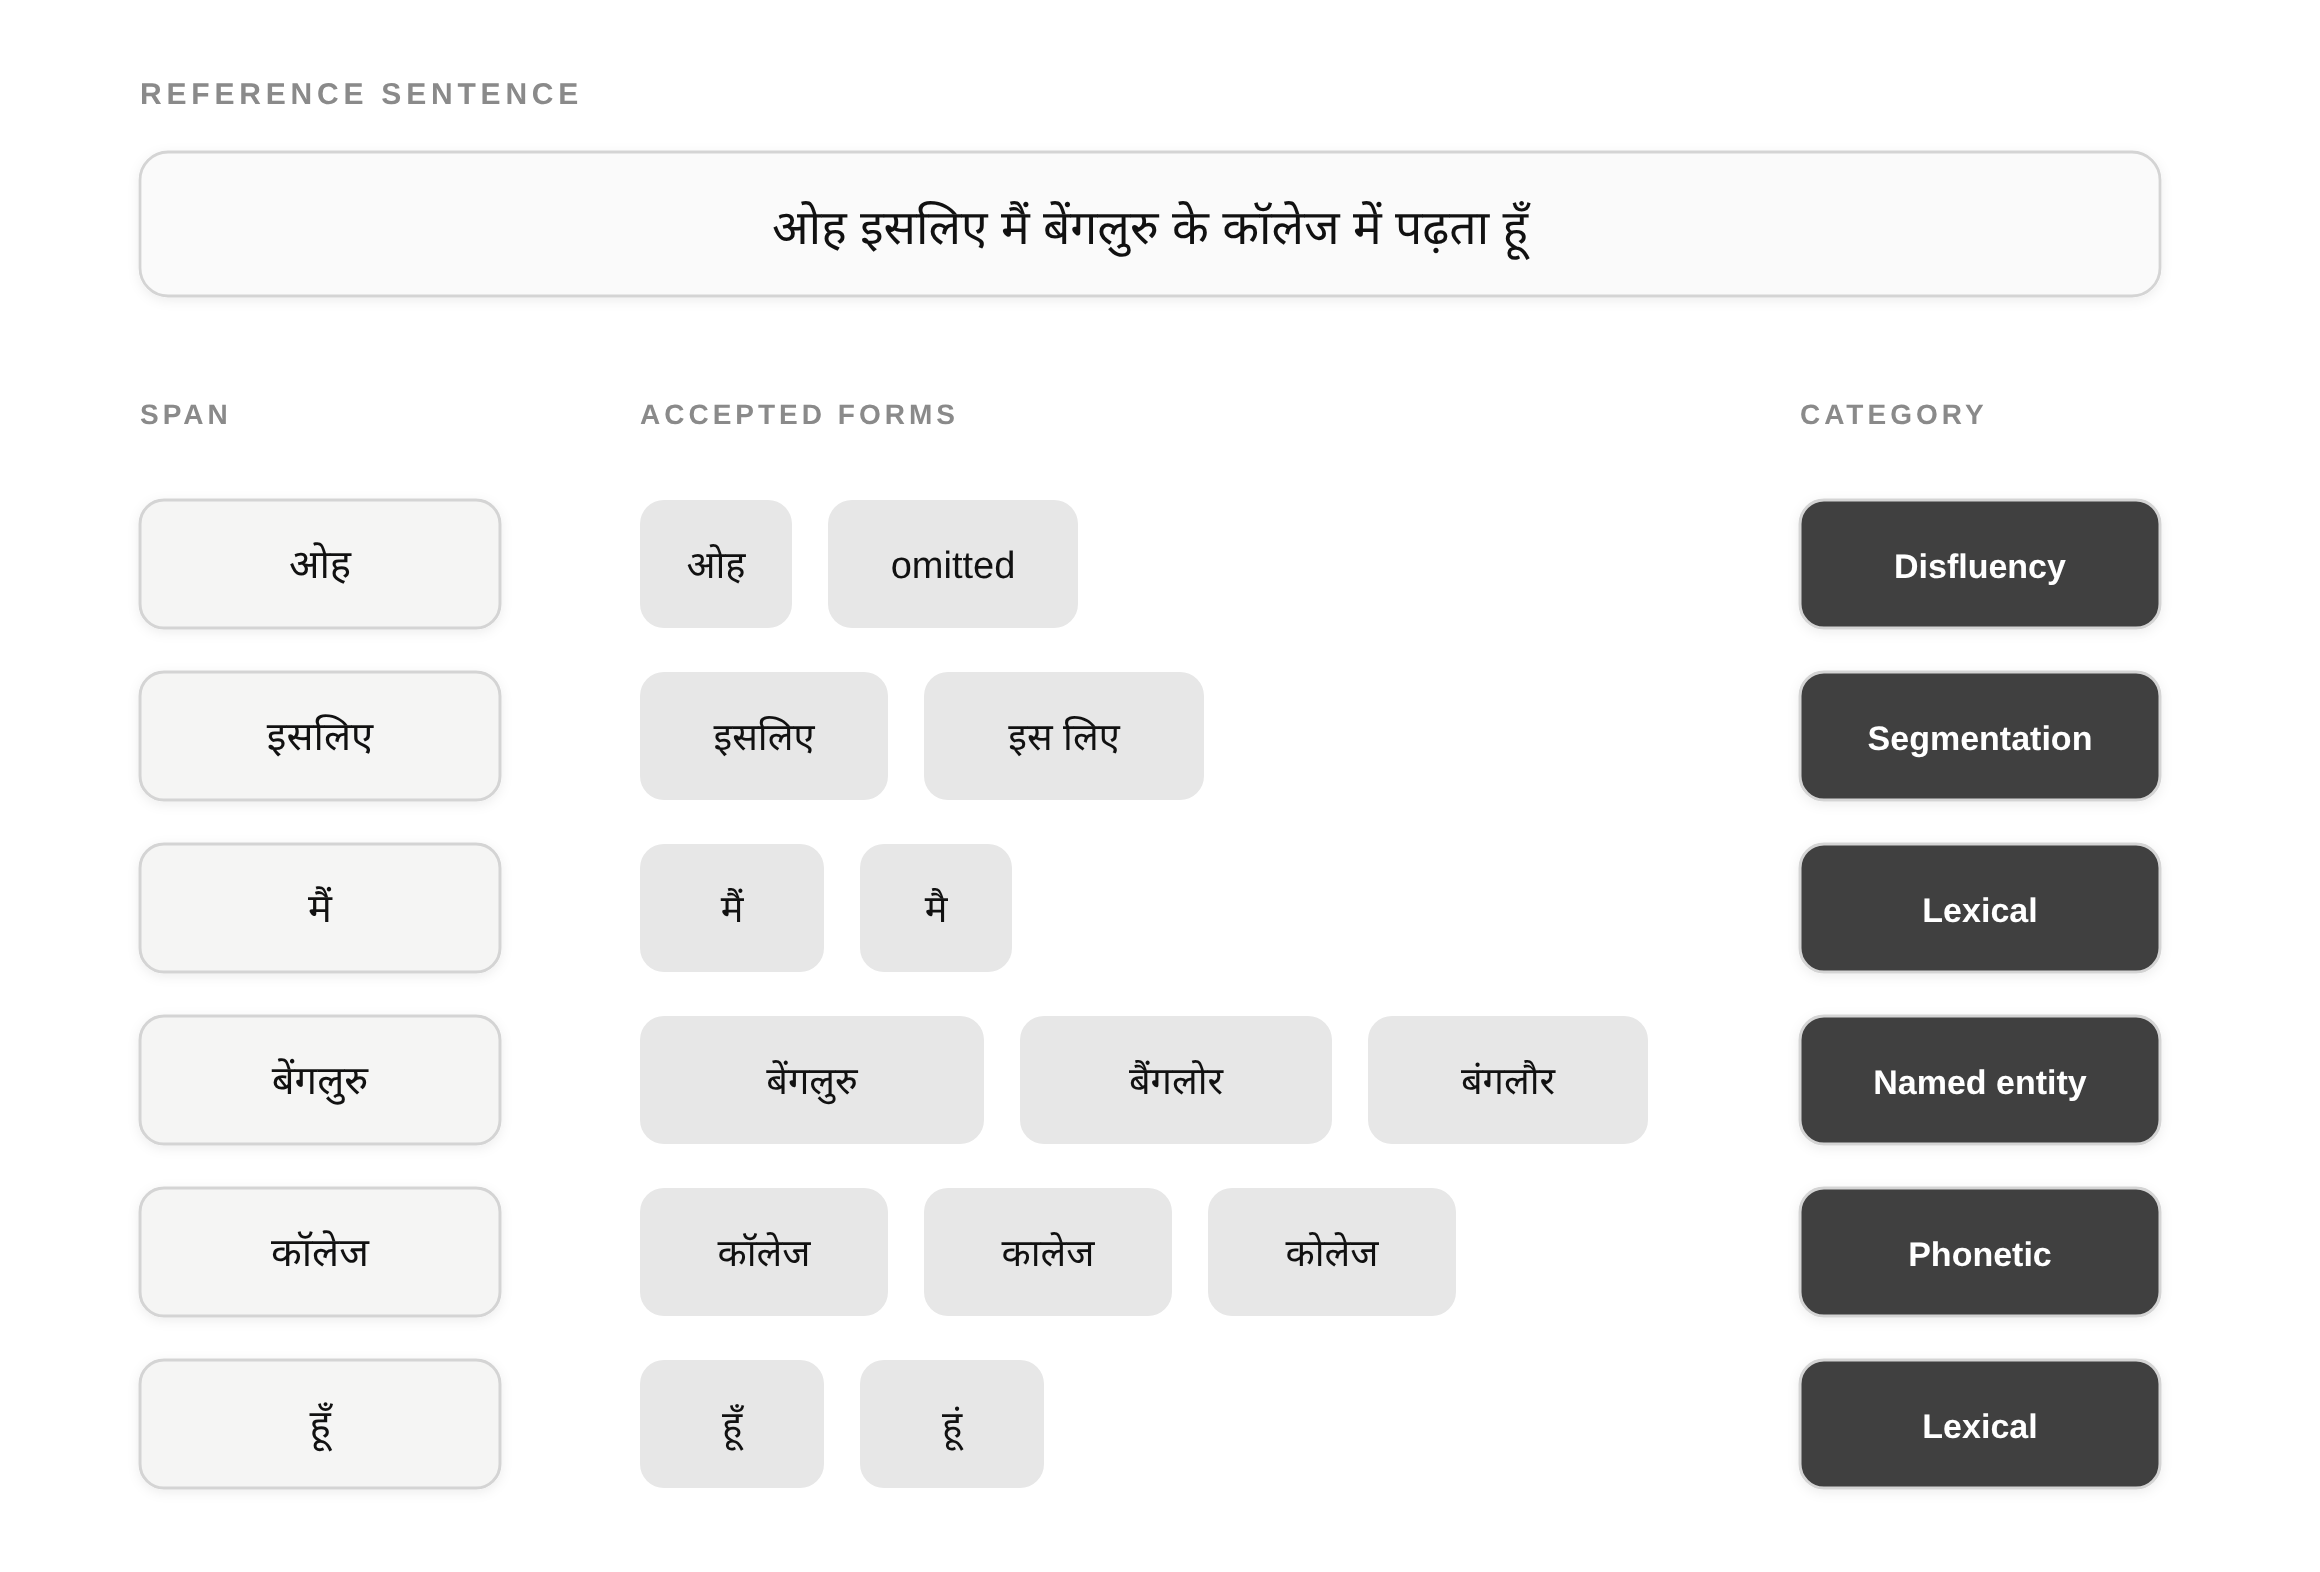
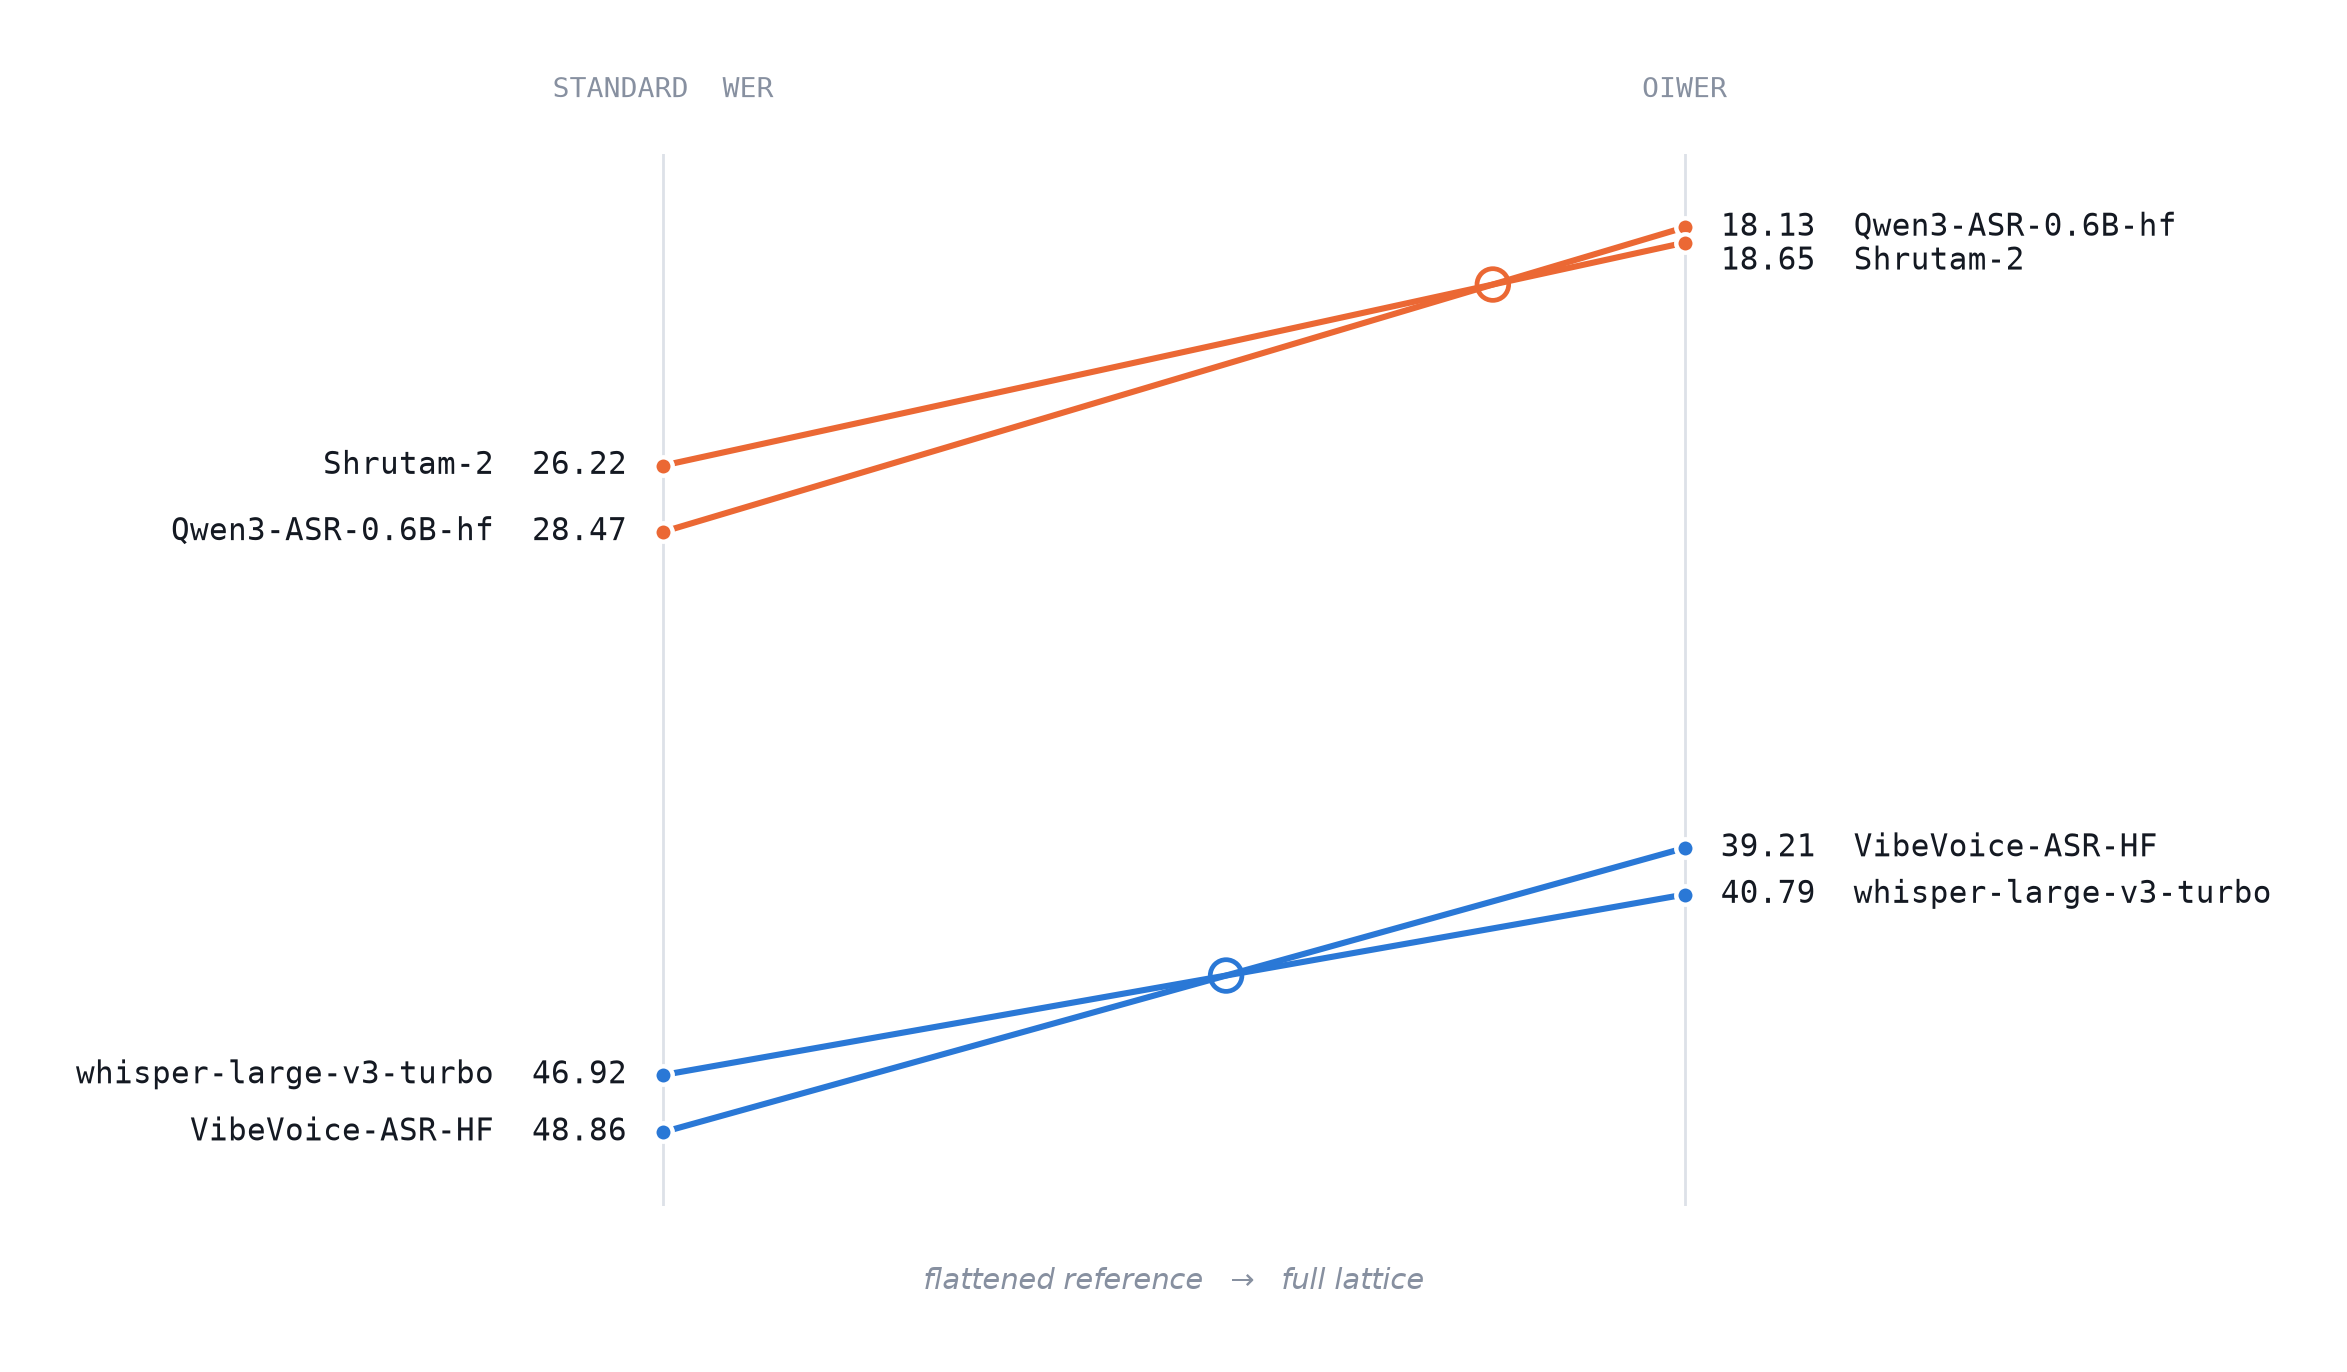
Thus, for Hindi we report the Orthographically-Knowledgeable Phrase Error Charge (OIWER), launched by AI4Bharat, as a substitute of WER. A speculation is aligned in opposition to the accepted set at every span, so any admitted type counts as right and solely real recognition errors are charged.
To quantify the impact, the identical hypotheses had been scored twice. Flattening every lattice to its first variant per span yields a single string reference of the type a standard benchmark offers; any of the admitted variants would serve equally nicely, and a distinct alternative would yield a distinct reference. Scored in opposition to the flattened reference, error charges rise for each system, and they don’t rise uniformly. Rankings change as a consequence. The determine beneath exhibits two pairs of programs that reverse order between the 2 references: beneath a single reference a system is rewarded partly for reproducing the annotator’s orthography, whereas the lattice scores solely recognition.
We additionally open supply our implementation, voi-oiwer, so each consequence on these units may be reproduced instantly.
Getting evaluated
For the personal splits, get your mannequin on the Open ASR Leaderboard and the Hugging Face staff will run the analysis. As earlier than, the method for including a mannequin to the leaderboard takes place on the Open ASR Leaderboard GitHub:
Open a pull request, a mannequin guidelines will seem. As earlier than, it’s best to report your outcomes on the general public datasets.
We’ll confirm the outcomes on the general public units and compute the metrics on the personal ones.
Verify the outcomes we have obtained.
Indian-English joins the primary leaderboard as Voice Area Monsoon, within the default column set slightly than as an opt-in toggle, so it contributes to the headline Common WER for each mannequin. The personal break up feeds the aggregated Personal (conversational) column alongside Appen and DataoceanAI information. The private and non-private Hindi seems within the Multilingual tab, the place a mannequin is ranked provided that it helps each chosen language, making that column a like-for-like comparability. Different, choose “Hindi” from the “Language dataset breakdown” dropdown menu.
What comes subsequent
Hindi is a pointy case of a normal downside. Any language written multiple manner, spoken by individuals a benchmark has not sampled, carries each of the failures described right here. These units don’t repair them. What they add is a approach to see them: a take a look at set on a leaderboard the sphere already watches, carrying sufficient about every speaker and every reference {that a} distinction between two programs may be traced to who was speaking and the way they write it, as a substitute of disappearing into one quantity.
These 4 units are a part of Monsoon, Voice Area’s broader dataset initiative for the World South.

