Agentic AI analysis in 2026 has moved previous the fundamental query of whether or not a mannequin will be known as a software. The more durable questions are whether or not an agent can end lengthy workflows, survive dwell web sites, confirm its personal work, recuperate from failure, and enhance its course of over time.
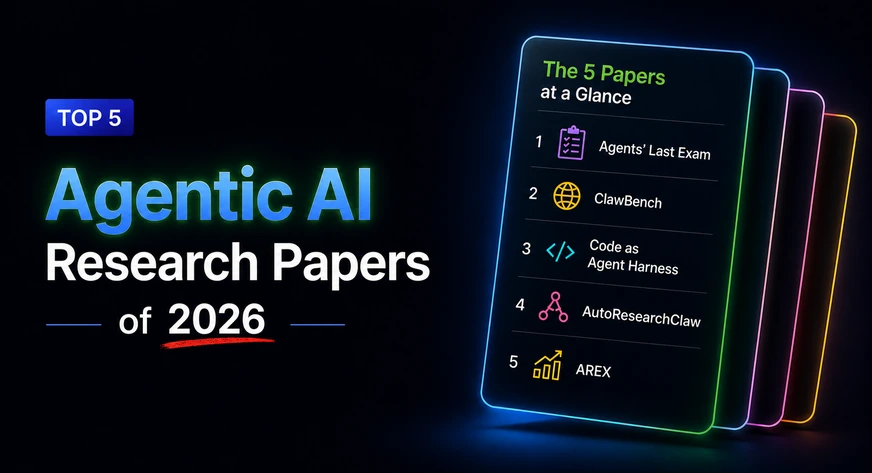
The 5 papers under map that shift nicely sufficient. Two give attention to analysis, one reframes code because the infrastructure round an agent, and two discover analysis methods that iterate on their very own work. Collectively, they’re a helpful snapshot of what the analysis in Agentic AI subject is attempting to resolve subsequent, from mannequin analysis to deep analysis.
#
Paper
Focus
Why it issues
1
Brokers’ Final Examination
Agent analysis
Can brokers end economically priceless skilled workflows?
2
ClawBench
Net brokers
What occurs when brokers should use actual, dwell web sites?
3
Code as Agent Harness
Agent infrastructure
Code because the runtime substrate for reasoning, instruments, state, and verification.
4
AutoResearchClaw
Autonomous analysis
A analysis pipeline that debates, repairs failures, verifies, and learns throughout runs.
5
AREX
Deep analysis brokers
A analysis agent that makes use of verification to recursively enhance its reply and course of.
1. Brokers’ Final Examination
CATEGORY
Agent Analysis
Brokers’ Final Examination (ALE) asks a extra sensible query than whether or not an AI can clear up a tough immediate: can it really end an expert workflow and ship one thing that may be checked?
Constructed with enter from 250+ business consultants, ALE covers 1,000+ duties throughout 55 subfields and 13 industries. The main target is on long-horizon execution and measurable outcomes, giving a clearer image of how brokers carry out when the work resembles what individuals really do.
What the paper discovered
The toughest tier was nowhere close to solved at publication: mainstream agent harness and spine configurations averaged a 2.6% full-pass price.
Partial progress shouldn’t be sufficient. The benchmark is designed round workflows the place the ultimate deliverable should fulfill a verifiable goal.
ALE is meant to be a dwelling benchmark, so its job pool can broaden as new industries and workflows are added.
TAKEAWAY ALE turns ‘can the mannequin purpose?’ into ‘can the system end the job?’ That may be a rather more helpful take a look at for real-world brokers.
2. ClawBench: Can AI Brokers Full On a regular basis On-line Duties?
CATEGORY
Net Brokers / Benchmarking
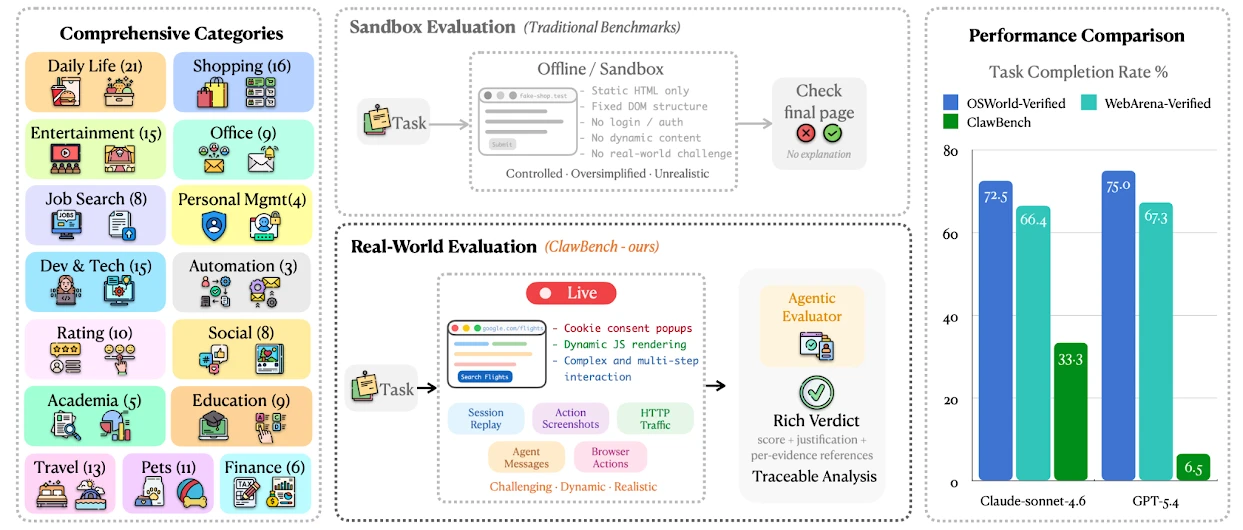
ClawBench exams AI brokers the place issues really get messy: on the dwell internet. It evaluates 153 on a regular basis duties throughout 144 platforms, protecting areas like buying, journey, hiring, finance, and workplace work.
That issues as a result of actual web sites introduce friction that clear benchmarks usually take away. Authentication, dynamic pages, lengthy varieties, paperwork, and surprising interactions all turn into a part of the problem, making the analysis a lot nearer to real-world agent use.
What the paper discovered
The benchmark captures 5 layers of conduct, together with session replay, screenshots, HTTP site visitors, agent messages, and browser actions.
A light-weight interception layer blocks the ultimate submission request so brokers will be examined on dwell websites with out finishing irreversible actions.
Throughout seven frontier fashions, the strongest outcome reported within the paper was solely 33.3% job completion.
TAKEAWAY If an agent is supposed to make use of the online for you, take a look at it on the net, not on a museum reproduction of the online.
3. Code as Agent Harness
CATEGORY
Agent Infrastructure
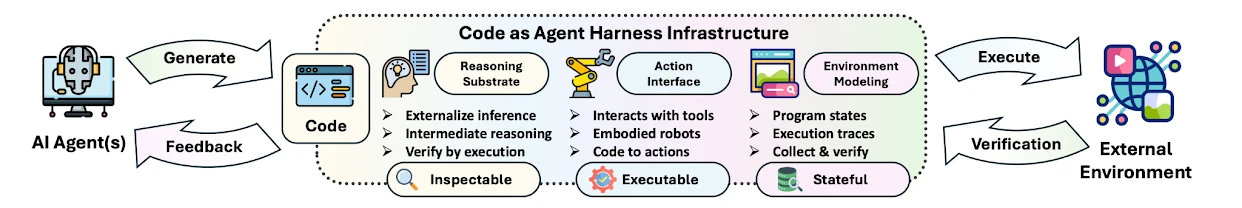
Code as Agent Harness takes a unique angle, specializing in the infrastructure behind succesful brokers somewhat than one other benchmark. It argues that code is changing into a part of how brokers purpose, act, preserve state, use instruments, and confirm their work.
The necessary shift is that code is now not simply the ultimate output. It could possibly function the layer connecting the mannequin to its surroundings, reminiscence, management circulation, instruments, and verification mechanisms.
The three layers
Harness interface: code connects reasoning to actions and surroundings fashions.
Harness mechanisms: planning, reminiscence, software use, suggestions, and optimization help longer and extra dependable execution.
Multi-agent scaling: shared code artifacts can coordinate brokers, protect shared state, help assessment, and confirm work.
TAKEAWAY A succesful mannequin can nonetheless be a foul agent if the runtime round it’s brittle. Harness engineering is changing into a first-class a part of agent design.
4. AutoResearchClaw: Self-Reinforcing Autonomous Analysis with Human-AI Collaboration
CATEGORY
Autonomous Analysis
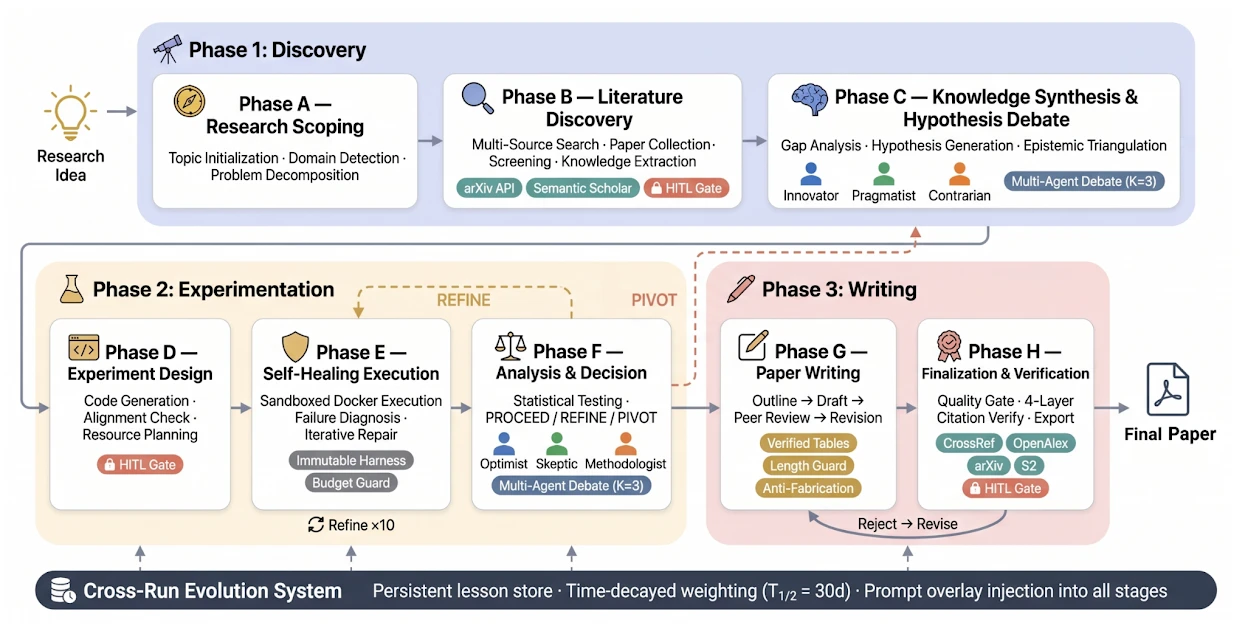
AutoResearchClaw treats scientific analysis as an iterative course of somewhat than a straight pipeline. It combines multi-agent debate, self-healing execution, verification, and human collaboration so the system can reply when experiments fail or concepts want to vary.
The fascinating half is the suggestions loop. As a substitute of merely producing a paper, the system can detect failures, select whether or not to refine or pivot, confirm outcomes, and carry helpful classes into future runs.
What stands out
Multi-agent debate is used throughout speculation era and outcome evaluation so one reasoning path doesn’t dominate unchecked.
The Pivot/Refine loop treats failed experiments as info. The system can restore an execution path or change route as an alternative of merely stopping.
The framework consists of seven human-intervention modes, starting from near-autonomy to step-by-step oversight.
On ARC-Bench, a 25-topic experiment-stage benchmark, the paper experiences a 54.7% enchancment over AI Scientist v2.
TAKEAWAY AutoResearchClaw treats analysis as an iterative system with checkpoints, repairs, and reminiscence, not a one-shot immediate that occurs to output a paper.
5. AREX: In direction of a Recursively Self-Bettering Agent for Deep Analysis
CATEGORY
Deep Analysis Brokers
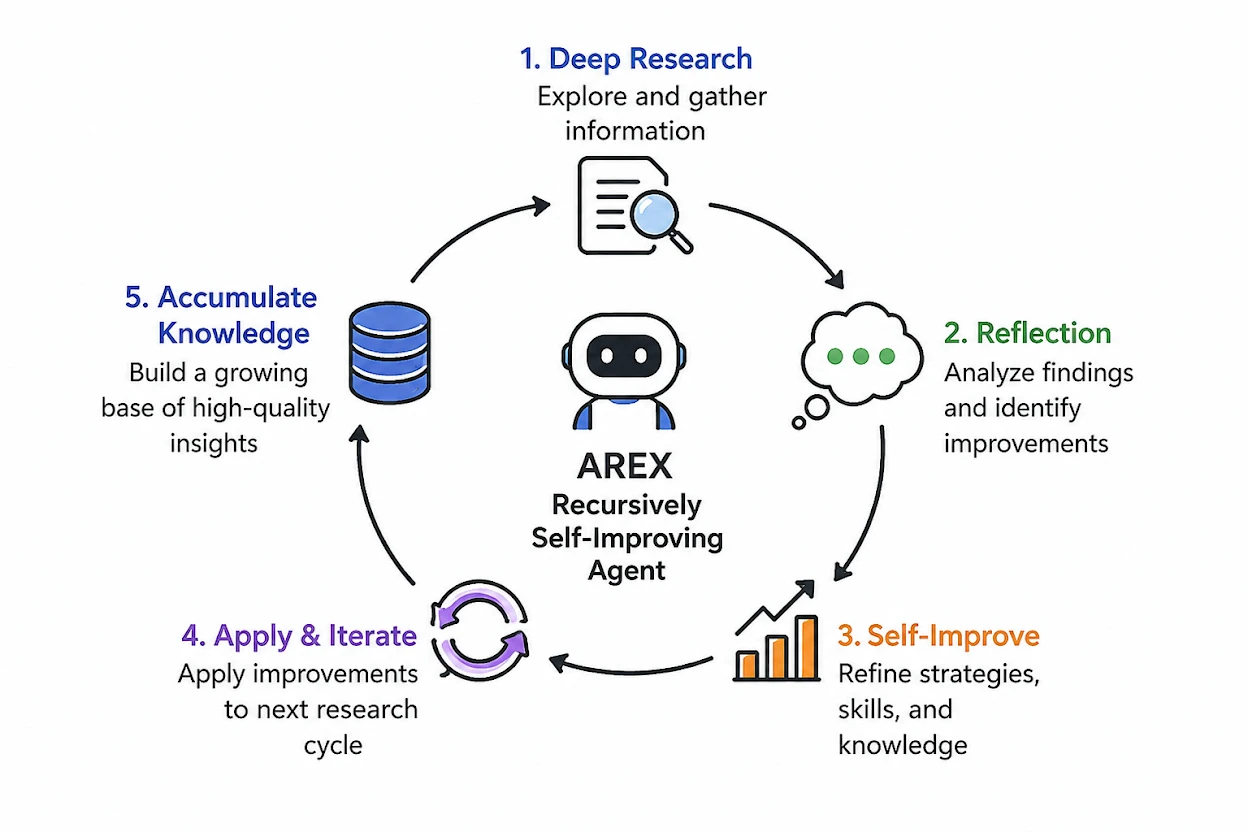
AREX takes a unique method to deep analysis. As a substitute of treating analysis and verification as the identical course of, it separates them. Discovering a solution could also be costly, however checking whether or not it satisfies a selected constraint will be a lot simpler.
The system makes use of two loops. One gathers proof and builds a solution, whereas the opposite audits it constraint by constraint. When one thing stays unsupported, AREX triggers focused follow-up analysis as an alternative of beginning your entire search over once more.
What makes it completely different
Constraint-wise verification separates discovery from checking, making it simpler to establish precisely what remains to be unsupported.
A discovered context-update software compresses lengthy interplay historical past right into a smaller enchancment state that preserves verified proof and unresolved constraints.
The paper trains each a dense 4B mannequin and a bigger mixture-of-experts mannequin utilizing agentic mid-training and long-horizon reinforcement studying.
AREX is evaluated throughout BrowseComp, WideSearch, DeepSearchQA, Humanity’s Final Examination, and different reasoning and tool-use benchmarks, the place the authors report sturdy outcomes towards comparable-scale baselines.
TAKEAWAY AREX makes verification a part of the analysis course of itself. The agent improves by narrowing uncertainty, not just by looking out longer.
What These Papers Reveal About Agentic AI in 2026
In case you’d take a better take a look at the earlier papers, a transparent sample emerges throughout them. Although they’re from various domains, they’re hinting in the direction of an total shift of the domains towards the next tangents:
Analysis is transferring from quick benchmark questions to finish, work-like duties with verifiable outcomes.
The harness issues. Fashions want state, instruments, execution, suggestions, and verification round them to behave like dependable brokers.
Failure is changing into a part of the loop. Newer methods attempt to diagnose dangerous makes an attempt, refine them, and protect helpful classes.
Autonomy is being paired with checks. Human approval, deterministic verification, and constraint-level audits seem repeatedly throughout the strongest work.
Learn extra: Agentic Misalignment Defined: When AI Brokers Go Rogue
Steadily Requested Questions
A. Begin with Brokers’ Final Examination for analysis, Code as Agent Harness for structure, or AutoResearchClaw in case you are particularly enthusiastic about autonomous analysis methods.
A. No. They’re a helpful recognition sign, however they don’t measure scientific rigor, reproducibility, or long-term influence.
A. AutoResearchClaw focuses on an end-to-end multi-agent scientific workflow with human collaboration. AREX focuses on deep analysis that recursively improves by constraint-wise verification and focused follow-up analysis.

Finding out, evaluating, and explaining AI methods for over 6 years.
“𝘖𝘯𝘤𝘦 𝘮𝘦𝘯 𝘵𝘶𝘳𝘯𝘦𝘥 𝘵𝘩𝘦𝘪𝘳 𝘵𝘩𝘪𝘯𝘬𝘪𝘯𝘨 𝘰𝘷𝘦𝘳 𝘵𝘰 𝘮𝘢𝘤𝘩𝘪𝘯𝘦𝘴 𝘪𝘯 𝘵𝘩𝘦 𝘩𝘰𝘱𝘦 𝘵𝘩𝘢𝘵 𝘵𝘩𝘪𝘴 𝘸𝘰𝘶𝘭𝘥 𝘴𝘦𝘵 𝘵𝘩𝘦𝘮 𝘧𝘳𝘦𝘦. 𝘉𝘶𝘵 𝘵𝘩𝘢𝘵 𝘰𝘯𝘭𝘺 𝘱𝘦𝘳𝘮𝘪𝘵𝘵𝘦𝘥 𝘰𝘵𝘩𝘦𝘳 𝘮𝘦𝘯 𝘸𝘪𝘵𝘩 𝘮𝘢𝘤𝘩𝘪𝘯𝘦𝘴 𝘵𝘰 𝘦𝘯𝘴𝘭𝘢𝘷𝘦 𝘵𝘩𝘦𝘮.” — 𝖥𝗋𝖺𝗇𝗄 𝖧𝖾𝗋𝖻𝖾𝗋𝗍, 𝖣𝗎𝗇𝖾
Login to proceed studying and luxuriate in expert-curated content material.
Preserve Studying for Free