


Each enterprise has helpful information trapped in messy, unstructured paperwork. At the moment, Databricks Doc Intelligence helps hundreds of shoppers put their information to work, turning billions of pages into structured information that powers manufacturing pipelines, brokers, and purposes. Prospects like Panasonic, EY-Parthenon, and Intercontinental Change (NYSE) use Doc Intelligence on their most demanding workflows, processing tens of millions of paperwork weekly.
When working with prospects, we seen a number of tough extraction issues the place current massive language mannequin (LLM) or rules-based doc extraction options fall quick:
Lengthy paperwork. A lease whose page-1 renewal phrases rely upon a clause on web page 80, or an settlement whose page-150 paragraph redefines a time period from web page 3. Present options fail to resolve these cross-references.Massive, nested outputs. A multi-page invoice of lading with tons of of SKUs, or an bill with hundreds of line objects. Present options drop or truncate fields as outputs develop.Advanced schemas and reasoning. A threat classification that synthesizes three monetary statements, or a contract worth that applies listed reductions throughout each recorded value. Present options fail to constantly apply the proper logic throughout paperwork.
At the moment, we’re excited to introduce Precision Mode in our doc extraction API, ai_extract, setting a brand new bar for accuracy on essentially the most advanced enterprise paperwork and duties.
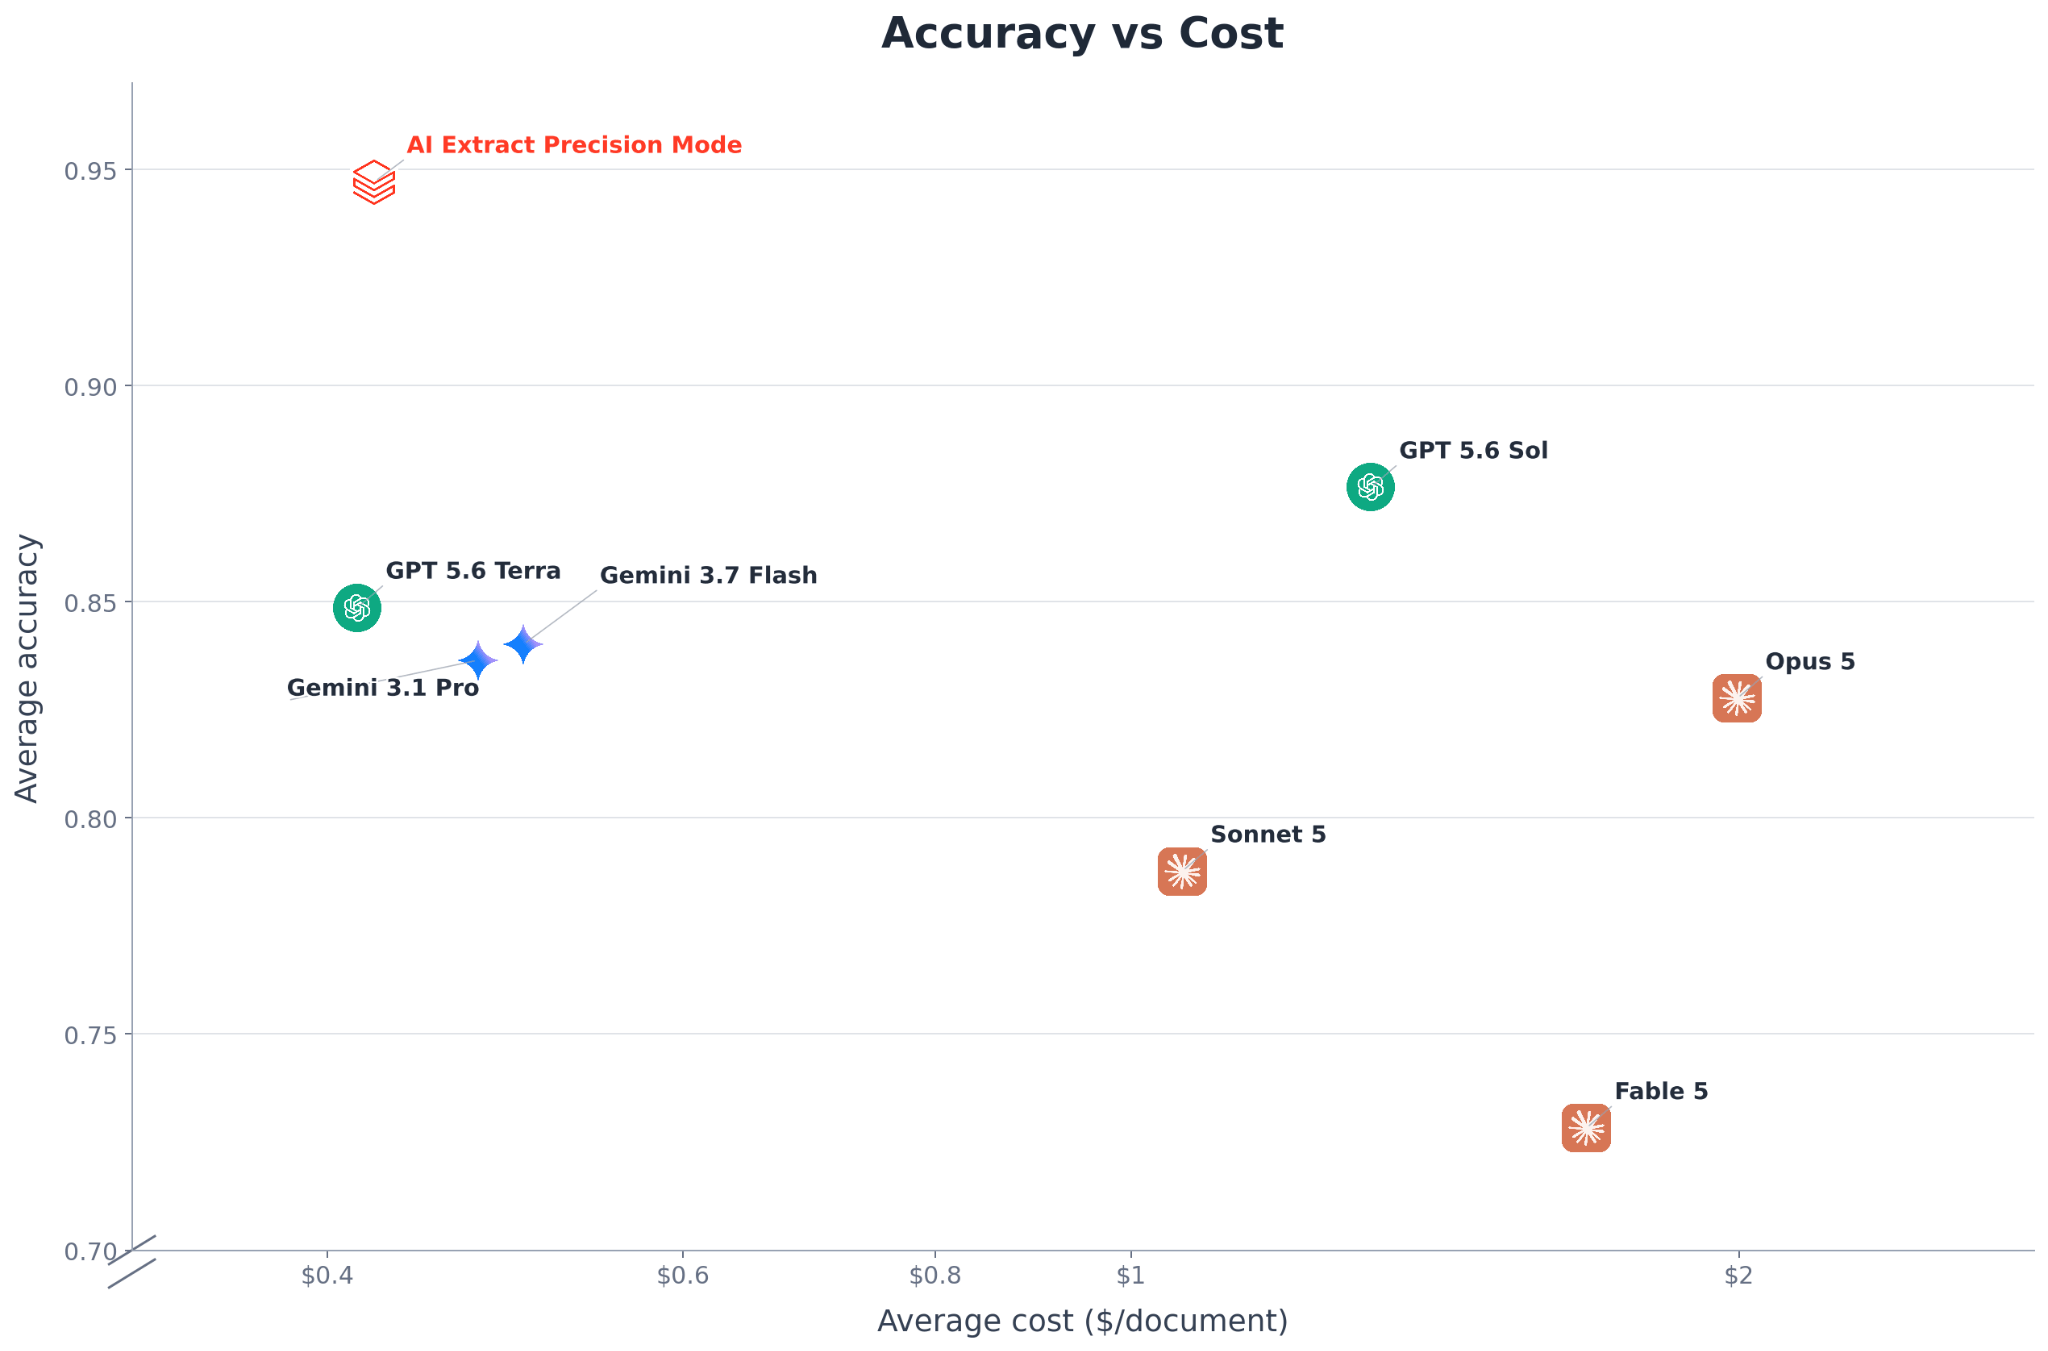
Precision Mode combines our custom-trained fashions for doc extraction with an agentic harness to ship dependable and correct extraction on lengthy paperwork, massive outputs, and reasoning-heavy schemas. Throughout benchmarks spanning roughly 9,000 advanced paperwork, Precision Mode achieves the cutting-edge high quality, outperforming the newest frontier fashions on extract accuracy by a big margin.
“At Intercontinental Change, we course of tens of millions of advanced, extremely variable monetary paperwork each month. Doc Intelligence helps us flip that complexity into structured market intelligence, enabling us to maneuver sooner, ship higher worth to our purchasers, and unlock agentic workflows that speed up evaluation and decision-making at scale.”—Anand Pradhan, CTO and Head of AI, Mortgage Information at Intercontinental Change (NYSE)
A New Method to Advanced Doc Extraction
To push accuracy on the toughest extraction duties, our analysis and engineering groups approached doc extraction high quality from two layers: customizing the mannequin itself and constructing an efficient agent harness across the mannequin.
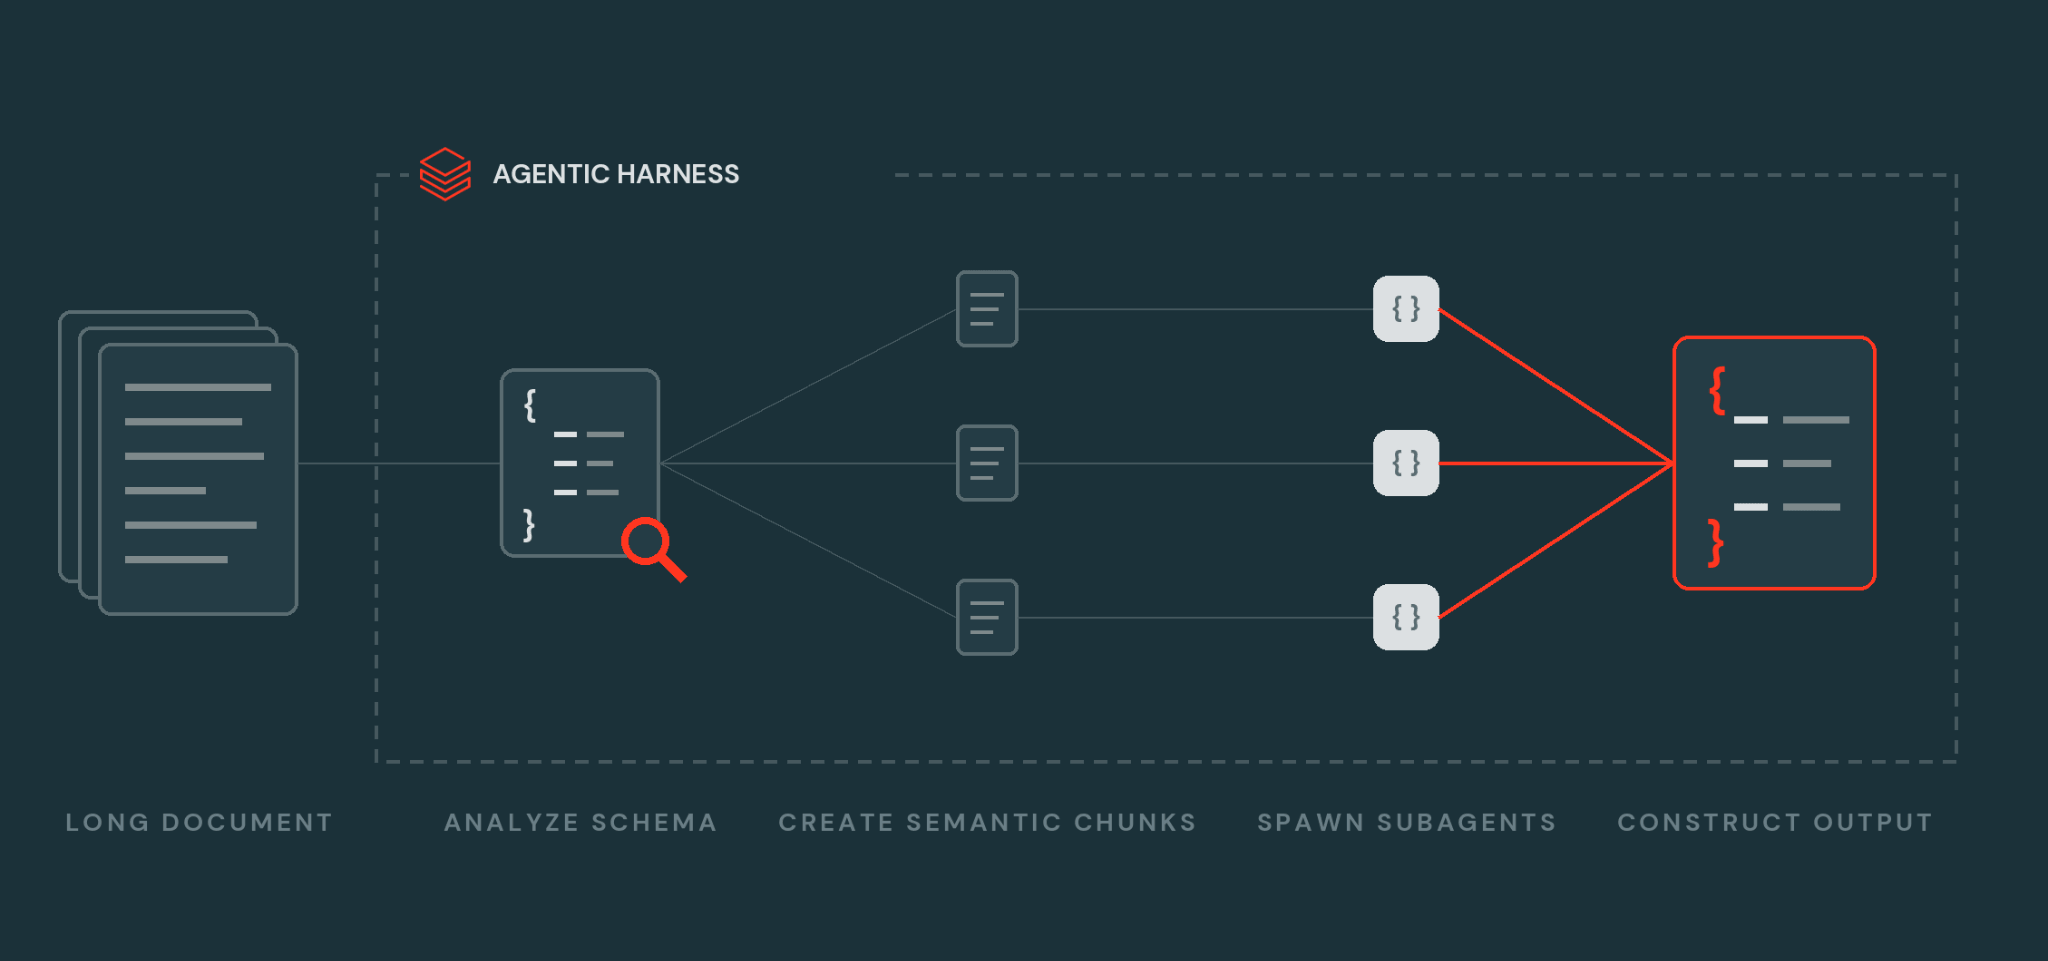
We educated {custom}, environment friendly fashions for doc extraction. Working from benchmarks constructed round tough buyer workloads, our analysis workforce educated {custom} fashions to seek out, motive over, and extract structured info from advanced paperwork. Slightly than counting on more and more massive general-purpose fashions, we optimized for the duty we need to remedy: correct structured extraction.We constructed an extraction harness designed to beat mannequin failure modes. Even a powerful mannequin can wrestle when it has to motive throughout tons of of pages or generate hundreds of fields directly. Our workforce constructed an agent harness, impressed by Databricks MemEx, that semantically decomposes massive extraction jobs, executes smaller duties in parallel, preserves intermediate outcomes, and reconciles them into one remaining structured output.
Analysis Methodology
Benchmark Design and Dataset Composition
To validate Precision Mode, we designed our analysis benchmarks round workloads that push current approaches to their limits.
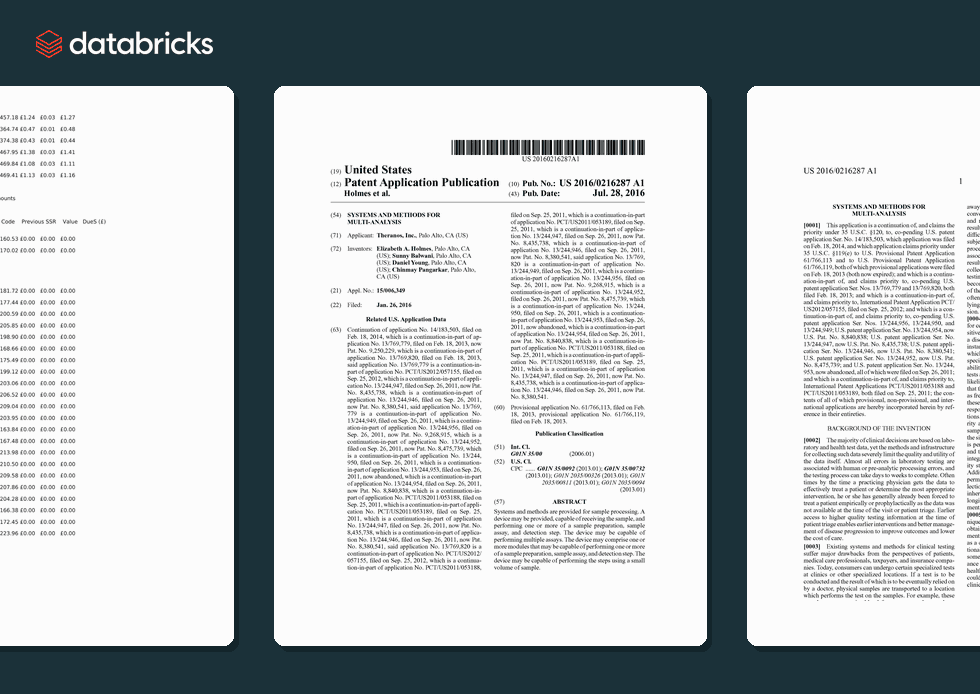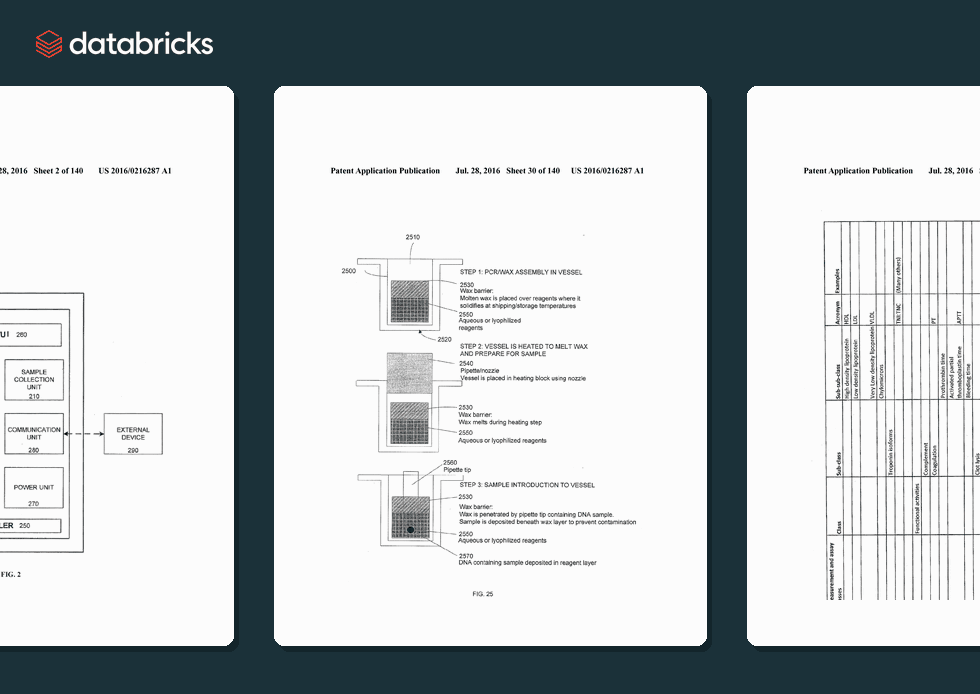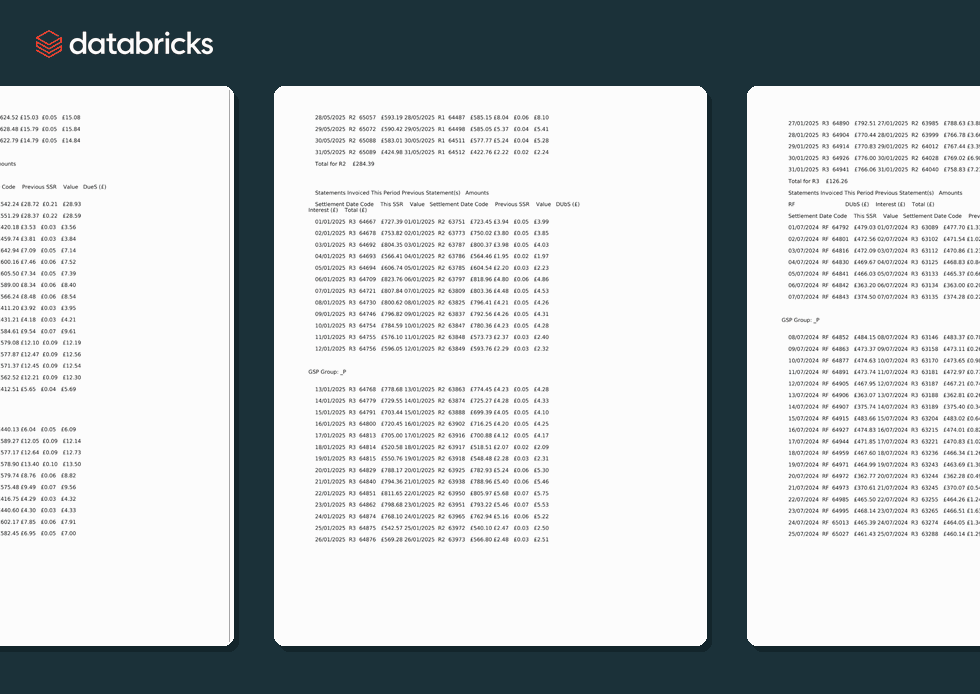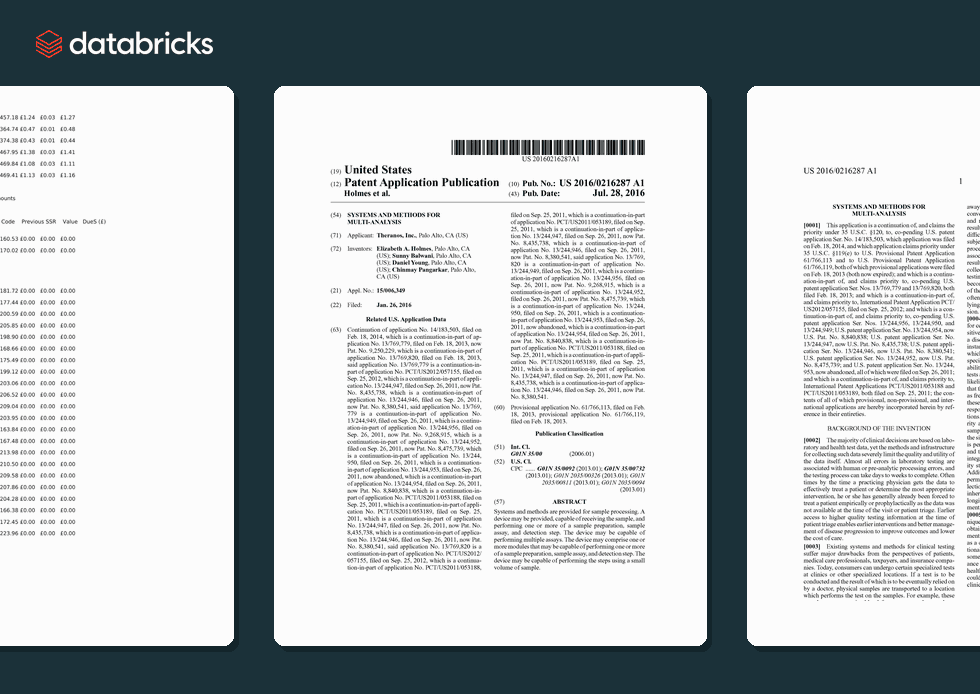
Concretely, we evaluated Precision Mode on roughly 9,000 paperwork spanning the three extraction challenges it was designed to resolve. The analysis consists of paperwork as much as 2,000 pages, invoices with hundreds of line objects, dense multi-page tables and charts, schemas with greater than 300 deeply nested fields, and reasoning-heavy duties that require cross-referencing info throughout a doc.
The paperwork come from two units of benchmarks:
10 inner datasets impressed by essentially the most tough buyer workloads we’ve seen, spanning key industries together with monetary companies, manufacturing, and healthcare.5 public benchmarks: VAREX, RealDocBench, LongExtractBench, and LEDGER, plus a long-document stress check utilizing the Caselaw Entry Challenge dataset.
Collectively, these datasets cowl paperwork together with 10-Okay filings, payments of lading, technical manuals, monetary paperwork, scientific notes, authorities patent and funding purposes, and extra.
Baseline Design and Mannequin Comparisons
A pure place to begin for doc extraction is a single frontier-model name: go within the doc and schema, and ask the mannequin to return the structured output. However on the dense and sophisticated workloads we consider, that strategy rapidly breaks down. Lengthy paperwork can exceed mannequin context limits, inflicting inaccurate and incomplete outcomes.
So we benchmarked towards a stronger, extra life like baseline: chunk-and-merge. We cut up every doc into smaller chunks, extract from every independently, and merge the outcomes right into a remaining output—the identical sample we see engineers use when a single mannequin name is not sufficient.
We examined the chunk-and-merge strategy utilizing main GPT, Claude, and Gemini fashions with their default API settings. Then, we in contrast every towards Precision Mode on extraction accuracy. ¹
Benchmark Outcomes
Throughout our benchmarks, Precision Mode reaches 94.7% accuracy, outperforming the strongest frontier mannequin chunk-and-merge baseline, GPT-5.6 Sol, by seven factors.
Notably, on tough long-document workloads, we noticed frontier-models encounter quite a few operational failure modes together with chunk timeouts, truncated outputs, and incomplete remaining merges that didn’t conform to the requested schema. Then again, Precision Mode’s agentic strategy is strong towards these failure modes, and our custom-trained extraction fashions preserve extractions environment friendly and correct.
Getting Began
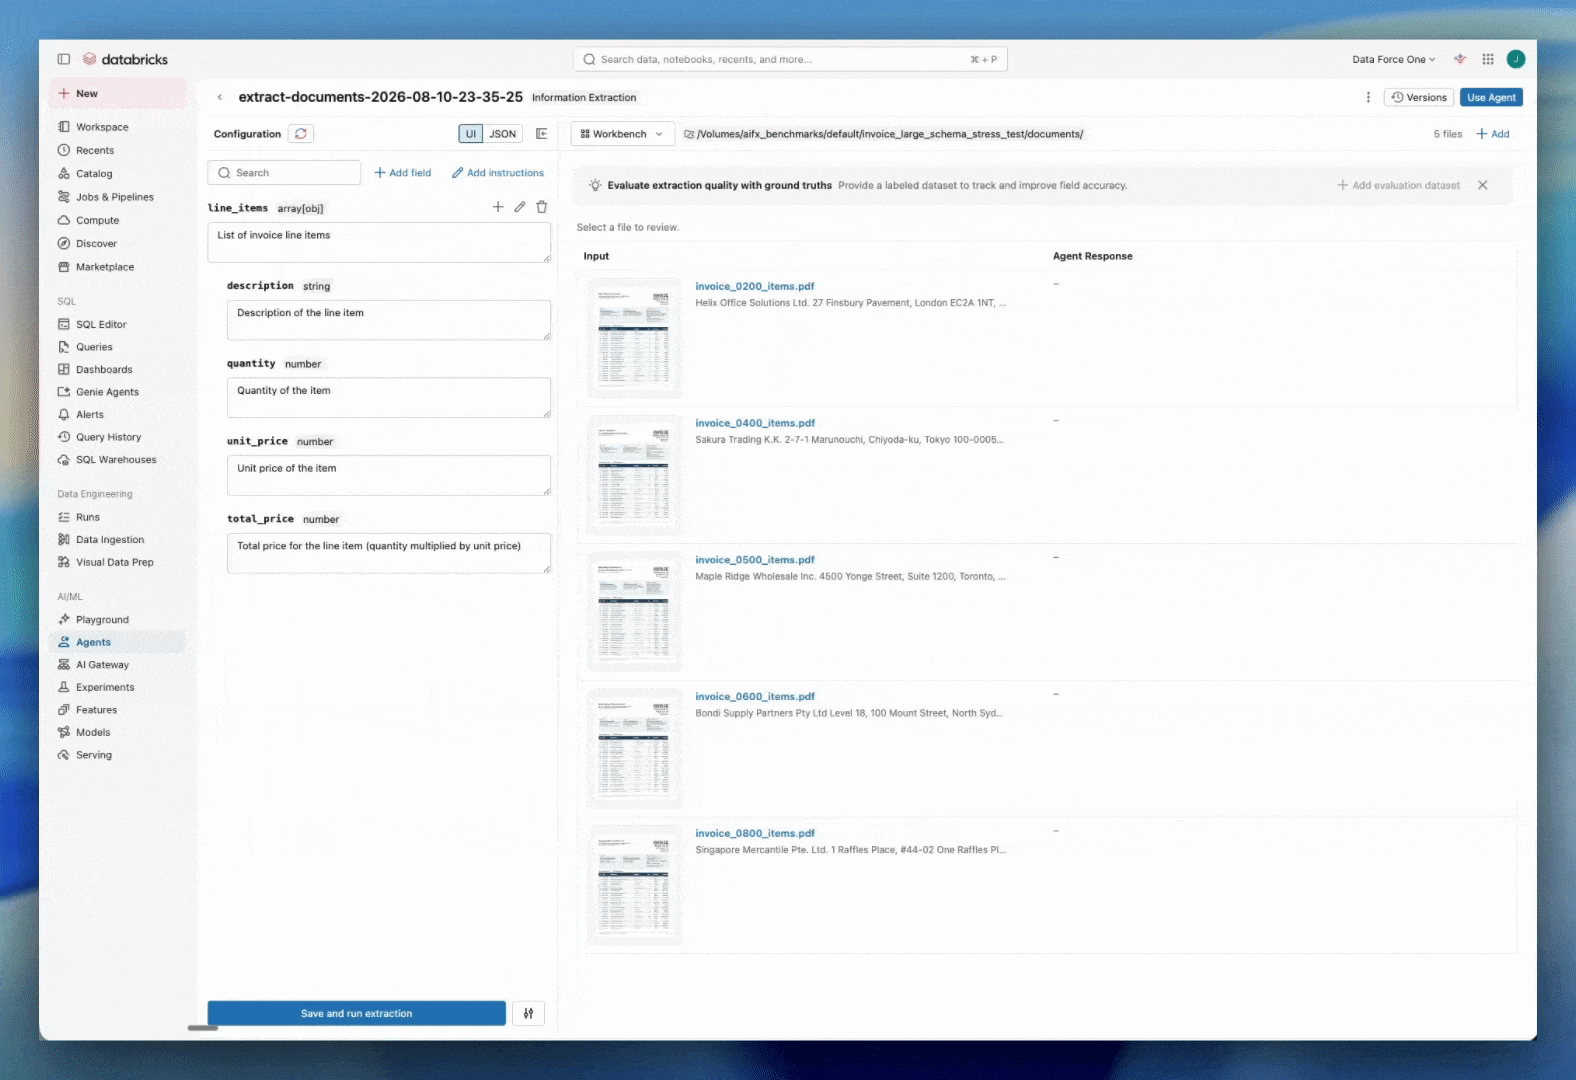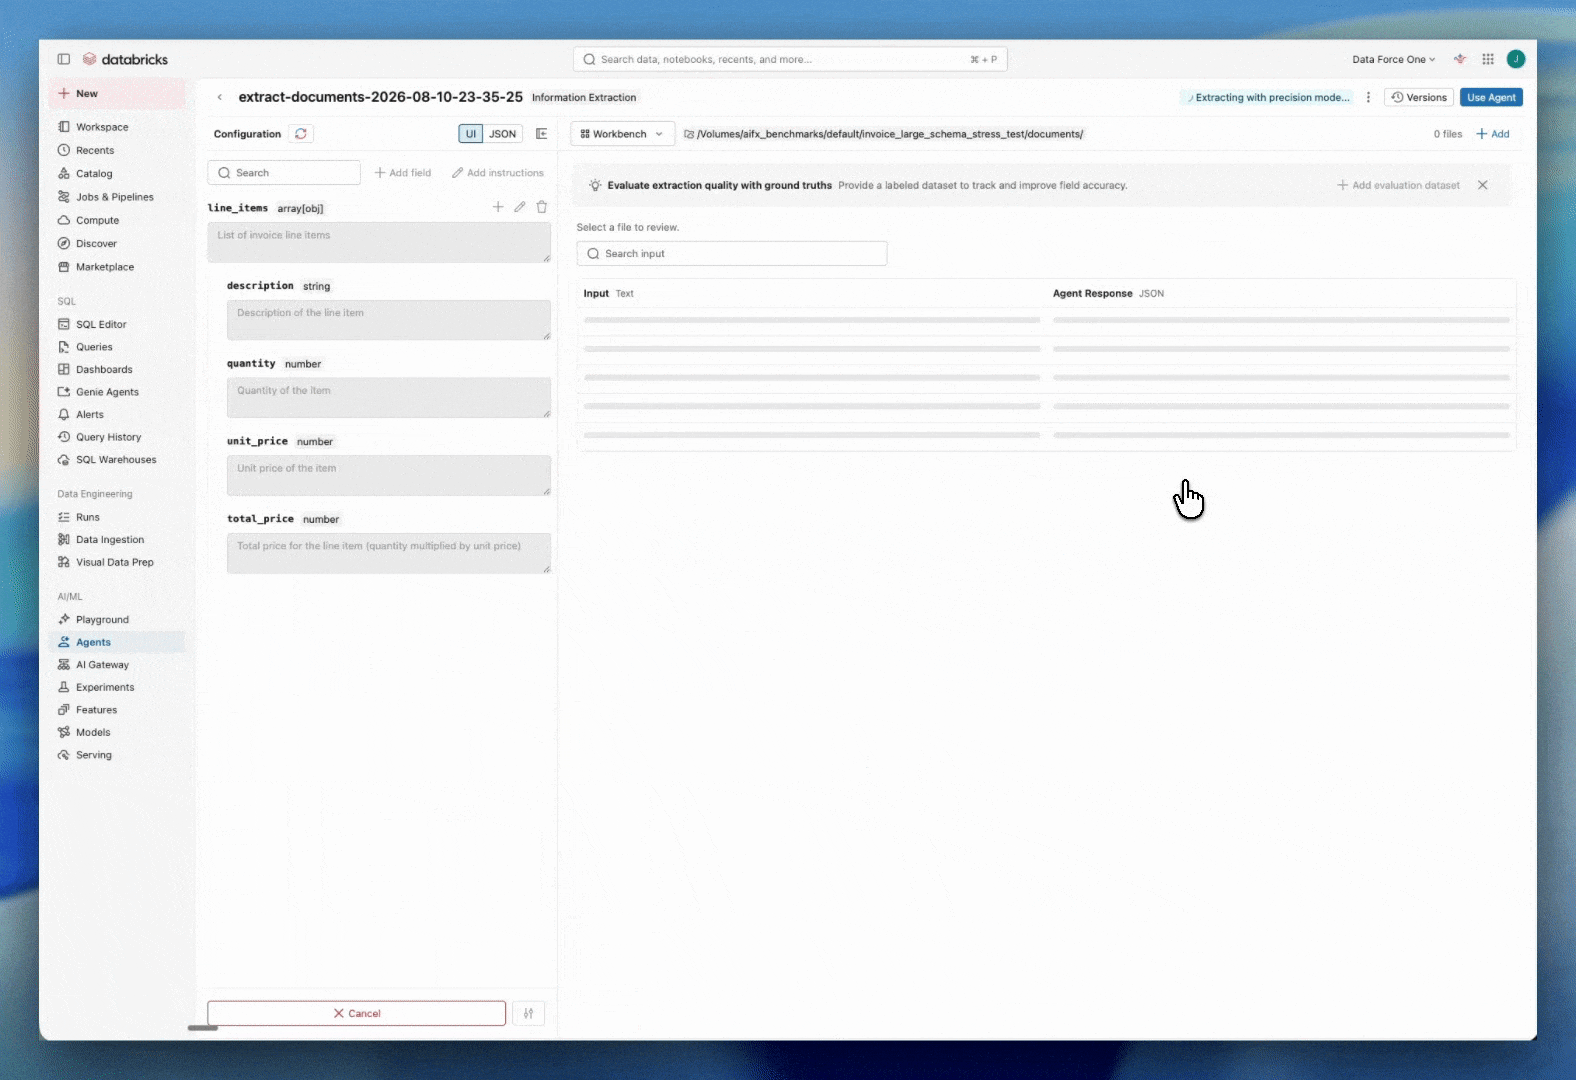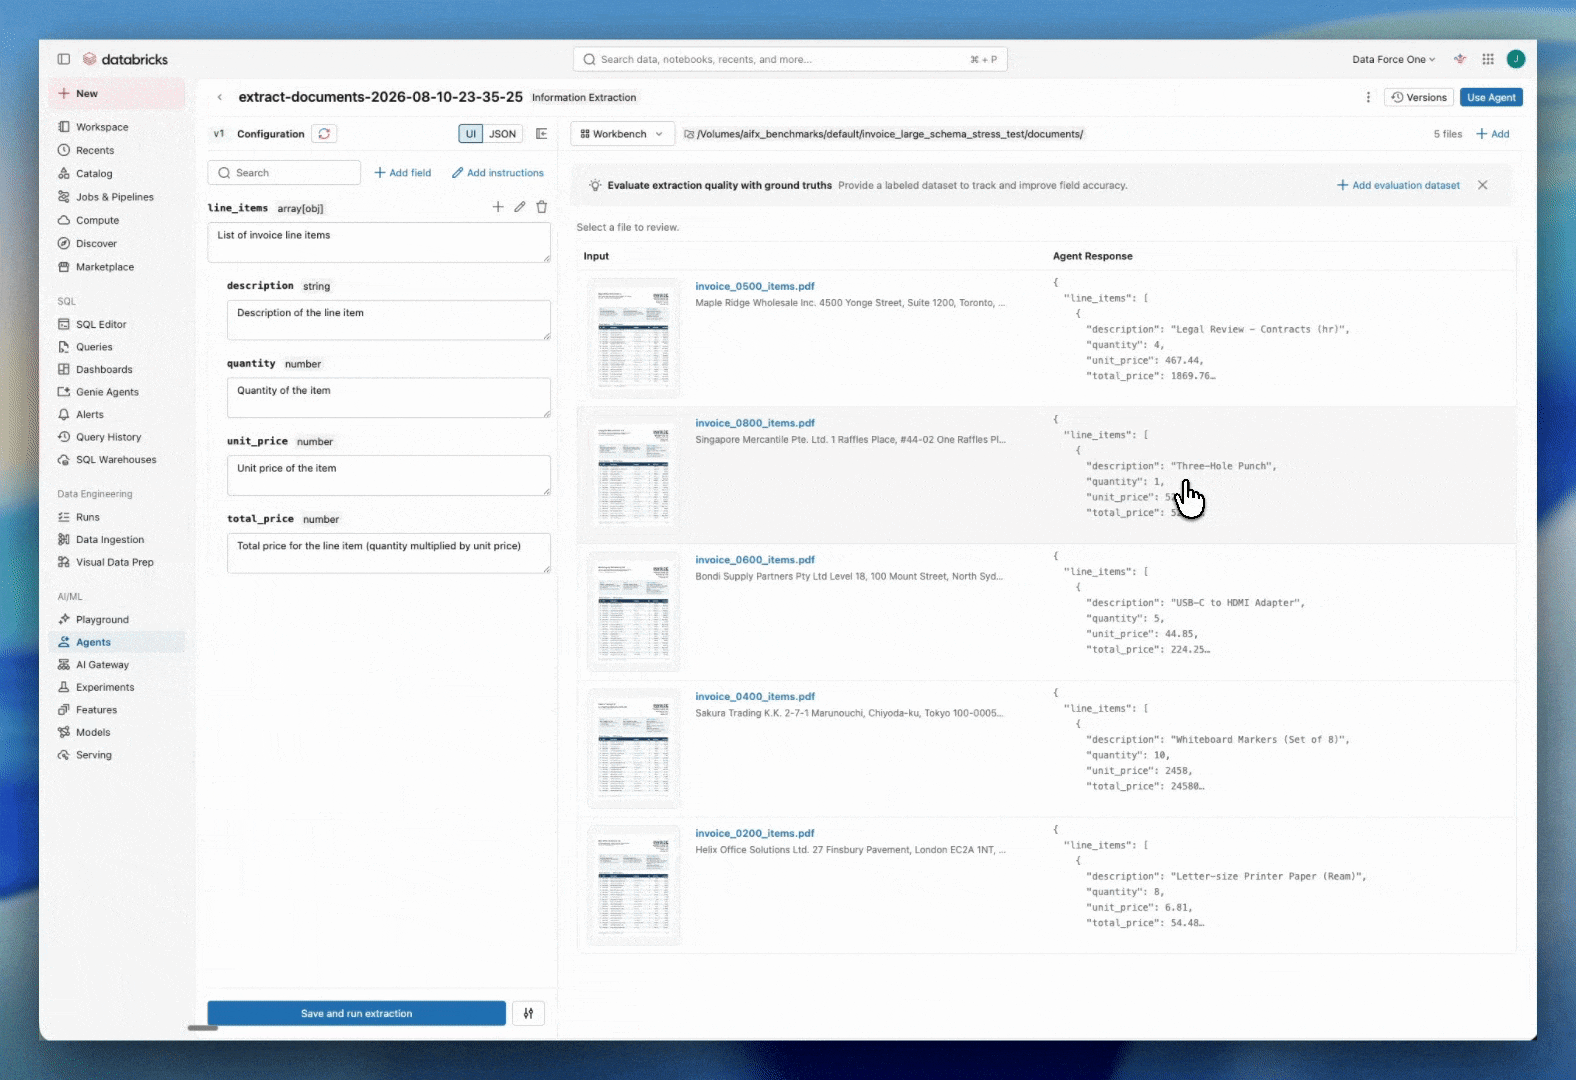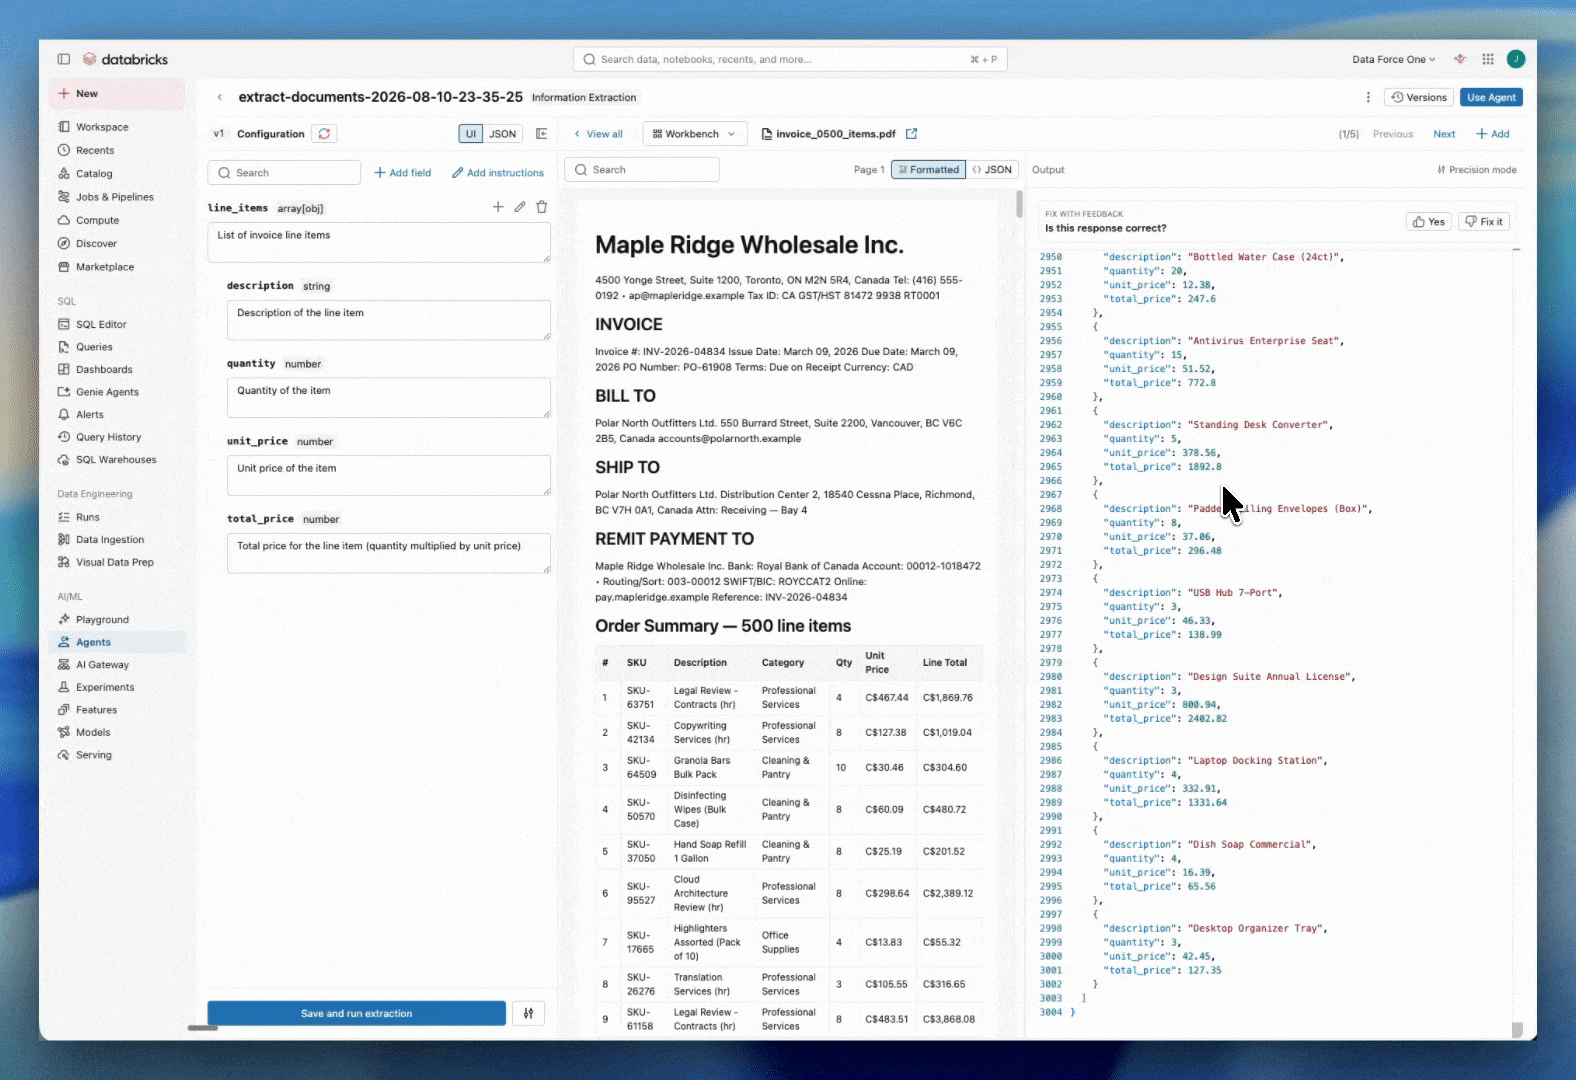
On your most advanced doc extraction duties, AI Extract Precision Mode is now obtainable. Set the mode to precision when calling ai_extract operate, or activate the precision mode toggle within the Info Extraction UI on the Brokers web page:
Strive AI Extract Precision Mode
Footnotes:
¹ We outline accuracy because the fraction of extracted objects that match the ground-truth object. Scoring depends upon sort. Primitives (booleans, floats, integers, enums) use direct match. Strings attempt direct match first, then fuzzy match, then an LLM choose. Arrays are scored by discovering the closest pairing between predicted and anticipated objects, then averaging throughout pairs. Objects are scored per subject by sort, then averaged throughout all fields.

