


On this article, you’ll be taught three sensible methods for managing small context home windows in giant language fashions, together with working Python examples that display how two of these methods are carried out.
Subjects we are going to cowl embrace:
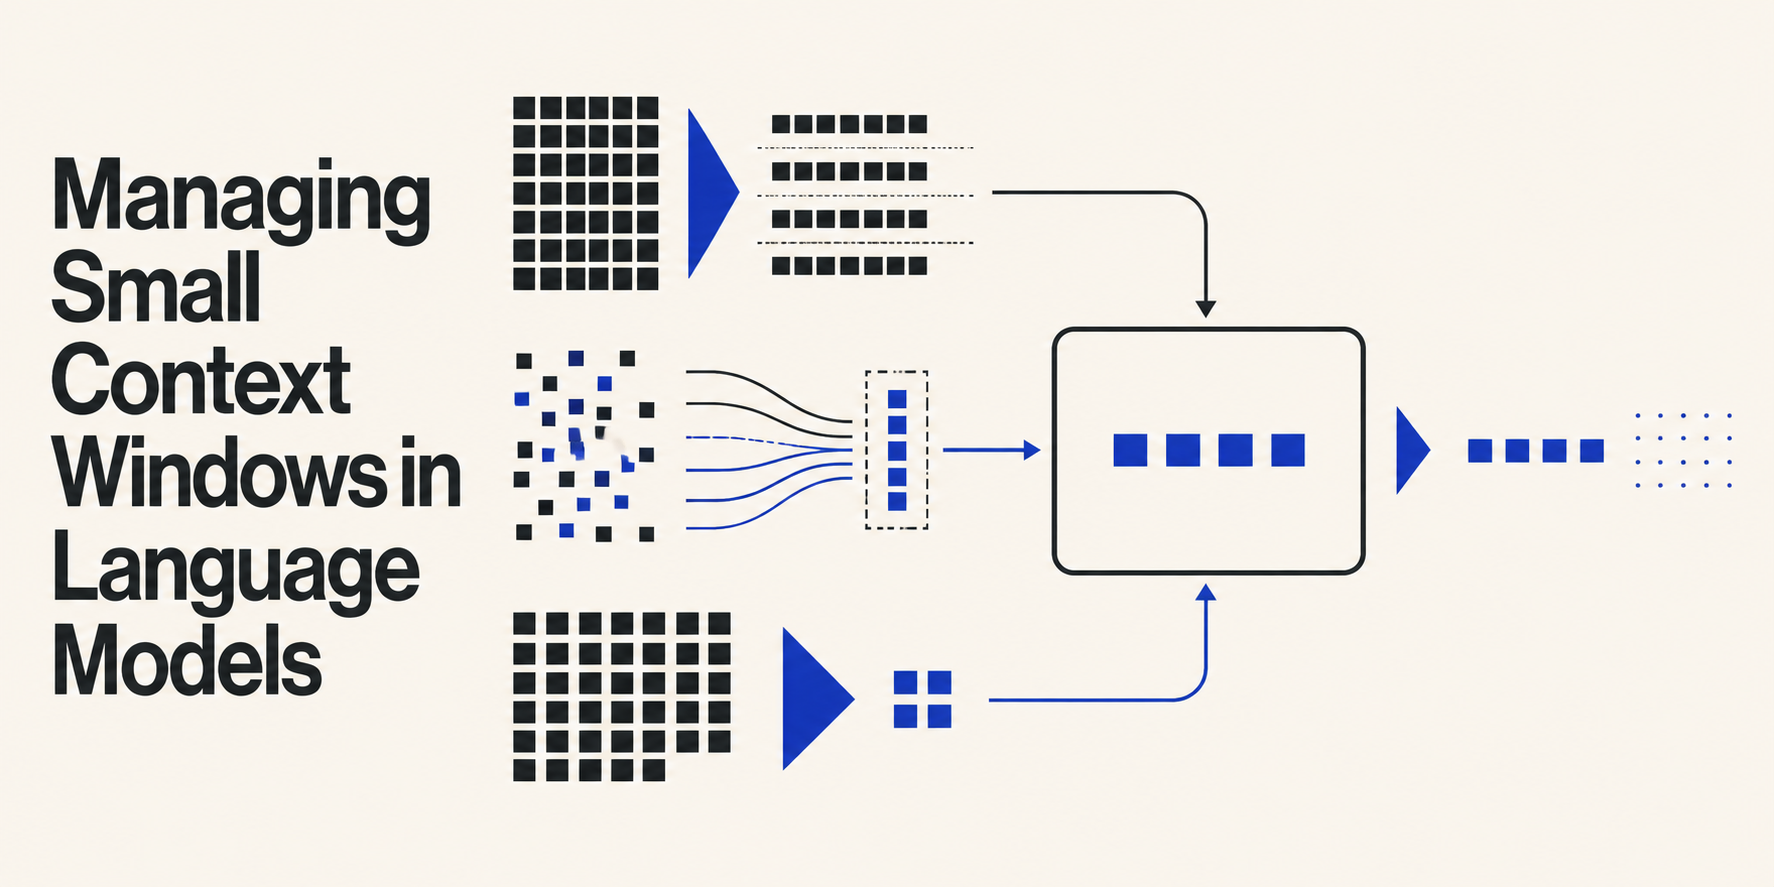
How context truncation by way of the sliding window method retains token utilization flat and predictable.
How token budgeting mixed with retrieval-augmented technology ensures solely essentially the most related context suits inside a immediate.
A concise overview of further methods for extra specialised use circumstances — rolling summaries, immediate compression, and remark masking.
Introduction
High-tier AI industries have develop into considerably obsessive about language fashions able to ingesting huge context home windows, e.g. a complete e-book in a single immediate. Nonetheless, what they received’t admit simply is that in real-world LLM purposes, these huge context home windows include varied limitations and challenges, together with hovering API prices, unacceptable response occasions, and even worse, the so-called “misplaced within the center” drawback whereby a mannequin ignores knowledge deeply buried in the midst of the enormous immediate. No shock, then, that working with small but well managed context home windows may yield superior outcomes, decreasing latency, minimizing prices, and forcing the mannequin to focus on what actually issues to generate its response.
This text unveils three of essentially the most broadly adopted sensible methods for managing and mastering small context home windows in language fashions, together with examples that mimic the implementation of a few of them for higher understanding.
Context Truncation: Sliding Window
There’s a consensus that sliding home windows are arguably the commonest and easiest technique for managing shortened context home windows in language fashions. As a substitute of offering a complete person dialog historical past to the mannequin, the context is handled as a FIFO (First-In-First-Out) queue: as new interactions (exchanged messages) are available in, the oldest ones are merely dropped. All it takes is defining the scale of the context window and placing a steadiness between enough previous context retention and latency-cost management.
The primary benefit of truncating the context by way of sliding home windows is absolute management and predictability over token utilization and computing overhead. The utmost variety of interactions handled by the mannequin at a given time stays mounted, conserving latency flat and surprise-free.
To higher perceive how this method works, let’s have a look at the next Python code in which you’ll freely alter the worth of max_turns (context window measurement) and see the way it impacts the “reminiscence” injected into the present immediate:
class SlidingWindowMemory:
def __init__(self, max_turns=3):
“””Maintain solely the final `max_turns` of a dialog.”””
self.max_turns = max_turns
self.historical past = []
def add_interaction(self, user_text, ai_text):
self.historical past.append({“person”: user_text, “ai”: ai_text})
# The logic behind a sliding window: drop the oldest turns if limits are surpassed
if len(self.historical past) > self.max_turns:
self.historical past = self.historical past[-self.max_turns:]
def build_prompt(self, new_query):
immediate = “System: Reply concisely primarily based on current context.nn”
for flip in self.historical past:
immediate += f”Consumer: {flip[‘user’]}nAI: {flip[‘ai’]}n”
immediate += f”Consumer: {new_query}nAI:”
return immediate
# — Testing the Sliding Window mechanism: be at liberty to regulate the worth of max_turns —
reminiscence = SlidingWindowMemory(max_turns=2)
# Simulating a protracted dialog
reminiscence.add_interaction(“Hello, I am studying Python.”, “Nice selection!”)
reminiscence.add_interaction(“What are lists?”, “Lists are mutable arrays.”)
reminiscence.add_interaction(“Can they maintain blended sorts?”, “Sure, they’ll.”)
# The immediate will solely comprise the final ‘max_turns’ interactions, saving tokens
print(reminiscence.build_prompt(“How do I append to 1?”))
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
class SlidingWindowMemory:
def __init__(self, max_turns=3):
“”“Maintain solely the final `max_turns` of a dialog.”“”
self.max_turns = max_turns
self.historical past = []
def add_interaction(self, user_text, ai_text):
self.historical past.append({“person”: user_text, “ai”: ai_text})
# The logic behind a sliding window: drop the oldest turns if limits are surpassed
if len(self.historical past) > self.max_turns:
self.historical past = self.historical past[–self.max_turns:]
def build_prompt(self, new_query):
immediate = “System: Reply concisely primarily based on current context.nn”
for flip in self.historical past:
immediate += f“Consumer: {flip[‘user’]}nAI: {flip[‘ai’]}n”
immediate += f“Consumer: {new_query}nAI:”
return immediate
# — Testing the Sliding Window mechanism: be at liberty to regulate the worth of max_turns —
reminiscence = SlidingWindowMemory(max_turns=2)
# Simulating a protracted dialog
reminiscence.add_interaction(“Hello, I am studying Python.”, “Nice selection!”)
reminiscence.add_interaction(“What are lists?”, “Lists are mutable arrays.”)
reminiscence.add_interaction(“Can they maintain blended sorts?”, “Sure, they’ll.”)
# The immediate will solely comprise the final ‘max_turns’ interactions, saving tokens
print(reminiscence.build_prompt(“How do I append to 1?”))
Output:
System: Reply concisely primarily based on current context.
Consumer: What are lists?
AI: Lists are mutable arrays.
Consumer: Can they maintain blended sorts?
AI: Sure, they’ll.
Consumer: How do I append to 1?
AI:
System: Reply concisely primarily based on current context.
Consumer: What are lists?
AI: Lists are mutable arrays.
Consumer: Can they maintain blended sorts?
AI: Sure, they can.
Consumer: How do I append to one?
AI:
You can too strive extending the dialog historical past by appending new reminiscence.add_interaction() calls with further query-response pairs of your personal, to check the mechanism for bigger context home windows.
Token Budgeting and RAG (Retrieval-Augmented Technology)
RAG methods complement LLMs with engines that reference and retrieve exterior paperwork to complement the unique person immediate with based, related context. Small context home windows could intuitively pressure a ruthless perspective towards the info to incorporate within the context. To deal with this, token budgeting splits the context window into zones with strict limits per zone. As an example, a token budgeting criterion may permit as much as 20% of the context for system directions, 20% for the chat historical past (together with the newest person question), and the remaining 60% for retrieved knowledge. This incorporates a extra dynamic retrieval and knowledge chunking habits, halting insertion as quickly as finances limits are hit.
The primary benefit of token budgeting is stopping unduly giant retrieved paperwork from shortly exhausting the immediate and making certain solely extremely related, concentrated info is included, thus avoiding aspect points just like the aforementioned “misplaced within the center” drawback.
This code excerpt exemplifies using the mechanism in Python, utilizing a easy phrase rely as a free, light-weight proxy for token budgeting — to make it extra real looking, you may take into account the generally accepted heuristic of 1 phrase = 1.3 tokens on common. The loop contained in the perform reveals learn how to reliably pack a immediate with out surpassing enforced limits:
def build_budgeted_prompt(system_prompt, retrieved_chunks, user_query, max_words=50):
“””Packs context chunks right into a immediate till a strict phrase finances is hit.”””
# Calculating the mounted price of obligatory components
base_words = len(system_prompt.break up()) + len(user_query.break up())
current_words = base_words
included_chunks = []
for chunk in retrieved_chunks:
chunk_words = len(chunk.break up())
# Solely add the chunk if it suits inside the strict finances
if current_words + chunk_words <= max_words:
included_chunks.append(chunk)
current_words += chunk_words
else:
print(f”Price range hit! Unnoticed {len(retrieved_chunks) – len(included_chunks)} chunks.”)
break
context_str = “n—n”.be a part of(included_chunks)
return f”{system_prompt}nnContext:n{context_str}nnUser: {user_query}”
# — Testing the Budgeted Immediate Mechanism —
system_msg = “Use the context to reply.”
question = “What’s the capital of Spain?”
docs = [
“Seville is a city in Andalusia, Spain.”,
“Madrid is the capital of Spain.”, # We want this to fit
“Spain is located in Southwestern Europe.”, # This might get cut off
“The population of Spain is roughly 47 million.”
]
# Setting a really small finances to see the cutoff in motion
print(build_budgeted_prompt(system_msg, docs, question, max_words=30))
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
def build_budgeted_prompt(system_prompt, retrieved_chunks, user_query, max_words=50):
“”“Packs context chunks right into a immediate till a strict phrase finances is hit.”“”
# Calculating the mounted price of obligatory components
base_words = len(system_prompt.break up()) + len(user_query.break up())
current_words = base_words
included_chunks = []
for chunk in retrieved_chunks:
chunk_words = len(chunk.break up())
# Solely add the chunk if it suits inside the strict finances
if current_words + chunk_words <= max_words:
included_chunks.append(chunk)
current_words += chunk_words
else:
print(f“Price range hit! Unnoticed {len(retrieved_chunks) – len(included_chunks)} chunks.”)
break
context_str = “n—n”.be a part of(included_chunks)
return f“{system_prompt}nnContext:n{context_str}nnUser: {user_query}”
# — Testing the Budgeted Immediate Mechanism —
system_msg = “Use the context to reply.”
question = “What’s the capital of Spain?”
docs = [
“Seville is a city in Andalusia, Spain.”,
“Madrid is the capital of Spain.”, # We want this to fit
“Spain is located in Southwestern Europe.”, # This might get cut off
“The population of Spain is roughly 47 million.”
]
# Setting a really small finances to see the cutoff in motion
print(build_budgeted_prompt(system_msg, docs, question, max_words=30))
Output:
Price range hit! Unnoticed 1 chunks.
Use the context to reply.
Context:
Seville is a metropolis in Andalusia, Spain.
—
Madrid is the capital of Spain.
—
Spain is situated in Southwestern Europe.
Consumer: What’s the capital of Spain?
Price range hit! Left out 1 chunks.
Use the context to reply.
Context:
Seville is a metropolis in Andalusia, Spain.
—–
Madrid is the capital of Spain.
—–
Spain is situated in Southwestern Europe.
Consumer: What is the capital of Spain?
Past the Fundamentals: Different Methods
To shut out, let’s shortly define another methods for managing small context home windows, significantly for specialised use circumstances. Bear in mind that a few of these methods sometimes require dwell API calls or further exterior dependencies for his or her implementation.
Rolling Summaries: This methodology makes use of an auxiliary LLM for summarization that condenses older dialog historical past right into a compact paragraph, changing the uncooked immediate textual content. It helps retain long-term reminiscence with out token bloat, however requires further API calls to request and procure the summaries, introducing added overhead and potential prices.
Immediate Compression: As a substitute of resorting to an auxiliary mannequin, an algorithm is invoked to strip out filler phrases, redundant knowledge, and cease phrases from the uncooked context earlier than feeding it to the primary mannequin. This could drastically scale back latency with out compromising enter high quality or semantic intent, but when utilized too aggressively, it may strip away delicate but invaluable nuances wanted by the mannequin to generate an appropriate response.
Statement Masking: This method evaluates the context to cover or masks older, structural noise — resembling database queries in agent-based methods or intermediate code execution logs — whereas the core logic stays intact. It’s a well-liked approach in autonomous brokers fueled by LLMs, permitting them to remain targeted on their rapid aim with out being distracted by previous inside steps. Nonetheless, it’s extra complicated to implement, because it requires figuring out which observations are secure to masks with out compromising the agent’s reasoning chain.
Closing Remarks
Small context home windows shouldn’t be considered a limitation however moderately as an architectural function for stopping main points like extreme price and latency. This text introduced quite a few methods for successfully managing small context home windows in LLMs to yield quicker and cheaper options with out compromising accuracy.

