Qwen 3.8 27B is superb, but it surely defaults to wildly overthinking issues
sixteenth August 2026
Friday’s large launch was Qwen 3.8 27B, an Apache 2 licensed 27B parameter vision-capable LLM from Alibaba’s Qwen analysis lab. I’ve been trying ahead to this one: 27B is a wonderful dimension for operating a mannequin on a fairly specced laptop computer, and its predecessor Qwen 3.6 27B was spectacular.
Qwen’s self-reported benchmarks for this mannequin are eye-opening. They present a lift from each Qwen 3.6 27B and the closed-weight Qwen 3.7-Plus, which was one among Qwen’s strongest fashions of any dimension as lately as Might this 12 months. It will likely be attention-grabbing to listen to what impartial benchmarks must say concerning the mannequin.
I’ve been operating the mannequin on two completely different machines: my 128GB M5 Max MacBook Professional, and an NVIDIA DGX Spark. On each machines I’m operating LM Studio and their 17GB Q4_K_M quantized construct. I additionally tried utilizing llama-server instantly on the Spark.
Qwen’s documentation describes the mannequin as defaulting to xhigh for the reasoning effort, and the LM Studio GGUF I’ve been making an attempt preserves that default:
Qwen3.8 comes with official assist for reasoning_effort, which can be utilized to regulate reasoning depth and management value:
xhigh (default): for advanced duties demanding thorough evaluation
medium: balancing accuracy and velocity
low: environment friendly reasoning optimizing for velocity and value
This can be a hilarious default. It’s completely not a great way to run the mannequin, particularly on client {hardware}. I’ve been discovering the outcomes extraordinarily entertaining.
I rapidly bumped into issues with LM Studio’s default context restrict of 8,192 tokens—Qwen was utilizing all of them up occupied with even essentially the most mundane of issues. I loaded the mannequin with the total 262,144 most context size and that drawback went away.
Right here’s the pelican driving a bicycle SVG I bought from my first try with that elevated context size. It took 21 minutes to generate, utilizing 22,276 reasoning tokens to provide 3,223 tokens of output. You’ll be able to learn the reasoning hint right here.
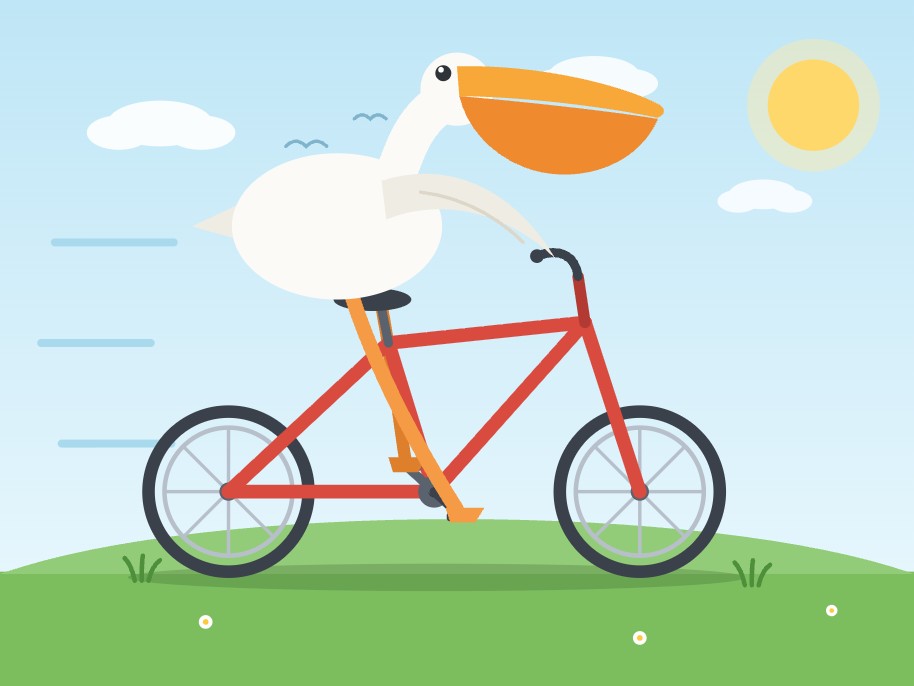
That is by far the very best pelican SVG I’ve been in a position to generate with a mannequin that runs on a neighborhood machine—and this Qwen is fairly small, only a 17GB file on disk. There’s quite a bit to love about this:
The bicycle body is the appropriate form
It has legs on all sides of the bike—that’s very uncommon
Good, clear pelican pouch
The wings prolong to the touch the handlebars!
The movement strains are behind, not in entrance
It has a tasteful background—good solar, clouds, hill, flowers and grass.
Was that value ready 21 minutes for? Completely not.
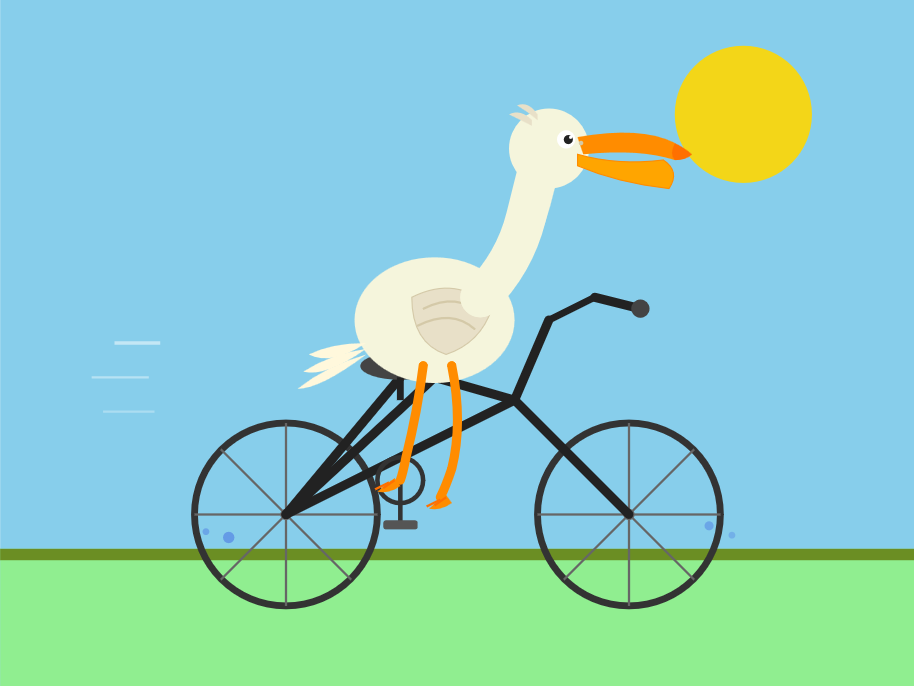
Right here’s that very same immediate run with reasoning turned off—transcript right here. This one produced 3,715 tokens and took 137s—simply over two minutes.
And only for completeness, I used OpenRouter to run the identical immediate via the a lot bigger Qwen 3.8 2.4T-A95B (launched final week) and bought this snazzy animated SVG:
Your browser doesn’t assist HTML5 video.
I stated Qwen at xhigh tends to over-think issues, however how dangerous actually is it?
I attempted a a lot easier immediate, once more with that default further excessive setting:
draw an svg of a circle
Qwen’s reasoning hint began like this:
The person is asking for an SVG drawing of a circle. Easy request — however I would like it to be a fastidiously crafted piece. Let me make one thing that goes past simply : a single self-contained SVG file with character — perhaps a geometrical “circle examine,” with delicate animation, layered rings, and a particular palette.
Preserve the scope proper: they requested for an SVG of a circle. So the core is a circle. However I can add craft: concentric information circles (like a compass/geometry drawing), tick marks, a gentle gradient fill on the principle circle, restrained ambient movement (a slowly rotating dashed ring, pulsing glow). Respect prefers-reduced-motion? That’s extra for CSS; SVG SMIL or CSS inside SVG will do.
Palette choices: deep teal ink on heat paper? Or daring vermilion circle on off-white with navy development strains — Bauhaus/compass-drawing vibe. Let me go along with a “geometric examine” look: cool slate background, or vivid paper white? Paper white is ok if it’s not the cream-and-terracotta combo. […]
A number of minutes later it produced this positively stunning animated circle, which was solely not what I had requested for!
Your browser doesn’t assist HTML5 video.
My robust advice: ignore that default. Run Qwen 3.8 27B on low and even no reasoning ranges at first. It’s an excellent mannequin, however wow that default setting is a foul place to start out.
It’s excellent at bounding packing containers
A enjoyable approach to check a imaginative and prescient mannequin is to see how properly it might return bounding packing containers round objects in {a photograph}. I’ve seen earlier Qwen fashions deal properly with this, so I made a decision to place it to the check drawing bounding packing containers round some pelicans.
I’ve seen asking for 0-1000 scale produce good outcomes up to now. I attempted this:
-m lmstudio/qwen/qwen3.8-27b
‘Return JSON bounding packing containers for the pelicans on this picture, 0-1000 scale for every dimension‘
Right here’s the reasoning hint, which produced this:
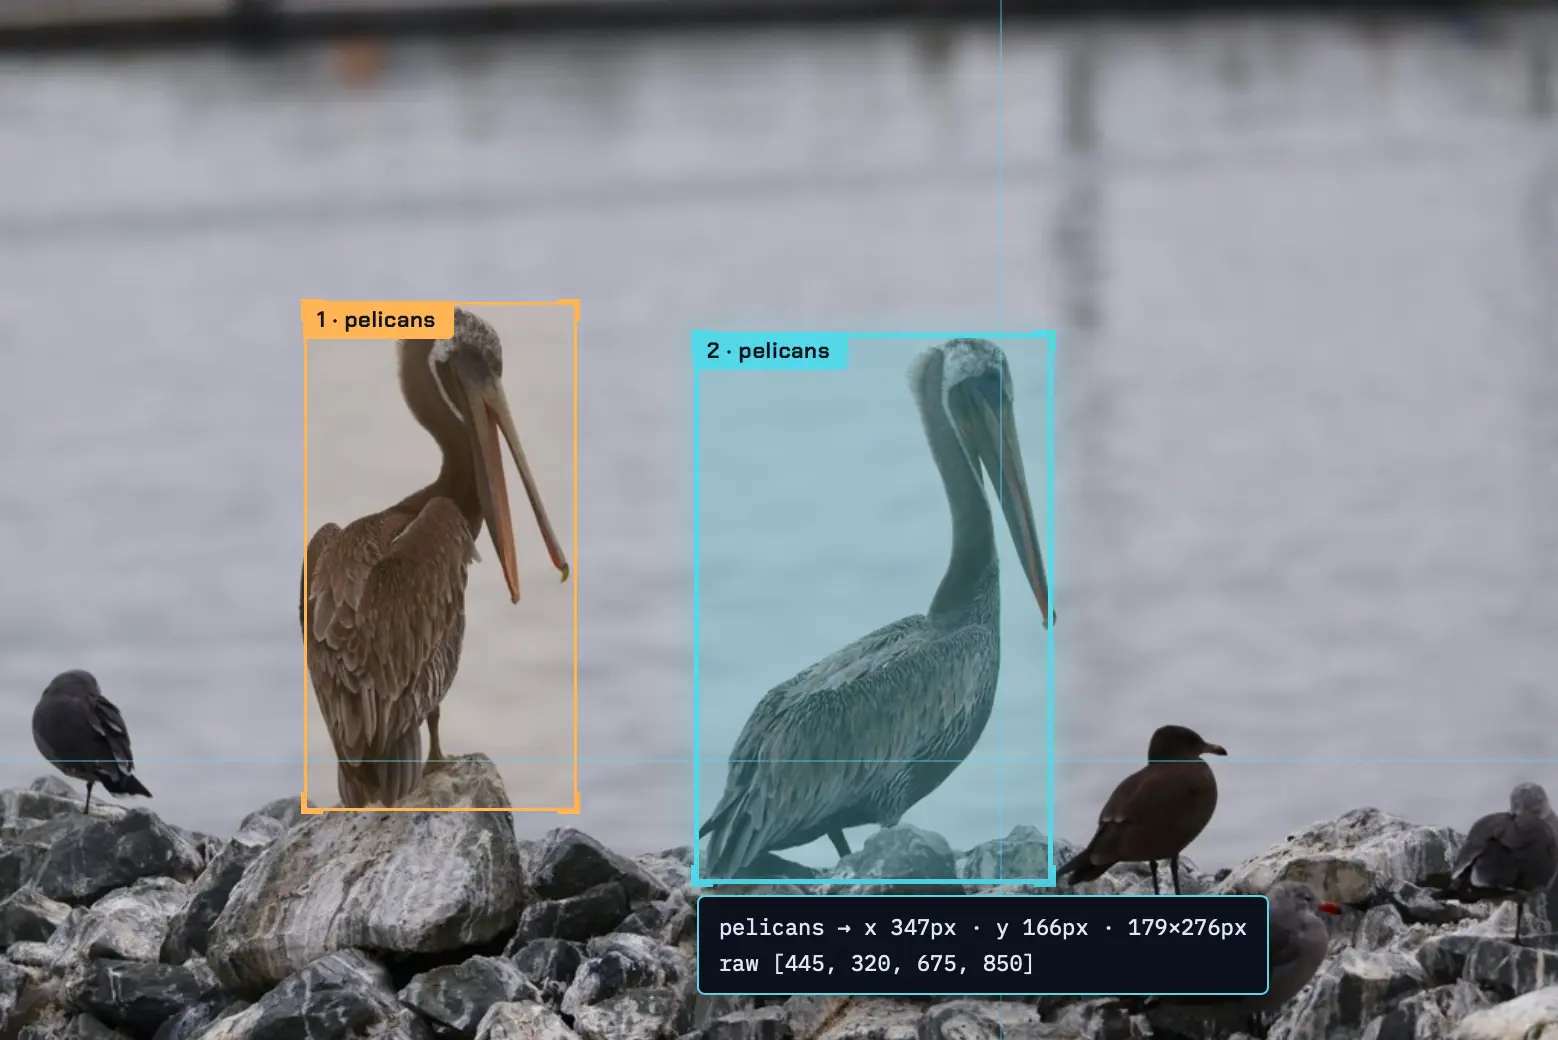
{“bbox_2d”: [195, 290, 370, 780], “label”: “pelicans“},
{“bbox_2d”: [445, 320, 675, 850], “label”: “pelicans“}
]
That is such a very good match. Listed below are these packing containers rendered on prime of the picture:
Constructing a device to label bounding packing containers
That visualization of the bounding packing containers was taken utilizing a brand new customized device that I had Qwen 3.8 27B construct for me, operating offline on my laptop computer.
I forgot to dial down the pondering effort so it was massively over-engineered, but it surely did handle to provide this full interface from this single immediate:
[
{“bbox_2d”: [195, 290, 370, 780], “label”: “pelicans”},
{“bbox_2d”: [445, 320, 675, 850], “label”: “pelicans”}
]Construct an HTML web page which has an enter field for accepting the URL to a picture and a textarea for accepting the above fashion of JSON.
It appends the picture to the web page, measures its width and peak, then treats the coords within the bbox_2d as scaled from 0-1000 and scales them in opposition to the precise width and peak, then it renders labelled packing containers over the picture.
This screenshot exhibits one of many options I didn’t ask for—a demo scene, for in case you don’t have {a photograph} to check the device with:
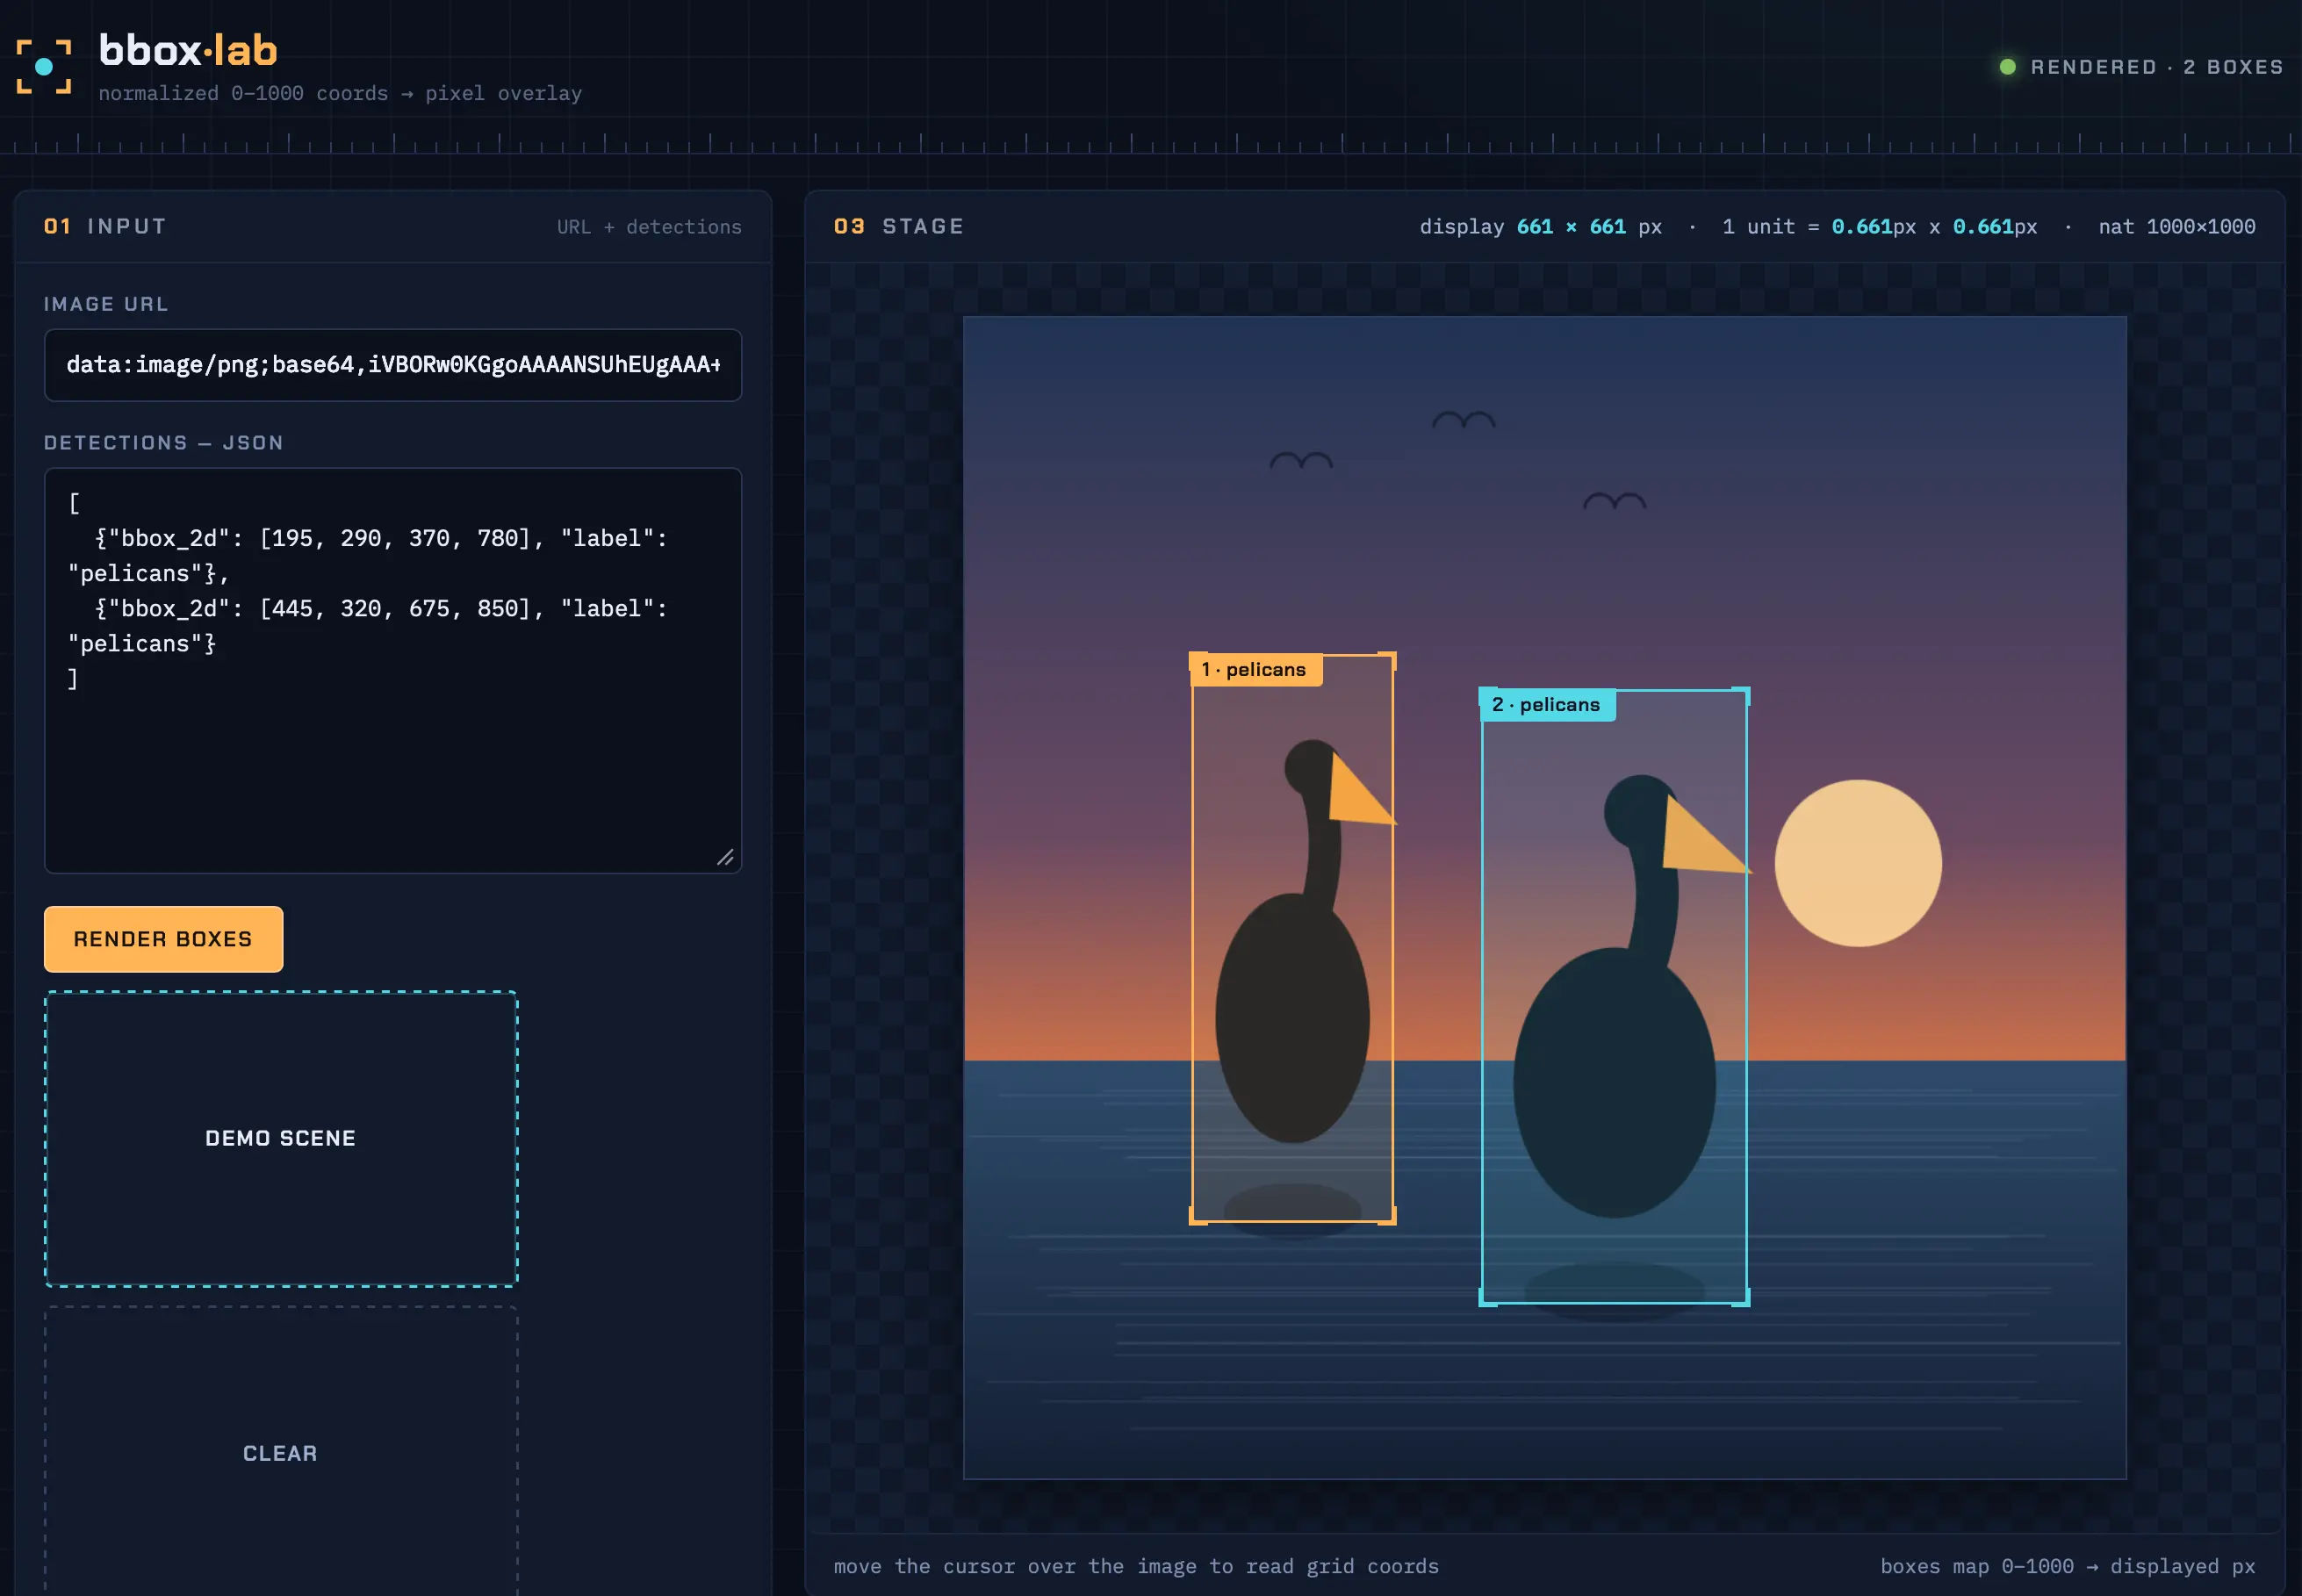
Right here’s the related section of the pondering hint, the place it determined to attract its personal pelicans purely as a result of I had used the label “pelicans” within the instance JSON I gave it within the immediate:
Additionally a “load pattern” that makes use of a identified picture? Can’t rely on exterior photos, however… the picture URL enter is user-provided; I may add a “attempt with pattern” button […] Hmm, I can draw a easy scene on canvas, export it as an information URL, and cargo it into the picture — that’s self-contained and demo-able! […] However the person’s coords are for an precise pelican picture; a generated placeholder can nonetheless demo the scaling. Generate a 1000×1000 placeholder: gradient water + two blob-like “pelican” silhouettes positioned on the given bboxes (utilizing the identical scale — cute: silhouettes on the precise 0-1000 positions, displaying the packing containers align). This makes for a enjoyable, self-contained demo. Preserve it easy: sky gradient, solar, water, two pelican-ish shapes (ellipse physique, circle head, beak). Place at bbox facilities.
(I’m barely nervous that fashions world wide might need a bias in the direction of drawing pelicans at any probability they’ll get, introduced on by almost two years of publicity to my very own silly benchmark.)
Is all that over-thinking essential? Perhaps it’s, no less than a bit. I attempted with reasoning turned off and bought this model, (transcript right here), which almost works however exhibits the packing containers within the fallacious place:
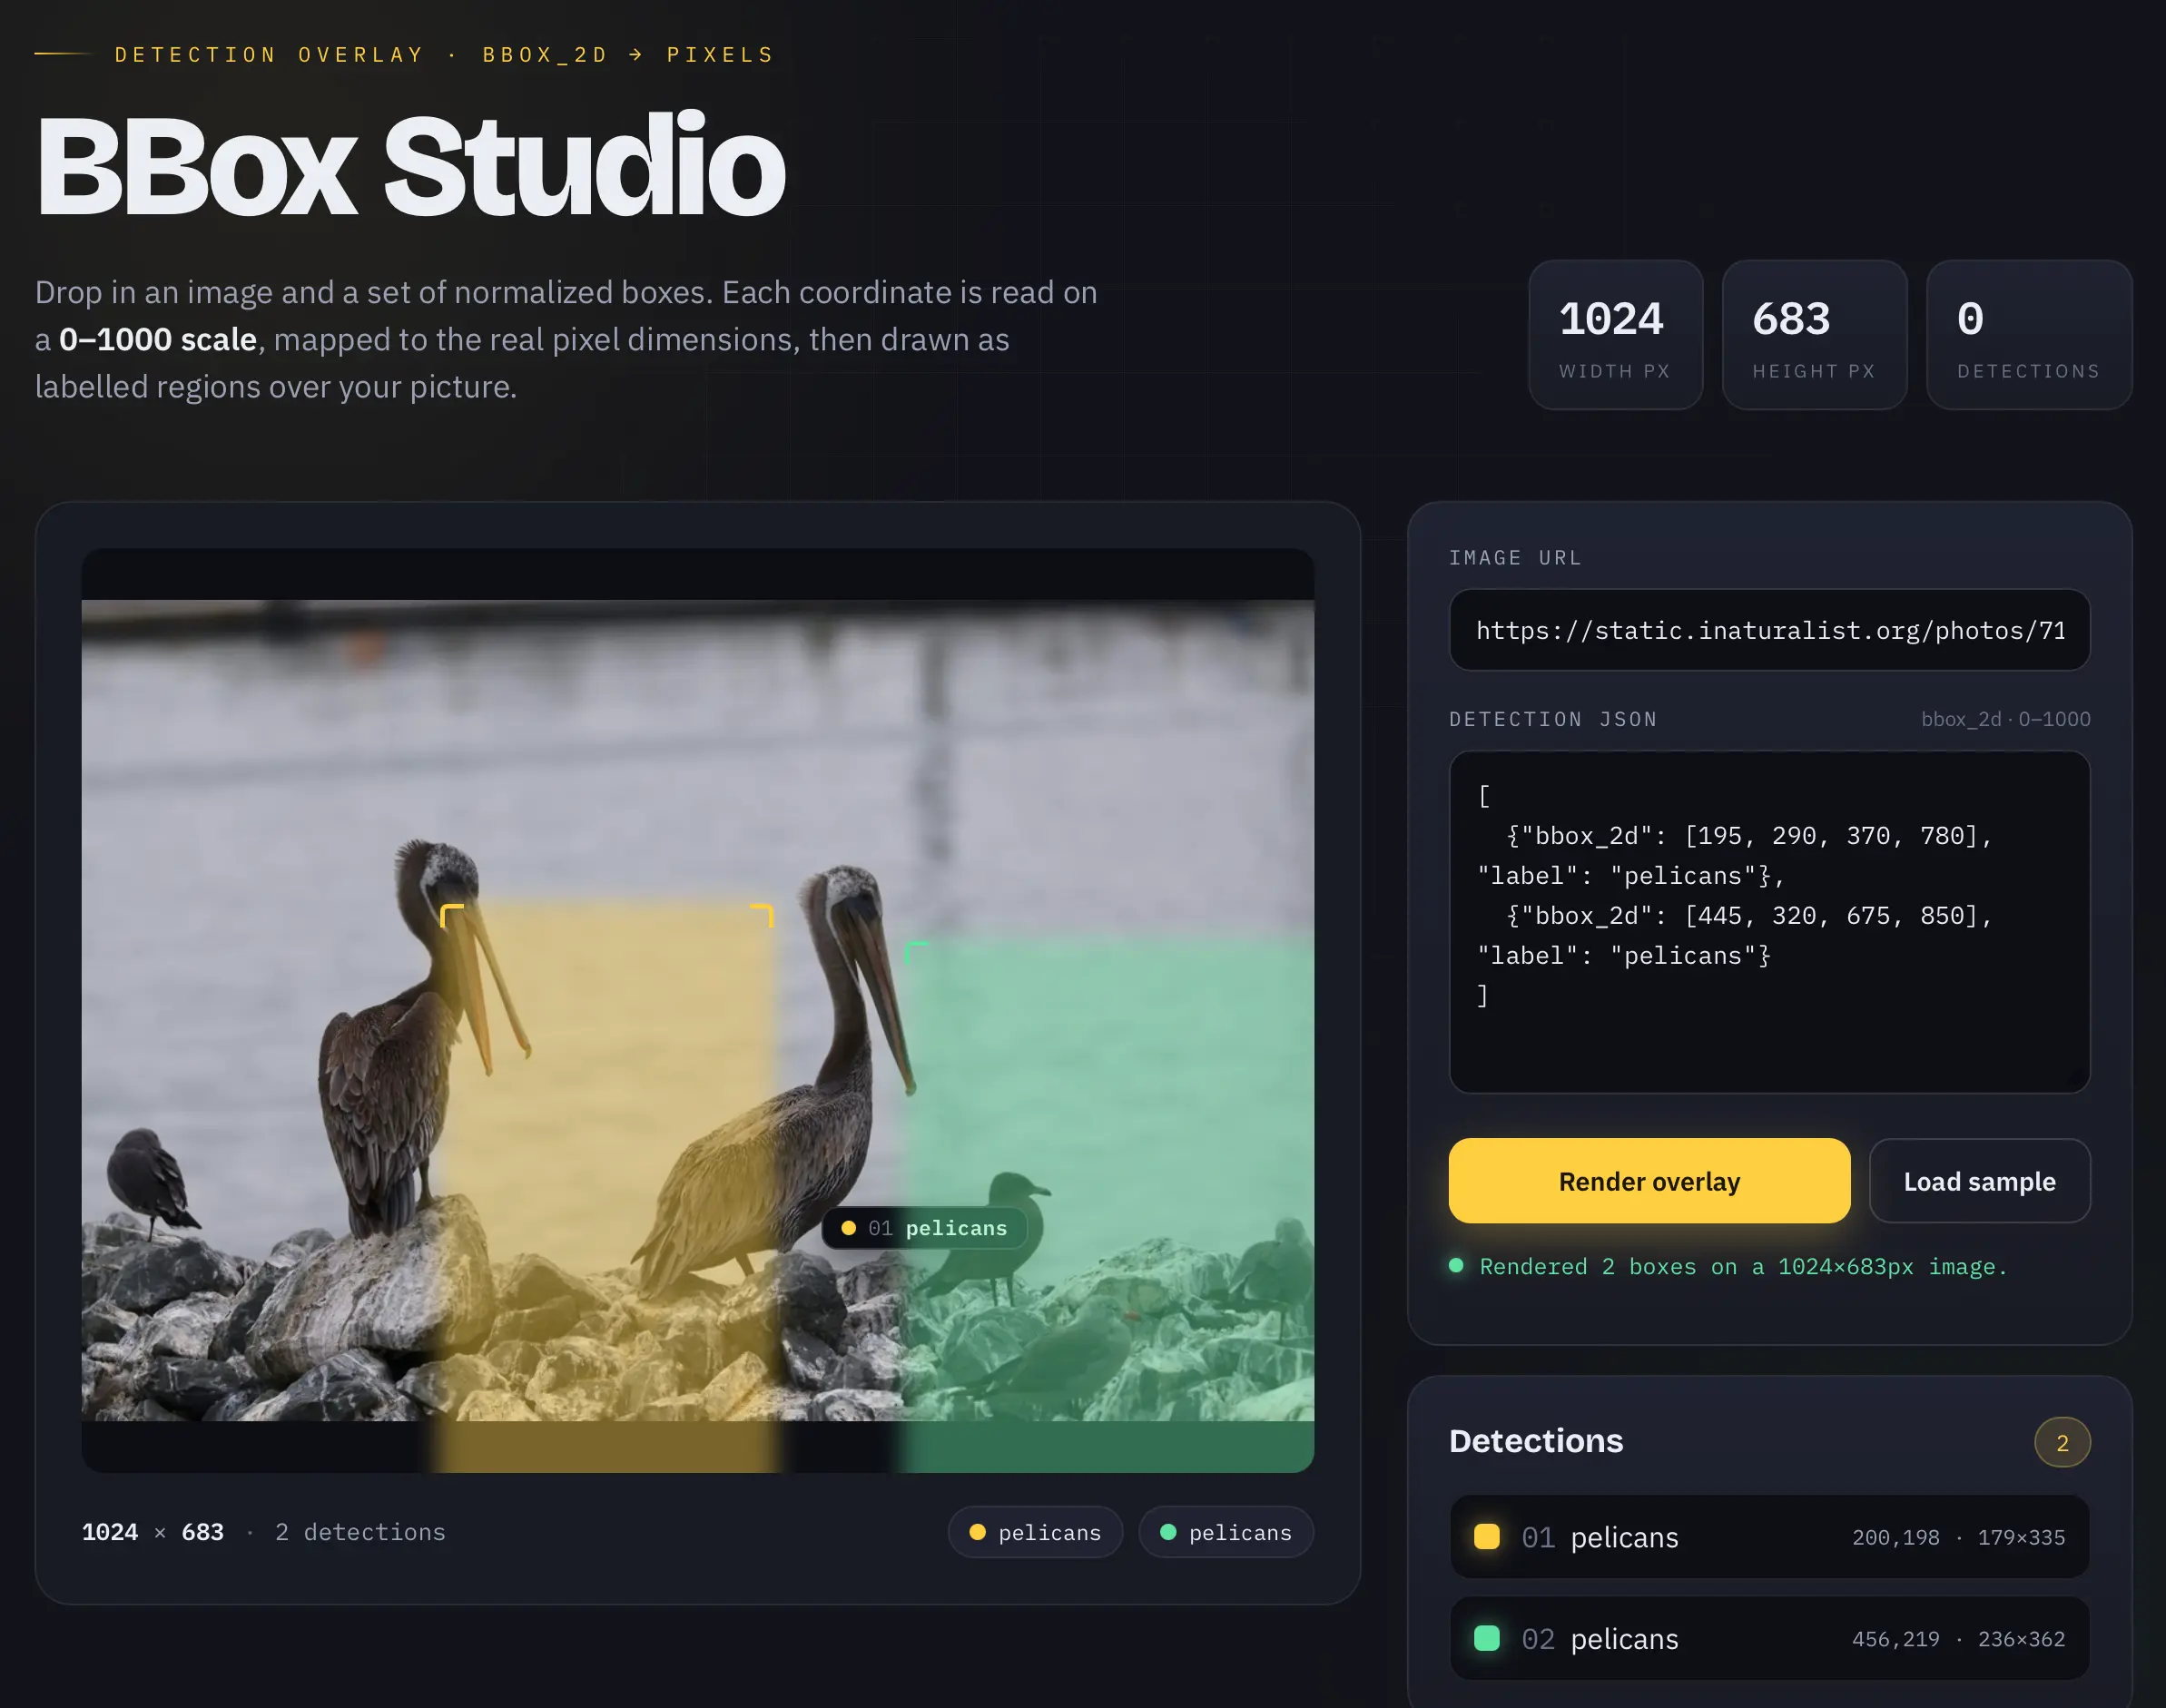
So with out reasoning it didn’t fairly one-shot a working device. I’m positive it may get there with some follow-up prompts, however it is a good instance of how reasoning could make a distinction.
Sure, it might drive coding brokers
One of many largest questions round native fashions is whether or not or not they’ve sufficient horsepower to efficiently run a coding agent loop. Coding brokers require lengthy context, robust code technology assist and dependable tool-calling. On paper Qwen 3.8 27B has all three of those, so is it as much as the duty?
My preliminary experiments with Pi have been very promising. I selected Pi as a result of it has a shorter system immediate than most different choices, making it a greater match for making an attempt out smaller fashions.
I configured Pi to make use of Qwen 3.8 27B operating in LM Studio on the Spark (shared by way of tailscale serve) by including this to ~/.pi/agent/fashions.json:
“suppliers”: {
“spark”: {
“baseUrl”: “https://spark-18b3.tail68a31.ts.web/v1“,
“api”: “openai-responses“,
“apiKey”: “dummy“,
“fashions”: [
{
“id”: “qwen3.8-27b“,
“reasoning”: true
}
]
}
}
}
Then ran pi –provider spark –model qwen3.8-27b in my ~/dev/datasette folder and prompted:
how does auth work?
After a sequence of reasoning and power calls that accessed a bunch of various recordsdata it produced this reply, which may be very stable.
Only one drawback: I wished to share that transcript. So I pointed Pi and Qwen 3.8 27B on the JSONL transcript file in ~/.pi/agent/classes/–Customers-simon-Dropbox-dev-datasette– and prompted:
Write Python code to transform this jsonl to markdown
And it constructed and examined this pi_jsonl_to_md.py, which did precisely what I wanted. Right here’s that session transcript, printed utilizing the device that it created.
The hunt for velocity
Thus far that is all trying very promising. We now have a 17GB mannequin that runs on high-end client {hardware} and may write code, drive instruments, annotate photos and customarily do all the things that I would like from an LLM for getting actual work completed.
There’s one very important catch: it feels gradual—particularly when it begins over-thinking, however even with out that it’s not significantly sprightly.
I’ve been getting round 15-30 tokens a second from LM Studio. That’s not horrible, but it surely’s gradual sufficient that it’s going to be laborious to win me away from hosted API fashions, which might return outcomes a complete lot quicker. Synthetic Evaluation observe token velocity and present OpenAI 5.6 Sol at 74 tokens/second and 5.6 Luna at a formidable 184/second.
The excellent news is that the group have been exploring methods to hurry issues up for the reason that mannequin was first launched two days in the past.
One of the promising optimizations is baked into the mannequin itself. Qwen helps Multi-Token Prediction, an structure trick the place a less expensive mechanism guesses a number of tokens forward and the principle mannequin can then rapidly confirm if the guesses have been appropriate. This could have fairly a dramatic impact on inference efficiency.
Primarily based on this tweet from llama.cpp creator Georgi Gerganov I attempted operating the mannequin with MTP like this on the Spark:
-hf ggml-org/Qwen3.8-27B-GGUF:Q4_K_M
-hfd ggml-org/Qwen3.8-27B-GGUF:Q4_0
–spec-default
–spec-type draft-mtp
–reasoning-preserve
And positive sufficient, this gave me a big increase. I had GPT-5.6 in Codex run a comparative benchmark on the Spark and the –spec-type draft-mtp server outperformed the LM Studio default GGUF by round 72%.
I count on we’ll see a complete lot extra innovation round serving this mannequin quicker over the following few weeks. The MLX group doubtless have some tips brewing as properly.
Some observations
The truth that a 17GB file can do all of these things on my dwelling machines is a miracle. As soon as once more, I’m delighted and amazed at how a lot progress native fashions have made this 12 months. A 12 months in the past this is able to have been aggressive with the very best and costliest of the proprietary fashions—at this time it might run on a succesful laptop computer.
The one factor holding this again from being a every day driver is efficiency. It feels fairly gradual on each the M5 Mac and the DGX Spark. That’s the catch with these dense (non-Combination-of-Consultants) fashions—they require a complete lot of reminiscence bandwidth to carry out properly, and neither of the machines I’ve entry to are prime performers in that regard.
Crucial factor about Qwen 3.8 27B is what it demonstrates. We will have an open weights basic objective mannequin with an extended context, efficient device calling, robust imaginative and prescient capacity, and competent code technology, and we are able to match the entire thing in only a 17GB file.
The fashions at this dimension proceed to get higher at a formidable fee. We don’t have to spend half one million {dollars} on datacenter-class {hardware} simply to run a reliable mannequin.