This yr, many information groups have added AI brokers to their roadmaps. The thrill is actual: an agent that turns a two-day evaluation right into a two-minute dialog can change how analysts and enterprise groups work collectively.
However brokers are solely as dependable as the info basis beneath them. Level them at uncooked tables or outdated metadata, and so they could sound convincing whereas being incorrect. This text outlines a sensible framework for producing and deploying ruled semantic views on Snowflake.
Why Agent High quality Breaks Down
Three failure patterns present up repeatedly as soon as brokers transfer from demo to manufacturing:
Governance will get traded for velocity. Groups below strain to ship skip questions on information integrity and entry management till an agent is already answering questions for the enterprise.
Duplication proliferates. With no shared course of, completely different groups construct overlapping brokers that reply the identical query in subtly completely different – and inconsistent – methods.
Solutions are non-deterministic. The identical query, requested twice, returns two completely different numbers. That’s worse than being reliably incorrect, as a result of no one is aware of when to mistrust the reply.
All three hint again to 1 root trigger: there’s no standardized, enforced course of governing how a semantic definition will get created, reviewed, versioned, and promoted. Tooling that helps you creator semantic views sooner doesn’t resolve this by itself – velocity and governance are completely different axes, and a corporation can have loads of one and little or no of the opposite.
What a Semantic Layer Really Does
Ask 5 groups “what’s the complete variety of energetic members in Q1 2026?” and not using a shared semantic layer, and it’s possible you’ll get 5 completely different numbers. Every staff applies its personal filters, joins its personal tables, and defines “energetic” in another way – and an LLM requested the identical query with no grounding will hallucinate a sixth reply that sounds simply as assured as the opposite 5.
A semantic layer solves this by sitting between the uncooked warehouse and each client – dashboards, spreadsheets, and now AI brokers – and answering three questions the identical method, each time: which tables maintain this information, what filters apply, and what’s the aggregation logic and grain. Snowflake’s personal documentation frames this as addressing the mismatch between how enterprise customers describe information and the way it’s really saved in database schemas – for instance, defining “web income” as soon as, persistently, as SUM(gross_revenue * (1 – low cost)), somewhat than leaving the calculation to be reinvented in each report.
The place This Lives in Snowflake
In Snowflake, the semantic layer is carried out as a semantic view, a schema-level object saved immediately within the database that defines enterprise metrics and fashions entities and their relationships, which Cortex Analyst – Snowflake’s text-to-SQL software, can then question in pure language. Cortex Agent is the AI orchestrator that holds a number of semantic views, alongside search providers and customized instruments, and decides which useful resource solutions a given query – the identical structure underpinning Snowflake CoWork(previously Snowflake Intelligence).
Right here’s what that specification appears like stuffed in with an actual instance. Beneath is a semantic view over a SaaS billing dataset – two logical tables (billing and clients), joined on buyer ID, with three licensed income metrics outlined as soon as:
title: SAAS_BILLING
description: Combines buyer data with subscription billing particulars
to help licensed MRR, web MRR, and churned income metrics.
tables:
– title: BILLING
base_table: { database: FINANCE, schema: ANALYTICS, desk: FCT_SAAS_BILLING }
dimensions:
– title: BILLING_DATE
expr: BILLING_DATE
data_type: DATE
– title: PLAN_TYPE
expr: PLAN_TYPE
data_type: VARCHAR(20)
details:
– title: MRR_AMOUNT
expr: MRR_AMOUNT
data_type: NUMBER(10,2)
metrics:
– title: TOTAL_MRR
expr: SUM(billing.MRR_AMOUNT)
– title: NET_MRR
expr: SUM(billing.MRR_AMOUNT) – SUM(billing.DISCOUNT_AMOUNT)
– title: CHURNED_REVENUE
expr: SUM(IFF(billing.IS_ACTIVE = FALSE, billing.MRR_AMOUNT, 0))
primary_key: { columns: [BILLING_ID] }
– title: CUSTOMERS
base_table: { database: FINANCE, schema: ANALYTICS, desk: DIM_CUSTOMERS }
dimensions:
– title: COMPANY_NAME
expr: COMPANY_NAME
data_type: VARCHAR(100)
– title: INDUSTRY
expr: INDUSTRY
data_type: VARCHAR(50)
primary_key: { columns: [CUSTOMER_ID] }
relationships:
– title: CUSTOMER_BILLING
left_table: BILLING
right_table: CUSTOMERS
relationship_columns:
– { left_column: CUSTOMER_ID, right_column: CUSTOMER_ID }
(Trimmed for readability – the complete generated file consists of each column remark and entry modifier. Repo has the complete semantic definition )
What’s not in query is that this object works. What’s in query is: how does a semantic view like this get created within the first place?
The Two Governance Pillars Behind Each Licensed Metric
Earlier than the pipeline itself, it’s price being exact concerning the two ruled inputs it is dependent upon.
The Information Catalog: One authoritative supply for enterprise descriptions, information varieties, sensitivity tags (PII/PHI), pattern values, and certification standing for each column and desk. On this implementation that’s Snowflake Horizon – tags are set on the column degree or desk degree. The catalog comprises the info kind, description, synonyms, pattern values and so forth., and a dynamic masking coverage can prohibit who ever sees a flagged column. A certification_status=”Licensed” tag is the inexperienced gentle for th at column’s metadata for use in a semantic view in any respect.
The Metric Stock: A single ruled dwelling for each metric system, with an outline, enterprise proprietor, supply desk, area, sensitivity classification, and critically a certification standing. The operative rule: every metric is outlined as soon as and reused in all places, and “as soon as” is gated behind an precise sign-off from a website proprietor or information steward. That is what’s going to resolve the issue that the identical metric may be answered 6 other ways throughout groups.
The Framework: A Governance Harness for Semantic View Era
The core thought is straightforward to state: deal with semantic view technology as a ruled software program launch, not a one-off modeling train. In apply meaning 5 parts, every implementing a rule that a casual course of usually leaves optionally available. Earlier than strolling by way of every one, it helps to see the entire pipeline finish to finish, after which how that pipeline suits into the broader Snowflake structure – the 2 diagrams beneath cowl precisely that.
Governance Framework Circulate Diagram
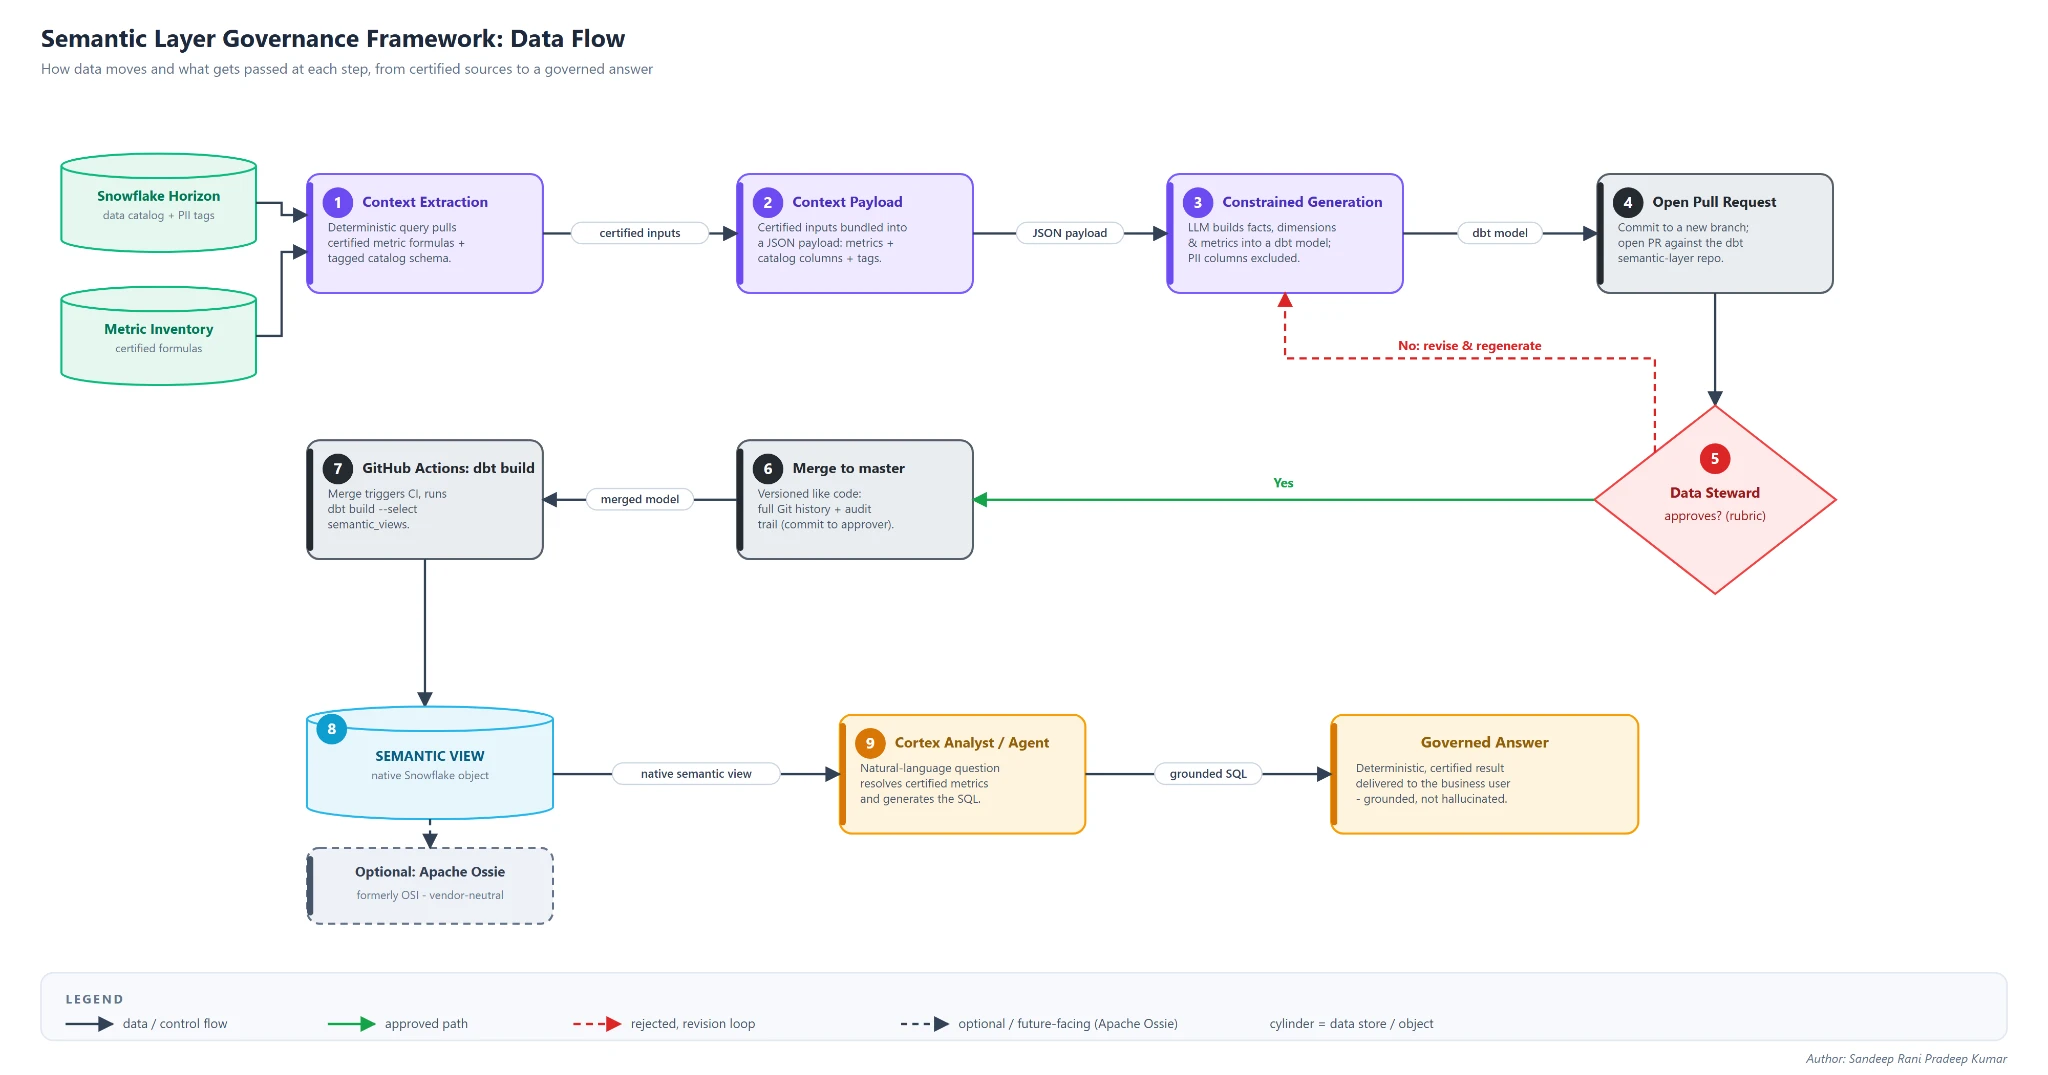
Zooming out one degree: this pipeline is barely the build-time half of the image. Determine 2 reveals the way it suits alongside the techniques that truly devour its output – Cortex Analyst, Cortex Brokers, Snowflake Cowork, and the BI instruments mentioned later on this article.
System structure
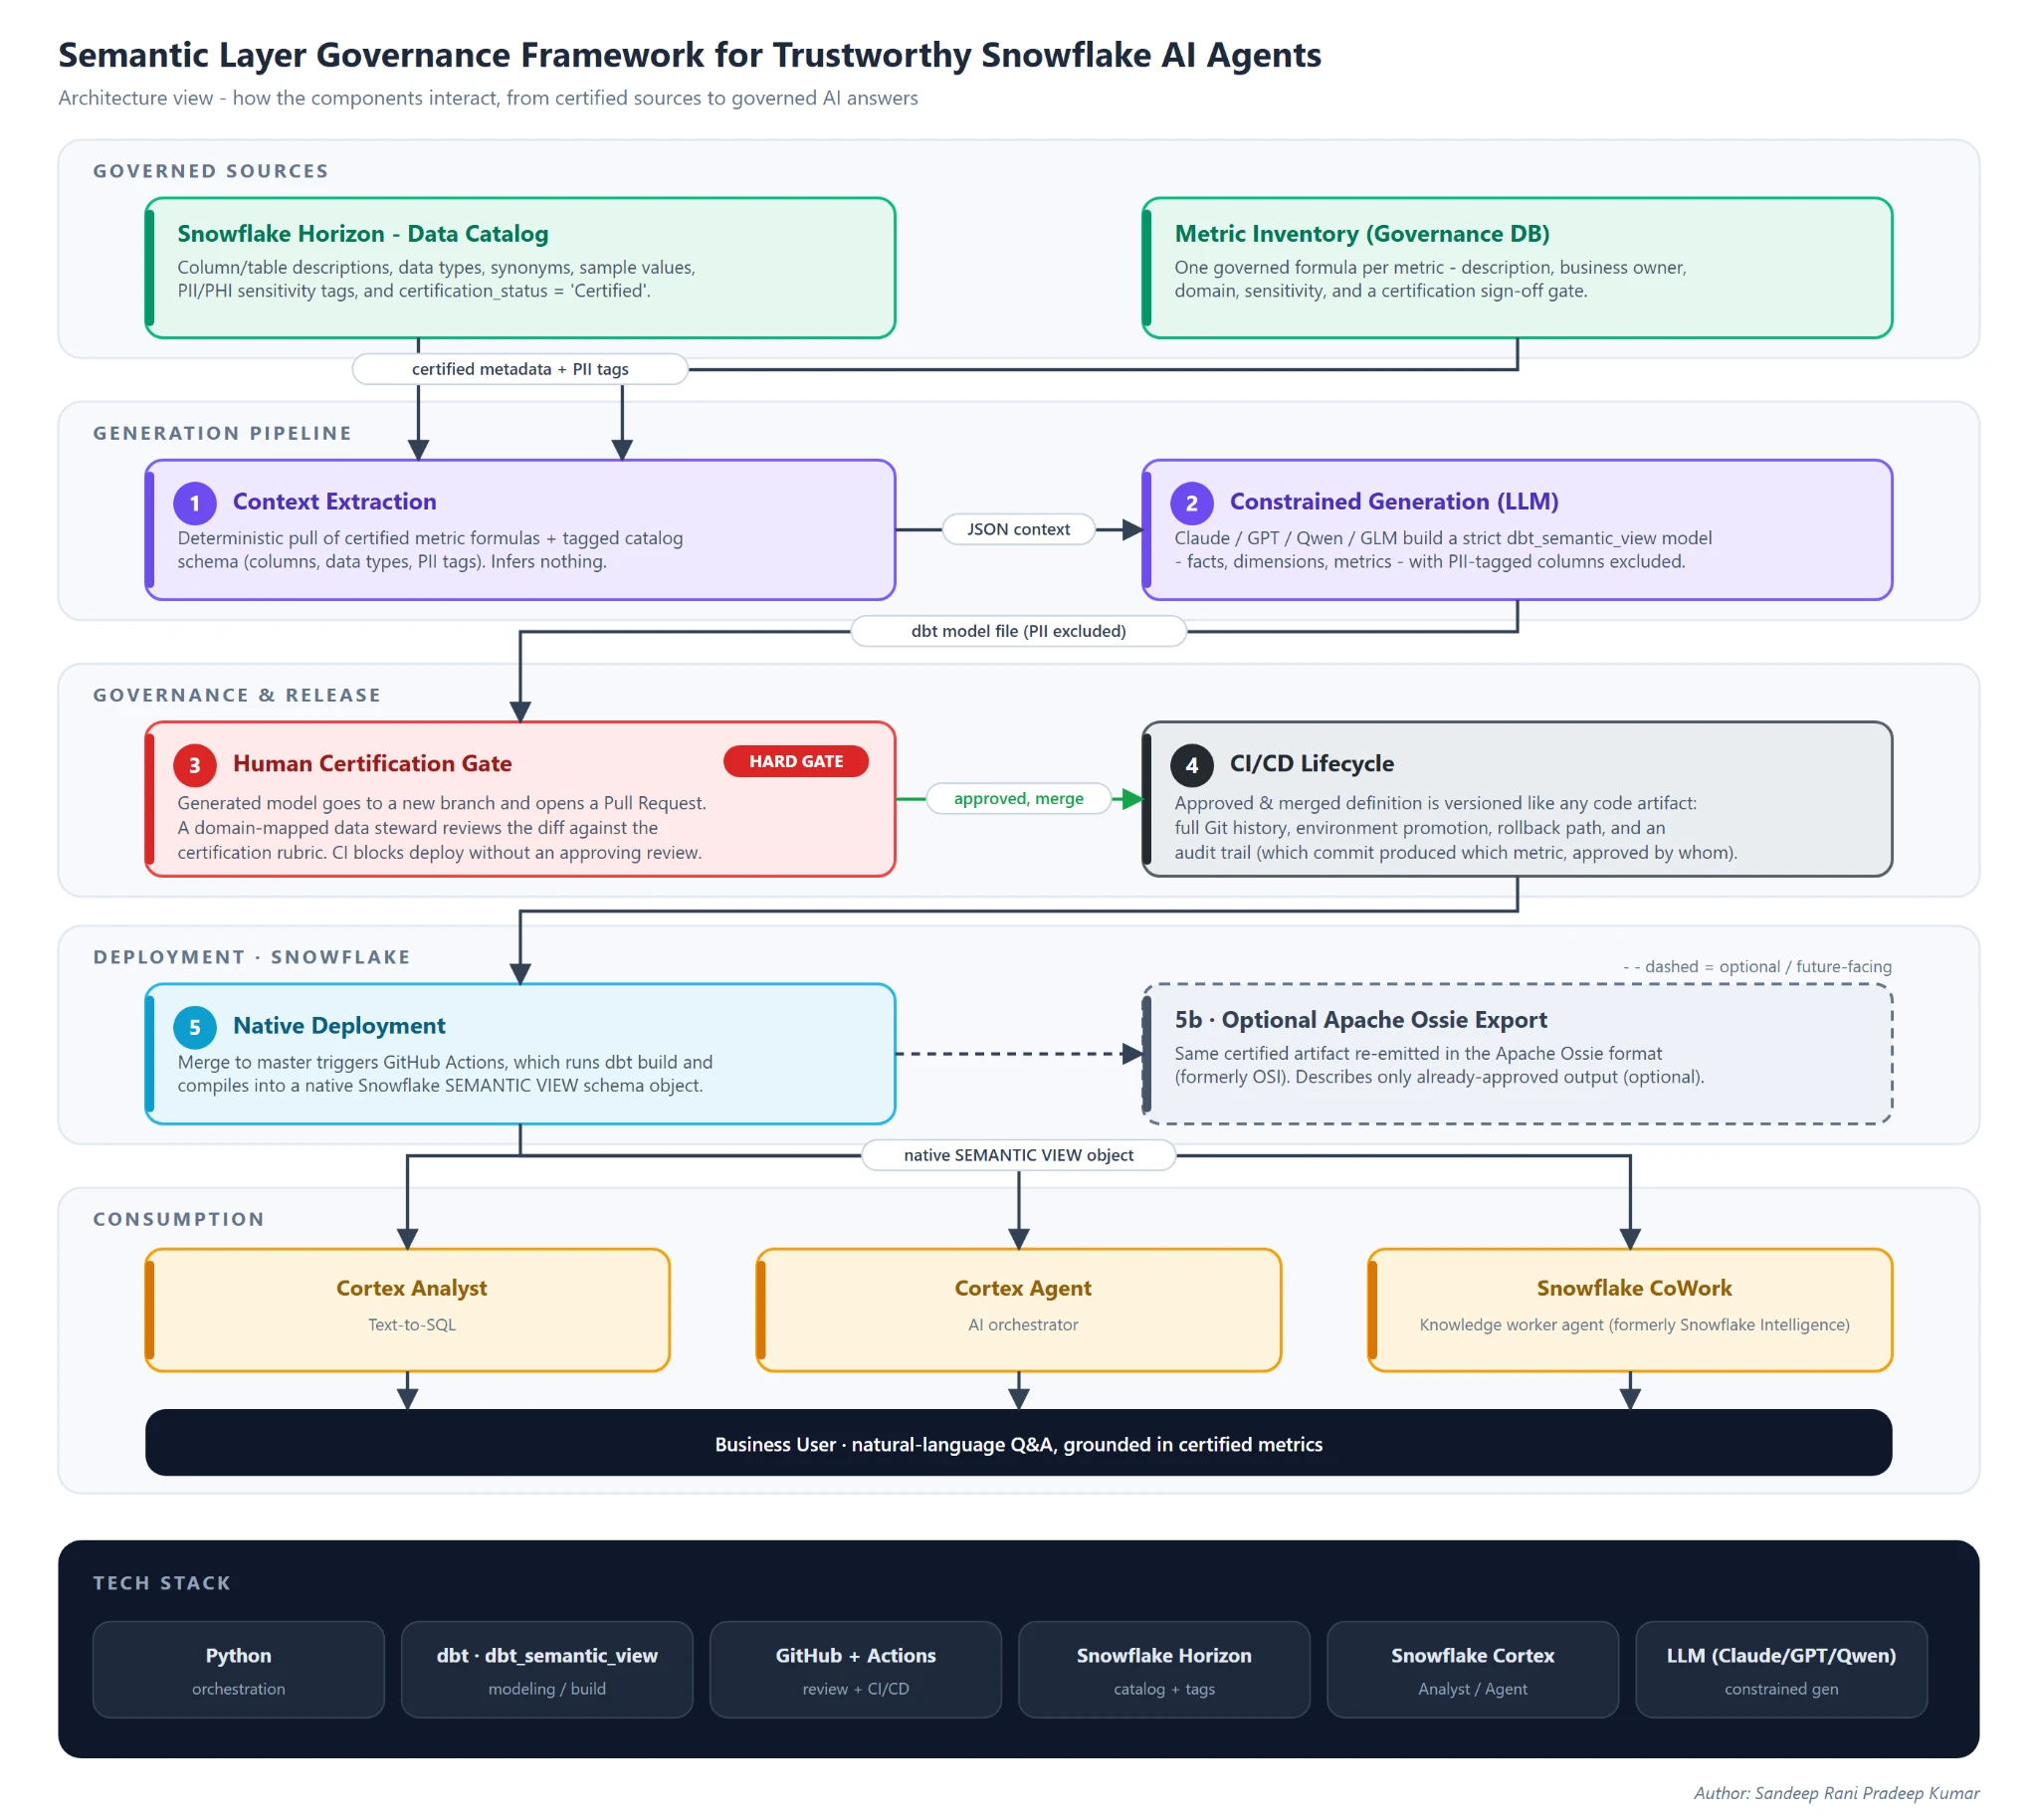
The total code for the beneath parts breakdown is right here.
An orchestration script connects to Horizon and the metric stock and pulls, for a given area, solely licensed metric formulation and tagged schema. This step is deterministic – it retrieves already-approved details, it doesn’t infer something:
cursor.execute(f”””
SELECT metric_name, description, expression, base_table
FROM GOVERNANCE_DB.SEMANTICS.METRIC_INVENTORY
WHERE certification_status=”Licensed”
AND base_table IN ({table_list})
“””)
metrics = [
{“metric_name”: r[0], “description”: r[1], “expression”: r[2], “desk”: r[3]}
for r in cursor.fetchall()
]
The method pulls schema and tag context immediately from Horizon tag references.
catalog_query = f”””
WITH physical_schema AS (
SELECT table_schema, table_name, column_name, data_type, remark AS column_description
FROM {database}.INFORMATION_SCHEMA.COLUMNS
WHERE table_schema IN ({schema_list}) AND table_name IN ({table_list})
),
horizon_tags AS ( {real_time_tags_cte} )
SELECT p.table_name, p.column_name, p.data_type, p.column_description, t.tag_value AS privacy_tag
FROM physical_schema p
LEFT JOIN horizon_tags t
ON p.table_name = t.table_name AND p.column_name = t.column_name
“””
That is the primary structural distinction from usage-inference approaches price stating plainly: this pipeline solely ever proposes definitions that hint again to a pre-approved supply, somewhat than a definition surfaced as a result of it was the most typical sample in somebody’s question historical past. Reputation is a helpful discovery sign; it isn’t the identical declare as governance sign-off.
Part 2 – Constrained Era
An LLM of selection (Claude, GPT, Qwen, GLM and so forth) converts the extracted context right into a strictly formatted dbt mannequin utilizing the dbt_semantic_view package deal syntax. The important thing management is constraint: the system immediate fixes the output schema and clause order and requires each generated area to map to a catalog or stock entry as an alternative of the mannequin’s personal judgment. A trimmed model of the particular system immediate used on this pipeline:
SYSTEM_PROMPT = “””You might be an knowledgeable Information Engineer constructing dbt semantic
fashions for Snowflake.
You’ll obtain a JSON context payload with:
– metrics: licensed metric definitions (metric_name, expression, desk)
– catalog: bodily columns per desk (desk, column, data_type,
description, tag)
– table_descriptions: [{ table, description }]
supply desk in Snowflake
Produce ONE legitimate dbt mannequin file utilizing the Snowflake-Labs dbt_semantic_view
package deal. Output ONLY the uncooked file contents. No prose, no markdown fences,
no preamble.
Required clauses, on this actual order, separated by newlines:
{{ config(materialized=’semantic_view’) }}
TABLES (
AS {{ supply(”, ”) }}
[ PRIMARY KEY () ] [ COMMENT = ” ]
)
RELATIONSHIPS (
AS () REFERENCES
)
FACTS (
. AS [ COMMENT = ‘…’ ] [, …]
)
DIMENSIONS (
. AS [ COMMENT = ‘…’ ] [, …]
)
METRICS (
. AS [ COMMENT = ‘…’ ] [, …]
)
COMMENT = ”
PII dealing with: any column whose `tag` comprises ‘PII’ (case-insensitive) MUST
be excluded from FACTS, DIMENSIONS, and METRICS.
“””
As a result of the extracted context consists of the PII tag, the mannequin robotically omits or masks flagged columns as an alternative of creating case-by-case judgments.
Past PII filtering, two controls implement governance:
Predictable output: Prohibit the mannequin to a strict, non-conversational format so reviewers can confirm the generated code persistently and effectively.
Information Integrity: The mannequin should solely use the precise information offered within the enter, which prevents it from “hallucinating” or inventing its personal columns and formulation.
By making use of this method immediate to the catalog and metric context, the pipeline robotically generates the required semantic view dbt mannequin, changing handbook coding with verified, automated output which might be 95% correct.
Part 3 – Human Certification Gate
Nevertheless correct the LLM’s output normally is, manufacturing metrics can’t tolerate even a small share of hallucinated logic. So the generated definition is rarely merged robotically – it’s dedicated to a brand new department and opened as a pull request in opposition to the semantic-layer dbt repository. The orchestrator operate ties 4 smaller GitHub API calls collectively:
def open_pr_for_file(proprietor, repo, file_path, content material, commit_message,
pr_title, pr_body, department, base=”grasp”,
token=””, draft=False) -> str:
if not token:
elevate ValueError(“GITHUB_TOKEN is required”)
base_sha = get_default_branch_sha(proprietor, repo, token, base=base)
create_branch(proprietor, repo, base_sha, department, token)
put_file(proprietor, repo, file_path, content material, commit_message, department, token)
return create_pr(proprietor, repo, pr_title, pr_body, department, base,
token, draft=draft)
Every of these 4 calls is a small, single-purpose wrapper across the GitHub REST API – intentionally stored easy so the evaluate path stays legible:
# Create a brand new department off the bottom commit
def create_branch(proprietor, repo, base_sha, new_branch, token) -> None:
r = requests.put up(
f”{API}/repos/{proprietor}/{repo}/git/refs”,
headers=_headers(token),
json={“ref”: f”refs/heads/{new_branch}”, “sha”: base_sha},
timeout=30,
)
_check(r)
# Lookup the present file SHA, if it already exists on this department
def get_file_sha(proprietor, repo, path, department, token) -> Optionally available[str]:
r = requests.get(
f”{API}/repos/{proprietor}/{repo}/contents/{path}”,
headers=_headers(token), params={“ref”: department}, timeout=30,
)
if r.status_code == 404:
return None
return _check(r).get(“sha”)
# Commit the generated semantic view file to that department
def put_file(proprietor, repo, path, content material, message, department, token) -> dict:
payload = {
“message”: message,
“content material”: base64.b64encode(content material.encode(“utf-8”)).decode(“ascii”),
“department”: department,
}
current = get_file_sha(proprietor, repo, path, department, token)
if current:
payload[“sha”] = current
r = requests.put(
f”{API}/repos/{proprietor}/{repo}/contents/{path}”,
headers=_headers(token), json=payload, timeout=60,
)
return _check(r)
# Open the PR for the info steward to evaluate
def create_pr(proprietor, repo, title, physique, head, base, token,
draft=False) -> str:
r = requests.put up(
f”{API}/repos/{proprietor}/{repo}/pulls”,
headers=_headers(token),
json={“title”: title, “physique”: physique, “head”: head,
“base”: base, “draft”: draft},
timeout=30,
)
return _check(r)[“html_url”]
A website-mapped information steward – the named proprietor from the metric stock – opinions the diff in opposition to the certification rubric outlined within the subsequent part. It is a arduous gate: the CI pipeline blocks deployment with out an approving evaluate from a certified reviewer, enforced the identical method a manufacturing codebase enforces required reviewers.
Part 4 – CI/CD Lifecycle
After approval and merge, Git variations the definition like another code artifact, preserving historical past, promotion workflows, and rollback functionality. That is what offers the group one thing advert hoc semantic-view creation structurally can not: an audit path answering, for any metric on any date, precisely which commit produced it and who permitted it.
Part 5 – Native Deployment
Merging to the primary department triggers a GitHub Actions workflow that runs dbt construct, compiling the licensed mannequin right into a native Snowflake SEMANTIC VIEW object:
on:
push:
branches: [master]
paths: [‘semantic_models/models/semantic_views/**’]
jobs:
deploy-dbt-models:
runs-on: ubuntu-latest
steps:
– makes use of: actions/checkout@v4
– makes use of: actions/setup-python@v5
with: { python-version: ‘3.10’ }
– run: pip set up -r necessities.txt
– run: dbt deps
– run: dbt debug
– run: dbt construct –select semantic_views
From this level ahead, Cortex Analyst, Cortex Brokers, and Snowflake CoWork question the deployed object precisely as they’d one constructed another method. One implementation observe: Snowflake internally represents the semantic view as YAML. Groups can deploy it immediately from a YAML specification, however dbt SQL permits the human-review and CI/CD workflow described above.
Part 5b – An Optionally available Apache Ossie (previously OSI) Export
Price designing for earlier than you want it: emit the identical licensed artifact a second time in Apache Ossie format, alongside the Snowflake deployment. Ossie is the vendor-neutral, Apache 2.0 spec previously referred to as Open Semantic Interchange (OSI), renamed when it entered the Apache Incubator in July 2026. It describes datasets, metrics, dimensions, relationships, and context so instruments and brokers interpret them persistently.
It suits the pipeline as a result of Ossie’s constructing blocks map nearly immediately onto what Elements 1 by way of 3 already extract and certify. Including it’s a serialization step on high of governance work you’ve already finished, not a brand new governance burden.
Specs
Beneath is a sneak peek (full spec right here), illustrative somewhat than a part of the reference repo since nothing consumes it but, constructed in opposition to the general public spec.yaml schema and mapping the identical licensed SAAS_BILLING fields into datasets / relationships / metrics:
model: 0.1.1
semantic_model:
– title: saas_billing
description: >
Combines buyer data with subscription billing particulars to
help licensed MRR, web MRR, and churned income metrics.
ai_context: >
Use this mannequin to reply questions on MRR, income churn, and
buyer billing. “Energetic” means IS_ACTIVE = TRUE on the billing document.
datasets:
– title: billing
supply: FINANCE.ANALYTICS.FCT_SAAS_BILLING
primary_key:
– BILLING_ID
fields:
– title: billing_date
expression:
dialects:
– dialect: SNOWFLAKE
expression: BILLING_DATE
dimension:
is_time: true
– title: plan_type
expression:
dialects:
– dialect: SNOWFLAKE
expression: PLAN_TYPE
– title: is_active
expression:
dialects:
– dialect: SNOWFLAKE
expression: IS_ACTIVE
– title: mrr_amount
expression:
dialects:
– dialect: SNOWFLAKE
expression: MRR_AMOUNT
description: Month-to-month recurring income quantity.
– title: clients
supply: FINANCE.ANALYTICS.DIM_CUSTOMERS
primary_key:
– CUSTOMER_ID
fields:
– title: company_name
expression:
dialects:
– dialect: SNOWFLAKE
expression: COMPANY_NAME
– title: trade
expression:
dialects:
– dialect: SNOWFLAKE
expression: INDUSTRY
relationships:
– title: customer_billing
from: billing
to: clients
from_columns:
– CUSTOMER_ID
to_columns:
– CUSTOMER_ID
metrics:
– title: churned_revenue
expression:
dialects:
– dialect: SNOWFLAKE
expression: SUM(IFF(billing.is_active = FALSE, billing.mrr_amount, 0))
description: Income misplaced from canceled plans
ai_context: >
Use this when the consumer asks about misplaced, canceled, or churned
income, not for questions on buyer counts.
This export offers two fundamental benefits:
Diminished conversion work, not magic portability: The expression.dialects construction lets a metric carry engine-specific expressions in a single widespread artifact, which cuts conversion effort for any client that implements the usual. It doesn’t make the metric robotically executable in all places – portability nonetheless is dependent upon every client supporting the related dialect and semantic conduct.
AI-facing context, not a governance retailer: The ai_context area is for AI steerage – synonyms, examples, and utilization directions that assist an agent select the suitable metric. Maintain possession, certification proof, and approval historical past in your authoritative governance techniques (catalog, metric stock, PR data), or in clearly outlined customized extensions – not in ai_context.
Doesn’t Snowflake already do that?
No. Snowflake’s tooling solves discovery. This framework solves certification.
Autopilot finds statistical consensus in question historical past. That tells you what individuals already do, not what’s appropriate, and two groups can produce two conflicting “consensus” definitions with no proprietor compelled to reconcile them.
Horizon Context helps brokers discover an current semantic view. It doesn’t inform you whether or not that view was ever reviewed, by whom, or in opposition to what model historical past.
Cortex Sense ranks undocumented information by relevance, recognition, and freshness, like net search. That’s a distinct belief mannequin totally.
None of it is a knock on Snowflake’s roadmap. For licensed metrics, require a named approver and a versioned audit path earlier than launch.
A technology framework has restricted worth when organizations can use licensed artifacts solely inside Snowflake AI surfaces.
Instrument
Integration
Standing
Metric reuse
Key limitations
Energy BI
Energy BI consuming a Snowflake semantic view immediately
Unsupported
No
Energy BI doesn’t help non-native semantic fashions.
Energy BI / Tableau (reverse)
Snowflake ingests .pbit/.pbix information through Semantic View Autopilot
Public Preview
Partial
Works in the wrong way; Energy BI nonetheless can not question a stay Snowflake semantic view.
Tableau (TDS export)
Export a semantic view as a Tableau Information Supply (.tds) from Snowsight
Public Preview
Sure
Auto-assigned dimensions and measures may have handbook adjustment.
Sigma
Sigma consuming Snowflake semantic views
Beta
Partial
Limitations round joins, unions, APIs, derived metrics, inherited semantics, and AI assistant consciousness.
Omni
Native two-way integration with Snowflake semantic views
Accessible
Sure
Some documented modeling and question edge circumstances stay.
AtScale (XMLA bridge)
Expose Snowflake semantic views to Energy BI and Excel through XMLA
Personal Preview (introduced Jun 2, 2026)
Sure
Preview characteristic; verify availability and manufacturing readiness earlier than adoption.
Few takeaways:
Snowflake nonetheless doesn’t help direct Energy BI consumption of semantic views, though it will probably ingest Energy BI property into Autopilot and a third-party XMLA bridge is in personal preview.
Assist stays uneven throughout platforms; Omni affords a comparatively direct two-way integration, Tableau offers a preview TDS export that preserves metrics, and Sigma stays in beta with notable limitations.
The place native help is absent, groups nonetheless must duplicate some modeling work, which open requirements akin to Apache Ossie purpose to scale back over time.
A Certification Rubric, So “Human within the Loop” Isn’t a Slogan
The effectiveness of your evaluate course of relies upon totally on the standard of the guidelines used. At a minimal, each human reviewer ought to confirm these factors:
Supply monitoring: Verify that each information level clearly traces again to an official, pre-approved checklist or catalog.
Defend privateness: Take away or prohibit entry to any column that comprises delicate private or well being info, and have a human confirm that the safety measure is in place.
Method accuracy: Confirm that the mathematics and logic within the code precisely match the official permitted variations, making certain the generated code is exact somewhat than only a shut estimate.
Make clear labels and naming: Outline all labels and phrases clearly so the AI doesn’t confuse completely different metrics or ideas.
Carry out sensible testing: Run no less than one real-world take a look at for each main metric and confirm that the code produces appropriate outcomes on precise information earlier than finalizing it.
Official approval: Get hold of formal sign-off from the area house owners or information stewards, confirming that they agree with the ultimate definitions.
Make these necessities a compulsory code-approval guidelines so human-in-the-loop evaluate turns into an enforceable apply, not a buzzword.
From Deployment to Reply: Cortex Analyst and Brokers
As soon as the SAAS_BILLING semantic view is stay, it may be opened immediately in Cortex Analyst and queried in pure language. Cortex Analyst resolves TOTAL_MRR, teams by PLAN_TYPE, and generates SQL robotically with out human-written queries or metric redefinition.
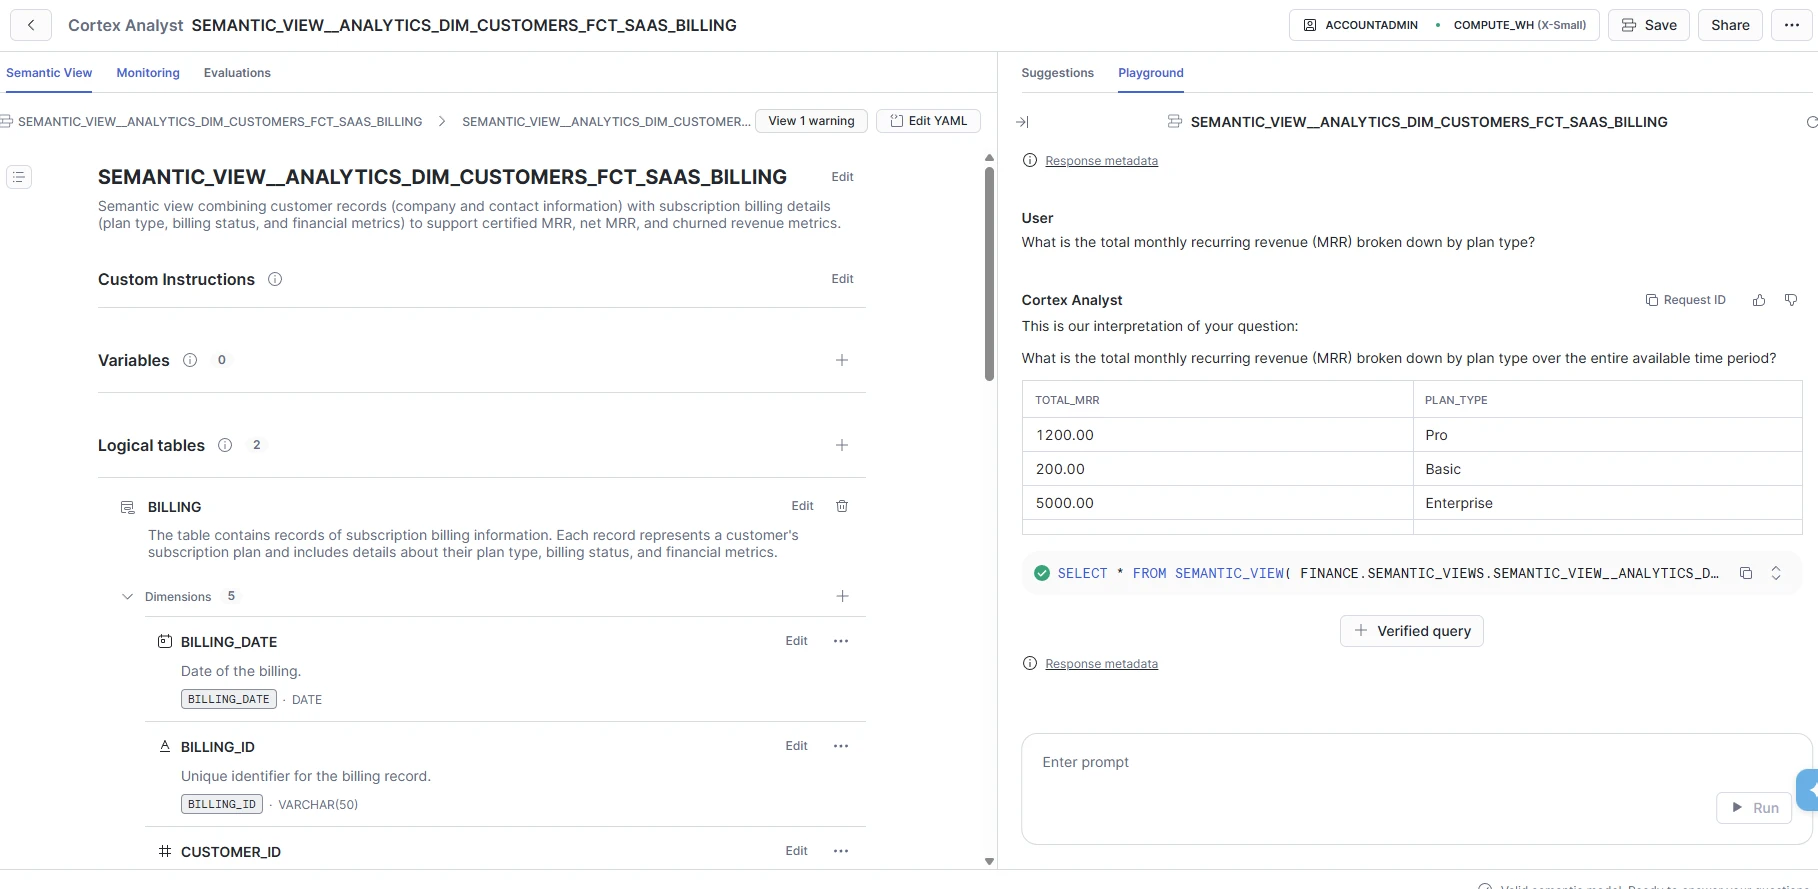
Cortex Analyst (Textual content-to-SQL)
From there, builders can construct a Cortex Agent that makes use of this semantic view as one among its instruments. They’ll connect a number of semantic views and supply orchestration directions that specify when the agent ought to use every one.
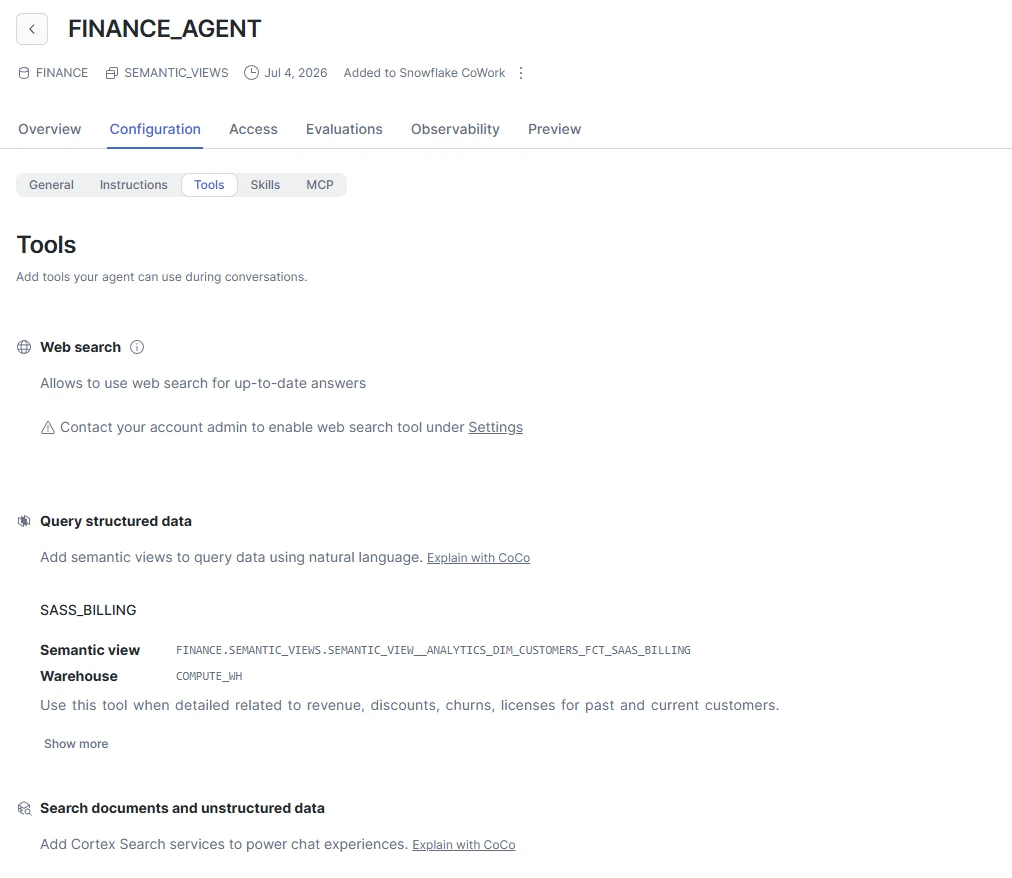
Cortex Agent
Previewed inside Snowflake CoWork (Previewed inside Snowflake Cowork) the agent presents a conversational, chat-style expertise,
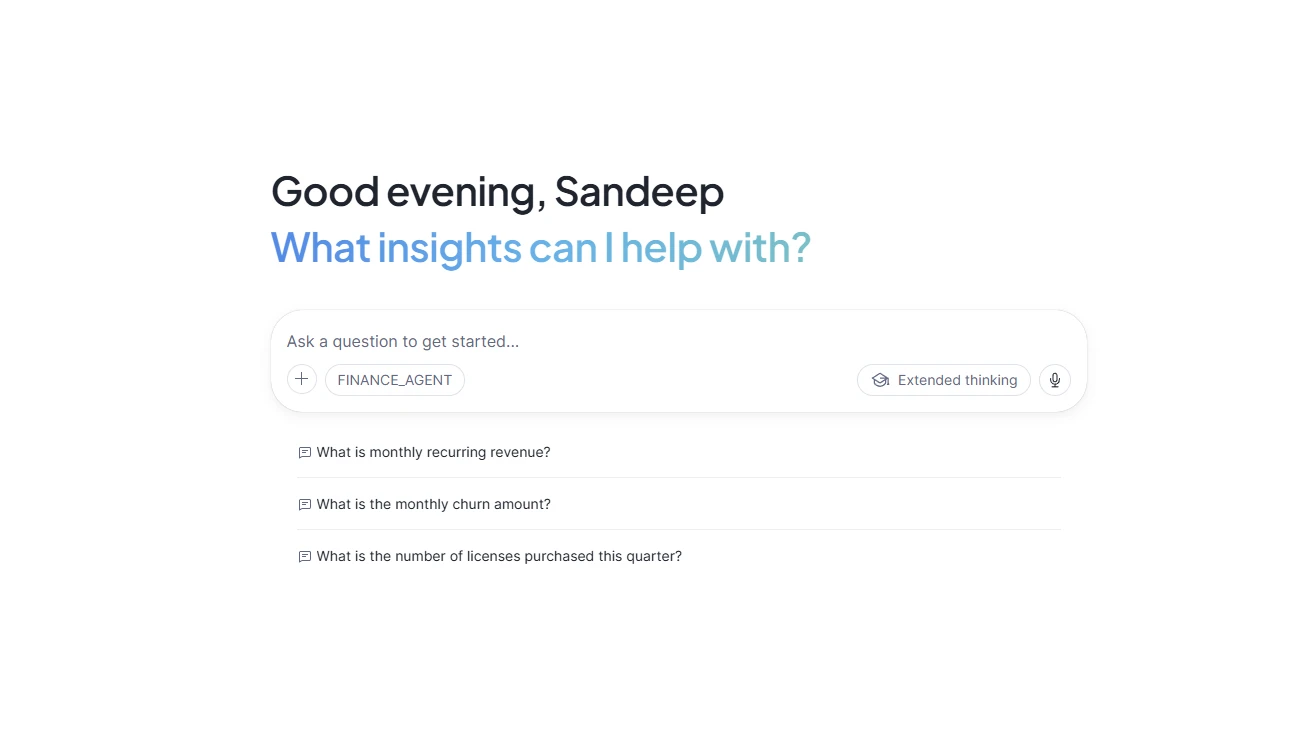
The next picture traces precisely what occurs between the consumer typing that query and the reply showing on display:
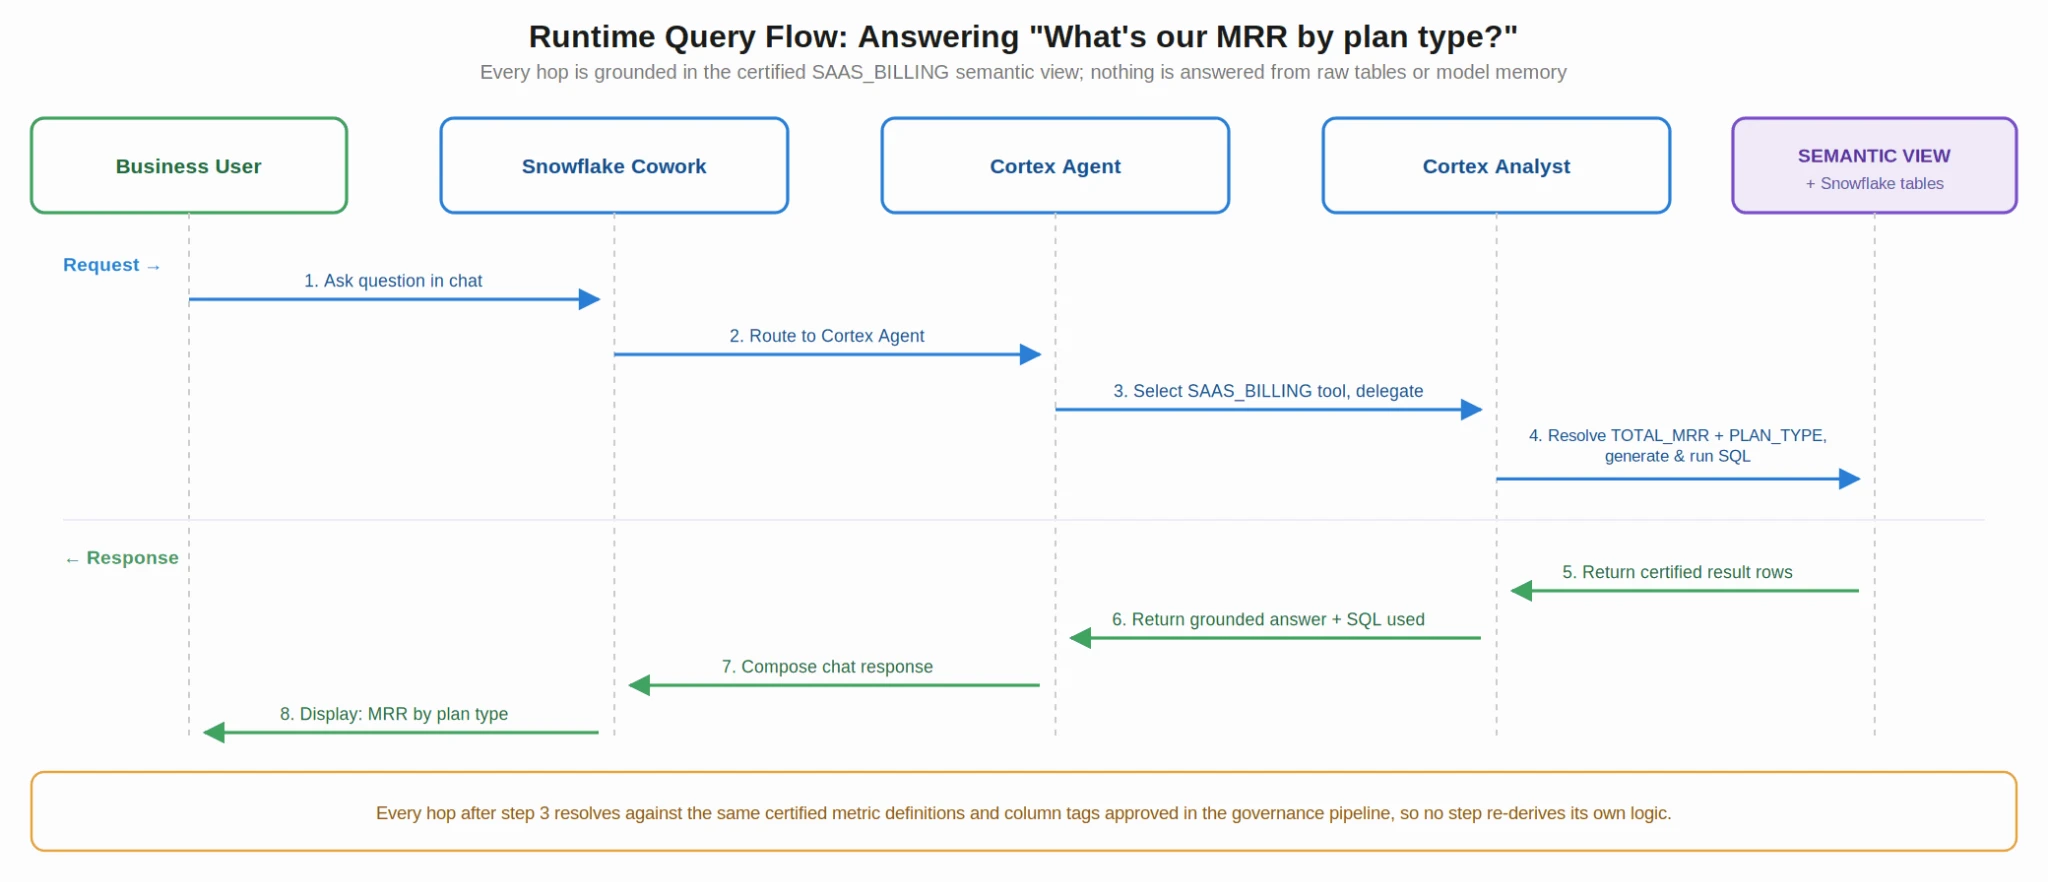
This chain grounds each reply in licensed metrics and column definitions that handed the Part 3 certification gate, not in model-generated logic. That’s the objective of the pipeline: earlier than a query reaches Cortex Analyst in Step 4, reviewers have already outlined, reviewed, and versioned the that means of “MRR” lengthy earlier than any consumer asks a query.
Conclusion
Agent high quality is essentially a governance drawback. A semantic view is barely as reliable as the method behind it, so organizations want certified-source extraction, constrained technology, human approval, and a whole CI/CD audit path earlier than deployment.
Deal with that course of as a regular in its personal proper, impartial of semantic-view authoring velocity. Including optionally available Apache Ossie export future-proofs licensed artifacts, whereas present BI-tool limitations present why portability nonetheless issues.
Learn extra: Unlocking Information Insights with Snowflake Cortex Analyst
Login to proceed studying and revel in expert-curated content material.
Maintain Studying for Free