


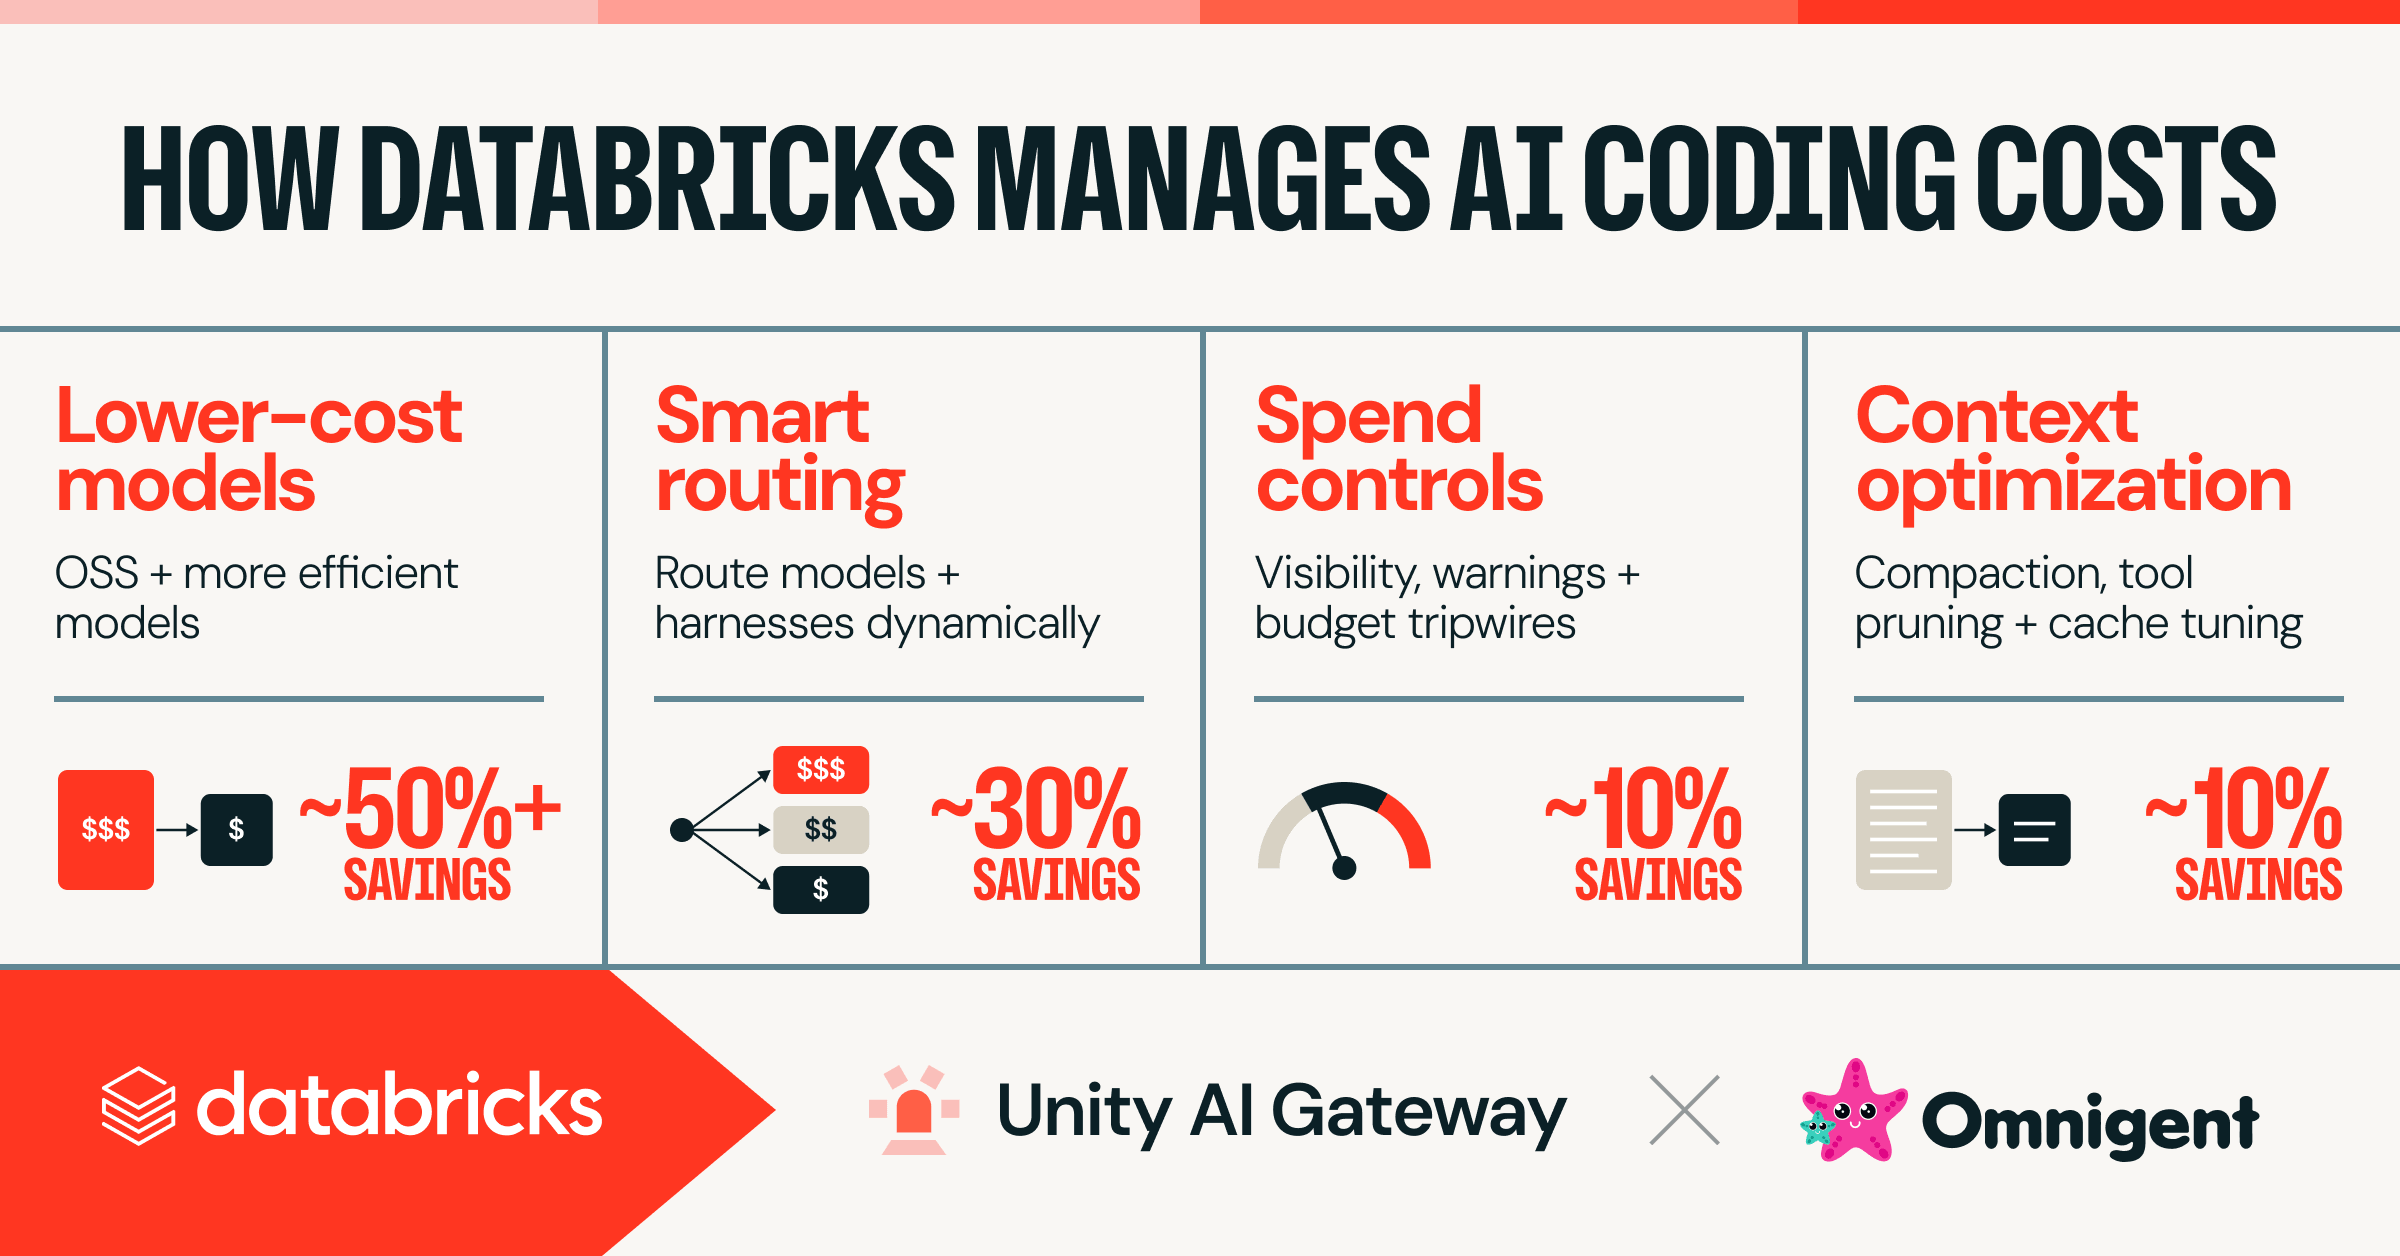
AI coding instruments ship immense worth: at Databricks, agentic coding has measurably improved each velocity metric we monitor and, in some groups, pushed an order-of-magnitude positive factors in output. However almost each firm deploying AI instruments at scale has hit the identical wall: exponentially rising prices. That curve is unsustainable – left unchecked it is going to ultimately overtake income. The spend explosion has left enterprises in a paradoxical state of affairs: on the one hand, wanting to maximally push AI transformation and put highly effective instruments within the arms of staff, and alternatively, having to reconcile with an combination value profile that threatens to undermine and even reverse the very effectivity positive factors AI supplies.
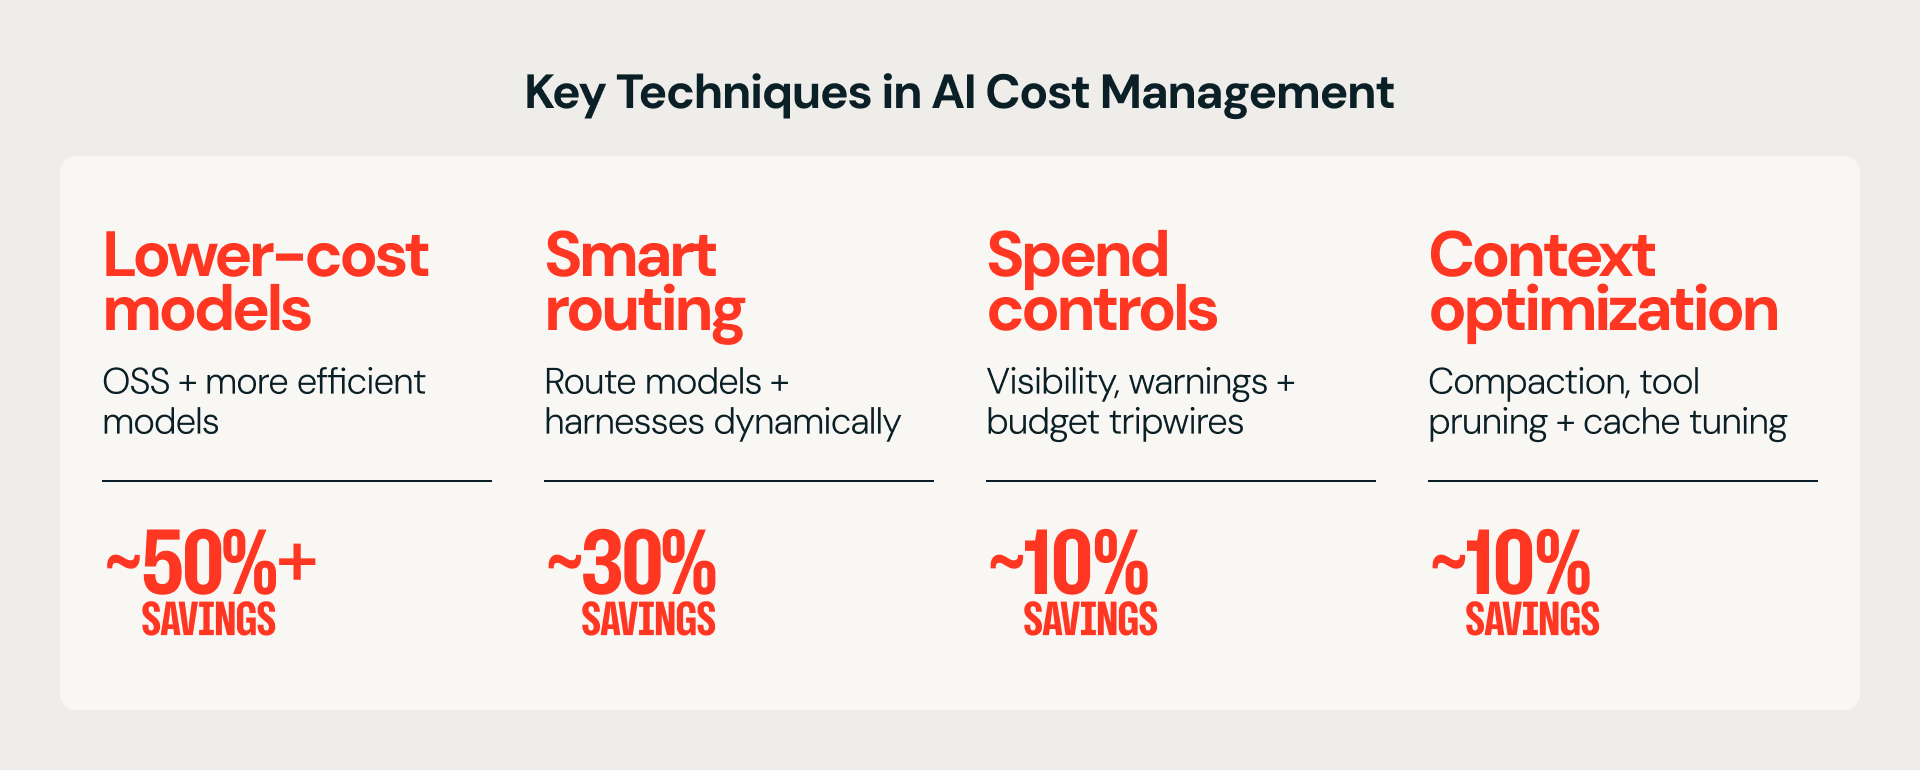
Thankfully, a number of of the earliest large-scale adopters have converged on a set of approaches that remedy this puzzle, reaching a “twin mandate”: (a) offering broad entry to AI tooling, with minimal friction, and (b) holding combination prices inside a roughly mounted envelope per person. This publish outlines confirmed value administration strategies, primarily based on our expertise at Databricks and conversations with a number of different digital-native firms, together with Stripe, Coinbase, Uber, and Ramp. The desk under summarizes present strategies and related financial savings; the numbers are directional, primarily based on an off-the-cuff survey of improvement groups:
A few of these strategies will be simply carried out with software program many firms already use. Others require new infrastructure, notably strategies that modify end-user shoppers or shift site visitors throughout fashions. At Databricks, we’ve open sourced or made freely out there our key infrastructure elements: an finish person meta-harness (Omnigent) and our AI Gateway (Unity AI Gateway). For completeness, this publish additionally covers software program utilized by different firms we spoke with.
The “Effectivity Frontier” for Coding Fashions
The only biggest value lever in transferring coding spend to extra environment friendly fashions as they’re launched. This level bears some dialogue, as the straightforward clarification of “cheaper fashions” actually hides a nuanced relationship between mannequin value and high quality.
Colloquially, the time period frontier mannequin means “the very best intelligence mannequin,” and frontier labs largely concentrate on advancing peak intelligence. Frontier fashions can now remedy novel issues in math or cybersecurity. However when AI is deployed at scale, a special kind of frontier issues extra: the effectivity frontier. The effectivity frontier is outlined by the set of fashions which have the most effective worth level for a given stage of intelligence. Most day-to-day coding does not require mathematical proofs or novel safety insights, so what issues in combination is the price of fashions that meet the standard bar for typical software program engineering work. This “effectivity frontier” is advancing far quicker than the intelligence frontier, with new fashions being launched nearly weekly that current higher intelligence-per-unit-price than prior fashions.
Price Lever #1: Transferring to open supply and decrease value fashions
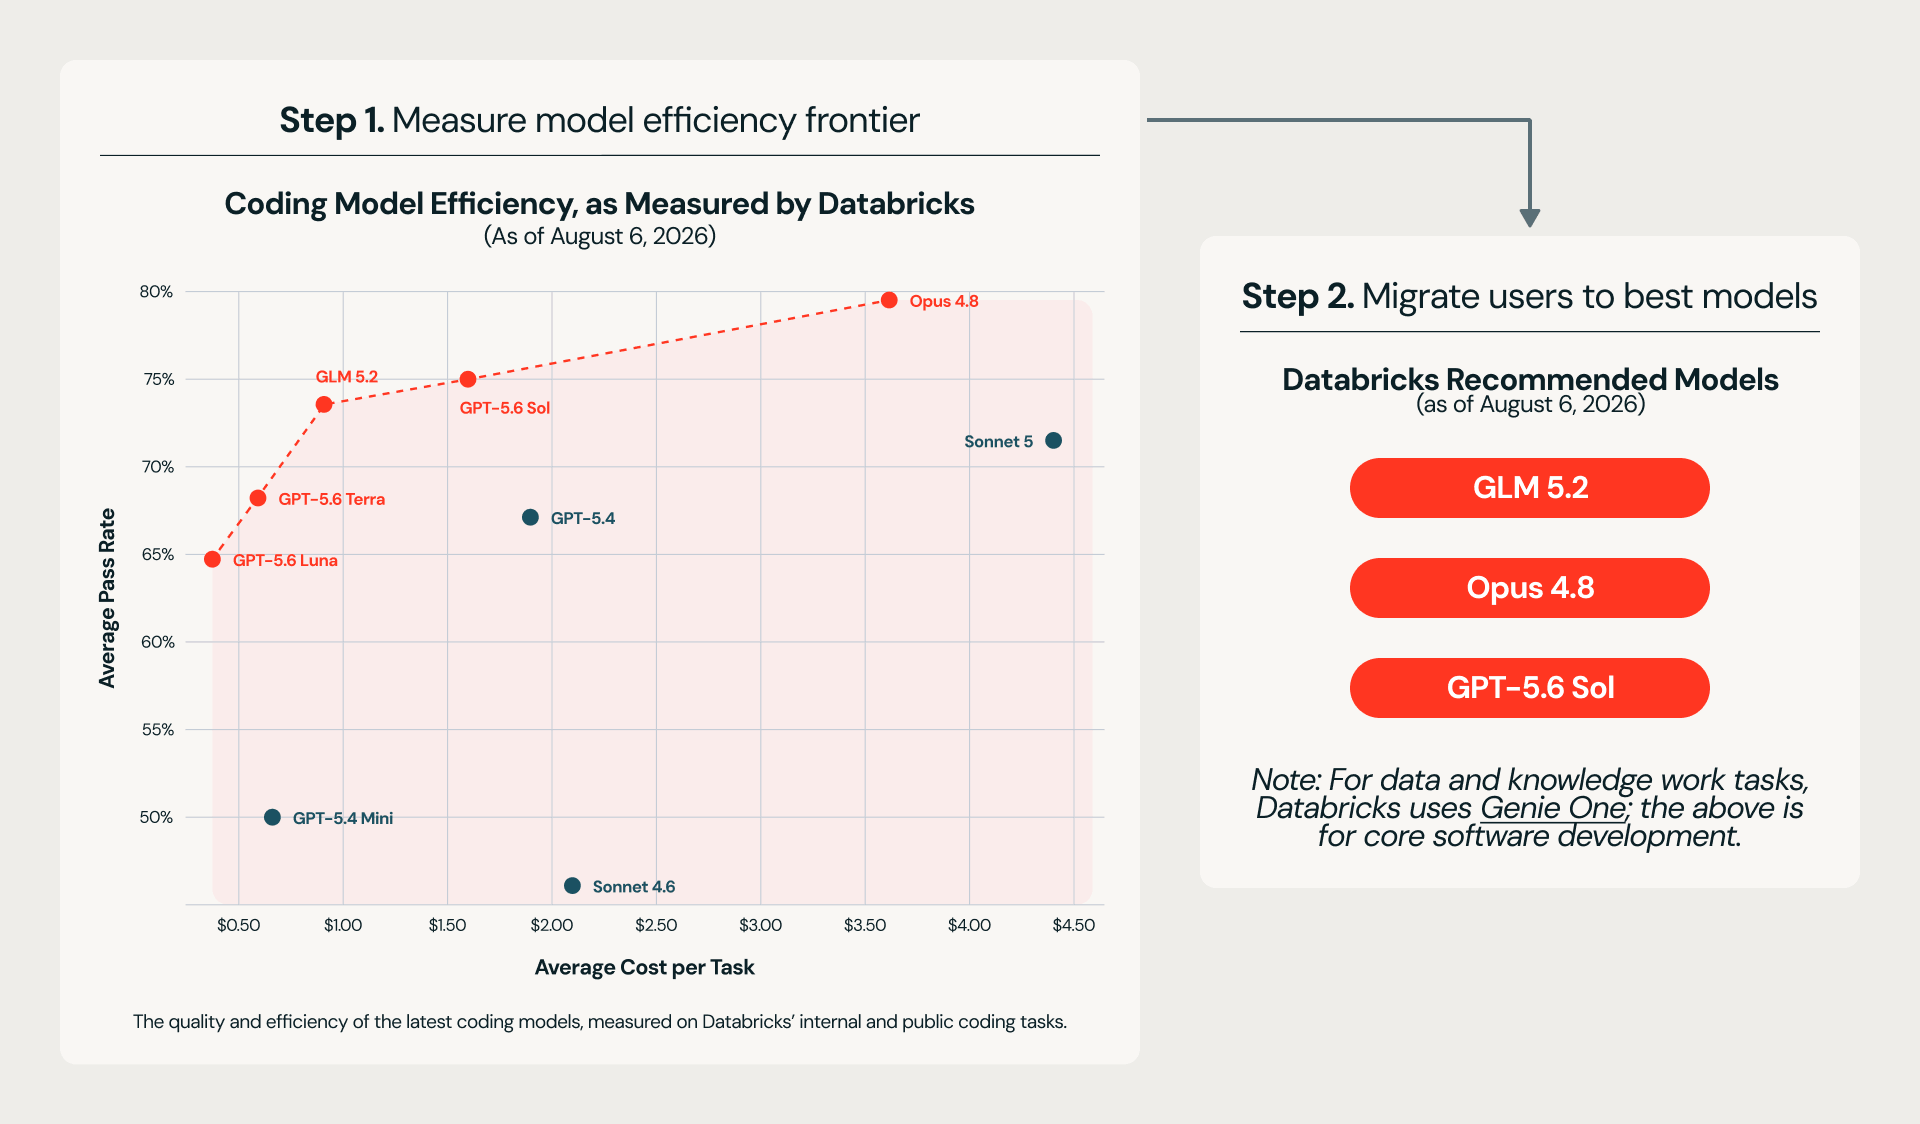
Quickly adopting newer, extra environment friendly fashions delivers the biggest value wins of any approach. However to seize these positive factors, an organization first must know which fashions truly beat its incumbents. This may be troublesome as a result of public benchmarks do a poor job of indicating real-world efficiency on coding duties. To dimension up new fashions, many firms have constructed automated evaluations that they imagine are extra consultant of their inside improvement combine. Databricks just lately revealed an instance of such a benchmark, by which we noticed extremely aggressive worth/efficiency for GLM fashions. That benchmark led us to roll GLM out to builders internally. Typically, new fashions don’t advance the effectivity frontier,and evaluations regularly produce unfavorable outcomes: Stripe discovered that Opus 4.7 didn’t meaningfully enhance high quality over Opus 4.6, whereas rising value. They due to this fact declined to make Opus 4.7 out there internally. Databricks noticed related value regressions when evaluating Opus 5.0 to 4.8.
Harness and Mannequin Flexibility
For the reason that largest wins come from switching to new fashions, adopting finish person tooling that enables for mannequin flexibility is changing into a important element of holding prices down. The device mostly utilized in concern with a selected mannequin is known as harness. Proprietary frontier fashions are more and more co-designed to work effectively with particular harnesses, which means sure harnesses “work higher” with sure fashions. If an organization needs to protect mannequin independence there are roughly two approaches:
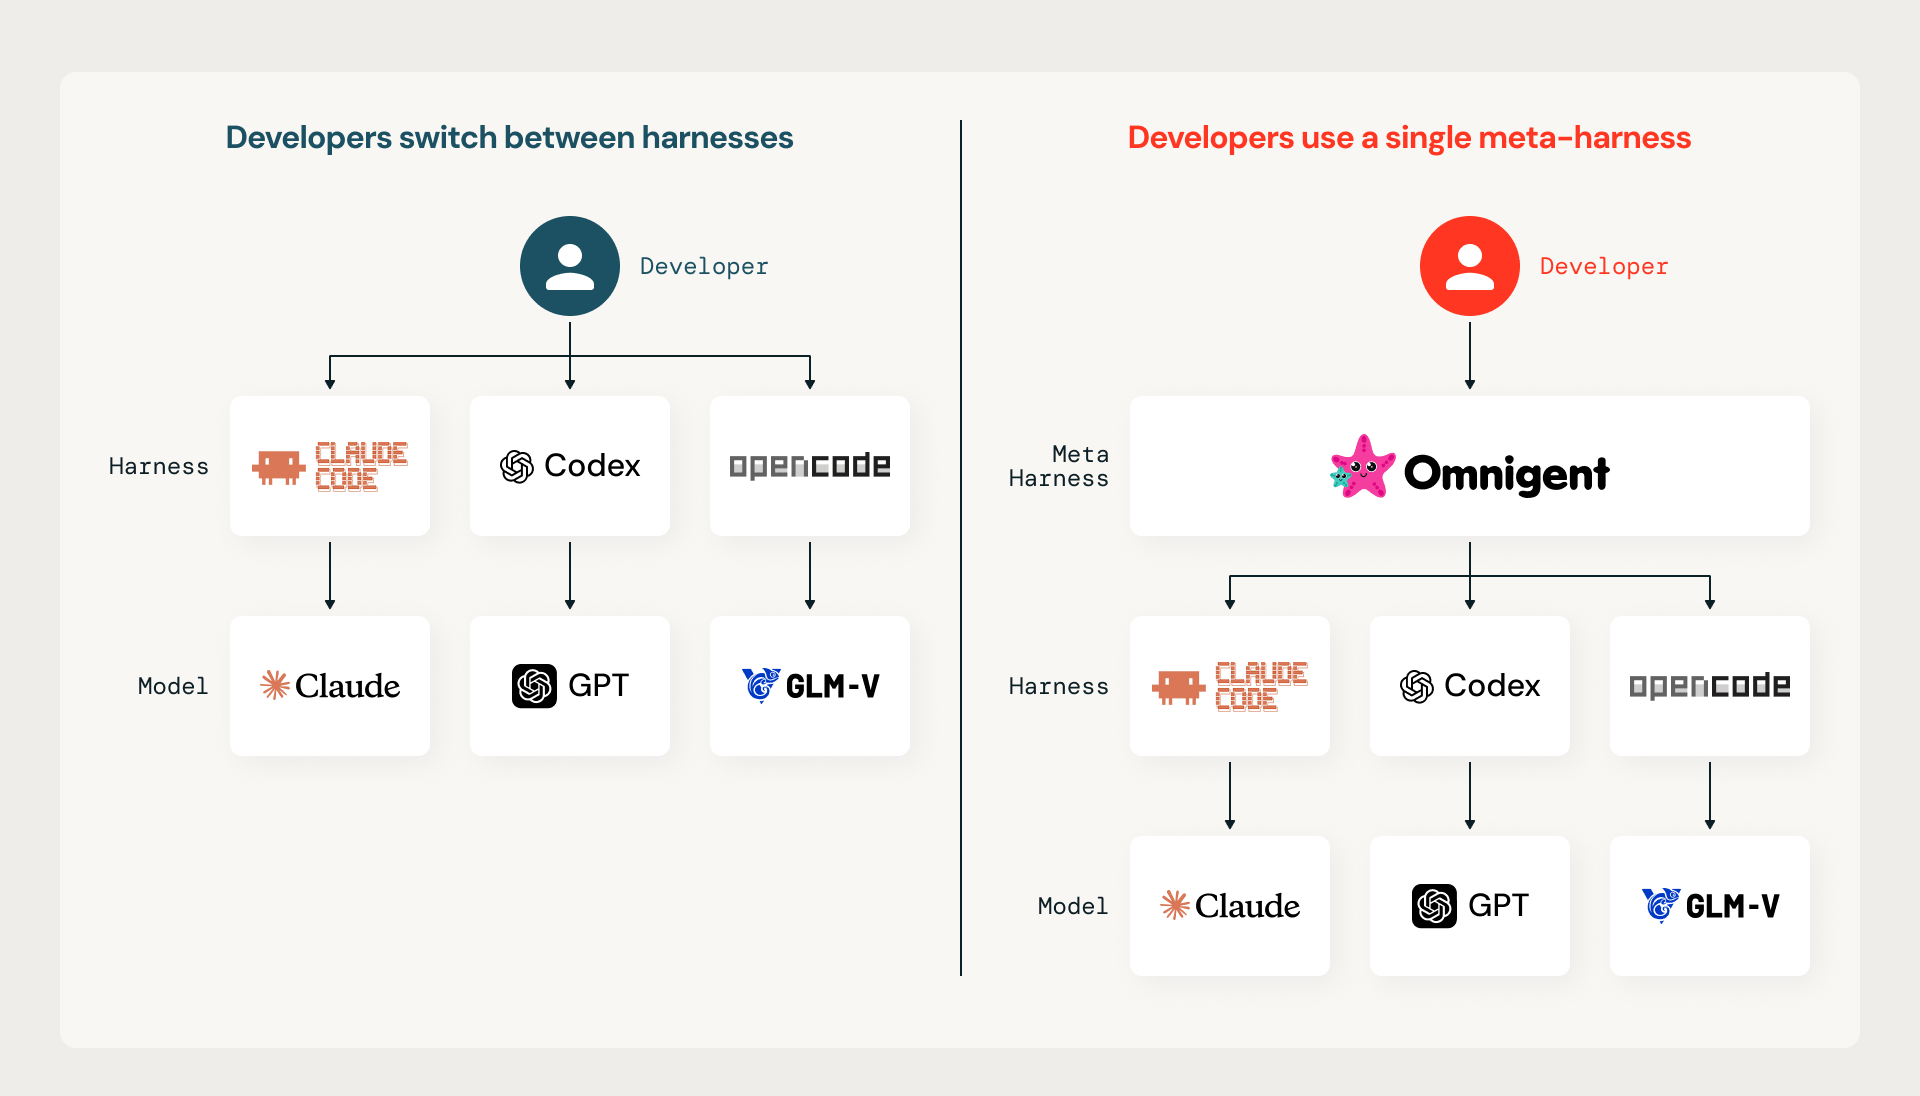
Ask customers to modify harnesses. One strategy is to supply builders with a set of harnesses (Claude Code, Codex, or Cursor) after which ask them to modify between harnesses when an organization needs emigrate spend to decrease value fashions. This lets customers work of their most well-liked harness when potential, however the draw back of this strategy is that switching prices for a person developer will be excessive. If switching prices turn out to be too excessive, the harness itself turns into a de facto lock-in to a mannequin household, limiting the power to maneuver spend to extra aggressive fashions.
Use a meta-harness. A brand new and more and more well-liked strategy is to make use of a meta-harness that surfaces a standard person expertise to builders whereas dispatching requests to underlying harnesses (each proprietary and open supply). This strategy permits each mannequin/harness independence whereas additionally lowering developer switching prices. At Databricks, that is the default mode for builders who leverage Omnigent. Some firms we talked to have constructed customized inside meta-harnesses that combine with their improvement toolchain.
Price Lever #2: Dynamic Request and Job Routing
As an alternative of asking customers to decide on task-appropriate fashions themselves, a rising physique of analysis means that automated mannequin and power choice might additional squeeze effectivity out of agentic coding workflows. Routing approaches roughly fall into three classes:
Request Stage Routing: A stateful proxy sits in between a shopper (akin to a coding harness) and the underlying basis fashions. The proxy makes an attempt to route requests to the lowest-cost mannequin able to answering every inference request. Routing for agentic use instances additionally must account for server-side caching, since a chilly cache hit has a really excessive value for big context workloads. A brand new wave of merchandise is exhibiting early, promising outcomes for routing. Examples are: Cursor Router, OpenRouter’s AutoRouter, Ramps Router function and Databricks personal Sensible Routing function in Unity AI Gateway.Job Stage Routing (Meta Harness): A client-side course of dispatches person duties to totally different harnesses primarily based on the complexity of the duty. A person activity may be “rename this element from X to Y” (a easy activity) or an open-ended activity like “Discover design issues that would scale back latency” (a fancy activity). The dispatcher, usually referred to as a Meta Harness, examines which stage of underlying mannequin is required for a activity after which delegates that total end-to-end activity to the mannequin. Omnigent is an instance of a Meta Harness that helps this sample.Escalation/Delegation Patterns: A single harness pairs two fashions (an costly, high-intelligence mannequin and an affordable employee mannequin). In some approaches, akin to Claude’s Advisor Instrument, the cheaper mannequin runs the present and escalates when it thinks a activity requires extra horsepower. The inverse sample additionally exists: In Cognition’s Devin Fusion, the upper value mannequin is the primary loop, and it selectively outsources work to a less expensive mannequin.Inside outcomes at Databricks counsel that our AI Gateway Sensible Router is ready to constantly cut back common activity value by greater than 30%, whereas roughly matching the standard of the most costly mannequin within the working set. Different firms we spoke with have seen related outcomes.

Price Lever #3: Giving builders visibility, tripwires, and budgets
It could be stunning that this complete article didn’t begin and finish with “Give customers a month-to-month price range and be finished with it.” Laborious budgets, the place utilization is completely lower off at a particular spend threshold, are sometimes used solely as a final resort possibility in each firm we spoke with. There are two causes that onerous token budgets aren’t notably efficient for AI spend administration: First, if a developer hits their price range ceiling, chopping off additional entry to AI instruments could be debilitating to productiveness. Neither the corporate or worker truly needs that consequence. Second, a minimum of a number of the “excessive spending” customers are actually those that have achieved monumental effectivity positive factors with AI and are producing immense output. Discouraging these customers is self-defeating.
As an alternative of a tough person spending cap, most firms are adopting a extra nuanced and progressive strategy that focuses on visibility for finish customers and elevated levels of friction as spend will increase.
Visibility: Each firm we spoke with had a mechanism to supply near-instantaneous suggestions to customers on their ongoing spend, with many additionally providing particular ideas or insights on how one can cut back spend through the use of inexpensive fashions. It is necessary that customers be capable of see their spend throughout all instruments, since they could need to affect their alternative of device the place they get the very best ROI.
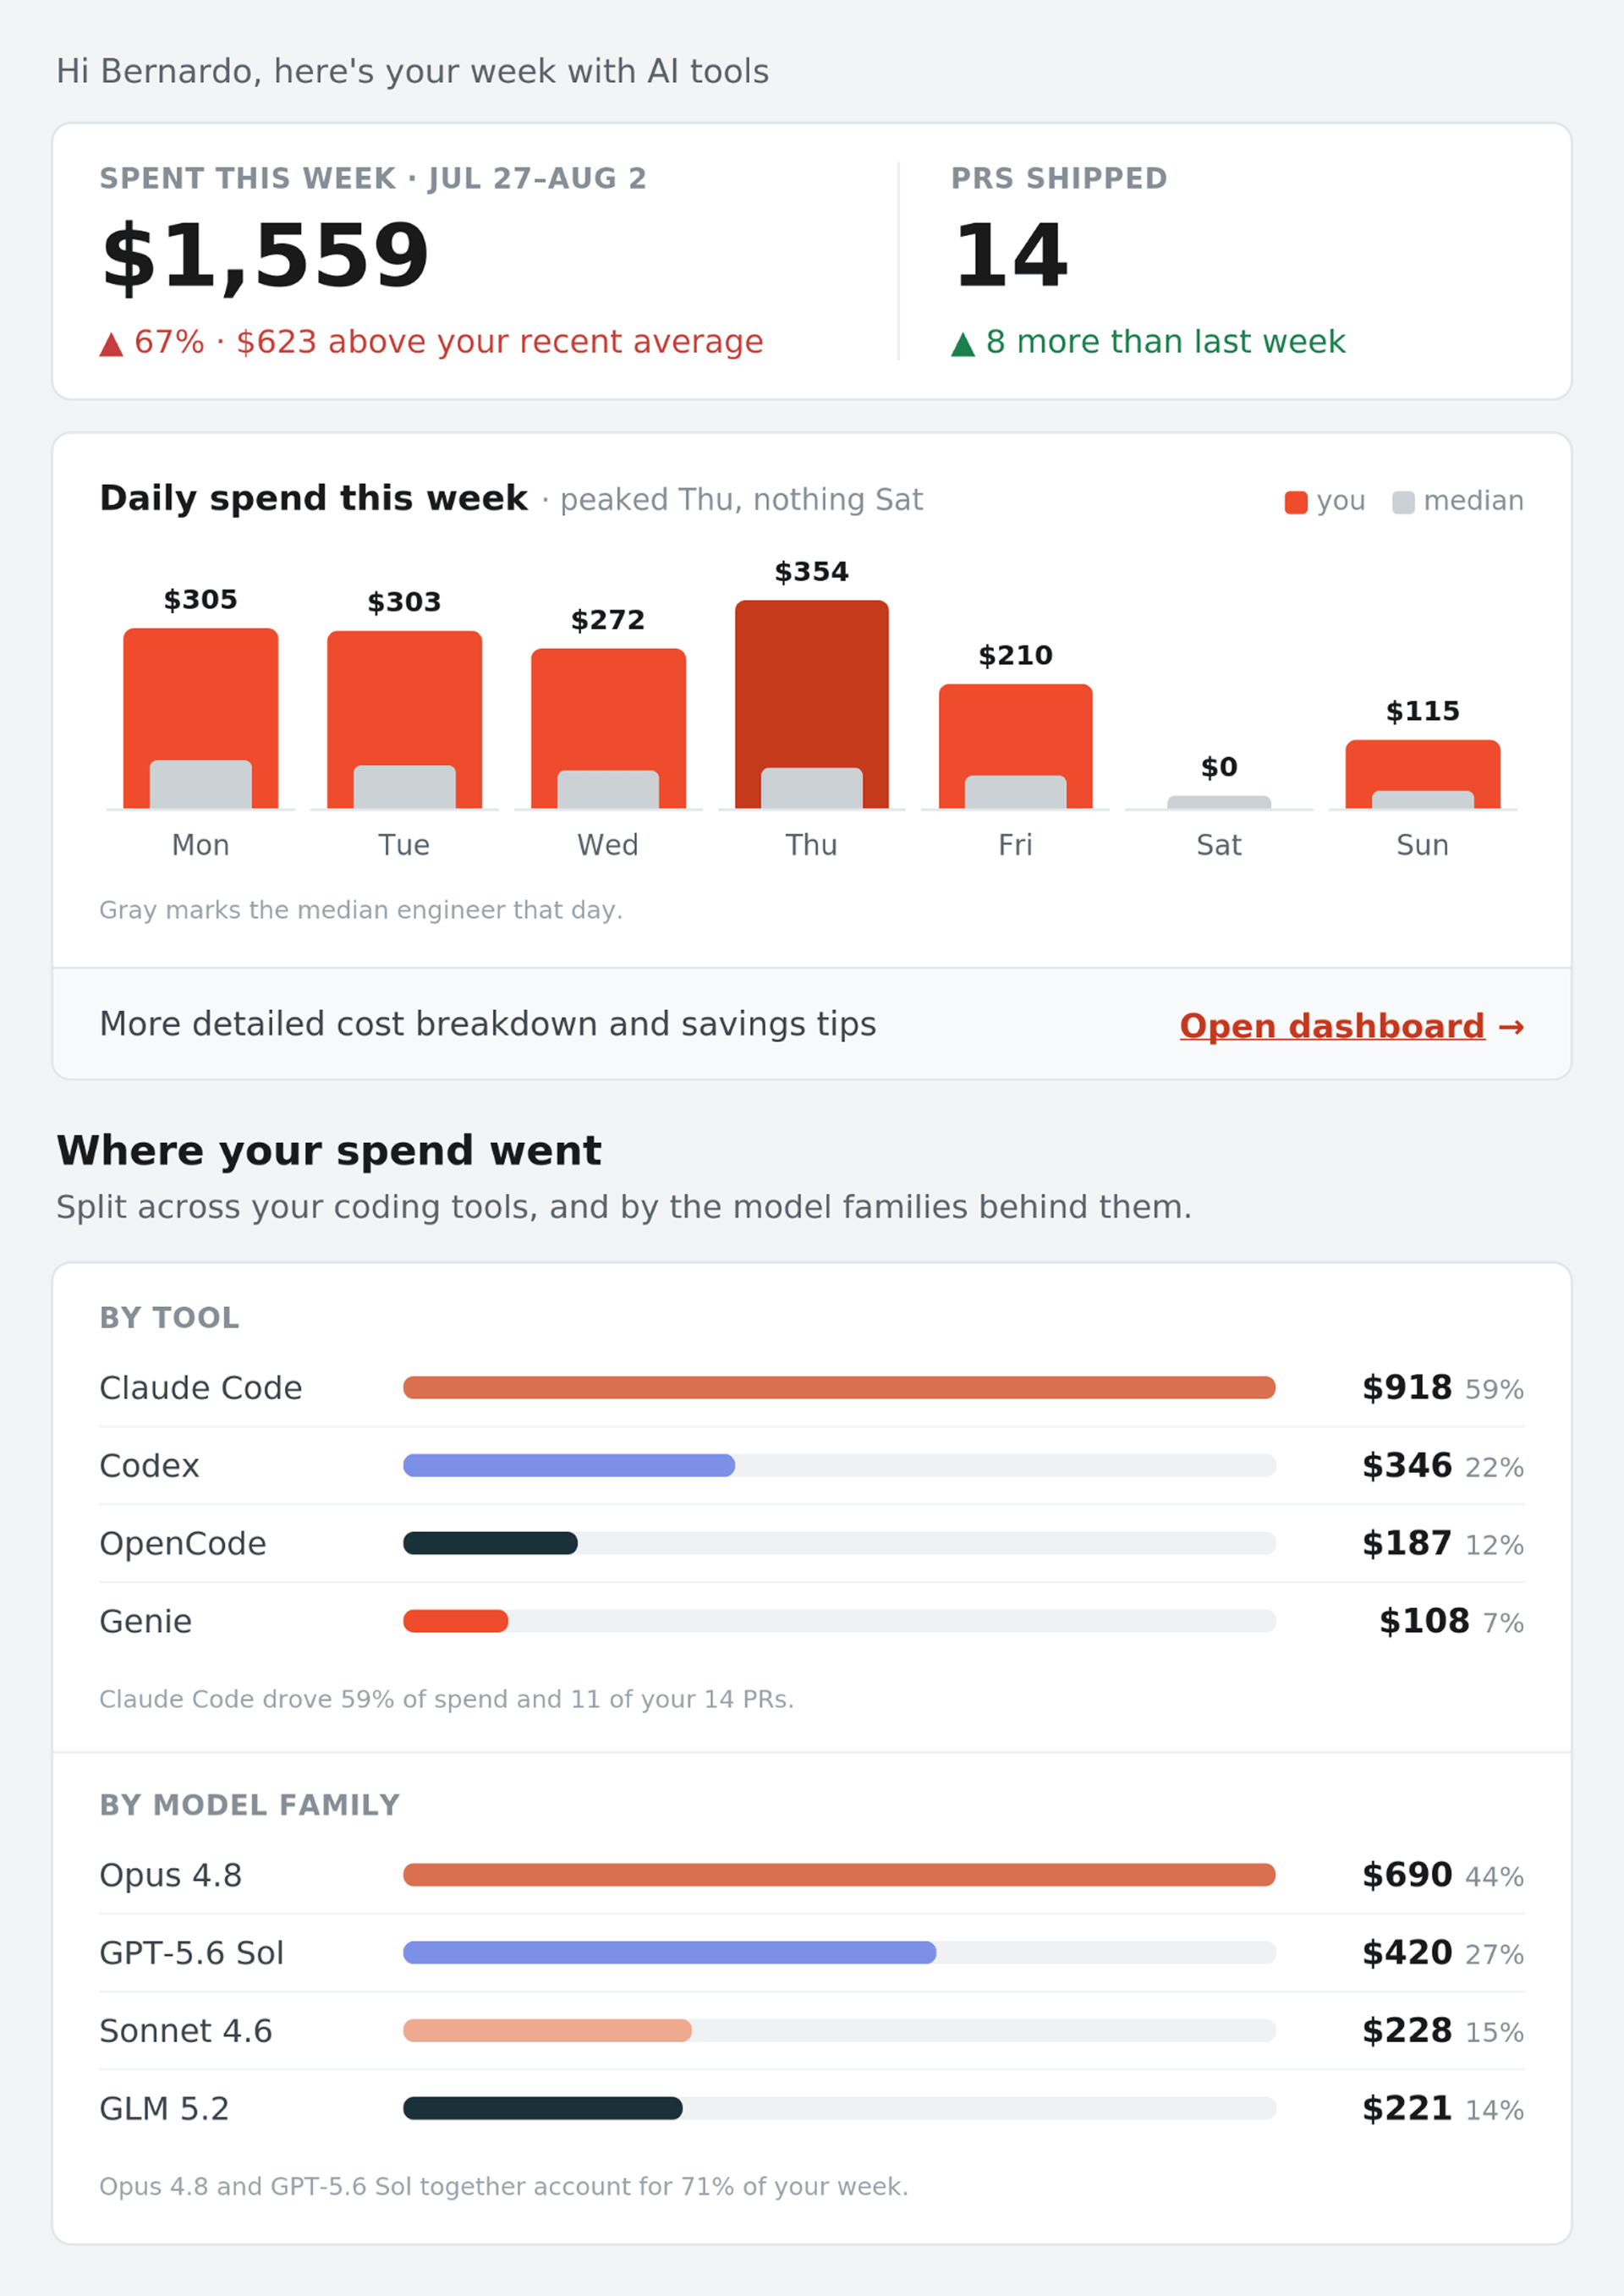
A developer dashboard at Databricks exhibiting lively spend
Spend Gates: Builders will be requested to take actions or search approvals at rising ranges of spend. The best type of spend gate is one that may be self-cleared and serves as a warning that the spend fee is rising above some threshold. At Databricks, we’ve discovered self-clearing gates a helpful mechanism for stopping unintended or unintentional spend. Additional gates will be launched that require express price range approval (usually via a administration chain).Downshifting: If a developer has hit a spend gate, they are often downshifted to a lower-cost mannequin reasonably than being completely suspended from token entry. For the reason that lowest-cost fashions are drastically inexpensive than frontier-intelligence fashions, this method permits builders to proceed getting work finished with out incurring huge ongoing spend.Suspension: Within the restrict case, most programs do retain the power to completely droop customers from all token entry. As said above, that is usually a short lived measure solely and the place to begin for a dialog about how one can effectively leverage AI.
Price Lever #4: Lowering Token Overhead
When a person varieties a comparatively easy request into an AI coding agent (akin to “Please examine and repair this bug.”), that agent subsequently gathers huge quantities of related context, invokes numerous instruments, searches via the codebase, and integrates expertise or system info supplied by the corporate. By the point expensive LLM inference happens, the person’s preliminary assertion accounts for less than a negligible fraction of the information fed into the AI system, which means prices are dominated by context the person didn’t explicitly embrace. Strategies in lowering context bloat are nonetheless new, however a number of promising approaches are being explored, akin to:
Coercing extra frequent compaction (compression) of the lively context.Utilizing harnesses which can be “much less chatty” (extra token environment friendly), or tuning present harnesses to generate much less token overhead.Auditing well-liked instruments and lowering their verbosity.Encouraging builders to interrupt duties into smaller particular person items of labor, lowering context scope.
When contexts get giant, immediate caching additionally performs a significant function in total efficiency. Each proprietary and open supply LLMs have settings that will let you allow immediate caching and tune how lengthy the cache is saved. Cache writes value cash, however cached reads can drastically cut back per-inference value. This trade-off depends on an organization’s particular workload, so hand-tuning of default cache settings to extend total cache hit fee can have drastic enhancements to total value.
At Databricks, comparatively easy tuning of our harness and caching settings led to an nearly 50% discount within the variety of generated tokens and related prices, with no noticed high quality degradation for builders. We proceed to discover strategies on this space and suppose significant extra optimization stays potential.
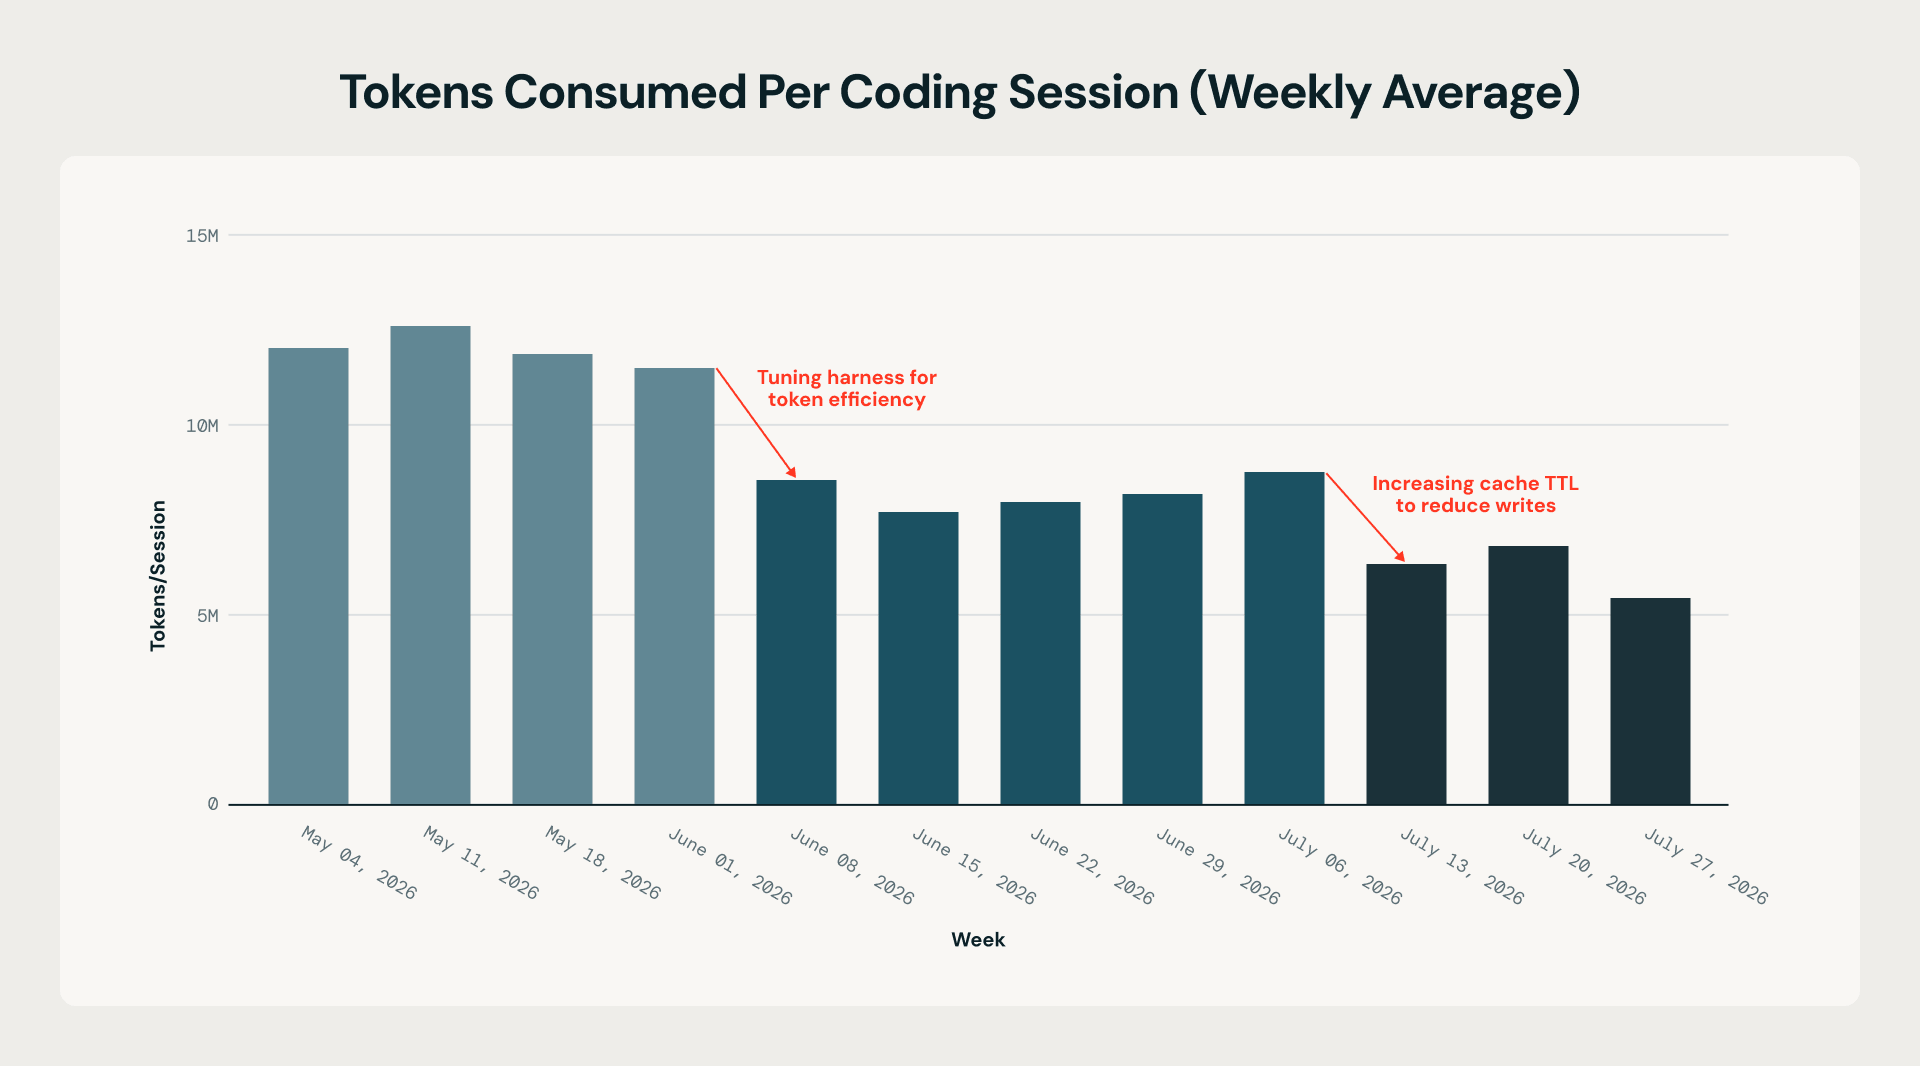
A drastic discount in tokens per session by eliminating extraneous inference calls and lowering cache writes.
The AI Gateway design sample
The strategies above had many implicit technical necessities: To quickly make the most of new fashions, firms should have a central location the place the “mannequin menu” is managed, and end-users should have a toolchain that helps mannequin mixing. To supply price range visibility throughout a number of AI instruments, a unified value observability functionality should exist. To handle context bloat, firms want a solution to observe typical toolcall outputs and implement compression or compaction. These wants are collectively being solved by a brand new class of infrastructure software program, finest described as an AI Gateway. An AI gateway is a central location the place all the following happen:
Capability administration and proxying of entry to underlying fashions (each proprietary and OSS fashions).Finances monitoring and enforcement, together with advanced price range insurance policies akin to progressive friction ranges and mannequin downshifting.Configuration administration for end-user instruments, to implement mannequin allow-lists, compaction settings, and different regionally mediated points.Logging of coding session traces for downstream effectivity evaluation and benchmark.
At Databricks, we rely closely on Unity AI Gateway for all of those capabilities.
Placing all of it collectively
The exponential development of AI coding prices will not be an inevitability, it is a solvable engineering and governance downside. Corporations which have tamed it share a standard playbook: relentlessly chase the effectivity frontier reasonably than the intelligence frontier, undertake tooling that preserves mannequin flexibility, route work intelligently to the most affordable succesful mannequin, exchange exhausting budgets with visibility and progressive friction, and lower the token overhead that dominates real-world spend. None of those strategies requires sacrificing the productiveness positive factors that made AI adoption worthwhile within the first place; collectively, they let organizations fulfill the twin mandate of broad, low-friction entry inside a predictable value envelope.
A set of recent infrastructure abstractions is rising to present firms the instruments to handle their prices. At Databricks, we’ve launched the important thing elements in our value administration stack as open supply or free software program merchandise: Our Unity AI Gateway for central administration and Omnigent for developer tooling. Hundreds of firms use these elements day-after-day. We invite extra firms to share findings and examine strategies as this know-how panorama quickly evolves.
Acknowledgements: Thanks to infrastructure leaders at Uber, Stripe, Coinbase, and Ramp who supplied commentary and critiques of this text. Thanks to Thrive Capital for suggestions on an early draft of this text.

