



and its system card. The choices that made it good keep in-house: the way it was skilled, what its reinforcement studying ran in opposition to, how they bought it low-cost sufficient to serve. That’s the traditional take care of a frontier lab, and most exterior writing about these methods has to work from the outputs alone.
Kimi K3 is the exception price studying. It’s open, it sits near one of the best closed fashions on most benchmarks, and Moonshot printed a forty-seven technical report that walks via the components different labs preserve personal. I learn it over a day. What stayed with me is how small a share of the work is the mannequin itself.
One caveat up entrance. The whole lot particular under is Moonshot’s. I assume the closed labs do their very own variations of the identical classes of labor, however I’m inferring that from the skin, so learn the broader “that is what the frontier seems like” claims as a guess.
The structure is a stack of small adjustments
The structure is the plain place to begin, and it holds the fewest surprises. K3 is a 2.8-trillion-parameter mixture-of-experts mannequin, and what lifts it during the last Kimi is three pretty strange engineering adjustments stacked collectively.
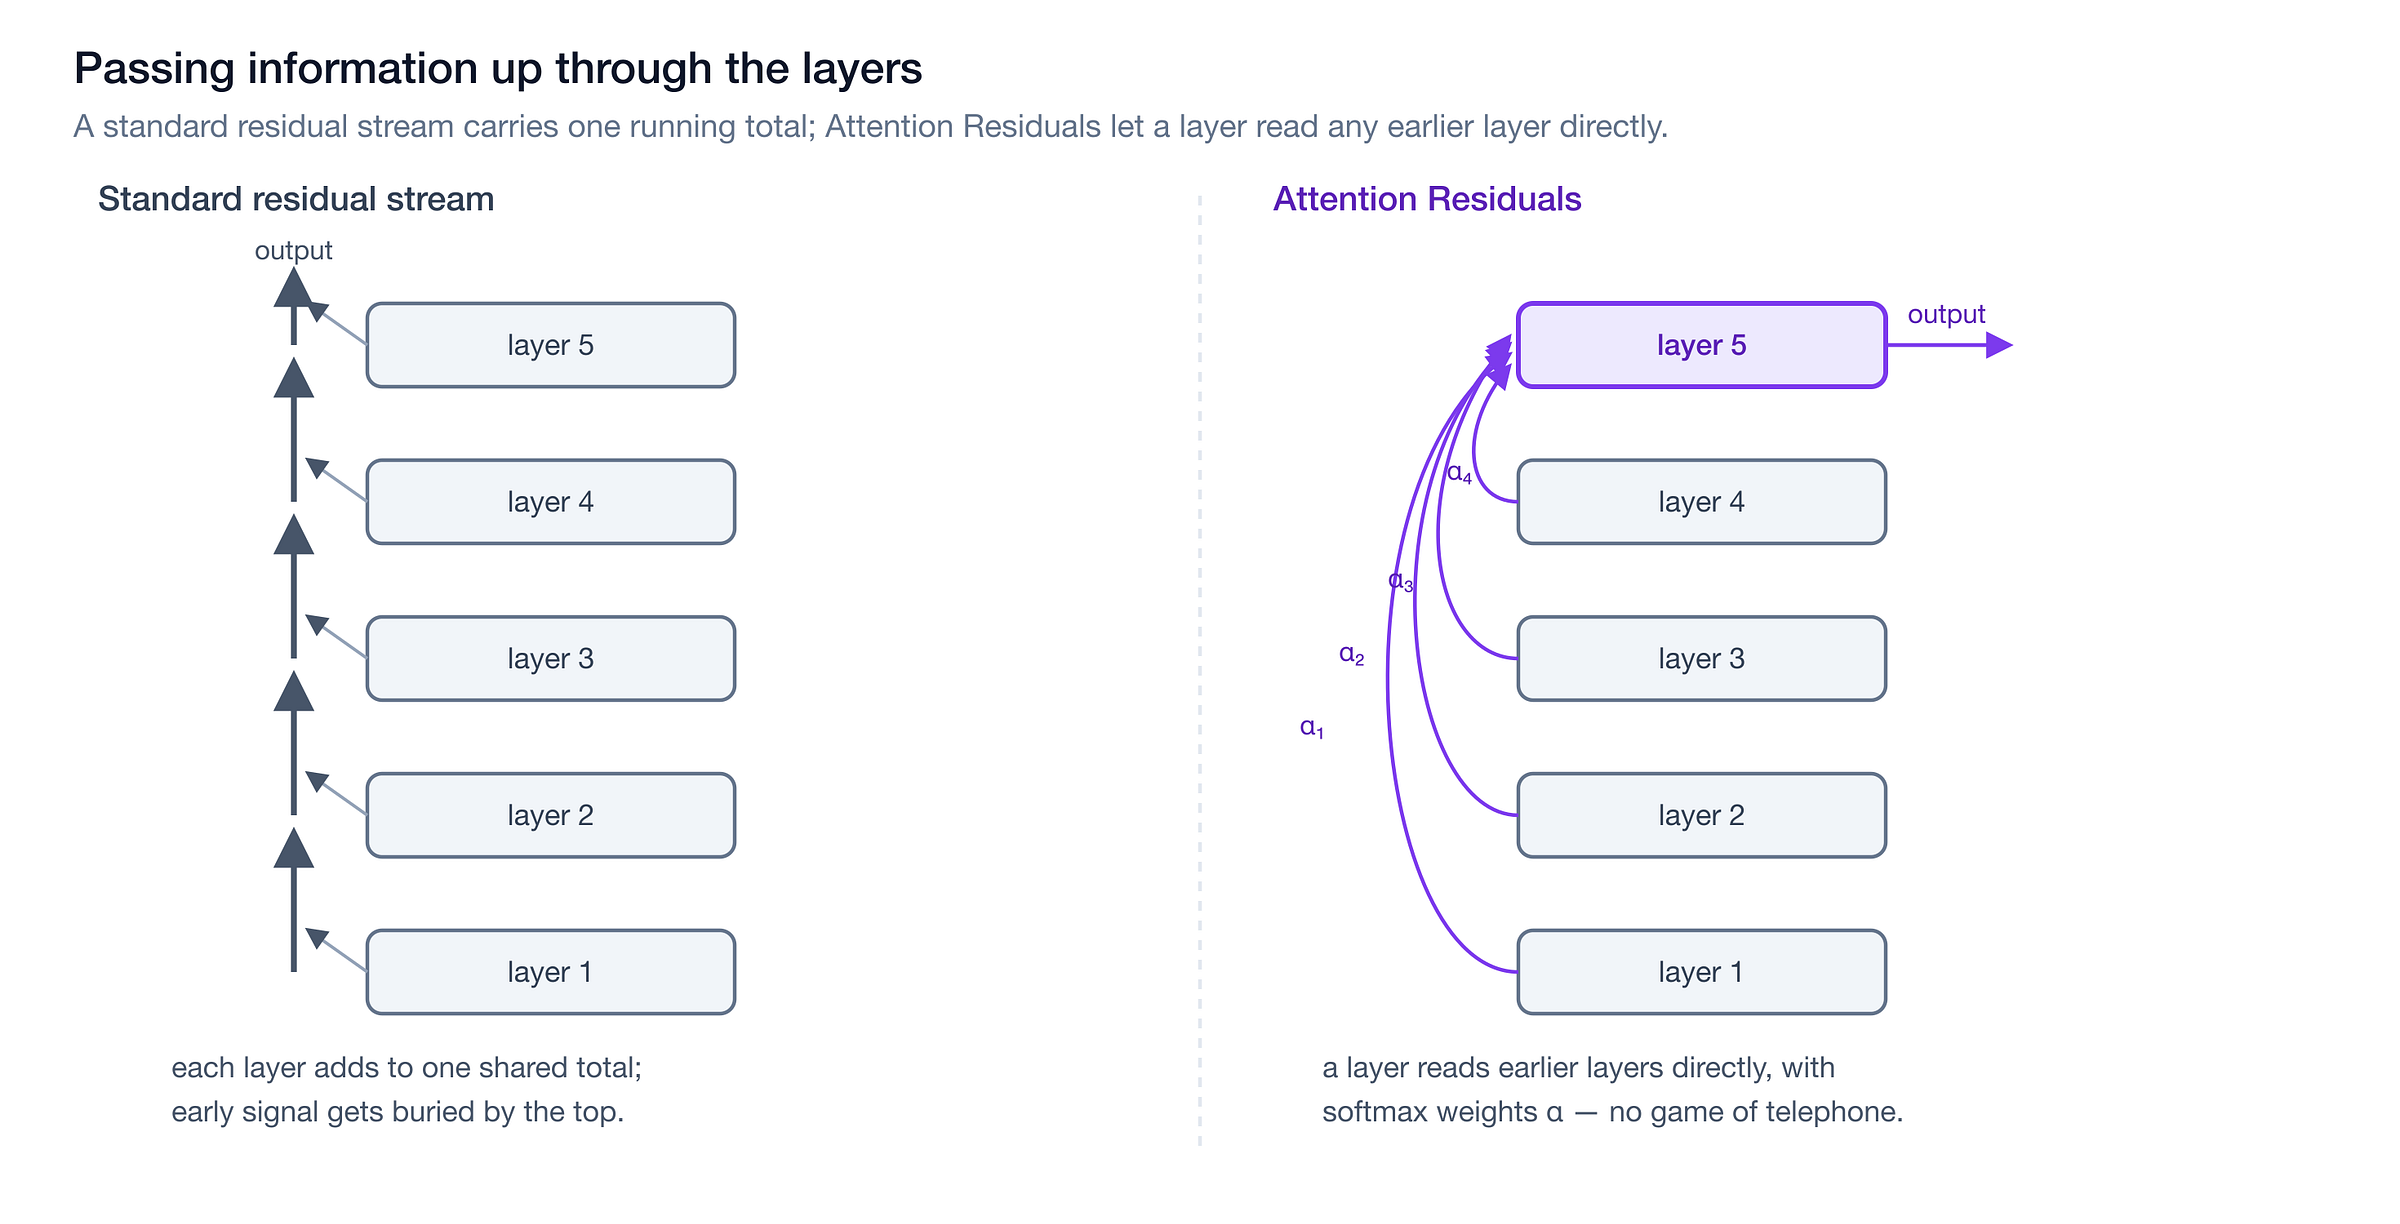
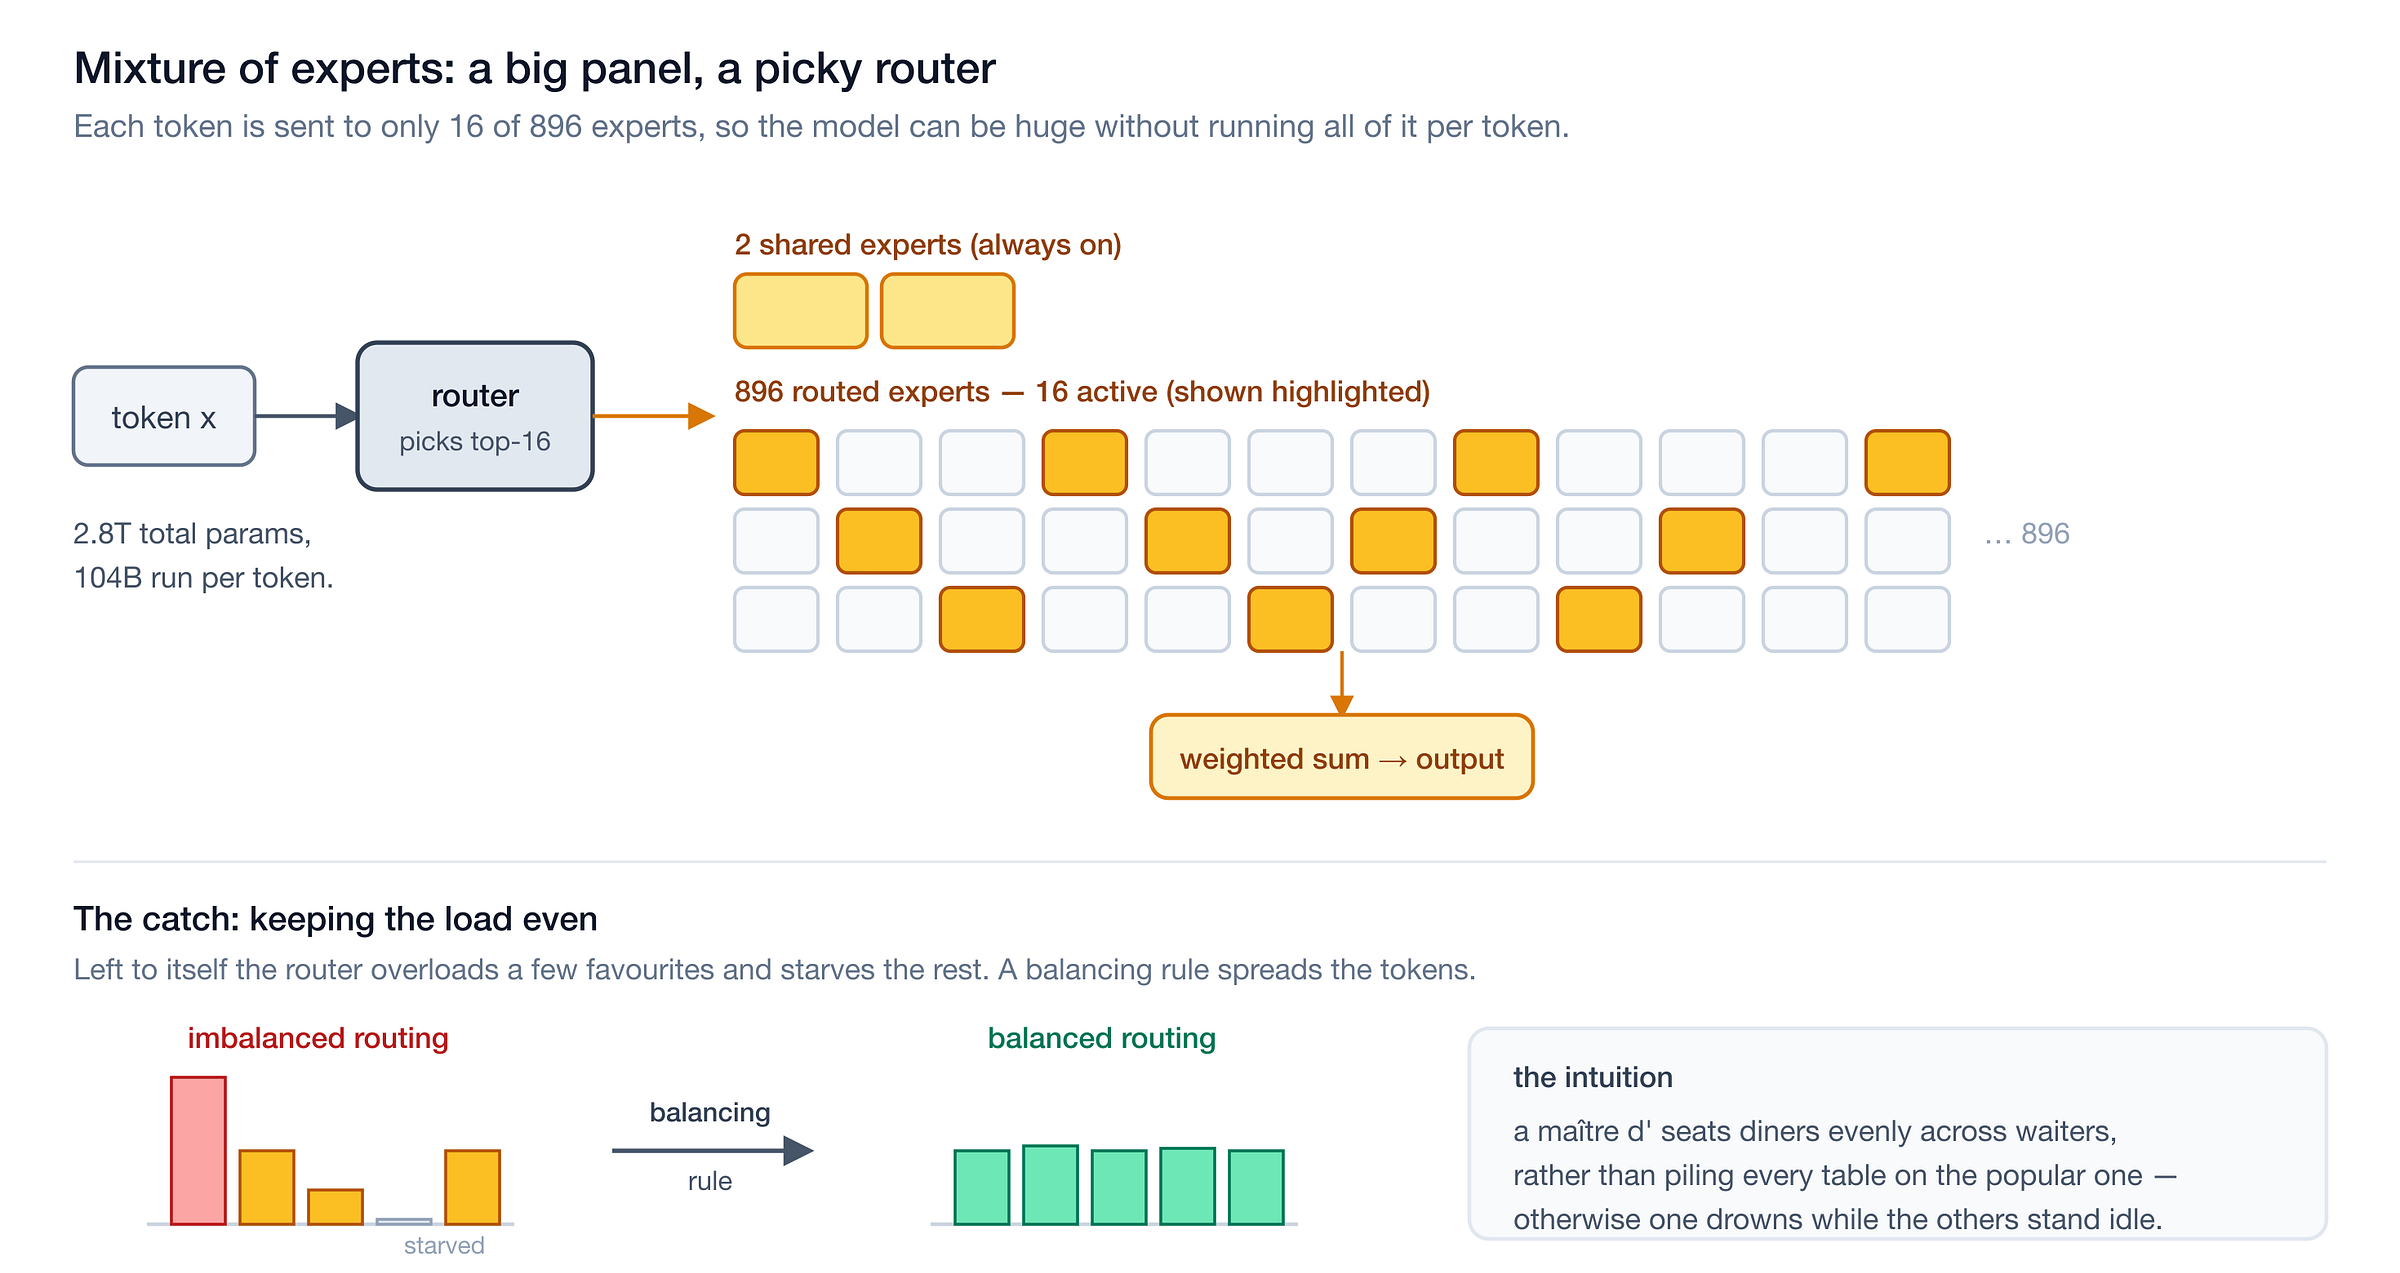
The eye retains a fixed-size operating state as a substitute of a cache that grows with the enter, which is what makes a million-token context reasonably priced; most layers use that low-cost model, and each fourth does full consideration. Positions aren’t encoded explicitly, so the recurrence has to hold them, which lets the mannequin stretch to one million tokens with out the same old rescaling hacks. Every layer can even look again at each layer beneath it, not solely the one straight under, so early sign doesn’t wash out on the way in which up. And every token is routed to 16 of 896 specialists, sparser than earlier than, which takes actual care to maintain steady.
Moonshot stories a 2.5× acquire in scaling effectivity over Kimi K2, roughly the identical high quality for beneath half the coaching compute. It credit the structure along with refined information and coaching recipes, with out apportioning the acquire between them, so don’t learn the two.5× as three structure adjustments multiplying out. Each bit is an strange, well-tested concept somewhat than a single breakthrough.
The three adjustments in plain English
Every of the three is straightforward to carry in your head when you drop the notation, and the plain model is the place the instinct lives.
Consideration is a lookup desk, and that’s why lengthy context is dear. A transformer handles every token by wanting again over each earlier token and pulling a weighted mix of them, a delicate lookup. To try this it retains a small key-and-value file for each token to this point, the KV cache. Consider a submitting cupboard that by no means throws a card away: every new phrase information a card, then flicks via each card already within the drawer to resolve what to take care of. Tremendous at a couple of thousand phrases. At one million, the drawer is big and each new phrase riffles your complete factor, so the price climbs with the sq. of the size.
K3’s predominant consideration swaps the cupboard for a single operating abstract, a fixed-size notepad it writes over because it goes. The notepad by no means grows, and that fastened measurement is what makes a million-token context reasonably priced. What you surrender is {that a} abstract can’t preserve all the pieces, so it has to overlook, and K3 fingers it a per-feature dial for how briskly outdated element fades. A abstract can also’t recall an actual earlier token on demand, so K3 retains one true cupboard layer for each three notepad layers and buys the exact recall again the place it counts.
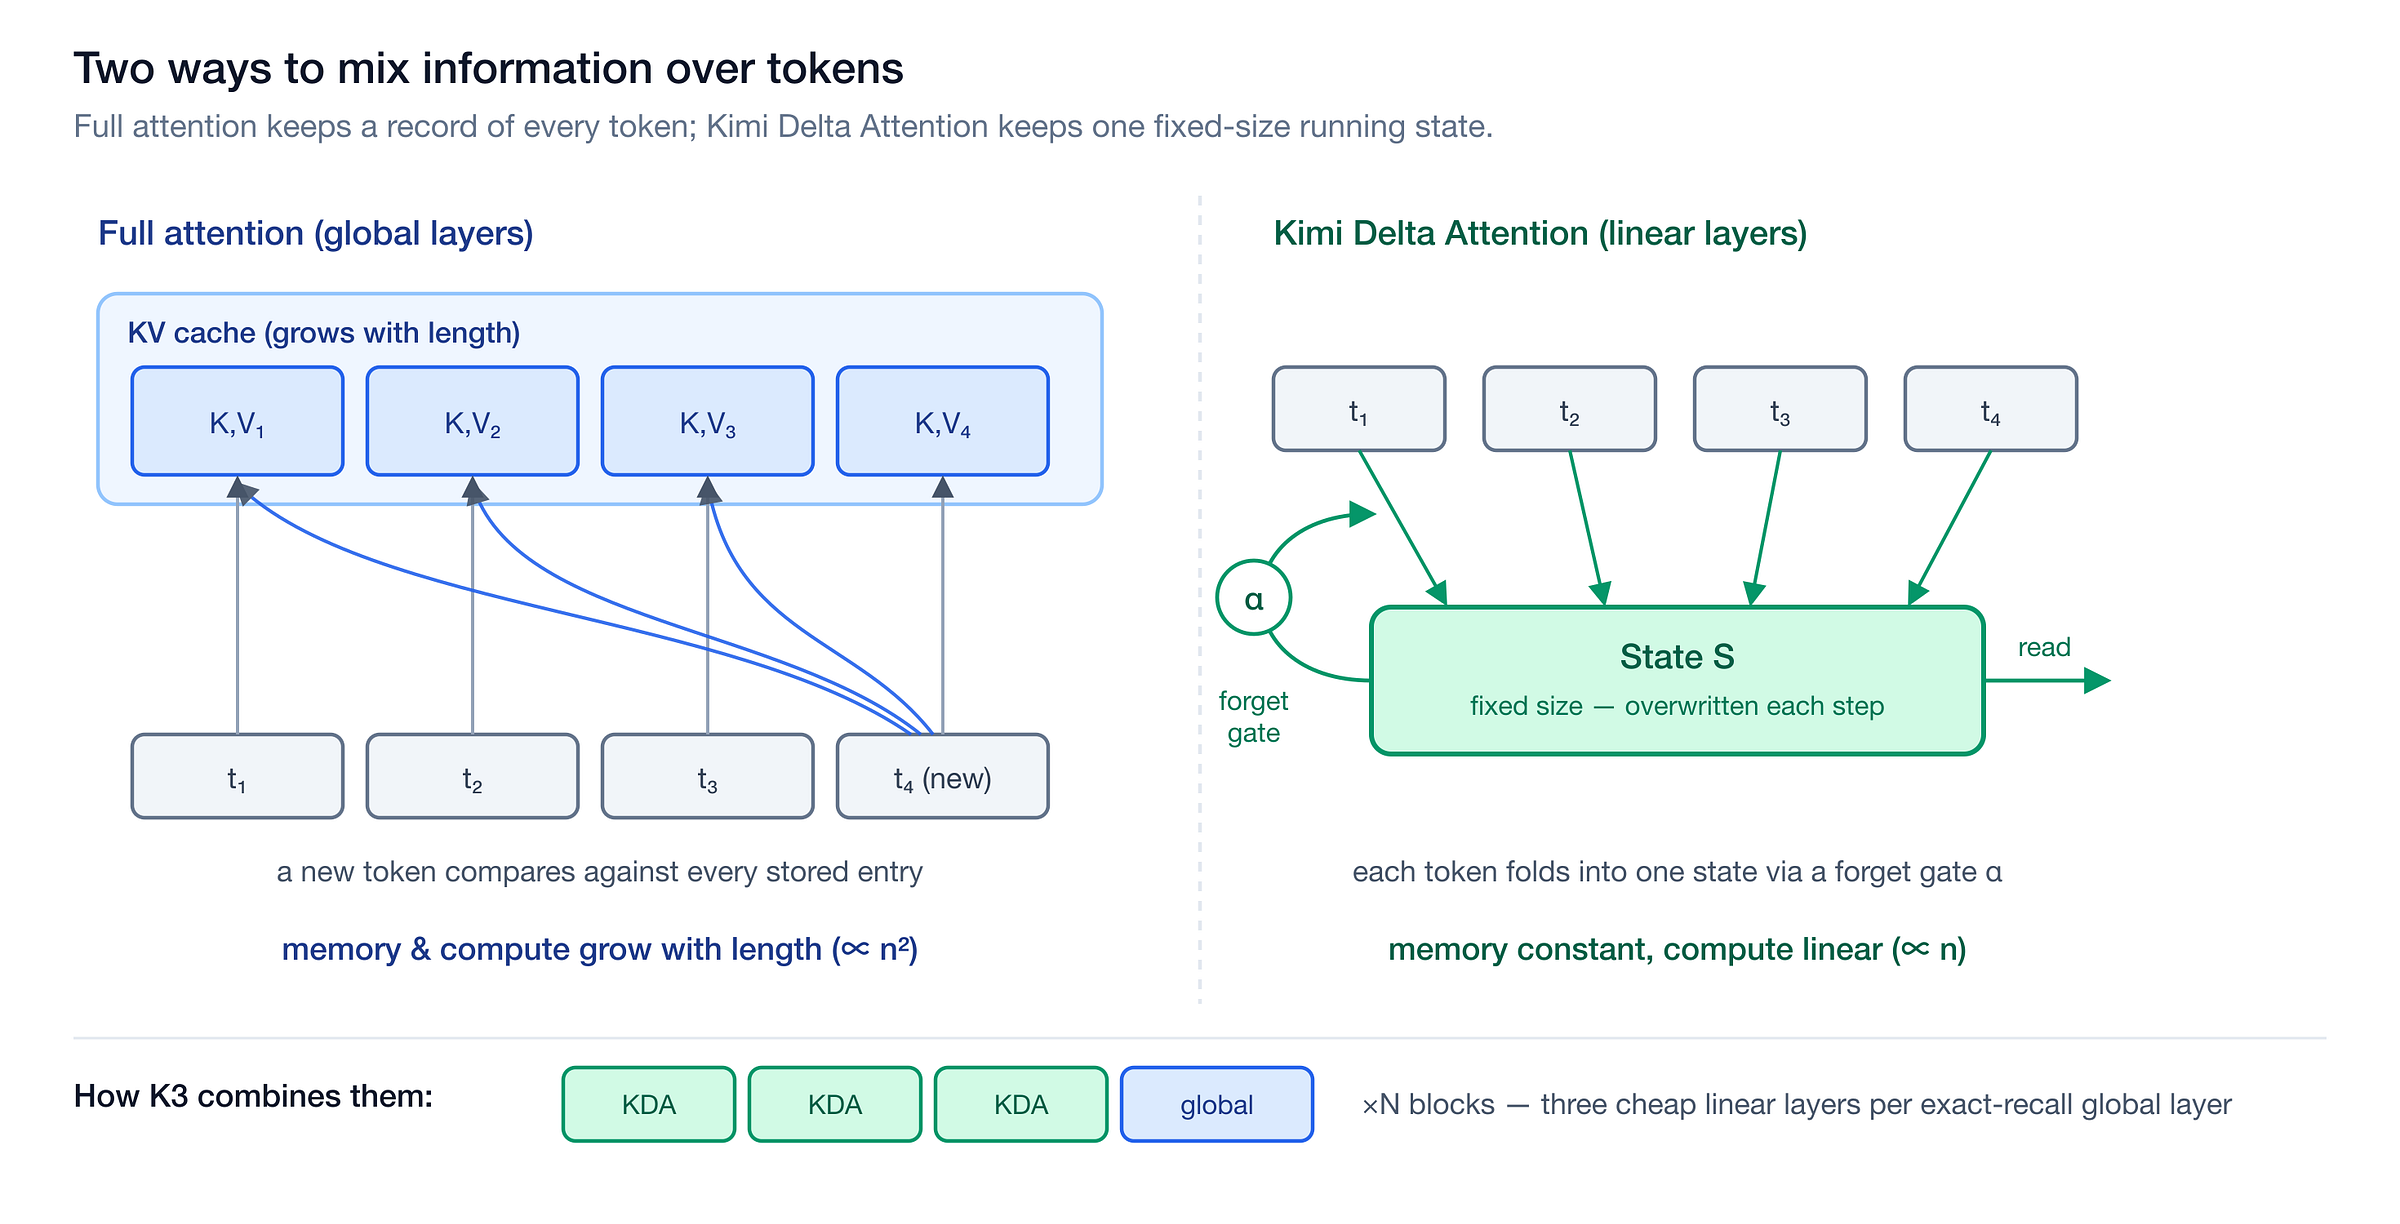
The fixed-state layers already monitor order as they replace, which lets K3 drop express positional encodings fully. Most fashions bolt place onto consideration with one thing like RoPE, and stretching the context window later means rescaling these frequencies or interpolating them, which is fiddly and lossy. K3’s recurrence carries place free of charge, so the identical weights run at 8K throughout early coaching and at 1M after the long-context stage with no positional surgical procedure in between.
The identical lookup trick, one degree up. Stack a whole lot of layers and each usually provides its output to a shared operating whole that flows up the community. Image that whole as a notepad handed up a line of individuals, every scribbling a line. By the highest the primary few traces are buried, and the community burns capability simply holding early data alive. Consideration Residuals let a layer attain again and skim earlier layers’ outputs straight, weighting them with a softmax, the identical soft-lookup equipment as consideration however pointed throughout depth as a substitute of throughout the sequence. A layer pulls a mix from supply as a substitute of enjoying phone up the stack. The fee is reminiscence somewhat than new equipment: each layer’s output has to remain reside for those above it, so K3 attends over a handful of block summaries as a substitute of all of its ninety-odd layers to maintain that invoice down.
Combination of specialists routes every token to a handful of specialists. Reasonably than push each token via one big feed-forward community, K3 retains 896 smaller knowledgeable networks and a router that fingers every token to simply 16 of them. Image a hospital with 896 specialists and a triage desk. No affected person sees everybody; the desk picks the few who match. That’s how the mannequin can maintain 2.8 trillion parameters and nonetheless solely run 104 billion for any given token. Capability and per-token price come aside, so you possibly can add specialists to widen the mannequin’s vary with out paying to run all of them. The saving is in compute, not reminiscence: all 2.8 trillion parameters nonetheless have to take a seat in quick reminiscence to be reachable, which is a part of why serving a mannequin this measurement is a cluster drawback. The snag is that routers play favourites. Depart it alone and it learns to funnel most tokens to a handful of star specialists, which jam up whereas the remainder sit idle and undertrained. So a working MoE has to pressure the load flat, the way in which a maître d’ spreads diners throughout all of the waiters as a substitute of seating each desk in a single part. K3 makes use of a rule that nudges every knowledgeable towards an equal share, and wrestling with that stability is an effective a part of why huge sparse fashions are twitchy to coach.
It comes down to a few concepts: delicate lookup, which turns up over tokens and once more over layers; a fixed-size operating state that stands in for that lookup wherever it bought too costly; and sparsity, which lets the mannequin develop broad with out rising its per-token price.
Making a serial recurrence run on parallel {hardware}
The operating state that makes Kimi Delta Consideration (KDA) low-cost creates its personal drawback, and the way Moonshot handles it is without doubt one of the extra fascinating components of the report. A recurrence is serial by nature: the state after token t is determined by the state after token t−1, so the naive implementation walks the sequence one token at a time. A GPU is the other sort of machine, constructed to run 1000’s of operations without delay, and a strict left-to-right loop leaves almost all of it idle.
The best way out is a chunkwise formulation. Break up the sequence into chunks of some hundred tokens. Inside a bit, the recurrence will be rewritten as a few dense matrix multiplications, which is strictly what the GPU’s tensor cores are quick at, so all the pieces inside a bit runs in parallel. Solely the small, fixed-size state has to go from one chunk to the subsequent, and that hand-off is the only serial step left. Moonshot’s kernel then overlaps the hand-off with the subsequent chunk’s matrix work, so the cores hardly ever stall ready on it. Nearly the entire price turns into parallel matmul, and the serial half shrinks to a sliver of the runtime.
Spreading a single very lengthy sequence throughout a number of GPUs wants another concept. Abnormal consideration has to ship a rising block of keys and values between GPUs because the context lengthens; linear consideration solely passes its fixed-size state, which is much cheaper. The complication is that KDA’s gated replace gained’t allow you to merely add up every GPU’s domestically computed state, as a result of its delta rule multiplies the incoming state by a token-dependent matrix, so what a section does is determined by the state that entered it. Moonshot’s reply splits every section into two issues a GPU can compute by itself, blind to the incoming state: a transition matrix that captures what the section does to any state fed in, and a separate state constructed as if it had began from zero. These items mix so as, so each GPU’s true beginning state is rebuilt with a single fixed-size trade and a scan down the ranks. The eye facet of a million-token coaching step then wants solely that small, fastened trade per chunk, not visitors that grows with the sequence. The specialists nonetheless pay their traditional per-token shuffle between GPUs, however that was by no means the half that scaled with context; this fixes the half that did.
A lot of the work is constructing environments
The closed labs sum up this stage in a single line. “We skilled it with reinforcement studying on agentic duties.” Moonshot spends twenty pages on what that entails, and it’s the clearest view I’ve had of it.
Almost all of K3’s reinforcement studying runs in opposition to environments the group needed to construct by hand, each in a position to examine its personal solutions. For coding there’s a GPU-kernel suite that scores an answer on correctness and velocity in opposition to an knowledgeable model, wired up with a hacking detector that docks the mannequin for faking the win via methods like CUDA graph replay or dropping precision. For assistant work there are mock Gmail, Notion, Slack and Canvas that preserve state throughout simulated days, the place one job can run to 1000’s of device calls.
A pair are price a more in-depth look.
The autonomous-execution duties are the toughest of the set. Each fingers the agent a beginning state, a objective, a set of instruments, a finances, and a verifier, and nothing else, no reference answer and no process to repeat. The agent has to decompose the issue, plan, act, get better from its personal errors and resolve when it’s finished, and it solely scores on what the verifier finds within the remaining state, not by itself declare to have completed. The report’s examples embody reconstructing a hidden system from black-box queries, discovering quantitative elements and tax auditing. To cease the mannequin gaming the grader, they cut up the verifier in two. A public one provides diagnostic suggestions the agent can study from; a hidden one scores held-out instances the agent by no means sees.
The kernel-optimisation suite runs the identical arms race. Rewards there combine correctness and velocity in opposition to an knowledgeable implementation, so a lazy mannequin reaches for a shortcut, replaying a cached CUDA graph, caching inputs, quietly dropping numerical precision. Every of these scores effectively with out doing the work, and every needed to be detected and penalised, with new guards added because the mannequin discovered recent cheats throughout coaching. That back-and-forth, a grader and a mannequin probing it for holes, is most of what constructing an atmosphere involves.
The place the coaching duties come from
An atmosphere solely helps in the event you can feed it sufficient good duties, and at this scale no one is writing them by hand. Moonshot builds them from a data graph the brokers develop themselves. It begins from a handful of broad seed matters; an agent takes every node, searches the online to know the idea, and provides finer sub-concepts beneath it, checking what already exists so it reuses nodes as a substitute of duplicating them. A department stops rising as soon as its idea is particular sufficient to be atomic. What you find yourself with is a hierarchy operating from broad domains right down to slender, specialised corners.
Duties are then drawn from that graph by sampling nodes, generally a single tremendous idea, generally a cluster of associated ones, and folding their key phrases along with context from their mother or father nodes into net queries. The true articles, code and paperwork these queries return are handed to a synthesis agent that writes the precise job. Sampling deeper or shallower units how specialised the duty is; sampling throughout totally different branches units the protection. That provides the group a dial on the coaching distribution, to allow them to intention it at skinny spots as a substitute of producing extra of what the mannequin already handles.
A second trick targets a subtler failure. An agent skilled inside one fastened harness, with one device schema and a technique of managing context, learns that harness as a lot as the duty beneath it. So Moonshot makes the harness itself configurable, a equipment of swappable components for instruments, prompts, reminiscence and subagents, and assembles it into mainstream setups like Claude Code, Codex and its personal Kimi Code, or into new ones. Throughout coaching the mannequin meets many of those preparations, so it generalises throughout scaffolds as a substitute of memorising one.
From 9 specialists into one mannequin
The pipeline runs in three phases. A supervised fine-tuning go provides the mannequin a reliable beginning coverage. Then reinforcement studying, and never as a single run. Moonshot trains throughout three broad domains (normal duties, normal brokers and coding brokers) at three separate ranges of reasoning effort, low, excessive and max. Three domains instances three effort ranges provides 9 specialist fashions, every good at its personal slice. Coaching them individually seemingly sidesteps the interference you get when one coverage has to serve coding, normal work and three effort regimes without delay; every specialist climbs sooner by itself slice, and the conflicts are left for distillation to reconcile. The third stage, multi-teacher on-policy distillation, folds all 9 again into the only mannequin you obtain, with every specialist educating the coed on the slice it is aware of greatest.
The reasoning-effort half can also be instructive. Throughout RL, every drawback will get a token finances estimated from the cold-start mannequin, and any trajectory that blows previous a a number of of that finances has its reward overwritten with a penalty. Coaching walks that multiplier down in phases, from a beneficiant max finances to tight low-effort settings, which is how you find yourself with a mannequin that may be instructed to assume arduous or assume cheaply and truly respects the distinction. The identical budgeting concept reappears on the reward facet: for duties with no computerized checker, a generative reward mannequin scores candidates in opposition to a rubric it writes on the spot, and a candidate that runs too lengthy robotically loses, so the mannequin can’t win by padding its reply.
Taken one by one, these are customary methods. What stands out is that the shaping occurs within the coaching loop and the reward design, not the community.
A frontier mannequin can also be an enormous methods mission
In the event you turned up anticipating largely machine studying, the sheer quantity of plain methods work is a jolt. Getting three awkward issues to run collectively is a lot of the engineering: a linear-attention mannequin, a 2.8-trillion-parameter sparse community and rollouts that stretch to one million tokens.
A few of it’s vivid. They run a microVM sandbox on Firecracker that checkpoints in 133ms and resumes in 49ms, they usually spun up 51 million sandboxes over the mission. A piece of the structure can also be formed by how the mannequin will probably be served. They prepare with the knowledgeable weights quantised to 4-bit within the ahead go, not simply on the finish, so the mannequin learns to reside on the precision it’ll be deployed at, with no train-inference mismatch to paper over later. Additionally they prepare the speculative-decoding draft mannequin from a small prediction layer constructed into the community, and optimise it straight for the acceptance fee that governs the speedup, as a substitute of a proxy. Each are structure selections pushed by serving price, not accuracy.
Just a few case research make the purpose. K3 tuned its personal consideration kernels, and Moonshot says an early checkpoint was already dealing with a lot of the group’s kernel work late within the mission. It wrote a Triton-like compiler finish to finish, and in a separate autonomous run laid out a small inference chip that closes timing at 100MHz. In a single analysis case research it reproduced a set of astrophysics outcomes, cross-checking greater than twenty papers and 1000’s of traces of its personal code, in a few hours in opposition to a human estimate of 1 to 2 weeks. Take the precise numbers with as a lot salt as you want. The report frames that methods work as elite human effort, and the mannequin is already doing a good chunk of it.
The serving classes that switch under frontier scale
That was constructing the mannequin. The final stretch of the report is about operating it, and it’s what I’d hand a working engineer first, as a result of most of it applies effectively earlier than you’re serving something at 3 trillion parameters.
The economics arrange the remainder. K3’s serving price is low by design, and a lot of the levers behind it are strange infrastructure, bent round one uncommon reality about language fashions. Each request carries a big, reusable, expensive-to-rebuild state, and the serving design treats that state because the scarce useful resource.
The most cost effective of these levers is prefix caching. In an extended coding session, a typical request is a 400K-token prefix carrying solely 4K tokens of genuinely new work. Re-run the entire prefix every step and also you pay for all of it every step; cache it and a success prices roughly a hundredth of a miss. Any agent that loops over a rising context pays this price time and again, which makes cache-hit fee the quantity to design round. K3 has a wrinkle of its personal right here: a rising KV cache will be reused as much as any level you want, however a fixed-size operating state solely exists the place you saved a replica, so its linear-attention layers should checkpoint their state at intervals for a later request to have something to reuse.
As soon as a prefix is cached, the request is much cheaper on the machine holding that cache than on a chilly one, as a result of transport the cache round is sluggish, so Moonshot pins every session to the cluster that owns its prefix and provides it a backup cluster by way of constant hashing in case the first dies.
The subtler drawback is mixing request sizes. Actual visitors ranges from 2K-token requests to 1M-token ones, so per-request price spans three orders of magnitude, and a burst of the massive ones will eat the field and go away brief requests queuing behind them till latency collapses for everybody. Moonshot’s repair is to offer every measurement class its personal finances, so a flood of lengthy requests can solely starve itself. Two smaller concepts spherical it out: tiering the cache, so idle prefixes get pushed from GPU reminiscence out to plain CPU RAM and pulled again earlier than reuse; and setting concurrency from reside indicators like cache stress and queue depth somewhat than a hard and fast guess that’s too timid early and overloaded late.
The items are all customary — caching, routing, admission management and backpressure, the toolkit of any busy service. The one twist is a workload the place the per-request state is big.
What the unbiased numbers say
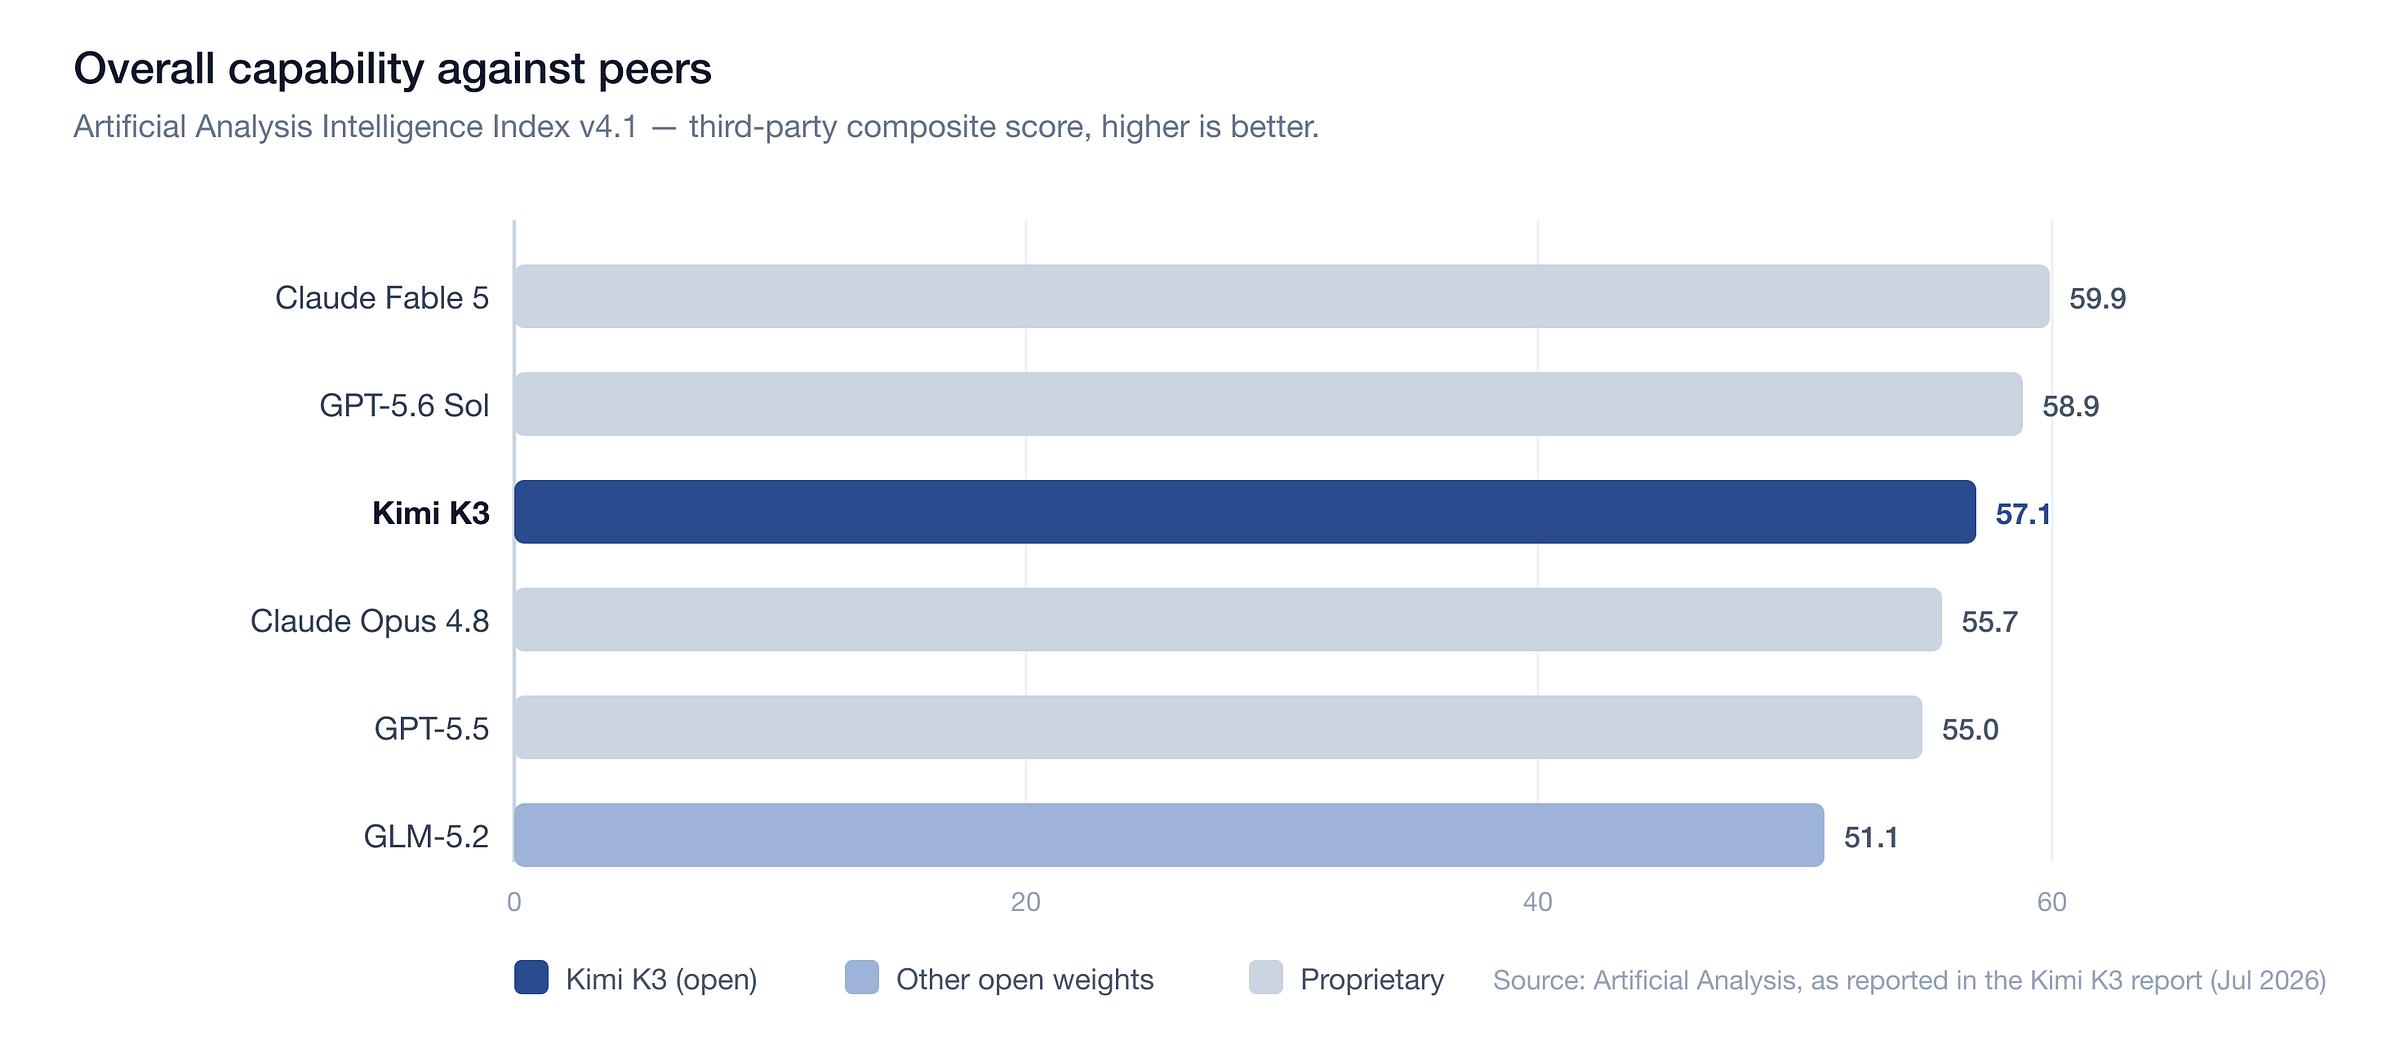
A recipe is barely fascinating if the result’s good, and unbiased numbers matter greater than the lab’s personal. By itself benchmarks K3 trails Claude Fable 5 and GPT-5.6 Sol and beats the remainder of the sphere, which is roughly the story the skin evaluations inform too. Synthetic Evaluation ranks it third amongst mannequin households on its intelligence index, behind solely Claude Fable 5 and GPT-5.6 Sol; it comes fourth of 580 uncooked entries, as a result of two of GPT-5.6 Sol’s effort settings sit above it as separate rows. On the crowd-voted WebDev Enviornment it ranks initially fashions, the primary open mannequin to high that board, although an enviornment measures which output people choose on one household of duties, a narrower query than a composite index; it’s the one board the place K3 leads outright. Vals AI’s industry-weighted suite has it second of thirty-nine. It’s not one of the best mannequin out there, however amongst open fashions it’s clearly the strongest, and the hole to the frontier is small.
The fee image ought to curiosity anybody paying an inference invoice, although each figures listed here are Moonshot’s personal runs. On BrowseComp it posts the highest rating at round two {dollars} a job, roughly half the worth of the closest closed mannequin at full effort and an order of magnitude beneath the priciest. On an inner coding benchmark its high-effort setting matches a powerful closed mannequin’s maximum-effort rating at a couple of third of the worth. These are API costs somewhat than compute prices, and open-weight fashions get hosted by competing suppliers bidding their margins down, so a part of the hole is market construction, not engineering. Even so, it sits at or close to the price-efficiency frontier.
The safety outcomes are probably the most particular factor within the report. On vulnerability discovery the mannequin turned up real bugs in present, broadly deployed software program, and of the findings that went to human assessment, round 70% have been confirmed actual, together with sixteen beforehand unknown vulnerabilities throughout six tasks. Two have been within the Linux kernel: a remotely triggerable out-of-bounds write, and a privilege-escalation bug within the RDMA subsystem the place an earlier repair had dropped a permission examine. On end-to-end exploit writing it solved 14 of 36 duties in opposition to 8 for the strongest open rival, GLM, although it stalled on the hardened kernel targets. Moonshot’s personal suite leaves the frontier closed fashions out right here, as a result of they refuse this sort of job over their public APIs. A separate assessmentby the UK AI Safety Institute and the US CAISI, which might take a look at the closed fashions beneath privileged entry, landed in a lot the identical place: K3 above the open competitors, wanting the frontier cyber fashions and unable to complete the toughest exploit chains.
Why the closed labs preserve this quiet
The rationale the recipe stays inside isn’t a conspiracy. The structure is a pile of printed concepts that anybody with the compute might copy. The environments, the reward equipment, the infrastructure and the info pipelines are the costly, hard-won components, and people are the sting that’s really defensible. Open-sourcing the weights fingers over the least protected factor a lab owns. Publishing the report, as Moonshot did, is greater than most will do, and even it holds again the precise information combine and a whole lot of the knobs.
It additionally says one thing about the place the benefit now sits. The moat was the mannequin itself; now it’s the equipment round it, the environments that may grade a job, the reward fashions which might be arduous to sport, the serving stack that retains an excellent mannequin low-cost. These take years to construct, and none of them leaves with the weights. An open mannequin will get matched or distilled inside months; the tooling behind it doesn’t transfer almost that quick.
Open weights and offensive tooling
There’s a price to all this openness. The identical K3 that finds actual vulnerabilities and writes working exploits is a free obtain, and as soon as it’s by yourself {hardware} it solutions with not one of the refusals or logging {that a} hosted API can impose. The report itself exhibits that cut up, with the frontier closed fashions declining cyber work on the public API whereas the open ones carry it out.
That “free obtain” deserves a caveat, although. The weights are open, however the licence isn’t the permissive sort. Moonshot retains industrial situations connected: a model-as-a-service enterprise previous roughly twenty million {dollars} a yr has to barter a separate settlement, and the most important deployments have to point out the Kimi K3 title of their interface. Abnormal inner use inside an organization is unrestricted, so most non-tech companies can run it with out a second thought. For the misuse query none of that issues, since an attacker writing malware gained’t honour an attribution clause. What does increase the bar is measurement: at round 1.5 terabytes the weights need critical {hardware}, which guidelines out informal native use whilst a decided operator, or a rented cluster, clears it with out a lot hassle.
A current evaluation of GLM, one other sturdy open mannequin, sharpens the near-term image. Its argument is that fashions of this class can now produce the routine constructing blocks of offensive tooling from pretty gentle prompting, the boilerplate that used to eat an operator’s afternoon. It doesn’t add functionality; it removes the trouble of assembling tooling operators already knew how you can construct. The components that have been all the time arduous (mapping an unfamiliar community, getting previous present endpoint defences, avoiding attribution) nonetheless want a talented human. So the near-term impact is usually quantity, many extra low-cost, near-identical samples, which is sufficient by itself to blunt signature-based detection and push defenders towards behavioural strategies.
The place to focus in the event you construct with these fashions
In the event you construct with these fashions as a substitute of coaching them, the report is a reasonably direct trace about the place to level your consideration.
The clearest sign is that analysis and atmosphere design at the moment are actual engineering disciplines. The one greatest slice of effort in the entire report is constructing duties a machine can grade and shutting the methods a mannequin video games them, which is identical ability it is advisable ship an agent you possibly can belief in manufacturing. Studying to write down an excellent verifier, and to assume adversarially about how a mannequin will cheat it, transfers straight from Moonshot’s RL loop to your personal eval harness, and it’s a ability with virtually no vendor lock-in.
Lengthy-horizon agentic engineering is shut behind. K3 is constructed for runs of a whole bunch to 1000’s of device calls over one million tokens of context, and the work that makes these runs maintain collectively (context administration, harness design, sandbox isolation, resumable state) is its personal self-discipline now, separate from prompting and separate from coaching.
Serving economics is the third, and probably the most instantly sensible. The fee benefits within the report come from prefix caching, cache-aware routing, request-class budgeting and quantisation, and each a type of is offered to a small group on a handful of machines. Making a succesful mannequin low-cost to run is one thing the frontier labs deal with as a headline consequence.
Techniques and kernel work sits barely aside, as a result of it’s each clearly priceless and the factor the mannequin is automating quickest. I’d study sufficient to direct and examine it somewhat than betting a profession on hand-writing kernels the mannequin will quickly draft. And I’d spend the least effort chasing structure novelty for its personal sake: the features there are actual however incremental, they arrive from a group with 3-trillion-parameter ablations to run, they usually’re the least reachable place for many of us to compete.
Disclaimer: The views and opinions expressed on this article are my very own and don’t signify these of my employer or any affiliated organizations. The content material relies on private expertise and reflection, and shouldn’t be taken as skilled or tutorial recommendation.
📚References
Kimi Workforce, Moonshot AI. (2026). Kimi K3: Open Frontier Intelligence. The 47-page technical report this text reads all through — an open 2.8-trillion-parameter mixture-of-experts mannequin with 104 billion lively parameters and a one-million-token context window — protecting the structure, reinforcement-learning environments, coaching pipeline, serving stack and evaluations mentioned right here.
Kimi Workforce. (2025). Kimi Linear: An Expressive, Environment friendly Consideration Structure. Launched Kimi Delta Consideration (KDA), the fixed-size-state linear-attention mechanism along with the chunkwise kernel and context-parallel formulation, which K3 adopts as a budget layers in its hybrid consideration and which underpin the serial-recurrence-on-parallel-hardware part.
Elango, V., et al. (2026). LatentMoE: Towards Optimum Accuracy per FLOP and Parameter in Combination of Specialists.Launched the latent-space routed-expert design that K3’s Steady LatentMoE builds on to scale to 896 specialists with 16 lively per token, decoupling mannequin capability from per-token compute whereas leaving all parameters resident in reminiscence.
DeepSeek-AI. (2024). DeepSeek-V3 Technical Report. Launched the auxiliary-loss-free load-balancing scheme for giant mixture-of-experts fashions that K3 extends with Quantile Balancing to maintain almost a thousand specialists evenly used throughout coaching.

