


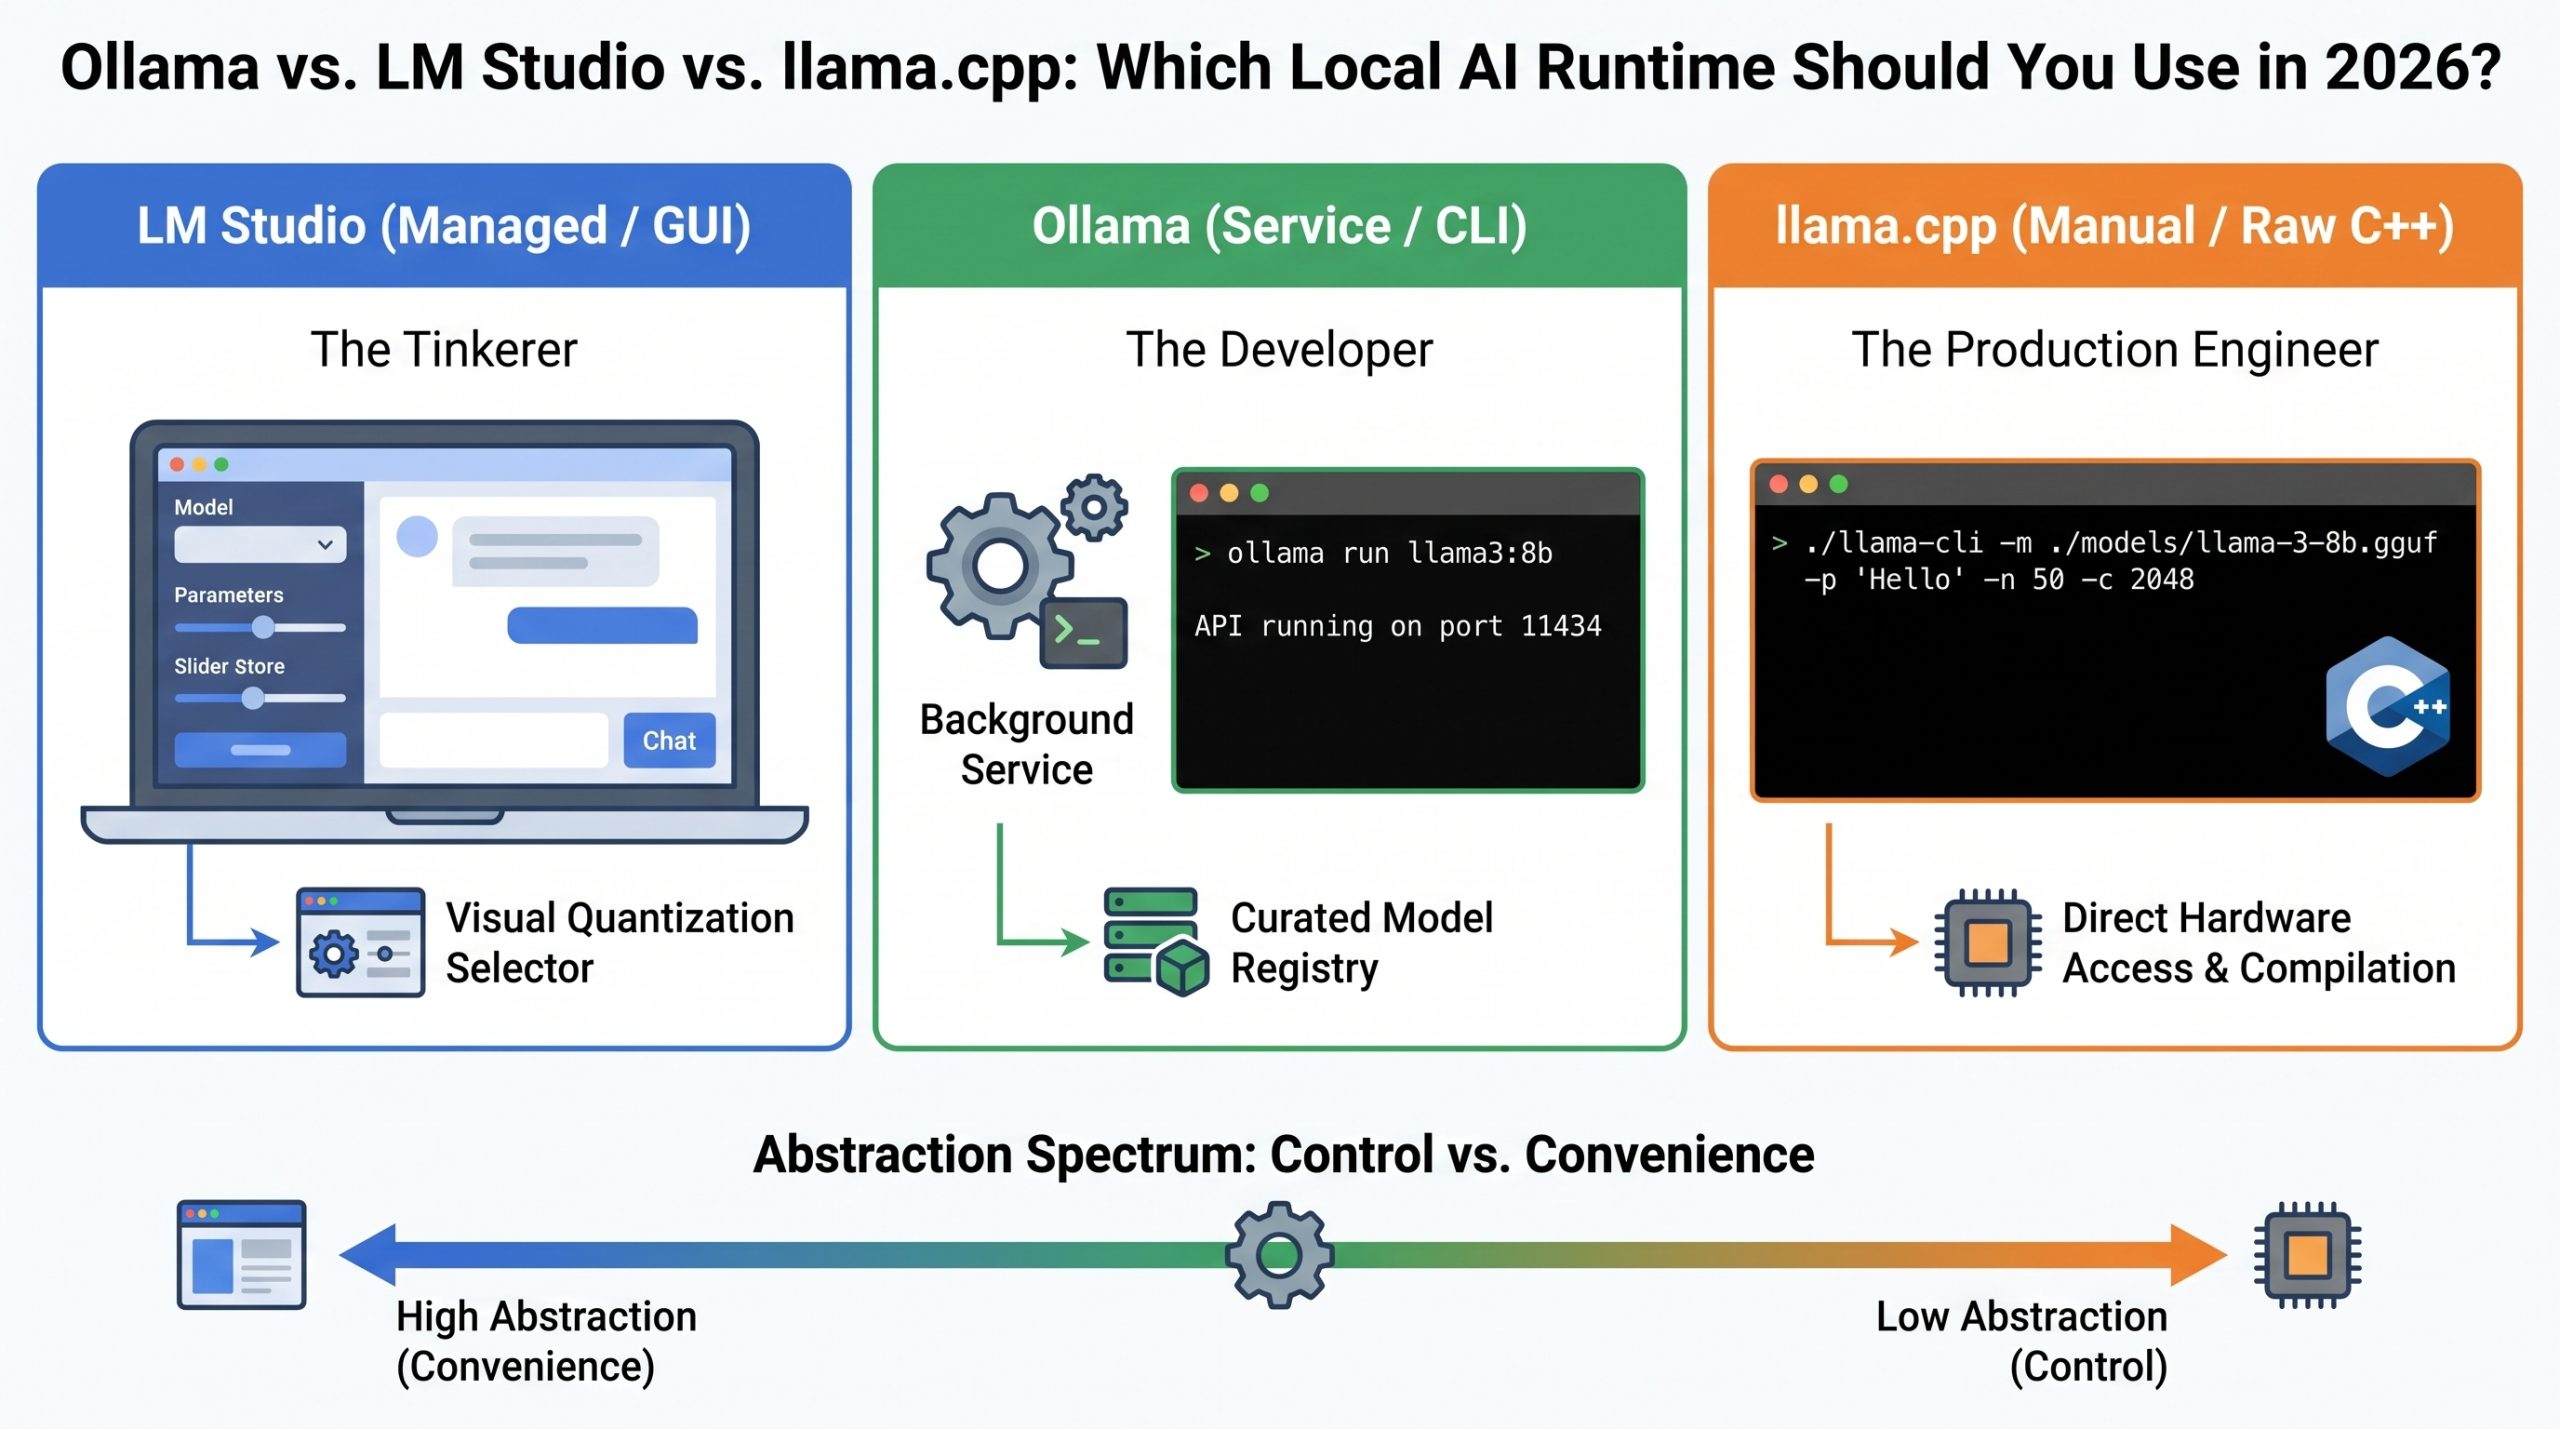
On this article, you’ll learn the way Ollama, LM Studio, and llama.cpp differ throughout the scale that matter most to practitioners, and the way to decide on the suitable one in your workflow.
Subjects we’ll cowl embody:
How the three runtimes evaluate throughout 5 key axes: interface, API compatibility, quantization management, mannequin discovery, and replace cadence.
Methods to match your working type to the suitable device utilizing three practitioner personas.
The pure development most practitioners comply with as their wants develop extra demanding.
Introduction
In our Introduction to Small Language Fashions, we lined why native, small-footprint AI is altering the event stack. We adopted that up with a have a look at essentially the most succesful hardware-friendly fashions in our High 7 Small Language Fashions You Can Run on a Laptop computer. Then we walked by means of the quickest option to get inference working domestically in Run a Native AI Mannequin in 15 Minutes: Your First Ollama Setup.
By now, you in all probability have a 3B or 8B parameter mannequin working quietly in your terminal. Spend sufficient time within the native AI ecosystem, although, and also you’ll discover Ollama isn’t the one choice competing in your arduous drive. Three instruments dominate the native AI runtime panorama: Ollama, LM Studio, and llama.cpp.
Selecting between them can really feel like guesswork, however all three are working the identical core inference engine below the hood. What truly differs is developer expertise, abstraction stage, and the way a lot management you need over the method. To make that concrete, let’s begin by taking a look at every device doing the very same job.
The Code Distinction: One Activity, Three Abstractions
The quickest option to perceive how these instruments differ in philosophy is to see them aspect by aspect. Right here’s the very same process — asking a neighborhood Llama 3.2 mannequin to say “Hi there” — throughout all three runtimes.
# —————————————————————
# The Similar Activity: Asking a neighborhood Llama 3.2 3B mannequin to say “Hi there”
# —————————————————————
# 1. LM Studio (Assuming the GUI is open and the native server is toggled ON)
curl http://localhost:1234/v1/chat/completions
-H “Content material-Kind: utility/json”
-d ‘{“mannequin”: “llama-3.2-3b”, “messages”: [{“role”: “user”, “content”: “Hello”}]}’
# 2. Ollama (By way of its devoted, background-daemon CLI)
ollama run llama3.2 “Hi there”
# 3. llama.cpp (By way of the uncooked, compiled C++ binary in your terminal)
./llama-cli -m ./fashions/llama-3.2-3b-q4_k_m.gguf -p “Hi there” -n 50 -c 2048 -ngl 33
# —————————————————————
# The Similar Activity: Asking a neighborhood Llama 3.2 3B mannequin to say “Hi there”
# —————————————————————
# 1. LM Studio (Assuming the GUI is open and the native server is toggled ON)
curl http://localhost:1234/v1/chat/completions
–H “Content material-Kind: utility/json”
–d ‘{“mannequin”: “llama-3.2-3b”, “messages”: [{“role”: “user”, “content”: “Hello”}]}’
# 2. Ollama (By way of its devoted, background-daemon CLI)
ollama run llama3.2 “Hi there”
# 3. llama.cpp (By way of the uncooked, compiled C++ binary in your terminal)
./llama–cli –m ./fashions/llama–3.2–3b–q4_k_m.gguf –p “Hi there” –n 50 –c 2048 –ngl 33
Discover the development. LM Studio wraps the whole lot in a graphical interface and exposes a pleasant API endpoint. Ollama tucks the advanced parameters behind a single CLI command. And llama.cpp places the whole lot on the desk: mannequin file path, token prediction restrict (-n), context window dimension (-c), and what number of neural community layers to dump to your GPU (-ngl), all of which you outline explicitly.
That spectrum from “managed” to “guide” runs by means of each dimension of how these instruments work. Let’s break each down.
The 5 Axes of Practitioner Comparability
Advertising bullet factors don’t let you know a lot about how a device truly feels once you’re deep in a growth cycle. Right here’s how the three runtimes evaluate throughout the scale practitioners truly discover.
1. GUI vs. CLI (The Interface Layer)
LM Studio is a full desktop utility constructed on Electron/React. It features a ChatGPT-style chat interface, a visible mannequin browser, and sliders for adjusting inference parameters.
Ollama runs as a silent background service. You work together with it by means of the command line or HTTP requests. It’s designed to remain out of your approach.
llama.cpp is a uncooked CLI. There’s no background service until you explicitly compile and run the llama-server binary, and each motion requires typing out execution flags by hand.
2. OpenAI API Compatibility (The Integration Layer)
The interface layer issues for day-to-day use, however the integration layer determines whether or not a device matches into your present codebase. Whenever you’re constructing functions, you need native fashions to drop in as a alternative for OpenAI’s cloud API with out rewriting your present logic.
Each Ollama (port 11434) and LM Studio (port 1234) expose /v1/chat/completions endpoints out of the field. Change the bottom URL in your Python or Node.js SDK and your app thinks it’s speaking to GPT-4.
llama.cpp additionally offers an OpenAI-compatible server, however getting it working requires guide shell scripting and a strong grasp of the accessible parameters.
3. Quantization Management (The {Hardware} Layer)
When you’ve sorted out the way you’ll connect with the mannequin, the subsequent query is how nicely it matches in your machine. Quantization shrinks massive fashions to laptop-friendly sizes by decreasing the precision of their inside weights, and the three runtimes deal with this very otherwise.
Ollama manages quantization for you. Pull a mannequin and it defaults to a well-tuned 4-bit quantization. In order for you one thing totally different, you append a particular tag through the CLI (e.g. :8b-instruct-q8_0).
LM Studio stands out right here: it reveals a visible checklist of each accessible quantization for a given mannequin, with a color-coded indicator telling you whether or not it’ll slot in your RAM earlier than you decide to the obtain.
llama.cpp provides you full management. You obtain the precise .gguf file you need, and you’ve got entry to the underlying Python scripts to quantize uncooked PyTorch tensors into customized codecs your self.
4. Mannequin Library Breadth (The Discovery Layer)
Management over quantization is barely helpful if you could find the fashions you wish to run. Right here’s how every device handles discovery.
Ollama maintains a curated central registry, comparable in really feel to Docker Hub. It’s clear and dependable, however it might lag a number of days behind main mannequin releases.
LM Studio has a built-in Hugging Face search bar. You get entry to hundreds of group fashions, fine-tunes, and experimental variants the second they go dwell.
llama.cpp doesn’t care about registries. If the .gguf file is in your arduous drive, it’ll run.
5. Replace Cadence (The Bleeding Edge)
The invention query connects naturally to a remaining, often-overlooked dimension: how shortly does every device preserve tempo with the quickly shifting mannequin panorama?
As a result of llama.cpp is the foundational open-source engine powering each different instruments, it picks up updates, bug fixes, and assist for brand new mannequin architectures every day. Ollama folds in these upstream modifications on a weekly or biweekly launch cycle. LM Studio, being a full GUI utility, typically ships updates on a slower month-to-month cadence.
Abstract Comparability
With these 5 axes in thoughts, right here’s the total image at a look.
Function / Axis
LM Studio
Ollama
llama.cpp
Major Interface
Desktop GUI
CLI / Background Daemon
Uncooked CLI / Compiled Binary
OpenAI API Assist
Sure (Port 1234, GUI Toggle)
Sure (Port 11434, At all times On)
Sure (Requires llama-server)
Quantization Management
Visible Choice & RAM Estimator
Tag-based (Defaults to This autumn)
Handbook File Dealing with & Creation
Mannequin Discovery
Constructed-in Hugging Face Search
Curated Docker-style Registry
Deliver Your Personal File (.gguf)
Replace Frequency
Month-to-month (GUI Launch Cycle)
Weekly (Quick Follower)
Day by day (The Bleeding Edge)
Greatest For
Prototyping, Chatting, Tinkering
App Growth, Automation
Complete Management, Manufacturing Serving
Persona Matching: Which One Are You?
A function desk tells you what every device can do. What it might’t let you know is which one matches the way you truly work. End up in one of many personas under and also you’ll have your reply.
The Tinkerer (Decide LM Studio)
You learn an AI analysis paper, wish to instantly obtain the mannequin they talked about, and see the way it performs. You want visible suggestions, wish to regulate system prompts in a clear textual content field, and wish to understand how a lot VRAM a mannequin will use earlier than committing to the obtain. You deal with native AI like a high-end desktop utility.
The Developer (Decide Ollama)
You’re not right here for chat interfaces. You’re constructing Retrieval-Augmented Era (RAG) pipelines, wiring up autonomous brokers, or automating workflows. You desire a dependable API endpoint that begins along with your laptop, runs quietly within the background, and plugs cleanly into frameworks like LangChain or LlamaIndex. You deal with native AI like a persistent database service.
The Manufacturing Engineer (Decide llama.cpp)
You’re squeezing each final drop of efficiency out of your {hardware}. You want steady batching to serve 20 concurrent customers, wish to apply customized LoRA (Low-Rank Adaptation) weights on the fly, and are snug compiling C++ from the terminal for a 5% velocity acquire. You deal with native AI as uncooked infrastructure.
The Migration Path
If none of these personas felt like an ideal match, don’t fear. Most practitioners don’t keep in a single class ceaselessly. There’s a well-worn development within the native AI group that maps nearly precisely to the three instruments lined right here: LM Studio → Ollama → llama.cpp.
Most individuals begin with LM Studio. The visible suggestions is reassuring, and it proves your {hardware} can truly run actual AI earlier than you decide to something extra advanced.
Indicators you’ve outgrown LM Studio: You retain minimizing the GUI simply to maintain the native server working whilst you write code. You wish to run fashions inside a Docker container, or you want to deploy on a headless Linux VPS with no monitor connected.
That’s when Ollama turns into your day by day driver. It’s quick, steady, straightforward to script, and stays out of your approach.
Indicators you’ve outgrown Ollama: You’ve picked up a 24GB VRAM GPU and Ollama’s default reminiscence allocation isn’t utilizing it nicely. A brand new experimental mannequin structure simply dropped on Hugging Face and Ollama’s registry hasn’t caught up but. You want fine-grained management over how the Key-Worth (KV) cache behaves when processing lengthy paperwork.
At that time, you progress to llama.cpp: compile the binaries your self, drop the abstractions, and work straight along with your {hardware}.
There’s no mistaken selection right here, and no strain to hurry the development. Decide the device that matches the place you at the moment are, construct one thing actual with it, and transfer down the stack solely when the abstraction begins getting in your approach. Since all three instruments share the identical inference engine beneath, nothing is wasted once you do make the leap. The data transfers cleanly.

