# Introduction
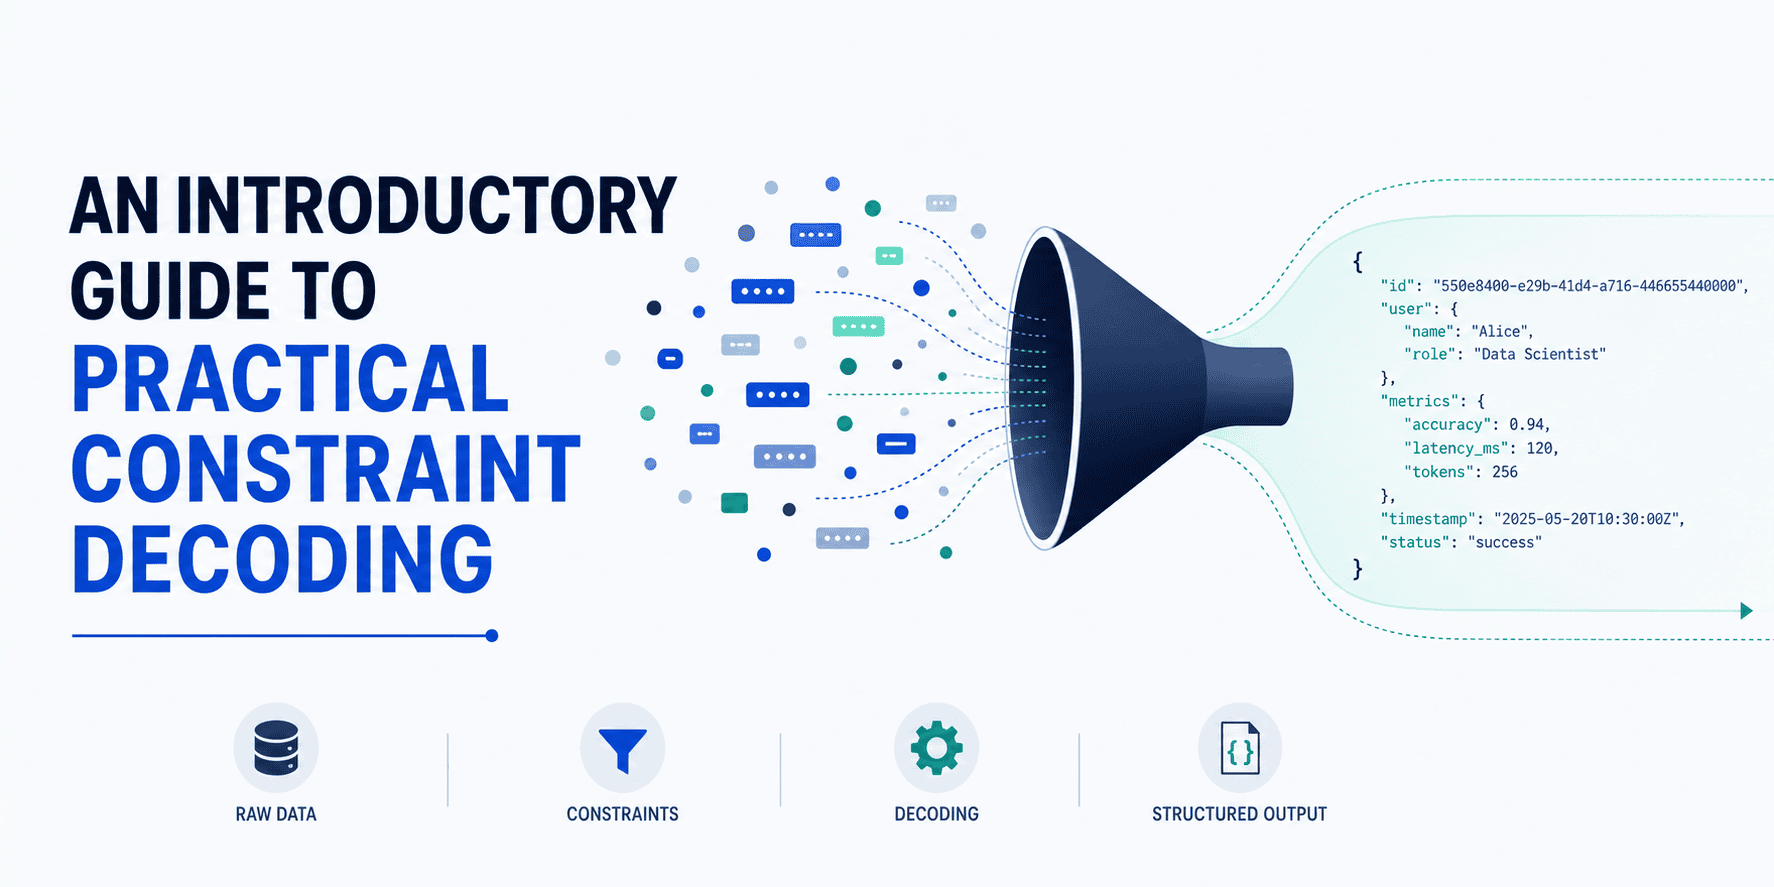
Sensible constraint decoding, also called structured era or guided decoding, encompasses the engineering methods to power a big language mannequin (LLM) to generate textual content outputs that strictly abide by a specified information schema, grammar, or common expression (regex) on the token choice stage.
With the introductory information to sensible constraint decoding on this article, you may now not have to beg your mannequin to “output legitimate JSON with out together with any markdown”, simply to quote an instance. Constraint decoding makes it mathematically unattainable for the LLM to ship something exterior the outlined constraints.
# How Does Sensible Constraint Decoding Work?
Whereas the standard LLM era course of works as an “act of religion” through which you move a immediate to the mannequin and it’d output precisely what you might be on the lookout for (or won’t), sensible constraint decoding takes a subtly distinct method. It deems the immediate and the textual content era as a singular, interleaved program. This makes it doable to lock down sure characters which might be key to sustaining a sure required syntax, permitting the mannequin to “fill within the blanks” in between.
We could go right into a bit extra element? When an LLM outputs the following token of its response, it initially produces a vector of uncooked scores, or logits — one for each doable token within the vocabulary at hand. This usually entails 1000’s of doable choices to select from.
However when utilizing sensible constraint decoding, one thing occurs earlier, earlier than the inference course of begins: a finite state machine is constructed, whereby a goal constraint is compiled — for example, by way of a Pydantic mannequin in Python. At a given inference step, the finite state machine evaluates the present state and supplies an inventory of allowed subsequent tokens. This “white record” is used as a masks on the LLM’s uncooked logits vector, such that for each token exterior that record, its logit is about to damaging infinity, i.e. -inf in Python.
After the masking course of, the mannequin retains working its softmax normalization and sampling course of as regular (primarily based on parameters like temperature, top-p, or top-k) on the “surviving tokens” to finally choose essentially the most possible one and generate it.
It could sound like making use of this course of to a complete vocabulary spanning many 1000’s of phrases would possibly considerably decelerate mannequin inference. The excellent news: it does not. Trendy Python libraries reap the benefits of the LLM’s vocabulary being static and pre-compile it earlier than the person begins typing their immediate. The state machine will not have to lookup the complete vocabulary, and latency overhead is introduced down drastically.
So, what’s the present gold commonplace for implementing sensible constraint decoding? Arguably, the outlines library has earned this distinction. It permits us to outline and move Pydantic fashions, JSON schemas, or regex on to a wrapped model of a pre-trained mannequin, thus constraining its freedom in producing outputs.
# Instance
Let’s stroll by way of an instance. First, set up outlines:
Now onto the code:
from pydantic import BaseModel
import outlines
from transformers import AutoTokenizer, AutoModelForCausalLM
class UserProfile(BaseModel):
title: str
age: int
is_active: bool
model_name = “TinyLlama/TinyLlama-1.1B-Chat-v1.0″
llm = AutoModelForCausalLM.from_pretrained(model_name)
tokenizer = AutoTokenizer.from_pretrained(model_name)
mannequin = outlines.from_transformers(llm, tokenizer)
outcome = mannequin(“Extract the person: John is a 34 12 months outdated pilot.”, UserProfile)
print(outcome)
Output:
This instance confirmed easy methods to use the outlines library to wrap a pre-trained mannequin together with its tokenizer, and constrain it to output JSON objects outlined by the customized class we outlined — named UserProfile and inheriting Pydantic’s BaseModel.
# Wrapping Up
Sensible constraint decoding has a sequence of trade-offs. Let’s take a look at a few of them.
Strengths:
If used appropriately, it supplies a 100% assure for proper syntax, eradicating the necessity for parsing blocks in your code.
It helps drastically save tokens in your prompts, now not requiring token-consuming few-shot examples to indicate the mannequin what an accurate JSON object ought to seem like, for example.
It contributes to the democratization of small fashions, turning a “tiny” 1B-parameter mannequin that may in any other case jeopardize JSON era use instances into an infallible information constructor.
Limitations:
If the LLM wanted to say it can’t reply one thing, however the schema forces it to output an integer, for example, it should accomplish that, making it now not sincere in edge instances.
On the primary run of a Pydantic schema towards an LLM, there could also be a freeze of some seconds to construct the finite state machine, making the primary run significantly slower — though subsequent ones will probably be smoother.
This text introduces sensible constraint decoding, unveiling why it’s essential in sure LLM-driven conditions, the way it works, and what essentially the most extensively adopted answer within the present panorama is: the outlines library. An instance of its use is likewise supplied.
Iván Palomares Carrascosa is a frontrunner, author, speaker, and adviser in AI, machine studying, deep studying & LLMs. He trains and guides others in harnessing AI in the actual world.