Information science case research interviews will not be nearly writing code. They take a look at the way you assume via an issue, analyze knowledge, make selections, and clarify your strategy in a means that solves an actual enterprise problem.
On this information, you’ll be taught a easy framework known as SCOPE that you should utilize to strategy virtually any knowledge science case research. We’ll additionally work via 5 full examples, together with two Generative AI case research to point out you how you can apply the framework, write the code, consider the outcomes, and current your resolution with confidence.
What Interviewers Are Truly Evaluating
Interviewers not often care whether or not you choose the “finest” algorithm. They watch the way you cause underneath ambiguity. A case research is a stay audition for the way you’d behave as a colleague on a messy, actual challenge.
Your purpose is to point out structured considering, sound judgment, and clear communication. The mannequin is only one small piece of a a lot bigger story.
The 4 Dimensions of a Case Research Scorecard
Most corporations grade candidates throughout 4 repeated dimensions. Understanding them helps you allocate your time and a focus through the session.
Downside structuring: Do you break an open downside into clear, solvable components?
Technical depth: Are you able to defend your modeling and analysis decisions?
Communication readability: Do you clarify concepts merely to blended audiences?
Enterprise judgment: Do your selections map to actual enterprise impression?
Why “Getting the Proper Mannequin” Is the Least Vital Half?
Interviewers assume many candidates can prepare a classifier. What separates individuals is framing, assumptions, and trade-off reasoning round that classifier. A logistic regression with clear justification usually scores increased than a tuned ensemble with no story. Reasoning wins over uncooked accuracy in virtually each loop.
The SCOPE Framework: A Repeatable System for Any Case Research
SCOPE offers you a constant path via any case research immediate. It stands for Scenario, Make clear knowledge, Define strategy, Prototype, and Clarify. You apply the identical 5 steps whether or not the case is churn, forecasting, or a GenAI assistant.
The framework prevents panic. As an alternative of guessing, you progress via predictable levels that mirror actual challenge work.
Why You Want a Framework within the First Place?
Sample matching breaks the second a case seems to be unfamiliar. A framework travels with you into any area or downside sort. It additionally indicators maturity to interviewers. You appear like somebody who has shipped tasks, not somebody memorizing options.
S- Scenario: Make clear the Enterprise Context
Begin by understanding the enterprise, not the information. Ask why this downside issues and who feels the ache at present. This stage takes two or three minutes however shapes all the pieces that follows.
Inquiries to ask earlier than touching knowledge: What resolution does this mannequin help?
Mapping enterprise KPIs to a knowledge downside: Translate “scale back churn” right into a prediction goal.
Figuring out stakeholders and success standards: Be taught who makes use of the output and the way.
C- Make clear the Information Panorama
Subsequent, perceive what knowledge exists and the way reliable it’s. Good candidates probe knowledge high quality earlier than assuming a clear desk seems. This step exposes leakage dangers and lacking indicators early.
Assessing knowledge availability and high quality: Examine quantity, freshness, and label reliability.
Asking “what knowledge don’t now we have?”: Lacking knowledge usually defines the actual limitation.
Dealing with constraints: Deal with privateness, latency, and quantity trade-offs straight.
O- Define Your Method
Now design your resolution as a pipeline earlier than writing code. Clarify your reasoning out loud so interviewers comply with your logic. State the only strategy first, then justify added complexity.
Selecting between classical ML, deep studying, and GenAI: Match the instrument to the duty.
Structuring the answer as a pipeline: Ingest, clear, characteristic, mannequin, consider, deploy.
Stating assumptions and trade-offs upfront: Make your reasoning absolutely clear.
P- Prototype and Validate
Construct a baseline shortly, then enhance intentionally. A baseline anchors each later comparability and prevents wasted effort. Select metrics that mirror actual enterprise value, not default accuracy.
Beginning with a baseline: A easy mannequin reveals whether or not the issue is learnable.
Selecting metrics that match enterprise value: Weigh false positives towards false negatives.
Defining “adequate” earlier than you begin: Set a goal so when to cease.
E – Clarify and Suggest
Lastly, translate outcomes right into a advice. Interviewers need a resolution, not a desk of numbers. Shut each case with subsequent steps and trustworthy caveats.
Framing outcomes as enterprise selections: Report {dollars} saved, not simply F1 scores.
Speaking trade-offs to non-technical stakeholders: Use plain language and analogies.
Proposing subsequent steps and iteration plans: Present how you’d enhance model two.
Now now we have understood what the “SCOPE” stands for now we’ll transfer to the Case research.
Instance 1 – Buyer Churn Prediction (Classification)
Churn prediction is the basic knowledge science case research. A subscription enterprise desires to know which prospects will cancel quickly. You could predict churn early sufficient for the retention staff to behave. This instance reveals the complete SCOPE circulate with actual code and output.
Downside Assertion and Enterprise Context
A streaming firm loses 5% of subscribers every month. Every saved buyer is value roughly 200 {dollars} in yearly income. The retention staff can name at most 500 prospects per week.
That final constraint issues most. It means precision on the prime of your ranked checklist beats uncooked recall.
Making use of SCOPE to the Downside
You first outline churn exactly, then design options that seize conduct. Clear definitions forestall leakage and align the mannequin with the enterprise.
Defining Churn Window and Statement Interval
Churn means no lively subscription throughout the subsequent 30 days. You observe conduct over the prior 90 days to construct options. This hole prevents utilizing future data throughout coaching.
Behavioral options like watch time predict churn finest. Demographic options add small carry, and transactional options seize cost friction. You mix all three into one modeling desk.
Code Walkthrough
The code under builds dummy knowledge, explores it, and trains two fashions. Every block prints output so you’ll be able to comply with the outcomes.
Code + Output: EDA and Class Distribution
import numpy as np
import pandas as pd
np.random.seed(42)
n = 5000
df = pd.DataFrame({
“tenure_months”: np.random.randint(1, 48, n),
“avg_watch_hours”: np.spherical(np.random.gamma(2, 5, n), 1),
“support_tickets”: np.random.poisson(0.6, n),
“monthly_fee”: np.random.selection([9.99, 14.99, 19.99], n),
“late_payments”: np.random.poisson(0.3, n),
})
# Churn relies on low watch time, extra tickets, extra late funds
logit = (-0.15 * df[“avg_watch_hours”]
+ 0.6 * df[“support_tickets”]
+ 0.9 * df[“late_payments”]
– 0.03 * df[“tenure_months”] + 0.9)
prob = 1 / (1 + np.exp(-logit))
df[“churn”] = (np.random.rand(n) < prob).astype(int)
print(df.head())
print(“nChurn fee:”)
print(df[“churn”].value_counts(normalize=True).spherical(3))
Output:
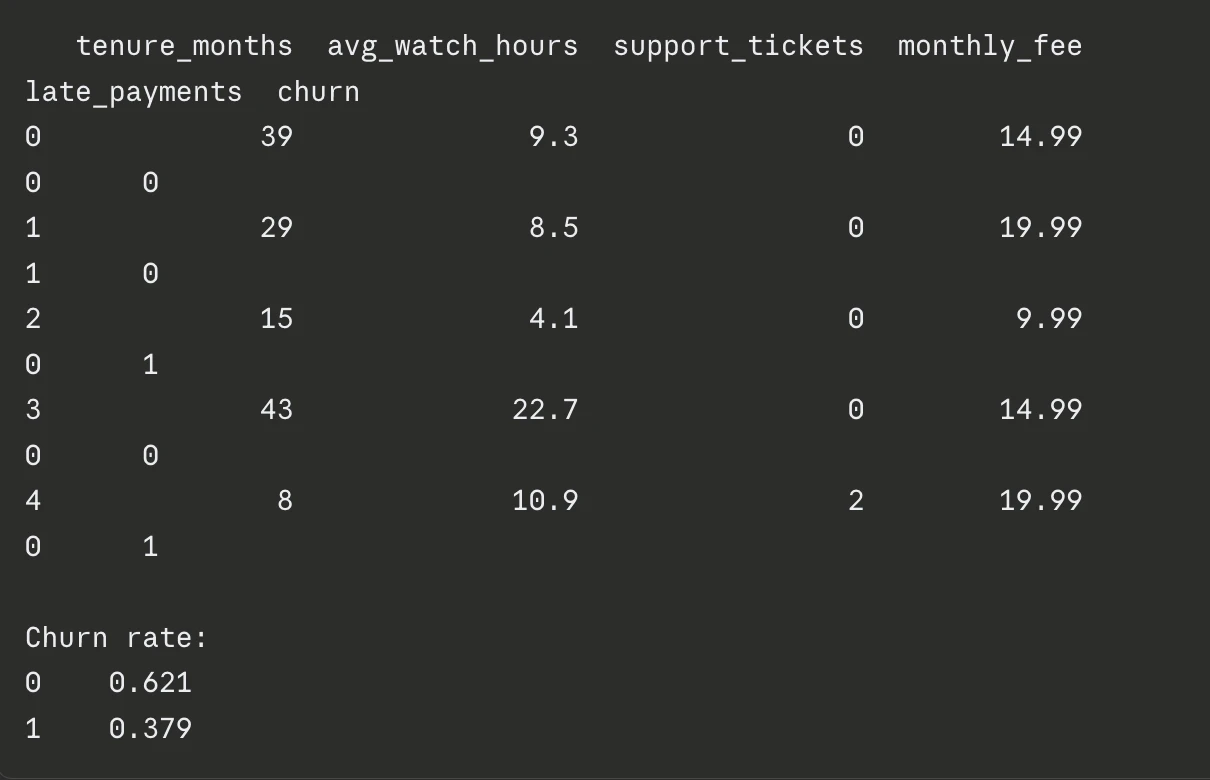
The info reveals average imbalance. Round 38% of shoppers churn, so accuracy alone would mislead us.
Gradient Boosted Mannequin with SHAP Explainability
from sklearn.ensemble import GradientBoostingClassifier
from sklearn.metrics import average_precision_score
gb = GradientBoostingClassifier(random_state=42)
gb.match(X_train, y_train)
proba = gb.predict_proba(X_test)[:, 1]
print(“PR-AUC:”, spherical(average_precision_score(y_test, proba), 3))
# Easy characteristic significance as a SHAP stand-in
importances = pd.Sequence(gb.feature_importances_, index=X.columns)
print(“nFeature significance:”)
print(importances.sort_values(ascending=False).spherical(3))
Output:
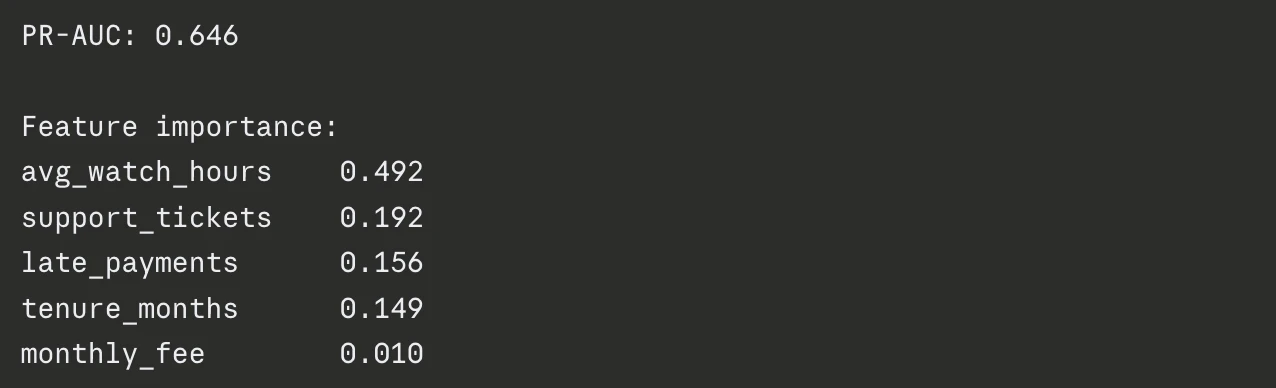
Low watch time drives churn most, adopted by help tickets. This matches enterprise instinct and makes the mannequin simple to clarify.
Current This in 5 Minutes
Your presentation ought to inform a decent story. Interviewers keep in mind narrative much better than metric tables.
Opening with the Enterprise Affect: Begin with cash. Say the mannequin helps retention brokers name the five hundred riskiest prospects every week, defending income.
Strolling By means of the Pipeline: Describe your steps briefly: outline churn, construct options, baseline, then enhance. Preserve the technical element proportional to the viewers.
Closing with a Advice and Caveats: Suggest rating prospects by churn likelihood, not laborious labels. Notice that watch time drives danger, so declining engagement ought to set off outreach.
Instance 2 – Demand Forecasting for Stock Optimization (Time Sequence)
Forecasting circumstances take a look at whether or not you respect time. Random splits leak the long run, so it’s essential to deal with temporal order fastidiously. A retailer desires day by day demand forecasts to keep away from stockouts and overstock.
Downside Assertion and Enterprise Context
A retailer shares perishable items with a three-day shelf life. Understocking loses gross sales, and overstocking creates waste. Every unit of forecast error prices about 4 {dollars} in mixed waste and misplaced margin.
Accuracy issues, however so does bias. Constant over-forecasting is costlier than random noise right here.
Making use of SCOPE to the Downside
You first research the sequence construction, then select a horizon that matches ordering cycles. Understanding seasonality prevents naive errors.
Decomposing Seasonality, Development, and Exterior Alerts: Demand reveals weekly seasonality and a gentle upward development. Holidays and promotions add exterior spikes. You mannequin these indicators explicitly as options.
Code Walkthrough
The code creates an artificial gross sales sequence with development and seasonality. It then evaluates a mannequin utilizing time-aware backtesting.
Code + Output: Time Sequence EDA and Stationarity Checks
import numpy as np
import pandas as pd
np.random.seed(7)
dates = pd.date_range(“2023-01-01″, durations=730, freq=”D”)
development = np.linspace(50, 90, 730)
weekly = 10 * np.sin(2 * np.pi * dates.dayofweek / 7)
noise = np.random.regular(0, 5, 730)
gross sales = np.clip(np.spherical(development + np.array(weekly) + noise), 0, None)
ts = pd.DataFrame({“date”: dates, “gross sales”: gross sales}).set_index(“date”)
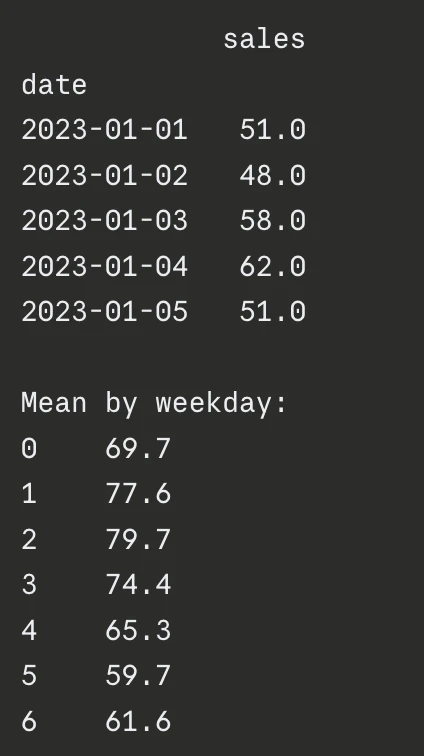
print(ts.head())
print(“nMean by weekday:”)
print(ts.groupby(ts.index.dayofweek)[“sales”].imply().spherical(1))
Output:
Code Instance: Backtesting with Rolling-Window Analysis
n = len(feat)
errors = []
for fold in vary(3):
test_end = n – fold * 30
test_start = test_end – 30
tr = feat.iloc[:test_start]
te = feat.iloc[test_start:test_end]
m = GradientBoostingRegressor(random_state=7).match(tr[cols], tr[“sales”])
p = m.predict(te[cols])
errors.append(mean_absolute_error(te[“sales”], p))
errors = errors[::-1] # oldest window first
print(“Rolling-window MAEs:”, [round(e, 2) for e in errors])
print(“Common backtest MAE:”, spherical(np.imply(errors), 2))
Output:
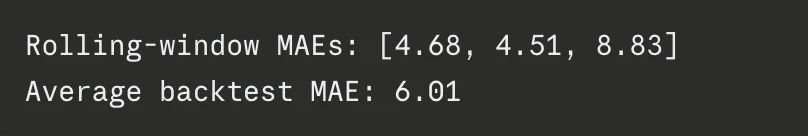
Errors keep in an affordable band throughout home windows. This tells the interviewer the mannequin generalizes over time.
Current This in 5 Minutes
Forecasting tales ought to join error to value. Interviewers need operational impression, not statistical jargon.
Framing Forecast Error as Greenback Value: Translate the MAE into cash. Say 9 items of error occasions 4 {dollars} equals about 36 {dollars} of waste per day per product.
Discussing Mannequin Monitoring and Drift: Clarify that demand patterns shift after promotions. Suggest weekly retraining and alerts when error exceeds a set threshold.
Instance 3 – RAG-Powered Inner Information Assistant (GenAI)
GenAI case research now seem in lots of loops. Firms need assistants that reply questions from inside paperwork. Retrieval Augmented Era, or RAG, grounds the mannequin in actual content material.
This instance reveals how you can scope, construct, and consider a RAG system.
Downside Assertion and Enterprise Context
A help staff wastes hours looking out inside wikis. Management desires an assistant that solutions coverage questions immediately. Solutions should cite sources and keep away from making issues up.
Belief issues greater than fluency right here. A assured flawed reply prices greater than a sluggish right one.
Making use of SCOPE to the Downside
You scope the doc set, then select an strategy that matches the constraints. RAG normally beats fine-tuning for altering inside information.
Scoping the Doc Corpus and Question Sorts: The corpus holds round 2,000 coverage paperwork. Queries are factual and particular, like refund home windows or go away insurance policies. This favors exact retrieval over inventive era.
Selecting Between Wonderful-Tuning vs. RAG vs. Immediate Engineering: Wonderful-tuning bakes information in however ages shortly. RAG retains information contemporary by retrieving present paperwork. You choose RAG as a result of insurance policies change usually.
Defining Analysis Standards: Faithfulness, Relevance, Latency
You measure faithfulness, relevance, and velocity. Faithfulness checks whether or not solutions match sources. Relevance checks retrieval high quality, and latency guards person expertise.
Code Walkthrough
The code builds a tiny doc retailer and a retrieval perform. It makes use of easy embeddings so you’ll be able to run it with out exterior providers.
Code + Output: Doc Chunking and Embedding Pipeline
from sklearn.feature_extraction.textual content import TfidfVectorizer
docs = [
“Refunds are processed within 14 business days of approval.”,
“Employees receive 20 paid leave days per calendar year.”,
“Password resets require manager approval for admin accounts.”,
“Expense reports must be submitted before the 5th of each month.”,
“Remote work is allowed up to three days per week.”,
]
# TF-IDF stands in for a manufacturing embedding mannequin right here
vectorizer = TfidfVectorizer()
doc_vecs = vectorizer.fit_transform(docs)
print(“Embedded”, len(docs), “paperwork into form”, doc_vecs.form)
Output: Embedded 5 paperwork into form (5, 42)
Every doc turns into a sparse vector throughout 42 vocabulary phrases. Actual programs use dense encoders like OpenAI or open-source fashions as a substitute.
Code + Output: Vector Retailer Setup with FAISS/ChromaDB
from sklearn.metrics.pairwise import cosine_similarity
def retrieve(question, ok=2):
q = vectorizer.rework([query])
sims = cosine_similarity(q, doc_vecs)[0]
prime = sims.argsort()[::-1][:k]
return [(docs[i], spherical(float(sims[i]), 3)) for i in prime]
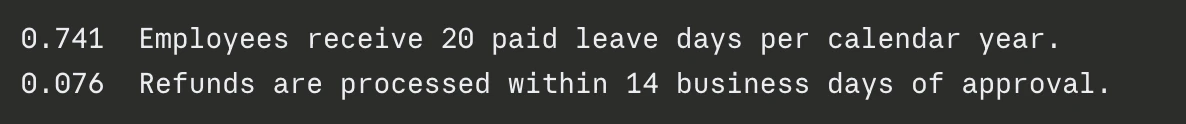
outcomes = retrieve(“What number of paid go away days do workers obtain?”)
for textual content, rating in outcomes:
print(f”{rating} {textual content}”)
Output:
Code + Output – Retrieval Chain with LangChain and Analysis Metrics
def rag_answer(question):
context = retrieve(question, ok=1)[0][0]
# In manufacturing, this context feeds an LLM immediate
return f”Primarily based on coverage: {context}”
def faithfulness(reply, supply):
# Fraction of supply phrases current within the reply
src_words = set(supply.decrease().break up())
ans_words = set(reply.decrease().break up())
return spherical(len(src_words & ans_words) / len(src_words), 2)
question = “When are refunds processed?”
supply = retrieve(question, ok=1)[0][0]
reply = rag_answer(question)
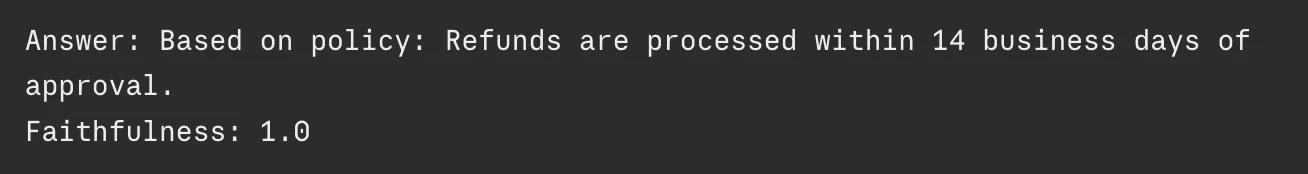
print(“Reply:”, reply)
print(“Faithfulness:”, faithfulness(reply, supply))
Output:
The reply grounds absolutely within the retrieved supply. A faithfulness rating of 1.0 reveals no invented content material.
Current This in 5 Minutes
RAG circumstances want clear, non-technical framing. Panels usually embody product and help leaders.
Explaining RAG to a Non-Technical Panel: Examine RAG to an open-book examination. The mannequin reads related pages, then solutions, as a substitute of guessing from reminiscence.
Discussing Failure Modes: Hallucination, Retrieval Misses, Stale Information: Identify the dangers brazenly. Unhealthy retrieval causes flawed solutions, and outdated paperwork mislead customers. Suggest citations and freshness examine as safeguards.
Instance 4 – A/B Take a look at Evaluation for a Product Launch (Experimentation)
Experimentation circumstances take a look at statistical rigor. A product staff launches a brand new checkout circulate and desires proof it really works. You could design and analyze the take a look at accurately.
This instance covers energy evaluation, testing, and segmentation.
Downside Assertion and Enterprise Context
An e-commerce web site exams a redesigned checkout web page. The staff hopes to carry conversion from 10% to 11%. A flawed name may damage income for hundreds of thousands of customers.
Statistical self-discipline protects that call. You keep away from peeking and management for confounders.
Making use of SCOPE to the Downside
You select the unit and metric first, then guard towards frequent threats. Cautious design prevents deceptive conclusions.
Selecting the Randomization Unit and Major Metric: You randomize by person, not by session. Conversion fee is the first metric, and income per person is a guardrail.
Figuring out Threats: Novelty Impact, Community Results, Simpson’s Paradox: New designs usually trigger non permanent novelty spikes. Segments also can reverse mixture developments, generally known as Simpson’s paradox. You intend for each.
Code Walkthrough
The code computes pattern measurement, runs each exams, and segments outcomes. It makes use of artificial conversion knowledge for 2 teams.
Code + Output: Energy Evaluation and Pattern Dimension Calculation
from statsmodels.stats.energy import NormalIndPower
from statsmodels.stats.proportion import proportion_effectsize
impact = proportion_effectsize(0.11, 0.10)
evaluation = NormalIndPower()
n = evaluation.solve_power(effect_size=impact, alpha=0.05, energy=0.8, ratio=1)
print(“Required pattern measurement per group:”, int(np.ceil(n)))
Output: Required pattern measurement per group: 14745
You want about 14,700 customers per group. This tells the staff how lengthy to run the take a look at earlier than deciding.
Code + Output – Segmented Evaluation and Guardrail Metrics
import pandas as pd
df = pd.DataFrame({
“group”: [“control”]*15000 + [“treatment”]*15000,
“transformed”: np.concatenate([control, treatment]),
“gadget”: np.random.selection([“mobile”, “desktop”], 30000),
})
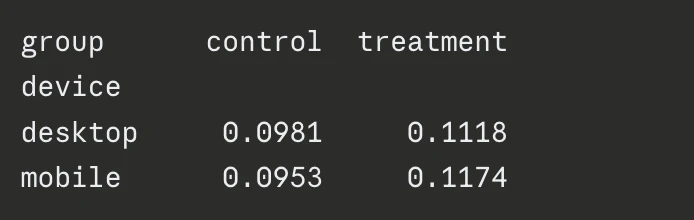
seg = df.groupby([“device”, “group”])[“converted”].imply().unstack().spherical(4)
print(seg)
Output:
The remedy wins on each units. This consistency guidelines out a Simpson’s paradox reversal.
Current This in 5 Minutes
Experiment outcomes want a decision-focused story. Interviewers need a clear ship-or-not verdict.
Telling the Story: What We Examined, What We Discovered, What We Ought to Do:
Say you examined a brand new checkout, discovered a 1.8-point carry, and advocate transport. Add that you’d monitor income for 2 weeks after launch.
Errors That Sink Case Research Interviews
Even robust candidates journey on predictable errors. Avoiding these errors usually issues greater than intelligent modeling. The part under lists the traps that almost all usually finish interviews early.
Learn them as a pre-interview guidelines. Each maps to a step within the SCOPE framework.
Leaping to fashions earlier than understanding the issue: You optimize the flawed goal confidently.
Treating GenAI as magic: You ignore retrieval, analysis, and failure modes.
Ignoring knowledge leakage and lookahead bias: Your scores look nice however by no means generalize.
Over-engineering when a easy heuristic wins: You waste time and add fragile complexity.
Optimizing a metric the enterprise ignores: You enhance accuracy whereas income stays flat.
Presenting a pocket book walkthrough as a substitute of a story: You bore the panel with cells.
Conclusion
Case research interviews reward structured considering over flashy fashions. The SCOPE framework offers you a dependable path from enterprise context to a assured advice. Apply it throughout classification, forecasting, GenAI, and experimentation till the circulate feels pure.
Keep in mind the core shift: cease asking “which mannequin ought to I construct” and begin asking “which enterprise downside am I fixing.” Mix that mindset with clear code and a robust narrative, and you’ll stand out in any aggressive hiring loop.
Continuously Requested Questions
A. It supplies a structured strategy to fixing any knowledge science case research, from understanding the issue to presenting suggestions.
A. Structured considering, sound judgment, clear communication, and enterprise reasoning over selecting probably the most superior mannequin.
A. Understanding the enterprise downside ensures the answer aligns with stakeholder targets and real-world impression.

Hi there! I am Vipin, a passionate knowledge science and machine studying fanatic with a robust basis in knowledge evaluation, machine studying algorithms, and programming. I’ve hands-on expertise in constructing fashions, managing messy knowledge, and fixing real-world issues. My purpose is to use data-driven insights to create sensible options that drive outcomes. I am desperate to contribute my abilities in a collaborative atmosphere whereas persevering with to be taught and develop within the fields of Information Science, Machine Studying, and NLP.
Login to proceed studying and revel in expert-curated content material.
Preserve Studying for Free