Your AI agent works nice in testing. Then you definately ship it, and one thing kinda breaks. A device known as loops endlessly, prefer it by no means learns. A retrieval step returns rubbish and prices spike. You don’t have any thought why, in any respect.
That’s the agent observability downside. And for those who’re constructing with LLMs, it is advisable clear up it earlier than manufacturing, not after. This publish kinda breaks down three of the most-used observability instruments: LangSmith, Langfuse and Arize. We’ll set every one up, hint the identical agent and examine what you truly get.
What’s Agent Observability?
Conventional utility monitoring tracks requests, errors, and latency, however that’s not sufficient for Brokers.
An Agent could name a number of instruments in sequence, with every LLM step having its personal immediate, token utilization, latency, and potential failure level. A single failed retrieval or device name can result in an incorrect remaining response.
Agent observability captures the complete execution graph: each step, resolution, LLM enter and output, device name, arguments, outcomes, token utilization, latency, and analysis rating. With out this visibility, debugging agent conduct turns into guesswork.
Setting Up the Check Agent
We are going to make the most of a quite simple LangChain agent to check them. The agent receives a query from the consumer, retrieves related context, and responds utilizing a number of instruments to supply a solution.
First, it is advisable create the take a look at agent and for that set up all of the required libraries.
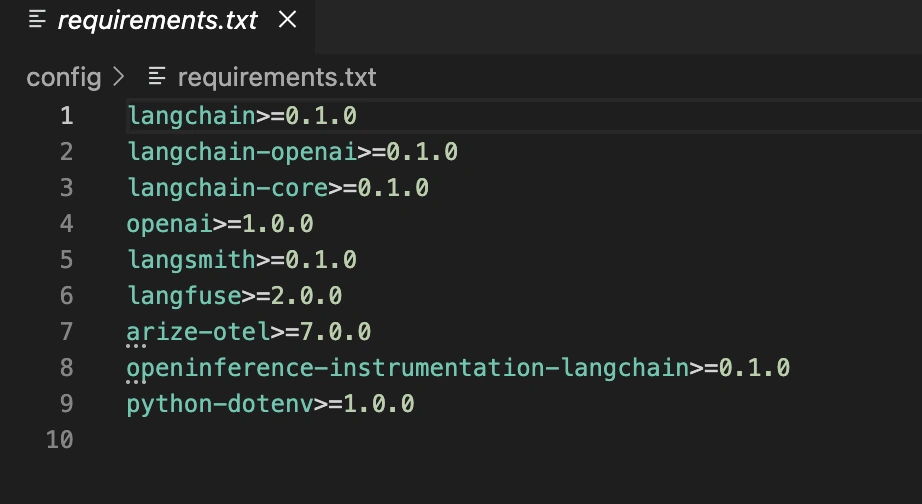
Let’s have a look at the bottom agent with two strategies (search_docs and get_order_status). This may act as our foundational base for comparability with the three observability instruments.
“””
Base agent used throughout all three observability demos.
Swap the OPENAI_API_KEY env var or name build_agent() from any demo file.
“””
import os
from dotenv import load_dotenv
from langchain.brokers import AgentExecutor, create_openai_tools_agent
from langchain.instruments import device
from langchain_core.prompts import ChatPromptTemplate, MessagesPlaceholder
from langchain_openai import ChatOpenAI
load_dotenv()
@device
def search_docs(question: str) -> str:
“””Search inner docs for related data.”””
# Simulated retrieval — swap along with your precise vector retailer
docs = {
“refund”: (
“Refunds are processed inside 5-7 enterprise days. ”
“Gadgets have to be returned inside 30 days.”
),
“delivery”: (
“Customary delivery takes 3-5 enterprise days. ”
“Categorical is 1-2 days.”
),
“account”: (
“You possibly can reset your password through the login web page. ”
“Contact help for account points.”
),
}
for key phrase, content material in docs.gadgets():
if key phrase in question.decrease():
return content material
return f”Discovered common docs associated to: {question}”
@device
def get_order_status(order_id: str) -> str:
“””Search for the standing of an order by ID.”””
# Simulated order lookup
statuses = {
“ORD-001”: “Shipped — anticipated supply 2026-05-30”,
“ORD-002”: “Processing — not but shipped”,
“ORD-003”: “Delivered on 2026-05-25″,
}
return statuses.get(
order_id,
f”Order {order_id} not discovered within the system.”,
)
def build_agent() -> AgentExecutor:
llm = ChatOpenAI(
mannequin=”gpt-4o”,
temperature=0,
api_key=os.environ[“OPENAI_API_KEY”],
)
instruments = [search_docs, get_order_status]
immediate = ChatPromptTemplate.from_messages(
[
(
“system”,
“You are a helpful customer support assistant. ”
“Use tools when needed.”,
),
(“user”, “{input}”),
MessagesPlaceholder(variable_name=”agent_scratchpad”),
]
)
agent = create_openai_tools_agent(llm, instruments, immediate)
return AgentExecutor(
agent=agent,
instruments=instruments,
verbose=False,
)
TEST_QUESTIONS = [
“What are the refund policies?”,
“What is the status of order ORD-002?”,
“How long does shipping take?”,
]
if __name__ == “__main__”:
executor = build_agent()
for query in TEST_QUESTIONS:
print(f”nQ: {query}”)
outcome = executor.invoke({“enter”: query})
print(f”A: {outcome[‘output’]}”)
This creates a candidate agent that will also be used with every of the instruments. The primary device we are going to discover would be the one supplied by LangSmith.
LangSmith: Native Langchain Tracing
The LangChain staff has developed LangSmith. In case you are utilizing LangChain, then integration might be fast and straightforward.
“””
LangSmith observability demo.
Setup:
pip set up langsmith
Set LANGCHAIN_API_KEY in your .env file.
The way it works:
LangSmith hooks into LangChain’s callback system through env vars, so no code
modifications are wanted past the 2 os.environ strains under.
“””
import os
from dotenv import load_dotenv
from agent_base import TEST_QUESTIONS, build_agent
load_dotenv()
# Allow LangSmith tracing. These two vars are all you want.
os.environ[“LANGCHAIN_TRACING_V2”] = “true”
os.environ[“LANGCHAIN_PROJECT”] = “agent-observability-demo”
# LANGCHAIN_API_KEY have to be set in your .env or setting.
def run_with_metadata(
executor,
query: str,
user_id: str = “demo-user”,
):
“””Run the agent and fix per-run metadata through config.”””
return executor.invoke(
{“enter”: query},
config={
“metadata”: {
“user_id”: user_id,
“supply”: “langsmith_demo”,
},
# Non-compulsory: tag runs for filtering within the dashboard.
“tags”: [“observability-blog”, “demo”],
},
)
def primary():
print(“=== LangSmith Demo ===”)
print(“Traces will seem at: https://smith.langchain.com”)
print(f”Mission: {os.environ[‘LANGCHAIN_PROJECT’]}n”)
executor = build_agent()
for query in TEST_QUESTIONS:
print(f”Q: {query}”)
outcome = run_with_metadata(executor, query)
print(f”A: {outcome[‘output’]}n”)
print(“Achieved. Open LangSmith to examine the complete hint tree for every run.”)
if __name__ == “__main__”:
primary()
LangSmith routinely connects to LangChain’s callback system with out the necessity for decorators or wrappers to see every run seem in your mission dashboard.
What you’ll see on the dashboard:
LangSmith’s hint view exhibits the complete agent execution tree, from the preliminary name to device use, LLM responses, and remaining output. Every node contains inputs, outputs, and latency.
You possibly can tag runs, add metadata, filter by final result, save runs as datasets, and run evaluations. That is helpful when bettering prompts or retrieval logic.
The immediate playground is one other sturdy function. You possibly can open any hint, edit the immediate inline, and rerun it to debug poor LLM efficiency.
LangSmith’s limitations seem at scale. The free tier has caps, and integration takes extra effort if you’re not utilizing LangChain, although OpenTelemetry is supported.
Langfuse: Open Supply and Framework-Agnostic
Langfuse is the open-source various right here. You possibly can both host it in your server, or use their cloud service. It additionally integrates with all frameworks like LangChain, LlamaIndex, uncooked OpenAI APIs, and so forth.
# Learn this Doc-string for putting in the dependencies and their setup
“””
Langfuse observability demo.
Setup:
pip set up langfuse
Set LANGFUSE_PUBLIC_KEY, LANGFUSE_SECRET_KEY in your .env file.
LANGFUSE_HOST defaults to https://cloud.langfuse.com; override for self-hosted.
Key variations from LangSmith:
– Callback handler is handed per-invoke for extra express management.
– Native session grouping for multi-turn conversations.
– You possibly can rating any hint after the very fact through the Langfuse consumer.
“””
import os
from dotenv import load_dotenv
from langfuse import Langfuse
from langfuse.callback import CallbackHandler
from agent_base import TEST_QUESTIONS, build_agent
load_dotenv()
def build_handler(
session_id: str,
user_id: str = “demo-user”,
) -> CallbackHandler:
return CallbackHandler(
public_key=os.environ[“LANGFUSE_PUBLIC_KEY”],
secret_key=os.environ[“LANGFUSE_SECRET_KEY”],
host=os.getenv(“LANGFUSE_HOST”, “https://cloud.langfuse.com”),
session_id=session_id,
user_id=user_id,
metadata={“supply”: “langfuse_demo”},
tags=[“observability-blog”, “demo”],
)
def score_trace(
trace_id: str,
rating: float,
remark: str = “”,
):
“””Add a correctness rating to a hint after reviewing the output.”””
lf = Langfuse(
public_key=os.environ[“LANGFUSE_PUBLIC_KEY”],
secret_key=os.environ[“LANGFUSE_SECRET_KEY”],
host=os.getenv(“LANGFUSE_HOST”, “https://cloud.langfuse.com”),
)
lf.rating(
trace_id=trace_id,
title=”correctness”,
worth=rating,
remark=remark,
)
lf.flush()
print(f”Scored hint {trace_id}: {rating}”)
def run_single_session(
executor,
session_id: str,
):
“””Run all take a look at questions in a single session so that they’re linked within the UI.”””
handler = build_handler(session_id=session_id)
trace_ids = []
for query in TEST_QUESTIONS:
print(f”Q: {query}”)
outcome = executor.invoke(
{“enter”: query},
config={“callbacks”: [handler]},
)
print(f”A: {outcome[‘output’]}n”)
# handler.get_trace_id() returns the hint ID for the final run.
trace_ids.append(handler.get_trace_id())
# Flush ensures traces are despatched earlier than the method exits.
# That is essential in batch jobs.
handler.flush()
return trace_ids
def primary():
print(“=== Langfuse Demo ===”)
print(f”Dashboard: {os.getenv(‘LANGFUSE_HOST’, ‘https://cloud.langfuse.com’)}n”)
executor = build_agent()
session_id = “demo-session-001”
trace_ids = run_single_session(executor, session_id)
# Instance: programmatically rating the primary hint.
if trace_ids and trace_ids[0]:
print(“nScoring first hint for example:”)
score_trace(trace_ids[0], rating=0.9, remark=”Reply was correct”)
print(f”nDone. Discover all runs below session ‘{session_id}’ in your Langfuse dashboard.”)
if __name__ == “__main__”:
primary()
You possibly can go callback handlers each run, which is somewhat bit extra express than LangSmith is, however gives better flexibility since you’ll be able to assign consumer IDs, session IDs, and customized metadata while you invoke it.
Analysis Workflow
Langfuse has a extremely good analysis workflow as effectively; you’ll be able to add scores after the hint has been accomplished.
from langfuse import Langfuse
lf = Langfuse()
# Rating a particular hint by ID.
lf.rating(
trace_id=”trace-abc123″,
title=”correctness”,
worth=0.9,
remark=”Reply was correct however barely verbose”,
)
This works together with human evaluations of the responses your staff scores, permitting you to get aggregated analysis metrics over time.
Customers can set up their classes by connecting them, so brokers can simply observe conversations throughout a number of turns. All of the traces in a person consumer session are linked within the utility, which lets you observe a complete dialog in a single place.
Arize: Manufacturing-Grade ML Observability
Initially developed as a platform for monitoring standard machine studying fashions, Arize is now able to observing each language fashions and brokers. The truth that it was initially created to assist groups deploy fashions into manufacturing at scale has remained intact.
Using OpenInference
Along with utilizing the OpenInference normal as its measurement scheme, Arize integrates with OpenTelemetry for instrumentation. Configuring Arize is extra difficult than it’s for many suppliers.
# Learn this Doc-string for putting in the dependencies and their setup
“””
Arize observability demo.
Setup:
pip set up arize-otel openinference-instrumentation-langchain
Set ARIZE_SPACE_ID and ARIZE_API_KEY in your .env file.
Key variations from the others:
– Makes use of OpenTelemetry below the hood, so it integrates with current OTel stacks.
– Instrumentation is international like LangSmith, not per-invoke like Langfuse.
– Finest-in-class manufacturing monitoring: drift detection, cohort evaluation, alerting.
– Phoenix, arize-phoenix, is the free native sibling for improvement use.
“””
import os
from arize.otel import register
from dotenv import load_dotenv
from openinference.instrumentation.langchain import LangChainInstrumentor
from agent_base import TEST_QUESTIONS, build_agent
load_dotenv()
def setup_arize_tracing():
“””Register Arize because the OTel tracer supplier and instrument LangChain globally.”””
tracer_provider = register(
space_id=os.environ[“ARIZE_SPACE_ID”],
api_key=os.environ[“ARIZE_API_KEY”],
project_name=”agent-observability-demo”,
)
LangChainInstrumentor().instrument(tracer_provider=tracer_provider)
return tracer_provider
def run_with_attributes(
executor,
query: str,
user_segment: str = “normal”,
):
“””Run the agent and fix span attributes for cohort evaluation in Arize.”””
from opentelemetry import hint
tracer = hint.get_tracer(__name__)
with tracer.start_as_current_span(“agent_run”) as span:
span.set_attribute(“consumer.phase”, user_segment)
span.set_attribute(“question.textual content”, query)
span.set_attribute(“demo.supply”, “arize_demo”)
outcome = executor.invoke({“enter”: query})
span.set_attribute(“response.textual content”, outcome[“output”])
return outcome
def primary():
print(“=== Arize Demo ===”)
print(“Traces will seem at: https://app.arize.com”)
print(“Mission: agent-observability-demon”)
setup_arize_tracing()
executor = build_agent()
# Simulate two consumer segments to exhibit cohort evaluation in Arize.
segments = [“premium”, “standard”, “standard”]
for query, phase in zip(TEST_QUESTIONS, segments):
print(f”Q: {query} [segment={segment}]”)
outcome = run_with_attributes(
executor,
query,
user_segment=phase,
)
print(f”A: {outcome[‘output’]}n”)
print(“Achieved. In Arize, use the cohort filter to check premium vs normal responses.”)
print(“Arrange screens on the Arize dashboard to alert on response high quality drift.”)
if __name__ == “__main__”:
primary()
The instrumentation is international like that of LangSmith, but it surely turns into a part of OpenTelemetry’s general measurement framework. Subsequently, Arize can make the most of the prevailing observability stack of your group whatever the precise framework you utilize (i.e., Jaeger, Grafana, and so forth.).
Which Ought to You Choose for Agent Observability?
To be fully open, there isn’t any single proper device for all use instances; all of it is determined by the place you might be within the improvement cycle and what your staff wants.
Function
LangSmith
Langfuse
Arize
Setup complexity
Minimal (2 env vars)
Low (callback handler)
Most boilerplate
Framework help
LangChain-native; others through OTel
Any framework
Any framework through OTel
Self-hosting
Restricted
First-class (Docker Compose)
Phoenix solely (native dev)
Hint visualization
Wonderful tree view
Good, session-linked
Good, OTel-standard
Analysis / scoring
Dataset + playground
Session-level human scores
Rubric-based evals
Manufacturing monitoring
Primary
Primary
Drift, alerting, cohorts
Multi-turn / classes
Thread-level
Native session grouping
Hint-level solely
Open supply
Proprietary
Absolutely open supply
Phoenix is OSS; platform isn’t
Free tier
Restricted traces/month
Beneficiant (self-host = limitless)
Restricted
Finest for
LangChain dev & iteration
Knowledge possession + any framework
Manufacturing-scale monitoring
Use LangSmith if you’re constructing with LangChain and need the quickest setup for immediate debugging and iteration.
Use Langfuse for those who want self-hosting, stronger knowledge possession, multi-framework help, or session-level monitoring for conversational brokers.
Use Arize when your agent is shifting into manufacturing and also you want monitoring, drift detection, cohorts, and alerts.
Conclusion
Agent observability is a kind of stuff you solely remorse skipping after one thing goes fallacious in manufacturing. Tracing an agent run after the very fact, with none instrumentation is like debugging a distributed system with print statements.
All three instruments coated listed below are manufacturing prepared. They every have a free path in. And so they every take below half-hour to combine with a LangChain agent. There’s no good purpose to ship an unobservable agent anymore.
Choose the device that matches your present stage. Add scoring early, even informally. And when your agent begins doing one thing bizarre at 2am, you’ll be glad you probably did.

Knowledge Science Trainee at Analytics VidhyaI am presently working as a Knowledge Science Trainee at Analytics Vidhya, the place I give attention to constructing data-driven options and making use of AI/ML strategies to resolve real-world enterprise issues. My work permits me to discover superior analytics, machine studying, and AI functions that empower organizations to make smarter, evidence-based choices.With a powerful basis in laptop science, software program improvement, and knowledge analytics, I’m captivated with leveraging AI to create impactful, scalable options that bridge the hole between know-how and enterprise.📩 You too can attain out to me at [email protected]
Login to proceed studying and revel in expert-curated content material.
Maintain Studying for Free