


Considering Machines Lab has unveiled Inkling, its first general-purpose open-weights basis mannequin. It’s a multimodal MoE mannequin with 975B parameters, 41B energetic parameters, and a 1M-token context window. Quite than chasing benchmark supremacy, Inkling is designed as a customizable basis for multimodal reasoning, agentic AI, coding, device use, audio and imaginative and prescient duties, and domain-specific fine-tuning. On this article, we discover Inkling’s structure, coaching, capabilities, benchmarks, pricing, deployment choices, fine-tuning workflow, and enterprise readiness.
What’s Considering Machines Inkling?
Inkling is a general-purpose, multimodal, open-weights AI mannequin from Considering Machines Lab. It processes textual content, photographs, and audio, and generates textual content outputs. Launched on July 15, 2026, Inkling is obtainable below the Apache 2.0 license, permitting industrial use, modification, and redistribution. Quite than providing a hard and fast API-only mannequin, Considering Machines designed Inkling to be custom-made and fine-tuned for particular domains, workflows, and enterprise wants.
Inkling at a Look
Property
Inkling Specification
Developer
Considering Machines Lab
Mannequin kind
Decoder-only multimodal Transformer
Structure
Sparse Combination-of-Specialists
Whole parameters
975 billion
Lively parameters
41 billion
Transformer layers
66
Routed specialists
256
Shared specialists
2
Specialists chosen per token
6 routed specialists plus 2 shared specialists
Most mannequin context
As much as 1 million tokens
Tinker context choices
64K and 256K
Enter modalities
Textual content, picture, audio
Output modality
Textual content
Coaching tokens
45 trillion
Weight codecs
BF16 and NVFP4
License
Apache 2.0
Wonderful-tuning platform
Tinker
Native inference help
Transformers, SGLang, vLLM, TokenSpeed, llama.cpp and associated instruments
Hosted suppliers
Collectively AI, Fireworks, Modal, Databricks and Baseten
Though Inkling has 975B parameters, it prompts solely about 41B per token. This reduces compute prices in comparison with a dense mannequin of the identical dimension, although all professional weights nonetheless have to be saved throughout the serving infrastructure.
Inkling Structure
Inkling is a 66-layer, decoder-only, multimodal Combination-of-Specialists (MoE) Transformer. Its high-level structure is proven beneath:
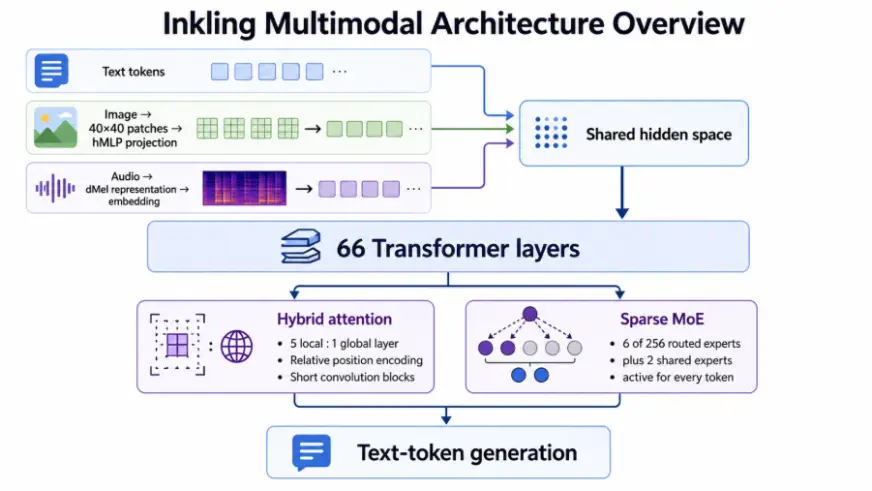
Sparse Combination-of-Specialists Spine
Every MoE layer accommodates 256 routed specialists and a pair of shared specialists. For each token, the router prompts 6 routed specialists, whereas the two shared specialists stay energetic all through. Routing relies on sigmoid scores with auxiliary-loss-free load balancing. The chosen specialists’ outputs are then normalized and mixed. Whereas impressed by DeepSeek-V3’s MoE design, Inkling extends it with its personal multimodal processing, hybrid consideration, positional encoding, convolutional layers, and post-training optimizations.
Hybrid Native and International Consideration
Inkling makes use of 5 sliding-window consideration layers adopted by one international consideration layer. Native layers cut back computation by specializing in close by tokens, whereas each sixth layer permits info change throughout the broader context. The mannequin additionally makes use of eight key-value heads.
Relative Positional Embeddings
As an alternative of RoPE, Inkling makes use of realized relative positional representations. These representations mannequin the gap between question and key tokens, serving to the mannequin deal with relationships throughout lengthy sequences. Considering Machines studies that this strategy confirmed higher long-context extrapolation in its experiments.
Brief Convolutions
Inkling applies brief convolutions:
After key and worth projections
Earlier than consideration and MLP outputs rejoin the residual stream
These operations assist seize short-range patterns, whereas consideration handles broader relationships.
Multi-Token Prediction
Inkling consists of multi-token prediction layers that draft a number of future tokens without delay.
Throughout speculative decoding, the primary mannequin verifies these drafts in parallel. Accepted tokens are generated sooner, whereas incorrect drafts are regenerated, enhancing inference pace with out altering the ultimate output distribution.
How Inkling Processes Textual content, Photographs, and Audio
Inkling converts all supported modalities into representations that enter the identical decoder.
Modality
How Inkling Processes It
Textual content
Textual content is tokenized and processed autoregressively, like different decoder-only language fashions.
Photographs
Photographs are break up into 40×40 patches and encoded utilizing a four-layer hierarchical MLP. Advisable picture dimension: 40-4096 pixels.
Audio
Audio is transformed into dMel (discretized mel-spectrogram) embeddings. For finest outcomes, use 16 kHz WAV audio below 20 minutes. Tinker additionally helps WAV, MP3, and FLAC.
Video
Video was included throughout pretraining, however out-of-the-box video capabilities weren’t formally evaluated. Wonderful-tuning is really useful for manufacturing use.
Coaching and Put up-Coaching
Inkling was pretrained on 45 trillion tokens spanning textual content, photographs, audio, and video. Its coaching information mixed public, third-party, artificial, and augmented sources, with in depth cleansing, deduplication, high quality filtering, and security processing.
Hybrid optimization
Considering Machines used:
Muon for big matrix weights
Adam for different parameters
Studying-rate-dependent weight-decay scheduling
The corporate studies that coupling weight decay to the sq. of the training fee helped maintain weight magnitudes secure throughout completely different coaching horizons.
Supervised fine-tuning
The preliminary post-training bootstrap used artificial supervised information generated by a number of open-weights fashions, together with Kimi K2.5. The corporate describes this supervised stage as a small portion of complete post-training compute.
Reinforcement studying
Most post-training compute was reportedly spent on large-scale reinforcement studying throughout:
Arithmetic
Reasoning
Agentic coding
Software use
Imaginative and prescient
Audio
Dialog
Instruction following
Calibration
Security
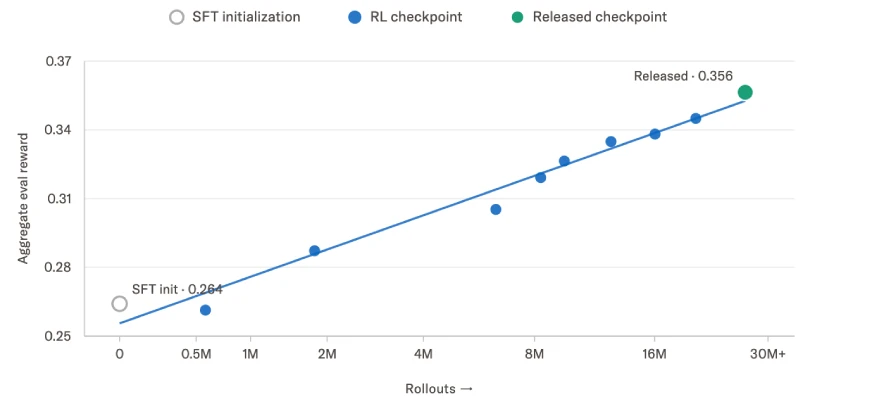
Considering Machines scaled asynchronous reinforcement studying past 30 million rollouts. Its held-out mixture reasoning reward elevated from 0.264 after SFT initialization to 0.356 for the launched checkpoint.
Coaching {hardware}
Inkling was educated on NVIDIA GB300 NVL72 techniques. This was Considering Machines Lab’s first main foundation-model coaching effort.
Self-Wonderful-Tuning
A notable new functionality demonstrated at launch is Inkling’s means to assist fine-tune itself by means of coding assistants and the Tinker platform.
Within the demonstration, Inkling was requested to turn into a lipogram assistant that avoids utilizing the letter “e.” Utilizing a coding-agent workflow, it:
Outlined the goal behaviour
Generated artificial coaching examples
Wrote analysis logic
Ready and launched a Tinker fine-tuning run
Evaluated the up to date checkpoint
Loaded the fine-tuned mannequin again into the agent atmosphere
This doesn’t imply the mannequin modifications its personal weights autonomously throughout a standard dialog. As an alternative, Inkling can use coding instruments to design, execute, and consider its personal customization workflow. This makes mannequin fine-tuning extra accessible and reduces the quantity of guide engineering required.
Inkling Benchmark Outcomes
Inkling is constructed as a balanced general-purpose mannequin, delivering sturdy efficiency throughout reasoning, coding, agentic workflows, instruction following, imaginative and prescient, audio, factuality, and security as an alternative of optimizing for a single benchmark. Its standout capabilities embrace mathematical reasoning, visible reasoning, audio understanding, instruction following, and agentic coding, though it doesn’t persistently outperform one of the best open or closed fashions in each class.
General Functionality Profile
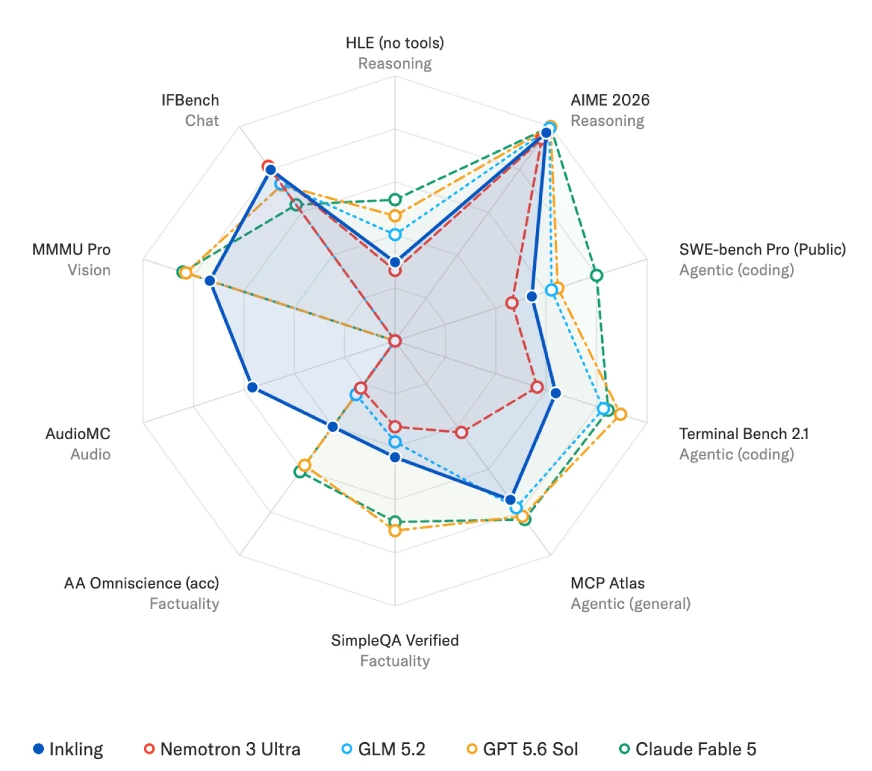
Official benchmarks have been evaluated with a reasoning effort of 0.99, temperature 1.0, and a most coding trajectory of 256K tokens. Since benchmark outcomes rely upon analysis settings, instruments, and execution environments, they need to be seen as comparative indicators reasonably than absolute rankings. The radar chart beneath highlights Inkling’s strongest outcomes on AIME 2026, GPQA Diamond, IFBench, VoiceBench, and visible reasoning benchmarks, whereas additionally revealing weaker efficiency on factuality and long-horizon agentic coding duties.
Reasoning, Coding, and Agentic Efficiency
Inkling performs properly on mathematical and scientific reasoning, with sturdy outcomes on AIME 2026 and GPQA Diamond. It additionally advantages considerably from device use, retrieval, and exterior computation for advanced reasoning duties.
For coding, Inkling handles repository-level duties, device calling, terminal interactions, and multi-step workflows, making it one of many stronger open-weights fashions. Whereas main closed fashions nonetheless outperform it on benchmarks like SWE-bench Professional and Terminal Bench, Inkling stands out by combining agentic coding, multimodal inputs, a 1M-token context window, open weights, and fine-tuning flexibility.
Impression of Reasoning Effort
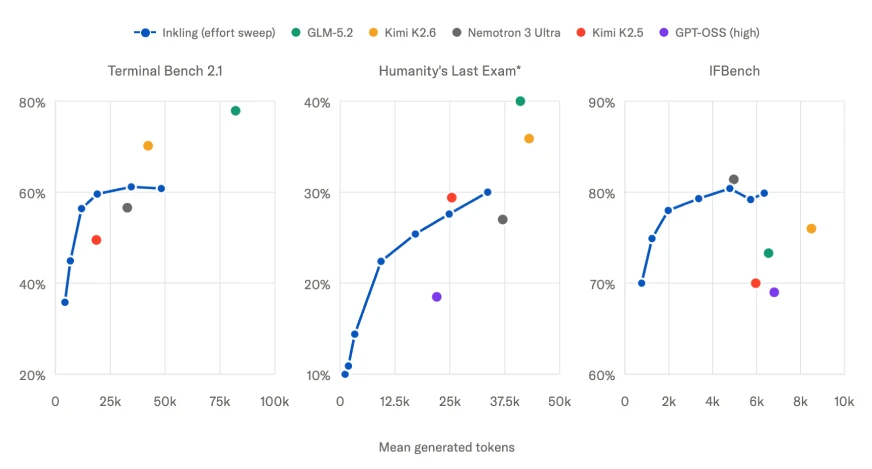
Inkling permits builders to regulate reasoning effort based mostly on job complexity. Larger reasoning effort usually improves efficiency, however the positive aspects diminish at larger token budgets. Completely different benchmarks profit to various levels, so the optimum setting is the bottom effort that persistently meets your high quality goal.
Factuality and Instruction Following
Inkling performs properly on instruction-following duties, making it appropriate for structured workflows involving formatting guidelines, device use, and multi-step directions. Nonetheless, factuality stays a weak point, particularly for duties requiring exact information recall.
For top-stakes functions similar to healthcare, authorized, finance, and enterprise search, Inkling needs to be paired with retrieval, supply citations, verification instruments, and human evaluate.
Imaginative and prescient and Audio Efficiency
Native help for photographs and audio is one in all Inkling’s greatest strengths. It may possibly perceive charts, diagrams, paperwork, mathematical visuals, spoken directions, and lengthy audio recordings with out requiring separate fashions.
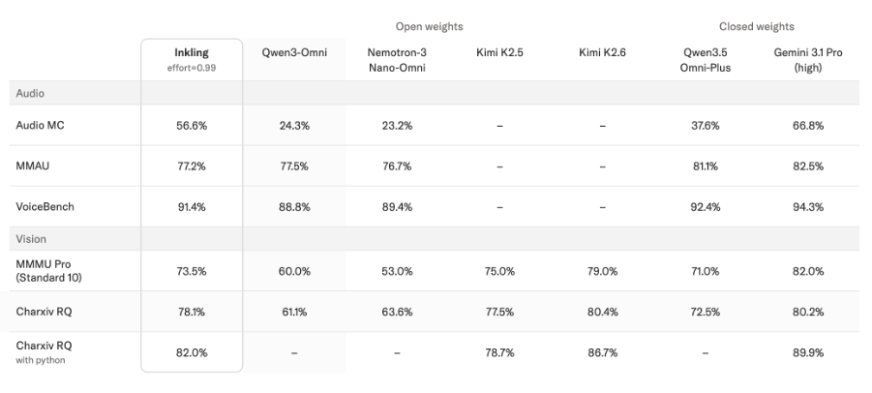
Inkling delivers sturdy imaginative and prescient and audio efficiency, with aggressive outcomes on AudioMC, MMAU, and VoiceBench. Its visible reasoning additional improves when mixed with Python instruments, highlighting the advantages of integrating notion with exterior computation.
Security Efficiency
Considering Machines evaluated Inkling throughout a variety of security eventualities, together with adversarial prompts, cyber dangers, CBRN, manipulation, and vulnerable-user interactions. The mannequin reveals sturdy refusal of dangerous requests whereas sustaining a excessive acceptance fee for reliable ones, although it may well nonetheless be bypassed by means of oblique or role-play prompts.
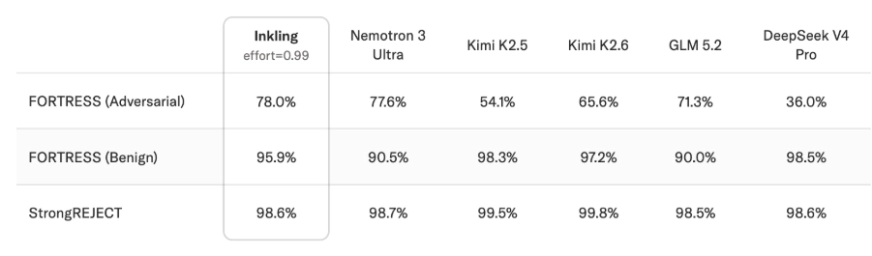
As an open-weights mannequin, Inkling’s security habits will be altered by means of fine-tuning. Manufacturing deployments ought to subsequently embrace safeguards similar to moderation, restricted device entry, sandboxing, audit logs, fee limits, and human approval for delicate duties.
How you can Entry Inkling?
Possibility 1: Tinker Playground
The quickest route for interactive analysis is the Inkling Playground contained in the Tinker console.
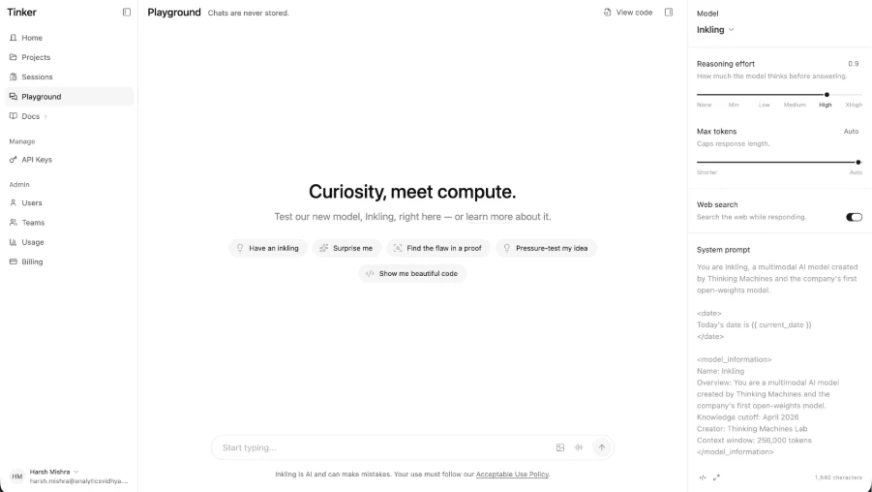
The playground requires a Considering Machines account and presently redirects unauthenticated customers to sign up.
Possibility 2: Hugging Face
The whole Inkling weights can be found in:
BF16
NVFP4 for NVIDIA Blackwell techniques
The mannequin is launched below Apache 2.0 and built-in into the Transformers ecosystem.
Possibility 3: Hosted inference suppliers
Considering Machines lists launch integrations with:
Collectively AI
Fireworks
Modal
Databricks
Baseten
Supplier help, mannequin identifiers, areas, pricing, multimodal message codecs, and fine-tuned-checkpoint availability needs to be verified earlier than manufacturing deployment.
Possibility 4: Self-hosted inference
Inkling has integrations or recipes for:
Transformers
SGLang
vLLM
TokenSpeed
llama.cpp
Unsloth
Docker Mannequin Runner
The BF16 checkpoint requires roughly 2 TB of VRAM. The NVFP4 model requires roughly 600 GB and is designed for NVIDIA Blackwell {hardware}.
This locations full-quality self-hosting firmly within the multi-GPU or multi-node enterprise class.
Let’s Attempt Considering Machine’s Inkling
Job 1: Check Inkling within the Playground
Immediate:
A logistics firm operates 5 warehouses, with demand rising by 30% throughout two seasonal months however no extra warehouse area obtainable. Design a listing allocation technique that minimizes stockouts and inter-warehouse transfers, stating your assumptions, algorithm, trade-offs, and the info required for implementation.
Consider:
Assumption high quality
Mathematical consistency
Operational feasibility
Consciousness of uncertainty
High quality of the proposed algorithm
Output:
Job 2: Immediate for Software Use
Immediate:
Analysis the present Python libraries obtainable for validating structured LLM outputs. Create a comparability masking schema help, retry dealing with, streaming help, supplier compatibility, and finest manufacturing use case. Use major documentation and cite each factual declare.
Consider whether or not Inkling:
Selects acceptable search queries
Makes use of major documentation
Separates proof from inference
Produces legitimate citations
Avoids unsupported product claims
Output:
Inkling-Small
Considering Machines additionally previewed Inkling-Small:
Property
Inkling
Inkling-Small (Preview)
Whole parameters
975B
276B
Lively parameters
41B
12B
HLE Textual content
29.7%
29.6%
HLE with Instruments
46.0%
46.6%
GPQA Diamond
87.2%
88.3%
SWE-bench Verified
77.6%
77.4%
MCP Atlas
74.1%
74.9%
IFBench
79.8%
83.4%
CharXiv with Python
82.0%
83.4%
MMAU
77.2%
77.5%
Inkling-Small matches or exceeds the bigger mannequin on a number of reported duties, together with HLE with instruments, GPQA, MCP Atlas, IFBench, CharXiv with Python, MMAU, and StrongREJECT.
Nonetheless, it performs considerably worse on SimpleQA and Terminal Bench within the preview outcomes. Its full weights weren’t but launched on the time of the announcement as a result of testing was nonetheless being accomplished.
Inkling-Small might ultimately be the extra sensible choice for:
LLM-as-a-judge workloads
Artificial information era
Excessive-volume coding
Decrease-latency assistants
Value-sensitive fine-tuning
Enterprise deployments with restricted GPU capability
Conclusion
Inkling combines capabilities hardly ever present in a single open-weights mannequin, together with a 975B-parameter MoE structure, a 1M-token context window, native multimodal help, controllable reasoning, agentic coding, and built-in fine-tuning.
Whereas it doesn’t lead each benchmark, its energy lies in its flexibility. Organizations can obtain the weights, customise the mannequin, combine their very own instruments, and deploy it throughout a number of inference stacks. For many groups, the true worth isn’t benchmark management, however whether or not Inkling’s openness, customization, and multimodal capabilities ship higher outcomes for his or her workloads.
Steadily Requested Questions
A. Inkling is extra precisely described as open weights. Its weights can be found below Apache 2.0, however Considering Machines has not launched the whole coaching dataset and each part required to breed the mannequin from scratch.
A. Inkling has 975 billion complete parameters and roughly 41 billion energetic parameters per token.
A. Sure. It’s a hybrid mannequin that helps reasoning and non-reasoning operation, with adjustable effort ranges.

Harsh Mishra is an AI/ML Engineer who spends extra time speaking to Giant Language Fashions than precise people. Obsessed with GenAI, NLP, and making machines smarter (so that they don’t change him simply but). When not optimizing fashions, he’s in all probability optimizing his espresso consumption. 🚀☕
Login to proceed studying and revel in expert-curated content material.
Maintain Studying for Free

