# Inroduction
This text is a part of my noob collection the place we write concerning the questions folks Google most however could not perceive nicely due to advanced math and every little thing. So, in case you are right here, you might need heard fine-tuning someplace within the context of huge language fashions (LLMs) particularly. This idea already existed in conventional machine studying for years, but it surely gained recognition after LLMs as a result of now out of the blue everybody has entry to those big, common pretrained fashions that you may adapt based mostly in your duties, your personal wants, and in your personal tone. This act of adapting is principally referred to as fine-tuning, and it’s now one of the frequent issues folks do with LLMs. However you can’t perceive it till you perceive the step that comes earlier than it, and that’s “pretraining.” Fantastic-tuning is actually “tuning” one thing that already exists, and that “one thing” is a pretrained mannequin. So, let’s attempt to break down these ideas in order that sooner or later, if somebody asks you about it, you realize it.
# What Is Pretraining?
In case you begin with a freshly created mannequin that has thousands and thousands or billions of parameters assigned random numbers, and also you attempt to train it a really particular activity immediately — to illustrate methods to classify films into totally different classes — it has to be taught your complete English language from scratch on the identical time, which is not possible, particularly from the restricted dataset you might need. It is rather like instructing a toddler biology earlier than they will perceive the language or fundamental science ideas first.
Pretraining solves this downside by studying the exhausting and common stuff as soon as from a large quantity of information. The compute and information necessities are fairly excessive at this stage. However when you practice it, you should have a mannequin that already understands language. Throughout this stage, you train it a quite simple ability: predicting the subsequent phrase. You present the mannequin a bit of textual content with the subsequent phrase hidden, and it has to guess what comes subsequent. Good guesses get a small loss, dangerous guesses get a giant one, and the mannequin adjusts.
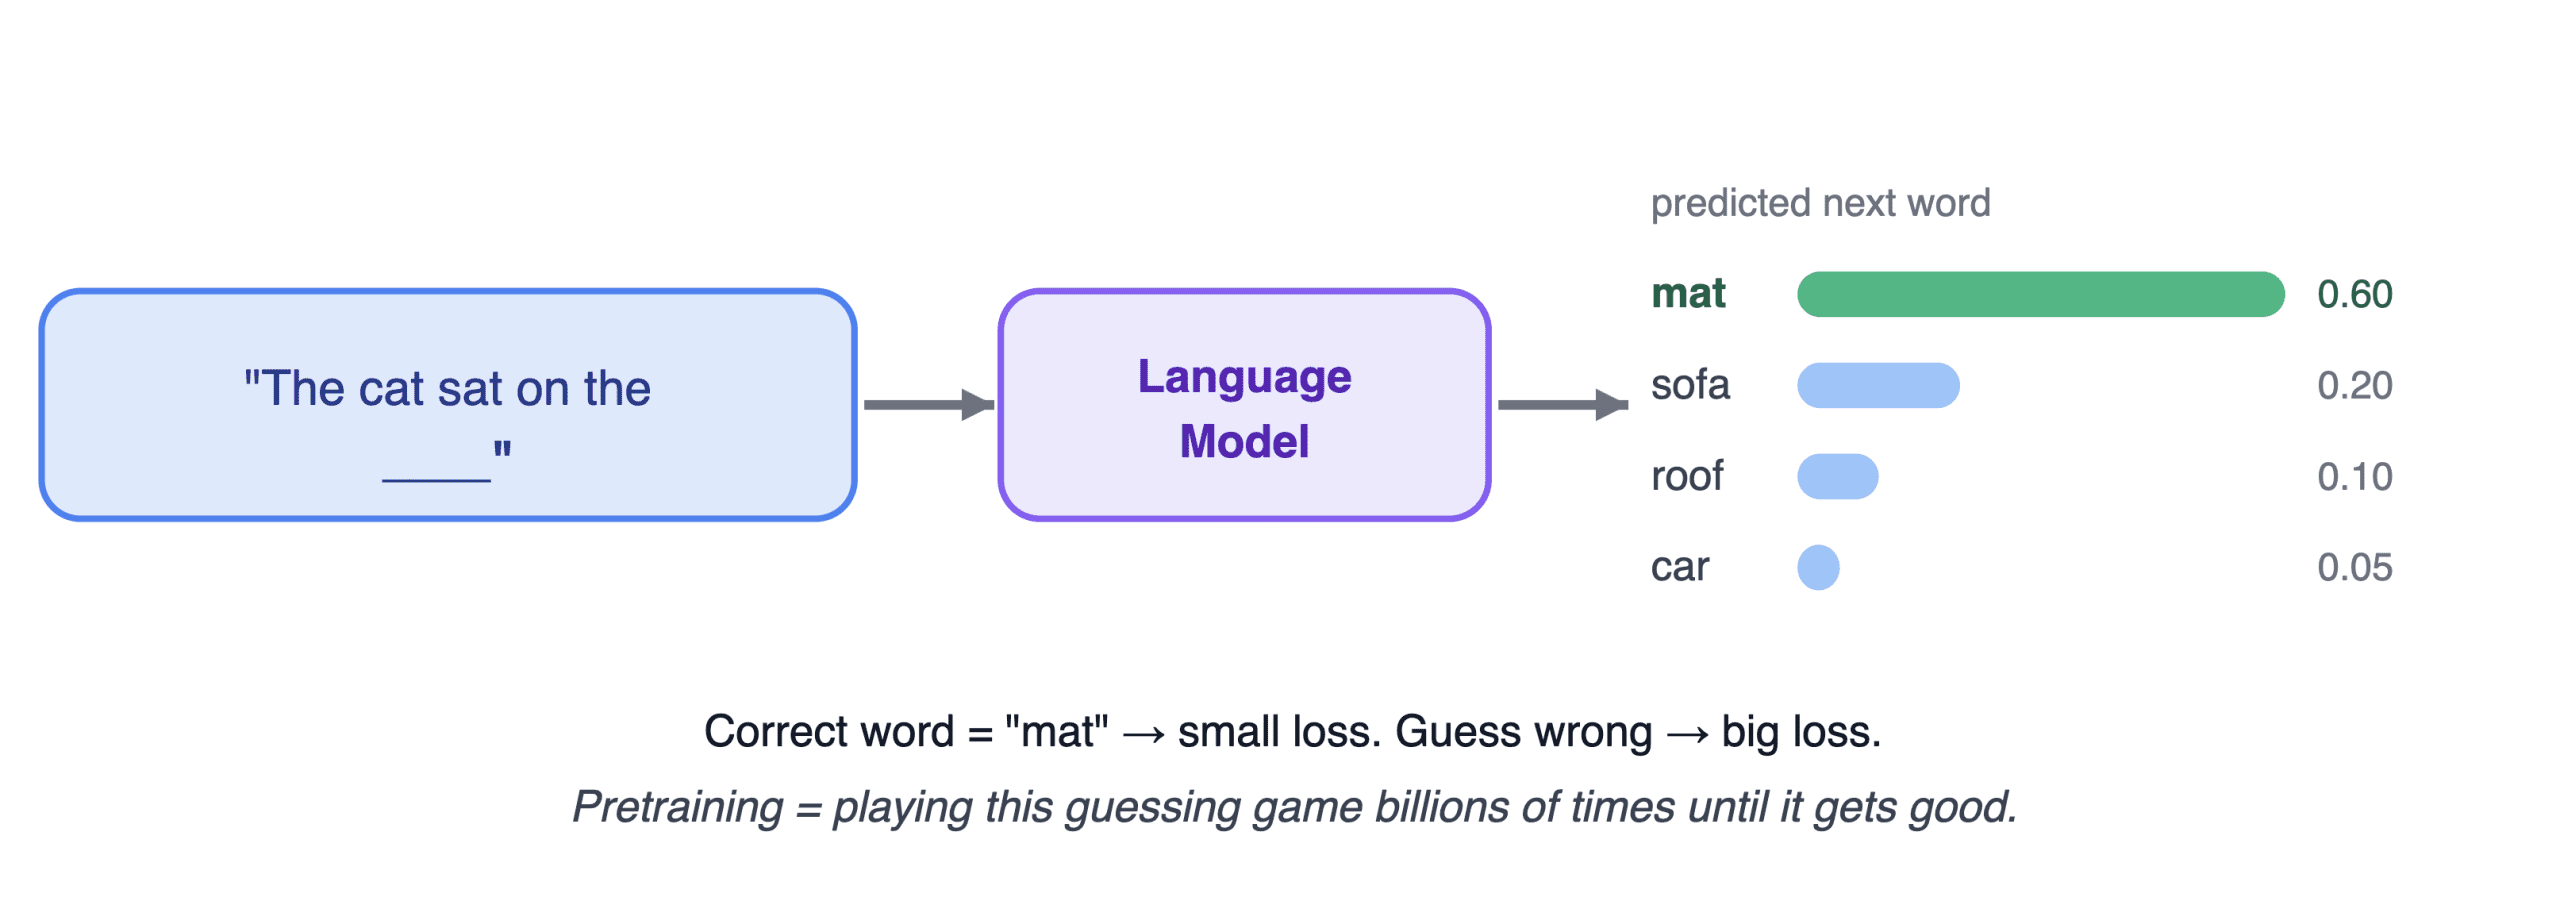
For instance, within the above diagram, if we give the sentence “The cat sat on the ____”, the mannequin learns that “mat” is much extra possible than “automotive”. Repeating this coaching throughout billions of sentences, books, and articles makes the mannequin an excellent next-word predictor and forces it to soak up grammar, details, reasoning patterns, and extra. After pretraining, you’ve gotten a mannequin that already understands language. Each activity you construct later will get to face on high of that basis as a substitute of ranging from zero. That can be why these are sometimes referred to as basis fashions.
You virtually by no means pretrain something your self. You obtain the completed outcome — a pretrained mannequin like Llama, Mistral, or Qwen — and begin from there. This brings us to our precise subject of fine-tuning.
# What Is Fantastic-Tuning?
Numerous novices assume that when a mannequin has been educated, the weights are frozen perpetually. In actuality, having a pretrained mannequin means the weights have been set to “good values” that encode intelligence and carry out nicely at common duties. Upon getting this mannequin, you may adapt that intelligence to your particular wants utilizing task-specific information — and that is referred to as “fine-tuning.” The information necessities at this stage are additionally a lot decrease than pretraining, because you solely want examples for the duty you have an interest in.
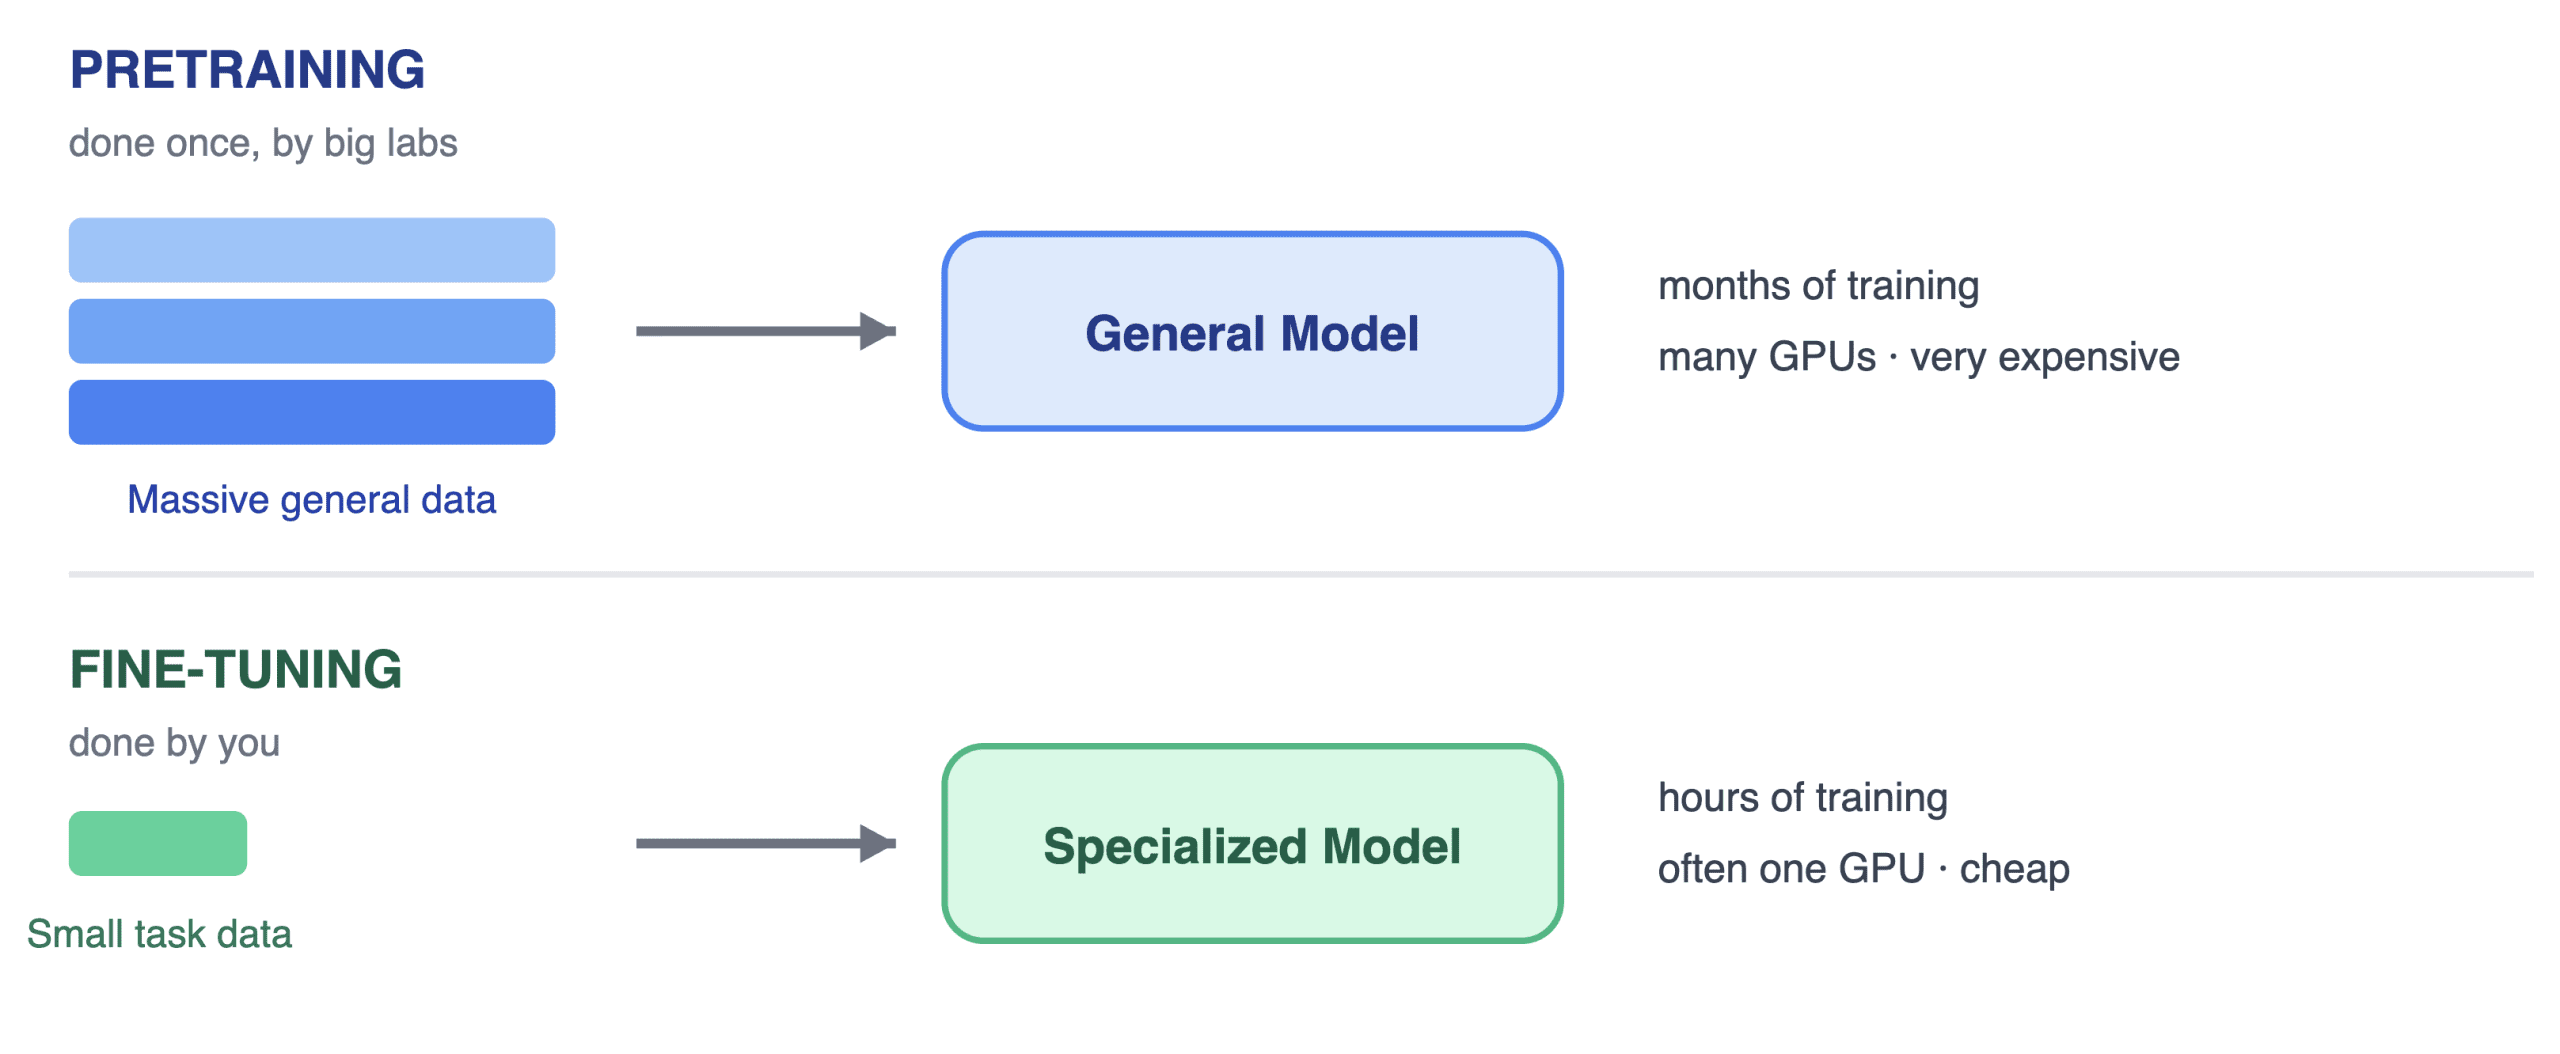
It is vitally just like how totally different cooks are educated on the identical culinary college, after which once they be a part of a restaurant, they be taught restaurant-specific expertise. Since we aren’t constructing one thing from scratch right here, it’s cheaper — just like the concept coaching a very new particular person for a restaurant requires way more effort than coaching somebody who has already attended culinary college. The diagram beneath sums up the distinction between pretraining and fine-tuning.
# How Is Fantastic-Tuning Completed?
We mentioned next-token prediction and the method of pretraining. Now, let’s check out the fine-tuning loop.

You present the mannequin an instance of task-specific information — to illustrate a film — ask it to categorize the film and make a guess, then evaluate its reply to the perfect one, nudge the weights a bit, and repeat the method till it will get higher on the downstream activity. There are additionally two main issues performed otherwise in fine-tuning in comparison with pretraining:
Information → Small, high-quality, task-specific information as a substitute of your complete web.
Studying Price → A small studying charge and few passes, as a result of we would like the mannequin to adapt with out overwriting its common expertise.
# Two Widespread Varieties of Fantastic-Tuning
Although one can find totally different definitions throughout the web, based mostly on the variety of mannequin parameters you wish to tune or adapt, fine-tuning broadly falls into two classes:

Full Fantastic-Tuning: On this setting, each parameter in your mannequin is free to vary. You run the loop above and all the billions of numbers shift just a little towards your activity. The principle downside with this method is reminiscence — you want sufficient to carry and replace your complete mannequin, which for a big LLM means critical {hardware}. There may be additionally extra danger of catastrophic forgetting, which merely means the mannequin turns into good on the particular activity however loses its common skills on every little thing else.
Parameter-Environment friendly Fantastic-Tuning (PEFT): As an alternative of updating each weight within the community, PEFT strategies freeze the bottom mannequin — each authentic quantity stays locked — and introduce a small set of brand-new, trainable numbers, coaching solely these. There are totally different strategies to attain this, comparable to LoRA, QLoRA, and immediate tuning, however the particulars of these are past the scope of this text. PEFT requires much less reminiscence and coaching time, with a decrease danger of forgetting already-learned information. For many LLM fine-tuning, that is the default alternative.
# Is Fantastic-Tuning All the time the Reply?
Fantastic-tuning is great at instructing fashions a brand new ability, type, habits, or activity, however it’s not the one device — and infrequently not the primary one it’s best to attain for. A greater immediate can typically resolve your downside with none coaching in any respect. Equally, when it makes extra sense to lookup data both on-line or in a database at question time, retrieval-augmented era (RAG) is a greater match, particularly when details are giant in quantity or change typically. These approaches will not be rivals; in observe, most methods use them collectively. Price retaining in thoughts earlier than you decide to a full fine-tuning run.
# Further Sources
If you wish to observe fine-tuning particularly with LoRA, listed below are some really helpful sources:
Hugging Face PEFT: The usual open-source library for LoRA, QLoRA, immediate tuning, and extra. Begin with the docs and the repo.
Hugging Face TRL: Pairs with PEFT and provides you a ready-made SFTTrainer for the supervised fine-tuning loop.
Unsloth: Probably the most beginner-friendly path to LoRA/QLoRA, with free Colab and Kaggle notebooks, ~2× sooner coaching, and far decrease VRAM.
Axolotl: As soon as you might be comfy, a well-liked config-driven (YAML) device for operating fine-tuning pipelines with out writing a lot code.
The unique LoRA paper: “LoRA: Low-Rank Adaptation of Giant Language Fashions.”
The QLoRA paper: “QLoRA: Environment friendly Finetuning of LLMs.”
For first mission, seize a small instruct mannequin (one thing like an 8B Llama, Qwen, or Gemma), open an Unsloth QLoRA pocket book, fine-tune it on a couple of hundred clear examples of your activity, and watch the coaching loss drop. Upon getting performed it as soon as, each time period on this article will really feel rather more concrete.
Kanwal Mehreen is a machine studying engineer and a technical author with a profound ardour for information science and the intersection of AI with medication. She co-authored the e-book “Maximizing Productiveness with ChatGPT”. As a Google Era Scholar 2022 for APAC, she champions variety and educational excellence. She’s additionally acknowledged as a Teradata Variety in Tech Scholar, Mitacs Globalink Analysis Scholar, and Harvard WeCode Scholar. Kanwal is an ardent advocate for change, having based FEMCodes to empower girls in STEM fields.