# Introduction
When you find yourself simply beginning out with knowledge evaluation, one of many first belongings you study is methods to clear a dataset. It sounds fundamental, but it surely is among the most essential abilities you’ll use many times.
The humorous half is that whilst knowledgeable, you’ll nonetheless spend numerous your time cleansing knowledge as a substitute of analyzing it, constructing fashions, or evaluating outcomes. Why? As a result of uncooked knowledge isn’t clear. It may possibly have lacking values, incorrect codecs, duplicate rows, messy strings, invalid dates, unusual classes, and noisy entries.
Earlier than you possibly can perceive what the information is telling you, you might want to repair these points.
On this information, we’ll clear a messy buyer CSV file utilizing Python and pandas. We’ll begin by loading and inspecting the information, then clear column names, deal with lacking values, take away duplicates, standardize textual content, convert knowledge varieties, validate emails, and save the ultimate clear CSV file.
# 1. Loading the CSV
Step one is to load the messy dataset into pandas.
df = pd.read_csv(“messy_customers.csv”, keep_default_na=False)
df
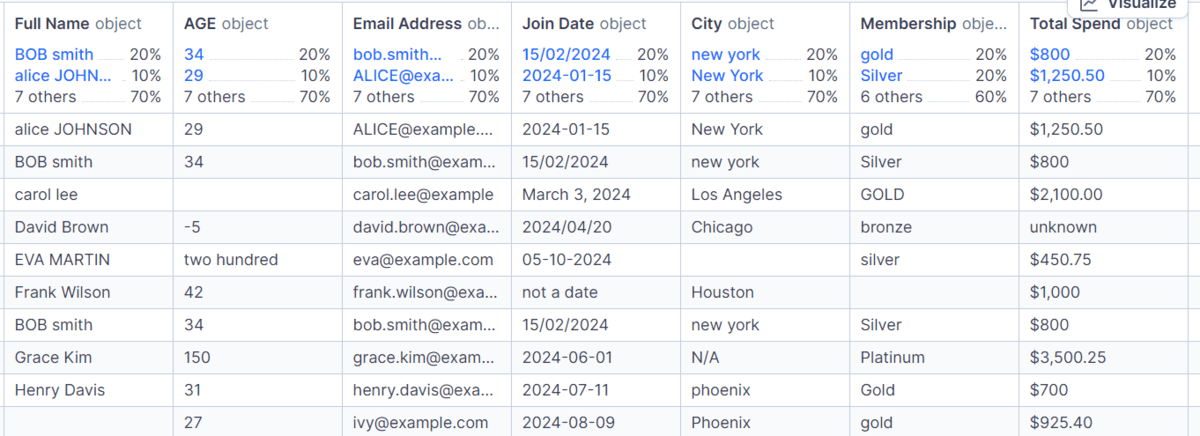
We’re utilizing a buyer CSV file that has frequent knowledge high quality points. As you possibly can already see, the file consists of messy column names, inconsistent textual content formatting, combined date codecs, lacking values, duplicate rows, and numbers saved as textual content.
# 2. Inspecting Earlier than Cleansing
Earlier than we begin cleansing, we have to perceive what is definitely contained in the dataset.
print(“nColumn names:”)
print(df.columns.tolist())
print(“nData varieties:”)
print(df.dtypes)
print(“nExact duplicate rows:”, df.duplicated().sum())
Output:
Column names:
[‘ Customer ID ‘, ‘ Full Name ‘, ‘AGE’, ‘ Email Address ‘, ‘Join Date’, ‘City’, ‘Membership’, ‘Total Spend’]
Knowledge varieties:
Buyer ID object
Full Identify object
AGE object
Electronic mail Deal with object
Be a part of Date object
Metropolis object
Membership object
Complete Spend object
dtype: object
Precise duplicate rows: 1
This offers us a fast overview of the dataset earlier than making any modifications.
We will see that the dataset has 10 rows and eight columns. The column names are messy as a result of a few of them have additional areas and inconsistent casing. We will additionally see that each column is saved as an object, which often means pandas is treating them as textual content.
The duplicate examine additionally exhibits that there’s 1 precise duplicate row. That is helpful to know early as a result of duplicate information can have an effect on the ultimate evaluation.
# 3. Cleansing the Column Names
Now that we all know the column names are messy, we’ll clear them first.
df.columns
.str.strip()
.str.decrease()
.str.change(r”s+”, “_”, regex=True)
)
df.columns.tolist()
Output:
‘full_name’,
‘age’,
’email_address’,
‘join_date’,
‘city’,
‘membership’,
‘total_spend’]
This step removes additional areas from the column names, converts every thing to lowercase, and replaces areas with underscores.
Now the column names are a lot simpler to work with. As an alternative of writing names with areas like Electronic mail Deal with, we will merely use email_address. This makes the code cleaner and helps keep away from small errors later.
# 4. Changing Clean Strings and Placeholders
Subsequent, we’ll change clean values and customary placeholders with correct lacking values.
df = df.change(
[“N/A”, “n/a”, “NA”, “unknown”, “not a date”],
pd.NA,
)
df.isna().sum()
Output:
full_name 1
age 1
email_address 0
join_date 1
metropolis 2
membership 1
total_spend 1
dtype: int64
Actual-world CSV information typically present lacking knowledge in several methods. Some cells are clean, some use N/A, and a few use values like unknown or not a date.
We convert all of those into correct lacking values so pandas can detect them appropriately. After this step, it turns into simpler to rely, fill, or take away lacking values later.
# 5. Eradicating Duplicate Rows
Now we’ll take away precise duplicate rows from the dataset.
df = df.drop_duplicates().copy()
print(“Rows after:”, len(df))
Output:
Rows after: 9
Duplicate rows can create issues in your evaluation as a result of the identical document could also be counted greater than as soon as.
Right here, we had 10 rows earlier than eradicating duplicates and 9 rows after. This implies one precise duplicate row was faraway from the dataset.
# 6. Cleansing Textual content Columns
Now we’ll clear the text-based columns so the values are extra constant.
for column in text_columns:
df[column] = df[column].astype(“string”).str.strip()
df[“full_name”] = (
df[“full_name”]
.str.change(r”s+”, ” “, regex=True)
.str.title()
)
df[“city”] = df[“city”].str.title()
df[“membership”] = df[“membership”].str.decrease()
df[“email_address”] = df[“email_address”].str.decrease()
df[text_columns]

Textual content columns often want additional cleansing as a result of folks write the identical sort of knowledge in several methods.
On this step, we take away additional areas from customer_id, full_name, email_address, metropolis, and membership. Then we clear the formatting so names and cities use title case, whereas emails and membership values use lowercase.
This makes the dataset simpler to learn and in addition helps us keep away from class points later. For instance, Gold, GOLD, and gold ought to all be handled as the identical membership worth.
# 7. Standardizing Classes
Now we’ll clear the membership column so it solely accommodates legitimate classes.
df.loc[~df[“membership”].isin(allowed_memberships), “membership”] = pd.NA
df[“membership”].value_counts(dropna=False)
Output:
gold 4
silver 2
2
bronze 1
Identify: rely, dtype: Int64
This step makes positive that the membership column solely accommodates the values we count on.
On this dataset, the legitimate membership varieties are bronze, silver, and gold. Any worth outdoors these classes, resembling platinum, is changed with a lacking worth so we will deal with it later.
# 8. Changing Age to a Quantity
Subsequent, we’ll convert the age column from textual content to numbers.
df.loc[~df[“age”].between(0, 120), “age”] = pd.NA
df[“age”] = df[“age”].astype(“Int64”)
df[[“full_name”, “age”]]

The age column was saved as textual content, so we have to convert it right into a numeric column earlier than utilizing it for evaluation.
We additionally take away values that don’t make sense, resembling detrimental ages or ages above 120. Any invalid age is was a lacking worth, which we’ll repair later.
# 9. Changing Combined Date Codecs
Now we’ll clear the join_date column.
df[“join_date”],
format=”combined”,
dayfirst=True,
errors=”coerce”,
)
df[[“full_name”, “join_date”]]
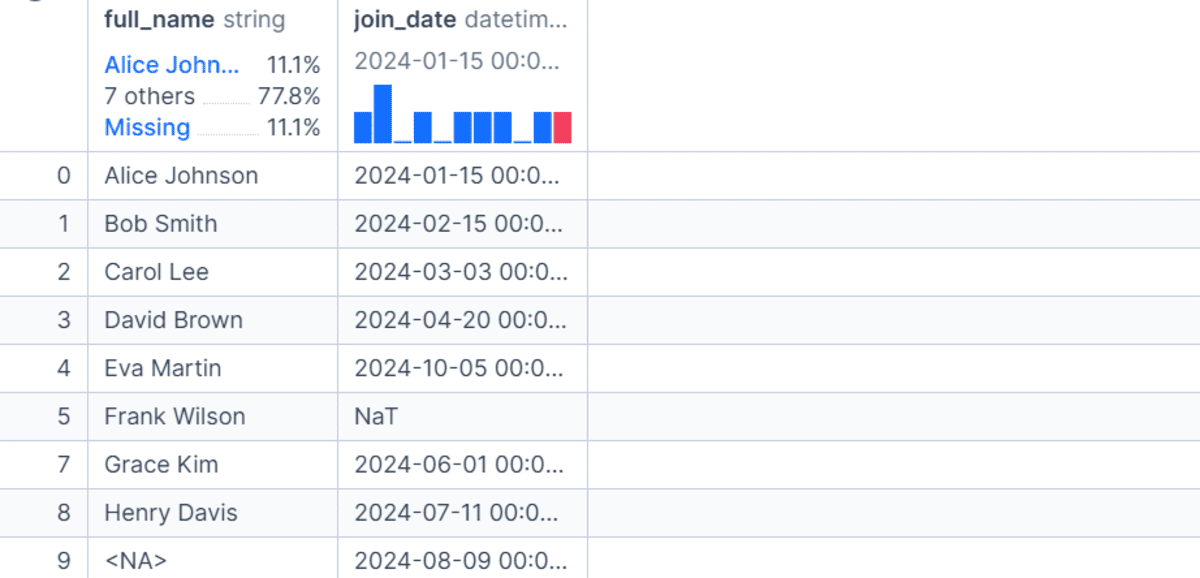
Dates are sometimes messy in CSV information as a result of they will seem in several codecs.
This step converts the join_date column into a correct datetime column. We use “combined” as a result of the dates on this file don’t all comply with the identical format. Any invalid date is transformed right into a lacking worth.
# 10. Cleansing Forex Values
Subsequent, we’ll clear the total_spend column.
df[“total_spend”]
.astype(“string”)
.str.change(r”[^0-9.-]”, “”, regex=True)
)
df[“total_spend”] = pd.to_numeric(df[“total_spend”], errors=”coerce”)
df[[“full_name”, “total_spend”]]
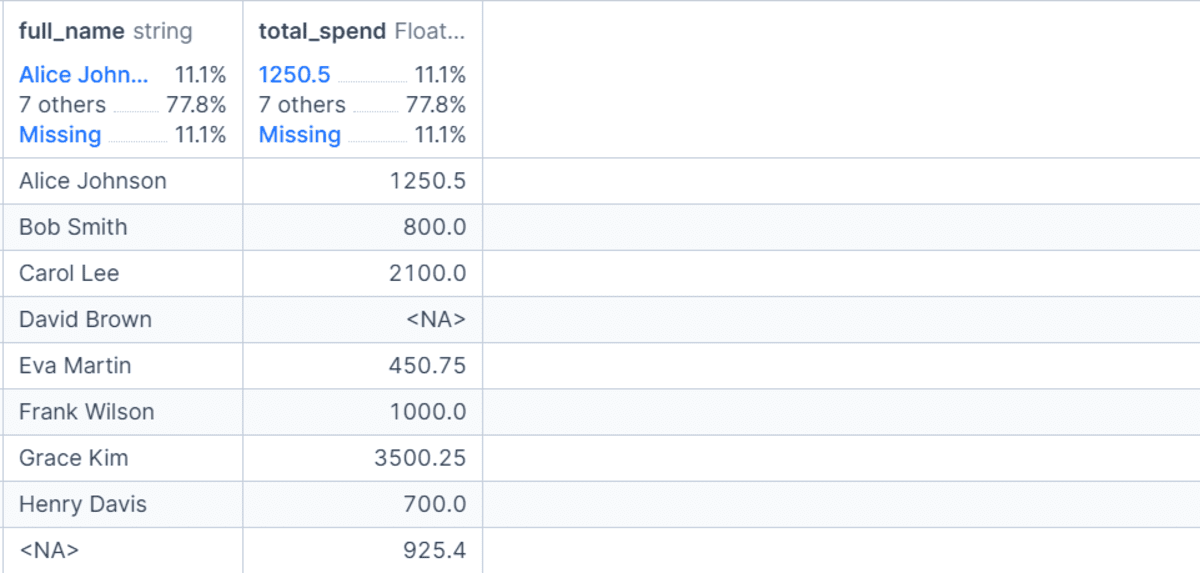
The total_spend column accommodates foreign money symbols, commas, and textual content values, so pandas can’t deal with it as a quantity but.
This step removes every thing besides numbers, decimal factors, and minus indicators. Then we convert the column right into a numeric worth so we will calculate totals, averages, and different helpful metrics.
# 11. Validating Electronic mail Addresses
Now we’ll examine whether or not the e-mail addresses have a legitimate format.
valid_email = df[“email_address”].str.match(email_pattern, na=False)
df.loc[~valid_email, “email_address”] = pd.NA
df[[“full_name”, “email_address”]]
This can be a easy electronic mail validation step.

It checks whether or not every electronic mail has the fundamental construction of an electronic mail handle. If an electronic mail is clearly invalid, we change it with a lacking worth. This helps maintain the email_address column cleaner and extra dependable.
# 12. Dealing with Lacking Values
Now we’ll resolve what to do with the remaining lacking values.
df[“full_name”] = df[“full_name”].fillna(“Unknown”)
df[“city”] = df[“city”].fillna(“Unknown”)
df[“membership”] = df[“membership”].fillna(“unassigned”)
median_age = int(df[“age”].median())
df[“age”] = df[“age”].fillna(median_age)
df[“total_spend”] = df[“total_spend”].fillna(0.0)
print(“Median age used:”, median_age)
df.isna().sum()
Output:
customer_id 0
full_name 0
age 0
email_address 1
join_date 1
metropolis 0
membership 0
total_spend 0
dtype: int64
For this dataset, we take away rows the place customer_id is lacking as a result of it’s the major identifier for every buyer.
For the opposite columns, we use smart replacements. Lacking names and cities turn into Unknown, lacking membership values turn into unassigned, lacking ages are stuffed with the median age, and lacking spending values are stuffed with 0.0.
We nonetheless have lacking values in email_address and join_date, and that’s okay. Generally it’s higher to maintain lacking values as a substitute of forcing a worth that is probably not appropriate.
# 13. Checking the Cleaned Knowledge
Earlier than saving the ultimate file, we must always examine that the cleaned dataset follows the principles we count on.
assert df[“customer_id”].notna().all()
assert df[“customer_id”].is_unique
assert df[“age”].between(0, 120).all()
assert df[“total_spend”].ge(0).all()
assert df[“membership”].isin(final_memberships).all()
print(“All validation checks handed.”)
Output:
These checks assist us verify that the essential cleansing steps labored.
We’re checking that each buyer has an ID, buyer IDs are distinctive, ages are legitimate, whole spend isn’t detrimental, and membership values are solely from the ultimate accredited checklist. If all checks go, we will really feel extra assured utilizing this cleaned dataset.
# 14. Reviewing the Ultimate Consequence
Now we will evaluate the cleaned dataset and ensure every thing seems to be appropriate.
At this stage, the information is way cleaner than earlier than.
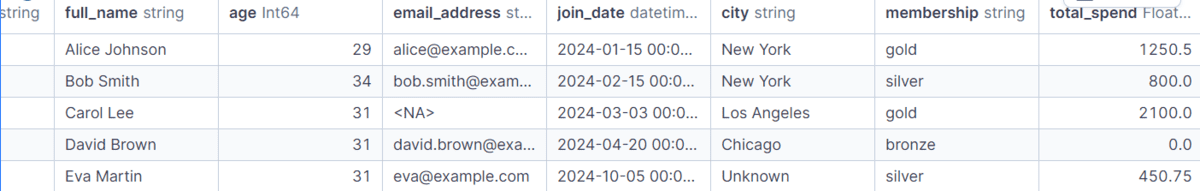
The column names are constant, the textual content values have been cleaned, the age column is now numeric, the be part of date is in a correct date format, and the full spend column is prepared for calculations.
This ultimate evaluate is essential as a result of it offers us one final likelihood to shortly spot any apparent difficulty earlier than saving the cleaned file.
# 15. Saving the Clear CSV
Lastly, we’ll save the cleaned dataset as a brand new CSV file.
“clean_customers.csv”,
index=False,
date_format=”%Y-%m-%d”,
)
print(“Saved clear file to clean_customers.csv”)
Output:
We save the cleaned dataset as a separate file so the unique messy CSV stays unchanged.
This can be a good follow as a result of you possibly can all the time return to the uncooked file if one thing goes incorrect or if you wish to apply a distinct cleansing strategy later.
# Ultimate Ideas
Most individuals suppose they know methods to clear a dataset, however the true problem begins when it’s a must to be certain that the information is definitely prepared for evaluation.
It isn’t nearly eradicating lacking values or fixing column names. You additionally have to examine knowledge varieties, deal with invalid values, take away duplicates, standardize classes, validate essential fields, and run ultimate checks earlier than trusting the dataset.
That’s the place many novices make errors. They clear the information on the floor, however they don’t validate whether or not the ultimate dataset is smart.
On this information, we adopted a easy however sensible workflow for cleansing a messy CSV file with Python and pandas. We loaded the information, inspected it, cleaned the columns, dealt with lacking values, fastened textual content, transformed numbers and dates, validated emails, checked the ultimate outcome, and saved a clear CSV file.
That is the form of workflow you possibly can reuse in nearly any real-world knowledge undertaking. The dataset might change, however the course of stays largely the identical: examine, clear, validate, and save.
Abid Ali Awan (@1abidaliawan) is a licensed knowledge scientist skilled who loves constructing machine studying fashions. Presently, he’s specializing in content material creation and writing technical blogs on machine studying and knowledge science applied sciences. Abid holds a Grasp’s diploma in know-how administration and a bachelor’s diploma in telecommunication engineering. His imaginative and prescient is to construct an AI product utilizing a graph neural community for college students scuffling with psychological sickness.