Coaching a multi-turn agent in Amazon SageMaker AI to resolve assist tickets or average content material means dealing with a sequence of dependent steps, not a single response. These brokers learn directions, make instrument calls, learn the outcomes, determine the following motion, and get better from a mistake earlier than committing to a solution. That flexibility can also be what makes agentic reinforcement studying (RL) difficult. Extra methods to behave imply extra methods to fulfill the reward with out doing the duty, and the setting the agent trains towards can quietly corrupt the coaching sign.
On this put up, we share greatest practices for dependable multi-turn RL coaching. We cowl tips on how to construct a coaching setting you may belief, arrange an exterior analysis, design a reward aligned with the top job, handle what modifications as soon as the agent runs for a number of turns, and monitor the metrics that inform you when to iterate. We draw our examples from the SOP-Bench dataset, an Amazon Science benchmark that evaluates brokers’ capacity to resolve duties primarily based on advanced Normal Working Procedures (SOP) throughout 12 enterprise domains.
SageMaker AI multi-turn reinforcement studying
Amazon SageMaker AI multi-turn RL (SageMaker AI MTRL) gives the coaching loop for agentic duties. Your agent can run on Amazon Bedrock AgentCore, Amazon Elastic Kubernetes Service (Amazon EKS), Amazon Elastic Compute Cloud (Amazon EC2), AWS Fargate, or infrastructure of your alternative. You join it by means of a small adapter that exposes your instrument floor to the rollout server, and SageMaker AI MTRL handles the remaining:
A modular agent-environment interface that retains integration low-code whereas providing you with full algorithmic management. Customized rewards, customized instrument loops, and multi-turn dialog shapes are all yours to outline.
Serverless execution that simplifies infrastructure considerations, so that you get production-scale agentic RL at per-token pricing with out provisioning or managing GPU clusters.
Asynchronous rollout and trajectory assortment with bounded off-policy staleness. Era and gradient updates run in parallel with out drifting too removed from the present coverage, which hastens coaching.
A local algorithm library spanning Proximal Coverage Optimization (PPO), Clipped Significance Sampling Coverage Optimization (CISPO), and importance-sampling (IS) losses, paired with a number of group-based benefit estimators (GRPO, GRPO cross@okay, RLOO, and extra). These cowl the alternatives most related to multi-turn agentic RL.
Sequence-extension coaching to maintain wall-clock down on lengthy multi-turn trajectories.
Trajectory and reward observability in MLflow managed by Amazon SageMaker AI, so you may learn what your agent did flip by flip, and throughout coaching steps.
Analysis jobs report reward, cross@okay, trajectory metrics, and extra earlier than you deploy to a SageMaker AI endpoint or Amazon Bedrock.
The service gives the coaching loop, {hardware}, and orchestration. The alternatives that determine whether or not you get a dependable agent are yours. You construct the setting the agent trains towards, measure success exterior the reward, design the reward itself, and determine tips on how to iterate when the curve stalls.
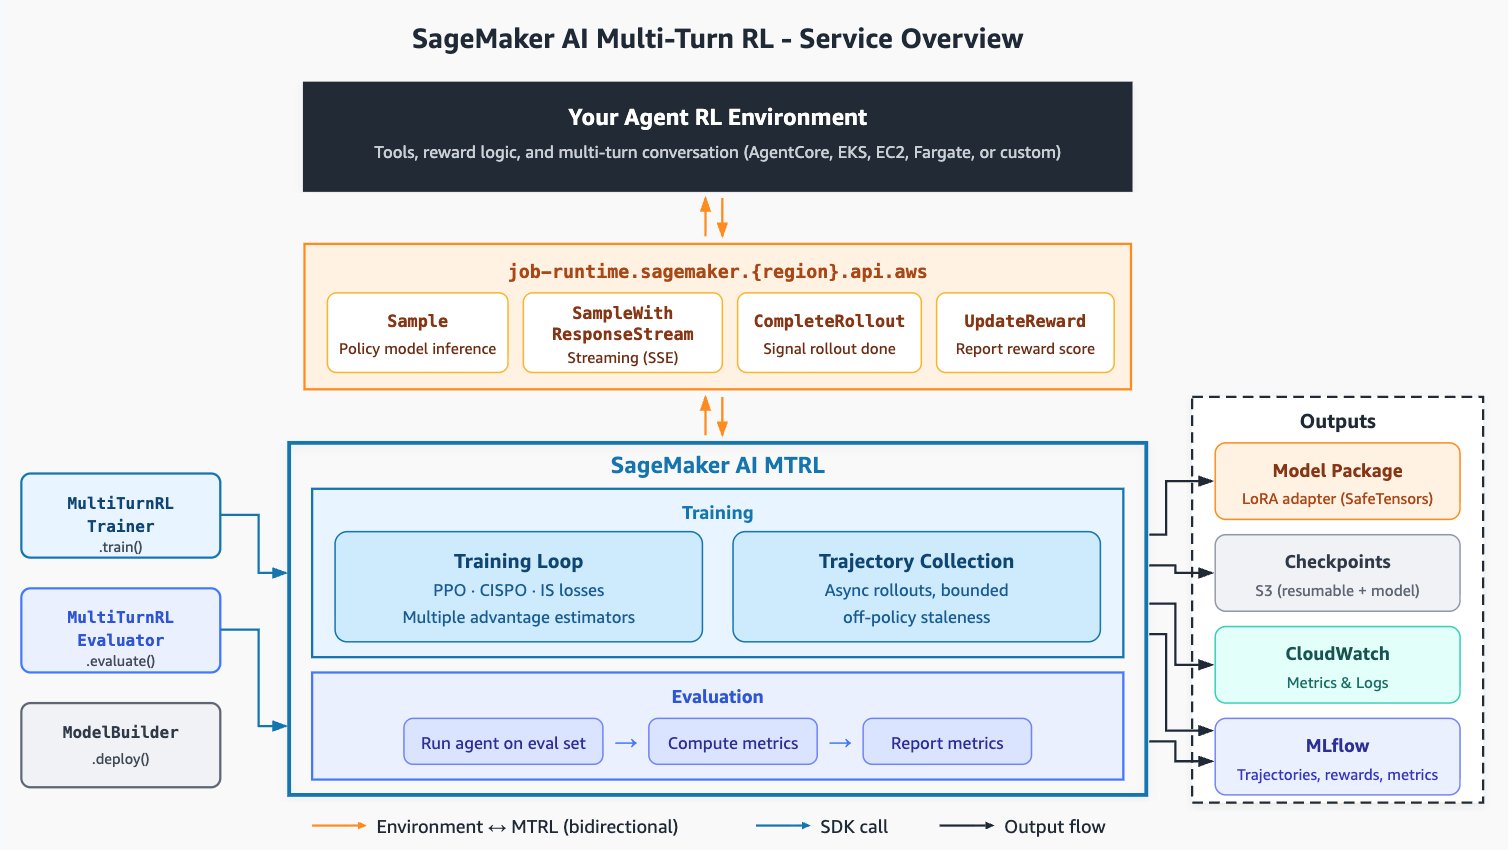
Determine 1: Overview of the SageMaker AI multi-turn RL service
Construct a coaching setting that’s low-cost, reproducible, and consultant
Single-turn RL wants a immediate and a reward perform. Multi-turn RL provides an setting for the agent to behave in throughout turns: the instruments it calls and the methods behind them. That setting is a part of your coaching setup, and the way in which you construct it shapes each what the mannequin can be taught and whether or not you may belief your metrics.
When coaching an agent, construct a sandboxed or simulated setting that resembles manufacturing however stays remoted from stay visitors. Device calls and responses preserve the identical schemas and enterprise logic. They’re pushed by recorded responses or remoted state as a substitute of stay calls.
Simulated environments are the really useful place to begin as a result of a typical run produces many 1000’s of rollouts, every making a number of instrument calls. For example, a batch dimension of 128 with group dimension 8 is 1,024 rollouts per step. Pointing that visitors at stay methods can result in buyer affect. With no simulated setting, exploration can produce actual unwanted side effects. For instance, an agent studying by trial and error will problem refunds, delete information, or set off workflows that you just didn’t intend. Moreover, stay information shifts below you, so the identical trajectory scores in a different way throughout runs. You could know the proper consequence to compute a reward, which implies a set, labeled set of duties (or a reliable decide mannequin) no matter the place the instrument calls go.
The way you construct the simulated setting is dependent upon what your instruments do. Three patterns cowl most use-cases you’ll encounter:
Learn-only instruments: Replay recorded responses keyed by their inputs. These instruments assist the agent retrieve data related to a job. For instance, in SOP-Bench the customer support job gives ten mocked instruments (validateAccount, getAuthenticationDetails, createSessionAndOpenTicket, and so forth), every returning a deterministic response from a fixture, resembling a particular row from a CSV file primarily based on the instrument name arguments.
Stateful instruments: Seeded sandboxes that maintain state for the size of an episode. When the agent writes one thing and reads it again, the setting wants reminiscence. The sample: allocate per-episode assets at the beginning of the rollout, and register every thing the agent creates. Tear all of it down in a attempt/lastly block when the episode ends, whether or not by reaching a terminal motion, hitting max_turns, or crashing. No state leaks into the following rollout.
Verifiable outcomes: Real execution in an remoted simulation setting. When the agent’s output is code, SQL, or math, you may run it in an remoted setting. Use a Docker exec for code, an in-memory SQLite per rollout for SQL, a pure Python eval for math. Actual execution, deterministic per-instance, similar enter plus similar sandbox state equals similar end result. For instance, AgentCore Code Interpreter gives managed remoted environments for code execution.
Whichever sample suits, maintain two properties fastened:
Reproducibility: the identical instrument referred to as with the identical arguments returns the identical end result, so the reward for an equivalent trajectory is steady and your analysis is comparable throughout runs.
Representativeness: construct the setting out of your actual schemas and information distributions so the conduct the mannequin learns transfers to manufacturing.
Earlier than you begin coaching, affirm your setting is configured accurately:
Device calls with the identical arguments give the identical end result, verified by working the identical occasion twice and diffing the rollout messages.
Per-rollout state is remoted (separate temp listing, separate IDs, separate DB connection).
Obtainable instruments match your manufacturing setting, together with instrument request/response schemas.
Arrange an exterior analysis earlier than you prepare
After your setting is in place and verified, construct a solution to measure success earlier than you write a reward perform. That measure ought to seize your finish objective immediately. RL optimizes the reward sign actually, so if the reward is the one quantity you watch, you can’t separate progress on the duty from progress on satisfying the reward standards. You want an exterior analysis you may belief to information your selections when you iterate on rewards, setting seeding, and hyperparameters.
Sample
Rise up a held-out analysis that scores the end result you care about at deployment, computed independently of the reward. In apply it is a small piece of code that takes a mannequin, runs it by means of the rollout server on a set take a look at cut up, and returns a single task-success charge. It may be minimal, so long as it’s sincere.
For SOP-Bench, the analysis is exact-match on the ultimate JSON object inside : each discipline within the agent’s output has to match the ground-truth discipline, or the rollout scores zero. The reward perform can compute partial credit score and weighted parts. The analysis doesn’t.
Earlier than any coaching, set up a baseline. Run the bottom mannequin and a reference mannequin (a frontier mannequin hosted on Amazon Bedrock is an efficient match) by means of the identical analysis. This tells you two issues: how far the bottom mannequin has to go, and what attractiveness like on this job.
Anti-pattern
Treating the coaching reward, or a metric derived from it, as your measure of success. This might sound intuitive, however to seize reward hacking, you want exterior analysis. Multi-turn brokers want particular consideration: a reward that pays out for instrument calls teaches the agent to name as many instruments as it may. A reward that penalizes flip rely teaches the agent to decide to a solution earlier than it has the knowledge it wants. Both approach, the coaching reward rises however the agent’s actual success at its job falls.
Earlier than you begin coaching, affirm your analysis is reliable:
The analysis is one perform, rating(rollout) -> float, scoring precisely what you ship.
Baseline analysis is non-zero on the bottom mannequin you propose to fine-tune (if it’s zero, see Ensure that the bottom mannequin has a foothold first within the subsequent part).
Run your analysis towards a frontier mannequin so you will have a sophisticated baseline to check towards.
Design an excellent multi-turn RL reward perform
Reward design is without doubt one of the tougher open issues in RL. The identical flexibility that lets the agent remedy an actual job lets it discover methods to fulfill the reward with out doing the duty. Each element you add, each reward weight you tune, each formatting bonus you layer in is one other floor the place the agent can climb with out fixing the duty. The mannequin optimizes what you wrote down, not what you meant. By default use the identical scoring rule for coaching and analysis, and solely deviate when you will have a concrete motive.
Take SOP-Bench. The benchmark expects the reply as a JSON object inside tags:
The benchmark scores 1 if each discipline matches and 0 in any other case. Coaching and analysis often share this scoring rule and differ solely in what you observe round it. The coach consumes one reward (scalar or record of scalars) per rollout. Analysis runs at decrease frequency on a set cut up, so you may monitor extra metrics: per-field accuracy, completion charge (did the agent emit in any respect), tool-call distribution, flip finances exhaustion, format compliance.
There are two actual causes to deviate from the default benchmark scoring rule, and each name for a denser reward.
The primary is algorithmic. RL computes the educational sign from variance throughout a bunch of group_size rollouts per immediate, utilizing a group-based benefit methodology (advantage_method). The service default group_based is GRPO. Many different strategies like rloo and grpo_passk are additionally out there. See the documentation for a full record. A binary rating can collapse that variance: when each rollout in a bunch scores the identical, the relative sign is zero and the group contributes no gradient. When rollout/reward/valid_mean (the imply over non-zero-advantage teams) drifts beneath rollout/reward/imply and the mannequin stalls, that hole is the symptom.
The second is convergence velocity. Even when group variance is wholesome, a dense reward provides the mannequin gradient towards partial progress on each rollout, not solely those that totally succeed. A rollout that will get 5 of six fields proper teaches the mannequin what nearer seems like. A binary rating teaches it nothing about that.
A dense reward for the SOP-Bench job scores every discipline independently and returns a reward scalar or record of scalars (per-turn rewards) plus a metrics dictionary.
Your agent studies the reward by means of update_reward, and the metrics dictionary (completion, field_acc) seems in MLflow. To credit score particular person turns as a substitute of the entire trajectory, update_reward additionally accepts a per-turn record, paired with the group_based_per_turn benefit methodology, so your reward perform may also return one reward worth per flip.
Confirm the reward on actual outputs earlier than you prepare on it. A reward parser extra forgiving than your analysis is its personal sort of reward hack. In one in every of our SOP-Bench runs the reward accepted a looser output format than the benchmark scored: a naked wrapper earned credit score regardless that the benchmark solely reads . Coaching did precisely what we requested: the mannequin discovered to drop the tag the benchmark wanted, the reward climbed, however the exterior analysis fell.
Ensure that the bottom mannequin has a foothold first. RL improves what the bottom mannequin can already do some fraction of the time. It doesn’t invent functionality from nothing. If the bottom mannequin produces zero profitable trajectories in your job, the reward sign has nothing to amplify and coaching stalls.
SageMaker AI MTRL can run such a baseline as a managed analysis job. MultiTurnRLEvaluator replays your agent over a held-out immediate set and studies eval/reward and cross@okay. When you’ve got already educated a mannequin, a single name with evaluate_base_model=True scores the bottom and fine-tuned mannequin facet by facet. As a result of cross@okay thresholds the reward at success_threshold, setting success_threshold=1 provides you a strict success charge: the fraction of rollouts that scored an ideal reward alongside the imply.
Within the specified s3_output_path, one can find the reported metrics of the analysis which you can too assessment in MLflow, together with analysis trajectories. For reward-based analysis of fine-tuned and base fashions, see the documentation on Mannequin analysis.
Hold one distinction in thoughts: the analysis job scores rollouts along with your agent’s personal reward perform, so it measures held-out generalization, not independence from the reward. A lenient reward parser would look wholesome right here, as a result of the metric is the reward itself. The unbiased verify that catches reward-parser bugs stays separate: rating the identical rollouts with a stricter, unbiased parser (for SOP-Bench, the benchmark’s exact-match scorer) and evaluate. You may even run that strict scorer as its personal analysis job by pointing MultiTurnRLEvaluator at an agent whose reward is the unbiased metric.
For a deeper therapy of reward design, sparse vs. dense rewards, decide fashions, multi-objective shaping, and the trade-offs between them, see the SageMaker AI reward design greatest practices.
Earlier than you belief your reward, affirm:
Coaching reward and analysis share the identical underlying scoring rule until you will have a measured motive to diverge (and that motive is documented).
Reward returns a float in [0, 1] (or [-1, 1] when you enable unfavorable regression phrases).
Reward over 100 baseline rollouts has variance (not all 0, not all 1). If it doesn’t, that’s the sort of measured sign that justifies both shaping or devising a devoted information curriculum.
No baseline rollout scores greater on the coaching reward than on the eval. If it does, the reward is over-rewarding one thing the exterior eval doesn’t credit score.
If the reward has a number of parts, confirm you log every individually in MLflow so you may learn divergence per time period.
Handle what modifications when the agent runs for a number of turns
A multi-turn agent has to handle considerations single-turn doesn’t see. These are value designing for explicitly earlier than you begin coaching.
Context grows each flip, and switch budgets are a part of the reward design. Every instrument name extends the dialog: the decision, its arguments, the end result, and the reasoning the mannequin produces between them. Lengthy trajectories accumulate context quick, and MTRL makes use of sequence-extension coaching to maintain wall-clock manageable as they develop. A job that wants eight calls in sequence may run out of room earlier than it finishes. Two budgets certain this: max_turns, which your agent loop controls, and the per-turn token finances, which the service units by means of sampling_max_tokens (rollout) and val_sampling_params.sampling_max_tokens (analysis). Choose each to match what your job wants and what you may afford to serve at deployment.
For SOP-Bench, eight turns and a 2,048-token per-turn finances cowl the canonical process with margin to spare (sampling_max_tokens permits as much as 8,192). A rule of thumb: if a human walkthrough of the duty takes N turns, set max_turns = ceil(N * 1.5) in your agent loop. The precise flip finances is the smallest one which lets the agent end with a small security margin. Watch rollout/tokens/response_max for responses clustering on the cap. If greater than 5 p.c of rollouts hit it, elevate sampling_max_tokens. That sign is silent loss in any other case. The mannequin learns from a truncated trajectory however doesn’t see the reward it might have earned by ending.
Separate completion from correctness
A trajectory that finishes with the unsuitable reply and one which by no means finishes are completely different failures, and conflating them hides the place the mannequin is breaking. The rollout and val metric households in MLflow offer you each indicators individually:
Metric
What it tells you
1
rollout/reward/imply
Common trajectory reward, your training-side sign
2
rollout/reward/zero_frac
Fraction of trajectories that scored precisely 0
3
rollout/turns/imply
Common turns per trajectory
4
evaluation/zero_adv_groups
Teams the place each rollout scored the identical, losing rollouts
5
val/reward/imply
Imply validation reward your held-out information sign
6
val/reward/pass_k_1, pass_k_8
cross@1 and cross@okay on the held-out set
A excessive val/reward/pass_k_1 on a low completion charge (rollouts hitting max_turns earlier than emitting a ) means the mannequin will get the simple paths proper and stalls on the laborious ones, suggesting turn-budget tuning. A excessive completion charge on a low val/reward/pass_k_1 means it solutions fluently however unsuitable, suggesting reward redesign. The 2 failure modes name for various fixes, so it’s value telling them aside.
Earlier than you commit a flip finances, affirm:
max_turns in your agent loop is calibrated to the duty, not left at an arbitrary default.
Lower than 5 p.c of coaching rollouts hit sampling_max_tokens on any single flip.
Lower than 10 p.c of coaching rollouts hit max_turns with out producing a closing reply.
Completion (closing reply emitted) and correctness (closing reply proper) are tracked as separate metrics in MLflow.
Monitor coaching metrics
After you’ve arrange and verified your analysis, setting, and reward, it’s time to start out coaching. SageMaker AI MTRL gives the high-level MultiTurnRLTrainer and MultiTurnRLEvaluator constructs to coach and rating your agent:
Whereas coaching, watch rollout/reward/imply subsequent to the completion charge and open a couple of trajectories in MLflow (below the Traces tab), so a reward that rises on flat completion doesn’t slip previous. The sign that issues at analysis is disagreement: when rollout/reward/imply climbs however val/reward/imply stays flat, the reward is being hacked. Open these trajectories and evaluate what the reward credited towards what the analysis scored. That comparability drives your reward design iteration: tighten the reward parser, reshape a element, or curate the information, then run once more. Every iteration is quicker than the final as a result of the setting and analysis keep fastened. Solely the reward and the information change, and MTRL’s per-model starter recipes offer you a tuned level to start out from.
For instance, in one in every of our earliest makes an attempt we had been attempting to coach an agent on all SOP-Bench duties on the similar time, which led to duties competing and reward fluctuating:
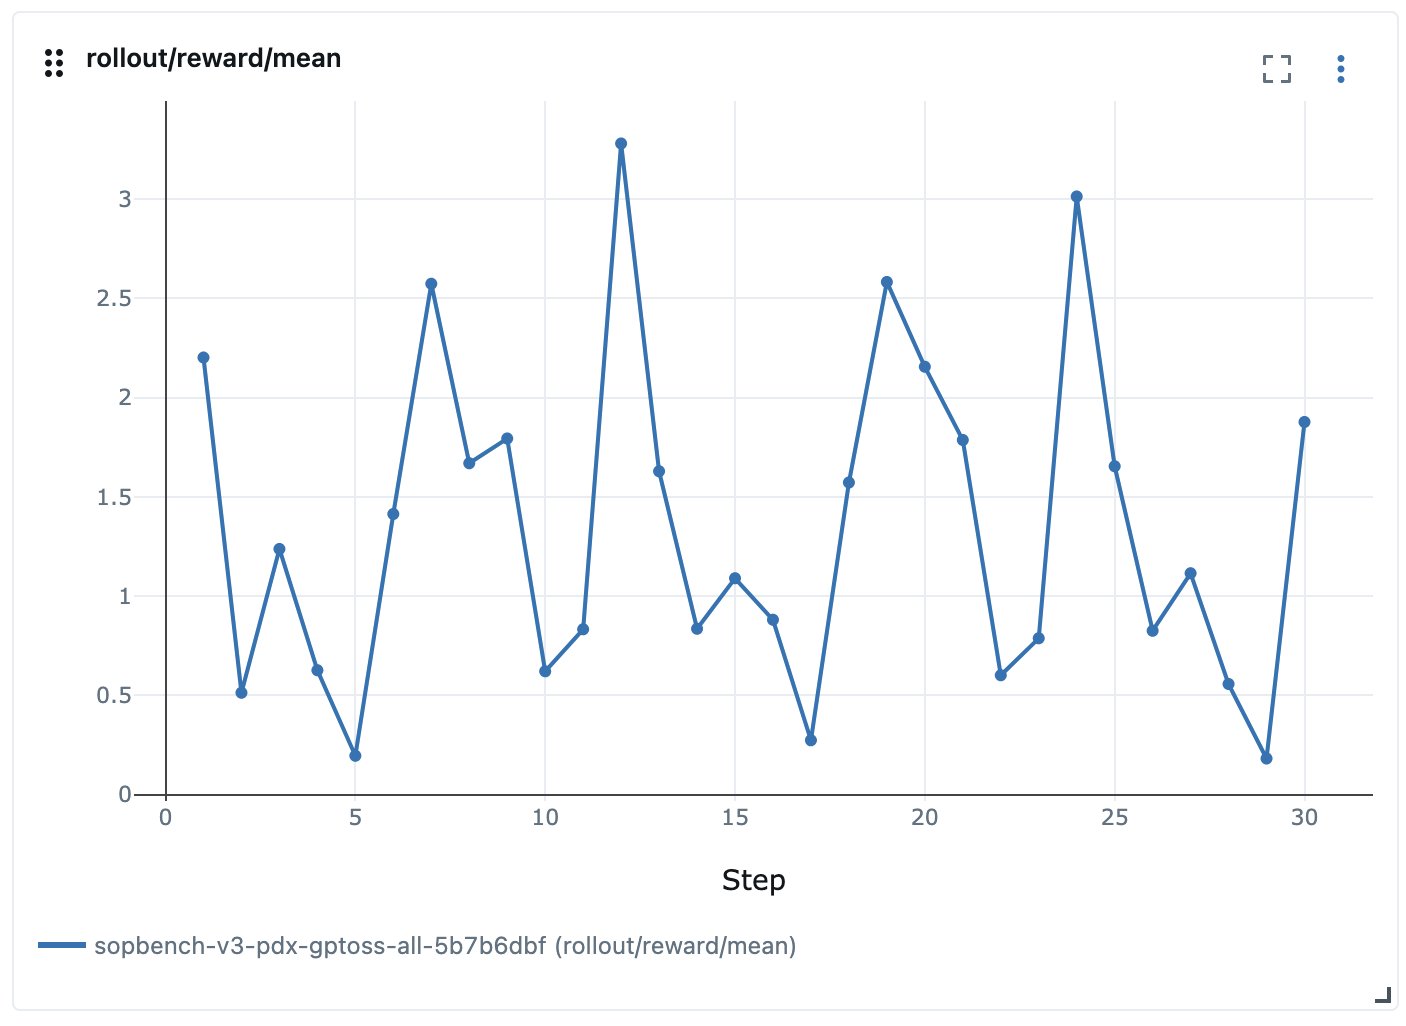
Determine 2: Reward fluctuating when attempting to coach all SOP-Bench duties collectively
After limiting our information to give attention to a single job (aircraft_inspection), we seen validation reward taking place whereas rollout reward had saturated. In our reward formulation the max reward was 5.0, however reward had stalled round 3.7:
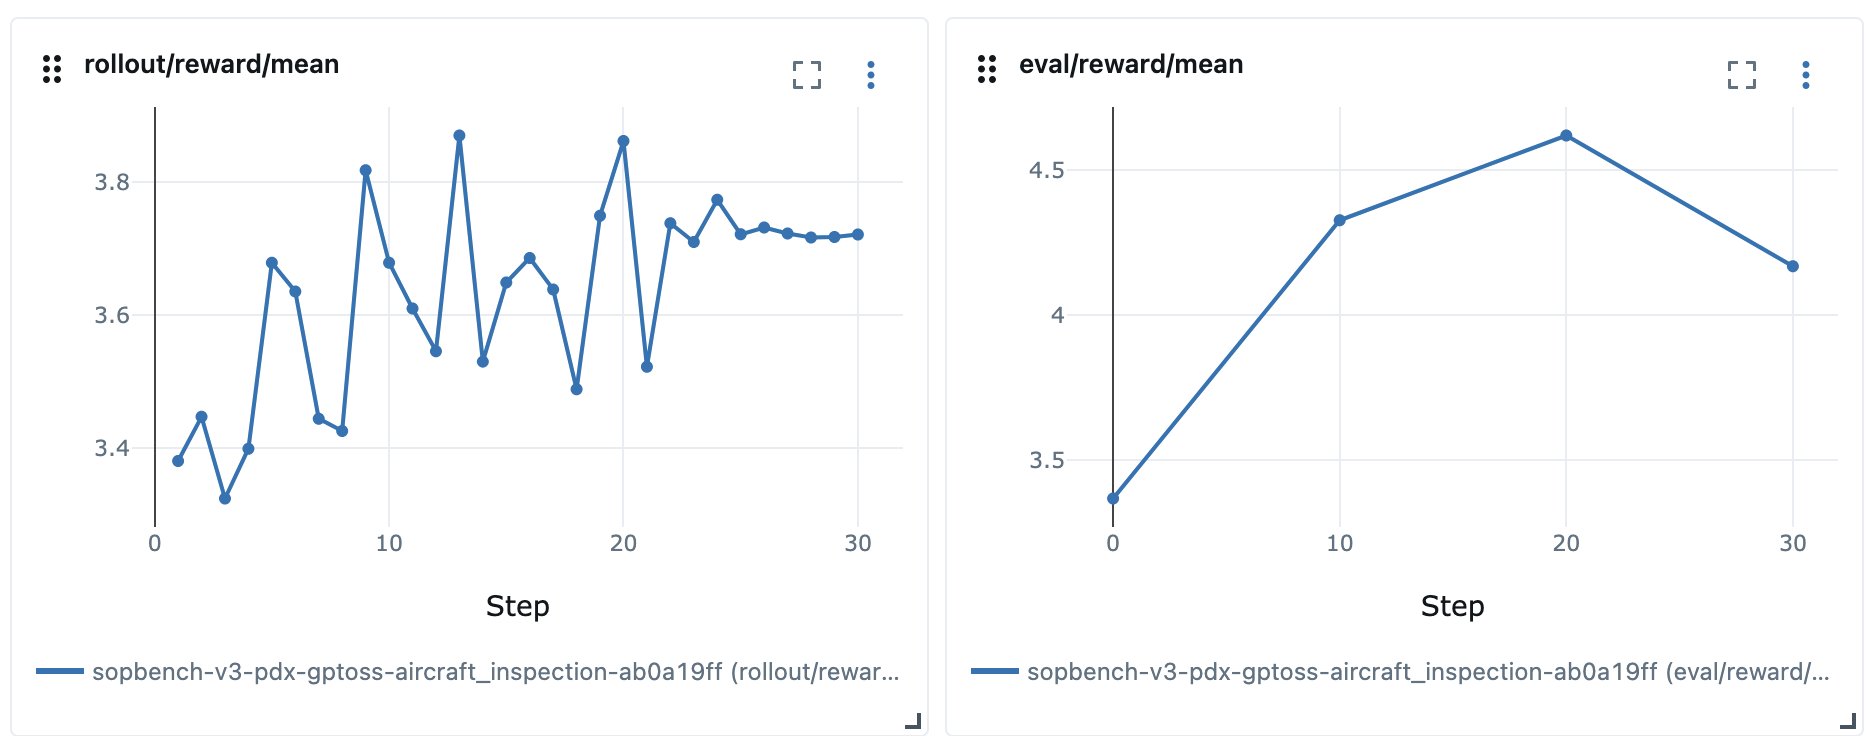
Determine 3: Reward stalling and validation reward dropping
The mannequin wasn’t incomes full reward on aircraft_inspection, and the Process Success Fee on the exterior benchmark went down for the fine-tuned mannequin in comparison with the bottom mannequin. We would have liked to assessment rollout trajectories to search out out why. The SOP’s one-shot instance didn’t match the duty’s ground-truth information in two methods. It omitted the cross_check_response discipline that the information required, so the mannequin couldn’t produce a whole reply, and it wrapped the output in a special tag than the analysis anticipated. We aligned the instance with the information and dropped the unanswerable discipline, which let the reward and the analysis measure the identical factor.
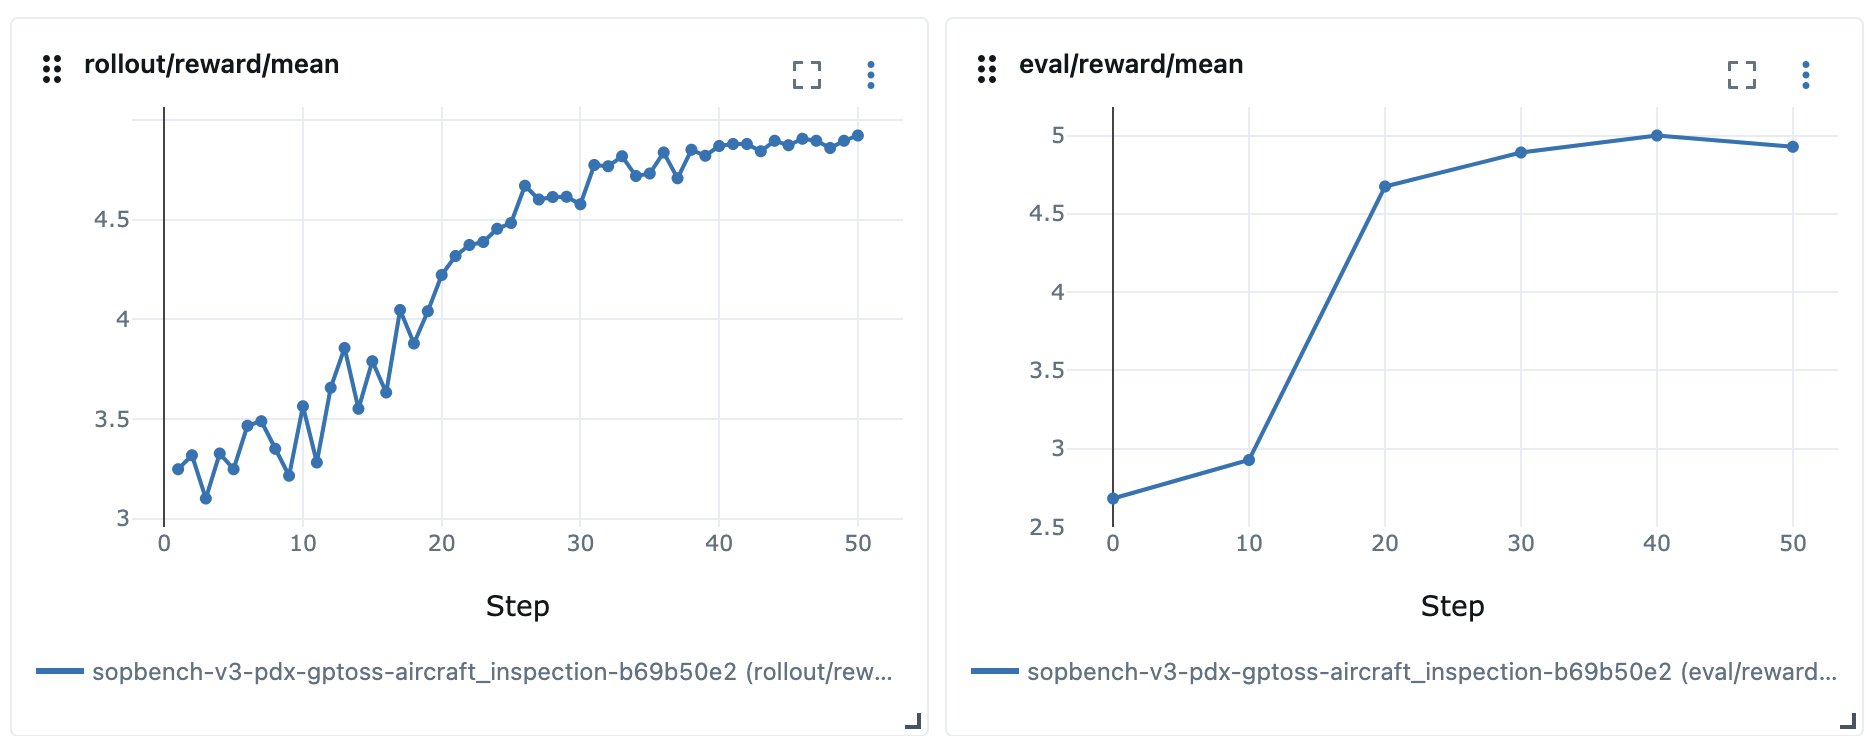
Determine 4: Wholesome reward indicators for the aircraft_inspection job of SOP-Bench
When measuring the Process Success Fee (TSR) of a fine-tuned GPT-OSS 20B mannequin towards the exterior benchmark, we noticed TSR improve by 13 p.c and per-field accuracy develop by roughly 16 p.c on the aircraft_inspection job, confirming that our reward perform aligns with our exterior analysis.
Placing it collectively: An iteration loop
The items described earlier add as much as a single coaching loop, run within the order they had been launched. You construct the setting and the analysis first, as a result of they’re the fastened scaffolding each later step is dependent upon. You then design the reward towards that analysis, and solely after that do you prepare and skim the metrics. Protecting the early items fastened is what makes every cross quick, so most of your effort goes into the reward and the information. A model that has labored properly for us:
Accumulate consultant job information and cut up into prepare, validation, and held-out take a look at units.
Construct the coaching setting from manufacturing schemas: airtight, seeded, reproducible.
Rise up the exterior analysis towards the take a look at set, computed independently of the reward.
Set up a baseline by working the bottom mannequin and a frontier reference mannequin by means of the analysis. If the bottom mannequin scores zero, cease and simplify earlier than persevering with.
Design the reward, then validate it on actual mannequin outputs from the baseline earlier than any coaching has occurred.
Practice, monitoring rollout/reward, completion charge, and a pattern of trajectories to know what your mannequin is producing throughout coaching.
Consider the educated mannequin with the exterior analysis. Learn trajectories, particularly those the place the reward and the analysis disagree.
Alter the reward, the setting, or the information, and run once more.
When the curve stalls or collapses, stroll these so as earlier than tuning the rest:
Symptom
Very first thing to alter
Diagnostic to verify
1
Reward flat from step 0
Confirm mannequin output codecs are aligned with reward
Carry out standalone evaluations on completely different rewards to align format reward with mannequin’s output construction
2
Practice reward flat, all teams rating the identical
Drop group_size from 8 to 4 and improve batch_size
Watch evaluation/zero_adv_groups, ought to drop
3
Practice reward rising however val/reward/imply flat
Reward is being hacked. Re-read trajectories, tighten the reward parser
Re-run the offline reward assessment towards new baseline rollouts
4
Reward collapses (drops to ~0.0) after step 40–80
Set async_config.max_steps_off_policy = 0. If on CISPO, change to PPO with (0.8, 1.2)
Reward ought to stabilize, even when decrease
5
Reward stalls with restricted enchancment, all knobs wholesome
Double LoRA capability (lora_rank=64, lora_alpha=128)
Greater ceiling inside 50 steps if there’s room to develop
Make one change at a time, observing metrics for 25–50 coaching steps (gradient updates) per resolution. In our runs, most failures turned identifiable inside roughly 30 steps when these parameters are adjusted intentionally.
Conclusion
Your reward high quality and your analysis determine whether or not coaching produces a helpful agent, far more than the algorithm or the hyperparameters do. The reward is the one sign the mannequin optimizes, and an analysis stored separate from it’s what tells you whether or not the agent is studying the duty or studying the reward. A fastidiously designed reward and an analysis that matches the top job can produce a helpful agent; with out them, even a powerful algorithm yields a mannequin that appears good in coaching and fails in manufacturing.
SageMaker AI multi-turn RL takes care of many of the operational work and complexity of working a distributed agentic RL coaching, abstracting away the {hardware}, orchestration, and coaching engine. With SageMaker AI multi-turn RL, you give attention to creating an correct setting, the place Strands Brokers and AgentCore may also help you transition your manufacturing setting to an agentic setup, and give attention to the reward design, analysis, and parameter tuning.
To get began with agentic RL, you may stroll by means of the instance pocket book for MTRL setup. See the SageMaker AI multi-turn RL documentation for service-level steerage and the reward design greatest practices for a deeper therapy of the reward matter, or this AWS weblog put up on GRPO with verifiable rewards. Lastly, the SOP-Bench paper and dataset are the supply of the working instance used right here.
Concerning the authors
Sapana Chaudhary
Sapana is an Utilized Scientist II at Amazon Internet Companies (AWS), the place she works on reinforcement studying post-training of huge language fashions. Her analysis sits on the intersection of reinforcement studying, robustness, and language fashions — with the objective to make AI methods extra dependable and reliable for downstream duties — whether or not by means of constrained optimization, risk-aware finetuning, or verifiable reasoning. Sapana holds a PhD from Texas A&M College (TAMU). Exterior of labor, she likes to hike, cook dinner, paint, and {photograph}.
Theodore Vasiloudis
Theodore is a Senior Utilized Scientist at AWS, the place he works on giant language mannequin post-training, with a give attention to scale and effectivity. He works on the intersection of methods and algorithms, creating coaching frameworks and providers for AWS prospects trying to fine-tune fashions at scale. Theodore holds a PhD from KTH Royal Institute of Expertise, Stockholm.