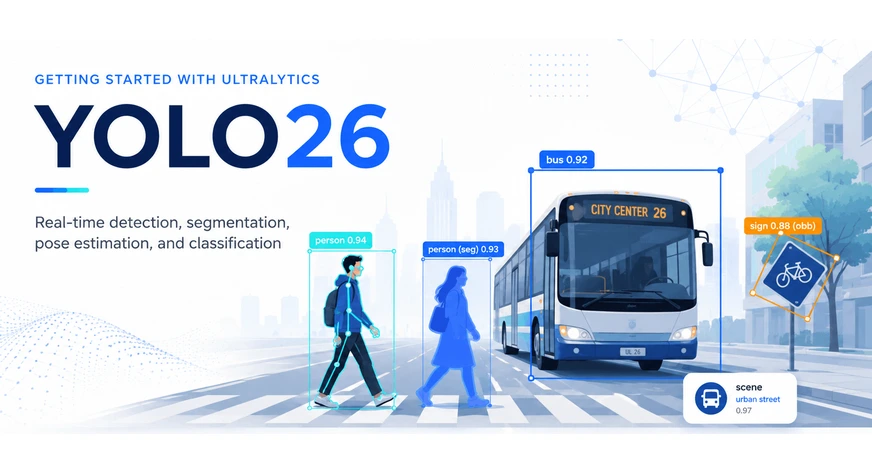
Trying to mannequin to implement pose estimation? I do know one thing that may carry out detection, occasion segmentation, pose estimation and classification, all of that in real-time. Sure, I’m speaking in regards to the YOLO26 from ultralytics.
It might support safety methods or could be fine-tuned to detect even smaller objects. Questioning easy methods to get began? No worries, we’ll cowl the fundamentals of YOLO and study to carry out inference utilizing the mannequin.
Background on YOLO
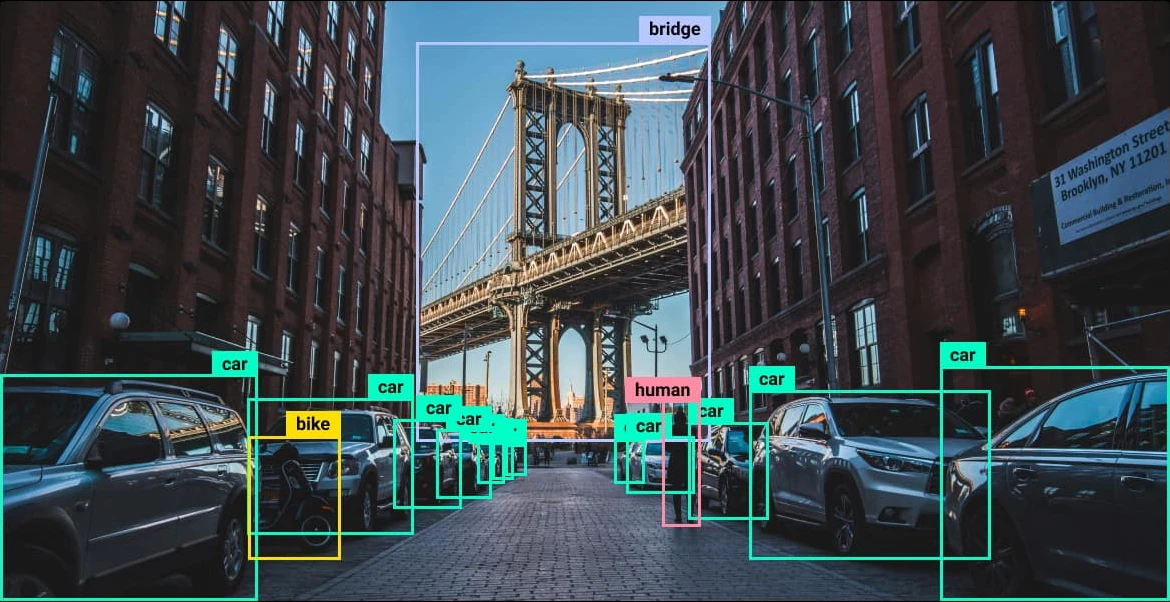
YOLO (You Look Solely As soon as) is a household of deep studying fashions used for pc imaginative and prescient duties; the foundational logic is the usage of localization and classification. In easy phrases, localization detects objects and finds the coordinates of every one. Then, the classifier predicts the category possibilities and assigns essentially the most possible class to that object. The newest household of fashions from YOLO is YOLO26, as talked about earlier they will carry out:
Object Detection: Finds a number of objects in a picture and predicts their class confidence rating and bounding field. This tells you what the thing is and the place it’s situated.
Classification: Assigns the picture to considered one of 1000 ImageNet classes. The category with the best likelihood is chosen as the ultimate prediction.
Pose Estimation: Detects the 17 human physique keypoints outlined by the COCO dataset. These embody factors just like the nostril, shoulders elbows, knees and ankles to estimate every particular person’s pose.
Oriented Bounding Field (OBB) Detection: Predicts rotated bounding containers utilizing 5 parameters. x. y. w. h and θ. That is particularly helpful for aerial and satellite tv for pc photos the place objects hardly ever seem completely aligned.
Occasion Segmentation: Generates a pixel degree masks for each detected object. This helps seperate particular person objects even after they belong to the identical class.
These fashions have a better accuracy and higher effectivity than the earlier generations of fashions.
Structure
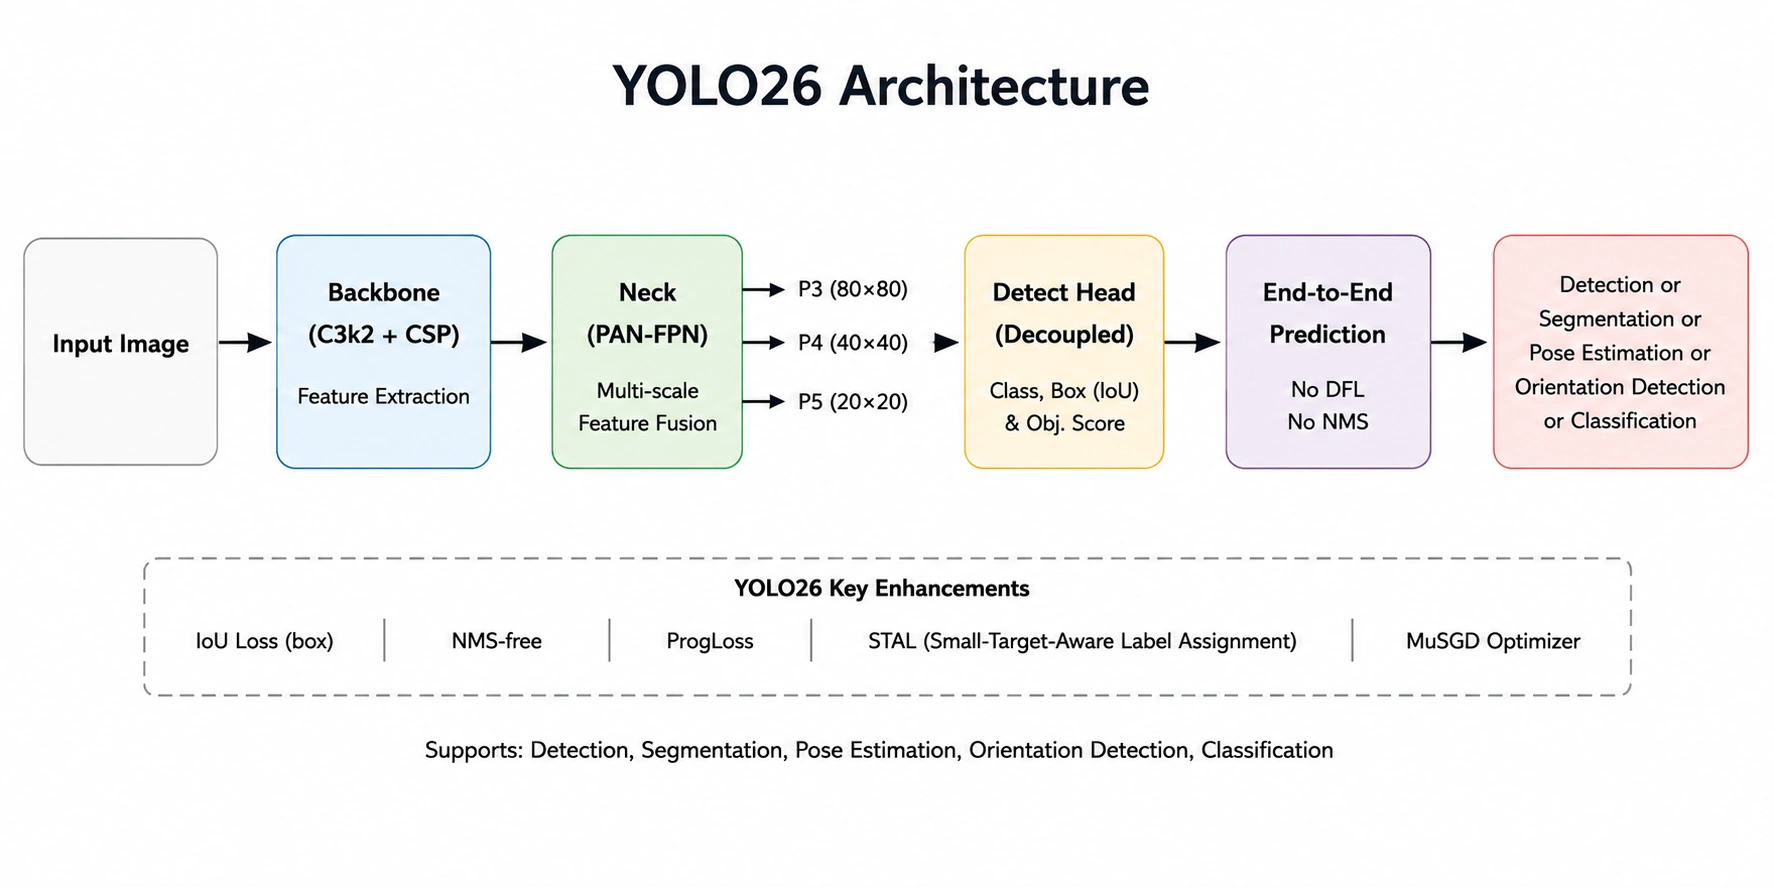
Enter Picture: The enter picture is resized and normalized earlier than the mannequin processes it.
Spine (C3k2 + CSP): Extracts options from the picture like edges, textures, shapes, and object patterns.
Neck (PAN-FPN): Performs fusion of P3, P4 & P5. This helps enhance the detection of small, medium, and enormous objects respectively.
Detection Head: Predicts the thing courses, bounding containers, and confidence scores utilizing the fused function maps.
Finish-to-Finish Inference: Eliminates a couple of issues current within the earlier generations, particularly DFL and NMS. Simplifying the pipeline whereas bettering inference latency.
Output: Object detection, segmentation, pose estimation, orientation detection, or classification.
For Context
C3k2: A function extraction block launched just lately in YOLO fashions. It improves function studying with fewer parameters.
PAN (Path Aggregation Community): Passes low degree and excessive degree options in each instructions, serving to object detection of various sized objects precisely.
FPN (Function Pyramid Community): Combines function maps from a number of depths, helps acknowledge objects at a number of scales.
P3 -> Excessive decision function map, P4 -> Medium decision function map and P5 -> Low decision function map. They assist the mannequin detect small, medium, and enormous objects respectively.
Palms-On
Let’s check out the YOLO26 with the assistance of Google Colab. We’ll primarily be utilizing this picture in the course of the inference:
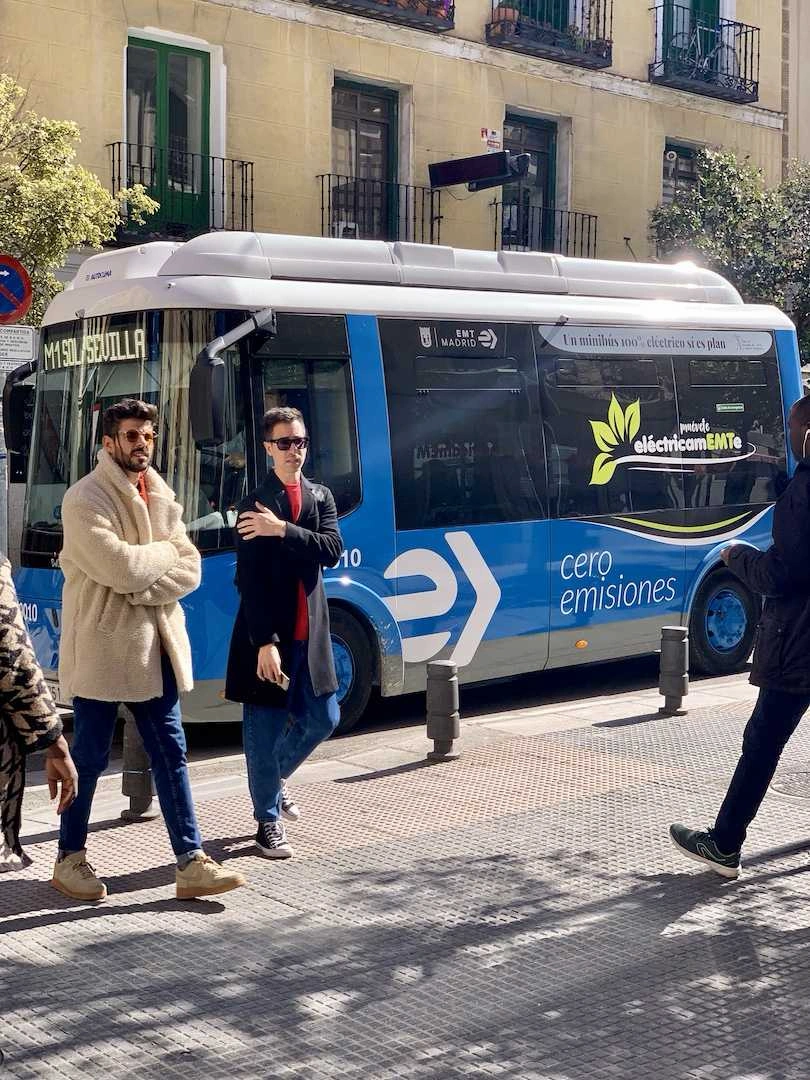
Observe: YOLO fashions don’t require high-end {hardware}, they are often run regionally in Jupyter Pocket book as nicely.
Installations
!pip set up -q “ultralytics>=8.4.0”
Right here ‘-q’ is used to put in the library and dependencies with out displaying something.
Defining Helper perform
from PIL import Picture
# helper perform
def present(end result):
show(Picture.fromarray(end result.plot()[…, ::-1]))
This can be used to show the outcomes.
Object detection
from ultralytics import YOLO
IMAGE = “https://ultralytics.com/photos/bus.jpg”
mannequin = YOLO(“yolo26n.pt”)
end result = mannequin(IMAGE)[0]
present(end result)
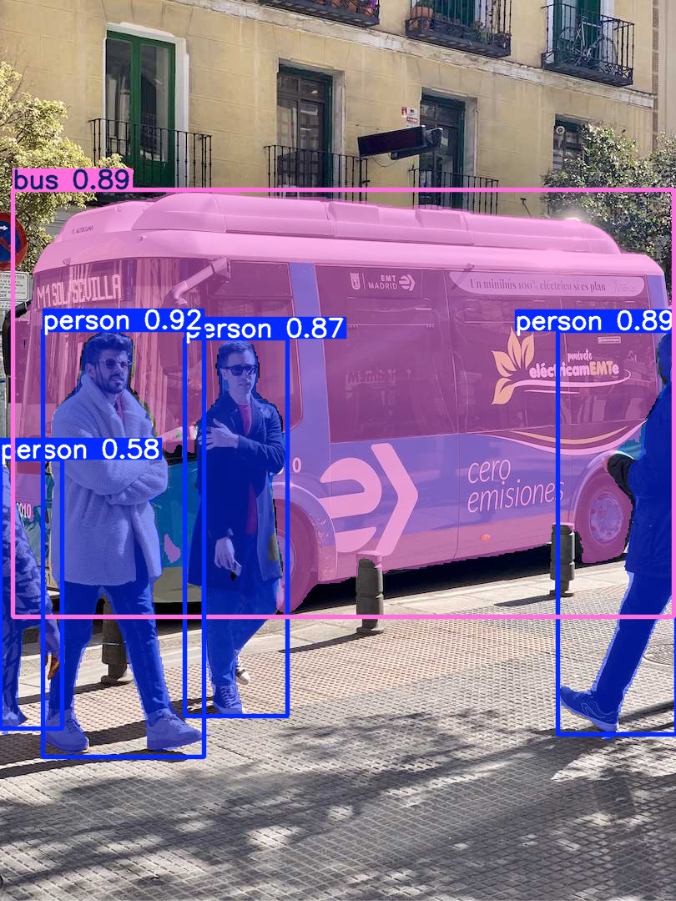
The mannequin has efficiently detected the bus and the folks.
Occasion Segmentation
seg_model = YOLO(“yolo26n-seg.pt”)
end result = seg_model(IMAGE)[0]
present(end result)
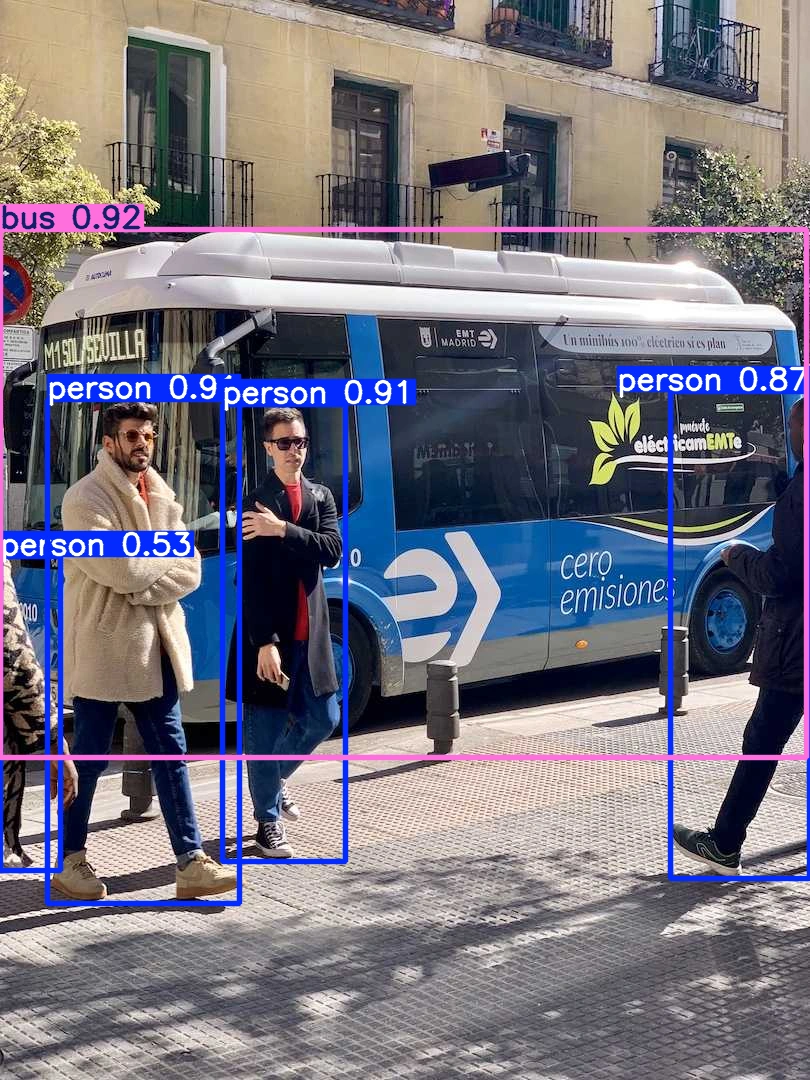
Right here the mannequin has carried out the segmentation, it has masked the objects it has detected. The sting detection additionally seems to be good.
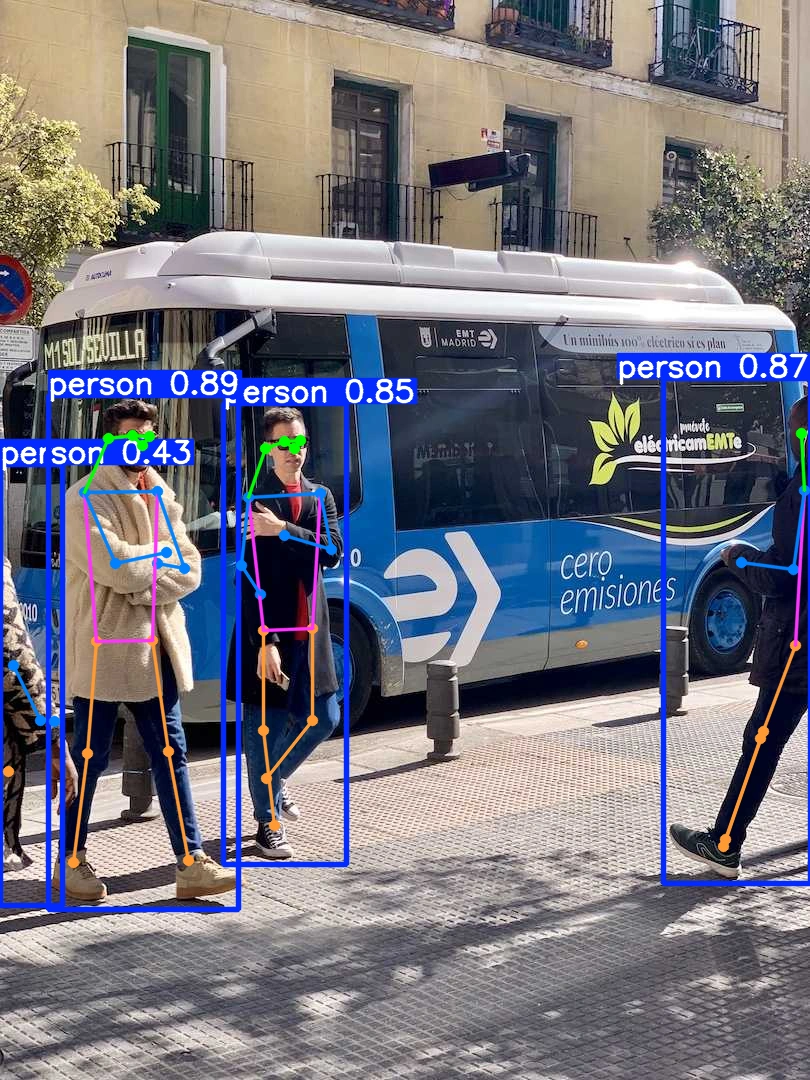
Pose / Keypoint Estimation
pose_model = YOLO(“yolo26n-pose.pt”)
end result = pose_model(IMAGE)[0]
present(end result)
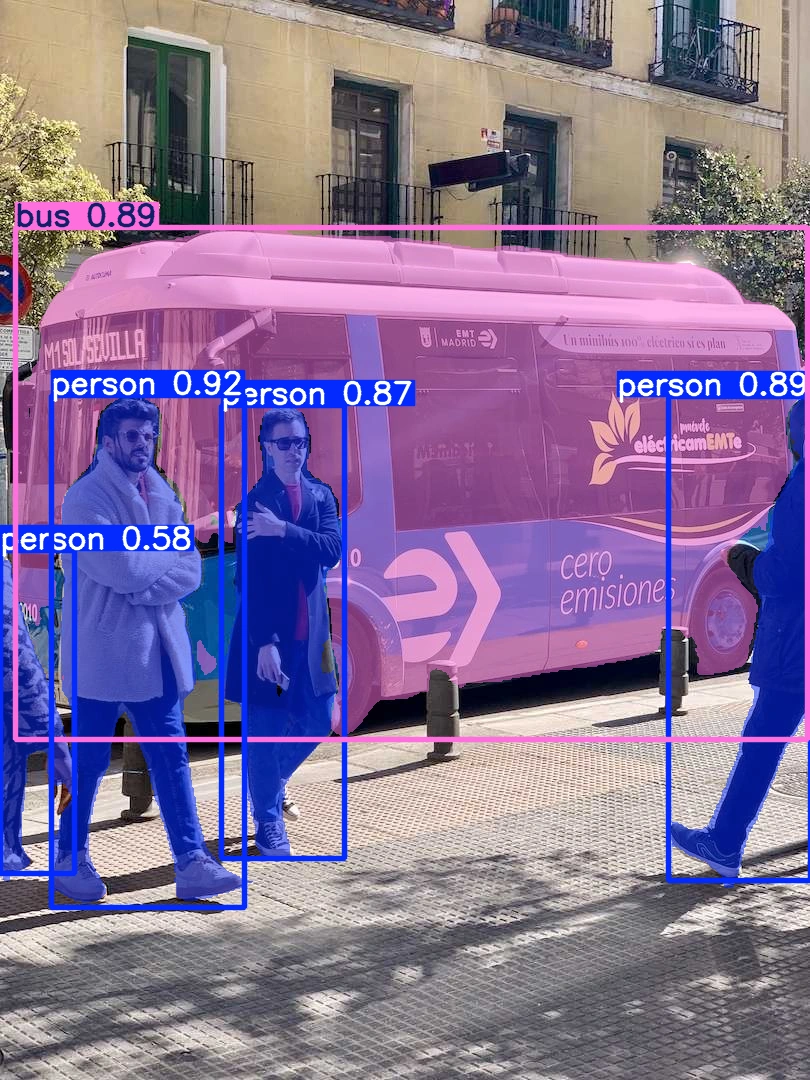
The mannequin has efficiently predicted the human physique key factors for pose detection.
Oriented Bounding Containers
obb_model = YOLO(“yolo26n-obb.pt”)
end result = obb_model(“https://ultralytics.com/photos/boats.jpg”)[0]
present(end result)
This mannequin can particularly detect objects in aerial, top-down, or satellite tv for pc photos. As you may see it has detected the ships within the picture very nicely.
Picture Classification
cls_model = YOLO(“yolo26n-cls.pt”)
end result = cls_model(IMAGE)[0]
for i in end result.probs.top5:
print(f”{end result.names[i]:<25} {end result.probs.knowledge[i]:.2%}”)
Output:
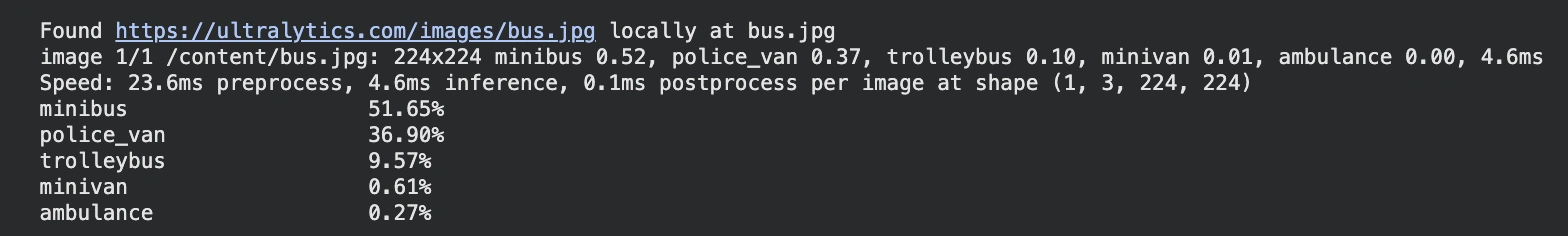
The mannequin outputs the chances of 1000 courses, right here the classifier predicted the category as minibus precisely.
Conclusion
In abstract, you discovered the fundamentals of YOLO and YOLO26, explored its structure, and carried out inference in Google Colab for object detection, occasion segmentation, pose estimation, oriented bounding containers, and picture classification. With its improved accuracy, effectivity, and real-time efficiency, YOLO26 is a pleasant alternative for a variety of pc imaginative and prescient functions.
Ceaselessly Requested Questions
A. In Google Colab, you may add a picture utilizing information.add() perform and go the uploaded path to the mannequin for inference.
A. Sure. You may learn the video as photos (frames), run the mannequin on each body, after which mix the processed frames as a video.
A. No. YOLO26 fashions can run on a CPU, though a GPU can be a lot quicker for inference for bigger duties.

Keen about expertise and innovation, a graduate of Vellore Institute of Expertise. Presently working as a Knowledge Science Trainee, specializing in Knowledge Science. Deeply inquisitive about Deep Studying and Generative AI, wanting to discover cutting-edge methods to unravel advanced issues and create impactful options.
Login to proceed studying and luxuriate in expert-curated content material.
Hold Studying for Free