


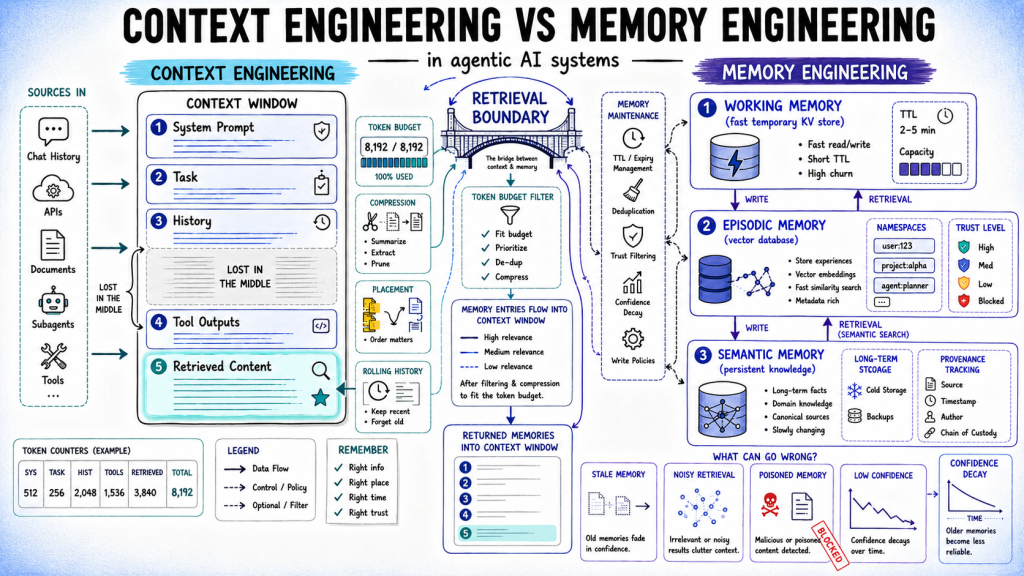
On this article, you’ll learn the way context engineering and reminiscence engineering clear up totally different issues in agentic AI methods, and the way the 2 disciplines meet on the level the place retrieved reminiscence enters the context window.
Subjects we are going to cowl embrace:
What context engineering entails, together with selective inclusion, structural placement, and compression, and why it issues for reasoning high quality inside a single inference name.
What reminiscence engineering entails, together with write coverage design, storage layer choice, retrieval technique, and upkeep, and the way these form long-term reliability.
How reminiscence and context engineering meet on the retrieval boundary, and the 2 most typical failure modes that happen when this boundary shouldn’t be managed properly.
With that framing in place, right here’s how every self-discipline works.
Introduction
As AI brokers transfer into longer workflows and multi-session use circumstances, a well-known sample emerges. Constraints get dropped mid-task, retrieved info resurfaces when it shouldn’t, and context from an earlier step bleeds into the present one. The failures are laborious to pinpoint as a result of no single part is clearly at fault.
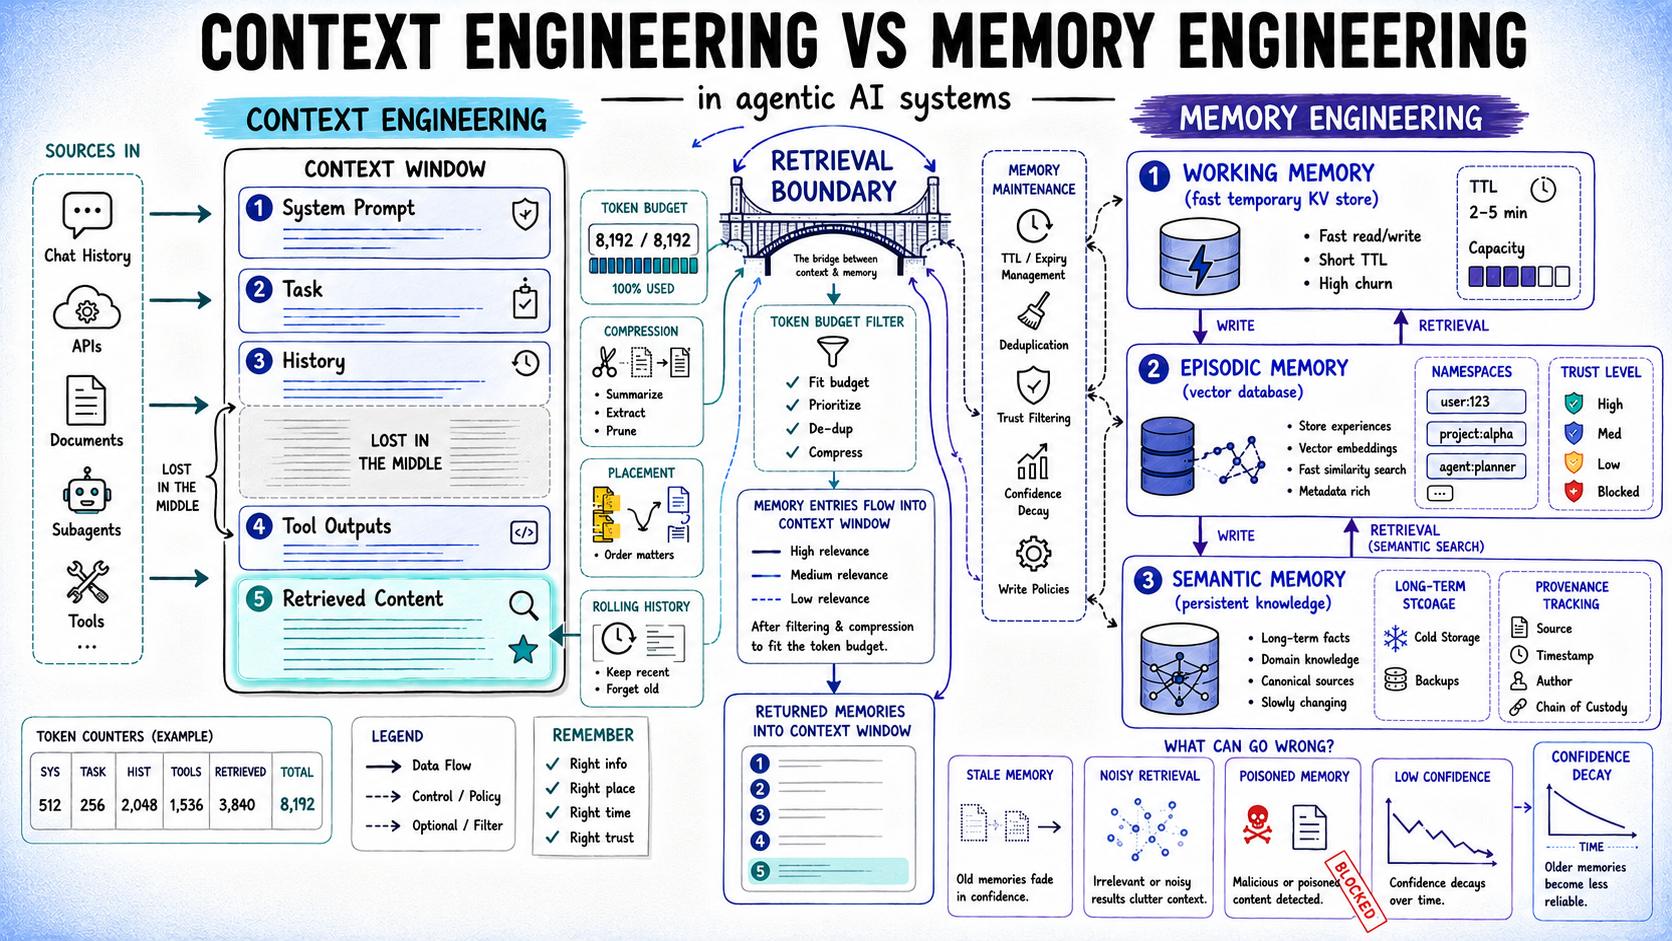
More often than not, the issue lies in two areas that get constructed collectively, conflated, or skipped: context engineering and reminiscence engineering. They’re associated however distinct, fail in several methods, and require totally different methods to get proper.
This text covers the core choices behind every self-discipline and the place they work together:
What context engineering entails and the particular choices that decide whether or not an agent causes properly inside a single name
What reminiscence engineering entails and the way write coverage, storage, retrieval, and upkeep every have an effect on long-term reliability
How the 2 disciplines share a boundary at retrieval time and what it takes to handle that boundary properly
Understanding each, individually and collectively, is what determines whether or not an agent holds up throughout actual workloads.
An Overview of Context and Reminiscence Engineering
Context engineering covers the design of a single inference name: what to incorporate, what to compress, the place to put issues, and what to discard. Every part in scope is ephemeral; when the decision ends, the window clears.
Reminiscence engineering focuses on what survives past a single interplay with a mannequin. It encompasses the methods and insurance policies chargeable for writing, storing, retrieving, updating, and governing info in order that future interactions could make use of it. When an agent remembers info from a earlier session, coordinates with one other agent, or applies a person choice discovered days or even weeks earlier, it’s counting on reminiscence engineering quite than context engineering.
Whereas context engineering determines what info is offered to the mannequin throughout a selected request, reminiscence engineering determines what info persists throughout requests and the way that info is maintained, retrieved, and trusted over time. Right here’s an outline:
Facet
Context Engineering
Reminiscence Engineering
Scope
One inference name
Throughout calls, classes, brokers
The place information lives
Contained in the mannequin’s energetic window
Exterior shops: vector DB, Ok/V, relational
Main drawback
What to incorporate and prepare it
What to persist, retrieve, and belief
Fails when
Window fills, placement is unsuitable, noise overwhelms sign
Retrieval misses, staleness, poisoning, no write coverage
Engineering floor
Immediate construction, compression, token budgeting
Storage schema, retrieval technique, write and replace insurance policies
Lifespan of information
Period of 1 LLM name
Relies on the reminiscence kind
Context Engineering: Assembling the Optimum Context Window
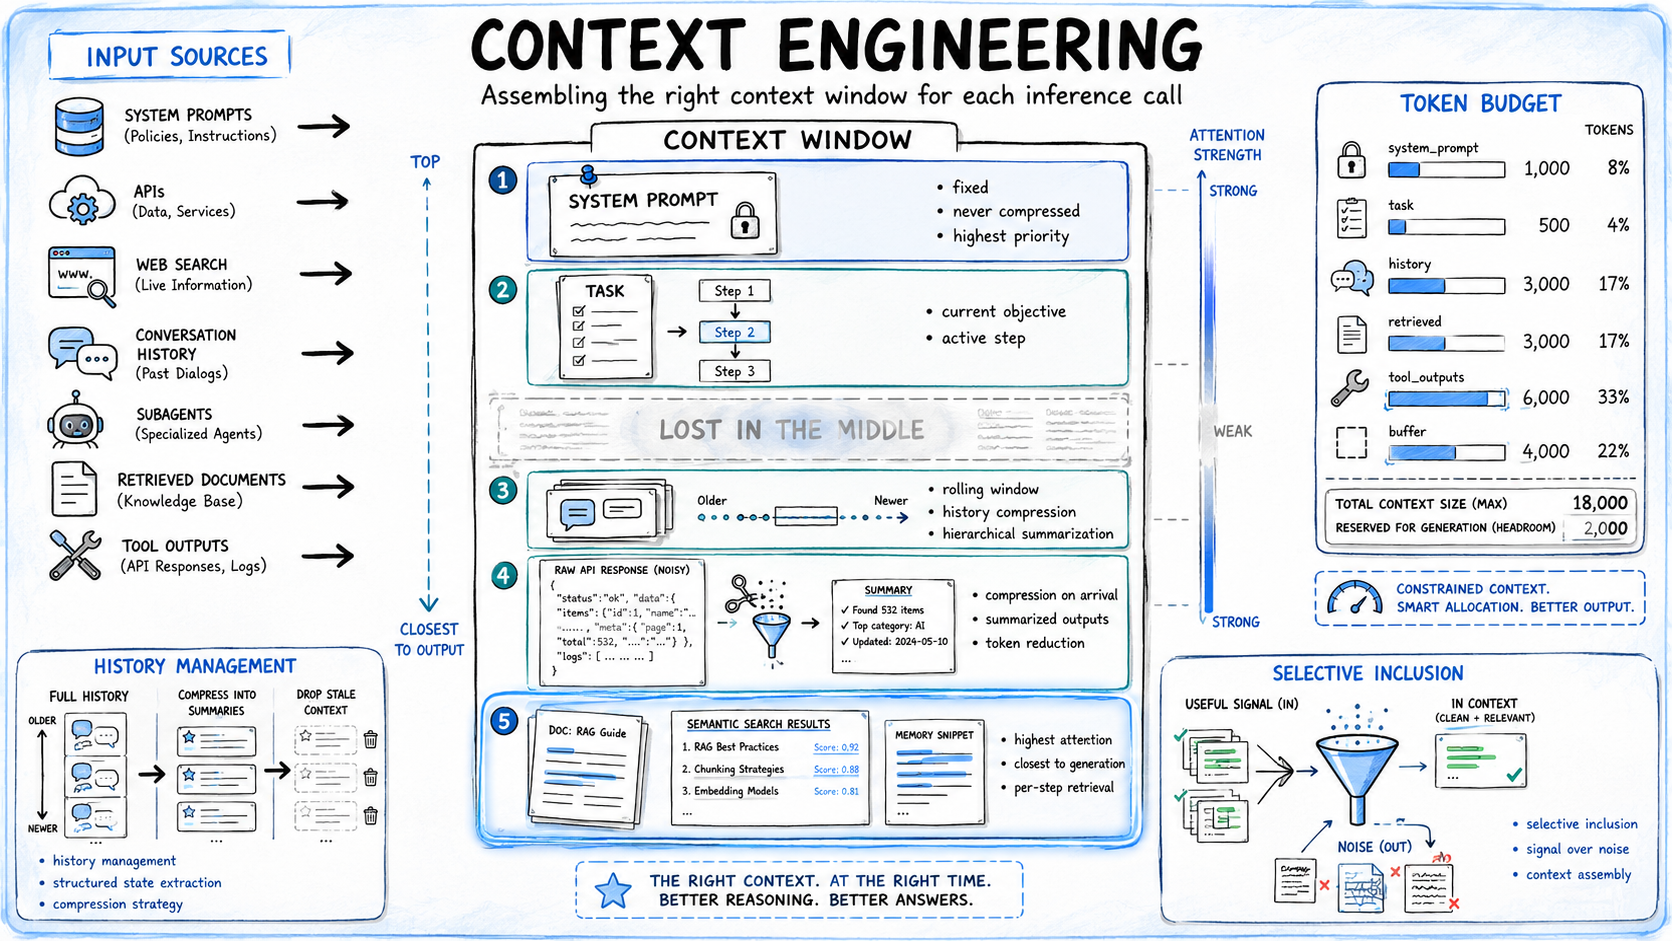
For an agent operating a multi-step workflow, each inference name assembles a context window from a number of sources: system immediate, job description, dialog historical past, instrument outputs, retrieved paperwork, subagent summaries. Context engineering is the set of selections that decide what every part contributes, in what type, and in what place.
Selective Inclusion
Not every thing accessible ought to enter the context. A database question returning tons of of rows, an online search returning 5 full articles, a code executor logging verbose output — all of those bloat the window and cut back reasoning high quality earlier than the token restrict is reached. The choice about what will get included verbatim, what will get compressed to key information, and what will get dropped is a design selection, not a default.
Structural Placement
The place info sits within the window impacts how reliably the mannequin makes use of it. Fashions attend extra strongly to content material originally and finish of lengthy contexts, with materials within the center receiving considerably much less weight. This is named the “misplaced within the center” impact.
Exhausting constraints and task-critical directions belong on the high of the window. Retrieved info that’s most related to the present job ought to be positioned close to the tip of the context window.
The present person question or job ought to sometimes observe the retrieved info, positioning each the related context and the rapid goal as shut as doable to the technology level. This association will increase the chance that the mannequin will successfully use the retrieved info when producing its response.
Context Engineering Overview
Compression on Arrival
Instrument outputs ought to be compressed after a name returns, not after the window fills. A uncooked API response carrying 3,000 tokens, of which the agent wants solely 150, ought to be summarized earlier than it enters context for the following step. Ready till the window is full after which scrambling to truncate is reactive administration of an issue that compression on the supply prevents.
Dialog Historical past Administration
Dialog historical past grows sooner than every other context part. For long-running brokers, carrying the total historical past into each name makes each subsequent inference costlier and fewer dependable. A compression technique — rolling window, hierarchical summarization, or structured state extraction — ought to be utilized at outlined intervals, not when the window overflows.
Reminiscence Engineering: Designing Persistent AI Reminiscence Methods
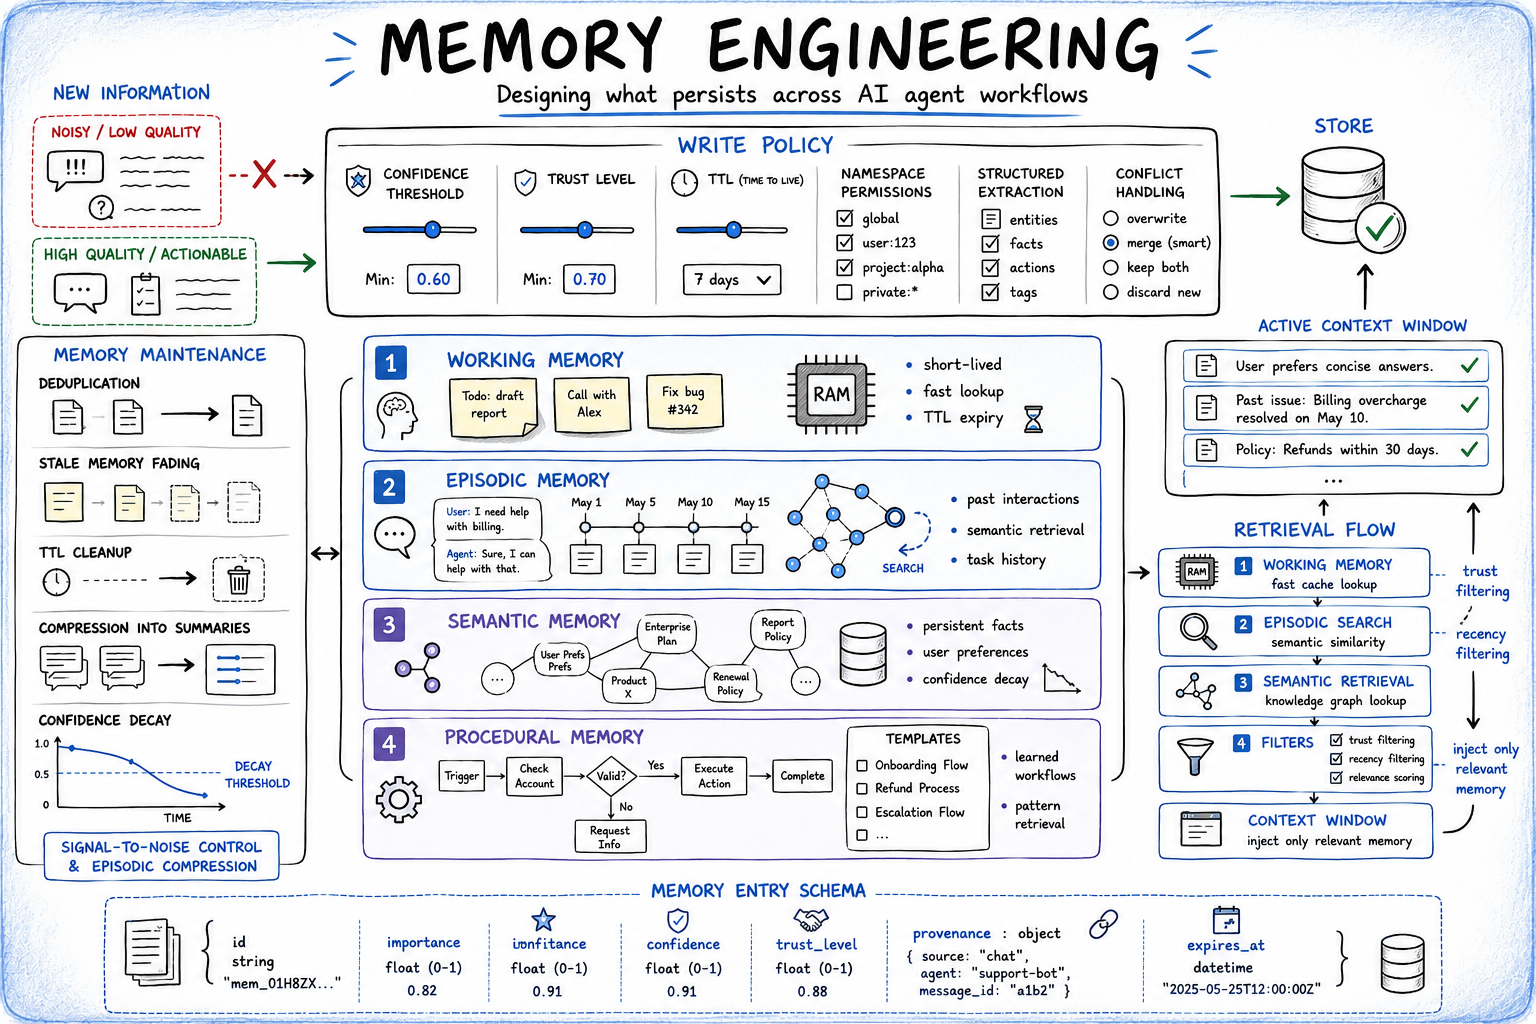
As soon as an inference name completes, reminiscence engineering determines what deserves to persist and beneath what situations it will get used once more. This covers 4 distinct considerations: what to jot down, the place to retailer it, retrieve it, and preserve it correct over time.
Write Coverage Design
Write coverage design is among the most neglected features of reminiscence engineering, but it has a disproportionate influence on reminiscence high quality over time. Whereas retrieval methods usually obtain essentially the most consideration, retrieval high quality is finally constrained by what enters the reminiscence retailer within the first place.
A well-defined write coverage specifies:
What occasions set off a write to reminiscence
Which info is eligible for storage
The format wherein info is saved, corresponding to uncooked textual content, structured information, extracted information, or summaries
The arrogance or validation necessities for accepting new entries
Which brokers, instruments, or system parts are permitted to jot down to particular reminiscence namespaces
How updates, corrections, and conflicting info are dealt with
Retention guidelines, expiration insurance policies, and time-to-live (TTL) necessities for various reminiscence sorts
With out express write insurance policies, methods usually default to storing an excessive amount of info, assigning equal belief to all entries, and retaining information indefinitely. Over time, low-value and outdated reminiscences accumulate, signal-to-noise ratios decline, and retrieval high quality degrades. The result’s a reminiscence system that grows repeatedly whereas changing into progressively much less helpful.
Storage Layer Choice
Totally different reminiscence sorts serve totally different functions and require totally different storage backends. The selection of backend additionally constrains which retrieval methods can be found.
Reminiscence Kind
What It Shops
Storage Backend
Retrieval Technique
Working
Lively job state, intermediate outcomes
In-memory or short-lived Ok/V (Redis)
Direct key lookup
Episodic
Previous interactions, job runs, choices
Vector retailer (Pinecone, Weaviate, Chroma)
Semantic similarity search
Semantic
Persistent information, person preferences, area information
Vector retailer + Ok/V hybrid
Semantic search or precise key
Procedural
Discovered workflows, profitable motion patterns
Structured retailer or immediate injection
Sample match, direct retrieval
OpenAI’s context personalization cookbook makes a helpful distinction between retrieval-based reminiscence and state-based reminiscence to be used circumstances requiring continuity. Retrieval-based reminiscence treats previous interactions as loosely associated paperwork and is brittle to phrasing variation and conflicting updates. Structured state extraction — writing typed, validated information quite than embedding uncooked dialog chunks — produces extra constant outcomes for information that have to be utilized reliably throughout classes.
Reminiscence Engineering Overview
Retrieval Technique
Studying from reminiscence shouldn’t be a single operation. A well-designed retrieval layer checks working reminiscence first (quick, low cost, precise key lookup), falls again to semantic search in episodic or semantic reminiscence when nothing related surfaces, applies metadata filters for recency and belief stage earlier than returning outcomes, and injects solely what the present step wants.
Reminiscence Upkeep
A retailer with no upkeep coverage degrades over time. The entries accumulate, stale information compete with present ones, and retrieval high quality falls as signal-to-noise ratio drops. The next upkeep routines matter in apply: confidence decay on unstable information, deduplication of semantically comparable entries, TTL-based expiry on working reminiscence and time-sensitive information, and periodic compression of previous episodic information into session-level summaries.
A MemoryEntry schema that encodes these considerations immediately makes write and upkeep logic simpler to cause about:
class MemoryEntry(BaseModel):
content material: str
memory_type: str # working | episodic | semantic | procedural
significance: float # 0.0–1.0, gates long-term storage
confidence: float # decays over time for unstable information
trust_level: float # 1.0 inside system, 0.5 person enter, 0.0 exterior
created_at: datetime
expires_at: datetime | None
provenance: dict # agent_id, tool_name, session_id, input_hash
def should_write_to_long_term(entry: MemoryEntry) -> bool:
return (
entry.significance >= 0.6
and entry.confidence >= 0.7
and entry.trust_level >= 0.5
)
class MemoryEntry(BaseModel):
content material: str
memory_type: str # working | episodic | semantic | procedural
significance: float # 0.0–1.0, gates long-term storage
confidence: float # decays over time for unstable information
trust_level: float # 1.0 inside system, 0.5 person enter, 0.0 exterior
created_at: datetime
expires_at: datetime | None
provenance: dict # agent_id, tool_name, session_id, input_hash
def should_write_to_long_term(entry: MemoryEntry) -> bool:
return (
entry.significance >= 0.6
and entry.confidence >= 0.7
and entry.trust_level >= 0.5
)
AI Agent Reminiscence Design Information – Working, Lengthy-Time period, and Procedural Reminiscence with Forgetting and Staleness Administration and seven Steps to Mastering Reminiscence in Agentic AI Methods are helpful overviews of agent reminiscence design.
The Retrieval Boundary: Connecting Reminiscence and Context Engineering
Reminiscence engineering and context engineering are sometimes mentioned as separate disciplines, however in apply they’re deeply interconnected. Each exist to resolve the identical elementary drawback: guaranteeing {that a} mannequin has entry to the fitting info on the proper time.
At a excessive stage:
Reminiscence engineering focuses on persistence: what info ought to be saved, up to date, retained, or forgotten over time.
Context engineering focuses on utilization: what info ought to enter the energetic context window for a selected job and the way it ought to be organized.
Retrieval is the boundary the place these two disciplines meet.
Reminiscence methods produce candidate info. Context meeting then decides:
Whether or not that info ought to enter the immediate
How a lot of it ought to be included
The place it ought to be positioned throughout the context window
Managing this boundary properly is what transforms a set of reminiscence parts right into a coherent agent system.
Failure Mode #1: Retrieval With no Context Finances
One of the vital frequent failures happens when retrieval is handled independently from context meeting.
A reminiscence search returns a set of related entries, and the context assembler injects all of them into the immediate. As extra reminiscences are added, the context window step by step fills with retrieved content material, leaving much less room for directions, instrument outputs, reasoning traces, and task-specific info.
The ensuing signs are sometimes deceptive:
Retrieval high quality seems excessive
Related reminiscences are efficiently discovered
System efficiency nonetheless degrades
In lots of circumstances, the reminiscence system has accomplished its job appropriately. The failure happens as a result of context meeting lacks a budgeting mechanism.
A greater method is retrieval-aware context meeting. As an alternative of retrieving first and budgeting later, the context layer allocates a token funds earlier than retrieval begins. The retrieval layer then returns solely the highest-value reminiscences that match inside that funds.
async def retrieve_for_step(
self,
step: AgentStep,
max_tokens: int
) -> str:
candidates = await self.reminiscence.search(
question=step.retrieval_query,
max_results=10,
filters={
“trust_level”: {“gte”: 0.5},
“expires_at”: {“gt”: datetime.now()}
}
)
chosen = []
used = 0
for entry in sorted(
candidates,
key=lambda e: e.relevance_score,
reverse=True
):
price = self.token_count(entry.content material)
if used + price > max_tokens:
break
chosen.append(entry.content material)
used += price
return “nn”.be a part of(chosen)
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
async def retrieve_for_step(
self,
step: AgentStep,
max_tokens: int
) -> str:
candidates = await self.reminiscence.search(
question=step.retrieval_query,
max_results=10,
filters={
“trust_level”: {“gte”: 0.5},
“expires_at”: {“gt”: datetime.now()}
}
)
chosen = []
used = 0
for entry in sorted(
candidates,
key=lambda e: e.relevance_score,
reverse=True
):
price = self.token_count(entry.content material)
if used + price > max_tokens:
break
chosen.append(entry.content material)
used += price
return “nn”.be a part of(chosen)
The important thing thought is straightforward: retrieval should function inside context constraints, not assume limitless area downstream.
Failure Mode #2: Poor Placement of Retrieved Info
Retrieval high quality alone shouldn’t be enough. Even extremely related reminiscences can fail if they’re positioned incorrectly contained in the context window.
A standard difficulty is treating retrieval purely as a search drawback whereas ignoring placement. Retrieved reminiscences are appended wherever they arrive, with out contemplating their function within the present reasoning step.
This turns into extra impactful in lengthy contexts. Consideration shouldn’t be uniformly distributed throughout the immediate. Info positioned deep inside a protracted context can obtain considerably much less affect than info positioned close to the start or finish. This results in a delicate failure mode:
The right info is retrieved
The knowledge is inserted into context
The mannequin behaves as whether it is lacking
The retrieval succeeded however the placement failed. Context meeting ought to due to this fact optimize each:
Choice: what enters the context window
Placement: the place it seems throughout the context window
Retrieved info that should affect the present step ought to be positioned close to the energetic reasoning area quite than appended arbitrarily.
Retrieval as a Step in Context Building
Retrieval is step one in turning saved reminiscence into usable context. The aim shouldn’t be solely to retrieve related info, however to make sure it’s the proper info for the present step, in the correct amount to suit throughout the context funds, and positioned in the fitting location the place the mannequin can successfully use it.
When reminiscence engineering and context engineering are handled as a single retrieval-to-context pipeline, quite than remoted parts, agent methods turn out to be extra dependable, environment friendly, and scalable.
Context Engineering – LLM Reminiscence and Retrieval for AI Brokers by Weaviate is a good reference.
Abstract
Context and reminiscence engineering are two layers of a single system that controls what the mannequin is aware of, when it is aware of it, and the way that information is used.
Context engineering operates at inference time, shaping the energetic info window. Reminiscence engineering operates throughout time, shaping what info persists and the way it may be retrieved later.
Dimension
Context Engineering
Reminiscence Engineering
Core query
What ought to the mannequin see proper now, and the way?
What ought to the system retain, and for the way lengthy?
Main artifact
Assembled context window per inference name
Persevered reminiscence entries throughout calls and classes
Token administration
Finances allocation per window part
Storage price per entry kind; retrieval price per question
Compression
Instrument outputs summarized earlier than injection; historical past rolled or extracted
Outdated episodic information compressed; stale information decayed or pruned
Freshness
Rolling historical past window; stale turns dropped
TTL on unstable information; confidence decay over time
Belief
Supply hierarchy governs meeting order
Provenance tracked per entry; low-trust content material sanitized earlier than write
Multi-agent
Every agent assembles its personal window independently
Scoped namespaces per agent; shared namespace for cross-agent information
Failure mode
Overflow, consideration degradation, noisy meeting
Poisoning, staleness, retrieval miss, unbounded development
Upkeep
Proactive compression at outlined intervals
TTL expiry, deduplication, confidence decay, episodic archiving
The place they meet
Retrieved reminiscence enters context: funds and placement govern how
Context meeting requests retrieval inside a token funds constraint
To sum up, an agentic system solely works when each layers are aligned: reminiscence determines what is offered, and context determines what turns into actionable.

