On this article, you’ll learn to consider AI brokers rigorously by analyzing their full execution course of moderately than solely their remaining outputs.
Matters we’ll cowl embrace:
Why agent analysis differs from conventional language mannequin analysis, and the place brokers fail throughout the reasoning and motion layers.
The right way to grade brokers with deterministic code-based checks and model-based judges, matched to the kind of agent you might be constructing.
The right way to account for non-determinism utilizing metrics like go@okay and go^okay, and lengthen analysis from improvement into manufacturing monitoring.
The Roadmap to Mastering AI Agent Analysis
Let’s not waste any extra time.
Introduction
Many groups constructing AI brokers nonetheless consider them the identical method they consider massive language fashions: run a number of duties, examine the ultimate output, and assume the whole lot is working. That method typically misses the failures that matter most. The mannequin might choose an inappropriate instrument or generate incorrect instrument arguments, whereas the agent system might deal with instrument failures poorly or observe an inefficient sequence of actions. Evaluating solely the ultimate response typically makes it tough to determine the place these failures occurred.
Agent analysis addresses this hole. Fairly than focusing solely on outcomes, it examines the total execution course of — how an agent causes, makes choices, makes use of instruments, and adapts as a job unfolds. This supplies a extra correct image of reliability, effectivity, and total efficiency, serving to groups determine points earlier than they attain manufacturing.
The ideas coated on this article type the muse of a scientific method to measuring and bettering agent efficiency.
Step 1: Understanding Why Agent Analysis Is Necessary
The intuition when an agent fails is to deal with it as a prompting downside: the system immediate must be clearer. Typically that’s true. Extra typically the failure is a measurement downside: the eval was not designed to catch what broke.
AI brokers function throughout layers, and people layers might fail independently:
The reasoning layer — powered by the language mannequin — handles planning, job decomposition, and power choice.
The motion layer — powered by instrument calls and exterior system responses — handles execution.
An agent can purpose accurately about what to do after which name the proper instrument with malformed arguments. Treating agent analysis as a single end-to-end accuracy verify misses each failure surfaces.
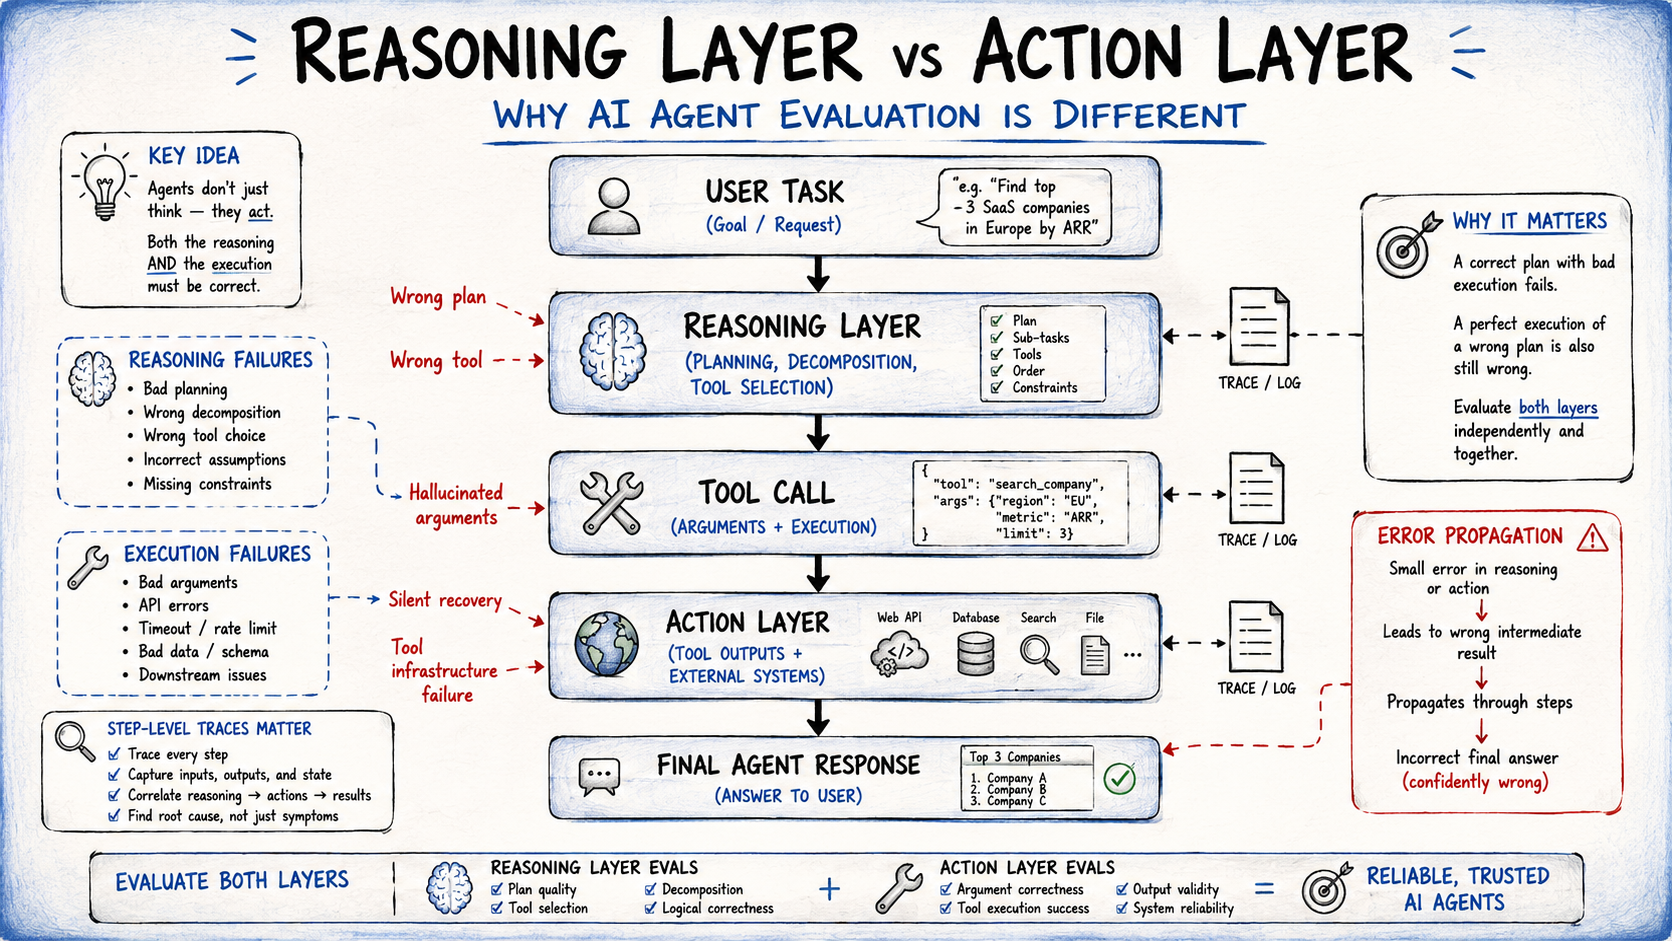
Reasoning vs Motion Layer
Helpful agent analysis runs at two scopes:
A job completion price of 80% tells you nothing about whether or not the 20% failure comes from unhealthy planning, incorrect instrument choice, incorrect arguments, or instrument infrastructure failures. Step-level traces — logs capturing every instrument name, its arguments, its outcome, and the next mannequin determination — are what make that prognosis doable. With out traces, debugging a manufacturing failure is guesswork.
Step 2: Defining What Agent Analysis Success Seems Like
Analysis is just pretty much as good as its success standards. A well-formed eval job is one the place two area specialists, working independently, would attain the identical go/fail verdict.
Begin with unambiguous job specs paired with reference options — known-correct outputs that go all graders. They show the duty is solvable and confirm that grading logic is accurately configured.
You want the next outlined for evals earlier than any grading runs:
The duty: what inputs the agent receives, what it’s anticipated to do, and what the atmosphere appears to be like like moving into
The success standards: not simply the ultimate reply, however the intermediate outcomes that matter: Was the proper instrument known as? Was the state accurately up to date? Was the response grounded within the retrieved context?
The unfavourable instances: one-sided evals create one-sided optimization. Balanced datasets — overlaying each when a conduct ought to happen and when it mustn’t — forestall brokers that over-trigger or under-trigger on a functionality
A set of well-specified duties drawn from actual utilization failures is a greater start line than ready for the right dataset. Evals get tougher to construct the longer you wait.
Step 3: Grading the Agent Motion Layer with Code-Primarily based Checks
Deterministic graders — code that checks particular circumstances with out model-in-the-loop judgment — are the quickest, most cost-effective, and most reproducible possibility in any agent eval stack. For the motion layer, they need to all the time be the place to begin:
Instrument name verification: whether or not the agent known as the proper instrument within the appropriate sequence
Argument validation: whether or not inputs have appropriate varieties, required parameters, and legitimate values
Consequence verification: whether or not the atmosphere ends within the anticipated state
Transcript evaluation: variety of turns, tokens consumed, and latency
These are sometimes quick, goal, and simple to debug, however brittle. A grader checking for “confirmation_code”: “CONF-789” will miss an accurate response that codecs the identical information in another way.
Step 4: Grading Agent Reasoning and Output High quality with Mannequin-Primarily based Judges
Some agent analysis dimensions resist deterministic checking — output high quality, tone, faithfulness to retrieved context, acceptable empathy. For these, a language mannequin used as a choose or LLM-as-a-Decide is the proper instrument: versatile and able to dealing with open-ended output, however introducing non-determinism and calibration drift that code-based graders don’t have.
The next practices hold model-based graders dependable:
Write structured rubrics. “Consider whether or not the response is useful” produces noise. A rubric specifying that the response should tackle the consumer’s query, floor claims in retrieved context, and keep away from out-of-scope ideas produces a sign. Grade every dimension with a separate, remoted judgment.
Calibrate towards human judgment commonly. LLM-as-judge accuracy needs to be checked towards a pattern graded by area specialists. The place divergence exhibits up, the rubric is sort of all the time the issue. Give the grader an specific “Can not decide” choice to keep away from compelled judgments on ambiguous instances.
Construct in partial credit score for multi-component duties. A assist agent that accurately identifies the issue and verifies the client however fails to course of the refund is meaningfully higher than one which fails on the first step. Binary go/fail hides the place the agent is definitely breaking down.
Step 5: Matching Agent Analysis Technique to Agent Kind
Grading methods apply broadly, however agent sort determines which graders carry essentially the most weight and which failure modes to prioritize.
Coding brokers write, check, and debug code. Software program is basically deterministic: does the code run, do the checks go, does the repair shut the difficulty with out breaking current performance? Benchmarks like SWE-bench Verified and Terminal-Bench observe this go/fail method, supplemented by rubric-based high quality checks for safety, readability, and edge case dealing with.
Conversational brokers work together with customers throughout assist, gross sales, and training workflows. The standard of the interplay is a part of what’s being evaluated — not solely whether or not the ticket was resolved, however whether or not the tone was acceptable and the decision clearly defined. This requires a second language mannequin simulating the consumer; τ-bench fashions precisely this, with graders assessing each job completion and interplay high quality throughout turns.
Analysis brokers collect and synthesize info throughout sources. Groundedness checks confirm claims are supported by retrieved sources, protection checks outline what a very good reply should embrace, and supply high quality checks affirm the agent consulted authoritative materials.
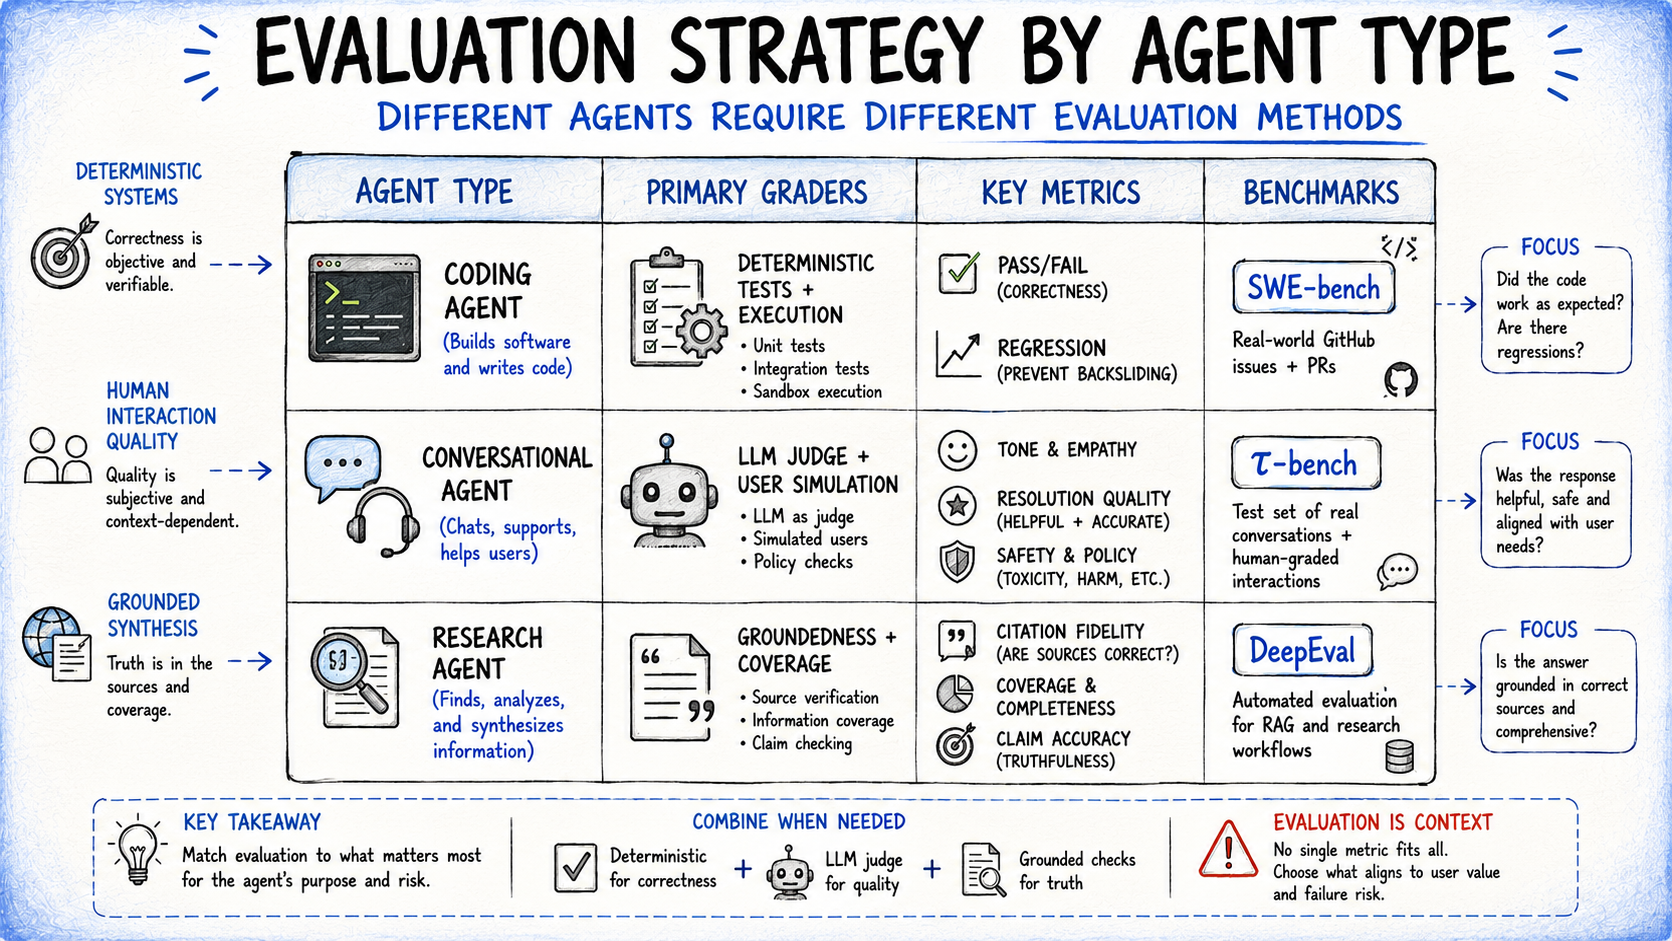
Matching Agent Analysis Technique to Agent Kind
Step 6: Accounting for Non-Determinism in Agent Analysis Outcomes
Agent conduct varies between runs; the identical job, identical inputs, identical agent can produce totally different instrument picks, reasoning paths, and outcomes. Single-trial analysis can subsequently be deceptive, because it hides variability that straightforward accuracy metrics fail to seize.
This can be a direct consequence of non-determinism in agent programs. Stochastic mannequin outputs, instrument latency, partial failures, and adaptive decision-making all introduce variability throughout runs. In consequence, evaluating an agent requires reasoning over distributions of outcomes moderately than a single execution hint.
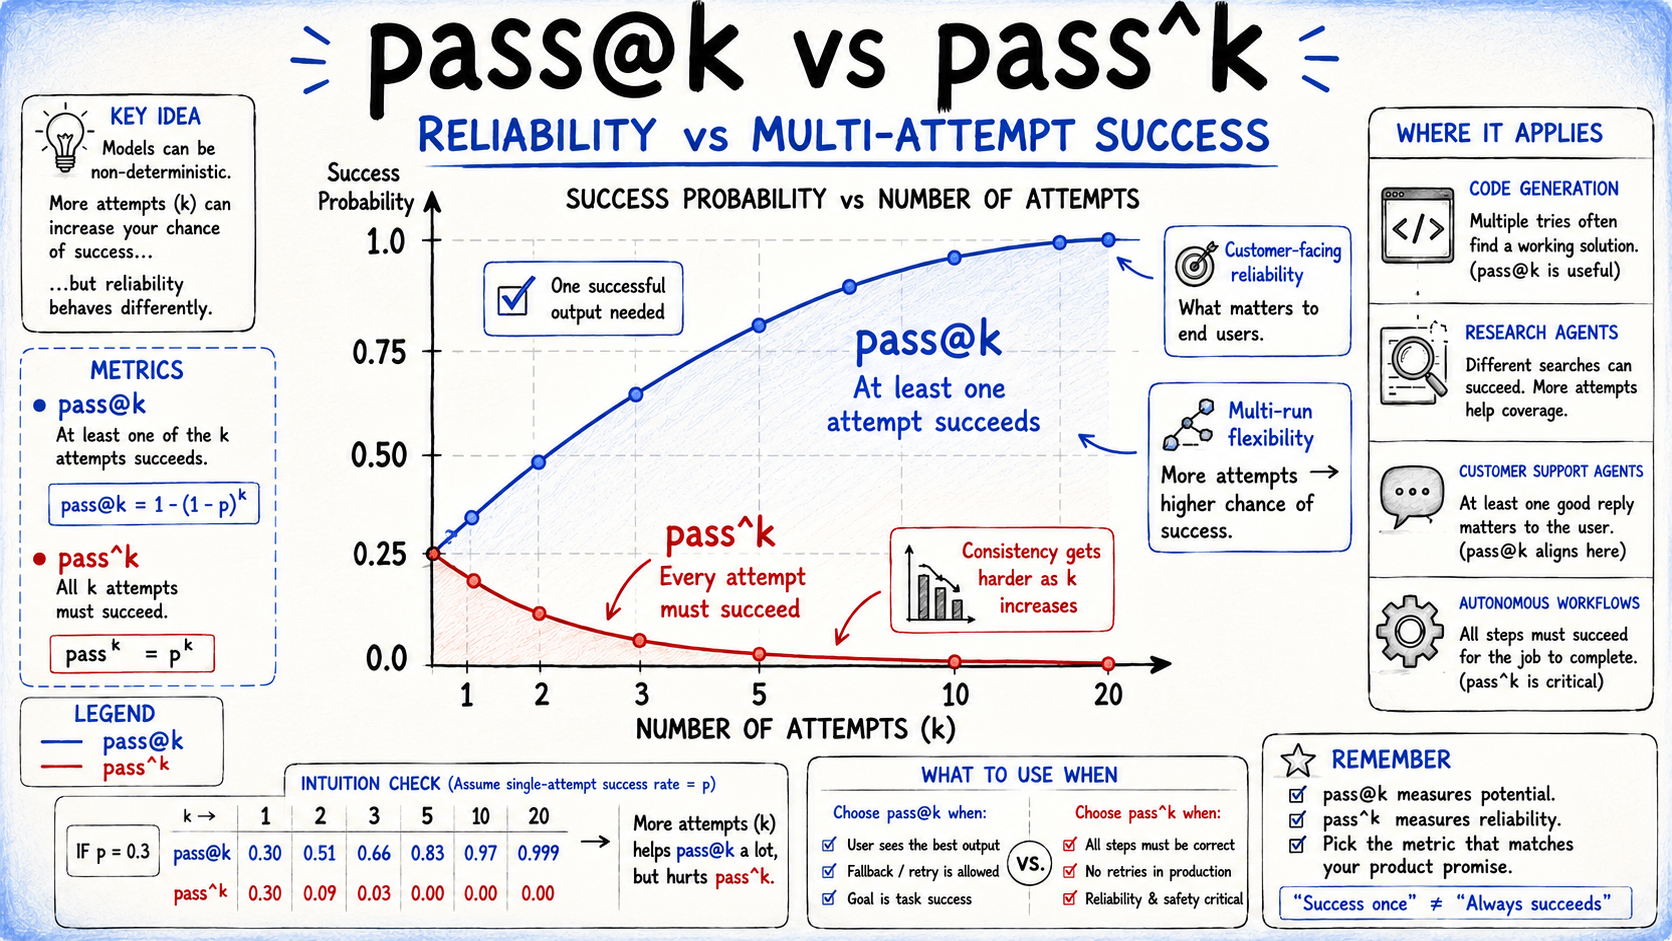
To account for this variability, metrics like go@okay and go^okay are generally used:
go@okay: the chance that not less than considered one of okay unbiased trials succeeds, helpful when a number of makes an attempt are acceptable
go^okay: the chance that each one okay trials succeed, necessary when each interplay should be dependable
For instance, an agent with a 75 % single-trial success price succeeds on all three makes an attempt solely about 42 % of the time, displaying how rapidly reliability degrades throughout repeated runs.
go@okay and go^okay
The selection between these metrics is finally a product determination moderately than a purely technical one. If just one appropriate consequence is required, go@1 or go@okay is beneficial. If each interplay should succeed persistently, go^okay is the extra significant measure.
Step 7: Separating Agent Functionality Evals from Regression Suites
Functionality evals are designed to reply a forward-looking query: what can this agent try this it couldn’t do earlier than? Due to that, they need to start with comparatively low go charges and give attention to duties which might be nonetheless difficult for the system. When a functionality eval reaches very excessive scores — say 90 % — it’s typically now not measuring functionality, however merely confirming reliability on already solved issues.
Regression evals serve a special goal. They ask whether or not the agent can nonetheless carry out the whole lot it beforehand may. These checks ought to run near one hundred pc and act as a safeguard towards efficiency regressions. Any significant drop in rating is a sign that one thing has damaged and needs to be investigated earlier than launch.
Over time, functionality evals naturally change into simpler for the agent. As go charges rise and efficiency stabilizes, these duties might be promoted into the regression suite. Nonetheless, as soon as a collection totally saturates, it turns into much less delicate to actual enhancements — that means significant progress might seem as noise moderately than sign. Because of this, new and tougher evals needs to be launched earlier than the present suite saturates, not after.
Step 8: Extending Agent Analysis into Manufacturing Monitoring
Improvement evals seize what you anticipate to fail; manufacturing reveals what truly does. Actual customers introduce inputs, edge instances, and contexts that not often seem in artificial check suites, making manufacturing monitoring a essential extension of analysis.
A whole analysis system combines a number of complementary alerts:
Technique
What it Captures
Automated evals
Run on each commit, overlaying identified failure modes at scale earlier than customers are impacted. Can create false confidence when real-world utilization diverges from the check distribution.
Manufacturing monitoring
Tracks latency, error charges, instrument failures, and token utilization. Surfaces points artificial checks miss, however sometimes solely after they happen.
Person suggestions
Highlights instances the place the agent appears appropriate by metrics however fails the consumer’s intent. Sparse and self-selected, however typically extremely informative.
Guide transcript evaluation
Gives qualitative perception into reasoning, instrument use, and determination paths, and helps validate whether or not automated graders are measuring the proper behaviors.
Collectively, these layers type a extra full view of agent efficiency in follow. Step-level traces — capturing reasoning, instrument calls, arguments, outcomes, and choices at every level within the loop — are the infrastructure that makes all of this work. Instruments like LangSmith, Arize Phoenix, Braintrust, and Langfuse present tracing and eval frameworks;Harbor and DeepEval deal with the harness layer.
Abstract of Key Agent Analysis Steps
Right here’s a fast overview of the steps we’ve mentioned:
Step
Why it Issues
Agent analysis as a definite downside
Brokers fail throughout reasoning and motion layers. Finish-to-end accuracy can conceal each forms of failures.
Defining success earlier than measuring it
Clear specs and reference outputs cut back noise and make analysis metrics extra significant.
Code-based graders for the motion layer
Deterministic checks rapidly determine instrument utilization, argument, and execution errors.
Mannequin-based judges for reasoning and output high quality
LLM-based grading captures nuanced qualities akin to correctness, faithfulness, and tone.
Analysis technique by agent sort
Totally different brokers fail in numerous methods, requiring analysis strategies tailor-made to every use case.
go@okay and go^okay for non-determinism
Single-run outcomes might be deceptive. Metrics ought to mirror whether or not one or all makes an attempt should succeed.
Functionality vs regression evals
Functionality evaluations measure progress, whereas regression evaluations defend current efficiency.
Extending analysis into manufacturing
Monitoring, consumer suggestions, and transcript evaluations reveal real-world failures that offline evaluations might miss.
As a subsequent step, learn Anthropic’s Demystifying evals for AI brokers information, particularly the part Going from zero to at least one: a roadmap to nice evals for brokers.